S1 · 目标检测 · F 主会固定版A Dual Weighting Label Assignment Scheme for Object Detection
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第4页 · P66
300 dpi PNG · 图注 · 源PDF
图2图注明确展示骨干、FPN、检测头、正负样本权重和检测损失的整体流程。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-18;arXiv v1:2022-03-18;CVPR 2022 fixed official PDF
已查看固定PDF及目标图;以最早已核实匹配版本日期作时间代理,不声称实际作图日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[75, 70, 523, 191],PDF点、左上角原点。
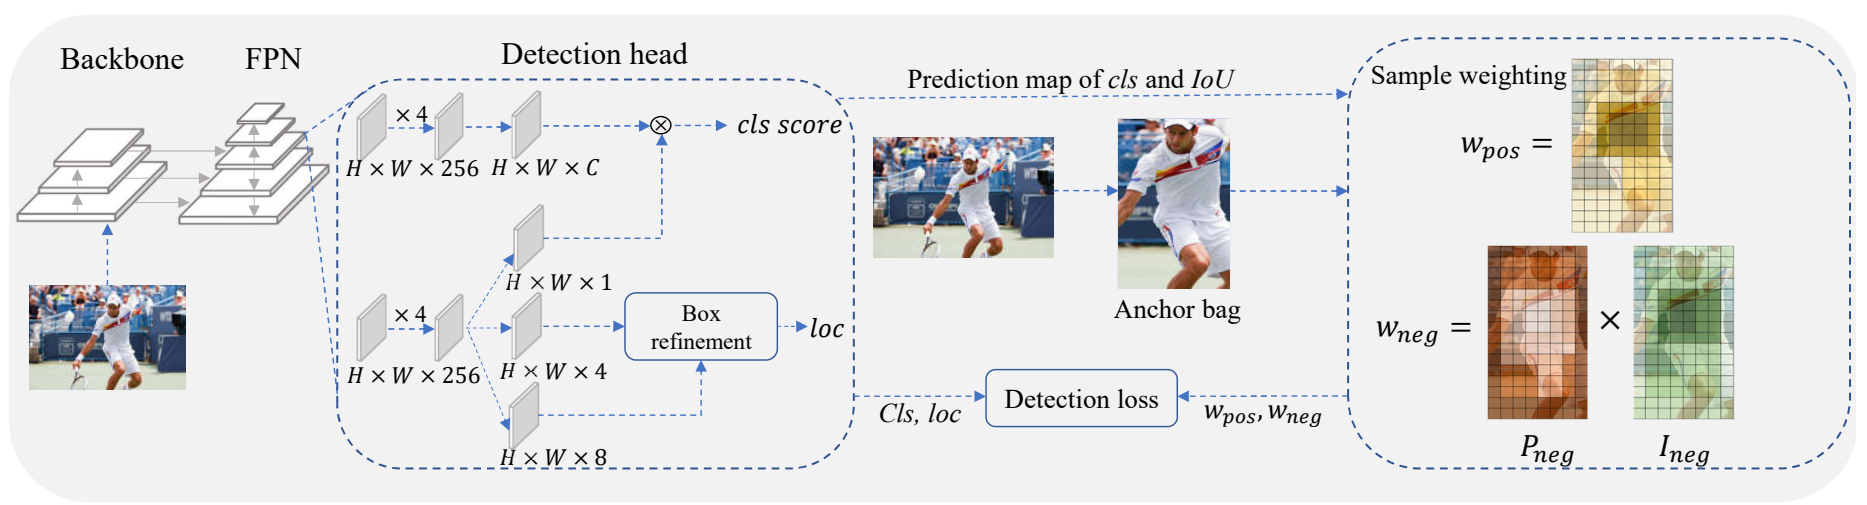
Figure 2. Pipeline of DW. The left part shows the overall detection model which consists of backbone, FPN and detection head. The
outputs from the classification branch (H × W × C) and the centerness branch (H × W × 1) are multiplied as the final cls score. The
box refinement module utilizes the four predicted boundary points (H × W × 8) to adjust the coarse prediction (H × W × 4) to finer
locations.The right part shows the weighting process. Given an object, a candidate anchor bag is first constructed by selecting the anchor
points near the object center. Each anchor will then be assigned a pos weight and neg weight from different aspects.
A Dual Weighting Label Assignment Scheme for Object Detection
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P65
300 dpi PNG · 图注 · 源PDF
图1与第3.3节以歧义候选框说明已有方法给予近似相同权重的问题,是标签分配概念对比。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-18;arXiv v1:2022-03-18;CVPR 2022 fixed official PDF
已查看固定PDF及目标图;以最早已核实匹配版本日期作时间代理,不声称实际作图日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[314, 215, 540, 357],PDF点、左上角原点。
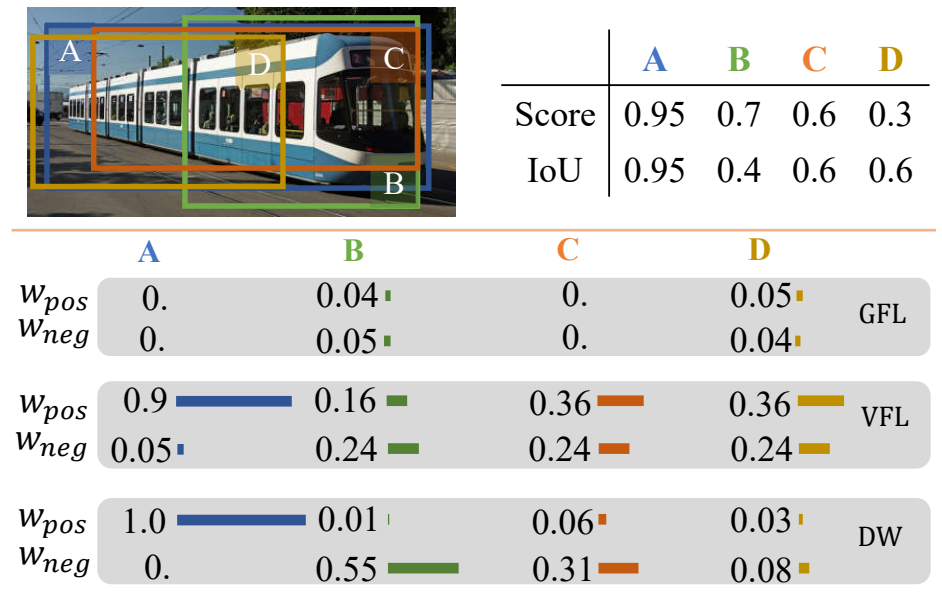
Figure 1. An illustration of the difference between the proposed
DWmethodandexistinglabelassignmentmethods,e.g.,GFL[21]
and VFL [43]. For ambiguous anchors B, C and D, GFL and VFL
willassignnearlythesameposandnegweightsto{B,D}and{C,
D}, respectively. In contrast, our DW assigns a distinct (pos, neg)
pair for each anchor.Cross Domain Object Detection by Target-Perceived Dual Branch Distillation
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第3页 · P226
300 dpi PNG · 图注 · 源PDF
图2明确为TDD整体框架,完整呈现源域/目标域/风格迁移输入、共享候选提取、双分支、目标感知器与监督损失。
完整图注、版本和筛选证据
最早核实视觉日期:2022-05-03;arXiv v1:2022-05-03;CVPR 2022 fixed official PDF
已读固定PDF图注、正文及作者单位。v1与会议F完全相同;M图参考文献编号由27/49改成29/51,保留历史裁剪证据,会议M采用官方Bibtex公开月份,不能声称v1已含更新的编号。完整导出已目检。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yali Wang;17994;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[98, 71, 497, 238],PDF点、左上角原点。
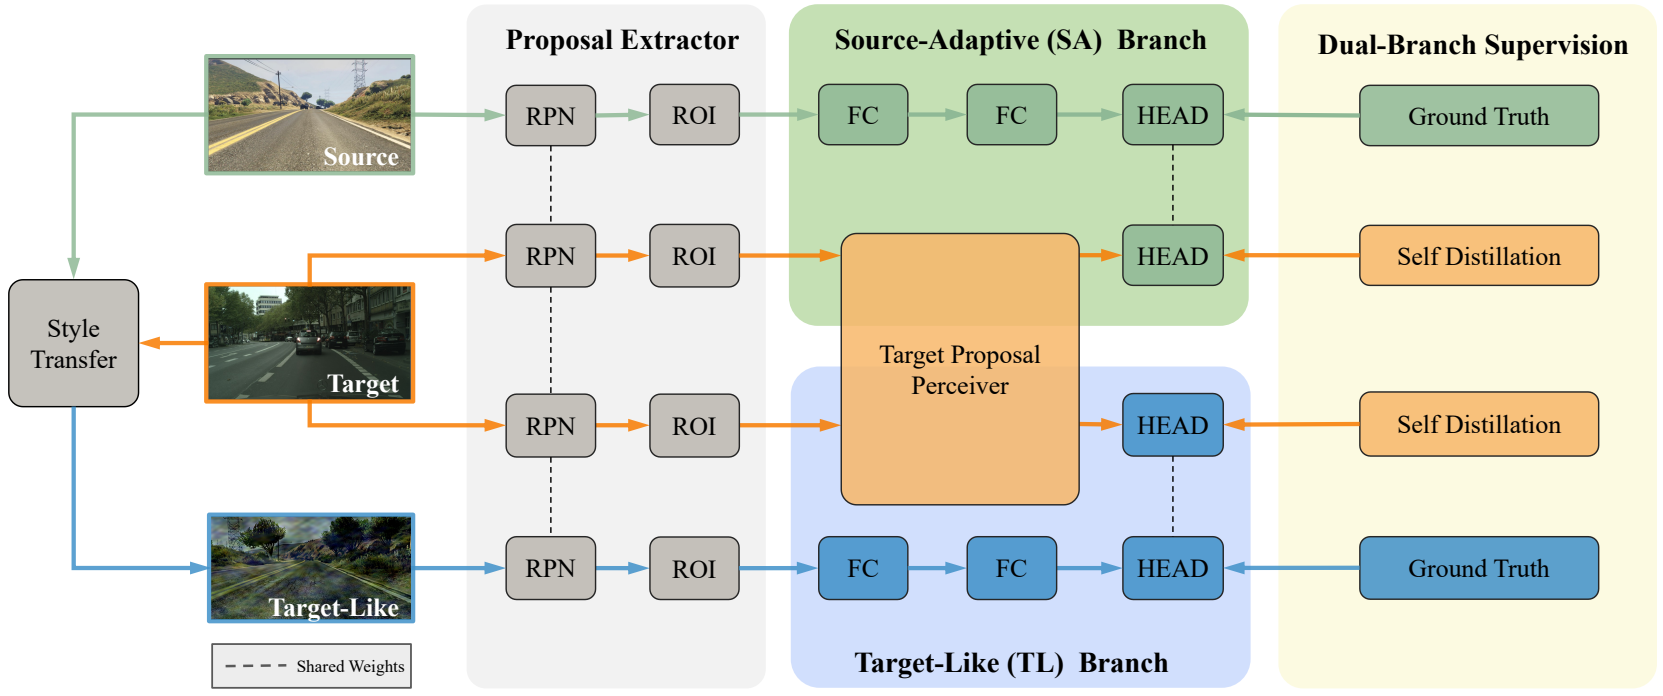
Figure 2. An overview of Target-perceived Dual-branch Distillation framework. To simplify the description, ROI refers to the operation
to get proposal features of each image. First, a source domain image is transferred into target-like domain. All of the images from three
domains are fed to a shared proposal extractor to get proposals and proposal features. Then, the proposal features of source and target-like
images are used to train corresponding branches with supervision of ground truth. Moreover, we feed the proposal features of a real target
domain image into both branches, for learning object knowledge from both source and target-like domains. As the images from target
domain are not annotated, the model is optimized by self-distillation.
Cross Domain Object Detection by Target-Perceived Dual Branch Distillation
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P225
300 dpi PNG · 图注 · 源PDF
图1图注及引言明确解释雾天UBT漏检、GPA把背景误判为摩托车/行人的失败案例,用于引出域差异与标签缺失双重问题。
完整图注、版本和筛选证据
最早核实视觉日期:2022-06;arXiv v1:2022-05-03;CVPR 2022 fixed official PDF
已读固定PDF图注、正文及作者单位。v1与会议F完全相同;M图参考文献编号由27/49改成29/51,保留历史裁剪证据,会议M采用官方Bibtex公开月份,不能声称v1已含更新的编号。完整导出已目检。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yali Wang;17994;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[309, 275, 546, 383],PDF点、左上角原点。
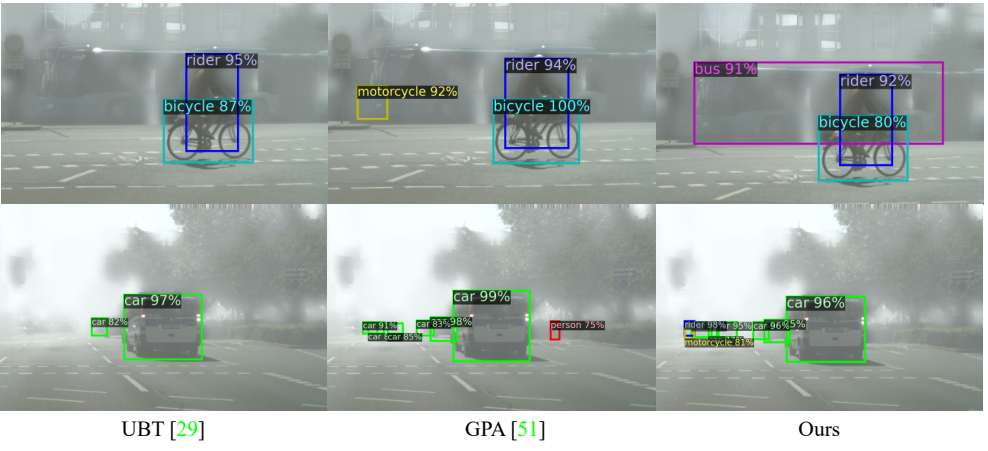
Figure 1. Two typical examples of detection results on the adverse
weather conditions adaptation experiments with different methods.
Semi-supervised method UBT [27] lacks awareness of objects in
the fog. Adversarial based GPA [49] attempts to exploit the objects
in the fog but gives some wrong predictions, such as the motorcy-
cle in the first row and the person in the second row. Our methods
can predict the boxes and categories more accurately.
Dense Learning based Semi-Supervised Object Detection
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第3页 · P96
300 dpi PNG · 图注 · 源PDF
第3.1节和图2展示教师、学生、自适应筛选、MetaNet和多项损失的完整半监督训练流程。
完整图注、版本和筛选证据
最早核实视觉日期:2022-04-15;arXiv v1:2022-04-15;CVPR 2022 fixed official PDF
已阅读会议版图注及正文并逐张查看导出。会议图与对应arXiv历史裁剪像素一致(MAE=0)。arXiv v1即为最早核实匹配版本。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[49, 70, 552, 237],PDF点、左上角原点。
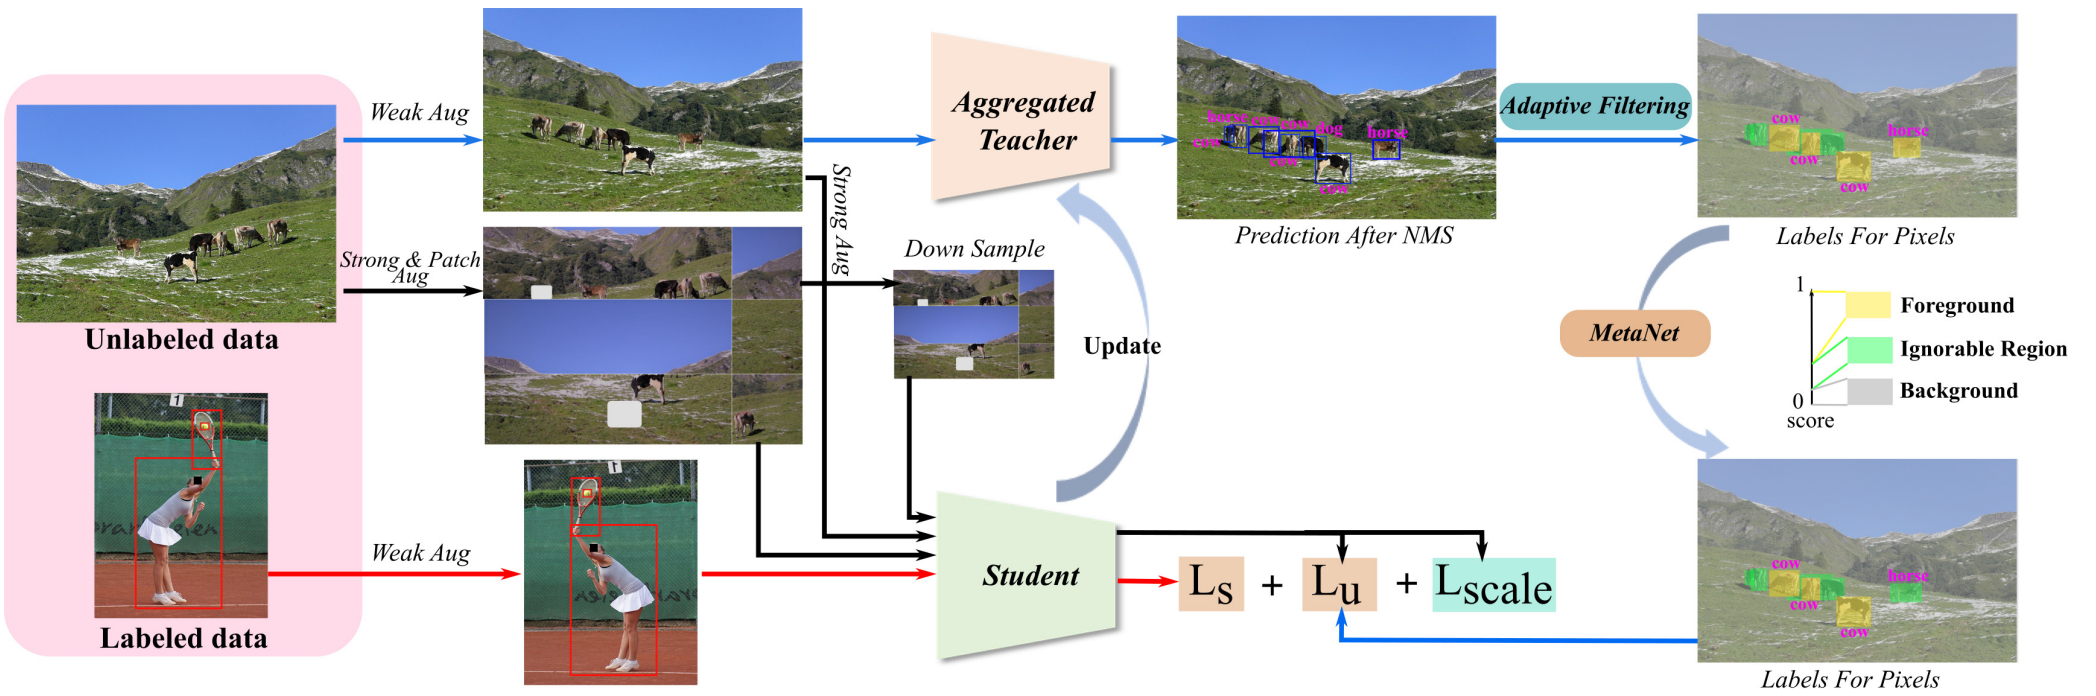
Figure 2. The pipeline of our proposed DenSe Learning (DSL) based SSOD method. The training data contain both labeled and unlabeled
images. During each training iteration, a teacher model is employed to produce pseudo-labels for weakly augmented unlabeled images.
In anchor-free based detectors like FCOS [44], each spatial location of the dense predictions will be assigned with one label, and the
model performance is sensitive to noisy pseudo-labels. To alleviate this problem, an Adaptive Filtering strategy is proposed to split the
pseudo-labels into three types, including background, foreground and ignorable regions. Moreover, there exist some false positive cases,
which have higher scores but are obviously wrong predictions. Thus, a MetaNet is proposed to refine these cases. To improve the model
generalization capability, unlabeled images are patch-shuffled and consistency regularizations are applied on these images with different
scales. For improving the stability and quality of pseudo-labels, the teacher model is updated by the student models via aggregation, called
Aggregated Teacher. After obtaining the fine-grained pixel-wise pseudo-labels, the detector can be optimized by the final loss, which is the
sum of L ,L and L .
s u scale
Dense Learning based Semi-Supervised Object Detection
会议:CVPR 2022 · 主会论文
Figure 3 · PDF第4页 · P95
300 dpi PNG · 图注 · 源PDF
第3.2节引用图3说明真实前景、错误前景与背景分数分布交叠,揭示单阈值伪标签的局限;并非方法性能排行。
完整图注、版本和筛选证据
最早核实视觉日期:2022-04-15;arXiv v1:2022-04-15;CVPR 2022 fixed official PDF
已阅读会议版图注及正文并逐张查看导出。会议图与对应arXiv历史裁剪像素一致(MAE=0)。arXiv v1即为最早核实匹配版本。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[84, 78, 239, 193],PDF点、左上角原点。
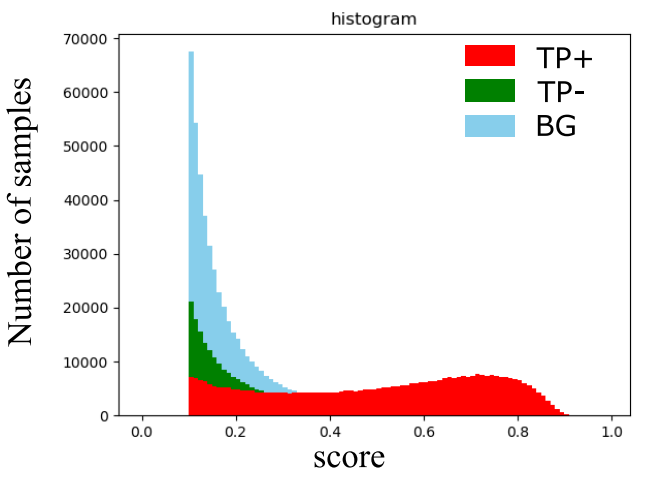
Figure 3. The distributions of TP+, TP- and BG when using 10%
labeled data on COCO. ‘TP+’ means that the estimated instance
has the same class ID as the ground-truth (GT) and the IOU of
BBox is above 0.5. ‘TP-’ means that the estimated instance has
the same class ID as GT but the IOU of BBox is below 0.5. ‘BG’
means that the estimated instance belongs to the background or
has wrong class ID.
Localization Distillation for Dense Object Detection
会议:CVPR 2022 · 主会论文
Figure 3 · PDF第3页 · P214
300 dpi PNG · 图注 · 源PDF
第3.2节引用图3展示所提LD训练的完整核心路径:教师/学生、定位头、概率分布、区域加权与蒸馏损失。图注说明仅画定位分支;本条按完整核心训练路径归F,不声称它展示基底检测器所有分支。
完整图注、版本和筛选证据
最早核实视觉日期:2021-11-25;arXiv v1:2021-02-24;CVPR 2022 fixed official PDF
已查看v1(2021-02-24)、v2(02-25)、v3(11-25)及v4(2022-03-31)。v1/v2为蓝橙简图,无区域加权;v3首次出现与会议版匹配的绿橙架构、定位头、区域权重及图例。采用v3日期,未将重绘图追溯到v1。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Ming-Ming Cheng;85763;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[49, 70, 548, 212],PDF点、左上角原点。
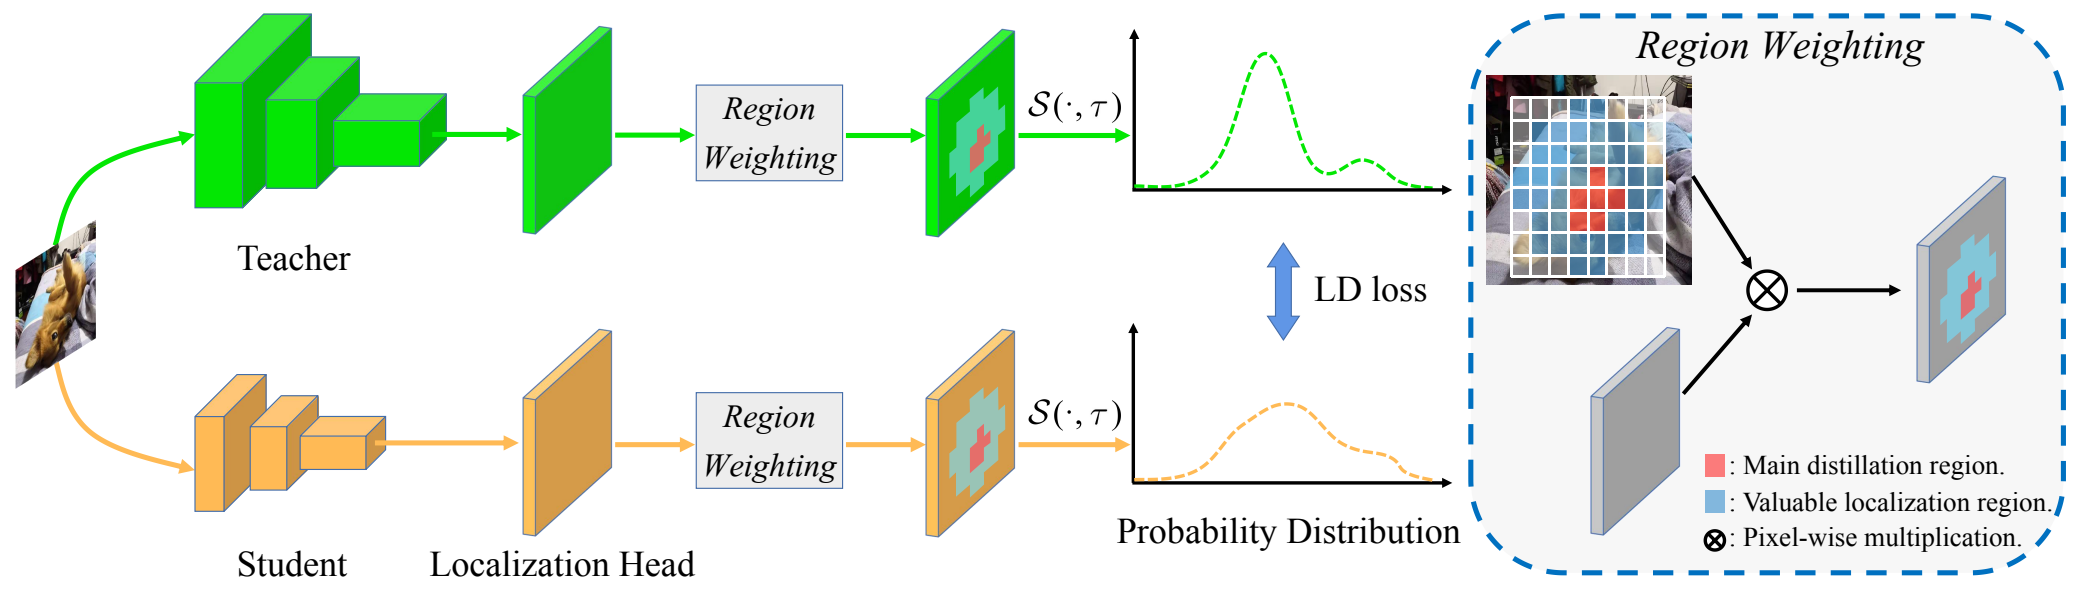
Figure 3. Illustration of localization distillation (LD) for an edge e ∈ B = {t, b, l, r}. Only the localization branch is visualized here.
S (·, τ ) is the generalized SoftMax function with temperature τ . For a given detector, we first switch the bounding box representation
to probability distribution. Then, we determine where to distill via region weighting on the main distillation region and the valuable
localization region. Finally, we calculate the LD loss between two probability distributions predicted by the teacher and the student.Localization Distillation for Dense Object Detection
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P213
300 dpi PNG · 图注 · 源PDF
引言与图1以大象底边和冲浪板右边的模糊边界说明定位歧义,属于问题示意。
完整图注、版本和筛选证据
最早核实视觉日期:2021-02-24;arXiv v1:2021-02-24;CVPR 2022 fixed official PDF
已对照arXiv v1:大象与冲浪板两图及红色虚线歧义标记一致,会议版仅等比调整显示尺寸与排版。图注文本抽取含PDF隐藏的(a)字符,依据可见图注转录并保留原始图注PDF。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Ming-Ming Cheng;85763;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[320, 226, 536, 321],PDF点、左上角原点。
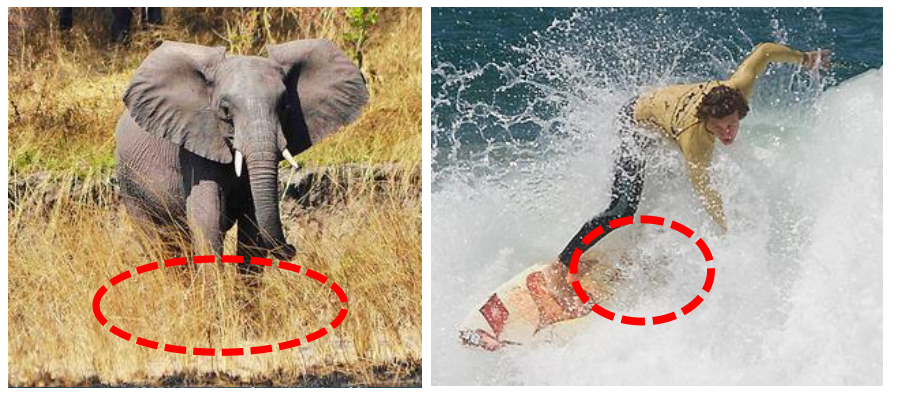
Figure 1. Bottom edge for “elephant” and right edge for “surfboard” are ambiguous.
Not All Labels Are Equal: Rationalizing The Labeling Costs for Training Object Detection
会议:CVPR 2022 · 主会论文
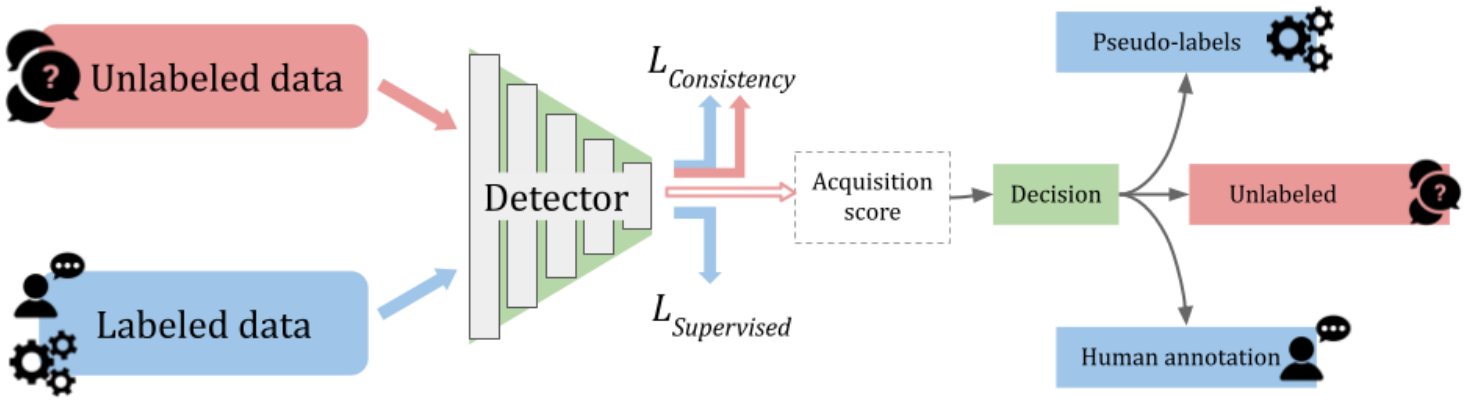
Figure 2 · PDF第3页 · P108
300 dpi PNG · 图注 · 源PDF
第3节与图2展示训练检测器、计算获取分数、选择人工标注或伪标注并进入下一训练循环的整体流程。
完整图注、版本和筛选证据
最早核实视觉日期:2021-11-29;arXiv v1:2021-06-22;CVPR 2022 fixed official PDF
已阅读固定版本图注和正文;与arXiv历史对应视觉比较,具体差异记入逐图核查记录。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Laura Leal-Taixé;26825;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[53, 75, 407, 172],PDF点、左上角原点。
Figure 2. Overview of our method.
Wefirsttrainthenetworkinasemi-
supervised manner. During active
learning, for each image, we use
the network to compute the acqui-
sition function and based on it de-
cide if we actively label the image,
if we pseudo-label it, or if we only
use it as part of the unlabeled data
for the next training cycle.
Not All Labels Are Equal: Rationalizing The Labeling Costs for Training Object Detection
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P107
300 dpi PNG · 图注 · 源PDF
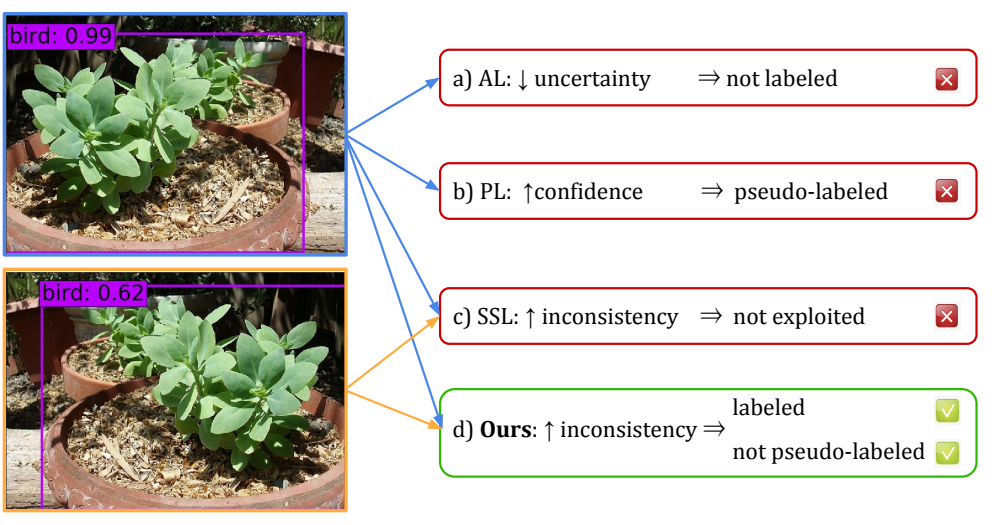
引言图1以盆栽误识别为鸟的案例解释低熵、高置信度和不一致性三种标注策略的失败机制。
完整图注、版本和筛选证据
最早核实视觉日期:2021-11-29;arXiv v1:2021-06-22;CVPR 2022 fixed official PDF
已阅读固定版本图注和正文;与arXiv历史对应视觉比较,具体差异记入逐图核查记录。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Laura Leal-Taixé;26825;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[309, 216, 547, 342],PDF点、左上角原点。
Figure 1. An object from a low-performing class (Pottedplant),
original image in blue, augmented version in orange. a) Because
of its low-entropy, uncertainty-based AL methods do not label the
image. b) Because of its high confidence, pseudo-label SSL meth-
ods wrongly pseudo-label the image and thus harm the training. c)
Because of its high-inconsistency, consistency-based SSL meth-
ods cannot learn from it. d) Our method selects the image for
labeling and prevents it from getting pseudo-labeled.
Progressive End-to-End Object Detection in Crowded Scenes
会议:CVPR 2022 · 主会论文
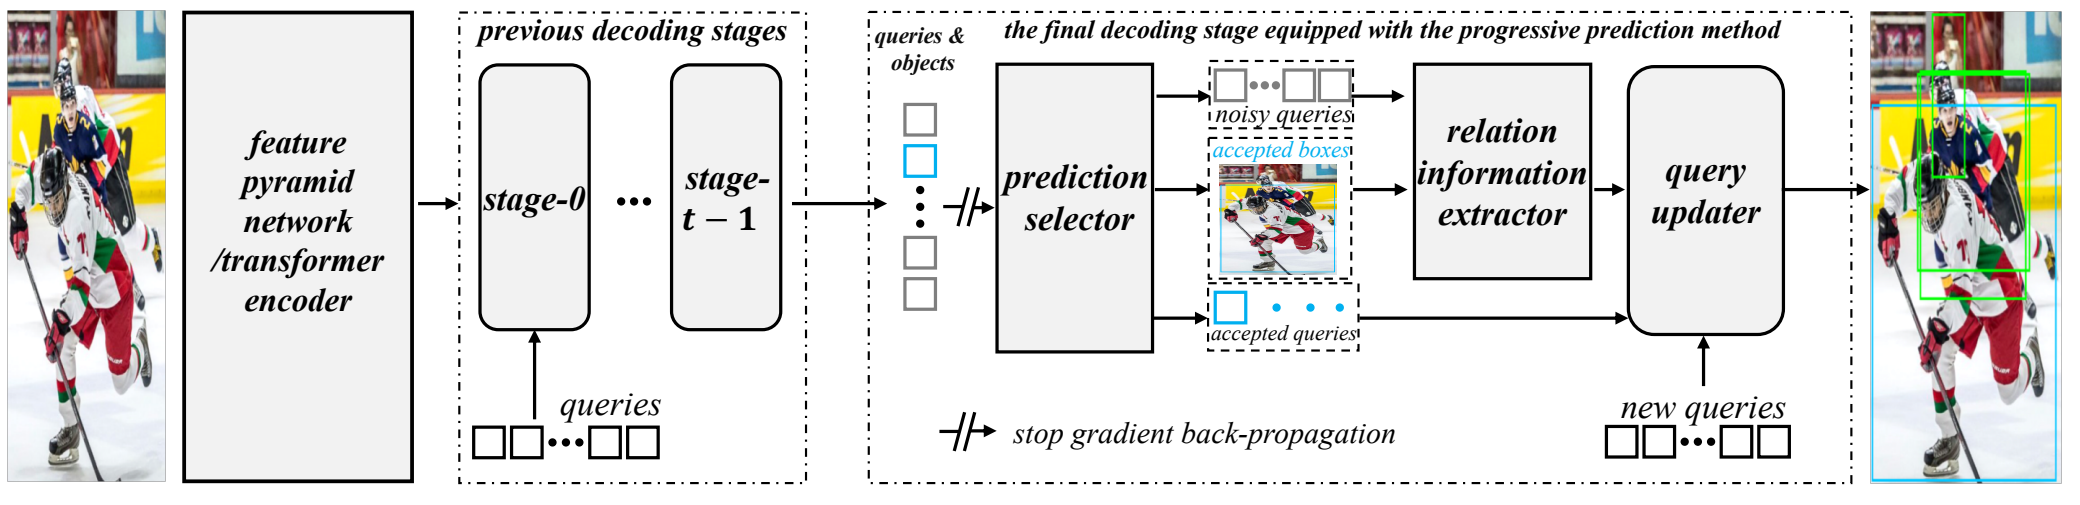
Figure 3 · PDF第4页 · P140
300 dpi PNG · 图注 · 源PDF
图3展示从图像、特征、解码阶段到预测选择、关系提取、查询更新及最终检测的整体流程。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-15;arXiv v1:2022-03-15;CVPR 2022 fixed official PDF
已比较固定会议PDF与arXiv v1的完整图形;目标视觉版本匹配。页面排版平移已在historical_crop_bbox中记录;非图形重绘。实际创作日期未知。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Xiangyu Zhang;481440;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[49, 70, 548, 191],PDF点、左上角原点。
Figure 3: The diagram of the proposed progressive end-to-end object detection framework. First, the prediction selector
select queries associated with high confidence scores as accepted queries, leaving the rest as noisy queries. Then Relation
information extractor models the relations between noisy queries and their neighbors from accepted predictions. Next, the
queries are fed into the queries updater to be further refined by performing a new local self-attention.
Progressive End-to-End Object Detection in Crowded Scenes
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P139
300 dpi PNG · 图注 · 源PDF
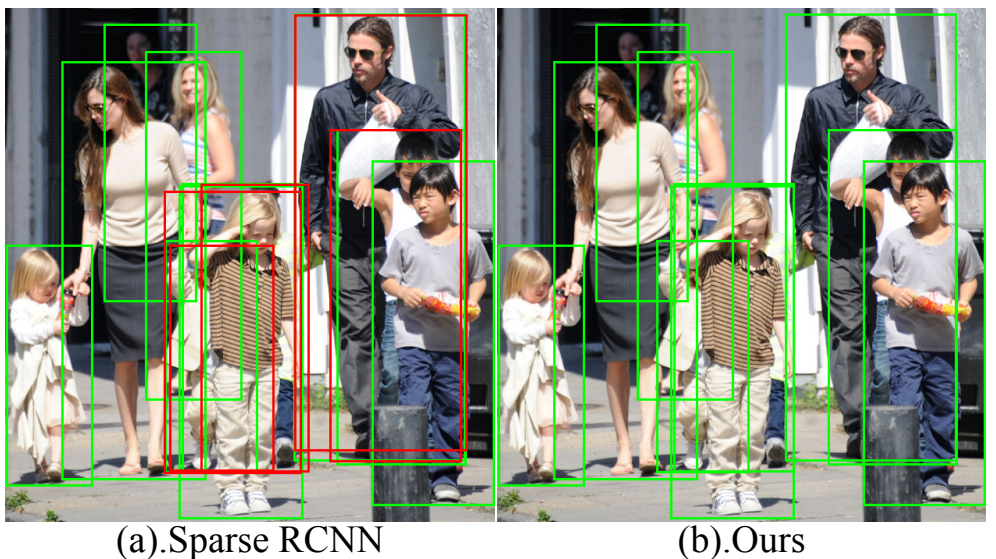
引言图1用红色重复框指出Sparse R-CNN在拥挤场景中的假阳性,并对比修正结果以引出重复预测问题。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-15;arXiv v1:2022-03-15;CVPR 2022 fixed official PDF
已比较固定会议PDF与arXiv v1的完整图形;目标视觉版本匹配。页面排版平移已在historical_crop_bbox中记录;非图形重绘。实际创作日期未知。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Xiangyu Zhang;481440;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[308, 219, 547, 353],PDF点、左上角原点。
Figure 1: 1a. Sparse RCNN [37] introduces false positives
in crowded scenes. 1b. Our approach can remove those
false positives and ensure each object can be detected only
once. Green boxes indicate true positives while red ones
represent false positives.
SIOD: Single Instance Annotated Per Category Per Image for Object Detection
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第3页 · P94
300 dpi PNG · 图注 · 源PDF
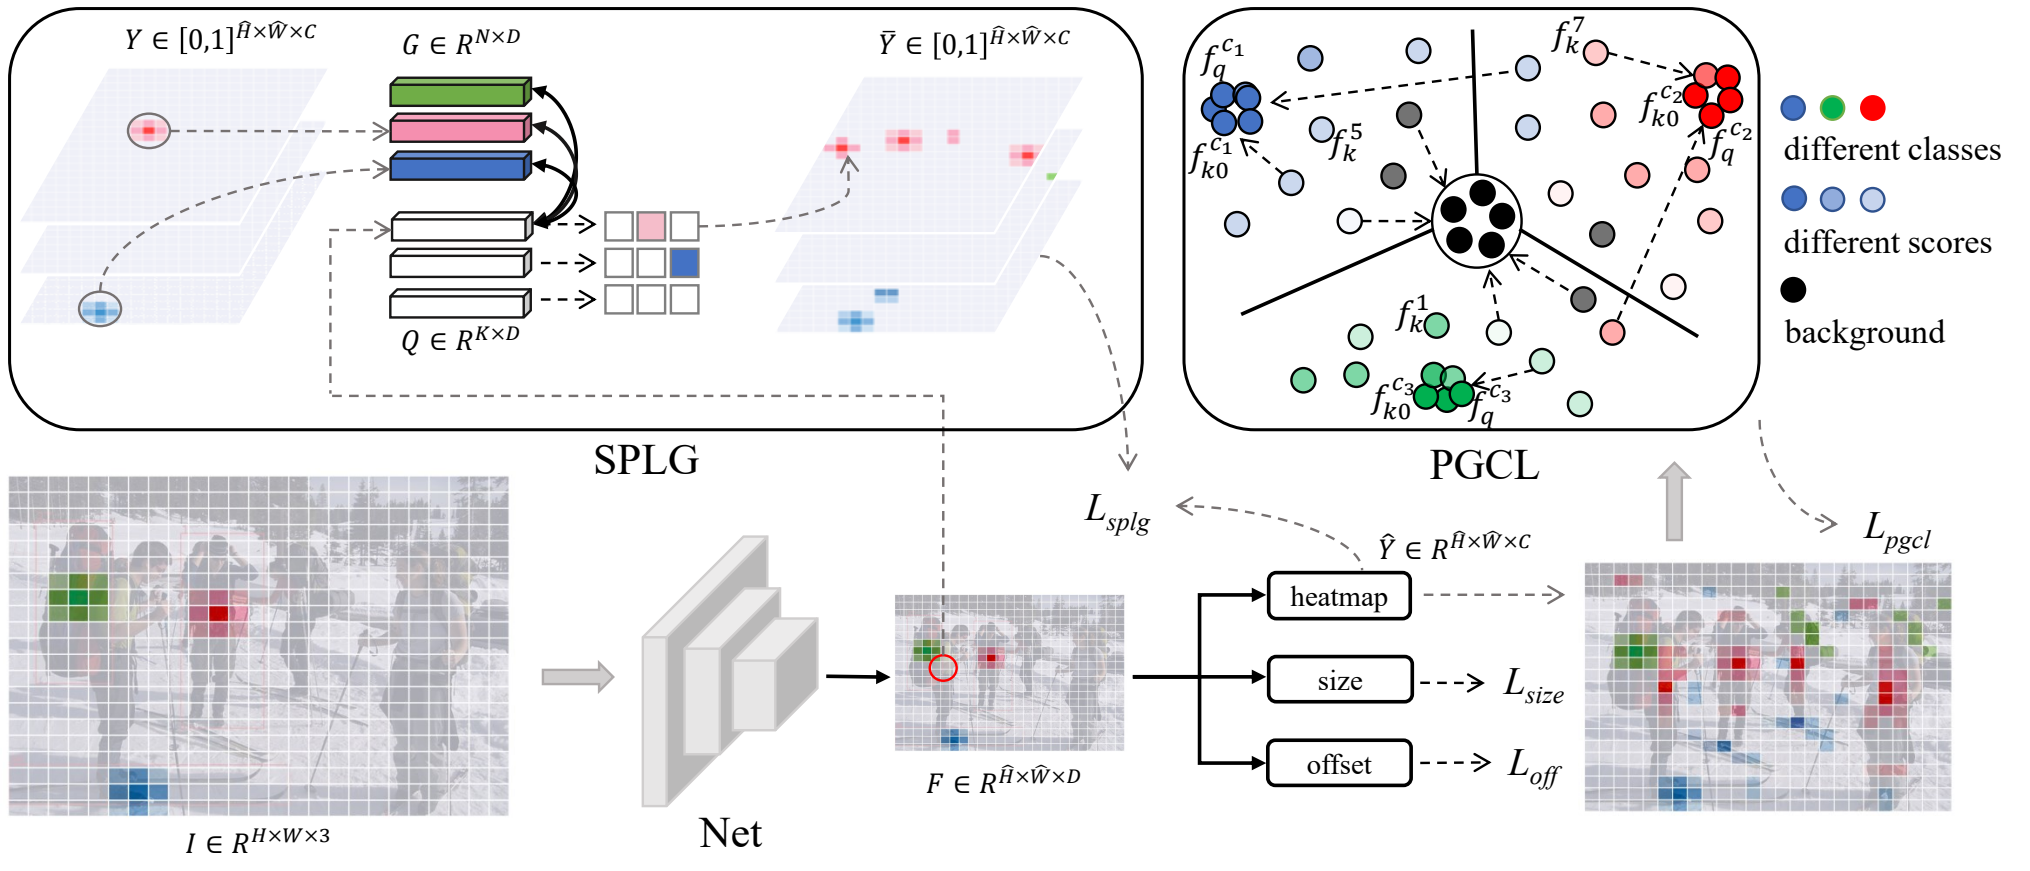
第3.1节及图2明确称DMiner整体框架,包含图像、主干、预测头、伪标注和对比学习的训练路径。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-30;arXiv v1:2022-03-29;CVPR 2022 fixed official PDF
已阅读会议版图注及正文并逐张查看导出。会议图与对应arXiv历史裁剪像素一致(MAE=0)。v1有符号或细节差异,v2(2022-03-30)首次核实逐像素一致,未套用v1日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Wei-Shi Zheng;31913;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 73, 545, 282],PDF点、左上角原点。
Figure 2. The overview of proposed DMiner, which consists of a Similarity-based Pseudo Label Generating module (SPLG) and a Pixel-
level Group Contrastive Learning module (PGCL). Let M ,M ,M =1 and refer to Eq. (6) to understand the meaning of M.
15 27 31
SIOD: Single Instance Annotated Per Category Per Image for Object Detection
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P93
300 dpi PNG · 图注 · 源PDF
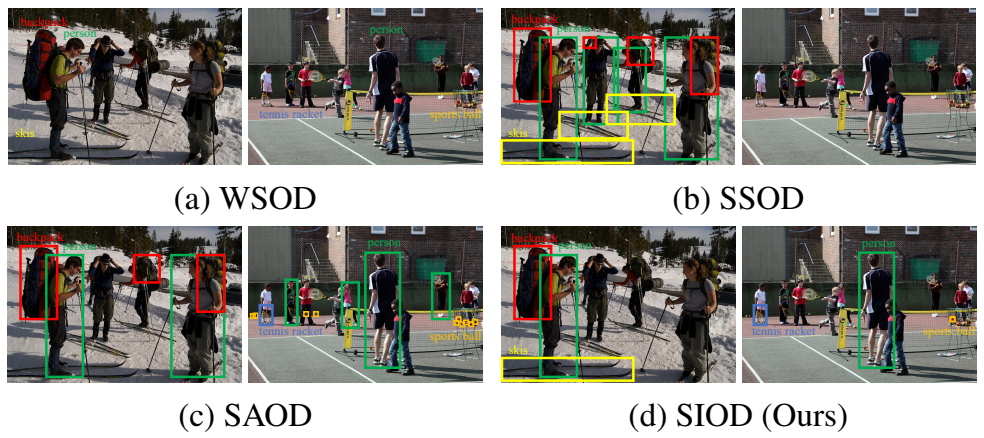
引言与图1对比四种标注设定,展示WSOD、SSOD、SAOD和SIOD的信息差别,属于问题设定概念对比。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-30;arXiv v1:2022-03-29;CVPR 2022 fixed official PDF
已阅读会议版图注及正文并逐张查看导出。会议图与对应arXiv历史裁剪像素一致(MAE=0)。v1有符号或细节差异,v2(2022-03-30)首次核实逐像素一致,未套用v1日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Wei-Shi Zheng;31913;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[309, 240, 545, 345],PDF点、左上角原点。
Figure 1. Different annotation setup for (a) WSOD, (b) SSOD, (c)
SAOD and (d) SIOD (Ours).
Scale-Equivalent Distillation for Semi-Supervised Object Detection
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P98
300 dpi PNG · 图注 · 源PDF
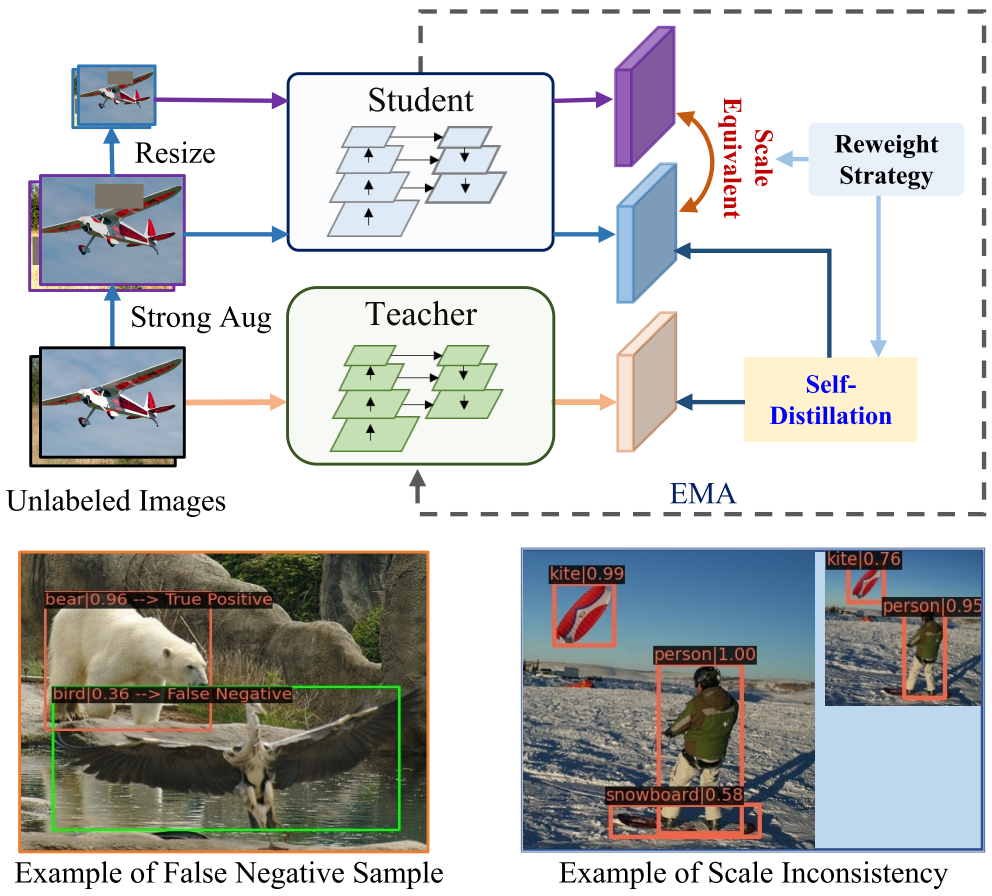
图注明确称SED整体框架,包含教师学生、尺度一致性、自蒸馏、重加权和EMA;保留图内用于解释流程的失败示例。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-23;arXiv v1:2022-03-23;CVPR 2022 fixed official PDF
已阅读会议版图注及正文并逐张查看导出。会议图与对应arXiv历史裁剪像素一致(MAE=0)。arXiv v1即为最早核实匹配版本。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yizhou Yu;35607;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[309, 213, 547, 428],PDF点、左上角原点。
Figure 1. The overall framework of SED. Our model improves the
scale equivalence, which is critical for object detectors, by regu-
larizing the consistency between different-sized images. Further-
more, the inherent False Negative sample noise is alleviated by
self-distillation. A re-weighting strategy is adopted to solve the
severe class imbalance problem. The bird in the left example is a
False Negative sample when the threshold is set to 0.7. The right
example shows the scale inconsistency of different-sized images.
Scale-Equivalent Distillation for Semi-Supervised Object Detection
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第3页 · P97
300 dpi PNG · 图注 · 源PDF
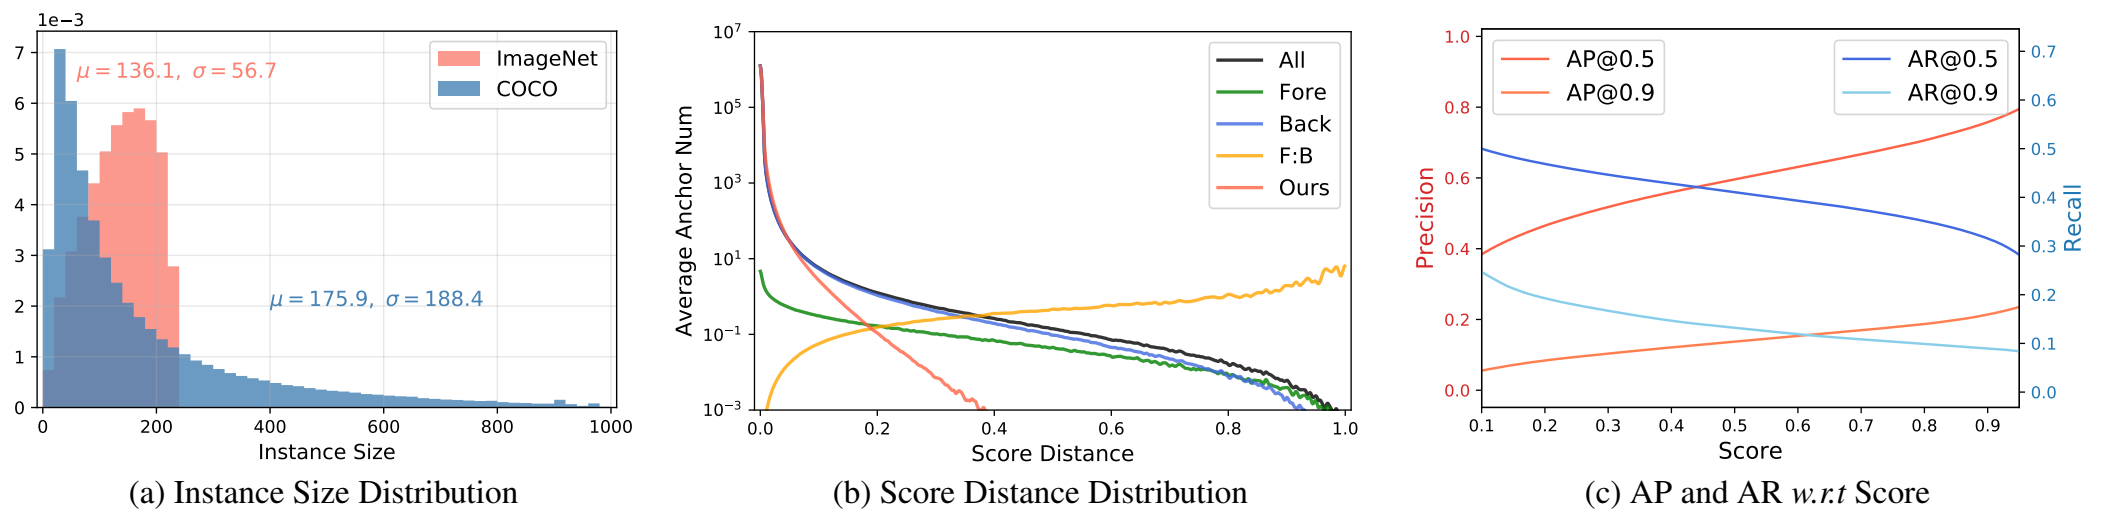
引言和图2用目标尺度、分数差异及硬伪标签精度召回诊断规模变化与假阴性问题;完整三面板主要论证已有训练假设的局限。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-23;arXiv v1:2022-03-23;CVPR 2022 fixed official PDF
已阅读会议版图注及正文并逐张查看导出。会议图与对应arXiv历史裁剪像素一致(MAE=0)。arXiv v1即为最早核实匹配版本。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yizhou Yu;35607;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[48, 49, 553, 174],PDF点、左上角原点。
Figure 2. (a) For the COCO dataset, all the images are resized such that the short edge has 800 pixels while the long edge has less than
1333 pixels. For the ImageNet dataset, all the images are resized to 224×224 to calculate the statistics. The scale of object is represented
as the square root of the area. We discuss the typical training input size for ImageNet classification and COCO detection tasks. (b) All the
scores are predicted on COCO minival dataset by the RetinaNet detector with FPN and ResNet 50 backbone, which is trained with 10%
COCO data. The score distance is the absolute difference between the predictions of the image in different sizes. The Y-axis is the average
numberofanchorsperimage. (c)Wepredictpseudo-labelontherestofCOCOtrainingdatawithaconvergedFaster-RCNNdetector(with
FPNandResNet50backbone), trainedwith10%COCOdata. Thelowaveragerecallandprecisionshowthathardpseudo-labelincurmore
noise with False Negative samples.
Task-specific Inconsistency Alignment for Domain Adaptive Object Detection
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第3页 · P160
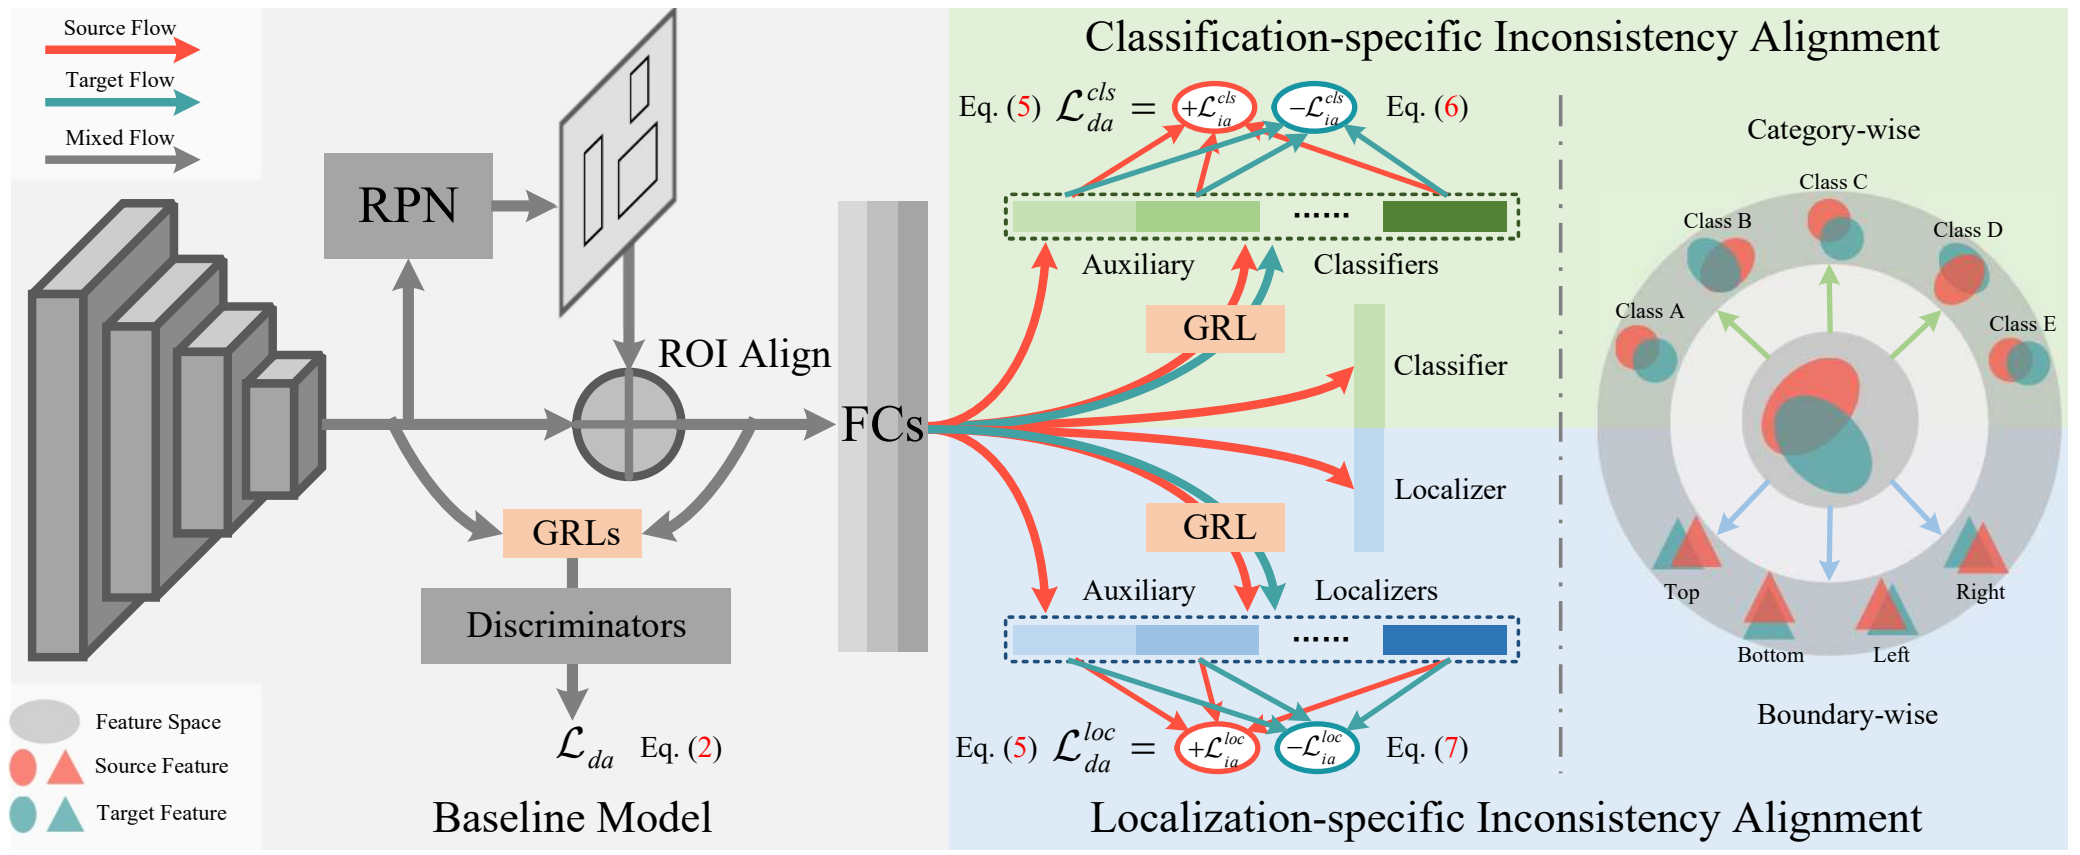
300 dpi PNG · 图注 · 源PDF
图2及第3节明确为overall architecture,完整显示骨干、RPN、RoIAlign与分类/定位两条不一致性对齐分支。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-29;arXiv v1:2022-03-29;CVPR 2022 fixed official PDF
已查看会议固定版与arXiv v1,目标图的构图、元素、连线、文字与颜色一致;存在排版平移或PDF渲染/压缩级别差异,无重绘证据。最早核实公开时间采用v1。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Limin Wang;57767;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[49, 70, 548, 275],PDF点、左上角原点。
Figure 2. Framework overview. Best viewed in color. We develop the high-level feature alignment into separate task spaces, by applying
the proposed Task-specific Inconsistency Alignment module to both the classification (green part) and localization (blue part) branches
of the baseline detector (gray part). In each branch, the behavioral inconsistency of multiple auxiliary predictors is optimized via the
corresponding inconsistency-aware loss, for essentially bridging the category-wise or boundary-wise margins between domains.
Task-specific Inconsistency Alignment for Domain Adaptive Object Detection
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P159
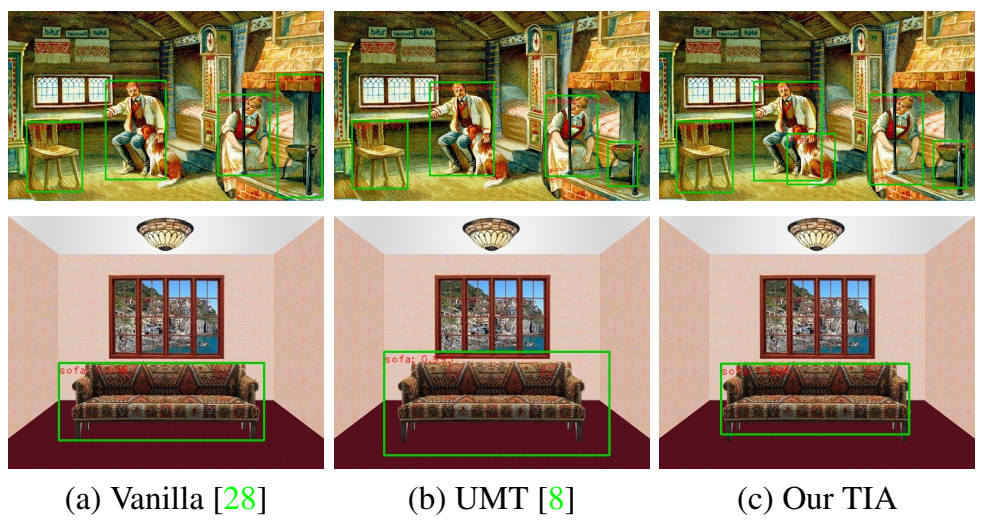
300 dpi PNG · 图注 · 源PDF
第1页引言明确引用图1说明UMT虽减少漏检却降低框定位质量,引出分类与定位迁移冲突;是具体失败诊断。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-29;arXiv v1:2022-03-29;CVPR 2022 fixed official PDF
已查看会议固定版与arXiv v1,目标图的构图、元素、连线、文字与颜色一致;存在排版平移或PDF渲染/压缩级别差异,无重绘证据。最早核实公开时间采用v1。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Limin Wang;57767;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[309, 211, 546, 337],PDF点、左上角原点。
Figure 1. Exampled images from PASCAL VOC [10] → Cli-
part [18]. Compared with vanilla detector [28], both UMT [8] and
TIA identify more foreground objects (Row 1), yet deliver lower
as well as higher quality bounding boxes (Row 2), respectively.
Towards Robust Adaptive Object Detection under Noisy Annotations
会议:CVPR 2022 · 主会论文
Figure 3 · PDF第4页 · P142
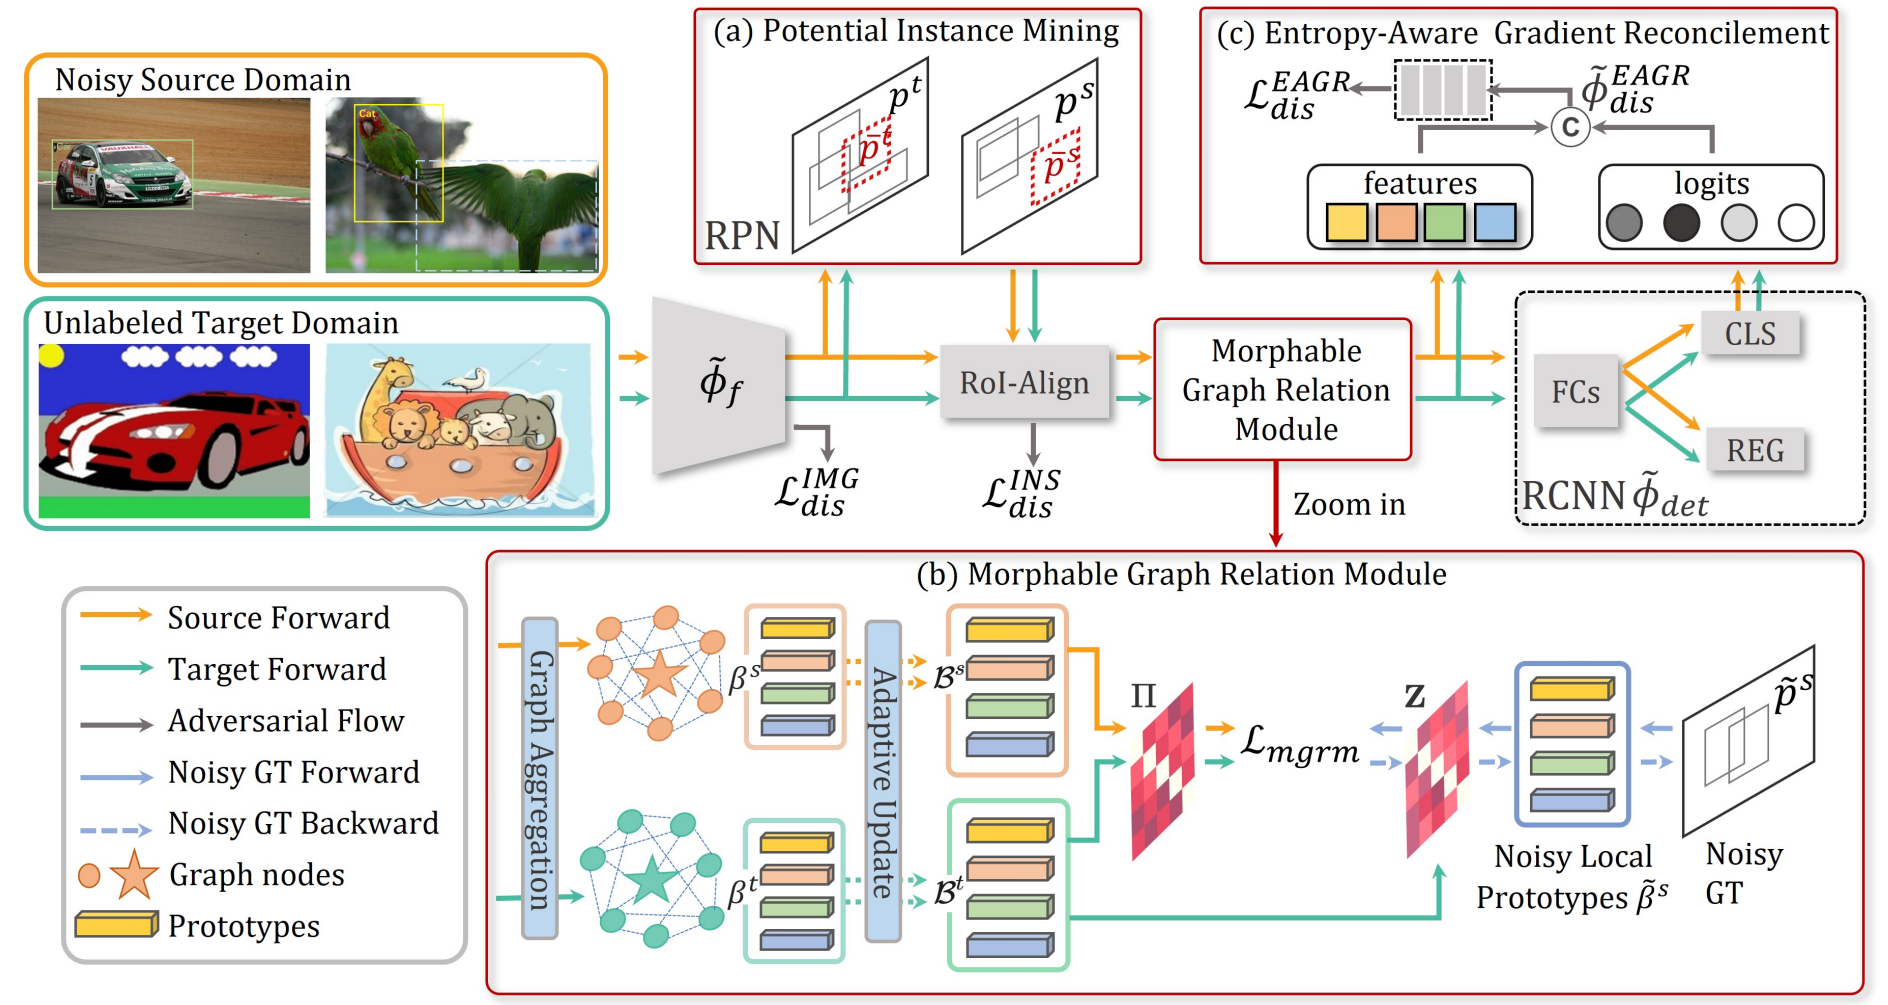
300 dpi PNG · 图注 · 源PDF
图3明确为NLTE整体框架,展示源域和目标域输入、PIM、MGRM、EAGR、检测器及多种损失的关系。
完整图注、版本和筛选证据
最早核实视觉日期:2022-04-06;arXiv v1:2022-04-06;CVPR 2022 fixed official PDF
已比较固定会议PDF与arXiv v1的完整图形;目标视觉版本匹配。页面排版平移已在historical_crop_bbox中记录;非图形重绘。实际创作日期未知。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yixuan Yuan;16227;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[68, 72, 521, 313],PDF点、左上角原点。
Figure 3. Overview of our NLTE framework, which includes PIM, MGRM and EAGR. ⃝c is the concatenation operation.
Towards Robust Adaptive Object Detection under Noisy Annotations
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P141
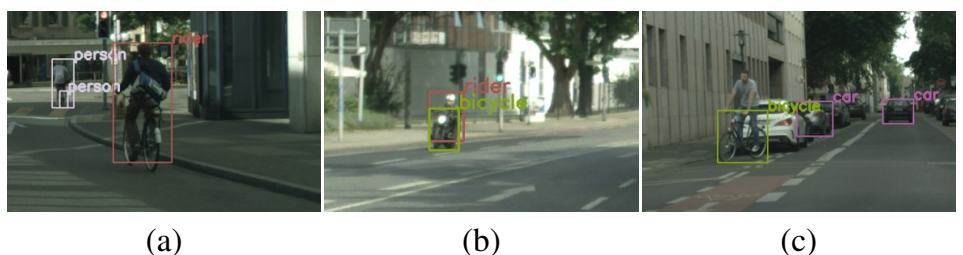
300 dpi PNG · 图注 · 源PDF
引言图1列举Cityscapes漏标及错类别的实际输入标注问题,是噪声设定的动机示例而非性能结果。
完整图注、版本和筛选证据
最早核实视觉日期:2022-06;arXiv v1:2022-04-06;CVPR 2022 fixed official PDF
v1与会议版三幅示例内容一致,但子图宽度与间距被调整。已查看全部arXiv历史版本;最早核实包含目标视觉版本的文献为CVF固定会议PDF,官方书目明确出版月June 2022。该月全在S1。月内首次公开日未知,不把会议版新画面追溯为v1日期。历史对照图保留差异,不声称像素相同。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yixuan Yuan;16227;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[313, 225, 544, 286],PDF点、左上角原点。
Figure 1. Examples of noisy annotations in Cityscapes dataset.
Miss-annotated samples: The bicycle in (a); the rider and car in
(c). Class-corrupted samples: The rider and bicycle are labeled
as person in (a); the motorcycle is labeled as bicycle in (b).
Class-Balanced Pixel-Level Self-Labeling for Domain Adaptive Semantic Segmentation
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第3页 · P100
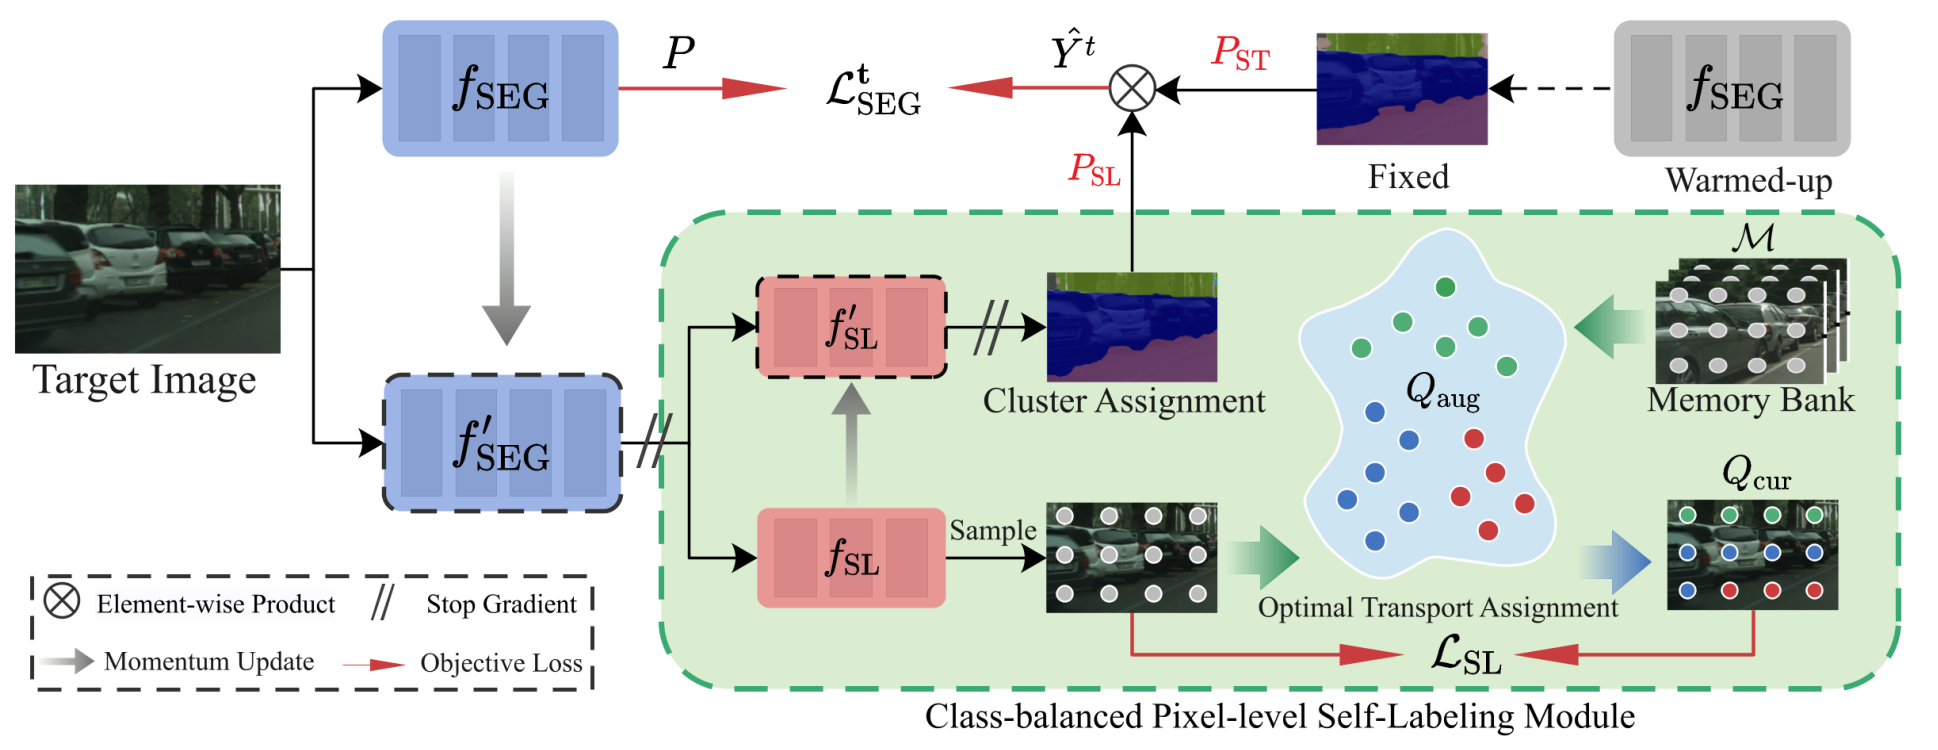
300 dpi PNG · 图注 · 源PDF
第3.1节及图1明确展示CPSL总体架构,包含主分割网络、动量分支、自标注、记忆库及优化目标。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-18;arXiv v1:2022-03-18;CVPR 2022 fixed official PDF
已阅读会议版图注及正文并逐张查看导出。会议图与对应arXiv历史裁剪像素一致(MAE=0)。arXiv v1即为最早核实匹配版本。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[68, 69, 533, 249],PDF点、左上角原点。
Figure 1. The framework of Class-balanced Pixel-level Self-Labeling (CPSL). The model contains a main segmentation network f and
SEG
its momentum-updated version f′ . The f′ is followed by a self-labeling head f and its momentum version f′ , which projects
SEG SEG SL SL
pixel-wise feature embedding into a class probability vector. The pixel-level self-labeling module produces soft cluster assignment P to
SL
gradually rectify soft pseudo label P . Then the segmentation loss Lt is computed between the prediction map P and the rectified
ST SEG
pseudo label Yˆt. To train the self-labeling head, we randomly sample pixels from each image, and use the memory bank M, which
contains previous batches of pixel features, to augment the current batch. Then we compute the optimal transport assignment Q over
aug
the augmented data by enforcing class balance, and use the assignment of current batch Q to compute the self-labeling loss L .
cur SL
Class-Balanced Pixel-Level Self-Labeling for Domain Adaptive Semantic Segmentation
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第4页 · P99
300 dpi PNG · 图注 · 源PDF
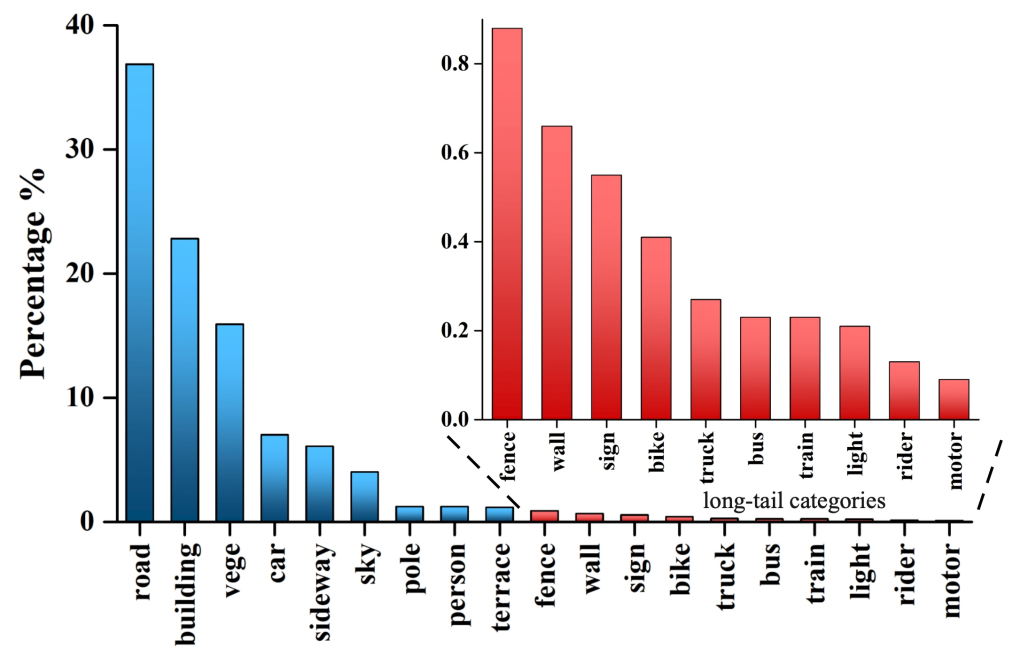
第2页以图2解释Cityscapes类别长尾不均衡,引出分布对齐设计;该柱状图显示数据分布而非模型性能。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-18;arXiv v1:2022-03-18;CVPR 2022 fixed official PDF
已阅读会议版图注及正文并逐张查看导出。会议图与对应arXiv历史裁剪像素一致(MAE=0)。arXiv v1即为最早核实匹配版本。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[48, 70, 290, 226],PDF点、左上角原点。
Figure 2. The class distribution of the Cityscapes dataset.
Decoupling Zero-Shot Semantic Segmentation
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第4页 · P126
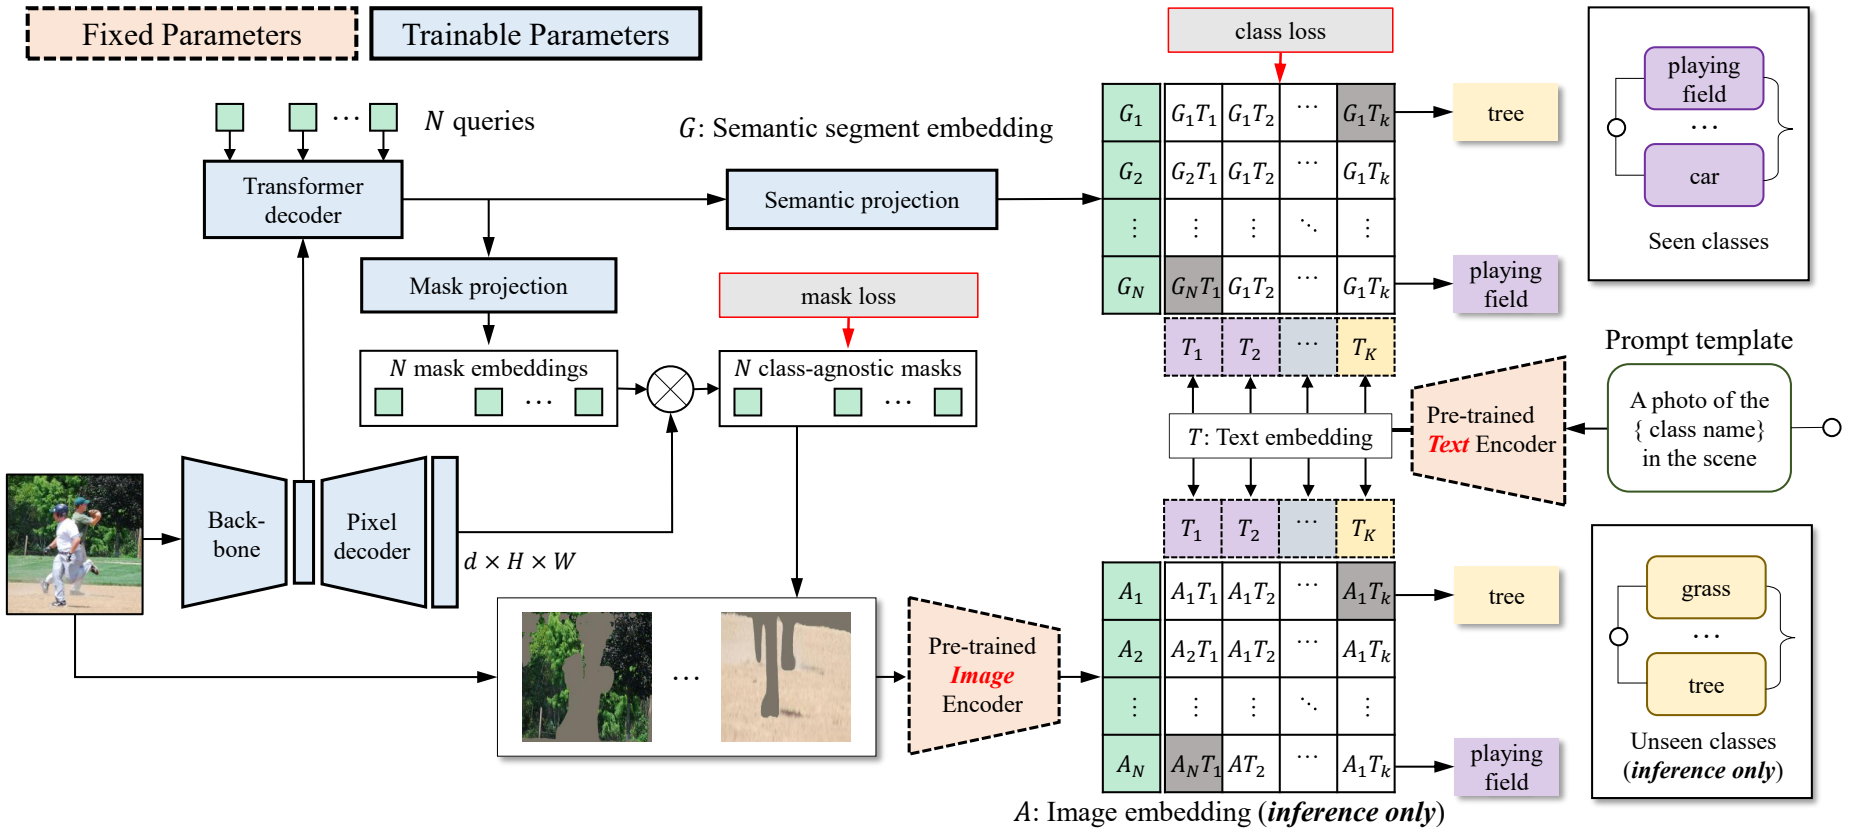
300 dpi PNG · 图注 · 源PDF
正文图2明确为完整ZegFormer流程,包含查询、图像与文本编码、掩码与语义投影以及训练和推理路径。
完整图注、版本和筛选证据
最早核实视觉日期:2022-04-15;arXiv v1:2021-12-15;CVPR 2022 fixed official PDF
已核查v1第5页图2:seen/unseen类别框、子图背景和矩阵着色不同。v2第4页匹配会议版,逐像素一致。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Dengxin Dai;23615;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[75, 65, 519, 264],PDF点、左上角原点。
Figure 2. The pipeline of our proposed ZegFormer for zero-shot semantic segmentation. We first feed N queries and feature maps to a
transformer decoder to generate N segment embeddings. We then feed each segment embedding to a mask projection layer and a semantic
projection layer to obtain a mask embedding and a semantic embedding. Mask embedding is multiplied with the output of pixel decoder
to generate a class-agnostic binary mask, while The semantic embedding is classified by the text embeddings. The text embeddings are
generated by putting the class names into a prompt template and then feeding them to a text encoder of a vision-language model. During
training, only the seen classes are used to train the segment-level classification head. During inference, both the text embeddings of seen
and unseen classes are used for segment-level classification. We can obtain two segment-level classification scores with semantic segment
embeddings and image embeddings. Finally, we fuse the these two classification scores as our final class prediction of segments.
Decoupling Zero-Shot Semantic Segmentation
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P125
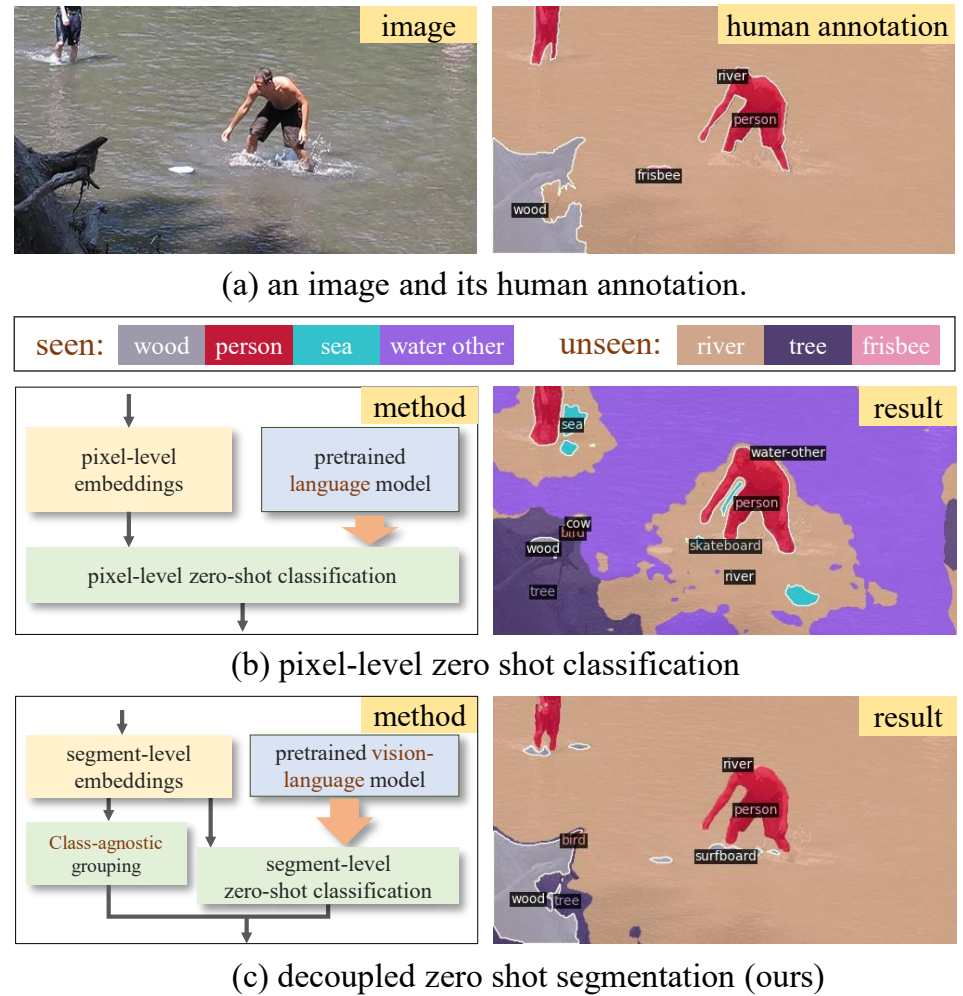
300 dpi PNG · 图注 · 源PDF
引言与图1对比像素级和片段级零样本分类,图中同时展示像素方法失败与分组解耦思路;用于引出建模限制。
完整图注、版本和筛选证据
最早核实视觉日期:2022-04-15;arXiv v1:2021-12-15;CVPR 2022 fixed official PDF
已核查v1:seen/unseen及language等文字使用粗斜体;v2改为会议版的正体。v2与会议图逐像素一致,不套用v1日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Dengxin Dai;23615;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[310, 208, 541, 447],PDF点、左上角原点。
Figure 1. ZS3 aims to train a model merely on seen classes and
generalize it to classes that have not been seen in the training (un-
seen classes). Existing methods formulate it as a pixel-level zero-
shot classification problem (b), and use semantic features from a
language model to transfer the knowledge from seen classes to
unseen ones. In contrast, as in (c), we decouple ZS3 into two
sub-tasks: 1) A class-agnostic grouping and 2) A segment-level
zero-shot classification, which enables us to take full advantage of
the pre-trained vision-language model.
Learning Affinity from Attention: End-to-End Weakly-Supervised Semantic Segmentation with Transformers
会议:CVPR 2022 · 主会论文
Figure 3 · PDF第3页 · P136
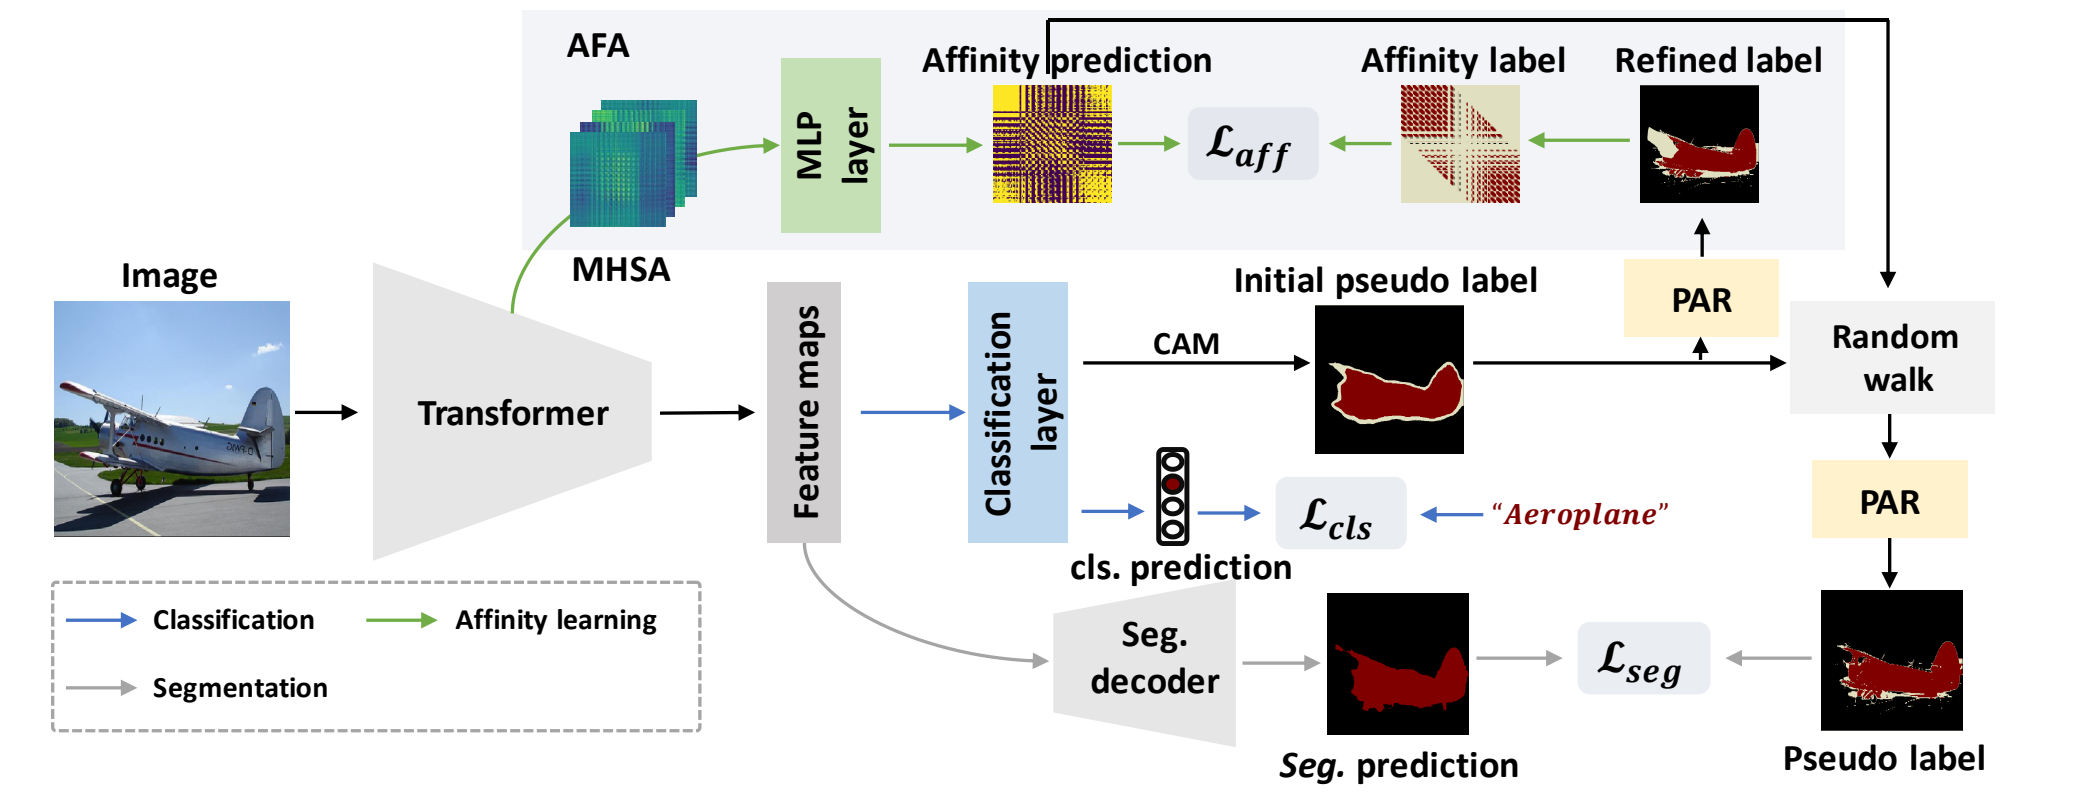
300 dpi PNG · 图注 · 源PDF
图3明确为端到端WSSS整体框架,包含编码、CAM、AFA、随机游走、PAR和分割监督路径。
完整图注、版本和筛选证据
最早核实视觉日期:2022-06;arXiv v1:2022-03-05;CVPR 2022 fixed official PDF
v1及v2为Initial pseudo,会议版补为Initial pseudo label。已查看全部arXiv历史版本;最早核实包含目标视觉版本的文献为CVF固定会议PDF,官方书目明确出版月June 2022。该月全在S1。月内首次公开日未知,不把会议版新画面追溯为v1日期。历史对照图保留差异,不声称像素相同。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Bo Du;50901;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[49, 70, 548, 261],PDF点、左上角原点。
Figure 3. The proposed end-to-end framework for WSSS. We use a Transformer backbone as the encoder to extract feature maps. The
initial pseudo labels are generated with CAM [59] and then refined with the proposed PAR. In the AFA module, we derive the semantic
affinity from MHSA in Transformer blocks. AFA is supervised with the pseudo affinity labels derived from the refined label. Next, we
employ the learned affinity to revise the pseudo labels via random walk propagation [2, 1]. The propagated labels are finally refined with
PAR as the pseudo labels for the segmentation branch.
Learning Affinity from Attention: End-to-End Weakly-Supervised Semantic Segmentation with Transformers
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P135
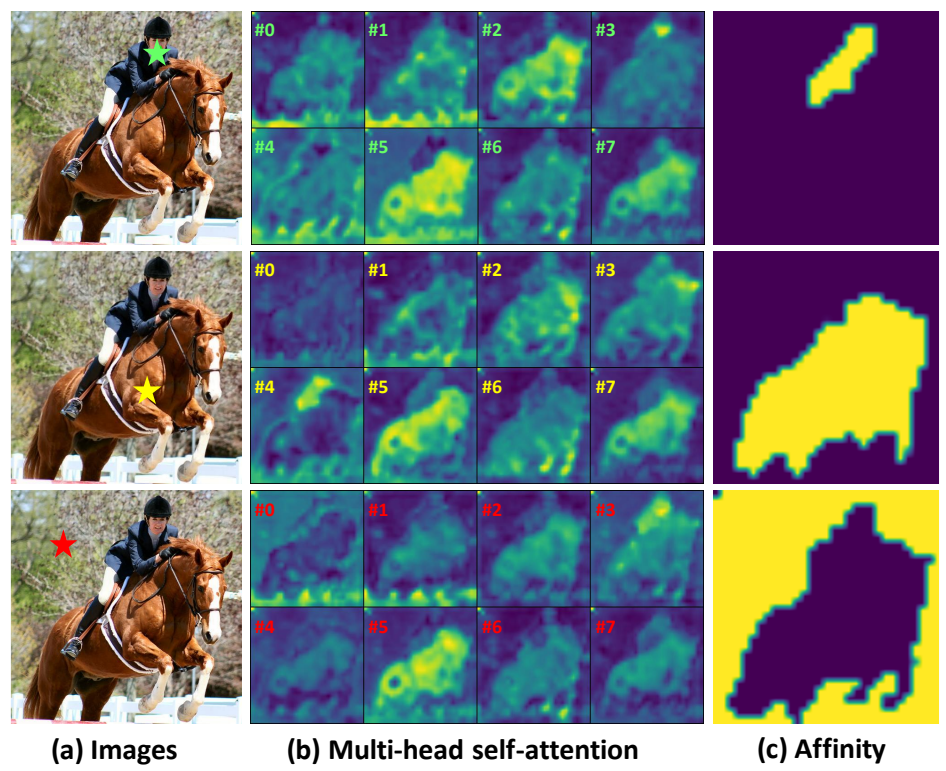
300 dpi PNG · 图注 · 源PDF
引言用图1指出多头自注意力只能形成粗糙语义亲和,导致不完整目标区域;这是引出亲和学习的问题诊断图。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-05;arXiv v1:2022-03-05;CVPR 2022 fixed official PDF
已比较固定会议PDF与arXiv v1的完整图形;目标视觉版本匹配。页面排版平移已在historical_crop_bbox中记录;非图形重绘。实际创作日期未知。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Bo Du;50901;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[313, 271, 540, 456],PDF点、左上角原点。
Figure 1. (a) Image and the query points (denote with ”⋆”) to vi-
sualize the attention and affinity maps; (b) the self-attention maps
in Transformer blocks only capture coarse semantic-level affin-
ity relations; (c) the learned reliable semantic affinity from self-
attention with our proposed method.
Multi-Class Token Transformer for Weakly Supervised Semantic Segmentation
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第3页 · P48
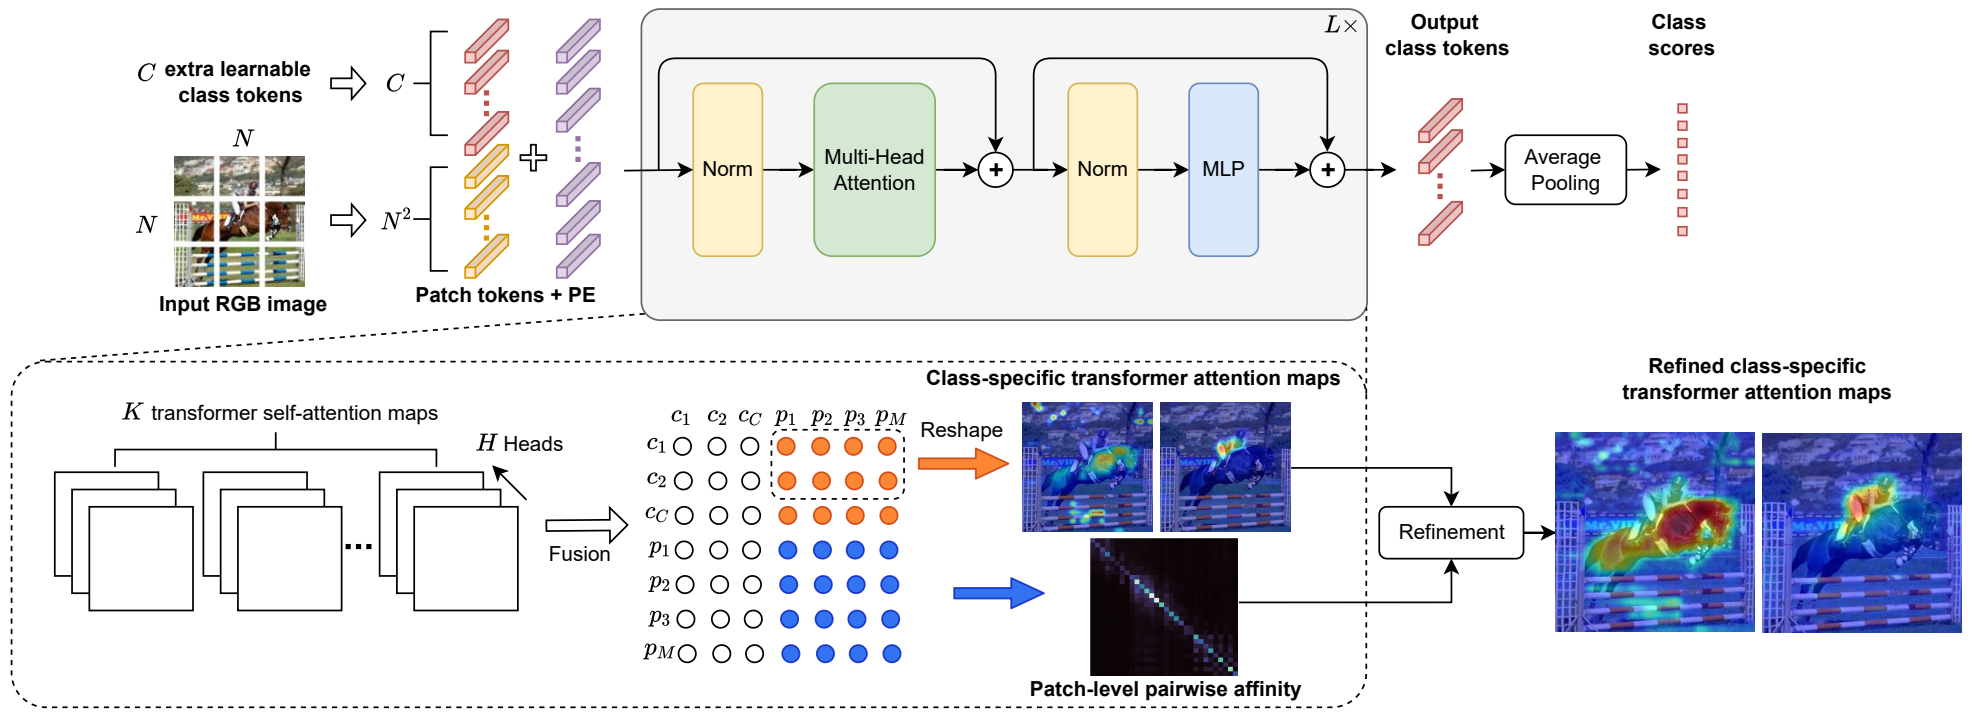
300 dpi PNG · 图注 · 源PDF
第3.1节Overview明确称图2为MCTformer-V1整体架构;包含输入token化、多层编码、分类及注意力细化完整路径。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-06;arXiv v1:2022-03-06;CVPR 2022 fixed official PDF
已逐页查看会议版与arXiv v1;图区设计一致,保留移动/缩放及PDF压缩差异,不声称像素完全一致。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Wanli Ouyang;81844;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[60, 71, 534, 242],PDF点、左上角原点。
Figure 2. An overview of the proposed multi-class token transformer (MCTformer-V1). It first splits and transforms an input RGB image
into a sequence of patch tokens. We propose to learn C extra class tokens, where C is the number of classes. The C class tokens are
concatenated with patch tokens, with added position embeddings (PE), which then go through consecutive L transformer encoding layers.
Finally, the output C class tokens are used to produce class scores via average pooling. We aggregate the transformer attentions from the
last K layers and multiple heads to generate a final attention map, from which we can extract class-specific object localization maps and a
patch-level pairwise affinity map from the class-to-patch and the patch-to-patch attentions, respectively. The patch-level pairwise affinity
can be used to refine the class-specific transformer attention maps to produce improved object localization maps.
Multi-Class Token Transformer for Weakly Supervised Semantic Segmentation
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P47
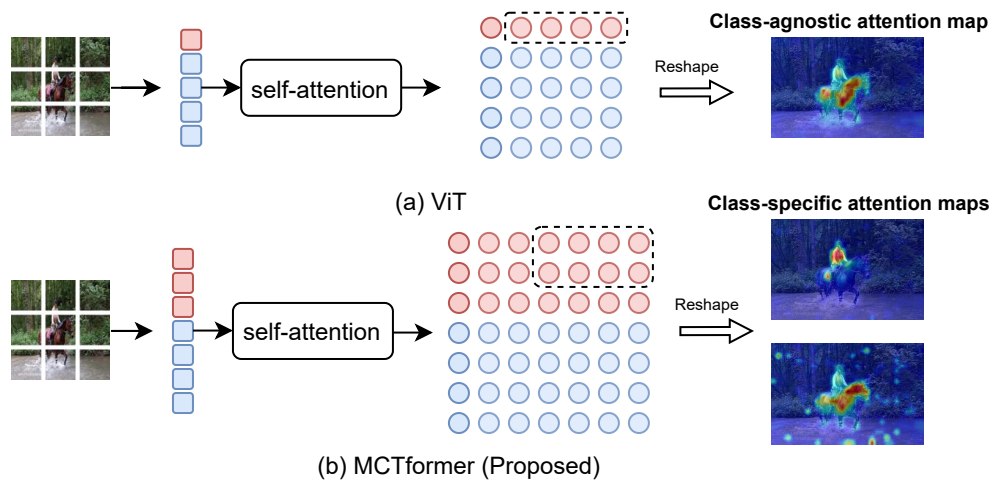
300 dpi PNG · 图注 · 源PDF
引言第2页引用图1解释单一class token的类无关注意力及定位歧义;整图对比单token和多token概念,是引出问题的范式对比。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-06;arXiv v1:2022-03-06;CVPR 2022 fixed official PDF
已逐页查看会议版与arXiv v1;图区设计一致,保留移动/缩放及PDF压缩差异,不声称像素完全一致。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Wanli Ouyang;81844;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[307, 240, 546, 357],PDF点、左上角原点。
Figure 1. (a) In previous vision transformers [10], only one class
token (red square) is used to aggregate information from patch to-
kens (blue square). The learned patch attentions corresponding
to the class token generate a class-agnostic localization map. (b)
In contrast, the proposed MCTformer uses multiple class tokens
to learn interactions between class tokens and patch tokens. The
learned class-to-patch attentions of different class tokens can pro-
duce class-specific object localization maps.
Novel Class Discovery in Semantic Segmentation
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第3页 · P74
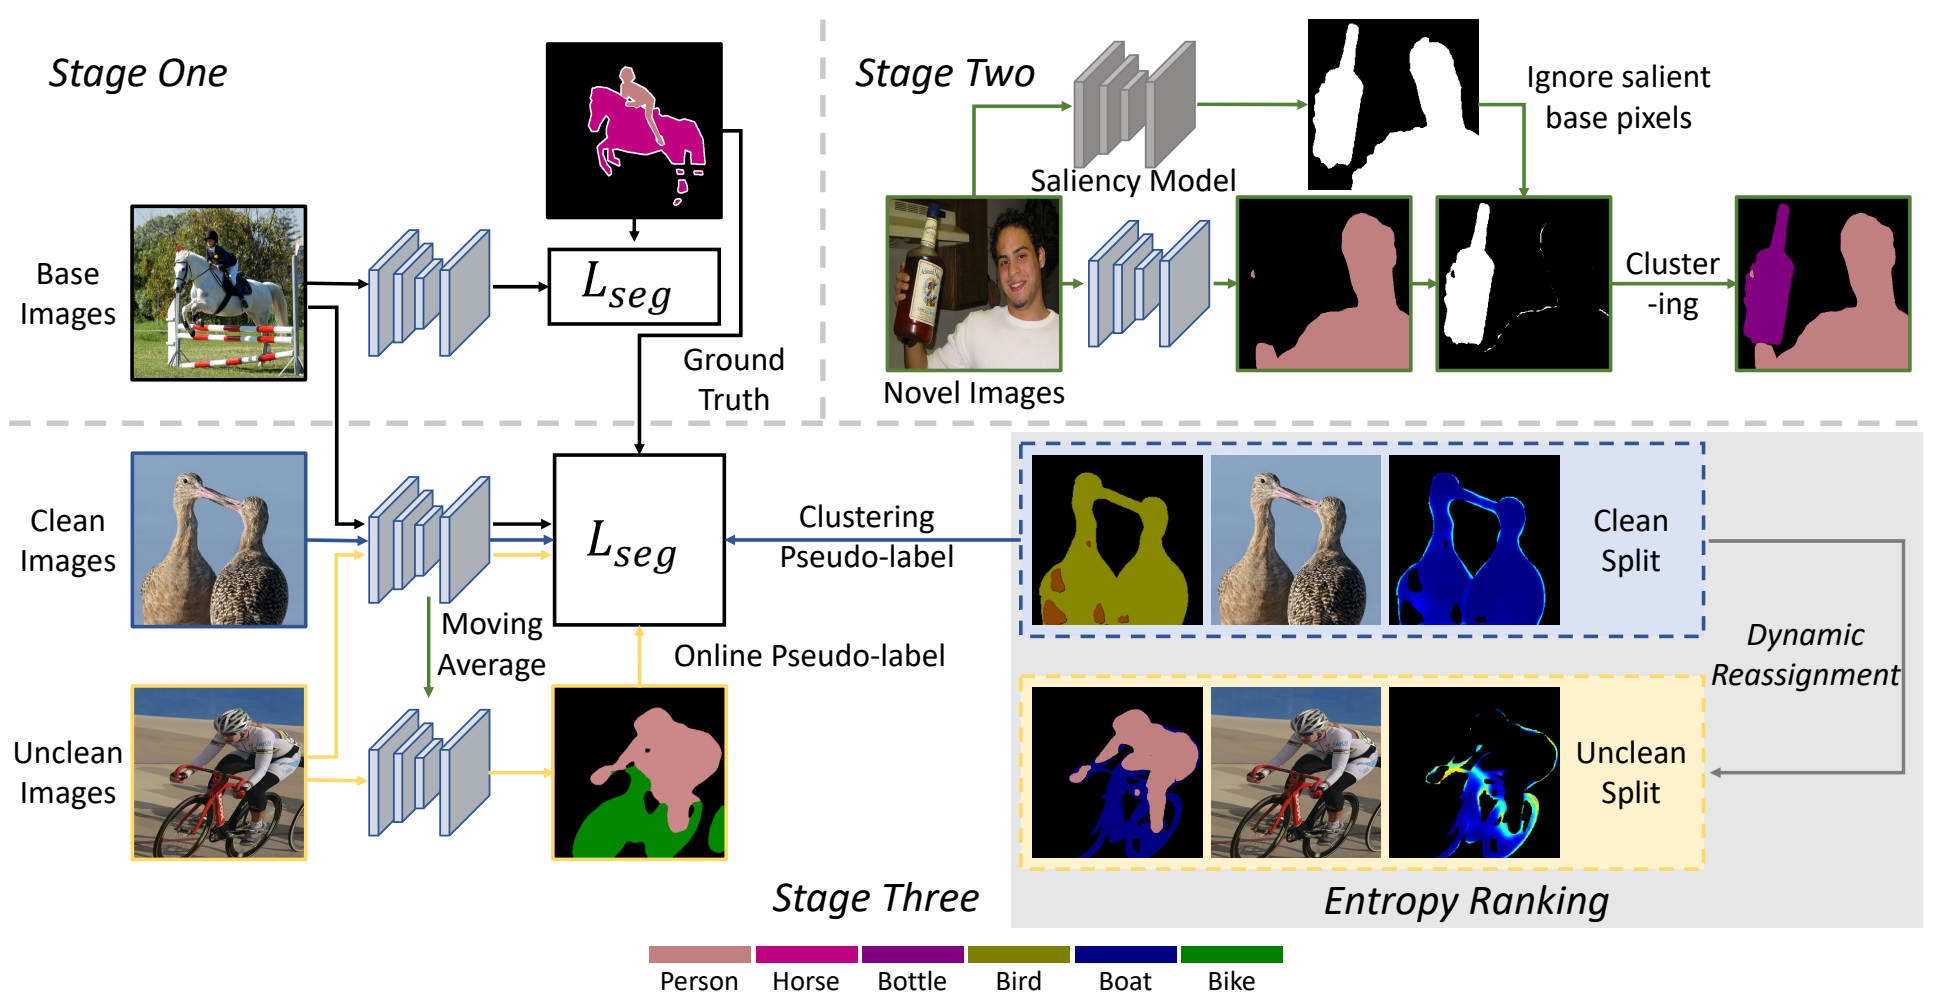
300 dpi PNG · 图注 · 源PDF
第3节Overview和图2展示基础训练、聚类与熵排序自训练三个阶段的整体流程。
完整图注、版本和筛选证据
最早核实视觉日期:2021-12-03;arXiv v1:2021-12-03;CVPR 2022 fixed official PDF
已查看固定PDF及目标图;以最早已核实匹配版本日期作时间代理,不声称实际作图日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Nicu Sebe;59898;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[65, 69, 529, 309],PDF点、左上角原点。
Figure 2. The overview of Entropy-based Uncertainty Modeling and Self-training framework. 1) The model is first trained on the labeled
base set. 2) For the novel images, the saliency maps are generated from a saliency model and high confidence base pixels are ignored. We
then apply clustering to the novel salient part to obtain clustering pseudo-labels. 3) We apply entropy ranking and dynamic reassignment
to split clean and unclean novel images and utilize them to optimize the model with clustering labels and online labels, respectively.
Novel Class Discovery in Semantic Segmentation
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P73
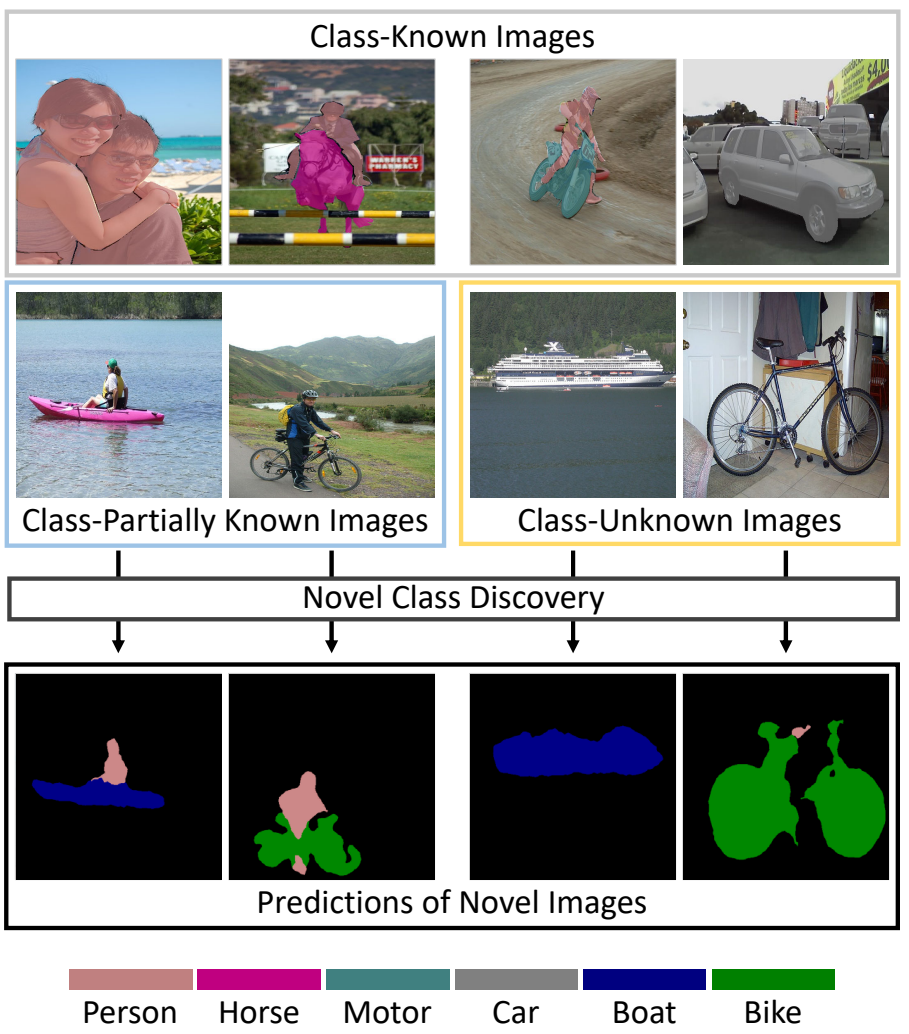
300 dpi PNG · 图注 · 源PDF
引言图1定义已知、部分已知、未知类别图像及新类别预测的任务场景,而非性能结果比较。
完整图注、版本和筛选证据
最早核实视觉日期:2021-12-03;arXiv v1:2021-12-03;CVPR 2022 fixed official PDF
v1与会议版的图内布局、颜色、元素一致,正文排版造成图整体下移;分别保存裁剪坐标。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Nicu Sebe;59898;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[317, 226, 535, 474],PDF点、左上角原点。
Figure 1. Illustration of Novel Class Discovery in Semantic Seg-
mentation(NCDSS).Givenalabeledset(person,horse,motorbike
and car) and a class disjoint unlabeled set (bike and boat), NCDSS
aims at leveraging all the data to segment novel images.
Open-World Instance Segmentation: Exploiting Pseudo Ground Truth From Learned Pairwise Affinity
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第3页 · P50
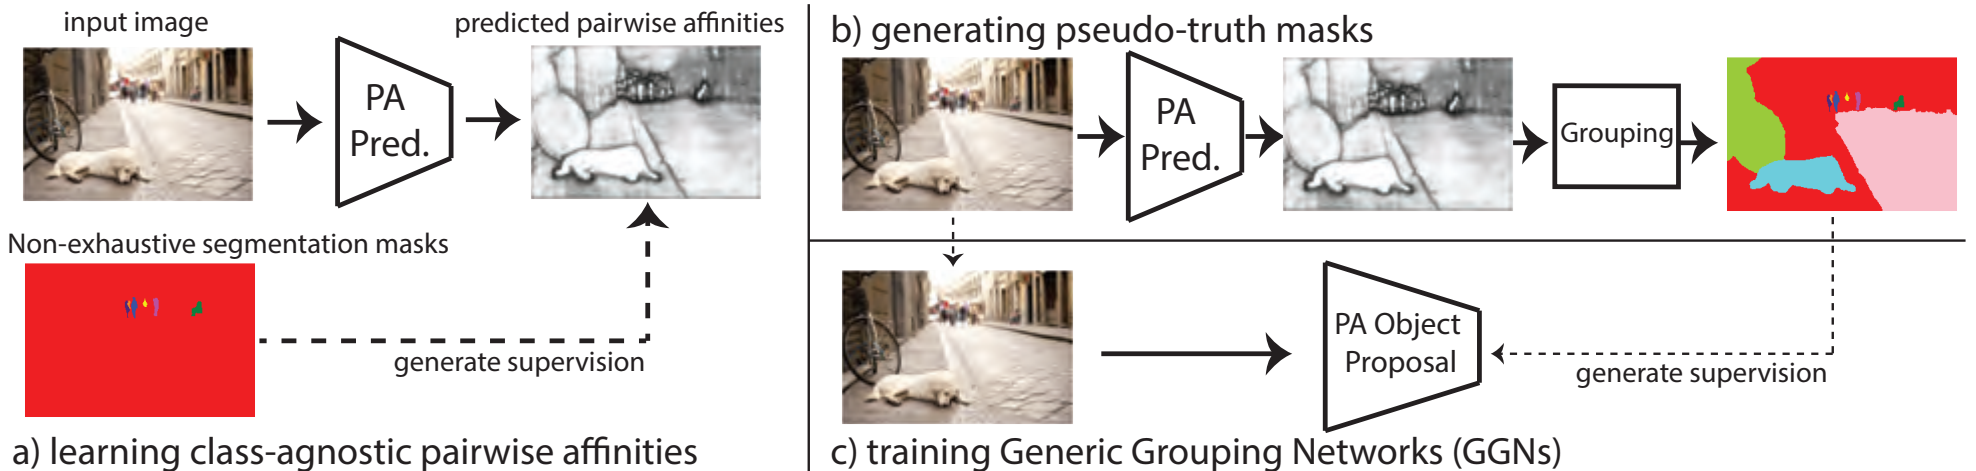
300 dpi PNG · 图注 · 源PDF
图2及第2页正文列出亲和预测训练、分组生成伪真值、训练通用实例提议网络三阶段,是端到端方法流程。
完整图注、版本和筛选证据
最早核实视觉日期:2022-04-12;arXiv v1:2022-04-12;CVPR 2022 fixed official PDF
已逐页查看会议版与arXiv v1;图区设计一致,保留移动/缩放及PDF压缩差异,不声称像素完全一致。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Jitendra Malik;374128;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[60, 71, 534, 184],PDF点、左上角原点。
Figure 2. Overview of our approach. (a) First, a Pairwise-Affinity Predictor (PA Pred.) is trained to predict pairwise affinities using non-
exhaustive segmentation masks as supervision. (b) Once trained, PA Pred. is used to predict pairwise affinities of the images. A grouping
module is then applied on the predicted pairwise affinity maps to generate pseudo-ground-truth masks. (c) A class-agnostic generic object
proposal network (e.g., class-agnostic Mask R-CNN) is trained end-to-end using a combination of GT and generated pseudo-GT masks.
Open-World Instance Segmentation: Exploiting Pseudo Ground Truth From Learned Pairwise Affinity
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P49
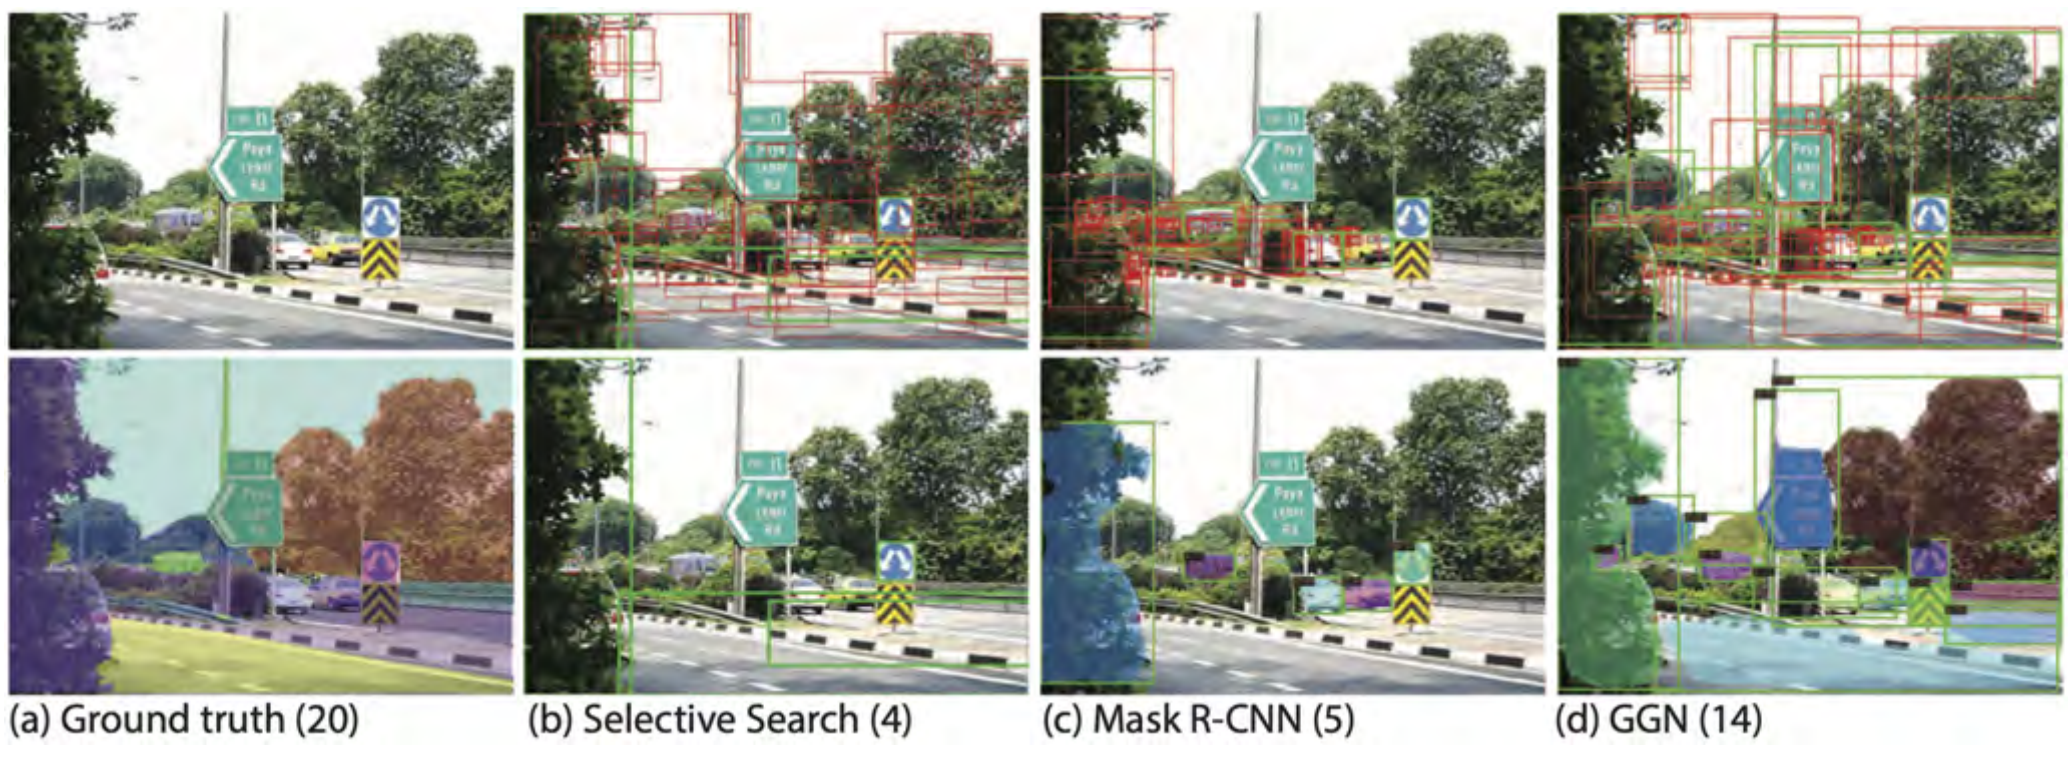
300 dpi PNG · 图注 · 源PDF
引言第2页明确引用图1(c)说明闭集方法无法发现训练类别之外的物体,图注解释SS碎片和Mask R-CNN漏检;按具体开放世界失败案例收录,保留全部八个子图。
完整图注、版本和筛选证据
最早核实视觉日期:2022-04-12;arXiv v1:2022-04-12;CVPR 2022 fixed official PDF
已逐页查看会议版与arXiv v1;图区设计一致,保留移动/缩放及PDF压缩差异,不声称像素完全一致。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Jitendra Malik;374128;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[49, 231, 546, 413],PDF点、左上角原点。
Figure 1. Comparison of GGN with different baselines. (a) an input image from ADE20K [61] (upper row) with the ground truth
object masks overlaid (lower row). Three different approaches: (b) Selective Search (SS) [51], (c) Mask R-CNN [22], and (d) our Generic
Grouping Network (GGN) are applied on the same image to predict the top 100 proposals. The upper images provide all top-100 proposals
predicted by three approaches with false and true positive proposals visualized in red and green boxes, respectively. The lower images
provide only true positive proposals. The number of true positive proposals or ground truth objects are denoted in parentheses. Among 20
ground truth objects, SS recalls only 4, Mask R-CNN detects 5, and GGN retrieves 14. SS is a bottom-up non-parametric approach, thus
has no notion of objectness. Mask R-CNN can make whole object proposals; however it still fails to detect objects that are not seen during
training. Our GGN can predict whole object proposals and generalize to unseen categories.
Representation Compensation Networks for Continual Semantic Segmentation
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P144
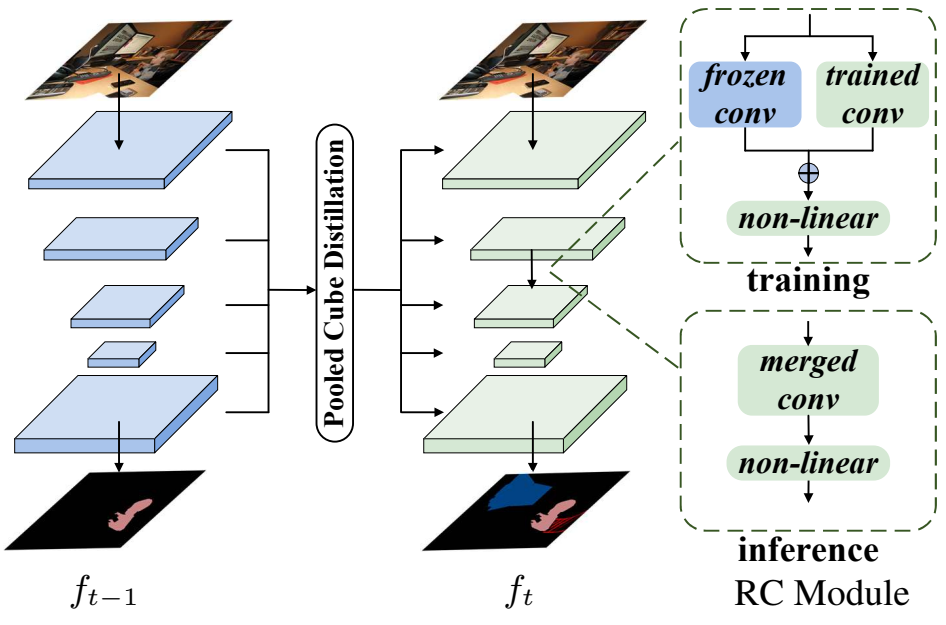
300 dpi PNG · 图注 · 源PDF
图1明确为完整持续分割训练框架,覆盖教师/学生、池化立方蒸馏以及表示补偿的训练和推理关系。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-10;arXiv v1:2022-03-10;CVPR 2022 fixed official PDF
已比较固定会议PDF与arXiv v1的完整图形;目标视觉版本匹配。页面排版平移已在historical_crop_bbox中记录;非图形重绘。实际创作日期未知。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Ming-Ming Cheng;85763;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[314, 207, 541, 357],PDF点、左上角原点。
Figure 1. Illustration of our proposed training framework for con-
tinual semantic segmentation to avoid catastrophic forgetting. We
design two mechanisms in our method, representation compensa-
tion (RC) module and pooled cube distillation (PCD).
Representation Compensation Networks for Continual Semantic Segmentation
会议:CVPR 2022 · 主会论文
Figure 5 · PDF第5页 · P143
300 dpi PNG · 图注 · 源PDF
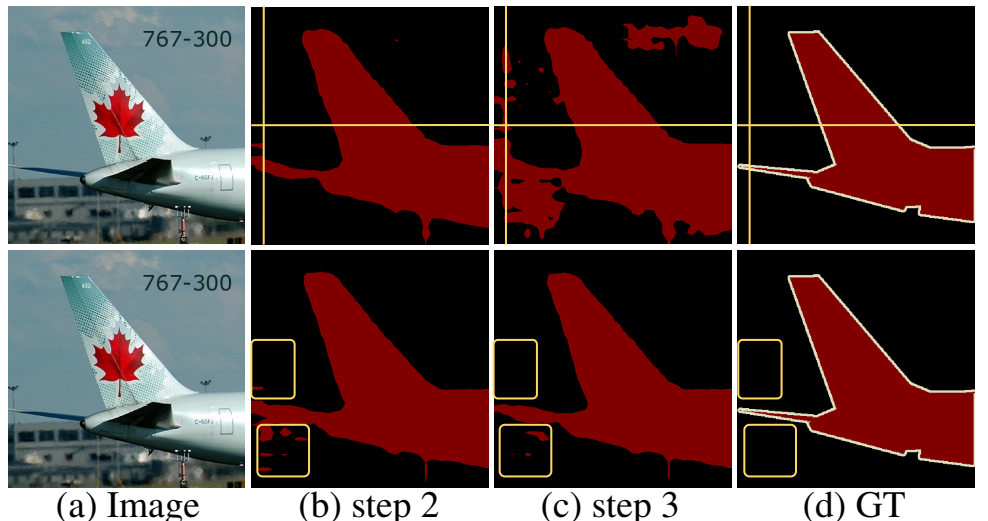
第3.3节在实验前用图5解释条带池化的长程噪声扩散及跨步错误累积;图4是局部池化操作示意,因此选择有明确失败诊断功能的图5。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-10;arXiv v1:2022-03-10;CVPR 2022 fixed official PDF
已比较固定会议PDF与arXiv v1的完整图形;目标视觉版本匹配。页面排版平移已在historical_crop_bbox中记录;非图形重绘。实际创作日期未知。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Ming-Ming Cheng;85763;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[49, 69, 286, 194],PDF点、左上角原点。
Figure 5. The impact of the strip pooling (top row) used in
PLOP [27] and the average pooling (bottom row) in our method.
Rethinking Semantic Segmentation: A Prototype View
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第3页 · P124
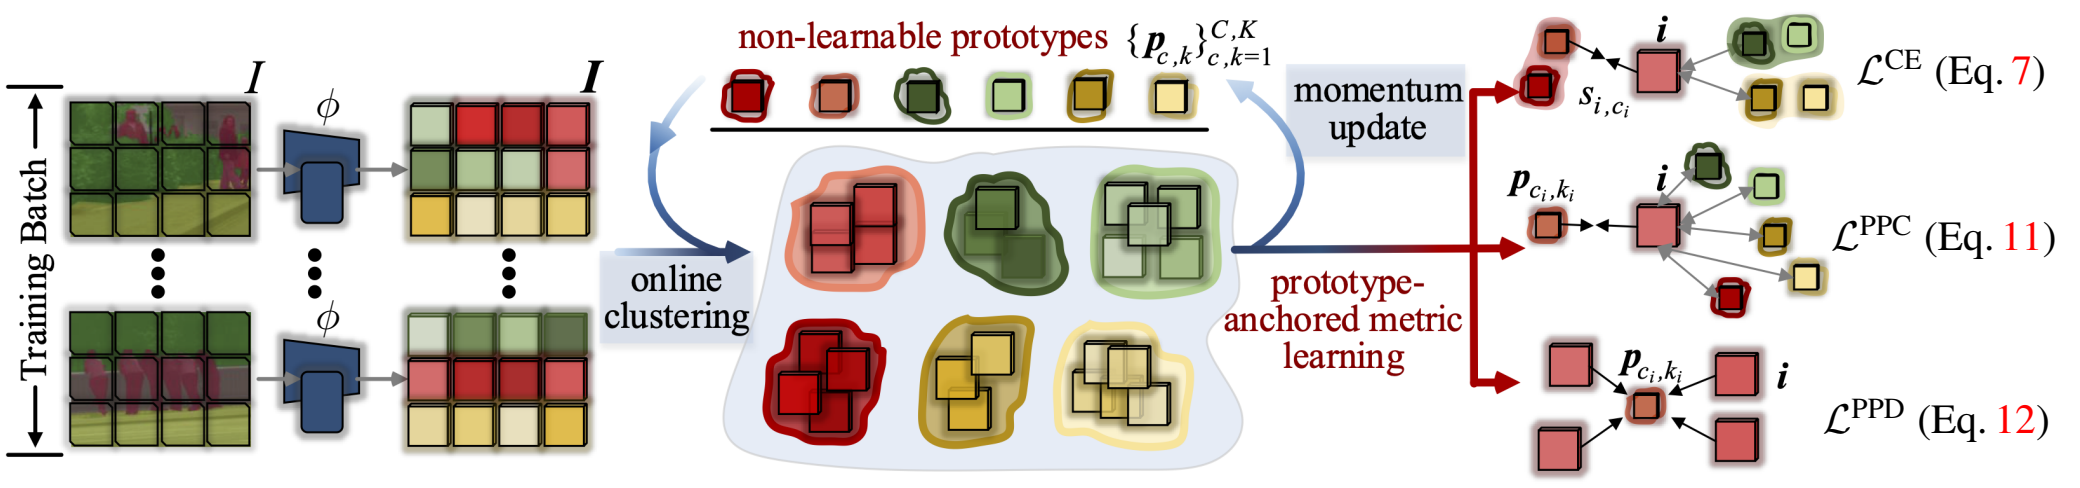
300 dpi PNG · 图注 · 源PDF
图2及第3节展示训练数据、编码、在线聚类、动量更新和三项损失的整体训练关系。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-28;arXiv v1:2022-03-28;CVPR 2022 fixed official PDF
v1图2与会议图逐像素一致。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Luc Van Gool;309926;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[49, 66, 548, 183],PDF点、左上角原点。
Figure 2. Architecture illustration of our non-learnable prototype based nonparametric segmentation model during the training phase.
Rethinking Semantic Segmentation: A Prototype View
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P123
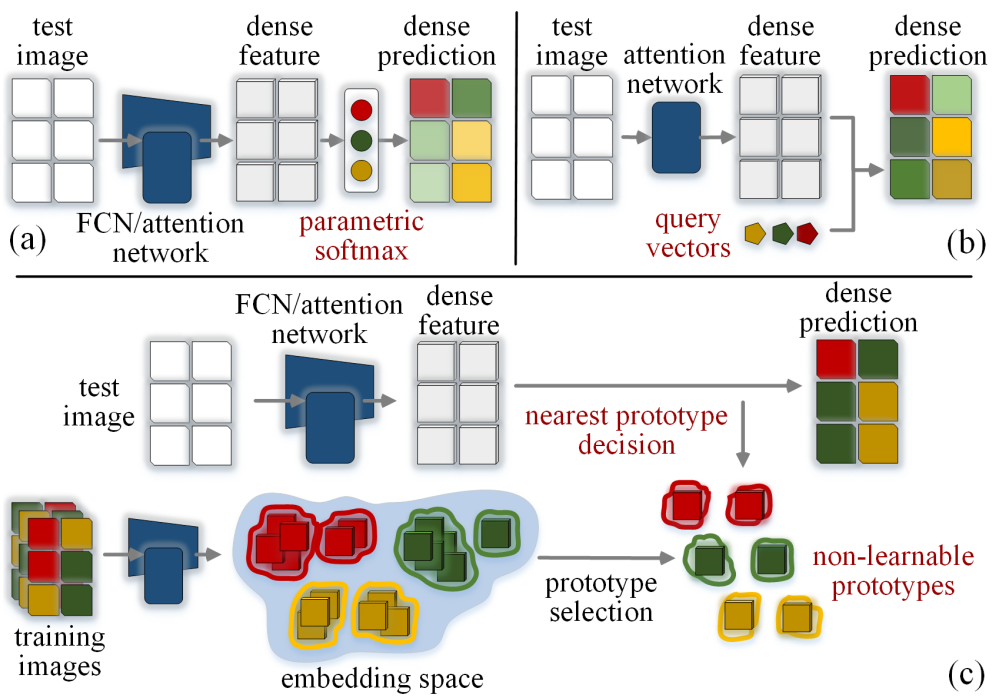
300 dpi PNG · 图注 · 源PDF
引言以图1对比两类参数化原型与非参数化原型范式,提出可学习原型代表性与类内多样性问题;属于概念对比。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-28;arXiv v1:2022-03-28;CVPR 2022 fixed official PDF
v1图1与会议图逐像素一致。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Luc Van Gool;309926;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[308, 201, 548, 368],PDF点、左上角原点。
Figure 1. Different sematic segmentation paradigms: (a-b) para-
metric vs (c) nonparametric. Modern segmentation solutions, no
matter using (a) parametric softmax or (b) query vectors for mask
decoding,canbeviewedaslearnableprototypebasedmethodsthat
learn class-wise prototypes in a fully parametric manner. We in-
steadproposeanonparametricscheme(c)thatdirectlyselectssub-
clustercentersofembeddedpixelsasprototypes,andachievesper-
pixel prediction via nonparametric nearest prototype retrieving.
SimT: Handling Open-set Noise for Domain Adaptive Semantic Segmentation
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第4页 · P138
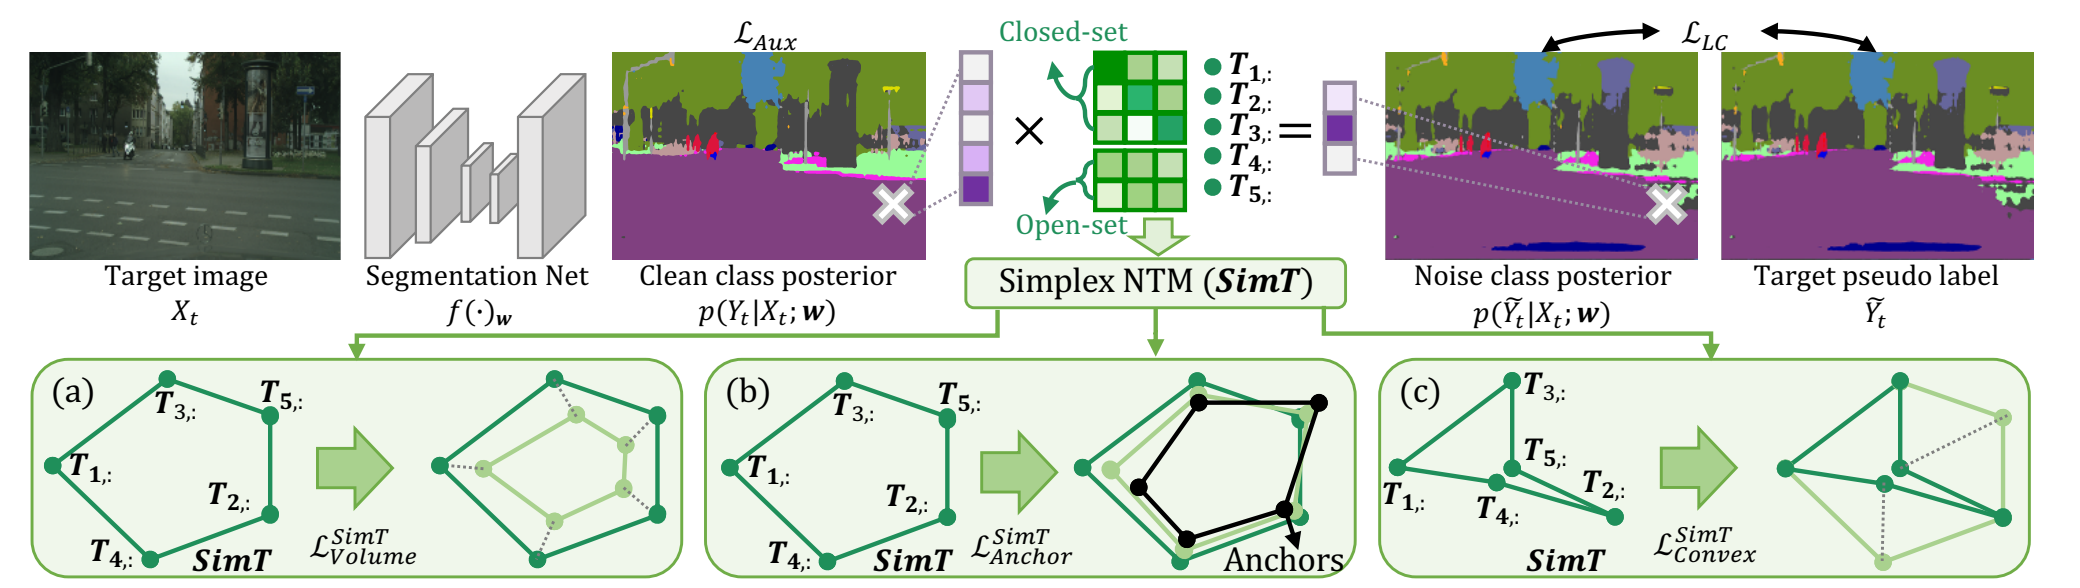
300 dpi PNG · 图注 · 源PDF
图2为完整域适应训练框架,覆盖输入、分割网、噪声转换、监督校正及三个正则化支路。
完整图注、版本和筛选证据
最早核实视觉日期:2022-06;arXiv v1:2022-03-29;CVPR 2022 fixed official PDF
v1的L_LC为单向箭头,v2已改成双向;会议版进一步调整全图比例与标签排布。已查看全部arXiv历史版本;最早核实包含目标视觉版本的文献为CVF固定会议PDF,官方书目明确出版月June 2022。该月全在S1。月内首次公开日未知,不把会议版新画面追溯为v1日期。历史对照图保留差异,不声称像素相同。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yixuan Yuan;16227;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[49, 57, 548, 198],PDF点、左上角原点。
Figure 2. The proposed domain adaption framework contains a segmentation net and a SimT. Target images are passed through the
segmentation net f(·) to perform semantic segmentation, and supervision signals are corrected by the learnable SimT. SimT is estimated
w
through the proposed (a) volume regularization, (b) anchor guidance and (c) convex guarantee.
SimT: Handling Open-set Noise for Domain Adaptive Semantic Segmentation
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第2页 · P137
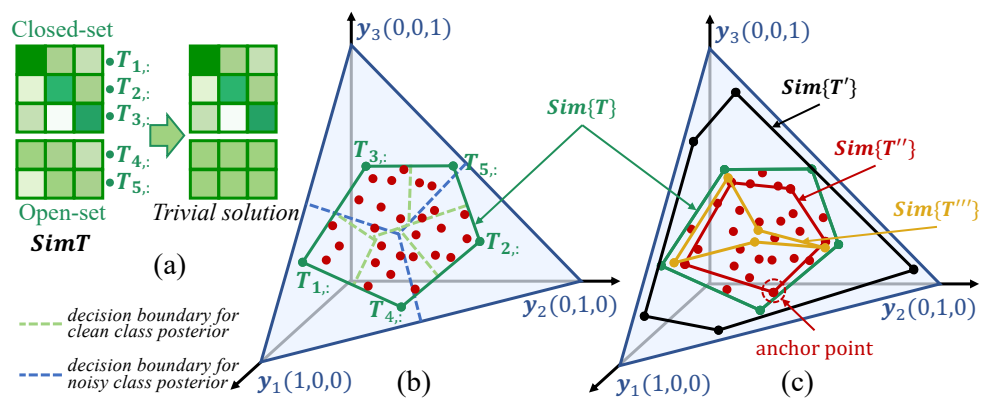
300 dpi PNG · 图注 · 源PDF
引言通过图1的几何示意说明闭集估计假设在开放集噪声下失效,并对比平凡解与正确单纯形;属于概念问题示意。
完整图注、版本和筛选证据
最早核实视觉日期:2022-06;arXiv v1:2022-03-29;CVPR 2022 fixed official PDF
v1及v2与会议版的几何示意比例、标签和图例位置有调整,未强行认作逐像素同一视觉版本。已查看全部arXiv历史版本;最早核实包含目标视觉版本的文献为CVF固定会议PDF,官方书目明确出版月June 2022。该月全在S1。月内首次公开日未知,不把会议版新画面追溯为v1日期。历史对照图保留差异,不声称像素相同。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yixuan Yuan;16227;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[48, 64, 289, 161],PDF点、左上角原点。
Figure 1. Geometric illustration of SimT with the setting of 3
pseudo label classes and 5 ground truth label classes. Note that
coordinates (x,y,z) of any points in blue triangle satisfy condi-
tions of x + y + z = 1 and 0 < x,y,z < 1.
Tree Energy Loss: Towards Sparsely Annotated Semantic Segmentation
会议:CVPR 2022 · 主会论文
Figure 3 · PDF第3页 · P134
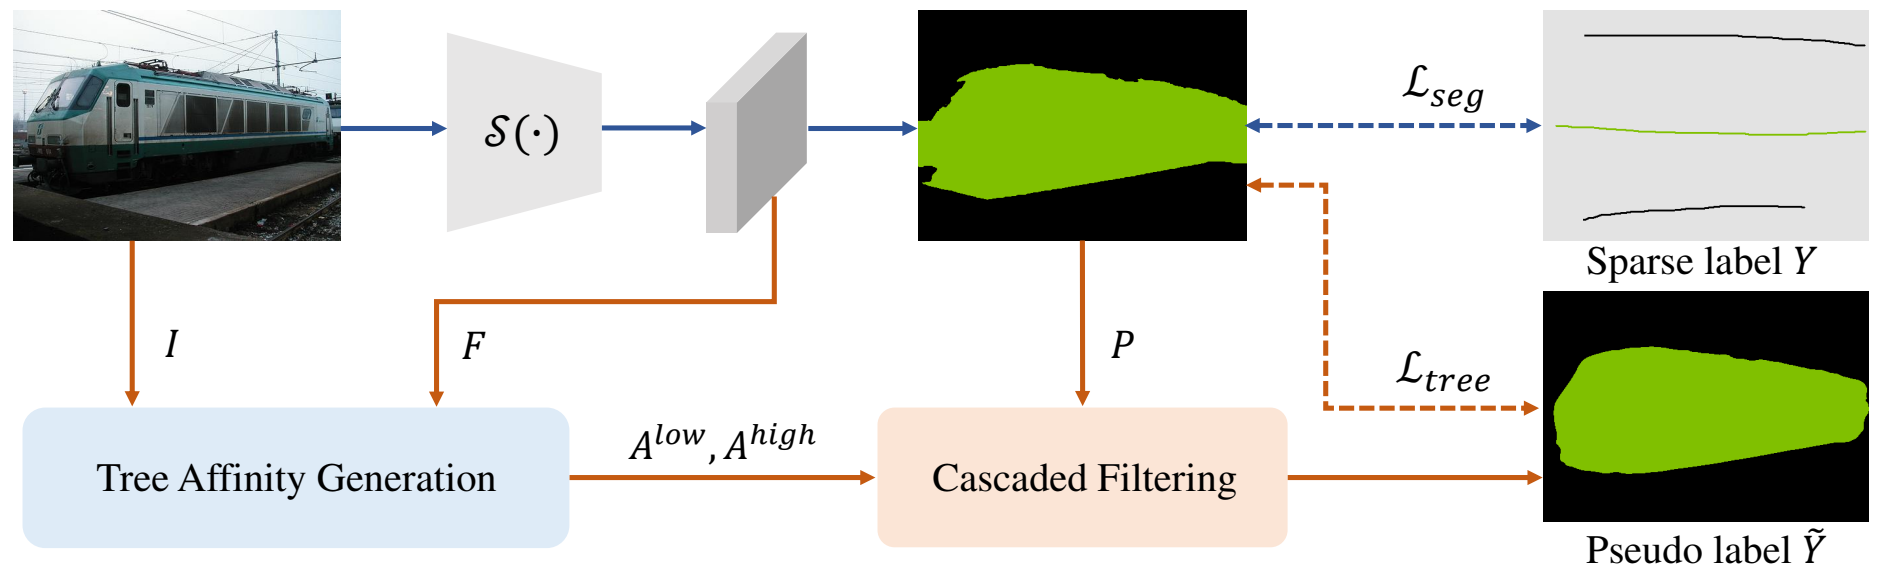
300 dpi PNG · 图注 · 源PDF
第3.2节明确图3为整体架构,包含分割、两级亲和生成、级联过滤、伪标签及两项训练损失。
完整图注、版本和筛选证据
最早核实视觉日期:2022-06;arXiv v1:2022-03-21;CVPR 2022 fixed official PDF
v1及v2的分割模型S(.)使用衬线字体,会议版该标签改为无衬线字体。已查看全部arXiv历史版本;最早核实包含目标视觉版本的文献为CVF固定会议PDF,官方书目明确出版月June 2022。该月全在S1。月内首次公开日未知,不把会议版新画面追溯为v1日期。历史对照图保留差异,不声称像素相同。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Xiangyu Zhang;481440;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[72, 70, 523, 207],PDF点、左上角原点。
Figure 3. Flowchart of the proposed single-stage SASS method, which is realized by incorporating an auxiliary branch into the traditional
segmentation model S(·). During training, the predicted masks P are split into the labeled and unlabeled parts, which are supervised by
the segmentation loss L and the tree energy loss L , respectively. To obtain pseudo labels for unlabeled pixels, the Tree Affinity
seg tree
Generation procedure (Eqs. 3-5) first utilizes the color information I and semantic features F to generate the low-level and high-level
affinity matrices Alow,Ahigh. Then the Cascaded Filtering operation (Eqs. 6-7) converts the network predictions P into soft pseudo labels
Y˜. During testing, the auxiliary branch is removed to avoid extra computational costs.
Tree Energy Loss: Towards Sparsely Annotated Semantic Segmentation
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P133
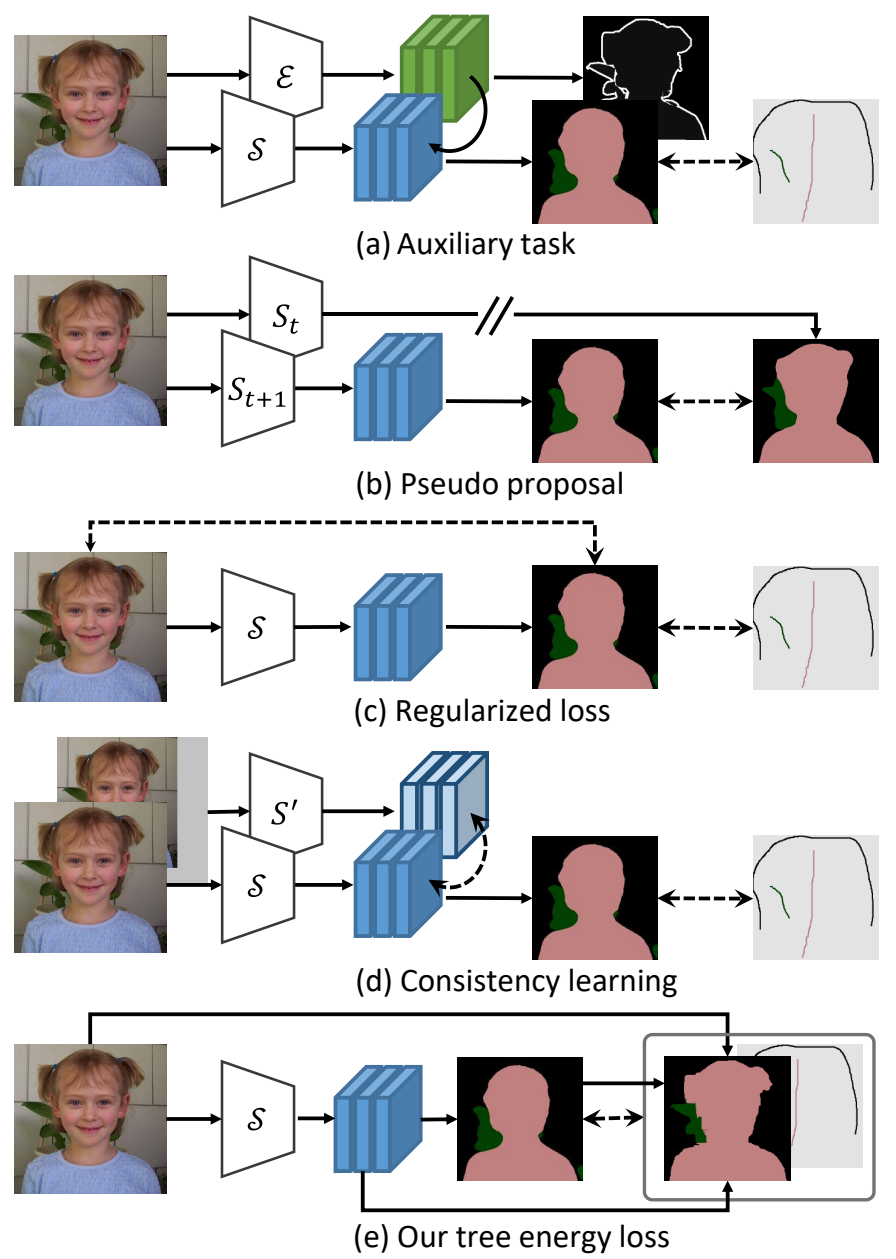
300 dpi PNG · 图注 · 源PDF
引言按图1比较辅助任务、伪标签、正则化和一致性学习范式,并逐项指出错误传播、多阶段训练和监督不足;全图用于引出问题。
完整图注、版本和筛选证据
最早核实视觉日期:2022-06;arXiv v1:2022-03-21;CVPR 2022 fixed official PDF
v1及v2的子图标题为衬线字体,会议版改为无衬线字体,且v2块形状也不同。已查看全部arXiv历史版本;最早核实包含目标视觉版本的文献为CVF固定会议PDF,官方书目明确出版月June 2022。该月全在S1。月内首次公开日未知,不把会议版新画面追溯为v1日期。历史对照图保留差异,不声称像素相同。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Xiangyu Zhang;481440;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[320, 214, 535, 516],PDF点、左上角原点。
Figure1. IllustrationofcurrentSASSapproaches. S andE denote
the segmentation and auxiliary models, respectively. Our method
leverages the minimum spanning trees (MSTs) to capture both
low-level and high-level affinities to generate soft pseudo labels,
performing online self-training.
A Text Attention Network for Spatial Deformation Robust Scene Text Image Super-resolution
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第3页 · P72
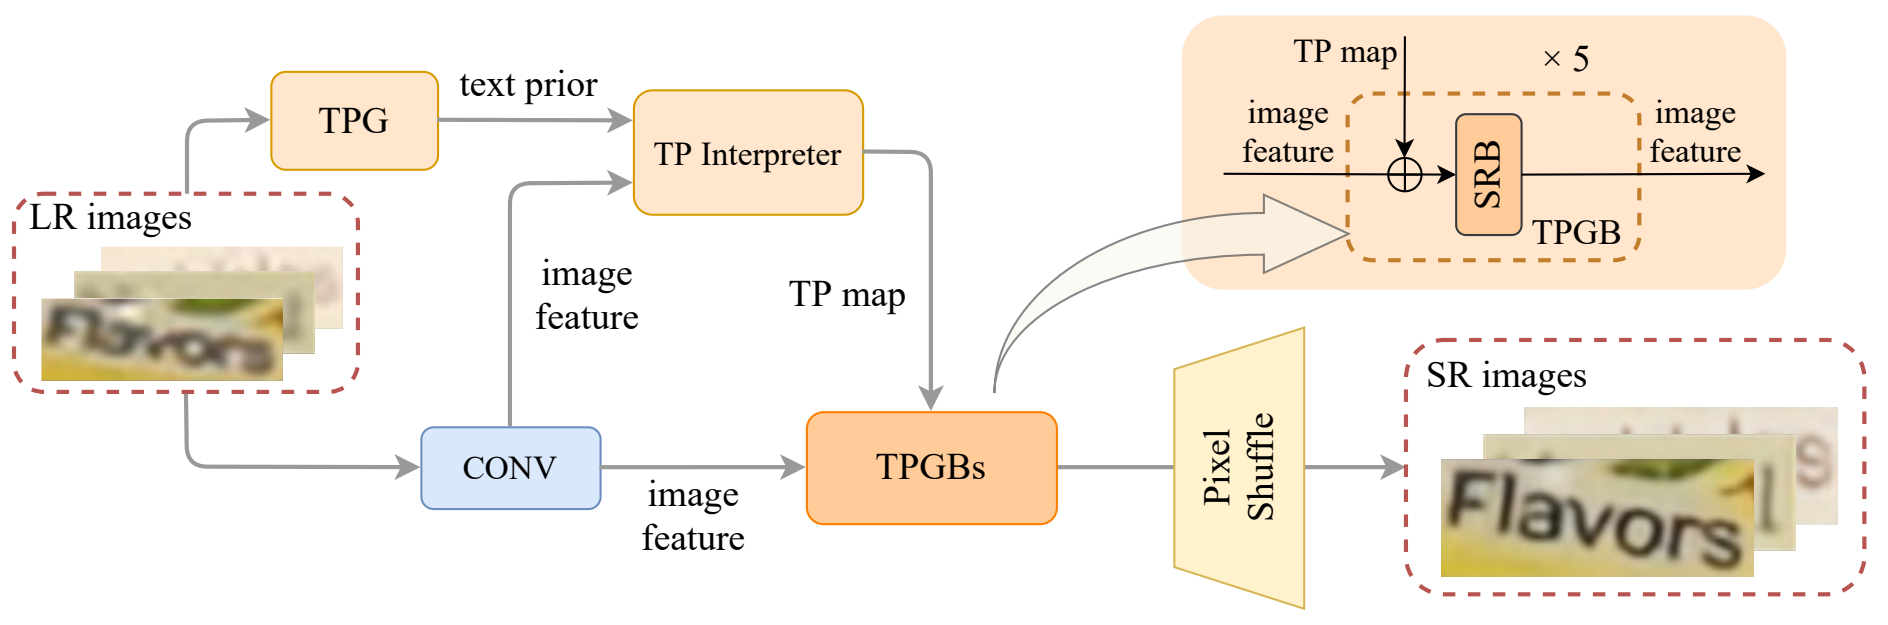
300 dpi PNG · 图注 · 源PDF
第3.1节Overall Architecture明确以图2展示TP生成、解释、图像特征融合和高分辨率输出全路径。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-17;arXiv v1:2022-03-17;CVPR 2022 fixed official PDF
已查看固定PDF及目标图;以最早已核实匹配版本日期作时间代理,不声称实际作图日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[72, 69, 525, 219],PDF点、左上角原点。
Figure2. ArchitectureofourproposedTATTnetworkforSTISR.TPGB,TPGandSRBareshortfortextpriorguidedblocks,TPGenerator
and Sequential-Recurrent Blocks, respectively, while ⊕ means the element-wise addition.
A Text Attention Network for Spatial Deformation Robust Scene Text Image Super-resolution
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P71
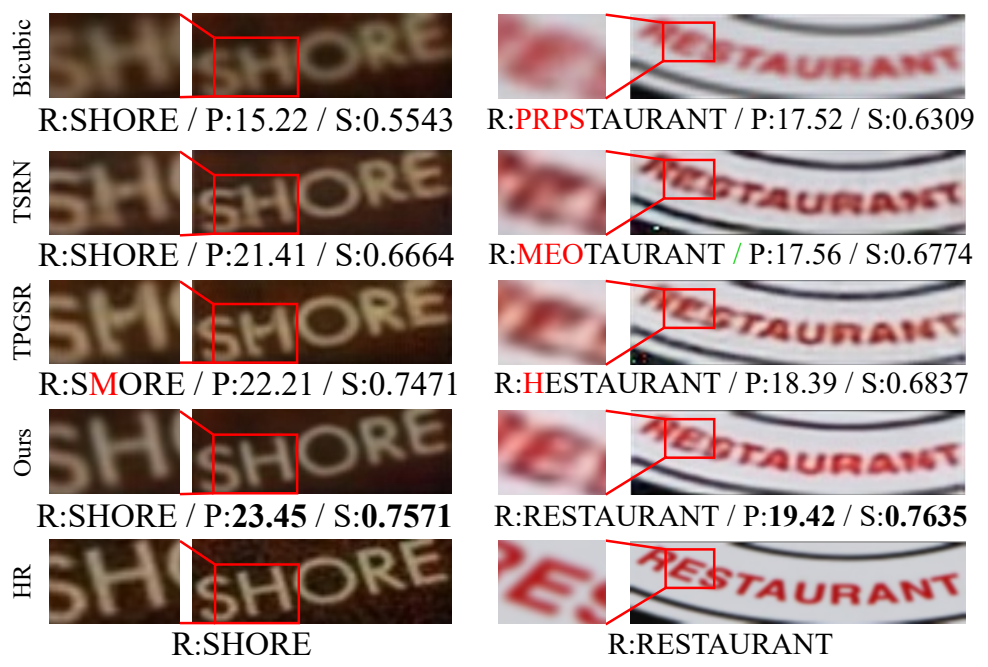
300 dpi PNG · 图注 · 源PDF
引言及图1用红色字符明确指出旋转和弯曲文字的语义识别错误,作为现有局部CNN方法的失败案例。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-17;arXiv v1:2022-03-17;CVPR 2022 fixed official PDF
已查看固定PDF及目标图;以最早已核实匹配版本日期作时间代理,不声称实际作图日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[309, 230, 546, 390],PDF点、左上角原点。
Figure 1. SR recovery of different models on rotated and curve-
shaped text images. ‘R’, ‘P’ and ‘S’ stand for recognition, PSNR
and SSIM results. Characters in red are missing or wrong.
Blind Image Super-resolution with Elaborate Degradation Modeling on Noise and Kernel
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第2页 · P130
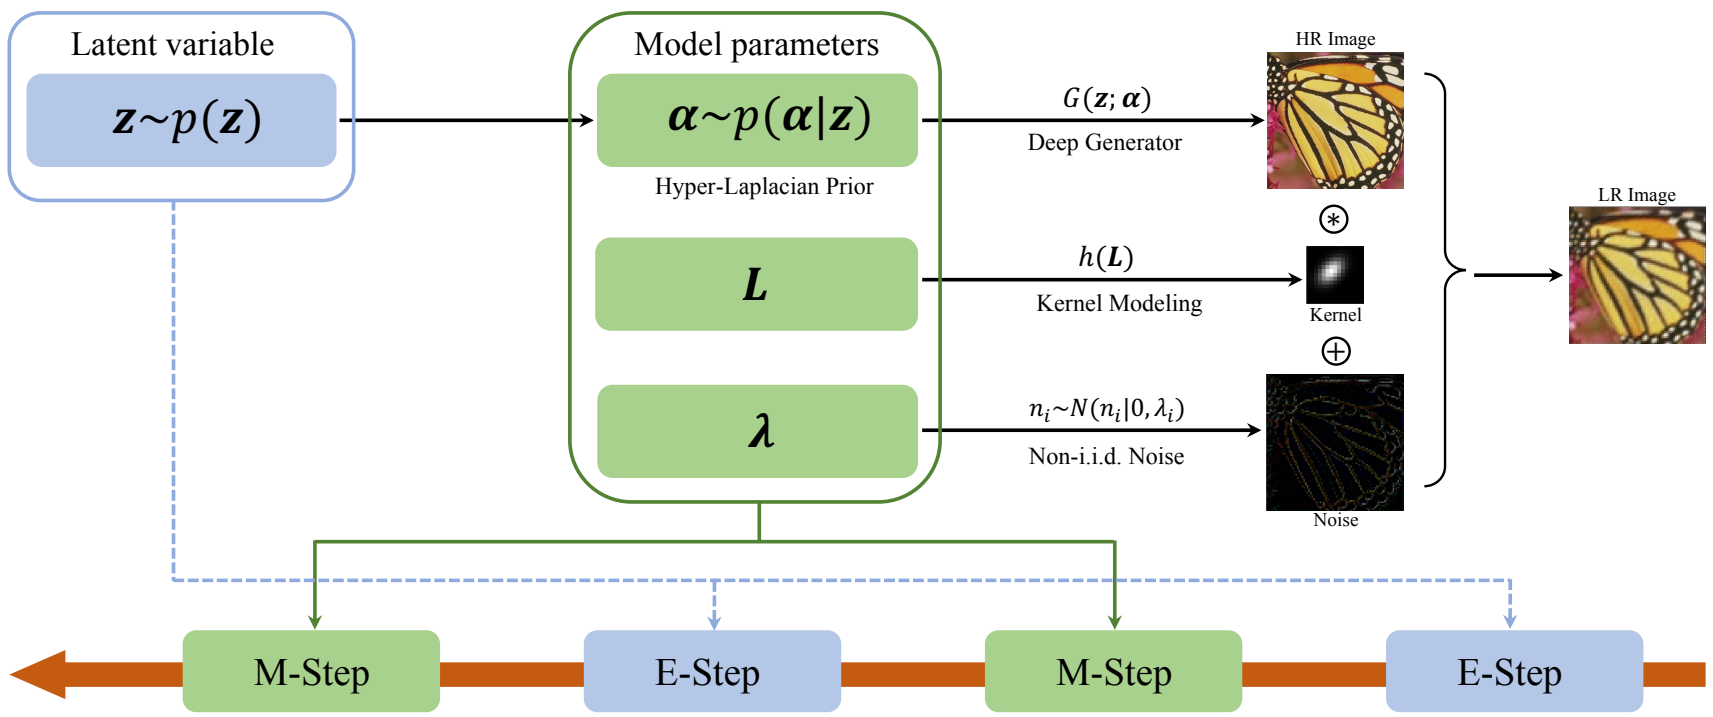
300 dpi PNG · 图注 · 源PDF
图1及方法概述展示潜变量、模型参数、噪声/核退化及EM交替更新的完整计算流程。
完整图注、版本和筛选证据
最早核实视觉日期:2021-11-11;arXiv v1:2021-07-02;CVPR 2022 fixed official PDF
v1/v2流程图为旧版;v3图1与会议版逐像素一致;v4未改变。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[91, 71, 502, 243],PDF点、左上角原点。
Figure 1. An overview of the proposed SISR method and the corresponding EM algorithm. A probabilistic model is constructed to depict the generation
process of the observed LR image, which mainly involves two groups of parameters, including the latent variable z and the model parameters {α,L,λ}.
AMonteCarloEMalgorithmisdesignedtoalternatelyupdatethemintheE-StepandM-Step,respectively.Blind Image Super-resolution with Elaborate Degradation Modeling on Noise and Kernel
会议:CVPR 2022 · 主会论文
Figure 3 · PDF第6页 · P129
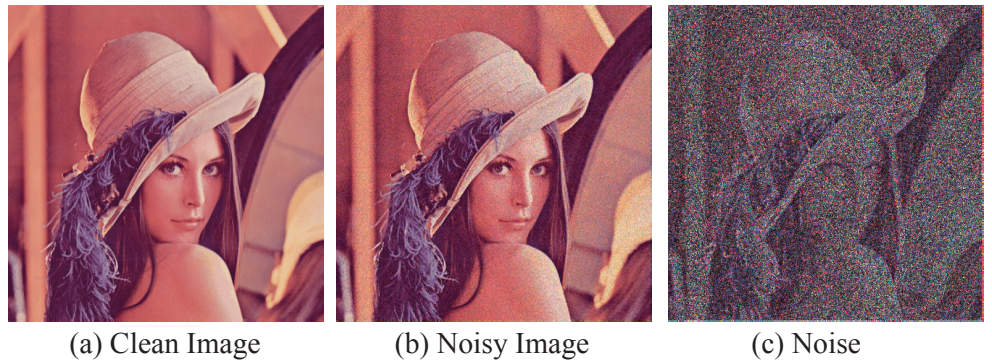
300 dpi PNG · 图注 · 源PDF
图3示意干净图、相机传感器噪声污染图与噪声残差,正文解释非独立同分布噪声这一待恢复输入条件;它不是模型性能结果拼图。图2仅列实验合成核,不计动机图。
完整图注、版本和筛选证据
最早核实视觉日期:2021-11-11;arXiv v1:2021-07-02;CVPR 2022 fixed official PDF
v1/v2旧图2含噪声方差图,构图不同;v3已换为会议图3三面板,相比会议排版纵坐标上移2.834pt;对应坐标逐图比对。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[308, 271, 546, 358],PDF点、左上角原点。
Figure3. IllustrationofcamerasensornoiseofCase2. Fromlefttoright:
(a) clean image; (b) simulated noisy image with camera sensor noise; (c)
absoluteresidual(ornoise)between(a)and(b).
Deblurring via Stochastic Refinement
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第2页 · P232
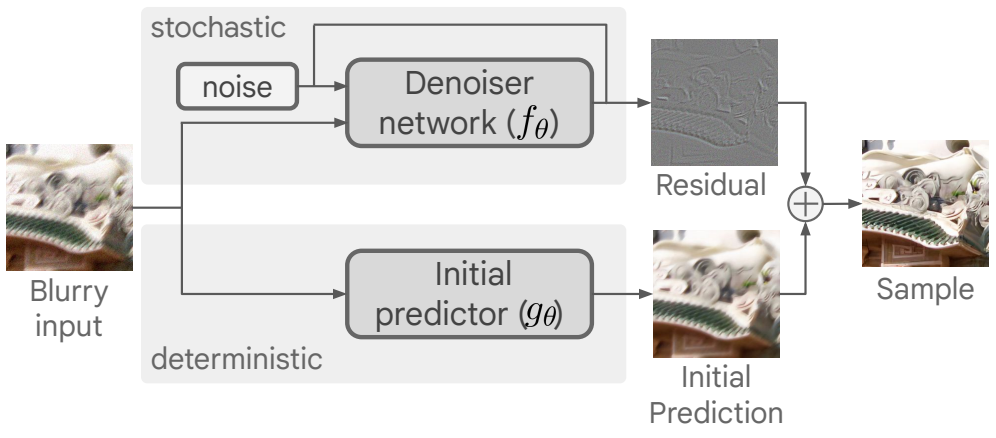
300 dpi PNG · 图注 · 源PDF
图2及引言明确为双网络整体架构,含模糊输入、初始预测、随机噪声、残差去噪、合成与输出。
完整图注、版本和筛选证据
最早核实视觉日期:2021-12-05;arXiv v1:2021-12-05;CVPR 2022 fixed official PDF
固定会议与v1两张图像素一致(MAE=0);已读图注正文与Google Research作者单位,完整300dpi导出已目检。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Peyman Milanfar;37874;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[308, 75, 547, 180],PDF点、左上角原点。
Figure 2. Diagram describing our dual-network architecture. The
initial predictor produces the deterministic candidate for the de-
noiser network, which then models the residual.
Deblurring via Stochastic Refinement
会议:CVPR 2022 · 主会论文
Figure 3 · PDF第4页 · P231
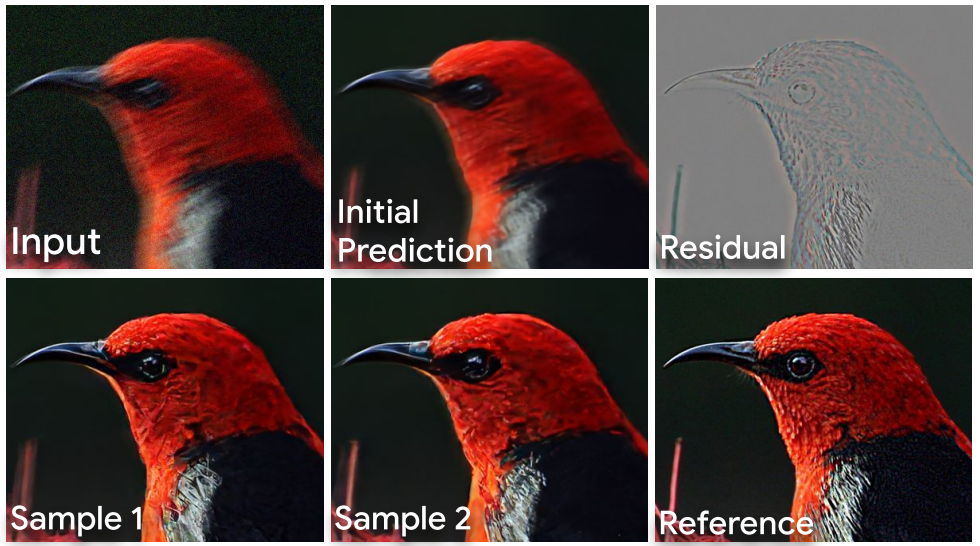
300 dpi PNG · 图注 · 源PDF
图3明确显示初始确定性预测过度平滑、缺少纹理及其残差;正文第2节解释均值回归造成纹理损失,第4节以此引出随机细化,不是普通性能结果拼图。
完整图注、版本和筛选证据
最早核实视觉日期:2021-12-05;arXiv v1:2021-12-05;CVPR 2022 fixed official PDF
固定会议与v1两张图像素一致(MAE=0);已读图注正文与Google Research作者单位,完整300dpi导出已目检。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Peyman Milanfar;37874;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[51, 73, 286, 204],PDF点、左上角原点。
Figure 3. Output of the initial predictor and multiple samples
generated from it. We see that the over-smoothed initial prediction
lacking texture is “corrected” by the stochastic sampler, producing
crisp and diverse final reconstructions. The residual (top right)
shows the the difference between reference and initial prediction.
Deep Constrained Least Squares for Blind Image Super-Resolution
会议:CVPR 2022 · 主会论文
Figure 4 · PDF第4页 · P216
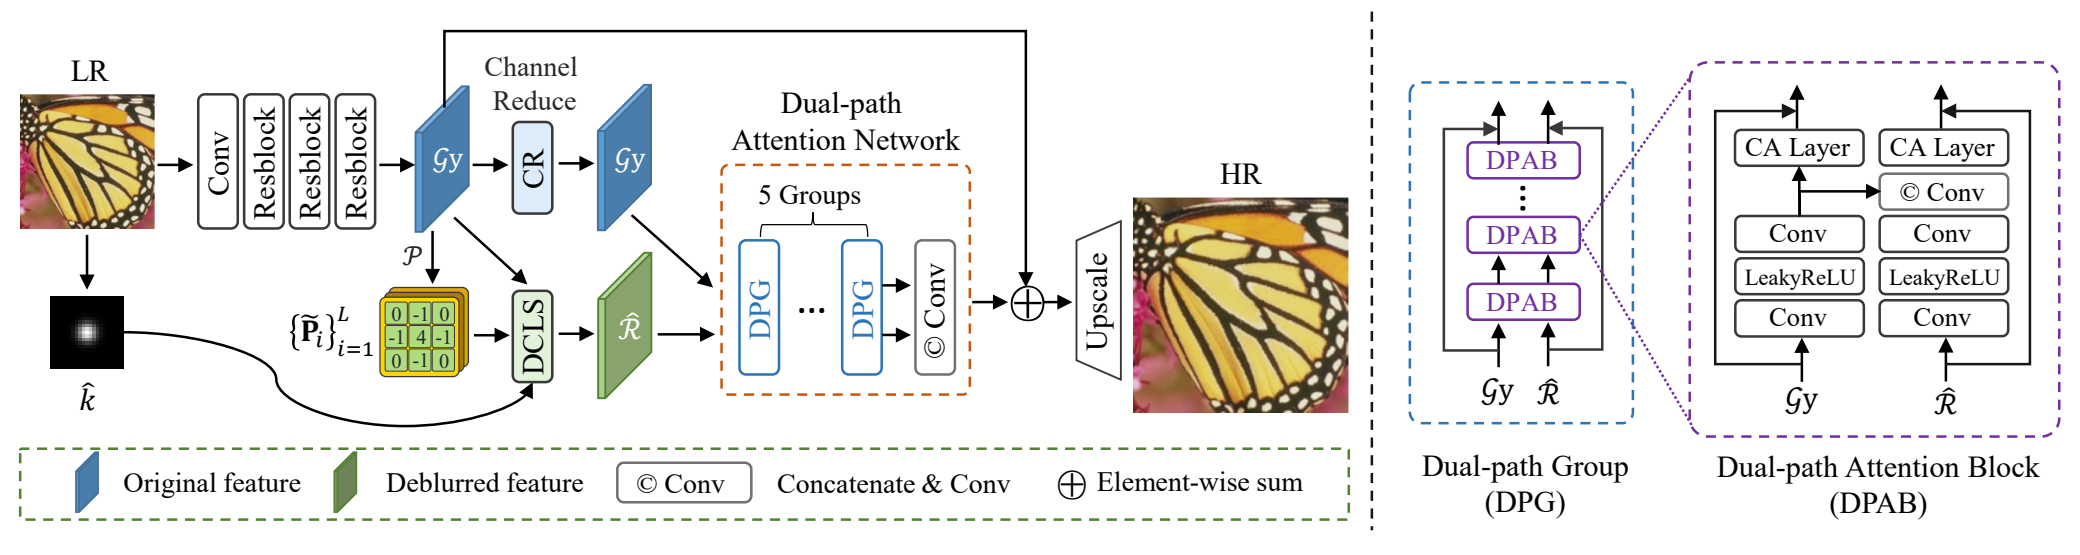
300 dpi PNG · 图注 · 源PDF
图4明确为所提方法的overview architecture,完整展示核估计、特征去卷积、双路径注意力及高分辨率输出。
完整图注、版本和筛选证据
最早核实视觉日期:2022-02-15;arXiv v1:2022-02-15;CVPR 2022 fixed official PDF
固定会议PDF与arXiv v1的目标图已对照;构图、配色、标签和连线一致。已在固定PDF首页及公开作者引用主页核对作者身份和机构。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Haoqiang Fan;13604;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[49, 70, 548, 203],PDF点、左上角原点。
Figure 4. The overview architecture of the proposed method. Given an LR image y, we first estimate the degradation kernel kˆ , and involve
it in the deep constrained least squares (DCLS) convolution in the feature domain. The deblurred features R(cid:98) are then concatenated with
primitive features G y to restore the clean HR image x through a dual-path attention network (DPAN).
Deep Constrained Least Squares for Blind Image Super-Resolution
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第2页 · P215
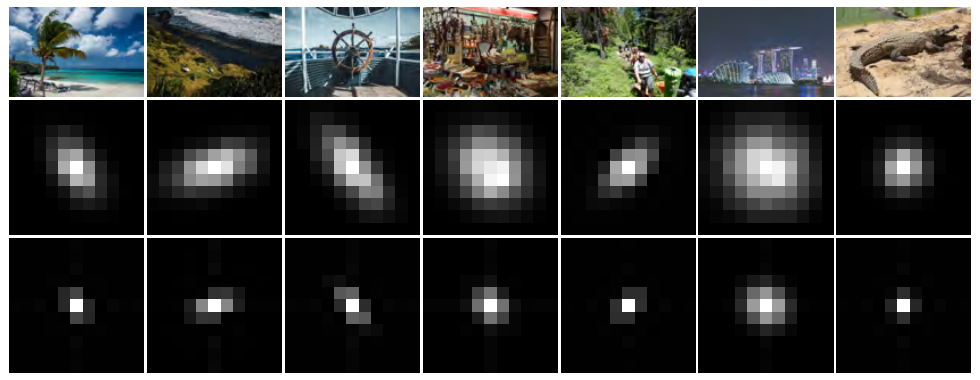
300 dpi PNG · 图注 · 源PDF
引言借图2对比原始HR空间核与重表述LR空间核,解释核和图像分辨率不一致的建模问题及概念转换;图1只是普通SR结果比较。
完整图注、版本和筛选证据
最早核实视觉日期:2022-02-15;arXiv v1:2022-02-15;CVPR 2022 fixed official PDF
固定会议PDF与arXiv v1的目标图已对照;构图、配色、标签和连线一致。已在固定PDF首页及公开作者引用主页核对作者身份和机构。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Haoqiang Fan;13604;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[310, 72, 545, 163],PDF点、左上角原点。
Figure 2. Kernel reformulation examples. The top row and middle
row are the LR images and the corresponding primitive kernels.
The bottom row is the reformulated kernels.
Details or Artifacts: A Locally Discriminative Learning Approach to Realistic Image Super-Resolution
会议:CVPR 2022 · 主会论文
Figure 6 · PDF第5页 · P122
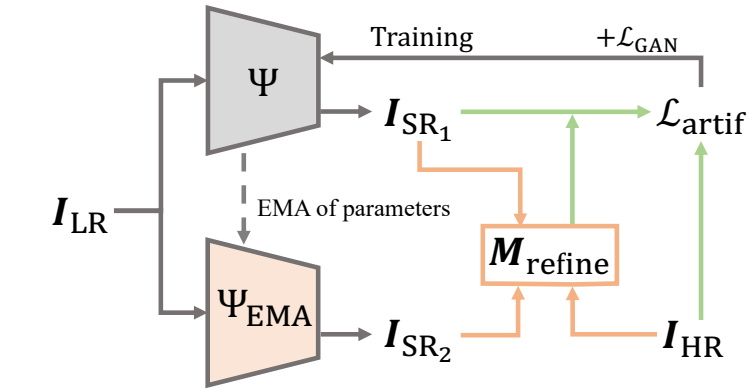
300 dpi PNG · 图注 · 源PDF
第3.3节明确把图6称整体学习流程,包含输入、模型和EMA分支、伪影图、损失与参数更新。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-17;arXiv v1:2022-03-17;CVPR 2022 fixed official PDF
固定会议PDF与arXiv v1目标图按对应坐标逐图比对;像素均差为0;arXiv v1与已知会议投稿均在指定阶段。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[329, 341, 509, 435],PDF点、左上角原点。
Figure 6. Overall learning pipeline of the proposed LDL method.
Details or Artifacts: A Locally Discriminative Learning Approach to Realistic Image Super-Resolution
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P121
300 dpi PNG · 图注 · 源PDF
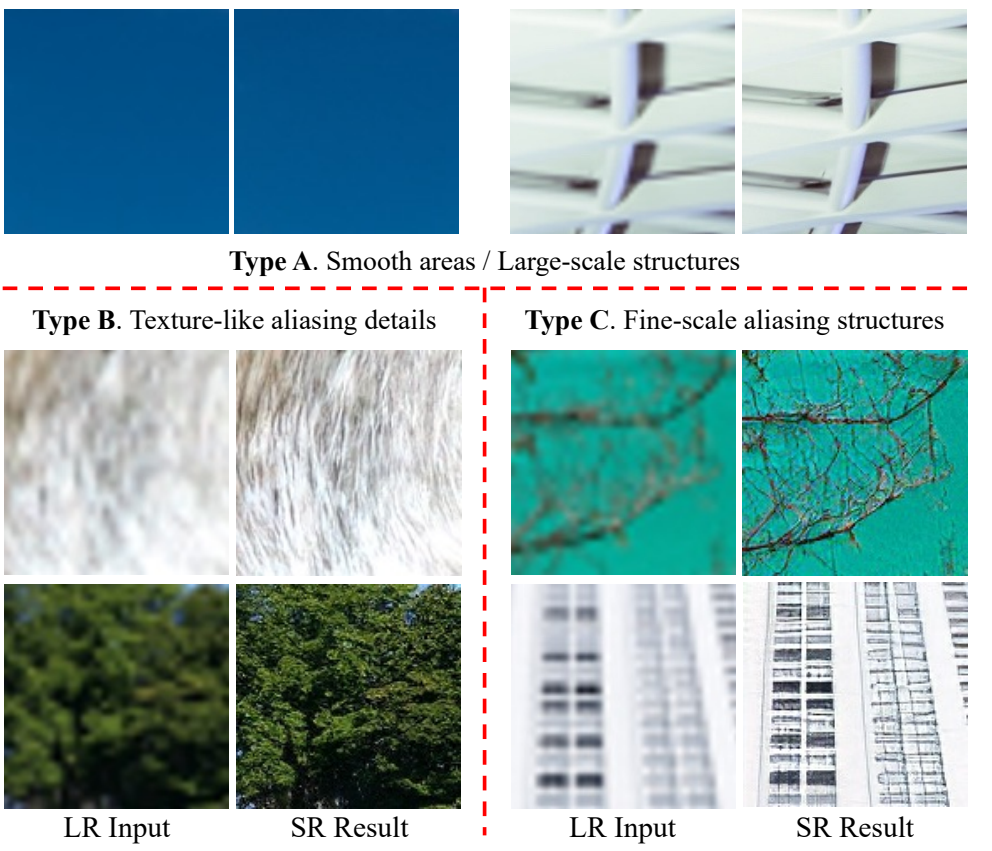
引言以图1区分平滑区域、随机纹理和细结构三类图像块,解释GAN超分辨率在C类出现不自然伪影的失败机制;并非一般结果拼图。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-17;arXiv v1:2022-03-17;CVPR 2022 fixed official PDF
固定会议PDF与arXiv v1目标图按对应坐标逐图比对;像素均差为0;arXiv v1与已知会议投稿均在指定阶段。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[309, 231, 547, 435],PDF点、左上角原点。
Figure 1. Three representative types of SISR regions generated by
ESRGAN [40]. For each example, the left is an LR patch and the
right is its GAN-SR result. Type A patches represent regions that
are easy to super-resolve, e.g., smooth and large-scale structural
areas, where the main structures are preserved in the LR input. In
contrast, patches of type B and type C are with fine-scale details,
which are hard to be faithfully restored due to the signal alias-
ing in the LR inputs. The results of texture-like type B patches
are perceptually realistic despite the pixel-wise differences to the
ground-truth, since the patterns are naturally irregular with weak
priorsforobservers. However,theresultsoftypeCpatchesexhibit
perceptually unpleasant visual artifacts since the overshoot pixels
and distorted structures are sensitive to human perception.
Dual Adversarial Adaptation for Cross-Device Real-World Image Super-Resolution
会议:CVPR 2022 · 主会论文
Figure 5 · PDF第4页 · P210
300 dpi PNG · 图注 · 源PDF
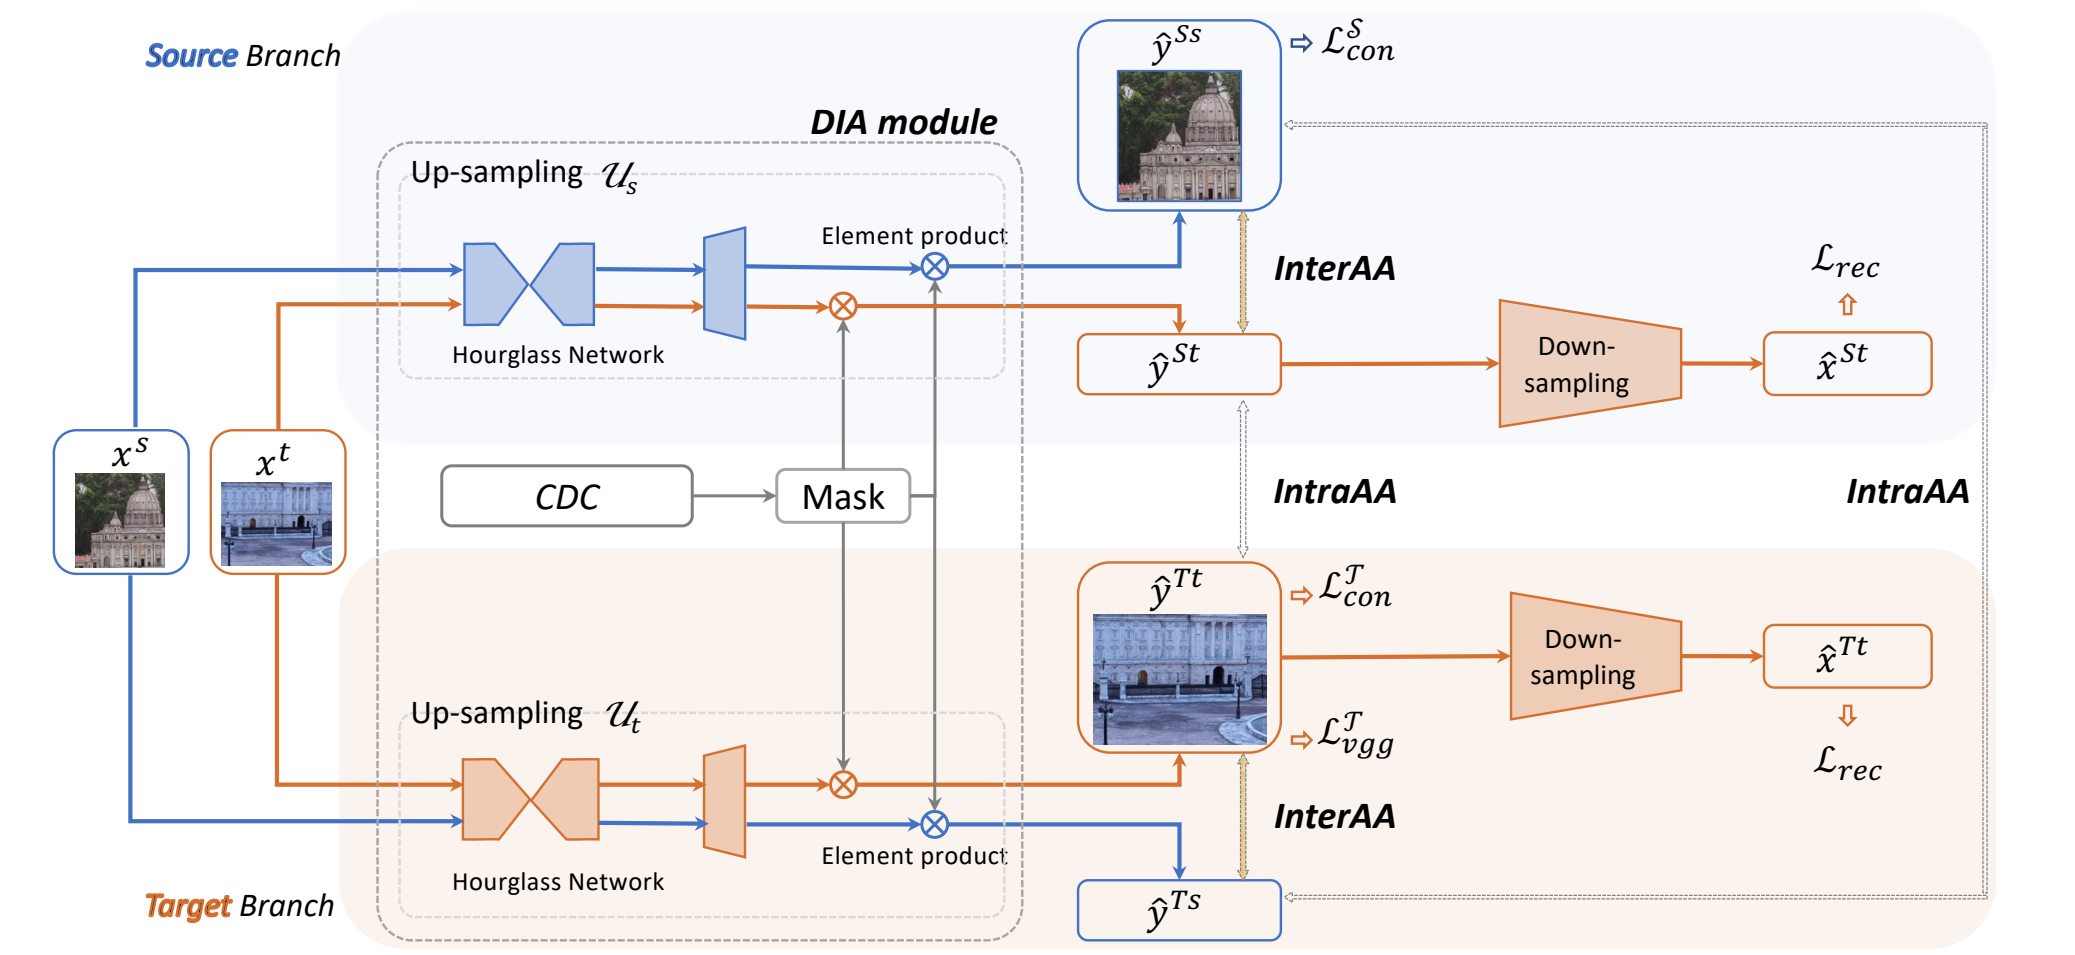
图5为DADA整体双分支训练框架,含源域/目标域循环重建、域内及域间对抗适配与测试路径说明。
完整图注、版本和筛选证据
最早核实视觉日期:2022-05-07;arXiv v1:2022-05-07;CVPR 2022 fixed official PDF
固定会议PDF与arXiv v1的目标图已对照;构图、配色、标签和连线一致。已在固定PDF首页及公开作者引用主页核对作者身份和机构。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Liang Lin;51769;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[50, 70, 548, 299],PDF点、左上角原点。
Figure 5. The proposed framework of our DADA. It includes a source branch and a target branch, both of which have an LR-HR-LR
reconstruction structure. In their up-sampling networks, a Domain-Invariant Attention (DIA) module provides component attentive masks
by a pre-trained CDC model. For InterAA, two LR images from different domains are fed into the up-sampling network for adversarial
adaptation in one branch. For IntraAA, one LR image is respectively fed into up-sampling networks in source and target branches for the
adversarial adaptation. For testing, the trained up-sampling network in target branch is utilized for inference.
Dual Adversarial Adaptation for Cross-Device Real-World Image Super-Resolution
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P209
300 dpi PNG · 图注 · 源PDF
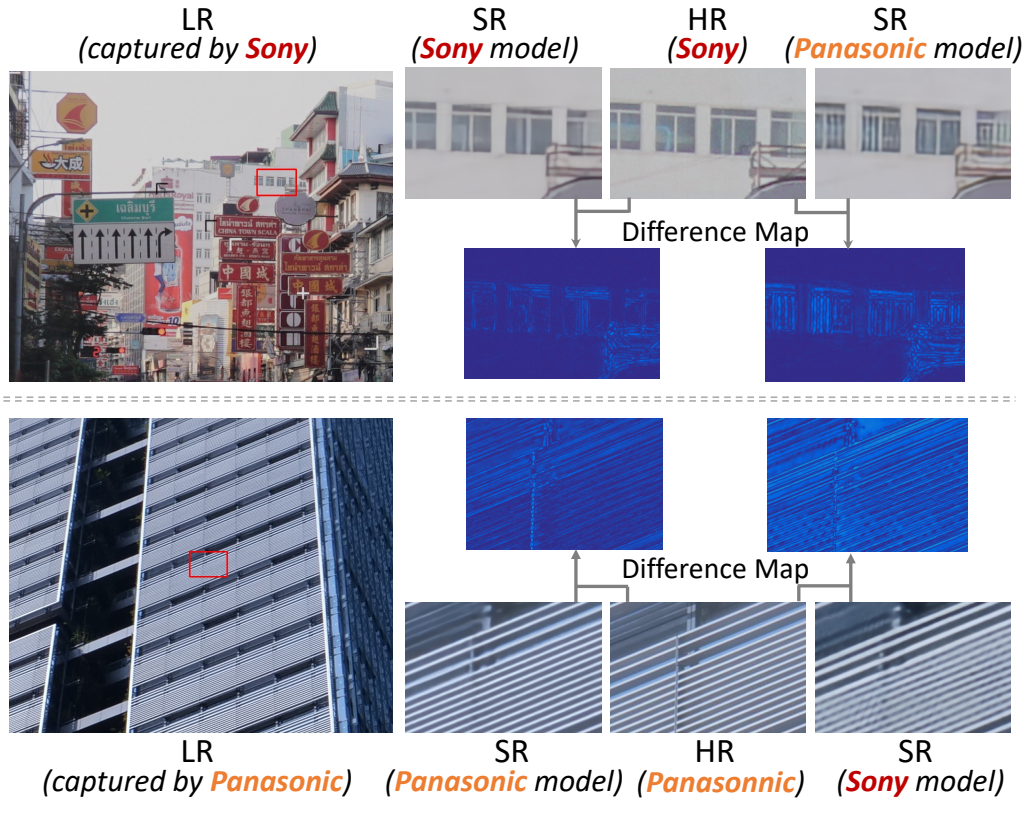
引言明确以图1展示跨设备域差异:同一SR模型在异品牌相机图像上出现模糊、伪影及较大误差,是引出新问题的失败案例。
完整图注、版本和筛选证据
最早核实视觉日期:2022-05-07;arXiv v1:2022-05-07;CVPR 2022 fixed official PDF
固定会议PDF与arXiv v1的目标图已对照;构图、配色、标签和连线一致。已在固定PDF首页及公开作者引用主页核对作者身份和机构。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Liang Lin;51769;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[309, 219, 555, 415],PDF点、左上角原点。
Figure 1. Comparison of real SR results across different trained
models from different camera data in the DRealSR dataset [18].
The Difference Map denotes the absolute difference between
ground-truth HR and SR image (The brightness in the map reflects
the magnitude of the difference).
Dual Pixel Exploration: Simultaneous Depth Estimation and Image Restoration
会议:CVPR 2021 · 主会论文
Figure 5 · PDF第5页 · P328
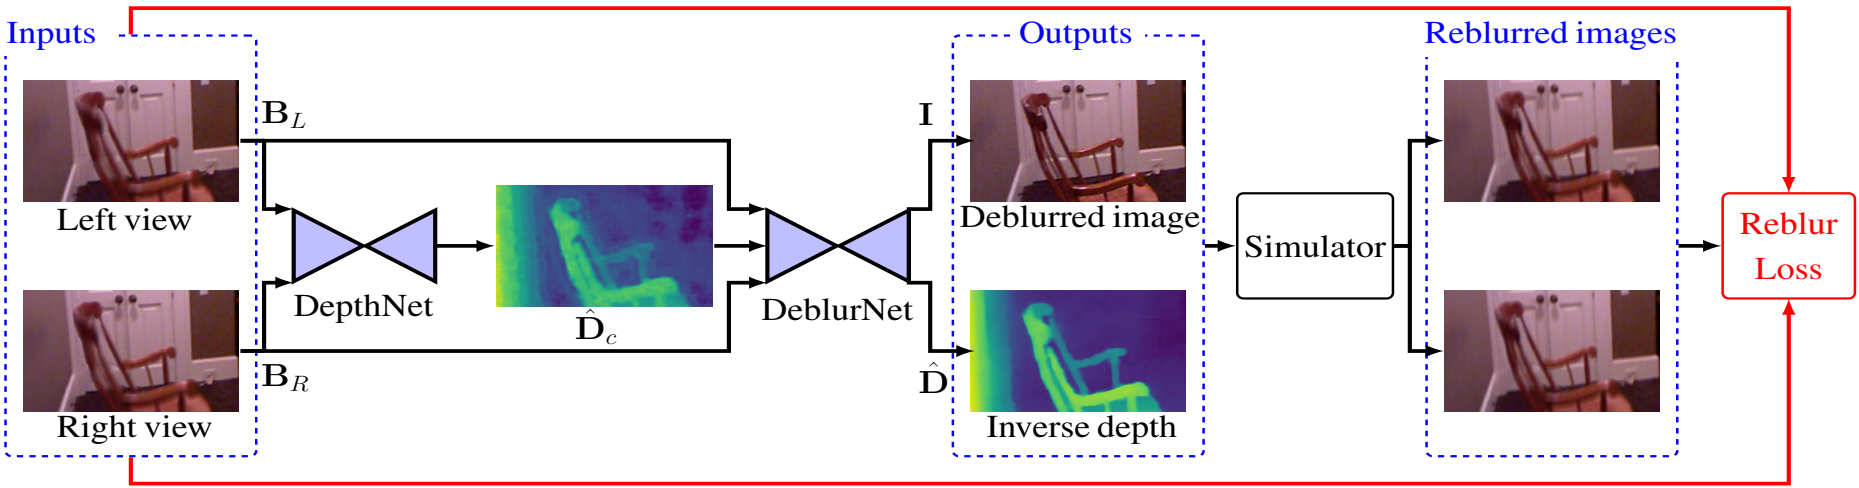
300 dpi PNG · 图注 · 源PDF
图5为完整DDDNet深度估计、去模糊与重模糊监督的端到端框架。
完整图注、版本和筛选证据
最早核实视觉日期:2021-06;arXiv v1:2020-12-01;CVPR 2021 fixed official PDF
已逐图对照arXiv v1与CVPR固定PDF。DASR图1会议版移除左侧统计图;DDDNet图5标签位置及构图比例有改动。其余图同样存在缩放/排版变化,保守使用CVF书目明确的2021-06固定版公开月份,不将重排或重绘版本倒溯至v1。真实作图日期未知;v1至会议公开均处S1。作者单位/邮箱已核对;Shuhang Gu的ETH历史任职由本人主页佐证。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Hongdong Li;33685;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[75, 55, 521, 172],PDF点、左上角原点。
Figure 5. The architecture of the proposed DDDNet. With the input DP image pair, the DepthNet first estimates a coarse inverse depth map
Dˆ . Then, we combine the coarse and blurred inverse depth map with B , and feed them to the DeblurNet. The deblurred image and
c {L,R}
estimated inverse depth map are fed to our DP simulator to synthesize a DP image pair. The synthesized DP images are compared to the
inputs using our reblur loss (Eq. (11)), to regularise the DDDNet in training. Note that, the ground truth inverse depth maps and sharp
images are used as supervision signals in training. (Best viewed in colour on screen.)Dual Pixel Exploration: Simultaneous Depth Estimation and Image Restoration
会议:CVPR 2021 · 主会论文
Figure 2 · PDF第3页 · P327
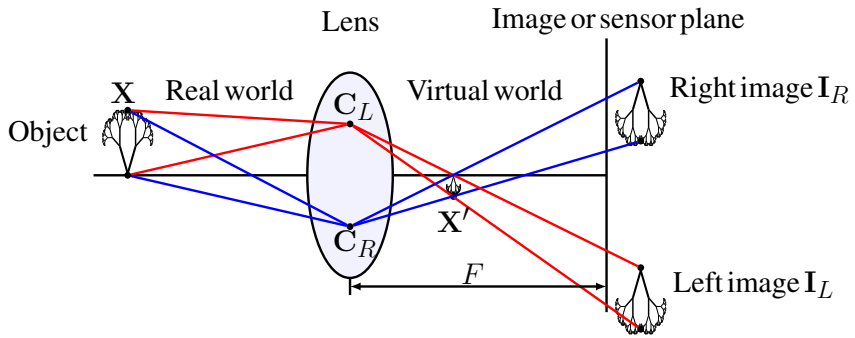
300 dpi PNG · 图注 · 源PDF
图2通过双像素成像模型说明离焦模糊与深度的关系,正文3.1节用于解释问题形成及方法动机。
完整图注、版本和筛选证据
最早核实视觉日期:2021-06;arXiv v1:2020-12-01;CVPR 2021 fixed official PDF
已逐图对照arXiv v1与CVPR固定PDF。DASR图1会议版移除左侧统计图;DDDNet图5标签位置及构图比例有改动。其余图同样存在缩放/排版变化,保守使用CVF书目明确的2021-06固定版公开月份,不将重排或重绘版本倒溯至v1。真实作图日期未知;v1至会议公开均处S1。作者单位/邮箱已核对;Shuhang Gu的ETH历史任职由本人主页佐证。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Hongdong Li;33685;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[64, 73, 269, 154],PDF点、左上角原点。
Figure 2. Formation of the two image I and I from two points
L R
C and C on the lens plane may be thought of as pin-hole pro-
L R
jections (with centres C L and C R and focal-length F ) of the vir-
tual image formed by the lens.
Exploring and Evaluating Image Restoration Potential in Dynamic Scenes
会议:CVPR 2022 · 主会论文
Figure 5 · PDF第5页 · P208
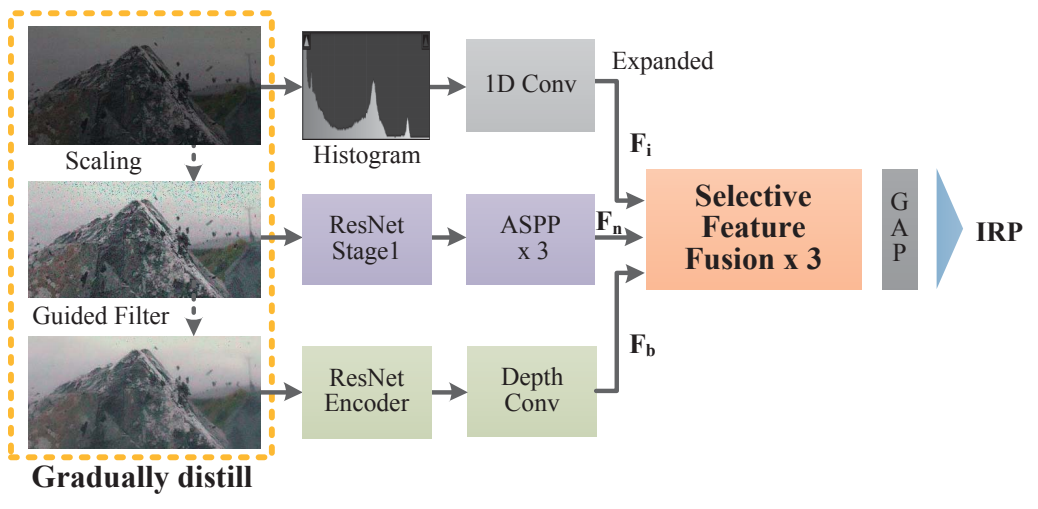
300 dpi PNG · 图注 · 源PDF
第4节及图5展示IRP预测完整路径:渐进分离退化因素、三路特征提取、选择性融合与IRP回归。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-22;arXiv v1:2022-03-22;CVPR 2022 fixed official PDF
固定会议PDF与arXiv v1的目标图已对照;构图、配色、标签和连线一致。已在固定PDF首页及公开作者引用主页核对作者身份和机构。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yanning Zhang;20703;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[308, 72, 557, 194],PDF点、左上角原点。
Figure 5. The proposed model architecture for IRP prediction.
Exploring and Evaluating Image Restoration Potential in Dynamic Scenes
会议:CVPR 2022 · 主会论文
Figure 1 · PDF第1页 · P207
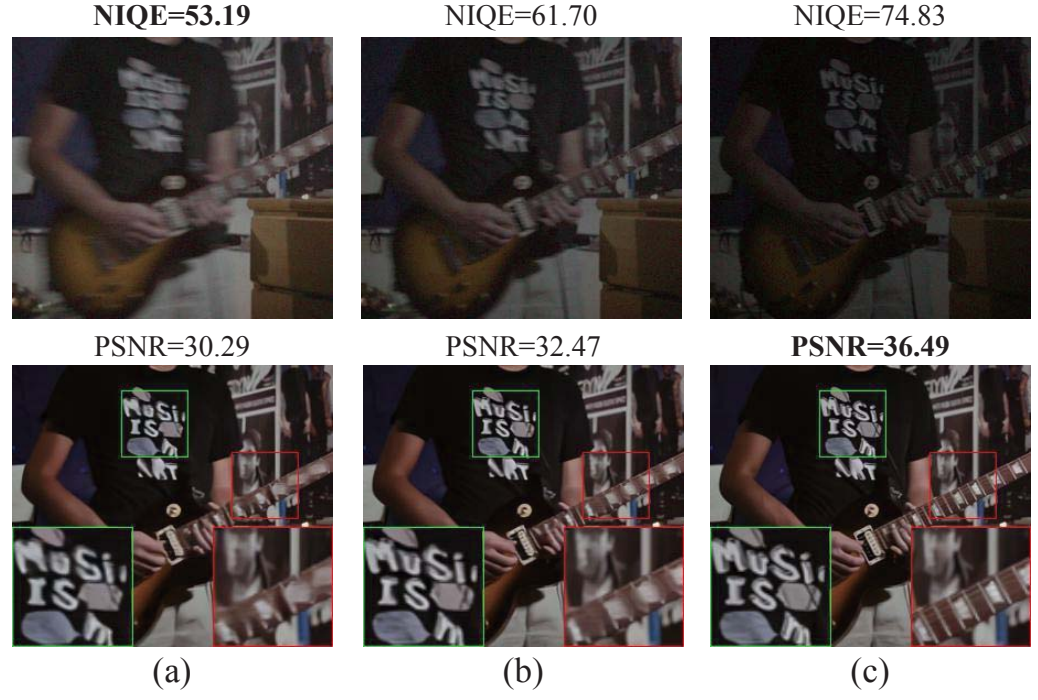
300 dpi PNG · 图注 · 源PDF
引言与图1说明看起来质量较好的输入不一定得到较好的复原结果,是传统视觉质量评估与复原潜力不一致的反例。
完整图注、版本和筛选证据
最早核实视觉日期:2022-03-22;arXiv v1:2022-03-22;CVPR 2022 fixed official PDF
固定会议PDF与arXiv v1的目标图已对照;构图、配色、标签和连线一致。已在固定PDF首页及公开作者引用主页核对作者身份和机构。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yanning Zhang;20703;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[308, 230, 557, 398],PDF点、左上角原点。
Figure 1. We show how the proposed concept IRP differs from
the traditional image metric visual quality. Given a sequence of
images captured under varying exposures in dynamic scenes (first
row), both IQA metric NIQE [23] and human observers favorite
either (a) or (b) as relatively good shots, but they do not neces-
sarily lead to better restored results (second row). As a compari-
son, a perceptually poor image (c) leads to the best restored image
quality. The result indicates the necessity of developing the IRP
metric which predicts if the restored image quality will be good
even before it is processed. All images are processed by the same
restoration model MPR [40] to ensure fairness.
SRWarp: Generalized Image Super-Resolution under Arbitrary Transformation
会议:CVPR 2021 · 主会论文
Figure 4 · PDF第5页 · P266
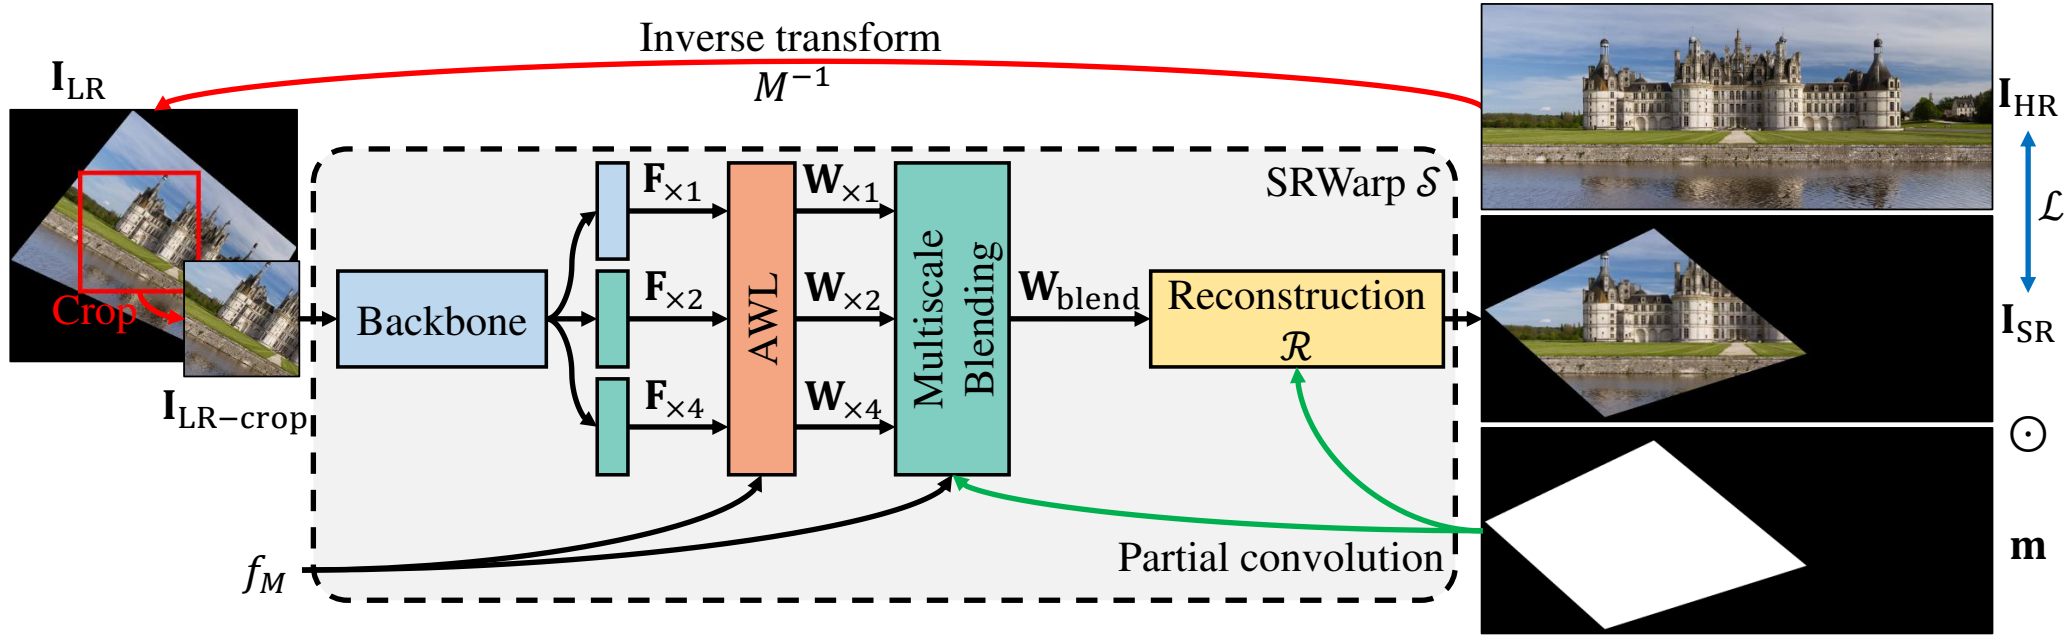
300 dpi PNG · 图注 · 源PDF
图4明确为SRWarp整体组织,展示多尺度提取、特征变换、融合与输出计算路径。
完整图注、版本和筛选证据
最早核实视觉日期:2021-04-21;arXiv v1:2021-04-21;CVPR 2021 fixed official PDF
已核对固定会议PDF与arXiv v1完整图页,未见目标图重绘;微小像素差源于PDF渲染。作者姓名与固定PDF单位、公开Scholar单位相符。已逐张查看300dpi导出、确认完整。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Kyoung Mu Lee;57875;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[49, 72, 546, 226],PDF点、左上角原点。
Figure 4: Overall organization of the proposed SRWarp model. More detailed architectures are described in our supplementary material. Black regions outside the warped image I_SR represent void pixels that are ignored.
SRWarp: Generalized Image Super-Resolution under Arbitrary Transformation
会议:CVPR 2021 · 主会论文
Figure 2 · PDF第3页 · P265
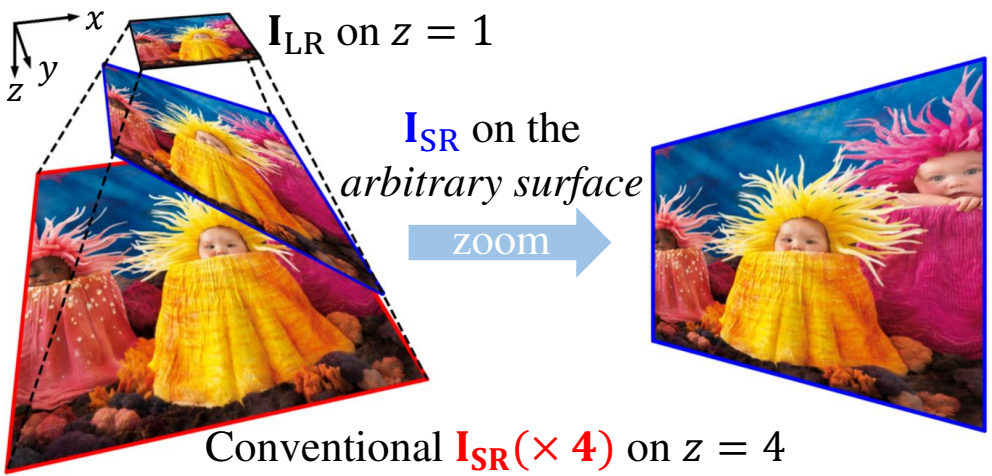
300 dpi PNG · 图注 · 源PDF
图2及第3节用图像金字塔对比固定倍率平面与任意变换曲面,说明传统超分辨率的任务限制。
完整图注、版本和筛选证据
最早核实视觉日期:2021-04-21;arXiv v1:2021-04-21;CVPR 2021 fixed official PDF
已核对固定会议PDF与arXiv v1完整图页,未见目标图重绘;微小像素差源于PDF渲染。作者姓名与固定PDF单位、公开Scholar单位相符。已逐张查看300dpi导出、确认完整。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Kyoung Mu Lee;57875;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[308, 70, 546, 184],PDF点、左上角原点。
Figure 2: Concept of the generalized SR. Dotted lines represent the upscale image pyramid in xyz-coordinate. While ×s super-resolved images from conventional methods (red) exist on the plane z = s only, our results (blue) exists on any arbitrary cutting surfaces of the pyramid. Note that the aspect ratio on the plane can be varied as well.
Unsupervised Real-world Image Super Resolution via Domain-distance Aware Training
会议:CVPR 2021 · 主会论文
Figure 2 · PDF第3页 · P326
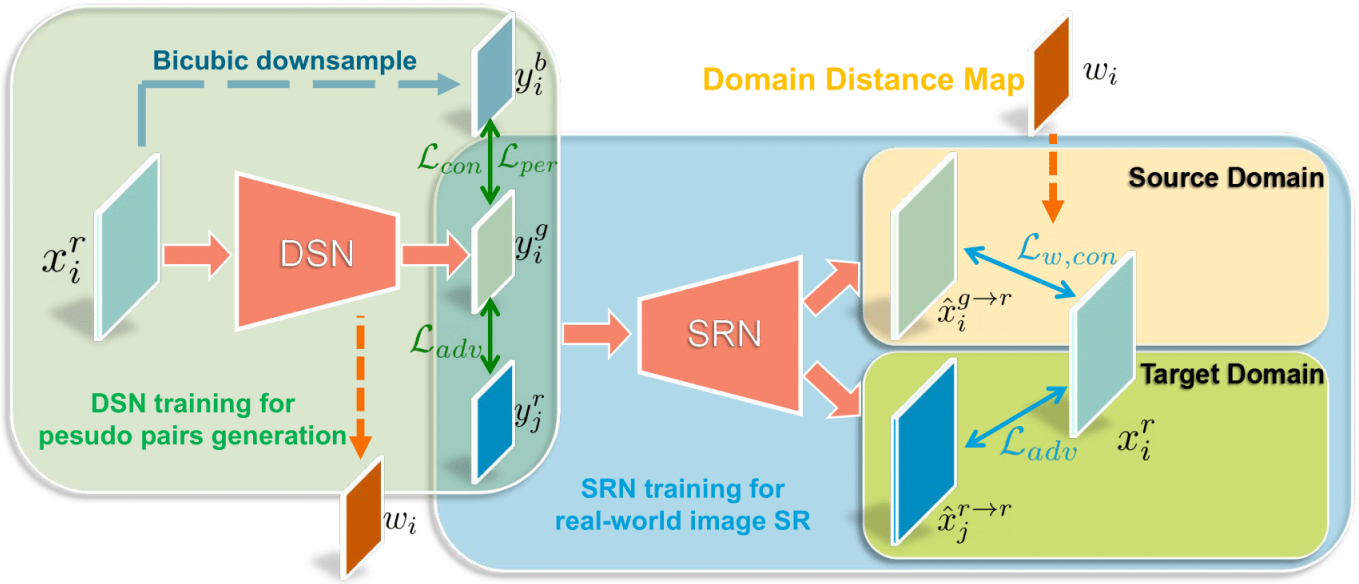
300 dpi PNG · 图注 · 源PDF
图2展示完整DASR训练与两类域距离监督路径。
完整图注、版本和筛选证据
最早核实视觉日期:2021-06;arXiv v1:2020-04-02;CVPR 2021 fixed official PDF
已逐图对照arXiv v1与CVPR固定PDF。DASR图1会议版移除左侧统计图;DDDNet图5标签位置及构图比例有改动。其余图同样存在缩放/排版变化,保守使用CVF书目明确的2021-06固定版公开月份,不将重排或重绘版本倒溯至v1。真实作图日期未知;v1至会议公开均处S1。作者单位/邮箱已核对;Shuhang Gu的ETH历史任职由本人主页佐证。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Shuhang Gu;21404;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[133, 73, 459, 213],PDF点、左上角原点。
Figure 2: Illustration of our DASR framework. DASR firstly trains a down-sampling network (DSN) which aims to generate
LR images y g in the real LR domain y r from HR images xr : y g = DS N (xr ). Then, DASR take the domain-gap between
generated LR images y g and real-world LR images y r into consideration, utilize the generated LR-HR pairs {y g , xr }, domain
distance maps w and real-world LR images y r to train super-resolution network (SRN).Unsupervised Real-world Image Super Resolution via Domain-distance Aware Training
会议:CVPR 2021 · 主会论文
Figure 1 · PDF第1页 · P325
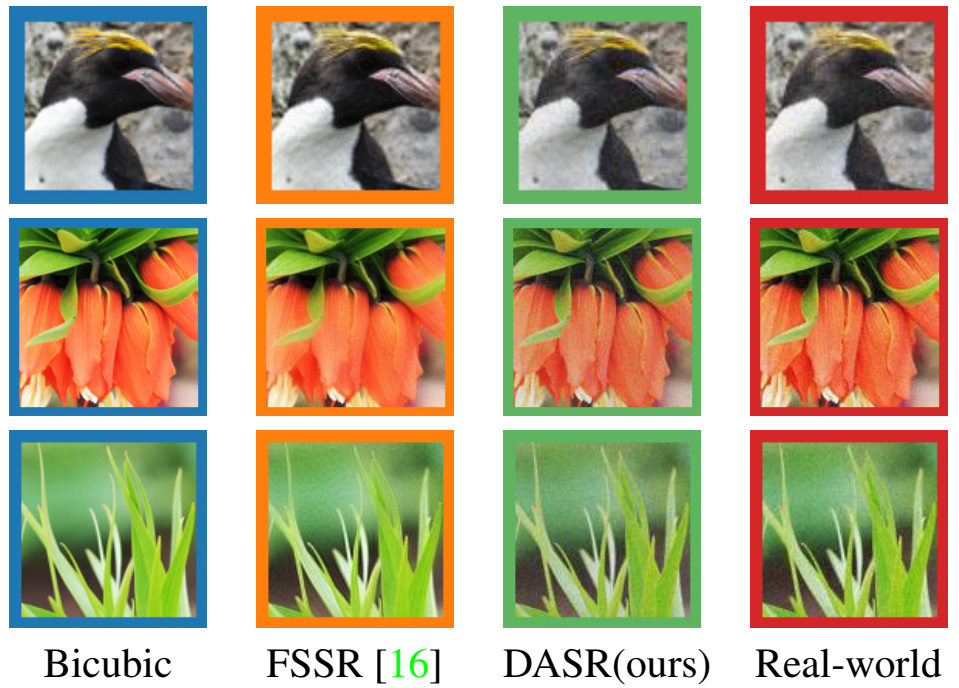
300 dpi PNG · 图注 · 源PDF
图1通过真实/合成低分辨率域差异及对应失败解释训练域差距;正文明确以此引出问题。
完整图注、版本和筛选证据
最早核实视觉日期:2021-06;arXiv v1:2020-04-02;CVPR 2021 fixed official PDF
已逐图对照arXiv v1与CVPR固定PDF。DASR图1会议版移除左侧统计图;DDDNet图5标签位置及构图比例有改动。其余图同样存在缩放/排版变化,保守使用CVF书目明确的2021-06固定版公开月份,不将重排或重绘版本倒溯至v1。真实作图日期未知;v1至会议公开均处S1。作者单位/邮箱已核对;Shuhang Gu的ETH历史任职由本人主页佐证。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Shuhang Gu;21404;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[312, 258, 542, 423],PDF点、左上角原点。
Figure 1: Visualization of the domain-gap between the gen-
erated LR images by different methods and LR images in
the AIM [40] dataset. More details can be found in our
main text.
Fostering Generalization in Single-view 3D Reconstruction by Learning a Hierarchy of Local and Global Shape Priors
会议:CVPR 2021 · 主会论文
Figure 3 · PDF第4页 · P164
300 dpi PNG · 图注 · 源PDF
第3.2节说明图3是完整Hierarchical Prior Network计算路径,多种尺度的局部/全局网络共同产生最终融合重建;图2仅是单个局部模块。
完整图注、版本和筛选证据
最早核实视觉日期:2021-04-01;arXiv v1:2021-04-01;CVPR 2021 fixed official PDF
已查看会议固定版与arXiv v1,目标图的构图、元素、连线、文字与颜色一致;存在排版平移或PDF渲染/压缩级别差异,无重绘证据。最早核实公开时间采用v1。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Thomas Brox;249461;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[50, 70, 287, 170],PDF点、左上角原点。
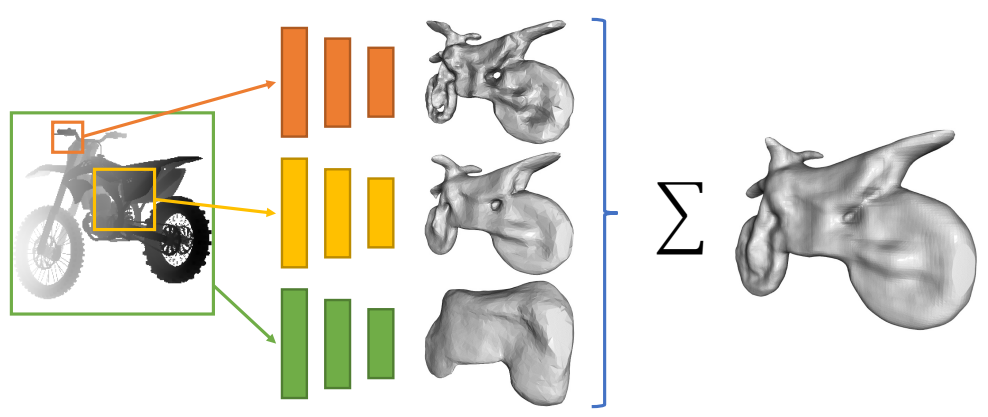
Figure 3. We use a hierarchy of networks operating on input
patches of different resolutions (including the global one) to pro-
duce multiple shape reconstruction variants. Those are fused by
simple averaging to yield the final reconstruction.
Fostering Generalization in Single-view 3D Reconstruction by Learning a Hierarchy of Local and Global Shape Priors
会议:CVPR 2021 · 主会论文
Figure 1 · PDF第1页 · P163
300 dpi PNG · 图注 · 源PDF
引言明确以两把椅子的图1说明已见过椅子却不能组合的全局形状先验失败,并据此提出层级局部先验。
完整图注、版本和筛选证据
最早核实视觉日期:2021-04-01;arXiv v1:2021-04-01;CVPR 2021 fixed official PDF
已查看会议固定版与arXiv v1,目标图的构图、元素、连线、文字与颜色一致;存在排版平移或PDF渲染/压缩级别差异,无重绘证据。最早核实公开时间采用v1。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Thomas Brox;249461;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[311, 244, 545, 455],PDF点、左上角原点。
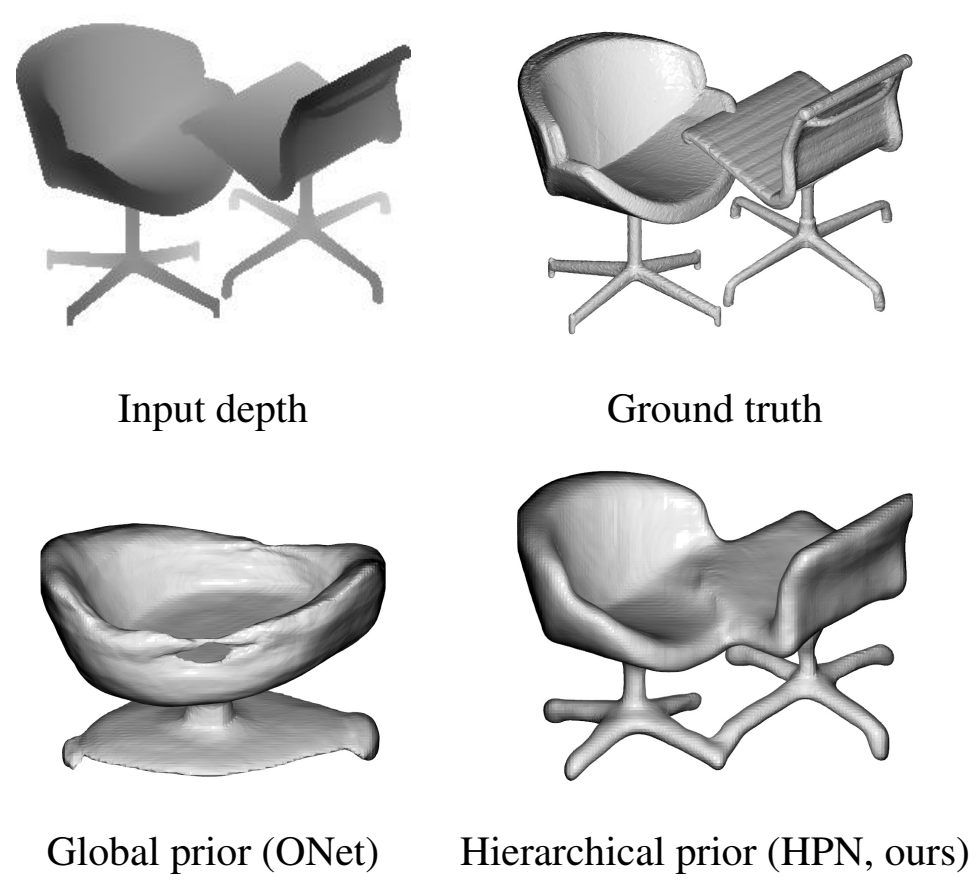
Figure 1. We employ a hierarchical shape prior to enable recom-
bination of partial shapes observed during training. This signif-
icantly improves generalization compared to conventional global
shape priors.
From Points to Multi-Object 3D Reconstruction
会议:CVPR 2021 · 主会论文
Figure 2 · PDF第2页 · P230
300 dpi PNG · 图注 · 源PDF
图2明确为Overview of the proposed approach,含输入、特征骨干、中心热图、形状选择、9DoF框与碰撞约束到三维输出。
完整图注、版本和筛选证据
最早核实视觉日期:2020-12-21;arXiv v1:2020-12-21;CVPR 2021 fixed official PDF
固定PDF图注、正文引用段落及作者单位已核验。导出完整图区域保留文字符号,300dpi与历史裁剪已逐张目检。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Bastian Leibe;44197;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[49, 70, 548, 182],PDF点、左上角原点。
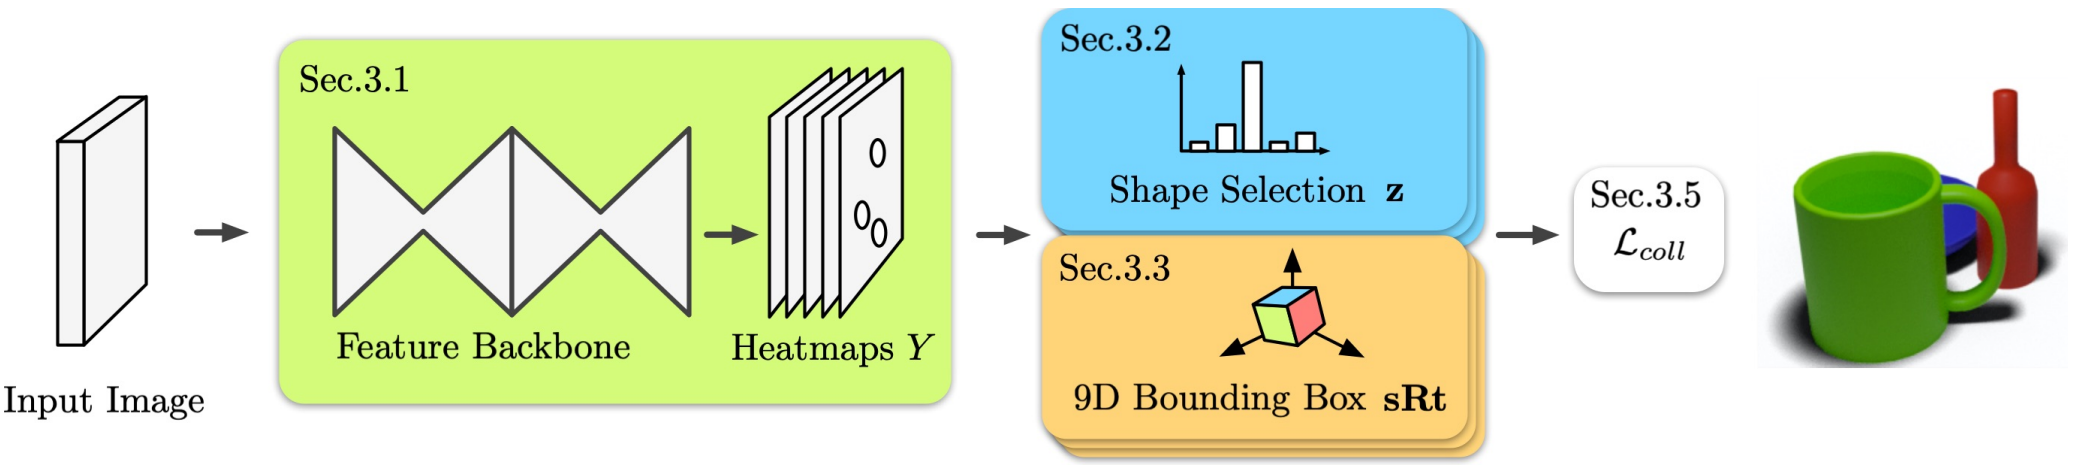
Figure 2: Overview of the proposed approach. Given a single RGB image, our model detects object centers as key-points in a heatmap Y .
The network directly predicts shape exemplars z and 9-DoF bounding boxes jointly for all objects in the scene. The collision loss L
coll
favors non-intersecting reconstructions. Our method predicts lightweight, realistic and physically plausible reconstructions in a single pass.
From Points to Multi-Object 3D Reconstruction
会议:CVPR 2021 · 主会论文
Figure 4 · PDF第4页 · P229
300 dpi PNG · 图注 · 源PDF
图4和第3.2节对比硬标签与软标签监督的概念分布;正文明确指出几何相似形状接受相互冲突的硬标签这一问题,图中柱高不是模型性能。
完整图注、版本和筛选证据
最早核实视觉日期:2021-06;arXiv v1:2020-12-21;CVPR 2021 fixed official PDF
已核查arXiv v1(2020-12-21)、v2(2021-04-07)、v3(2021-06-21):三者M的文字字形/渲染均不同于固定会议图;概念构图相同。故保守使用CVF官方Bibtex公开月份2021-06,明确月份精度,未推断确切首发日。三版裁剪及会议导出已查看。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Bastian Leibe;44197;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 73, 280, 142],PDF点、左上角原点。
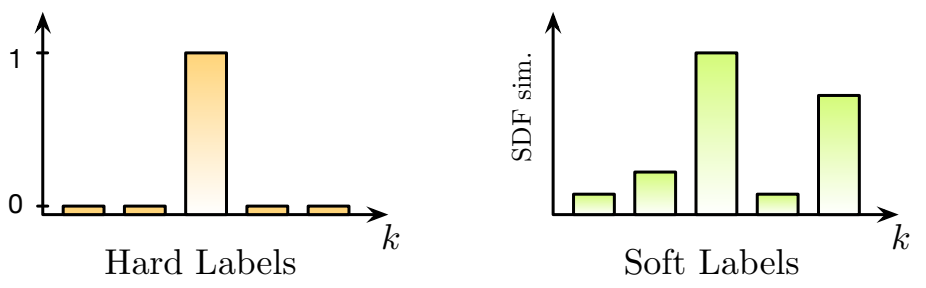
Figure 4: Shape selection. We compare one-hot encoding (hard
labels, left) for supervising the shape selection problem with soft
labels (right) which allow for multiple shape predictions at the
same time and are based on geometric similarity, specifically the
Euclidian distance between SDF shape representations.
Learning View Priors for Single-view 3D Reconstruction
会议:CVPR 2019 · 主会论文
Figure 2 · PDF第3页 · P162
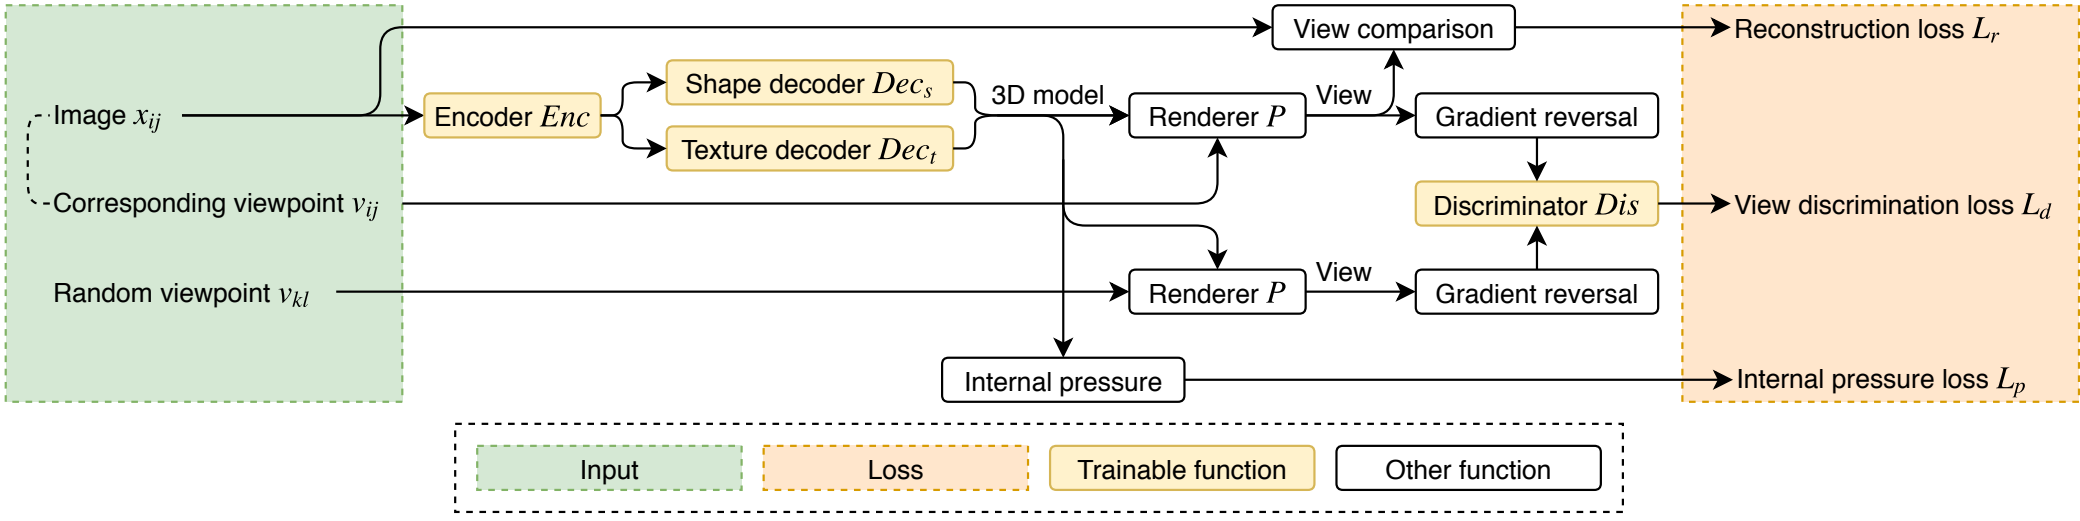
300 dpi PNG · 图注 · 源PDF
图2为完整视图先验训练架构,保留输入、编码器、形状/纹理解码器、渲染器、判别器与三项损失。
完整图注、版本和筛选证据
最早核实视觉日期:2018-11-26;arXiv v1:2018-11-26;CVPR 2019 fixed official PDF
已查看会议固定版与arXiv v1,目标图的构图、元素、连线、文字与颜色一致;存在排版平移或PDF渲染/压缩级别差异,无重绘证据。最早核实公开时间采用v1。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Tatsuya Harada;24085;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[49, 72, 548, 197],PDF点、左上角原点。
Figure 2. Architecture of the proposed method. The main point of our method is the use of discrimination loss to learn priors of views.
While the discriminator aims to minimize discrimination loss, the encoder and decoders try to maximize it using a gradient reversal layer.
Learning View Priors for Single-view 3D Reconstruction
会议:CVPR 2019 · 主会论文
Figure 1 · PDF第1页 · P161
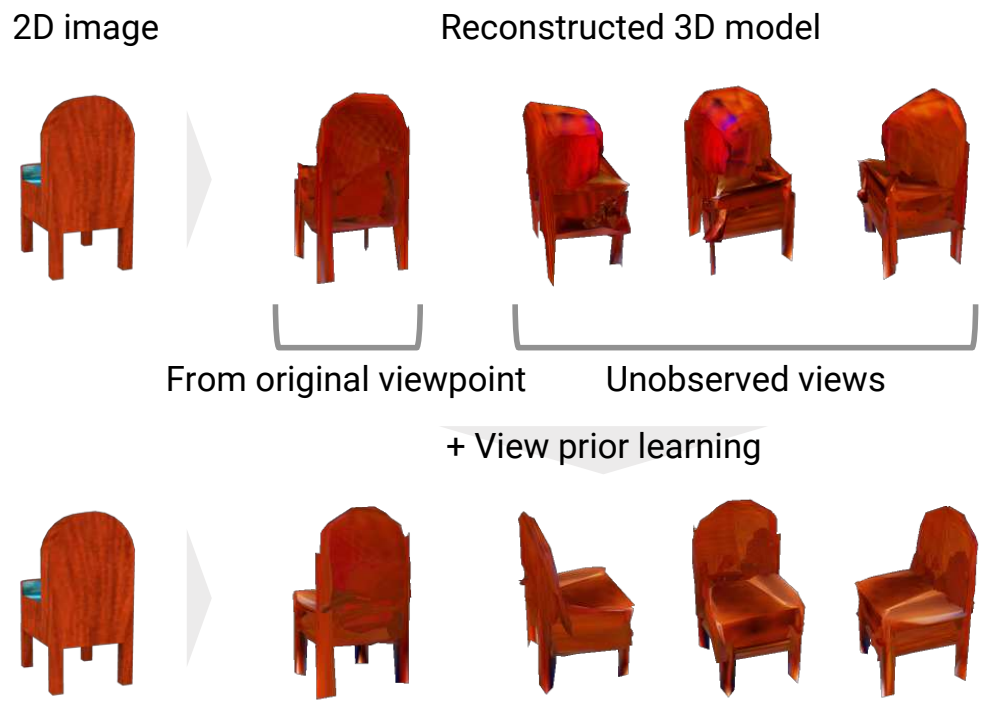
300 dpi PNG · 图注 · 源PDF
引言用图1说明单视图监督造成不可见视点形状歧义,上下两行及视点括号明确说明失败与视图先验的关系。
完整图注、版本和筛选证据
最早核实视觉日期:2018-11-26;arXiv v1:2018-11-26;CVPR 2019 fixed official PDF
已查看会议固定版与arXiv v1,目标图的构图、元素、连线、文字与颜色一致;存在排版平移或PDF渲染/压缩级别差异,无重绘证据。最早核实公开时间采用v1。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Tatsuya Harada;24085;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[309, 214, 546, 384],PDF点、左上角原点。
Figure 1. When a 3D reconstructor is trained using only a single
viewperobject,becauseofambiguityinthe3Dshapeofanobject,
itreconstructsashape whichonly fitsthe observedview andlooks
incorrect from unobserved viewpoints (upper). By introducing a
discriminator that learns prior knowledge of correct views, the re-
constructor is able to generate a shape that is viewed as reasonable
from any viewpoint (lower).
NeuralRecon: Real-Time Coherent 3D Reconstruction from Monocular Video
会议:CVPR 2021 · 主会论文
Figure 2 · PDF第3页 · P166
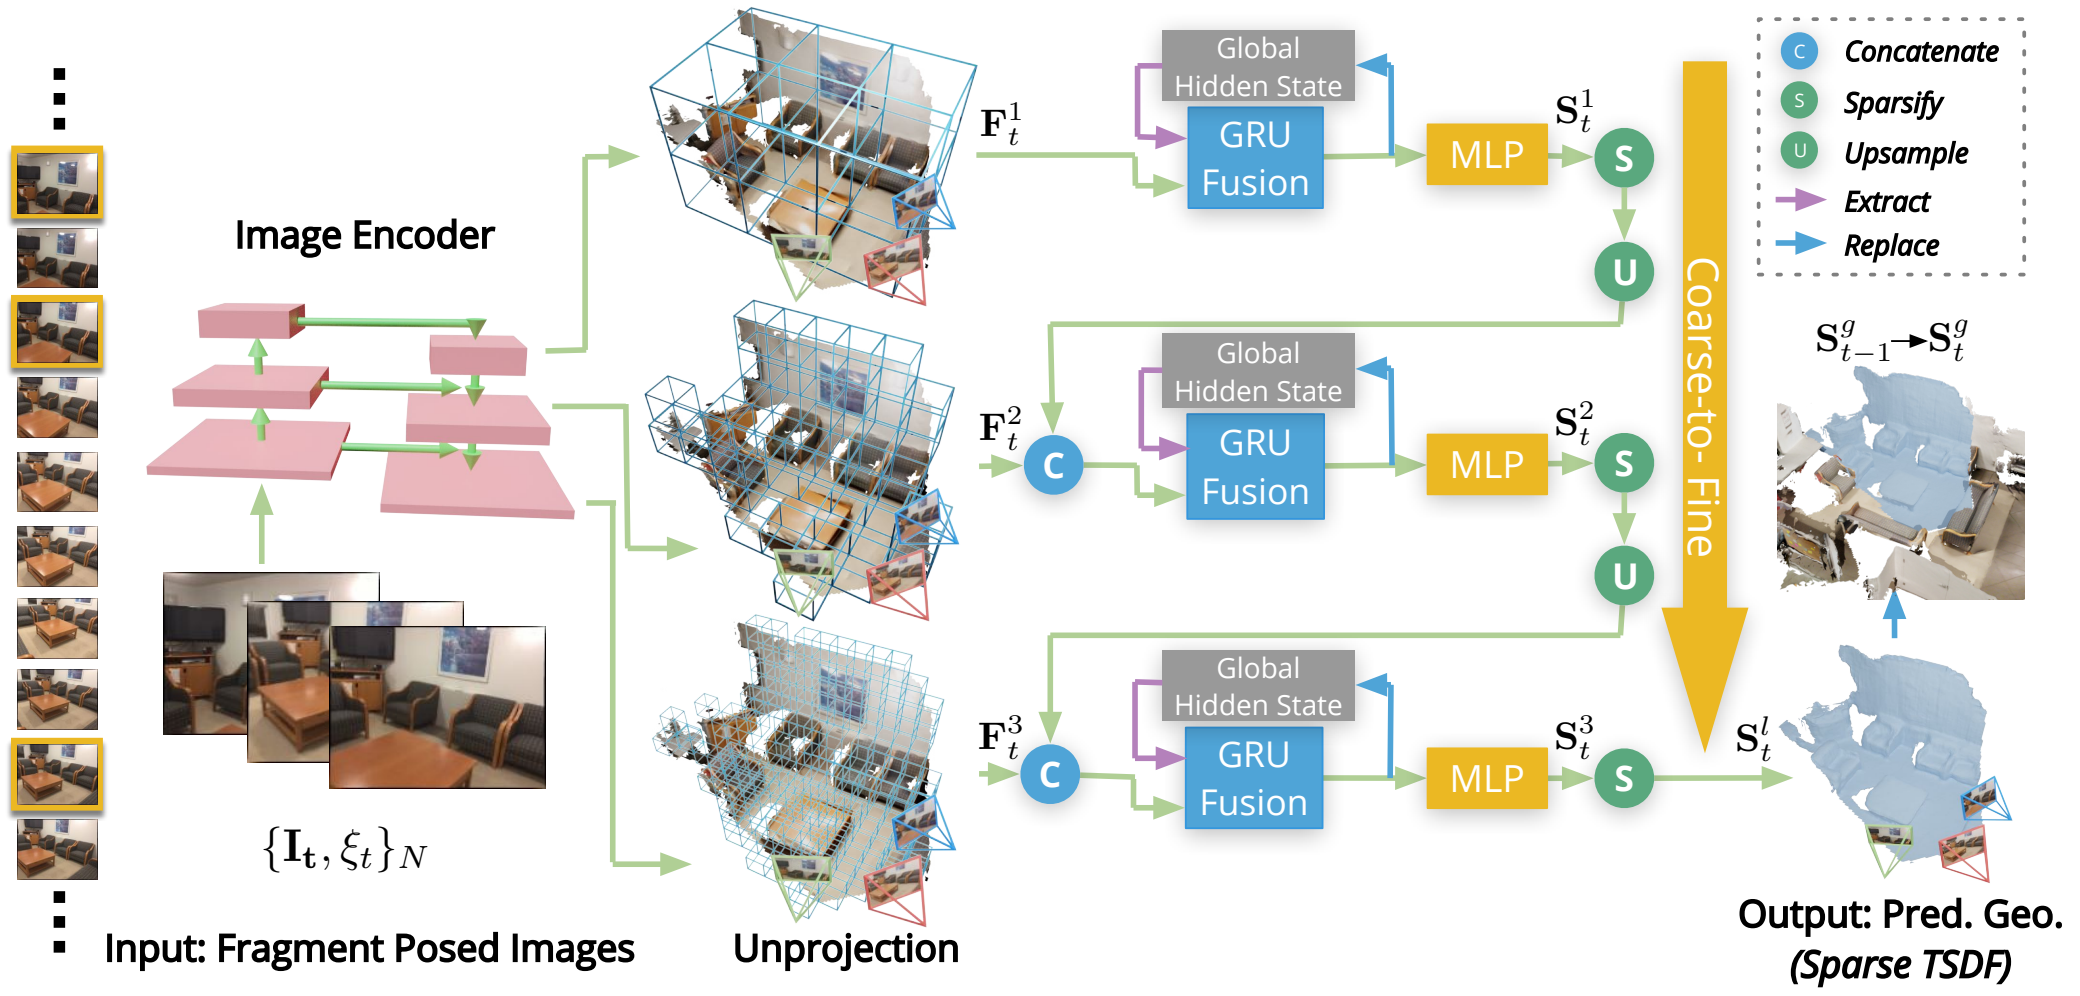
300 dpi PNG · 图注 · 源PDF
第3节将图2明确称为system architecture,包含输入片段、图像编码、多级反投影、GRU融合、MLP和全局TSDF更新。
完整图注、版本和筛选证据
最早核实视觉日期:2021-04-01;arXiv v1:2021-04-01;CVPR 2021 fixed official PDF
已查看会议固定版与arXiv v1,目标图的构图、元素、连线、文字与颜色一致;存在排版平移或PDF渲染/压缩级别差异,无重绘证据。最早核实公开时间采用v1。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Xiaowei Zhou;25061;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[49, 41, 548, 280],PDF点、左上角原点。
Figure 2. NeuralRecon architecture. NeuralRecon predicts TSDF with a three-level coarse-to-fine approach that gradually increases the
density of sparse voxels. Key-frame images in the local fragment are first passed through the image backbone to extract the multi-level
features. These image features are later back-projected along each ray and aggregated into a 3D feature volume Fl, where l represents the
t
level index. At the first level (l = 1), a dense TSDF volume S1 is predicted. At the second and third levels, the upsampled Sl−1 from the
t t
last level is concatenated with Fl and used as the input for the GRU Fusion and MLP modules. A feature volume defined in the world
t
frame is maintained at each level as the global hidden state of the GRU. At the last level, the output Sl is used to replace corresponding
t
voxels in the global TSDF volume Sg, yielding the final reconstruction at time t.
t
NeuralRecon: Real-Time Coherent 3D Reconstruction from Monocular Video
会议:CVPR 2021 · 主会论文
Figure 1 · PDF第1页 · P165
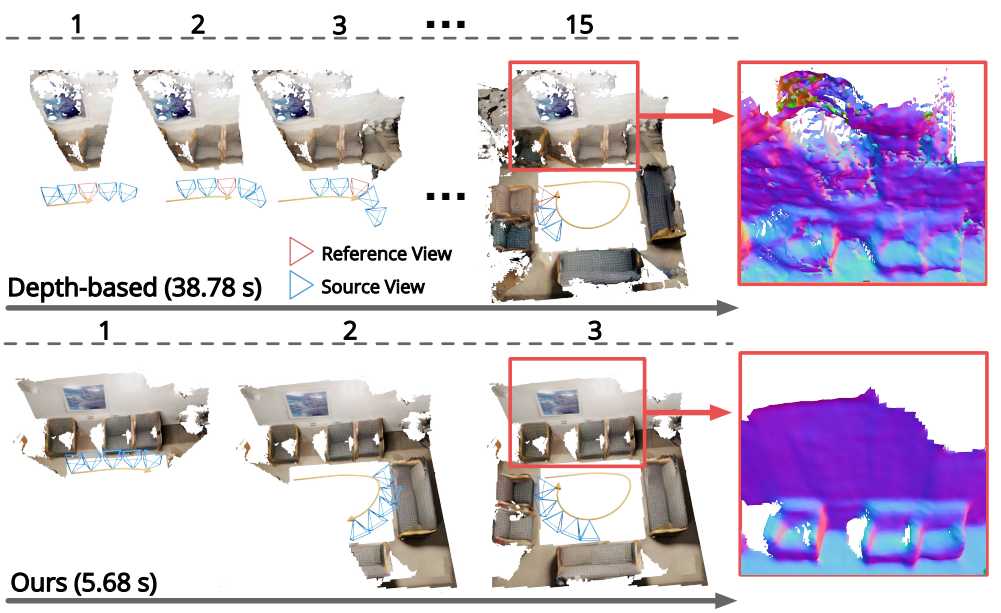
300 dpi PNG · 图注 · 源PDF
引言针对图1红框指出深度逐帧独立估计导致椅子与墙体不一致,并比较两种重建过程;是现有方法局限的概念对比。
完整图注、版本和筛选证据
最早核实视觉日期:2021-04-01;arXiv v1:2021-04-01;CVPR 2021 fixed official PDF
已查看会议固定版与arXiv v1,目标图的构图、元素、连线、文字与颜色一致;存在排版平移或PDF渲染/压缩级别差异,无重绘证据。最早核实公开时间采用v1。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Xiaowei Zhou;25061;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[308, 204, 548, 351],PDF点、左上角原点。
Figure1. Comparisonbetweendepth-based3Dreconstruction
methods and the proposed method. In depth-based methods,
key-frame depths are estimated separately from each key frame,
and later fused into a TSDF volume. In the proposed method, the
TSDF volume is directly predicted with all the key frames in a
local window. This design leads to a much more coherent recon-
struction and real-time speed.
Occupancy Networks: Learning 3D Reconstruction in Function Space
会议:CVPR 2019 · 主会论文
Figure 2 · PDF第4页 · P168
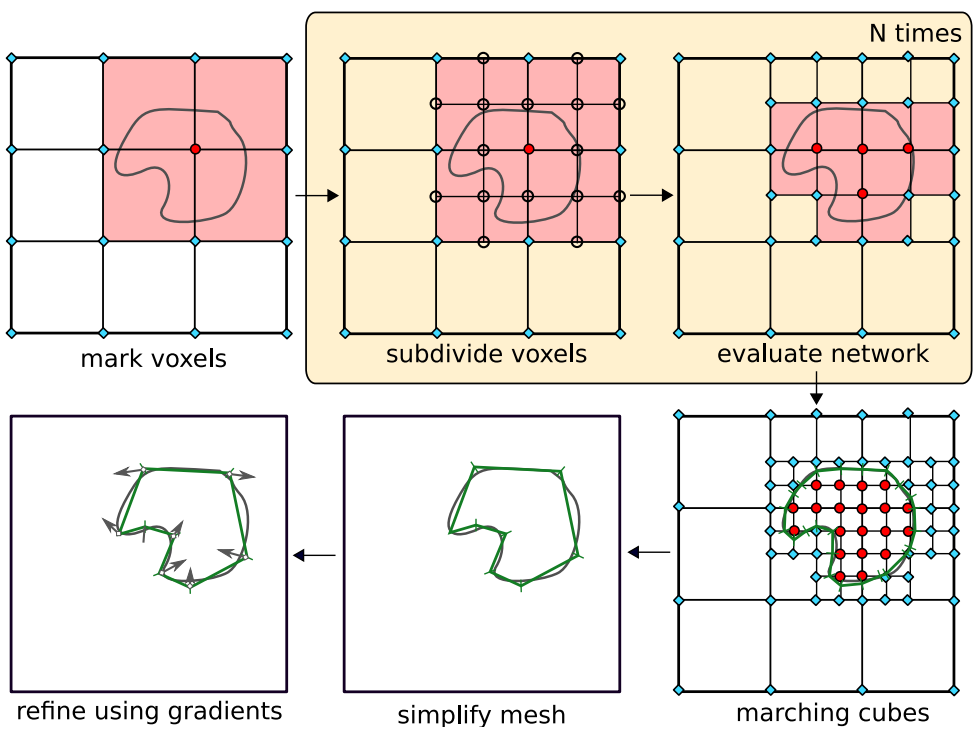
300 dpi PNG · 图注 · 源PDF
第3.3节Inference定义的完整MISE推理流程:网格标记、迭代细分、网络求值、Marching Cubes、简化与梯度细化,属于核心计算路径。
完整图注、版本和筛选证据
最早核实视觉日期:2018-12-10;arXiv v1:2018-12-10;CVPR 2019 fixed official PDF
已查看会议固定版与arXiv v1,目标图的构图、元素、连线、文字与颜色一致;存在排版平移或PDF渲染/压缩级别差异,无重绘证据。最早核实公开时间采用v1。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Andreas Geiger;110140;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[52, 75, 287, 250],PDF点、左上角原点。
Figure2: MultiresolutionIsoSurfaceExtraction: Wefirst
mark all points at a given resolution which have already
been evaluated as either occupied (red circles) or unoccu-
pied (cyan diamonds). We then determine all voxels that
have both occupied and unoccupied corners and mark them
as active (light red) and subdivide them into 8 subvoxels
each. Next, we evaluate all new grid points (empty circles)
that have been introduced by the subdivision. The previous
two steps are repeated until the desired output resolution is
reached. Finally we extract the mesh using the marching
cubes algorithm [44], simplify and refine the output mesh
using first and second order gradient information.
Occupancy Networks: Learning 3D Reconstruction in Function Space
会议:CVPR 2019 · 主会论文
Figure 1 · PDF第1页 · P167
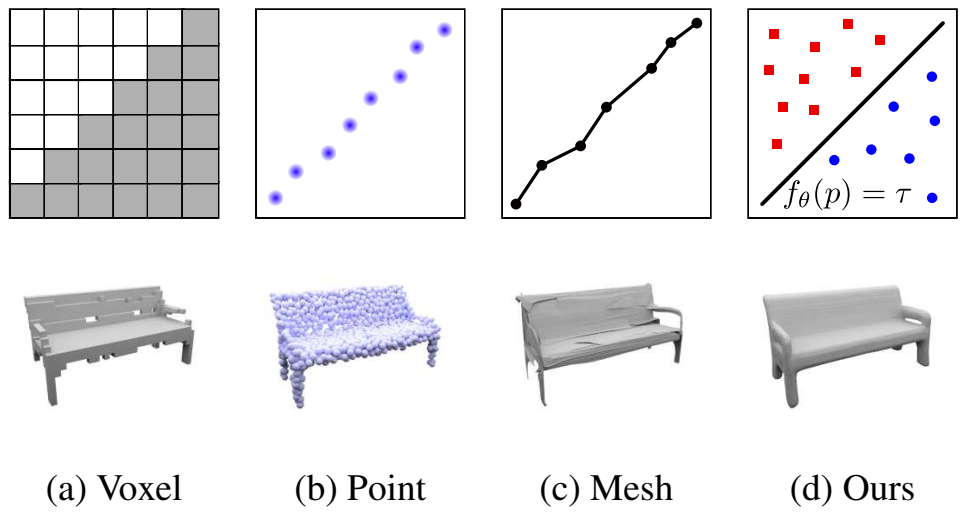
300 dpi PNG · 图注 · 源PDF
引言以图1概念性比较体素、点、网格与连续决策边界的表示差异,解释离散表示的分辨率、内存与拓扑局限。
完整图注、版本和筛选证据
最早核实视觉日期:2019-04-30;arXiv v1:2018-12-10;CVPR 2019 fixed official PDF
v1(2018-12-10)图1(c)的Mesh长椅实例与固定会议版不同;v2(2019-04-30)替换为与会议版相同长椅,按v2日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Andreas Geiger;110140;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[311, 241, 544, 364],PDF点、左上角原点。
Figure 1: Overview: Existing 3D representations discretize
the output space differently: (a) spatially in voxel represen-
tations, (b) in terms of predicted points, and (c) in terms of
vertices for mesh representations. In contrast, (d) we pro-
pose to consider the continuous decision boundary of a clas-
sifier f (e.g., a deep neural network) as a 3D surface which
θ
allows to extract 3D meshes at any resolution.
Photorealistic Monocular 3D Reconstruction of Humans Wearing Clothing
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第3页 · P242
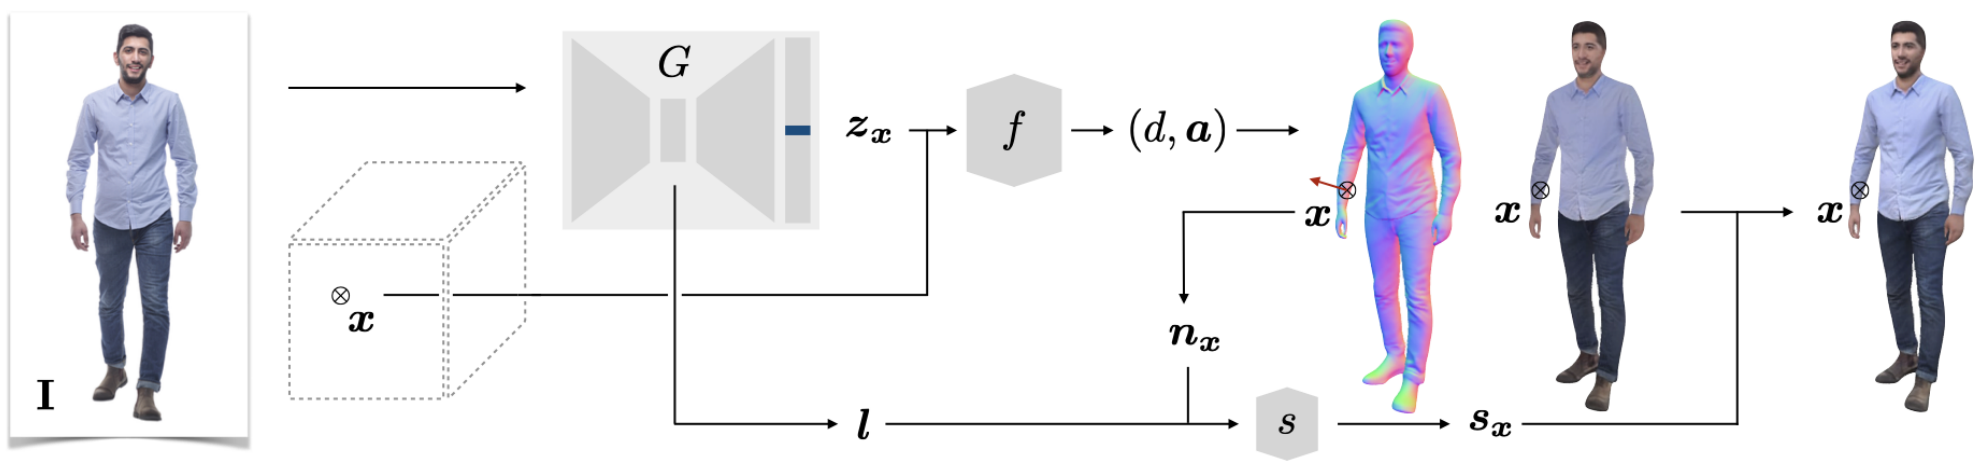
300 dpi PNG · 图注 · 源PDF
图2明确为整体方法,展示图像特征到SDF几何、反照率和阴影网络,再到完整三维输出。
完整图注、版本和筛选证据
最早核实视觉日期:2022-04-19;arXiv v1:2022-04-19;CVPR 2022 fixed official PDF
已查看固定会议PDF、图注和相关正文,核对唯一/最早v1目标图;源裁图与v1逐像素一致,MAE=0。保存v1及对应完整裁图。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Cristian Sminchisescu;24653;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 70, 535, 182],PDF点、左上角原点。
Figure 2. Overview of our method. The feature extractor network G produces pixel-aligned features z from an input image I for all points
x
in space x. The implicit signed distance function network f computes the distance d to the closest surface given a point and its feature.
Additionally f returns albedo colors a defined for surface points. The shading network s predicts the shading for surface points given its
surface normal n , as well as illumination l. On the right we show the reconstruction of geometry and albedo colors, and the shaded 3D
x
geometry.
Photorealistic Monocular 3D Reconstruction of Humans Wearing Clothing
会议:CVPR 2022 · 主会论文
Figure 8 · PDF第8页 · P241
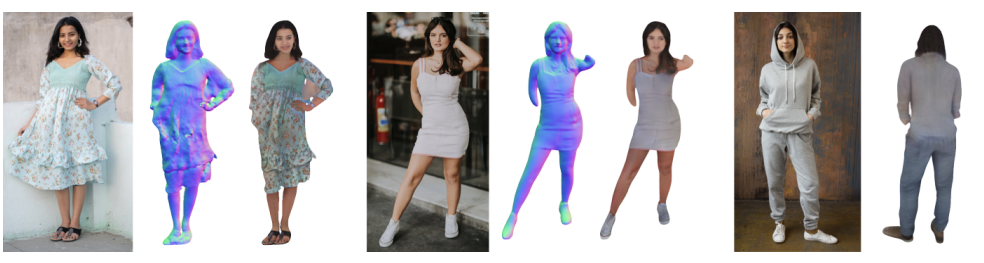
300 dpi PNG · 图注 · 源PDF
图8及第5节Limitations明确展示宽松衣服、复杂姿态与背面语义不一致的失败案例;此前图1、4、5、7是成功结果/重光照结果,图6是消融,不计M。
完整图注、版本和筛选证据
最早核实视觉日期:2022-04-19;arXiv v1:2022-04-19;CVPR 2022 fixed official PDF
已查看固定会议PDF、图注和相关正文,核对唯一/最早v1目标图;源裁图与v1逐像素一致,MAE=0。保存v1及对应完整裁图。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Cristian Sminchisescu;24653;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[308, 332, 544, 395],PDF点、左上角原点。
Figure 8. Failure cases. Wide clothing is under-represented in
our dataset and this can be addressed with more diverse training.
Complex poses can lead to missing body parts. The back-side
sometimes mismatches the front (subject is wearing a hood).
Pre-train, Self-train, Distill: A simple recipe for Supersizing 3D Reconstruction
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第2页 · P228
300 dpi PNG · 图注 · 源PDF
图2明确为Approach Overview,正文说明合成数据预训练、真实图像集合自训练及多类别蒸馏三阶段,完整呈现训练流程。
完整图注、版本和筛选证据
最早核实视觉日期:2022-04-07;arXiv v1:2022-04-07;CVPR 2022 fixed official PDF
固定PDF图注、正文引用段落及作者单位已核验。导出完整图区域保留文字符号,300dpi与历史裁剪已逐张目检。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Shubham Tulsiani;13507;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[78, 72, 510, 168],PDF点、左上角原点。
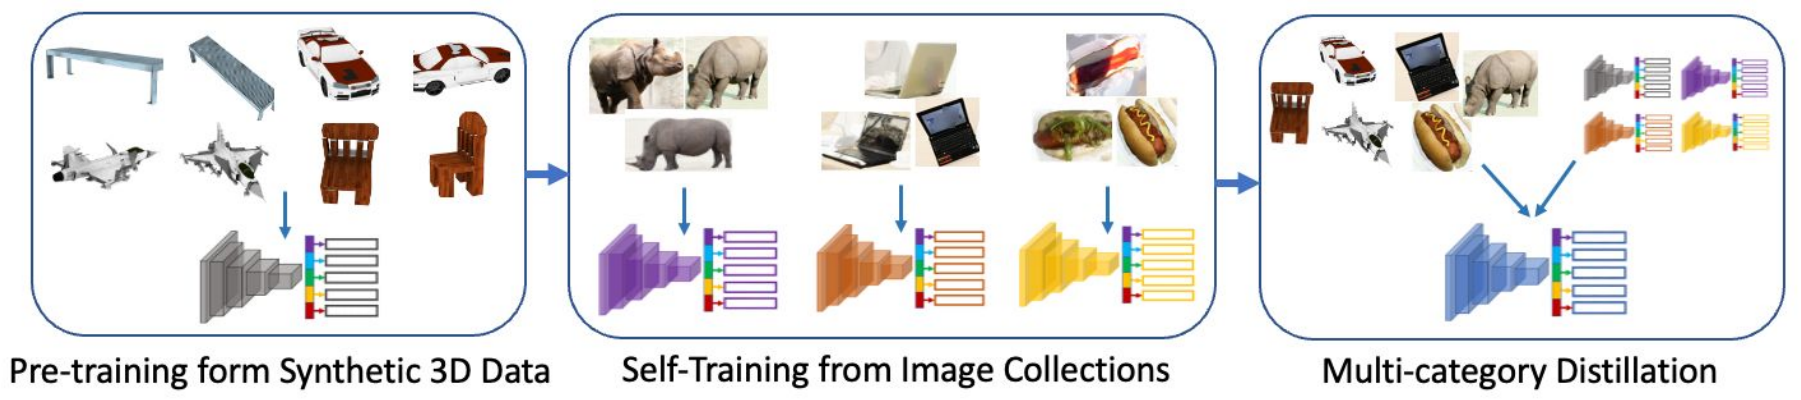
Figure 2. Approach Overview. We first pre-train a reconstruction model using multi-view renderings of synthetic data. We then self-train
category-specific models on diverse image collections in-the-wild with only foreground mask annotations. We finally distill the learned
models from prior training stages into a unified reconstruction model.
Pre-train, Self-train, Distill: A simple recipe for Supersizing 3D Reconstruction
会议:CVPR 2022 · 主会论文
Figure 8 · PDF第7页 · P227
300 dpi PNG · 图注 · 源PDF
图8及第4.3节、结论明确展示遮挡和困难类别的失败案例,说明单视图重建的限制;不是普通成功结果展示。此前图1普通结果,图3–7训练机制/实验比较,图8为明确诊断性失败图。
完整图注、版本和筛选证据
最早核实视觉日期:2022-04-07;arXiv v1:2022-04-07;CVPR 2022 fixed official PDF
固定PDF图注、正文引用段落及作者单位已核验。导出完整图区域保留文字符号,300dpi与历史裁剪已逐张目检。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Shubham Tulsiani;13507;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[310, 72, 543, 155],PDF点、左上角原点。
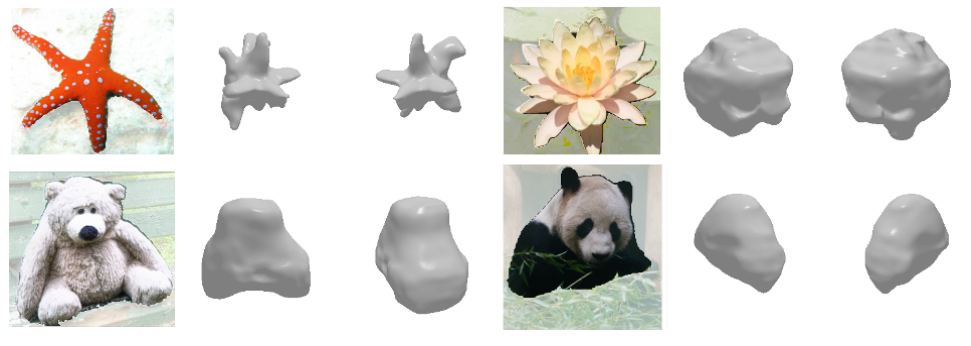
Figure 8. Failure modes. Our model is not robust to occlusion
and does not perform well on some difficult categories.
Single-Image Piece-wise Planar 3D Reconstruction via Associative Embedding
会议:CVPR 2019 · 主会论文
Figure 2 · PDF第3页 · P182
300 dpi PNG · 图注 · 源PDF
第3节明确图2为overall pipeline:像素嵌入与均值漂移产生平面实例,再联合平面参数与实例池化生成3D模型。
完整图注、版本和筛选证据
最早核实视觉日期:2019-02-26;arXiv v1:2019-02-26;CVPR 2019 fixed official PDF
已比较arXiv v1(2019-02-26)与固定会议图2,模块、标签、连线及配色一致;轻微像素差异来自栅格压缩/渲染。作者Shenghua Gao在文中单位ShanghaiTech,与公开主页履历一致。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Shenghua Gao;29917;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[75, 72, 520, 278],PDF点、左上角原点。
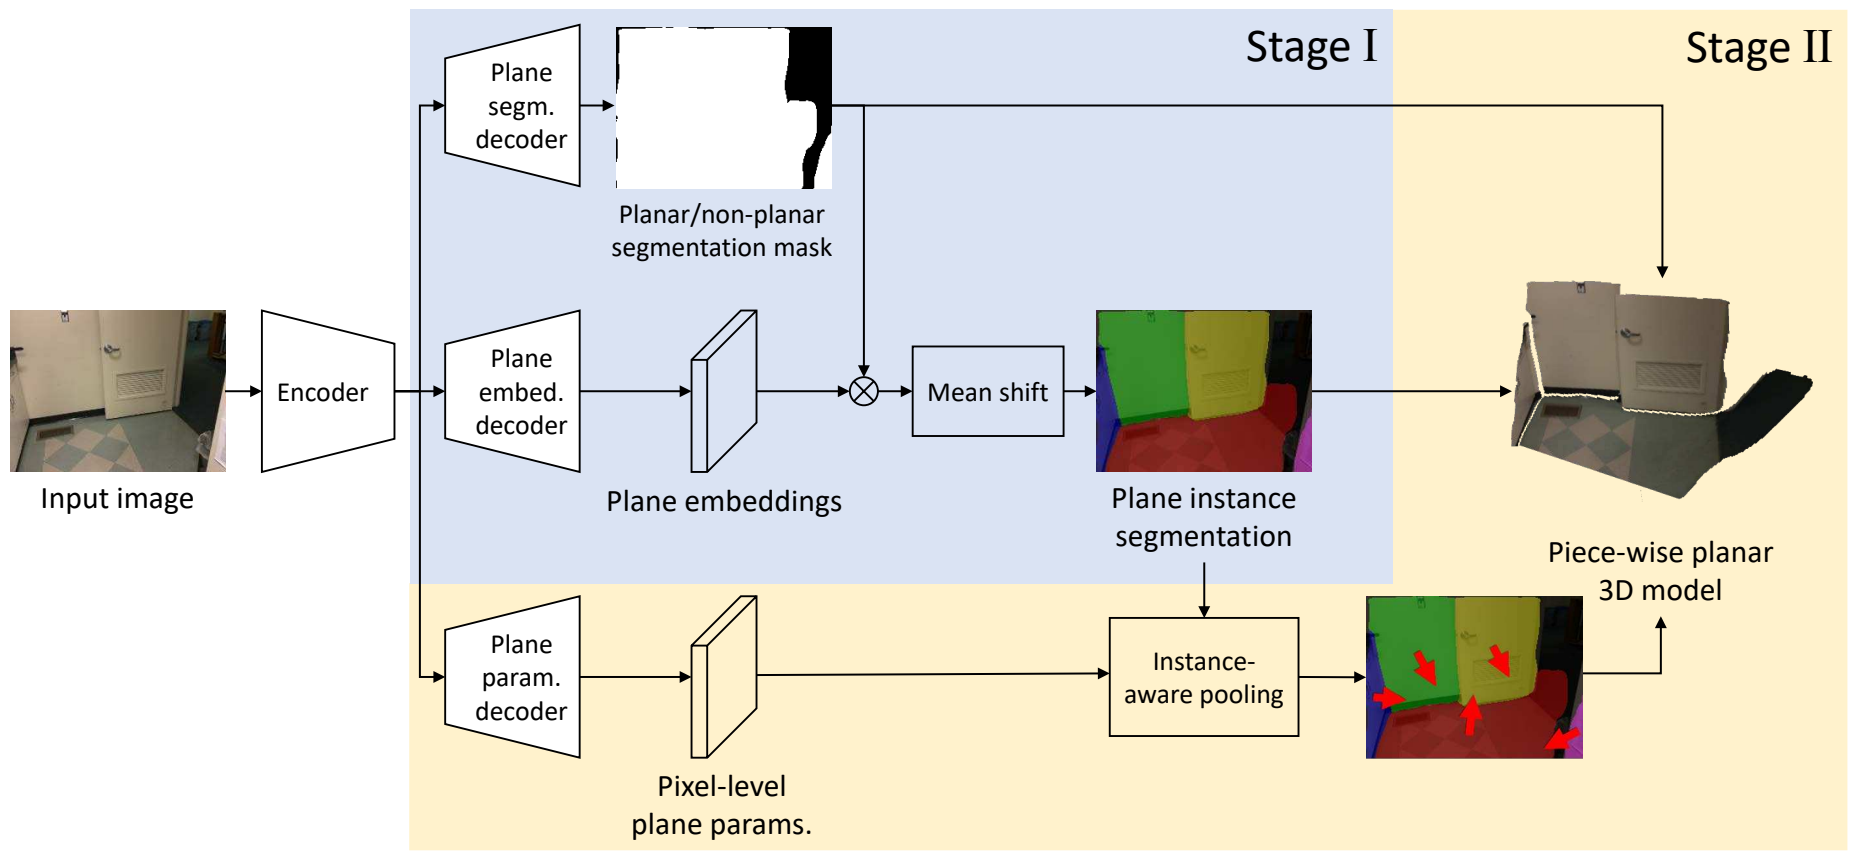
Figure 2: Network architecture. In the first stage, the network takes a single RGB image as input, and predicts a planar/non-
planar segmentation mask and pixel-level embeddings. Then, an efficient mean shift clustering algorithm is applied to
generate plane instances. In the second stage, we estimate parameter of each plane by considering both pixel-level and
instance-level geometric consistencies.
Single-Image Piece-wise Planar 3D Reconstruction via Associative Embedding
会议:CVPR 2019 · 主会论文
Figure 7 · PDF第8页 · P181
300 dpi PNG · 图注 · 源PDF
第4.4节Failure Cases及图7解释外观相似导致合并、外观差异导致过分割、标注不一致导致书架漏分割;是明确的局限与失败分析。图1是普通输出示例。
完整图注、版本和筛选证据
最早核实视觉日期:2019-04-24;arXiv v1:2019-02-26;CVPR 2019 fixed official PDF
已查看v1(2019-02-26)、v2(03-04)、v3(04-24)。三行失败案例的行间留白和文字排布在早期版本不同,v3才匹配会议排布;图像内容相同,轻微像素差异来自栅格压缩/渲染。使用v3日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Shenghua Gao;29917;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[305, 186, 548, 377],PDF点、左上角原点。
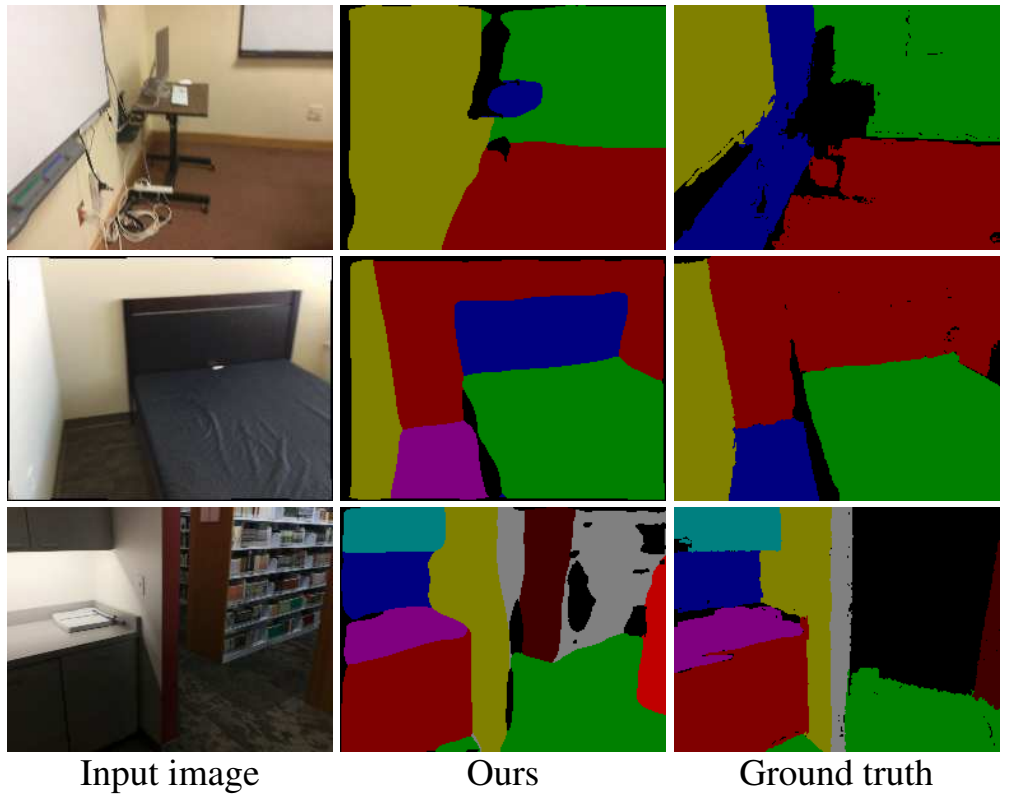
Figure 7: Failure cases.
Surface Reconstruction from Point Clouds by Learning Predictive Context Priors
会议:CVPR 2022 · 主会论文
Figure 2 · PDF第3页 · P86
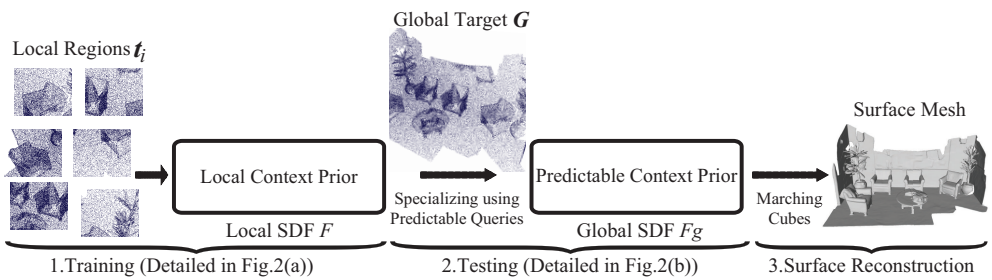
300 dpi PNG · 图注 · 源PDF
图2明确标注Overview,包含学习局部先验、测试时适配全局SDF和表面重建三个完整阶段;与下方局部细节图3分开。
完整图注、版本和筛选证据
最早核实视觉日期:2022-04-23;arXiv v1:2022-04-23;CVPR 2022 fixed official PDF
已查看固定PDF及目标图;以最早已核实匹配版本日期作时间代理,不声称实际作图日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Matthias Zwicker;17011;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[49, 70, 287, 137],PDF点、左上角原点。
Figure 2. Overview of our method.
Surface Reconstruction from Point Clouds by Learning Predictive Context Priors
会议:CVPR 2022 · 主会论文
Figure 4 · PDF第4页 · P85
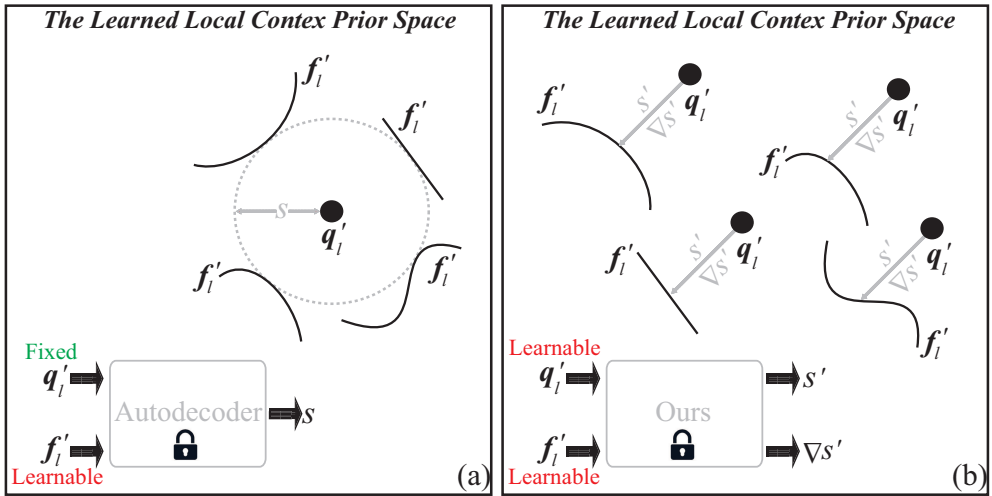
300 dpi PNG · 图注 · 源PDF
Intuition and Advantages段落用图4对比固定位置搜索与可学习位置搜索,解释已有局部先验的泛化局限。
完整图注、版本和筛选证据
最早核实视觉日期:2022-04-23;arXiv v1:2022-04-23;CVPR 2022 fixed official PDF
已查看固定PDF及目标图;以最早已核实匹配版本日期作时间代理,不声称实际作图日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Matthias Zwicker;17011;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[49, 71, 287, 190],PDF点、左上角原点。
Figure 4. Current methods can merely search similar regions at a
specific location q(cid:48) in the learned prior space by optimizing con-
l
dition f(cid:48). While we can search over the whole prior space by
l
simultaneously optimizing q(cid:48) and f(cid:48).
l l
Topologically-Aware Deformation Fields for Single-View 3D Reconstruction
会议:CVPR 2022 · 图源:存档 arXiv v1
Figure 2 · PDF第2页 · P20
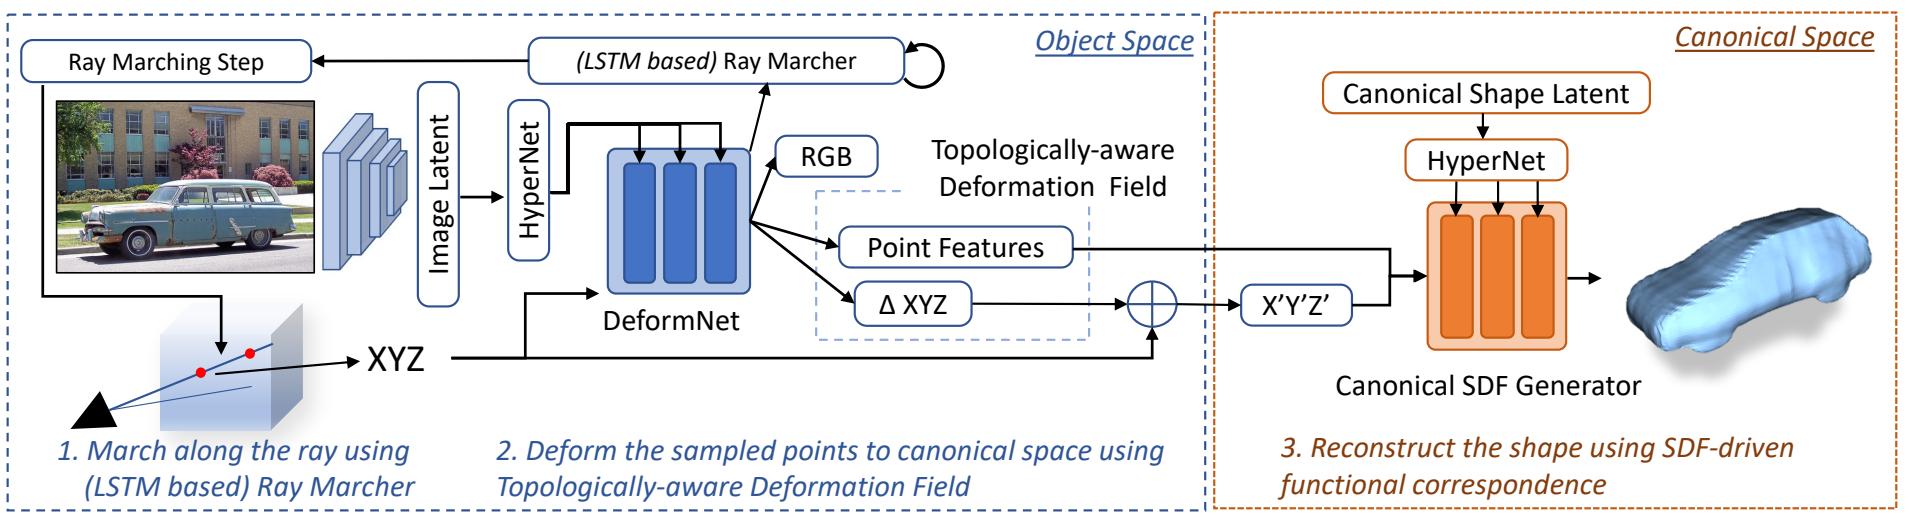
300 dpi PNG · 图注 · 源PDF
图注Overview及第2页方法说明明确给出从图像、射线行进、拓扑感知变形到规范SDF生成器的完整TARS计算路径。
完整图注、版本和筛选证据
最早核实视觉日期:2022-05-12;arXiv v1:2022-05-12;arXiv v1 fixed source
固定arXiv v1原件;会议视觉与早期版本存在差异,未给新版图套用v1日期。TARS已查看v1/v2及会议版;PassionSR已查看v1/v2/v3及会议版;具体差异保留在review页图中。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Deepak Pathak;37267;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[68, 70, 526, 194],PDF点、左上角原点。
Figure 2. Overview of TARS: Given a single image, we first map a 3D point in object space to a higher-dimensional canonical space using
our learned topologically-aware deformation field. The canonical point is then mapped to its SDF value using the Canonical Shape Generator
module. We leverage an LSTM-based differentiable renderer to guide the learning of deformation and signed distance fields.
Topologically-Aware Deformation Fields for Single-View 3D Reconstruction
会议:CVPR 2022 · 图源:存档 arXiv v1
Figure 1 · PDF第1页 · P19
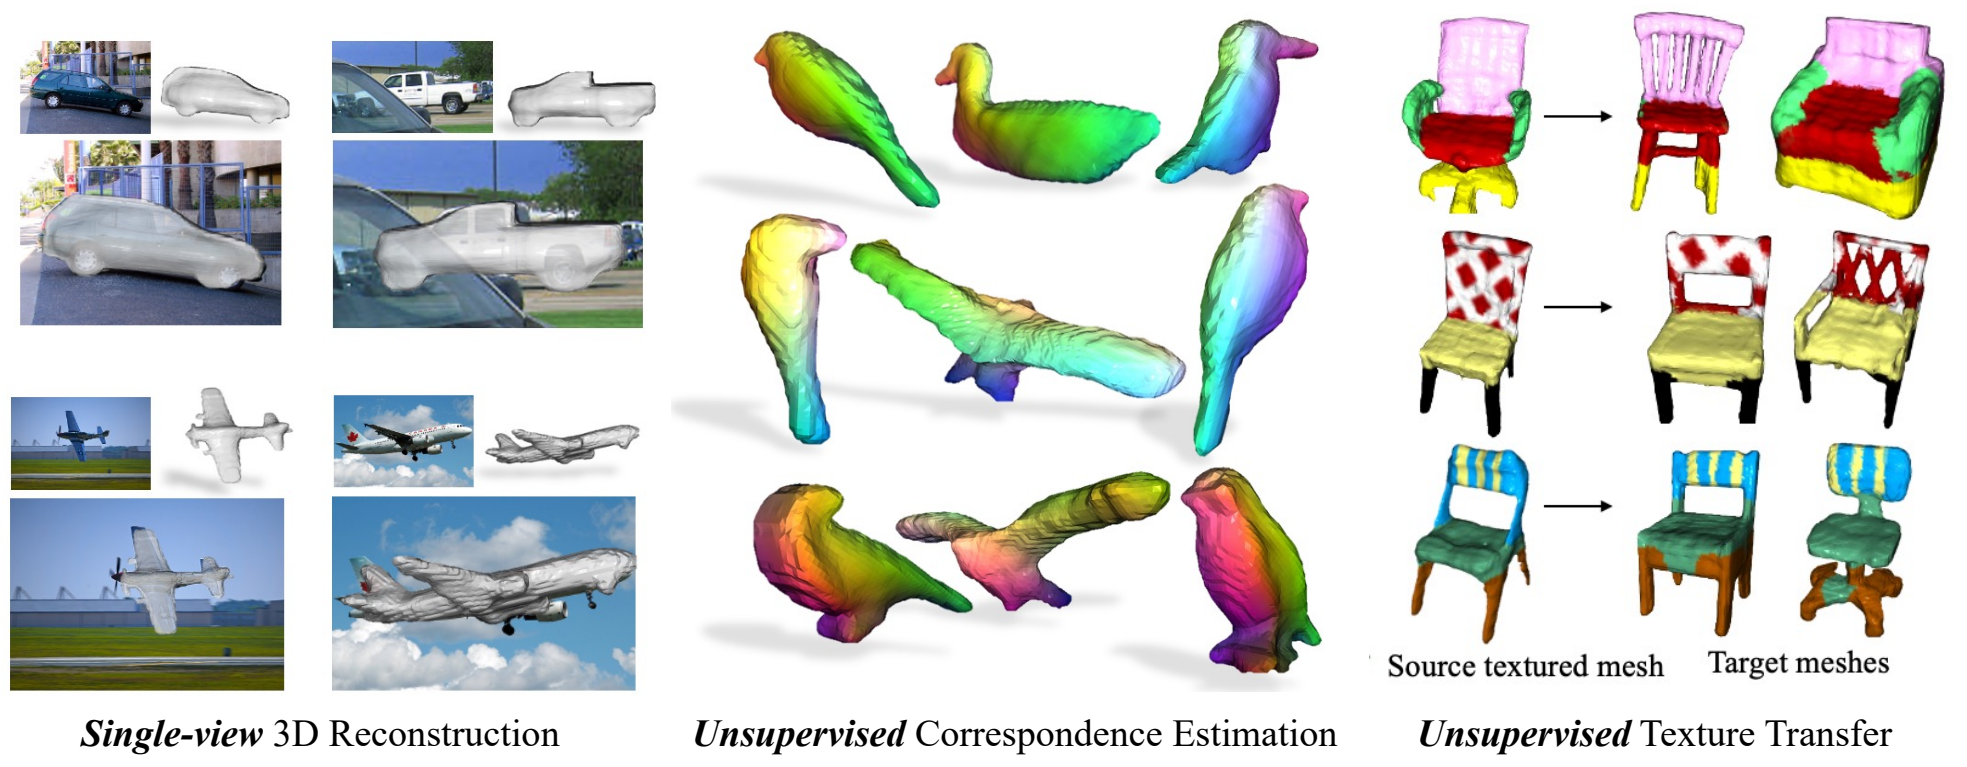
300 dpi PNG · 图注 · 源PDF
首图用三个标注任务展示单图重建、跨实例稠密对应及纹理迁移的应用关系;引言第2页解释共同形状表示如何支撑后两项用途。按应用场景收录,不因渲染质量评选。
完整图注、版本和筛选证据
最早核实视觉日期:2022-05-12;arXiv v1:2022-05-12;arXiv v1 fixed source
固定arXiv v1原件;会议视觉与早期版本存在差异,未给新版图套用v1日期。TARS已查看v1/v2及会议版;PassionSR已查看v1/v2/v3及会议版;具体差异保留在review页图中。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Deepak Pathak;37267;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[61, 139, 533, 323],PDF点、左上角原点。
Figure 1. Given an unpaired image collection (with known camera poses) of an object category at training time, our approach learns to: (a)
reconstruct the underlying 3D given only a single image at test time, and (b) model dense 3D correspondences across category instances.
The learned correspondence field is articulation-aware, topologically-aware and inherently captures structural properties of the category,
enabling the task of unsupervised texture transfer. Videos and code at https://shivamduggal4.github.io/tars-3D/
CAT: Exploiting Inter-Class Dynamics for Domain Adaptive Object Detection
会议:CVPR 2024 · 主会论文
Figure 2 · PDF第3页 · P268
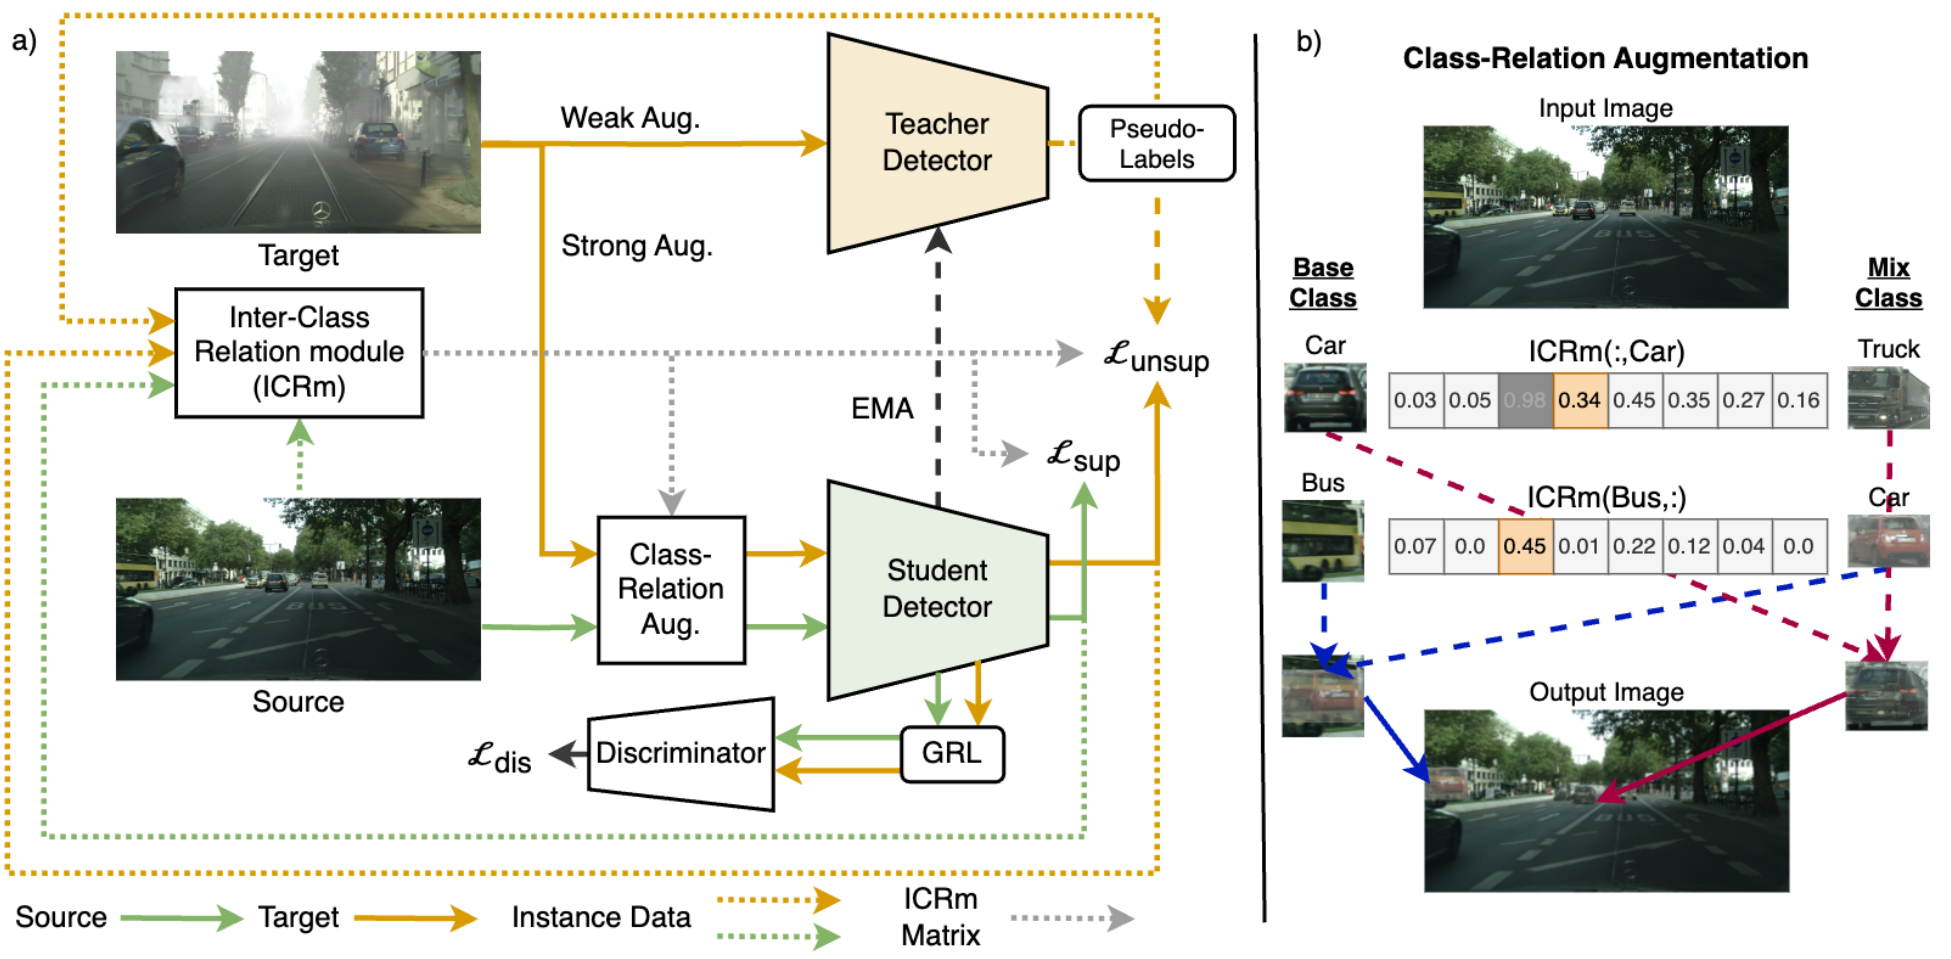
300 dpi PNG · 图注 · 源PDF
图2(a)包含完整师生网络、类间关系估计、增强及损失,(b)说明增强,保留全部子图。
完整图注、版本和筛选证据
最早核实视觉日期:2024-03-28;arXiv v1:2024-03-28;CVPR 2024 fixed official PDF
已核对固定会议PDF与arXiv v1完整图页,未见目标图重绘;微小像素差源于PDF渲染。作者姓名与固定PDF单位、公开Scholar单位相符。已逐张查看300dpi导出、确认完整。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Robby T. Tan;18517;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[67, 72, 535, 302],PDF点、左上角原点。
Figure 2. (a) Class-Aware Teacher (CAT) consists of: a student-teacher network; Inter-Class Relation module (ICRm), which estimates
inter-class biases; Class-Relation Augmentation, which augments images to reduce the inter-class biases by mixing the cropped instances of
related classes; and Inter-Class Loss, which emphasises the loss on highly misclassified minority classes. (b) Class-Relation Augmentation
demonstrated on majority (Car) and minority (Bus) classes.
CAT: Exploiting Inter-Class Dynamics for Domain Adaptive Object Detection
会议:CVPR 2024 · 主会论文
Figure 1 · PDF第1页 · P267
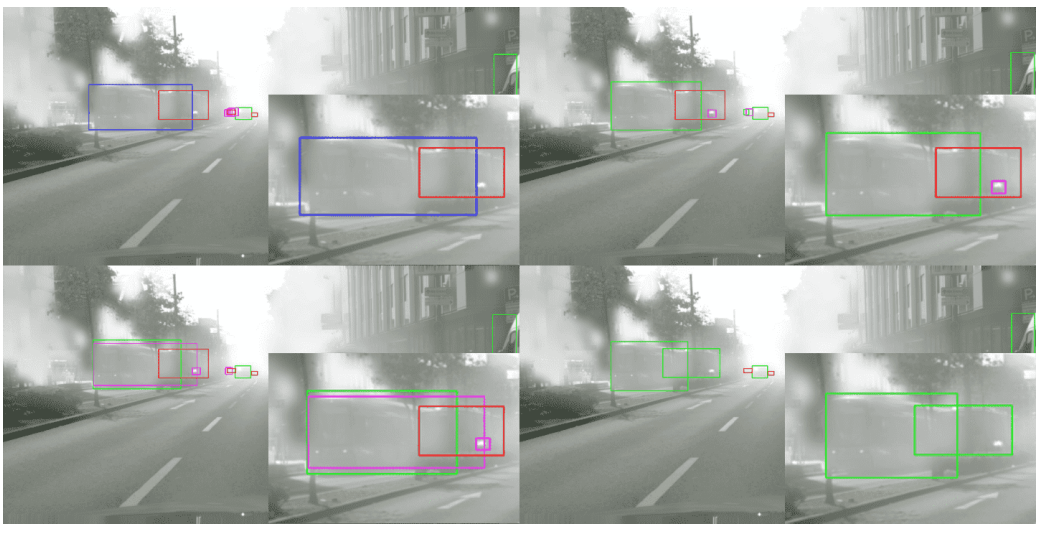
300 dpi PNG · 图注 · 源PDF
图1以带颜色框的错分类与假阳性明确诊断少数类问题;引言据此引出类别偏置动机,非普通结果展示。
完整图注、版本和筛选证据
最早核实视觉日期:2024-03-28;arXiv v1:2024-03-28;CVPR 2024 fixed official PDF
已核对固定会议PDF与arXiv v1完整图页,未见目标图重绘;微小像素差源于PDF渲染。作者姓名与固定PDF单位、公开Scholar单位相符。已逐张查看300dpi导出、确认完整。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Robby T. Tan;18517;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[308, 254, 558, 382],PDF点、左上角原点。
Figure 1. Performance of Class-Aware Teacher (CAT). AT [29]
(top left), with Inter-Class Loss, ICL, (top-right), with Class Rela-
tion Augmentation, CRA, (bottom-left), and CAT (bottom-right).
CAT is able to address misclassification and false positives, blue
and red boxes, respectively, in minority classes such as ’train’. The
combination of ICL and CRA further boosts performance by re-
ducing the number of false positives shown as pink boxes.
Efficient Test-time Adaptive Object Detection via Sensitivity-Guided Pruning
会议:CVPR 2025 · 主会论文
Figure 4 · PDF第3页 · P84
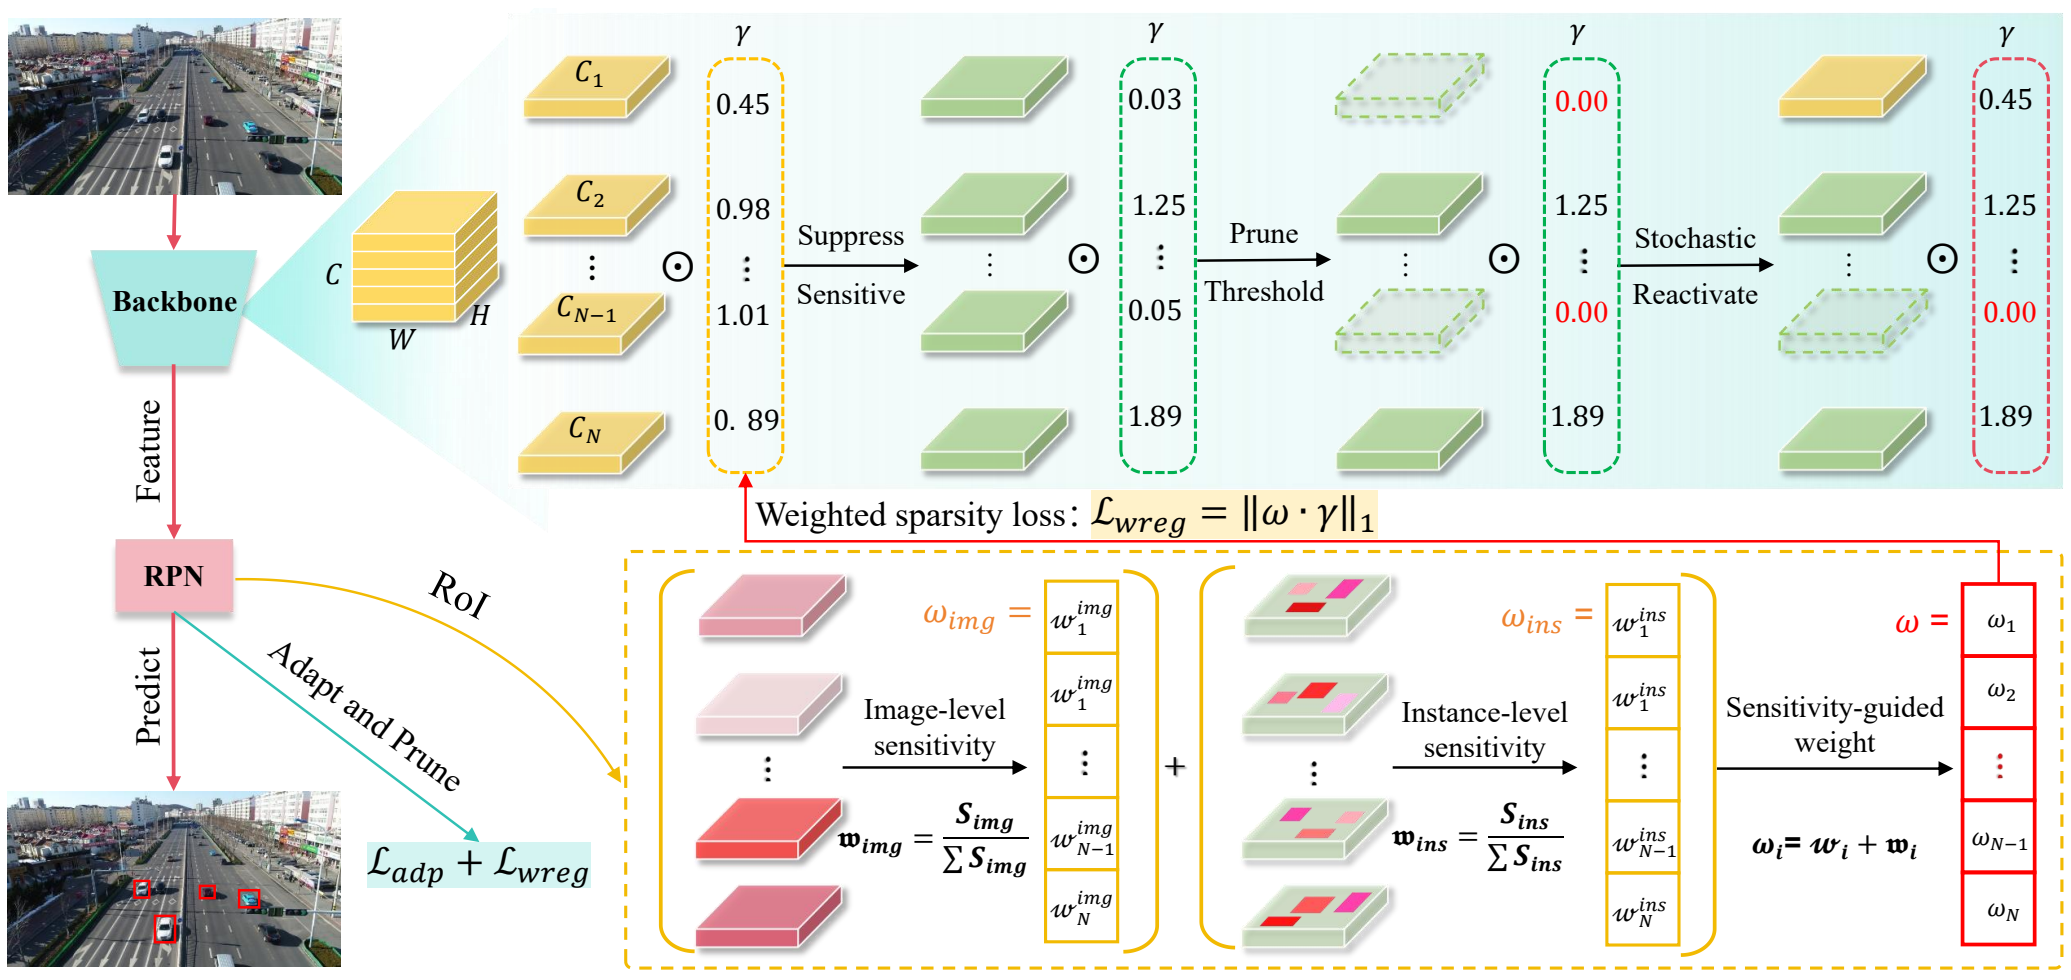
300 dpi PNG · 图注 · 源PDF
第3节明确称图4为总体方法,包含完整检测、敏感通道抑制、裁剪和随机再激活流程。
完整图注、版本和筛选证据
最早核实视觉日期:2025-06-03;arXiv v1:2025-06-03;CVPR 2025 fixed official PDF
已查看固定PDF及目标图;以最早已核实匹配版本日期作时间代理,不声称实际作图日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Zheng-Jun Zha;30479;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 70, 555, 305],PDF点、左上角原点。
Figure 4. Overview of our method. Motivated by the observation that certain feature channels learned from the source domain negatively
impact cross-domain performance, we propose suppressing and pruning sensitive channels while adapting invariant ones. We introduce
sensitivity-guided channel pruning, which quantifies the importance of each feature channel based on its image-level and instance-level
sensitivity to domain discrepancies. We then apply a weighted sparsity loss to the learnable parameters, promoting the pruning of channels
with higher sensitivity based on the predefined threshold and ratio. To prevent the loss of potentially useful channels from early pruning,
we introduce a stochastic channel reactivation mechanism.
Efficient Test-time Adaptive Object Detection via Sensitivity-Guided Pruning
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第1页 · P83
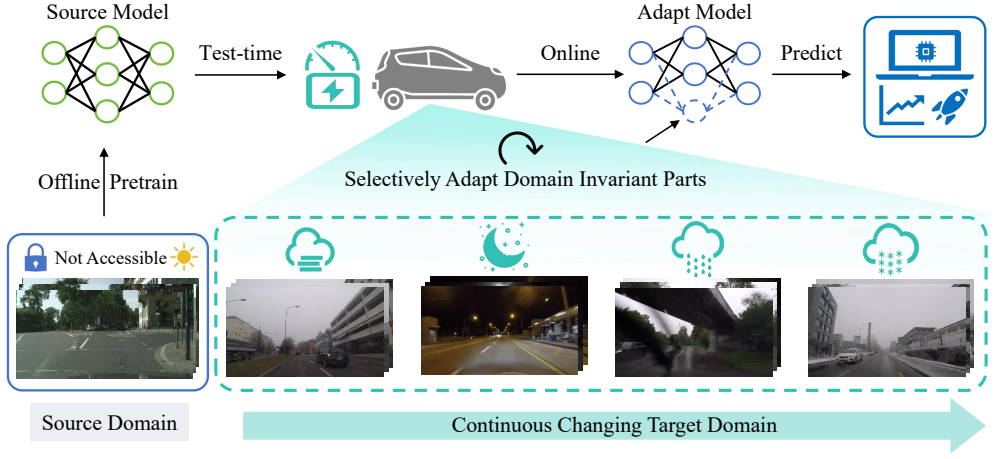
300 dpi PNG · 图注 · 源PDF
引言图1以连续变化的道路天气和在线适应示意应用问题,说明在算力受限场景中选择不变通道的动机。
完整图注、版本和筛选证据
最早核实视觉日期:2025-06-03;arXiv v1:2025-06-03;CVPR 2025 fixed official PDF
已查看固定PDF及目标图;以最早已核实匹配版本日期作时间代理,不声称实际作图日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Zheng-Jun Zha;30479;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[316, 258, 555, 368],PDF点、左上角原点。
Figure 1. We consider continual test-time adaptive object detec-
tion, which adapts a source detector to changing environments
during inference. By focusing adaptation efforts on invariant
parts while pruning sensitive parts, we improve computational ef-
ficiency, which is crucial for resource-constrained scenarios like
autonomous driving or UAV.
Fractal Calibration for long-tailed object detection
会议:CVPR 2025 · 主会论文
Figure 2 · PDF第3页 · P234
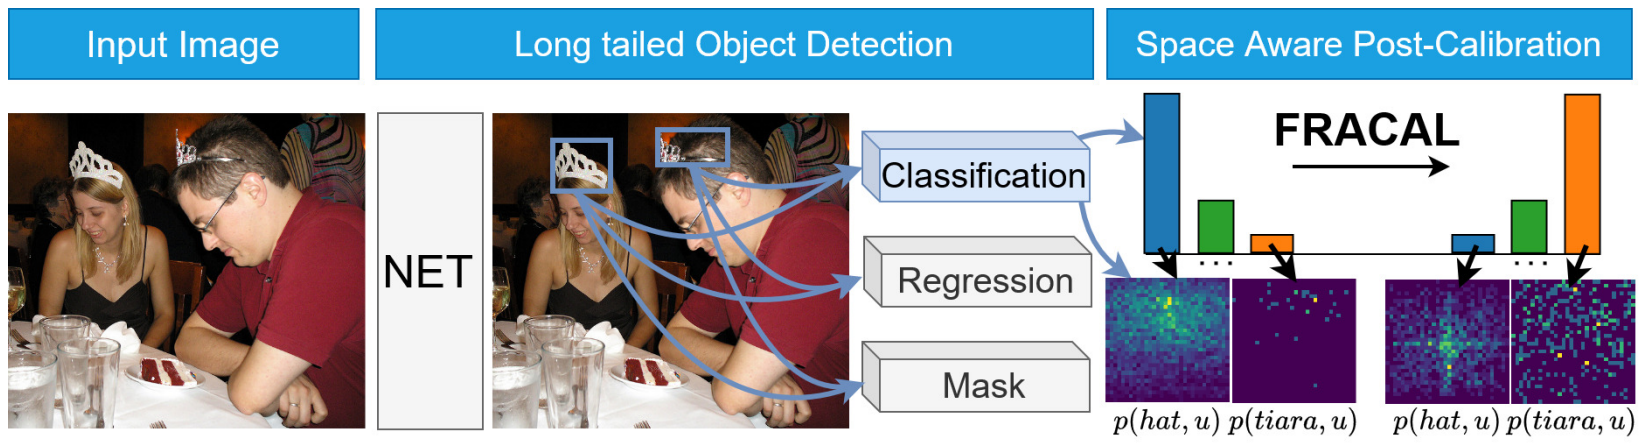
300 dpi PNG · 图注 · 源PDF
图2及第3节给出FRACAL整体流程,包含检测网络、类别频率与分形空间统计、联合校准及输出。
完整图注、版本和筛选证据
最早核实视觉日期:2024-10-15;arXiv v1:2024-10-15;CVPR 2025 fixed official PDF
已核查v1第4页图2、v2第3页图2及会议PDF。构图、标签、颜色、连线相同,仅版面缩放;最早匹配v1(2024-10-15)。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jiankang Deng;26964;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[106, 70, 501, 177],PDF点、左上角原点。
Figure 2. During imbalanced object detection, the model makes more frequent class detections like hat and less rare class detections like
tiara both of which have strong upper location bias. FRACAL utilises fractal dimension and debiases the logits both in the frequency and
space axes, making fewer hat detections and more tiara detections that are both evenly spread in image space.
Fractal Calibration for long-tailed object detection
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第1页 · P233
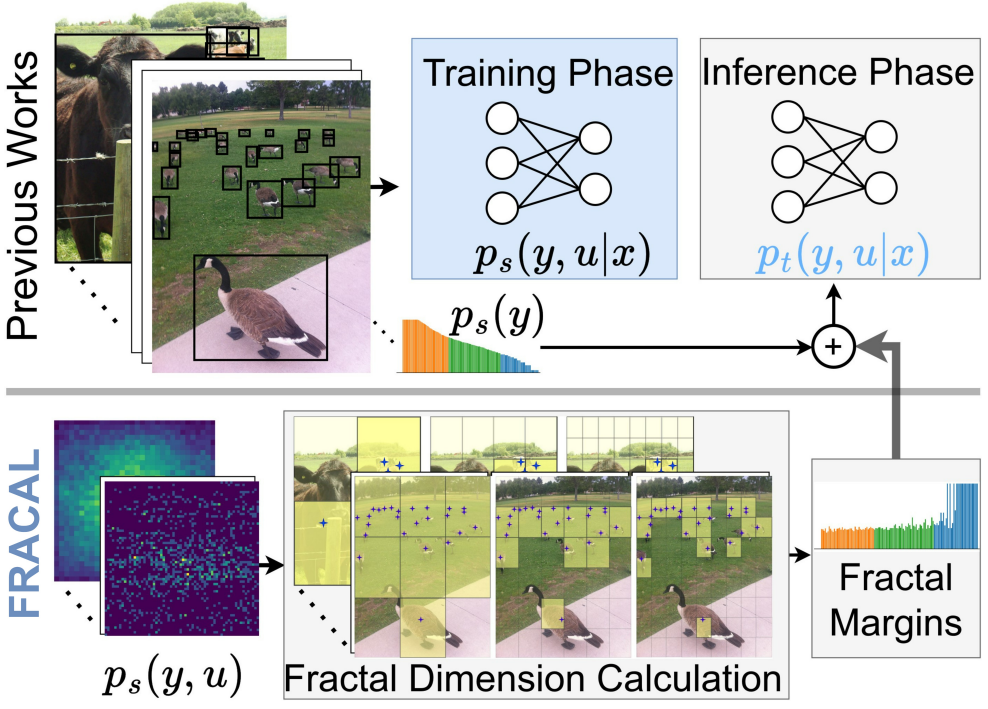
300 dpi PNG · 图注 · 源PDF
图1及引言对比只用类别频率的既有校准和结合空间统计的校准,说明忽视空间分布的问题;不是性能柱状图。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-05;arXiv v1:2024-10-15;CVPR 2025 fixed official PDF
已核查v1、v2及固定会议PDF。v1图1为横向并排;v2(2025-03-05)改为上下布局且与会议图逐像素一致,采用v2日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jiankang Deng;26964;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[318, 214, 555, 384],PDF点、左上角原点。
Figure 1. Previous works used class information p (y ) to align
s
the learned source distribution p (y , u|x) with the balanced target
s
distribution p (y , u|x), without considering the space u and class
t
y relationship i.e. p (y , u). FRACAL captures p (y , u), using
s s
the fractal dimension, and embeds fractal margins during infer-
ence, aligning the learned distribution p (y , u|x) with the target
s
p (y , u|x) better than previous works.
t
Generative Region-Language Pretraining for Open-Ended Object Detection
会议:CVPR 2024 · 主会论文
Figure 2 · PDF第4页 · P270
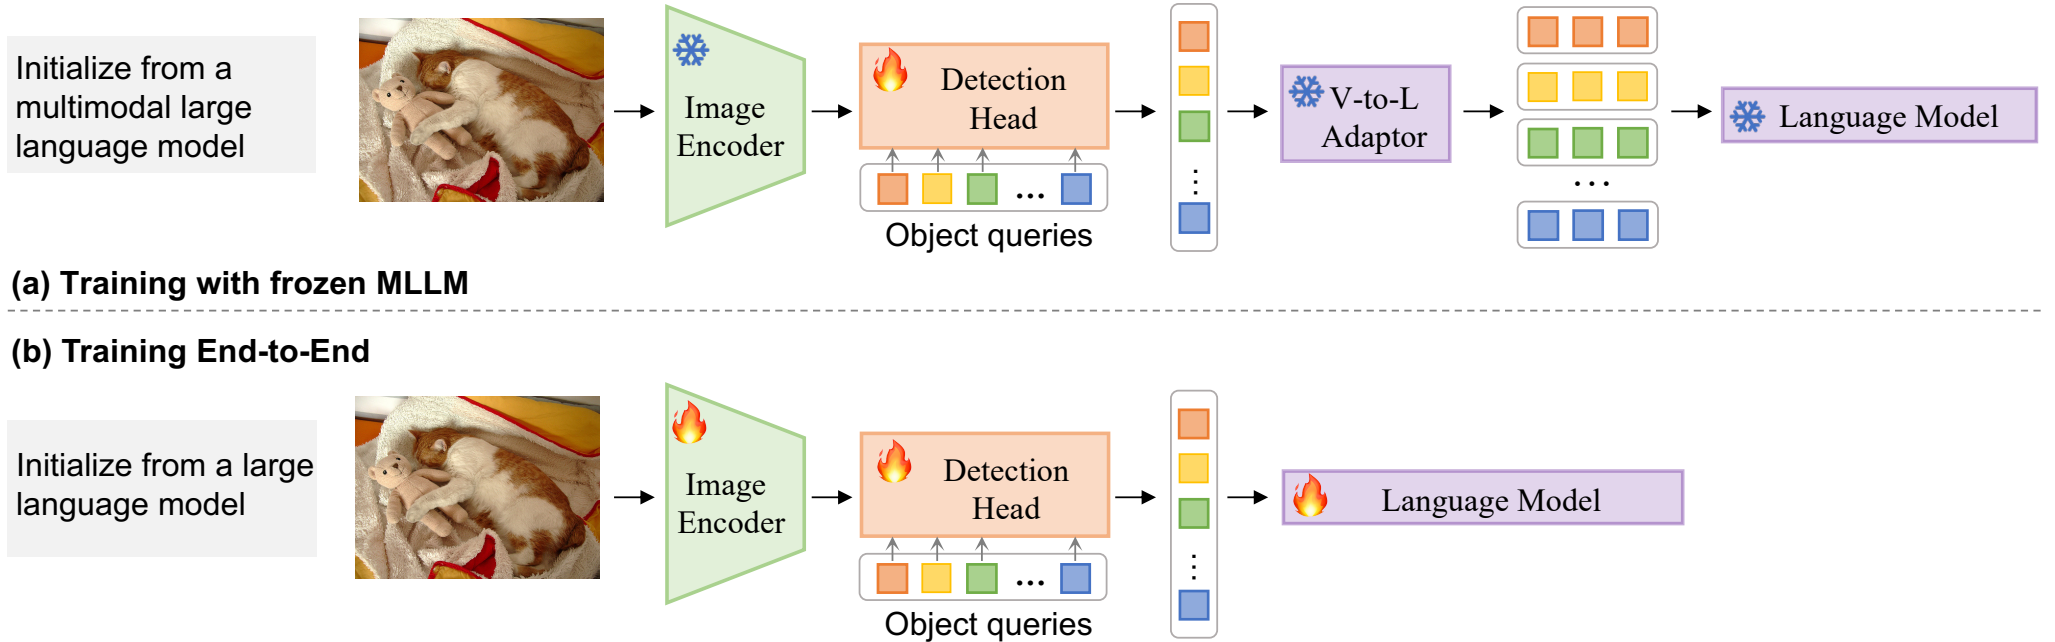
300 dpi PNG · 图注 · 源PDF
图2明确为GenerateU整体模型及两种训练策略,涵盖图像编码、检测、适配和语言生成路径。
完整图注、版本和筛选证据
最早核实视觉日期:2024-03-15;arXiv v1:2024-03-15;CVPR 2024 fixed official PDF
已核对固定会议PDF与arXiv v1完整图页,未见目标图重绘;微小像素差源于PDF渲染。作者姓名与固定PDF单位、公开Scholar单位相符。已逐张查看300dpi导出、确认完整。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jianfei Cai;40906;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[54, 72, 547, 226],PDF点、左上角原点。
Figure 2. Overview of our proposed open-ended object detection model, GenerateU, which comprises two major components: an object
detector and a language model. We compare two training strategies: (Top) We incorporate the class-agnostic DETR (with frozen image
encoder) into a pre-trained and frozen Multimodal Large Language Model (including Adaptor and Language Model), to facilitate a smooth
transfer of knowledge from the language domain to object detection; (Bottom) We activate the image encoder and language model as
trainable components, taking an end-to-end approach to seamlessly integrate region-level understanding into the language model.
Generative Region-Language Pretraining for Open-Ended Object Detection
会议:CVPR 2024 · 主会论文
Figure 1 · PDF第1页 · P269
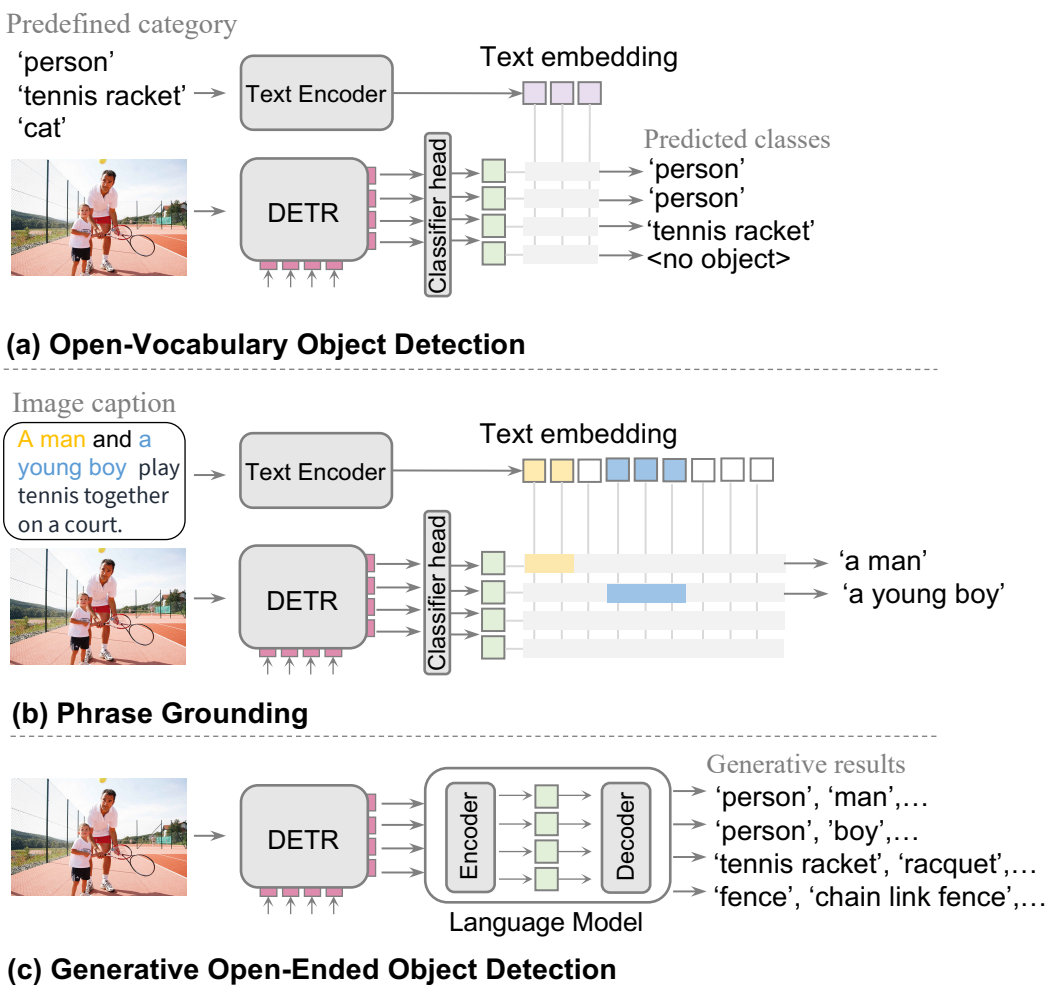
300 dpi PNG · 图注 · 源PDF
图1对比开放词汇检测、短语定位与开放式生成检测,说明推理依赖预定义类别的限制。
完整图注、版本和筛选证据
最早核实视觉日期:2024-03-15;arXiv v1:2024-03-15;CVPR 2024 fixed official PDF
已核对固定会议PDF与arXiv v1完整图页,未见目标图重绘;微小像素差源于PDF渲染。作者姓名与固定PDF单位、公开Scholar单位相符。已逐张查看300dpi导出、确认完整。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jianfei Cai;40906;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[312, 201, 565, 440],PDF点、左上角原点。
Figure 1. Comparing generative open-ended object detection with
other open-set object detection tasks. Open-vocabulary object de-
tection and phrase grounding typically require predefined cate-
gories or phrases in text prompts to align with image regions. In
contrast, our introduced generative open-ended object detection is
a more general and practical setting where categorical information
is not explicitly defined. Such a setting is especially meaningful
for scenarios where users lack precise knowledge of object cate-
gories during inference.
InstaGen: Enhancing Object Detection by Training on Synthetic Dataset
会议:CVPR 2024 · 主会论文
Figure 2 · PDF第3页 · P274
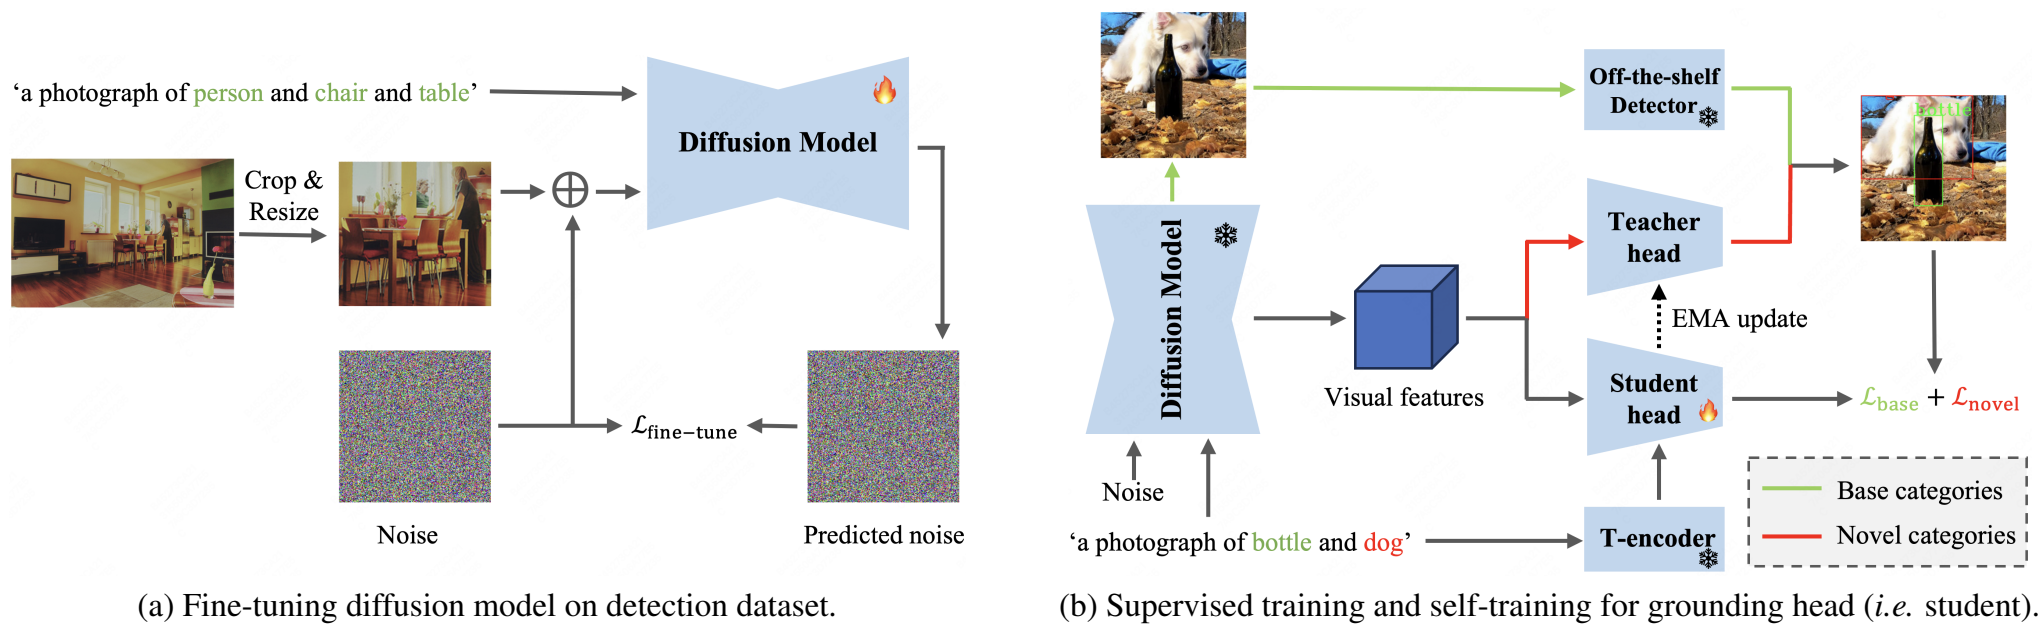
300 dpi PNG · 图注 · 源PDF
图2完整展示扩散模型微调与定位头监督/自训练两个训练阶段;第3.2–3.3节明确引用。
完整图注、版本和筛选证据
最早核实视觉日期:2024-02-20;arXiv v1:2024-02-08;CVPR 2024 fixed official PDF
对照v1、v2、v3:v1框架右侧检测示例及教师/学生分支细节不同;固定会议图最早匹配v2(2024-02-20),不用v1日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Weidi Xie;25742;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[52, 70, 541, 222],PDF点、左上角原点。
Figure 2. Illustration of the process for finetuning diffusion model and training the grounding head: (a) stable diffusion model is fine-tuned
on the detection dataset on base categories. (b) The grounding head is trained on synthetic images, with supervised learning on base
categories and self-training on novel categories.
InstaGen: Enhancing Object Detection by Training on Synthetic Dataset
会议:CVPR 2024 · 主会论文
Figure 1 · PDF第1页 · P273
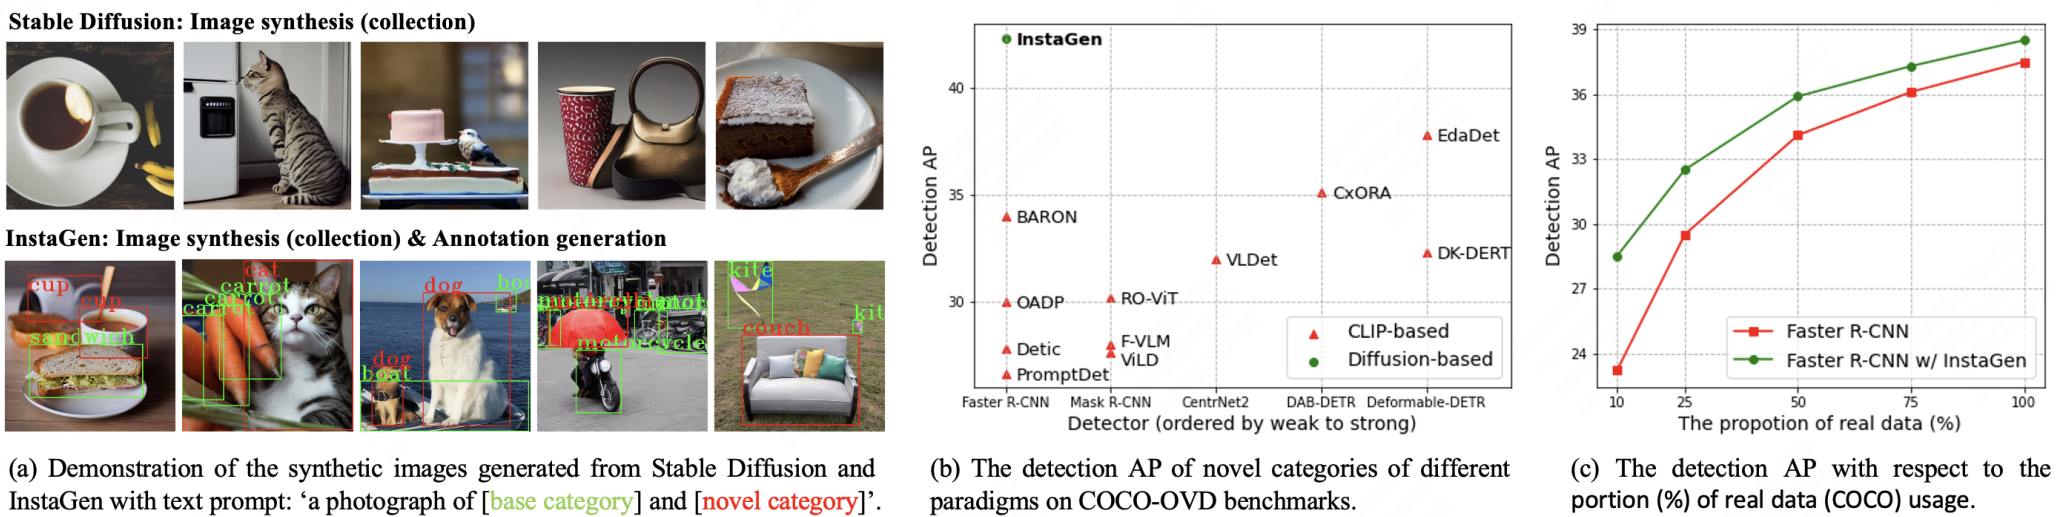
300 dpi PNG · 图注 · 源PDF
图1(a)及引言明确说明原有文本生图缺少实例框,不能直接支持检测训练;展示从图像生成到图像与框联合生成的概念差异,保留同图性能子图。
完整图注、版本和筛选证据
最早核实视觉日期:2024-02-08;arXiv v1:2024-02-08;CVPR 2024 fixed official PDF
图1在v1版下移8pt;校正位置后视觉元素、图内文字与结果一致,微小偏移/压缩差异不构成重绘。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Weidi Xie;25742;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[51, 190, 545, 314],PDF点、左上角原点。
Figure 1. (a) The synthetic images generated from Stable Diffusion and our proposed InstaGen, which can serve as a dataset synthesizer
for sourcing photo-realistic images and instance bounding boxes at scale. (b) On open-vocabulary detection, training on synthetic images
demonstrates significant improvement over CLIP-based methods on novel categories. (c) Training on the synthetic images generated from
InstaGen also enhances the detection performance in close-set scenario, particularly in data-sparse circumstances.
LLMDet: Learning Strong Open-Vocabulary Object Detectors under the Supervision of Large Language Models
会议:CVPR 2025 · 主会论文
Figure 4 · PDF第5页 · P88
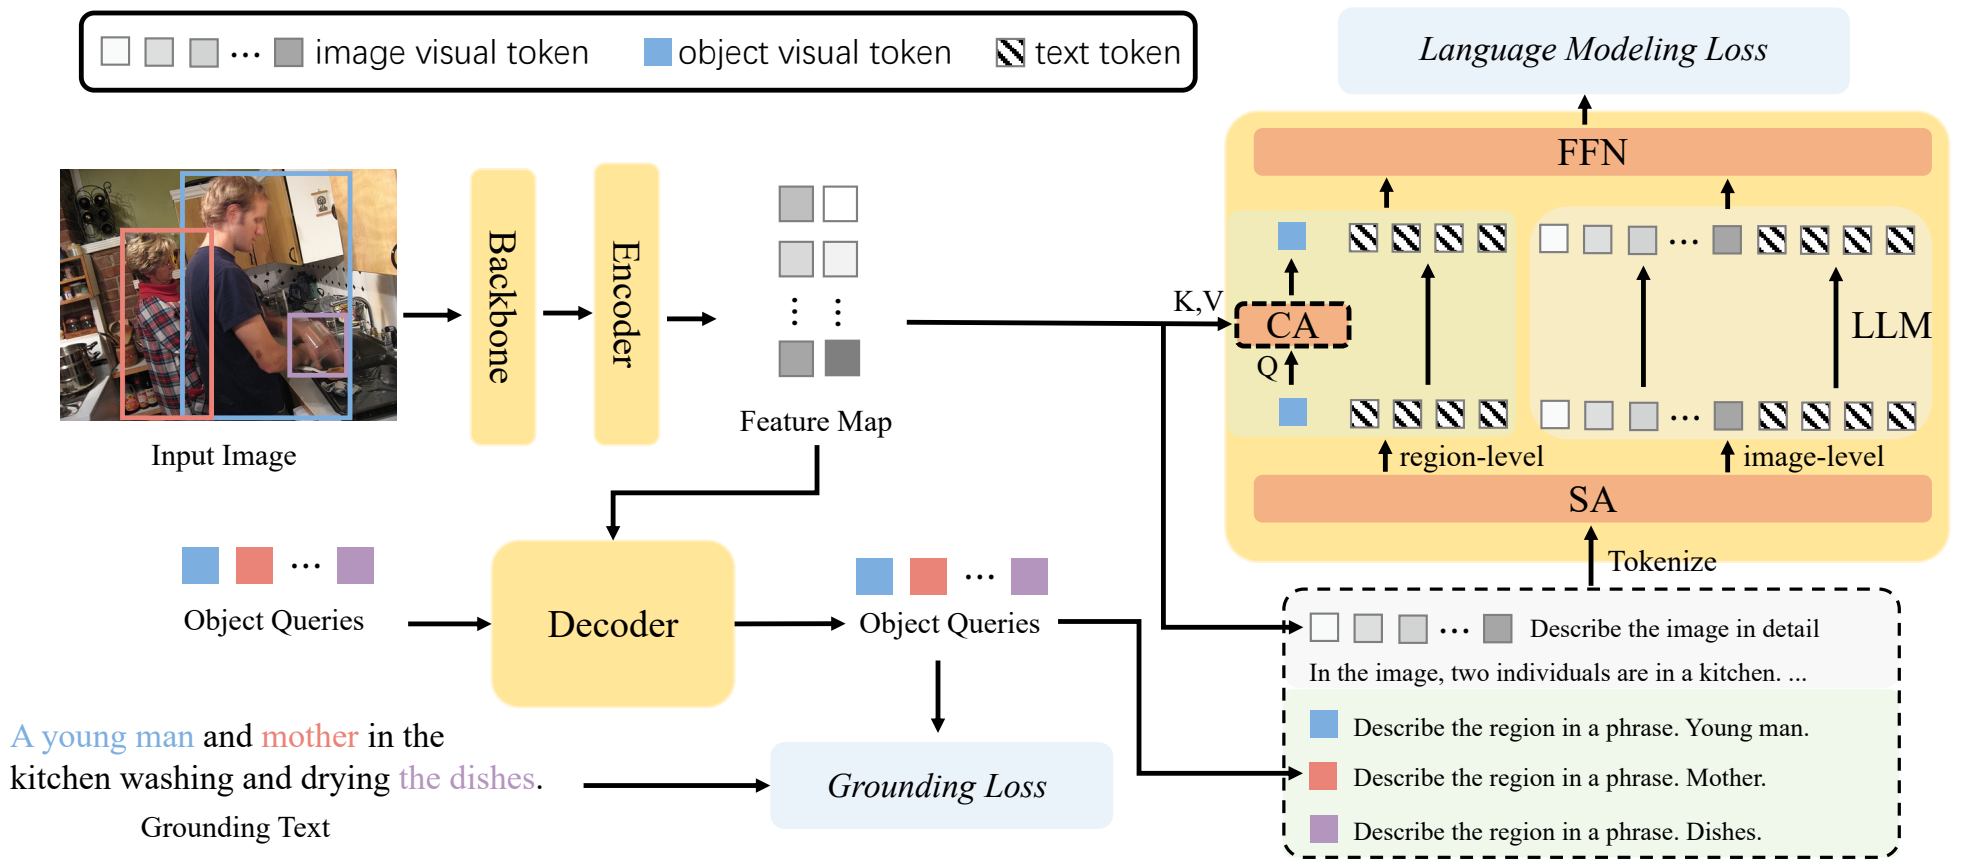
300 dpi PNG · 图注 · 源PDF
图4及第4节明确展示LLMDet总体架构,包含检测器、图像级和区域级LLM分支以及两个训练目标。
完整图注、版本和筛选证据
最早核实视觉日期:2025-01-31;arXiv v1:2025-01-31;CVPR 2025 fixed official PDF
已逐页比较arXiv v1与会议图4;整体图缩放与位置不同,节点、连接、示例图、配色和图例一致,作为同一视觉内容的排版缩放记录。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Wei-Shi Zheng;31913;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[71, 72, 542, 280],PDF点、左上角原点。
Figure 4. The overview of LLMDet. LLMDet contains a standard open-vocabulary detector and a large language model (LLM) and is
trained under both grounding loss and language modeling loss. The LLM is designed to generate both image-level captions using feature
maps as visual input and region-level captions using a single object query as visual input, which are separated by different prompts.
Only vision tokens in region-level generation pass through the cross-attention (CA) modules in LLM, which is highlighted by a dashed
boundary. Since the number of tokens in image-level and region-level generation varies greatly, we forward the LLM twice separately to
save memory and computation. The LLM can be discarded in the inference time so that there is no extra cost.
LLMDet: Learning Strong Open-Vocabulary Object Detectors under the Supervision of Large Language Models
会议:CVPR 2025 · 主会论文
Figure 2 · PDF第3页 · P87
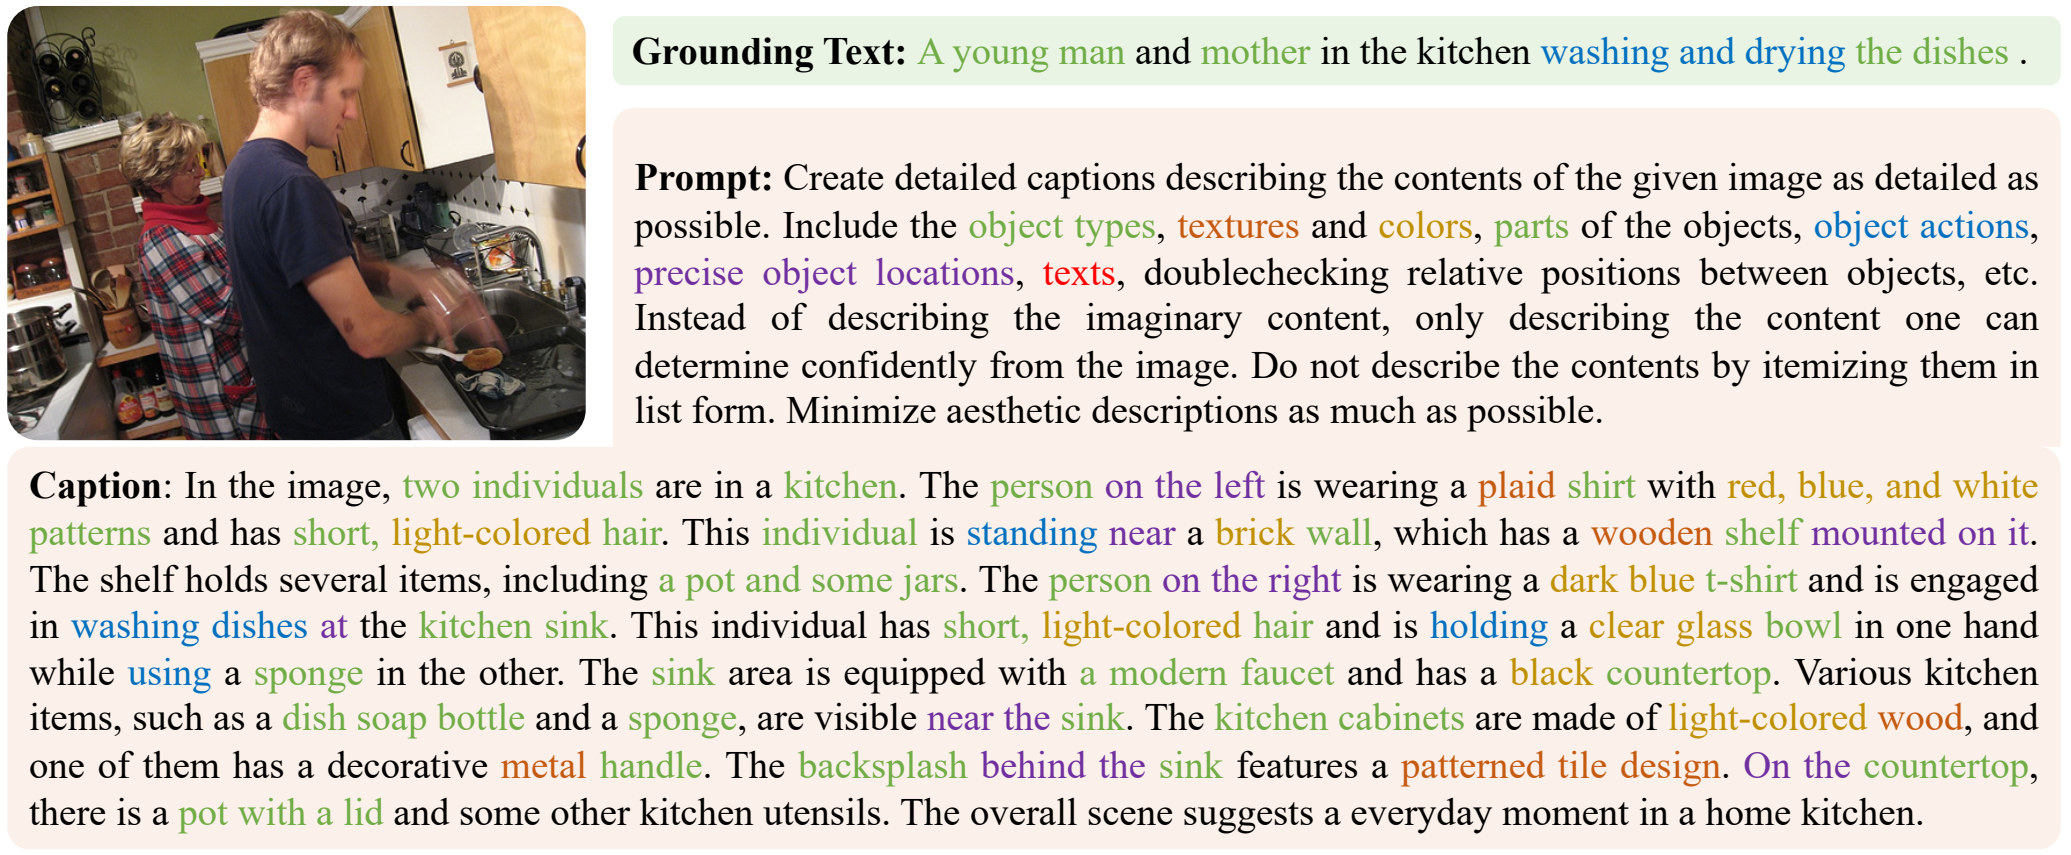
300 dpi PNG · 图注 · 源PDF
引言及数据定义以图2比较短grounding语句与含属性、位置和关系的长图像描述,说明已有短文本监督信息不足的概念。
完整图注、版本和筛选证据
最早核实视觉日期:2025-01-31;arXiv v1:2025-01-31;CVPR 2025 fixed official PDF
已查看固定PDF及目标图;以最早已核实匹配版本日期作时间代理,不声称实际作图日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Wei-Shi Zheng;31913;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 66, 555, 271],PDF点、左上角原点。
Figure 2. An example of GroundingCap-1M. Bounding box annotations are discarded for clarity. Compared with original short grounding
texts, the detailed captions in GroundingCap-1M are rich in object types, textures, colors, parts of the objects, object actions, precise object
locations and texts. Each caption in GroundingCap-1M has around 115 words on average.
Large Self-Supervised Models Bridge the Gap in Domain Adaptive Object Detection
会议:CVPR 2025 · 主会论文
Figure 2 · PDF第4页 · P250
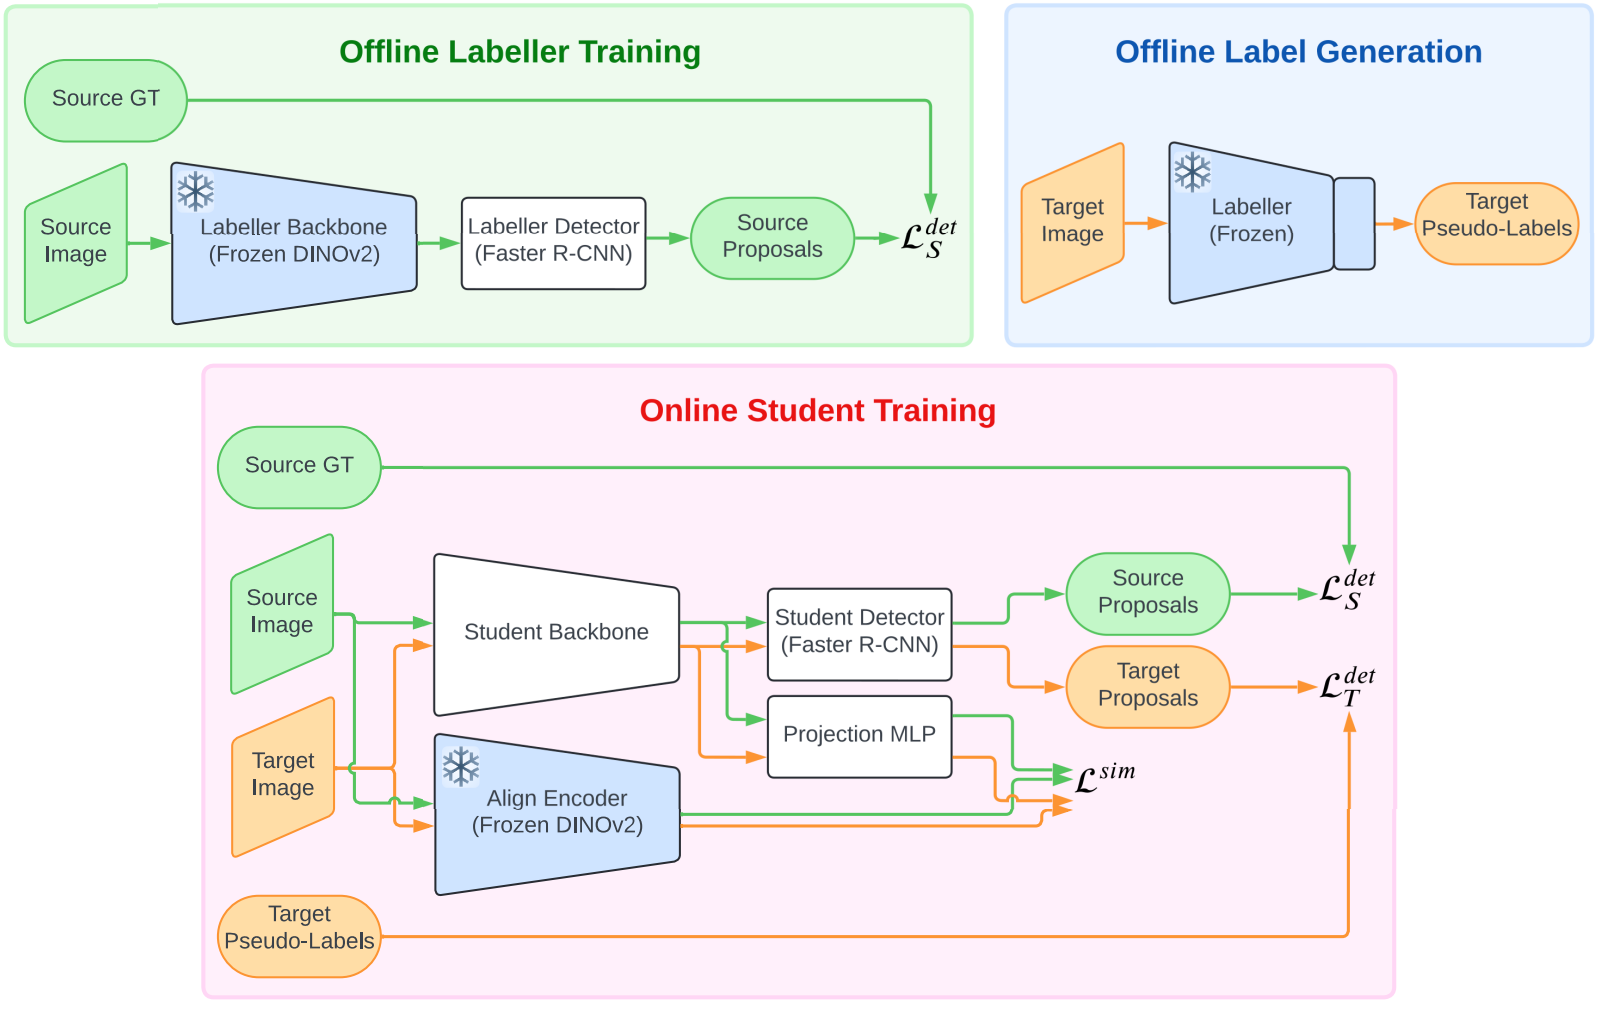
300 dpi PNG · 图注 · 源PDF
图2及第3节明确为整体DINO Teacher框架,包含离线标注器训练、伪标签生成和在线学生训练三个完整步骤。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-29;arXiv v1:2025-03-29;CVPR 2025 fixed official PDF
唯一arXiv v1于2025-03-29公开。固定会议版与v1裁图对照保存;已读图注、引言和第3节整体方法。论文Toronto身份与Steven L. Waslander公开Scholar18395次匹配。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Steven L. Waslander;18395;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[115, 72, 500, 314],PDF点、左上角原点。
Figure 2. Diagram of our proposed method. Offline Labeller Training: we add a detector head to a frozen DINOv2 encoder and train
it with source images only. Offline Label Generation: we combine and freeze the labeller backbone and detector, and generate target
pseudo-labels. Online Student Training: We train a student network using source ground truth boxes and target pseudo-labels, and align
patch features to a frozen DINOv2 encoder. During inference, the alignment encoder and projection MLP are not used.
Large Self-Supervised Models Bridge the Gap in Domain Adaptive Object Detection
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第1页 · P249
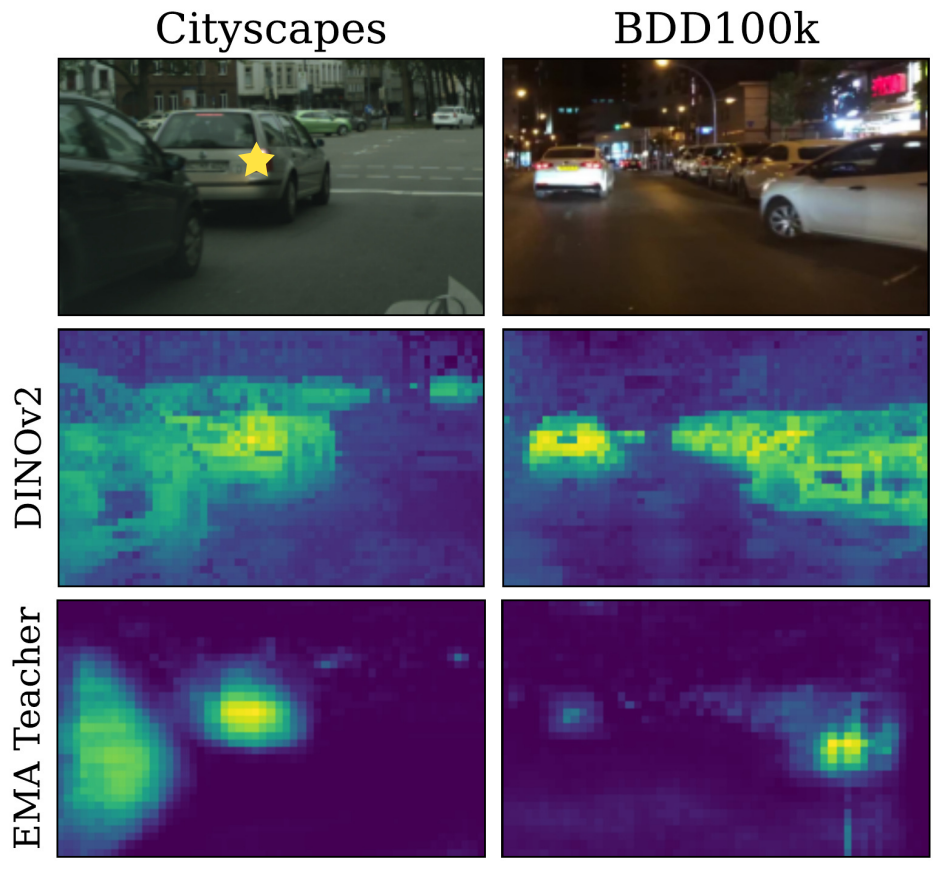
300 dpi PNG · 图注 · 源PDF
图1及引言用跨域特征相似性热图诊断EMA Teacher语义不稳定问题,并解释选择DINOv2特征的动机;不是一般检测结果拼图。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-29;arXiv v1:2025-03-29;CVPR 2025 fixed official PDF
唯一arXiv v1于2025-03-29公开。固定会议版与v1裁图对照保存;已读图注、引言和第3节整体方法。论文Toronto身份与Steven L. Waslander公开Scholar18395次匹配。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Steven L. Waslander;18395;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[322, 234, 548, 443],PDF点、左上角原点。
Figure 1. Cosine similarity of patch feature from Cityscapes to
BDD100k.. We evaluate the similarity between the yellow star re-
gion in the Cityscapes image and all other regions in both images.
Compared to the EMA Teacher, DINOv2 generates semantically
stable features across domains, justifying the choice to use it for
feature alignment and as a frozen backbone for our labeller.
Partial Weakly-Supervised Oriented Object Detection
来源:arXiv 2025 · 图源:存档 arXiv v1 · CVPR 2026 — 投稿另有记录
Figure 2 · PDF第3页 · P240
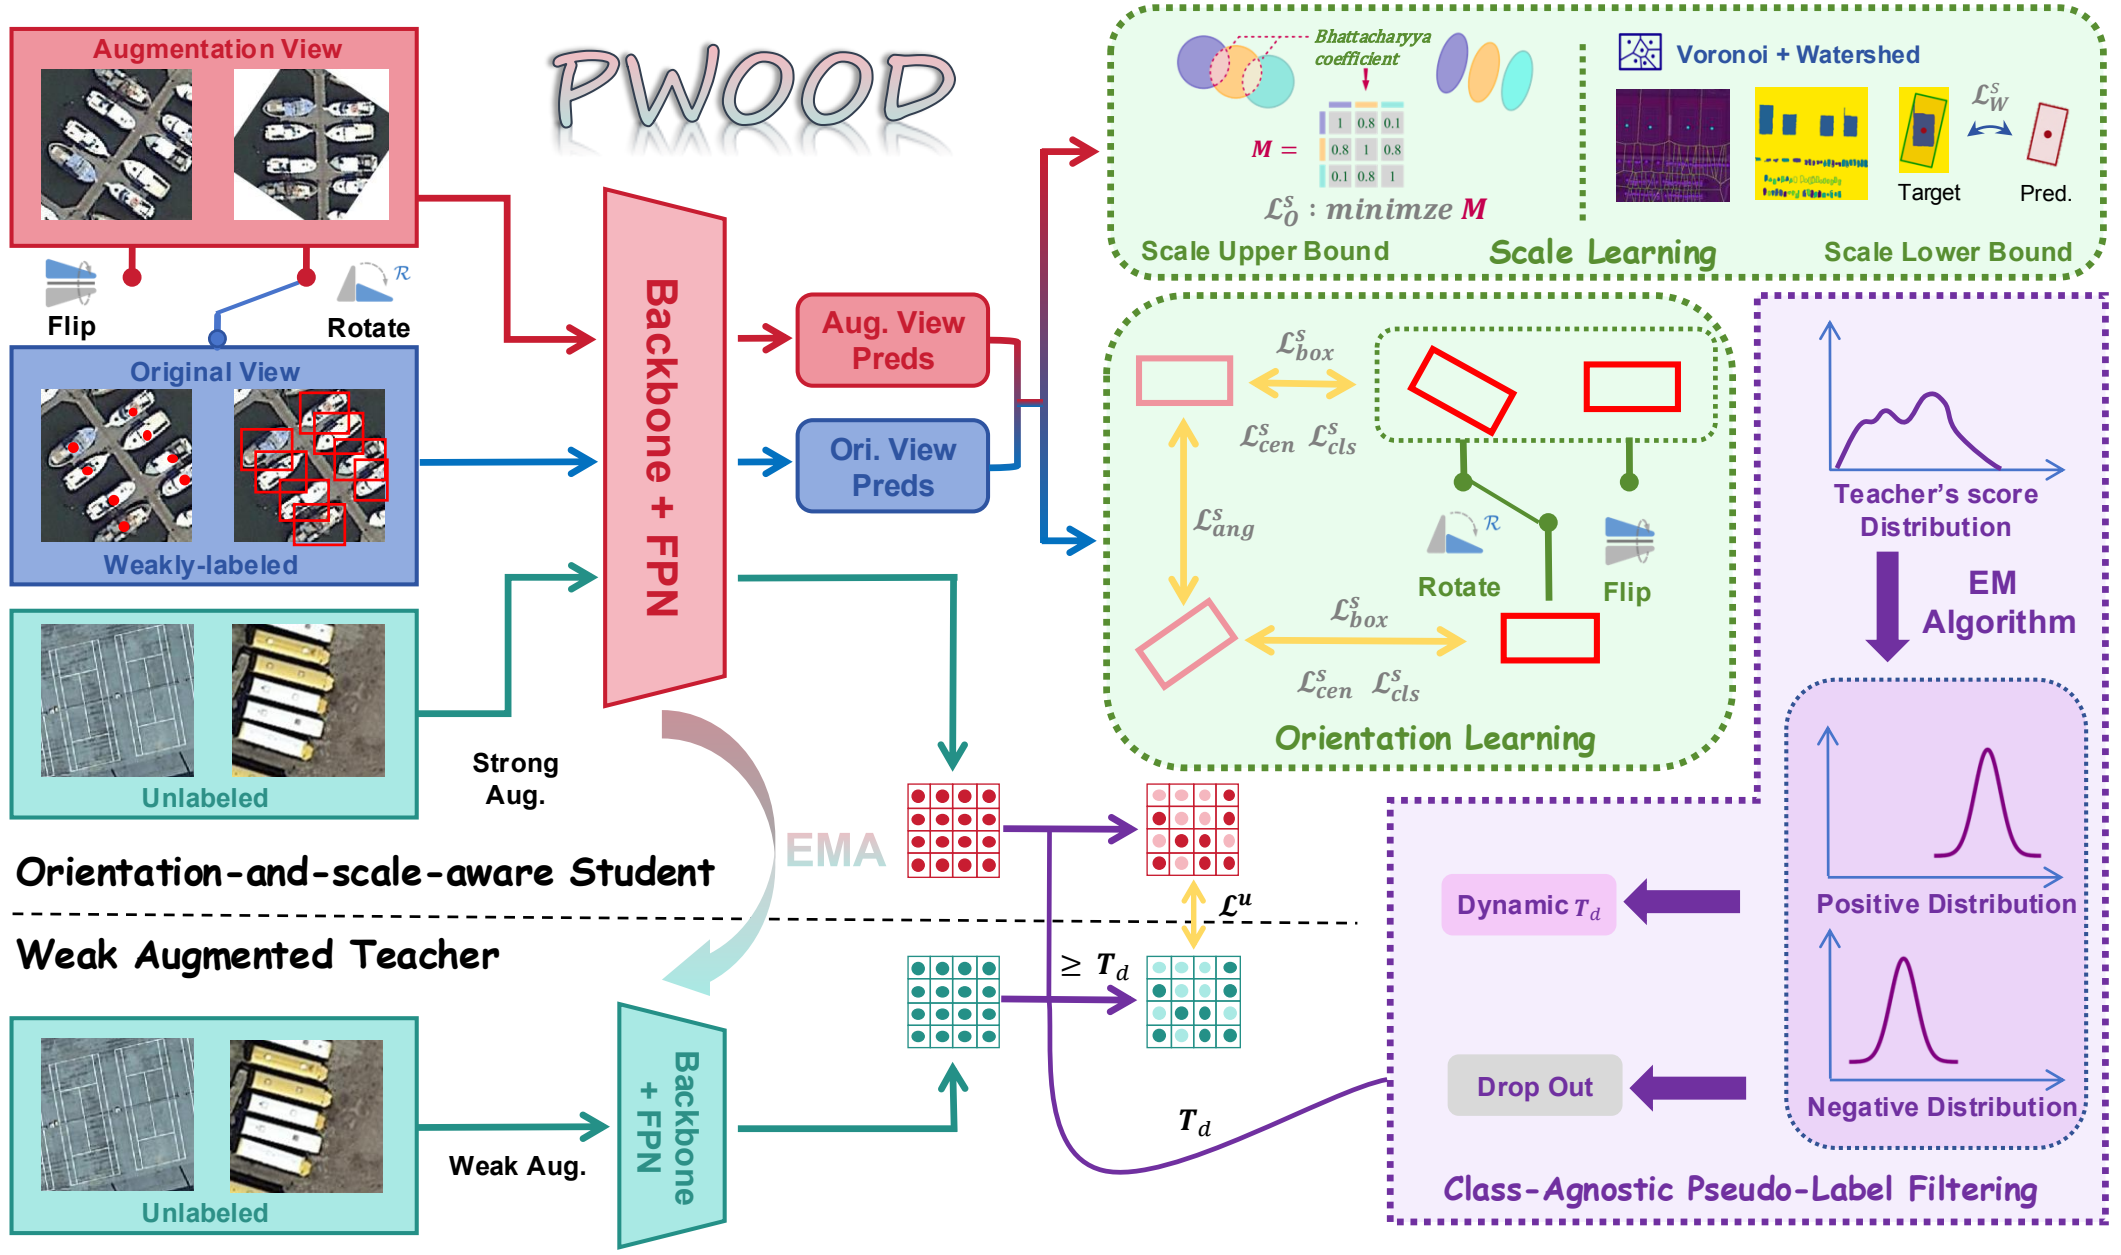
300 dpi PNG · 图注 · 源PDF
图2明确为整体PWOOD框架,含增强输入、师生网络、方向和尺度学习、伪标签过滤及训练反馈。
完整图注、版本和筛选证据
最早核实视觉日期:2025-07-03;arXiv v1:2025-07-03;arXiv v1 fixed
固定采集2025-07-03 arXiv v1图2;后来v2/v3和CVPR2026不用于追溯该样本。已查看v1整体框架和第III节;未发现更早投稿证据。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Xue Yang;14880;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[52, 52, 561, 353],PDF点、左上角原点。
Fig. 2. The overview of the proposed PWOOD framework. Orientation Learning and Scale Learning modules enables the Orientation-and-Scale-aware Student
to learn both scale and orientation information from weakly annotated data, as well as Class-Agnostic Pseudo-Label Filtering mechanism enhances pseudo-label
quality by leveraging dynamic thresholds.
Partial Weakly-Supervised Oriented Object Detection
来源:arXiv 2025 · 图源:存档 arXiv v1 · CVPR 2026 — 投稿另有记录
Figure 1 · PDF第1页 · P239
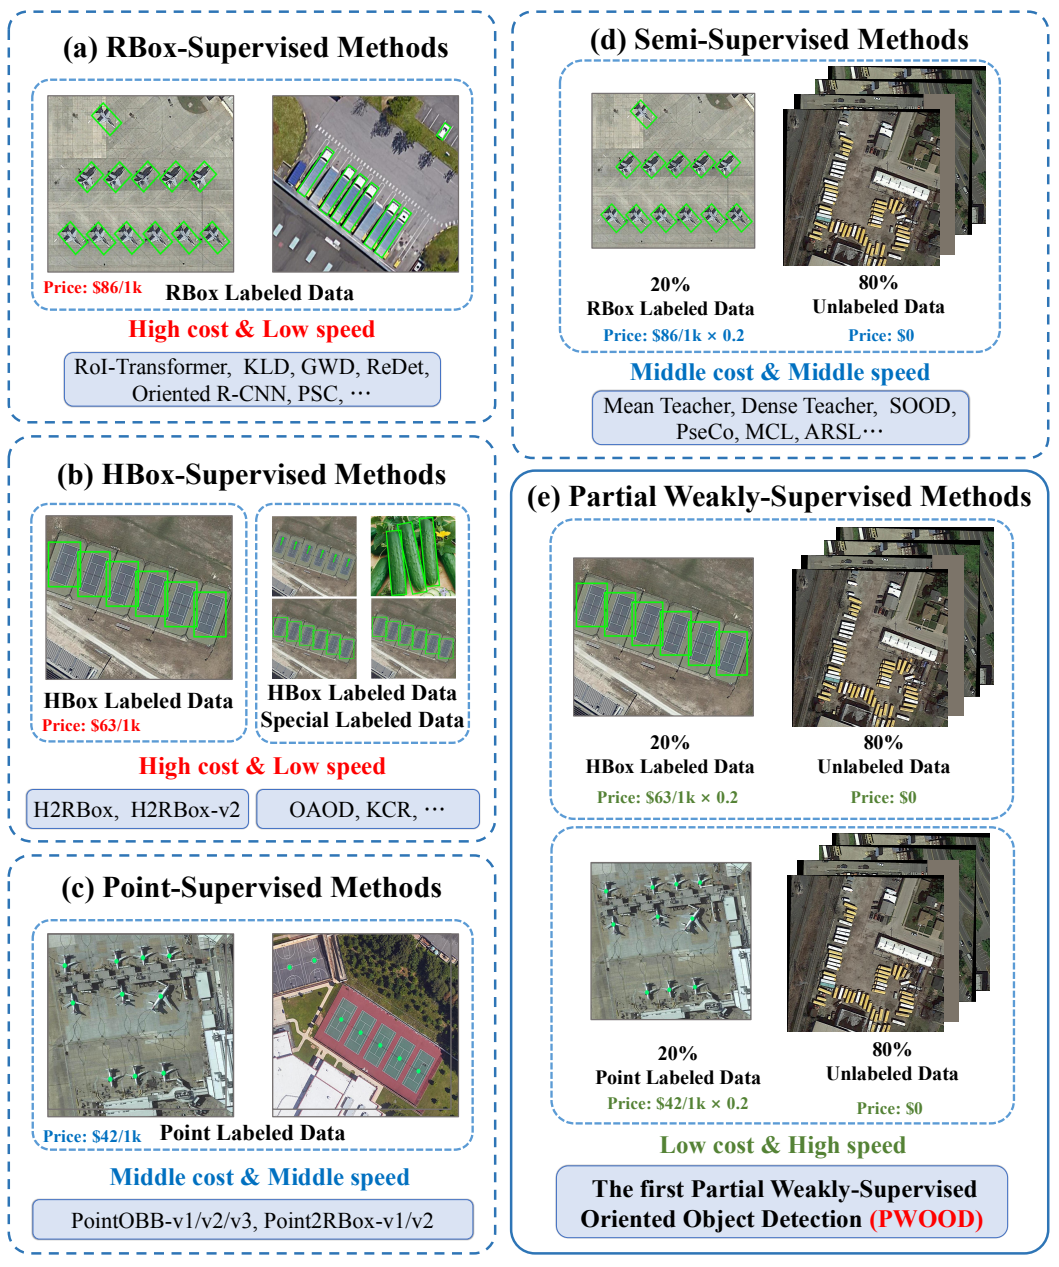
300 dpi PNG · 图注 · 源PDF
图1和引言对比五类旋转检测标注范式及标注成本/速度,说明密集旋转框标注负担;属于问题与概念对比。
完整图注、版本和筛选证据
最早核实视觉日期:2025-07-03;arXiv v1:2025-07-03;arXiv v1 fixed
固定采集2025-07-03 arXiv v1图1;后来v2/v3和CVPR2026不用于追溯该样本。已查看v1完整图与引言;未发现更早投稿证据。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Xue Yang;14880;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[311, 193, 565, 497],PDF点、左上角原点。
Fig. 1. The main paradigmatic types of existing oriented object detec-
tion. Existing methods are primarily divided into rotated boxes (RBox)-
supervised, horizontal boxes (HBox)-supervised, Point-supervised, and Semi-
Supervised approaches. Compared to these settings, our proposed Partial
Weakly-supervised methods have high annotation speed and low costs.
PointOBB: Learning Oriented Object Detection via Single Point Supervision
会议:CVPR 2024 · 主会论文
Figure 2 · PDF第3页 · P272
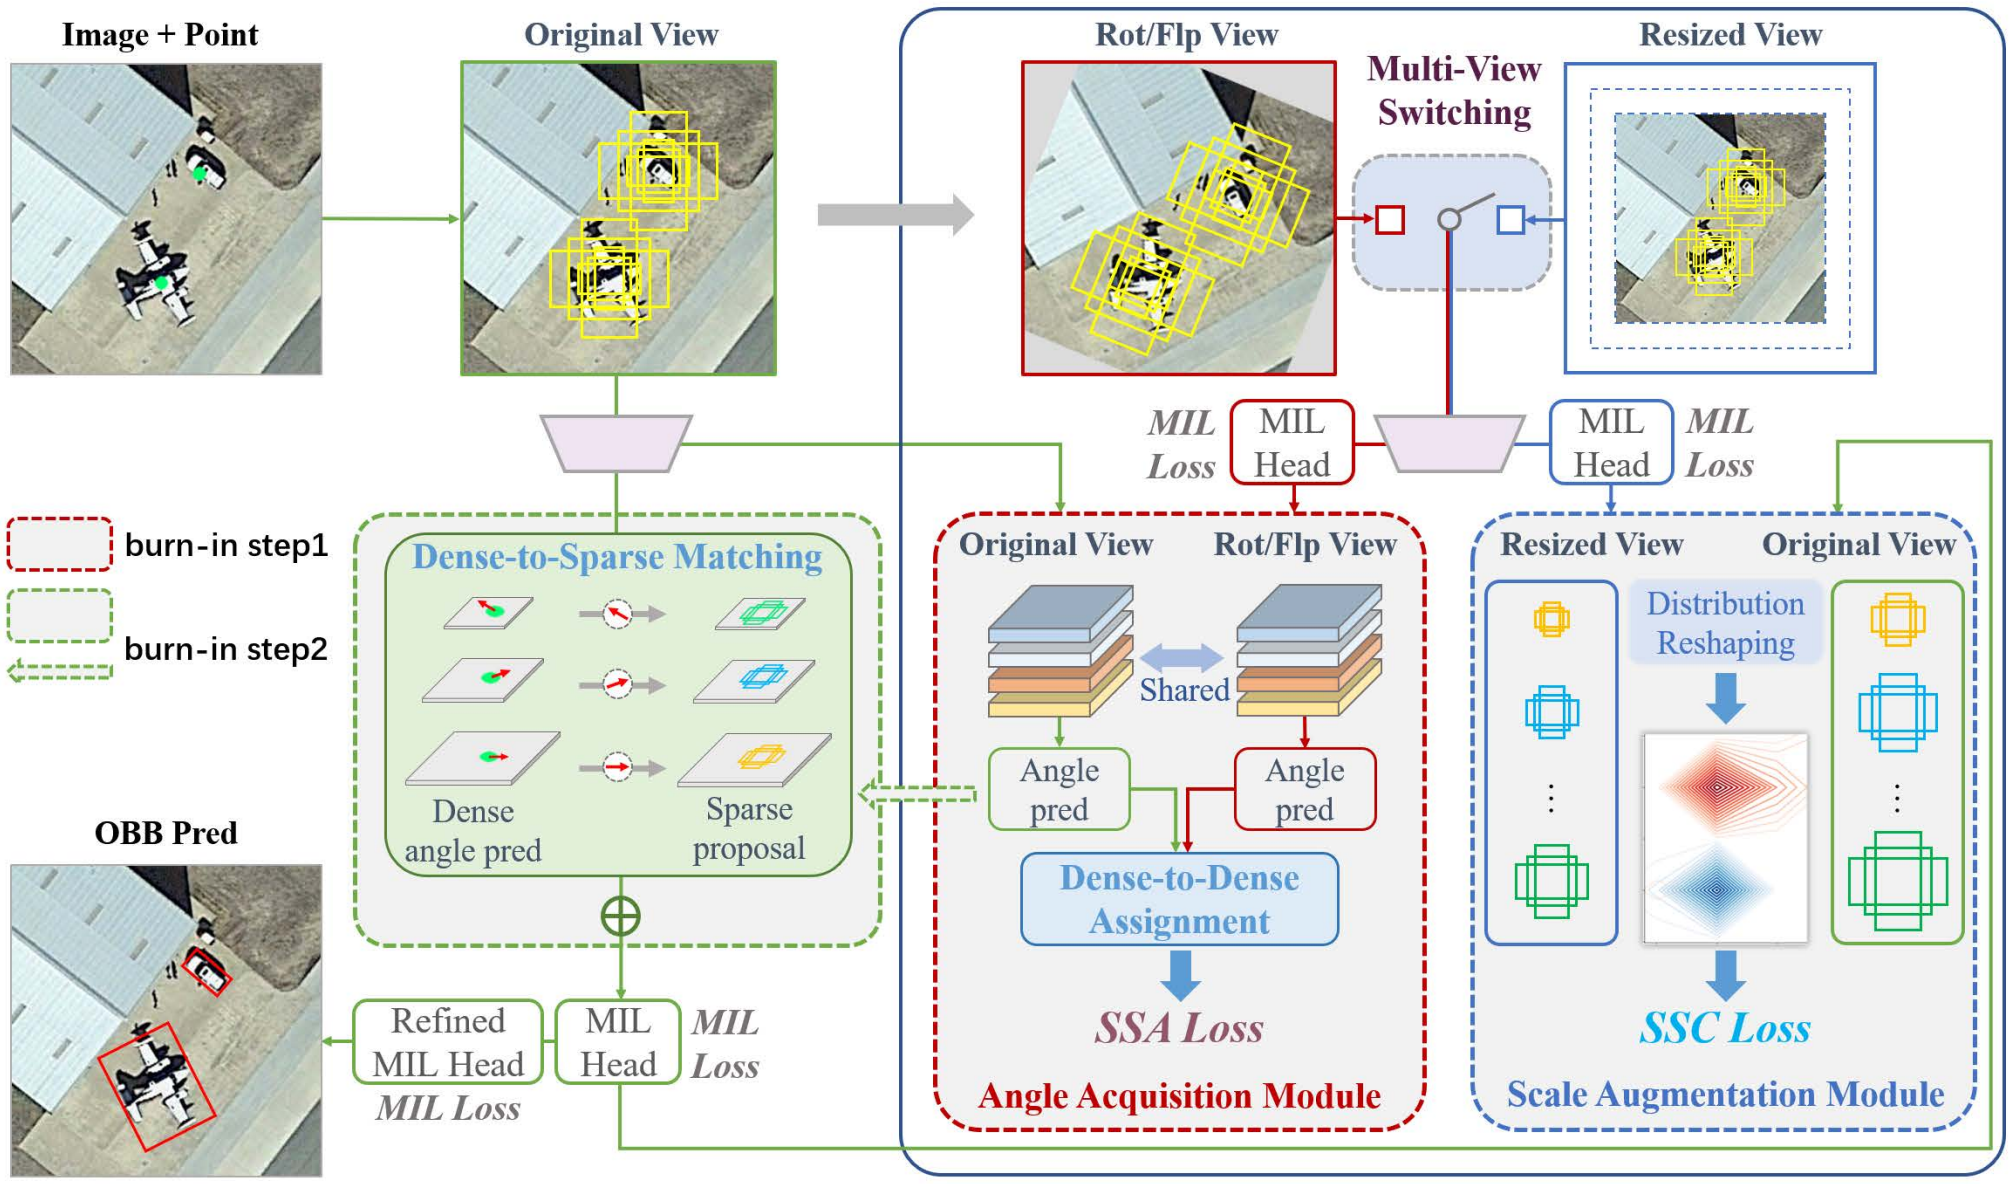
300 dpi PNG · 图注 · 源PDF
图2及3.1节明确为整体PointOBB,保留三视图、尺度增强、角度获取、匹配与输出。
完整图注、版本和筛选证据
最早核实视觉日期:2023-11-23;arXiv v1:2023-11-23;CVPR 2024 fixed official PDF
PointOBB图1在v1上移10pt,校正历史裁剪坐标后图1和图2均像素完全一致;门槛作者改用Junchi Yan,固定PDF的SJTU与Scholar任职经历SJTU(18-)相符。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Junchi Yan;47501;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[56, 74, 539, 358],PDF点、左上角原点。
Figure 2. The pipeline of the PointOBB. PointOBB contains three views in total. From these views, an angle acquisition module and
a scale augmentation module are constructed. The scale augmentation module incorporates a Scale-Sensitive Consistency (SSC) loss to
enhance scale perception ability. Within the angle acquisition module, a Dense-to-Dense sample assignment is designed for angle learning,
optimized using the Self-Supervised Angle (SSA) loss. Additionally, a Dense-to-Sparse (DS) matching strategy is proposed to obtain more
precise object angles. During the training, a progressive multi-view switching strategy is designed to switch the resized and rot/flp views,
along with their corresponding modules.
PointOBB: Learning Oriented Object Detection via Single Point Supervision
会议:CVPR 2024 · 主会论文
Figure 1 · PDF第1页 · P271
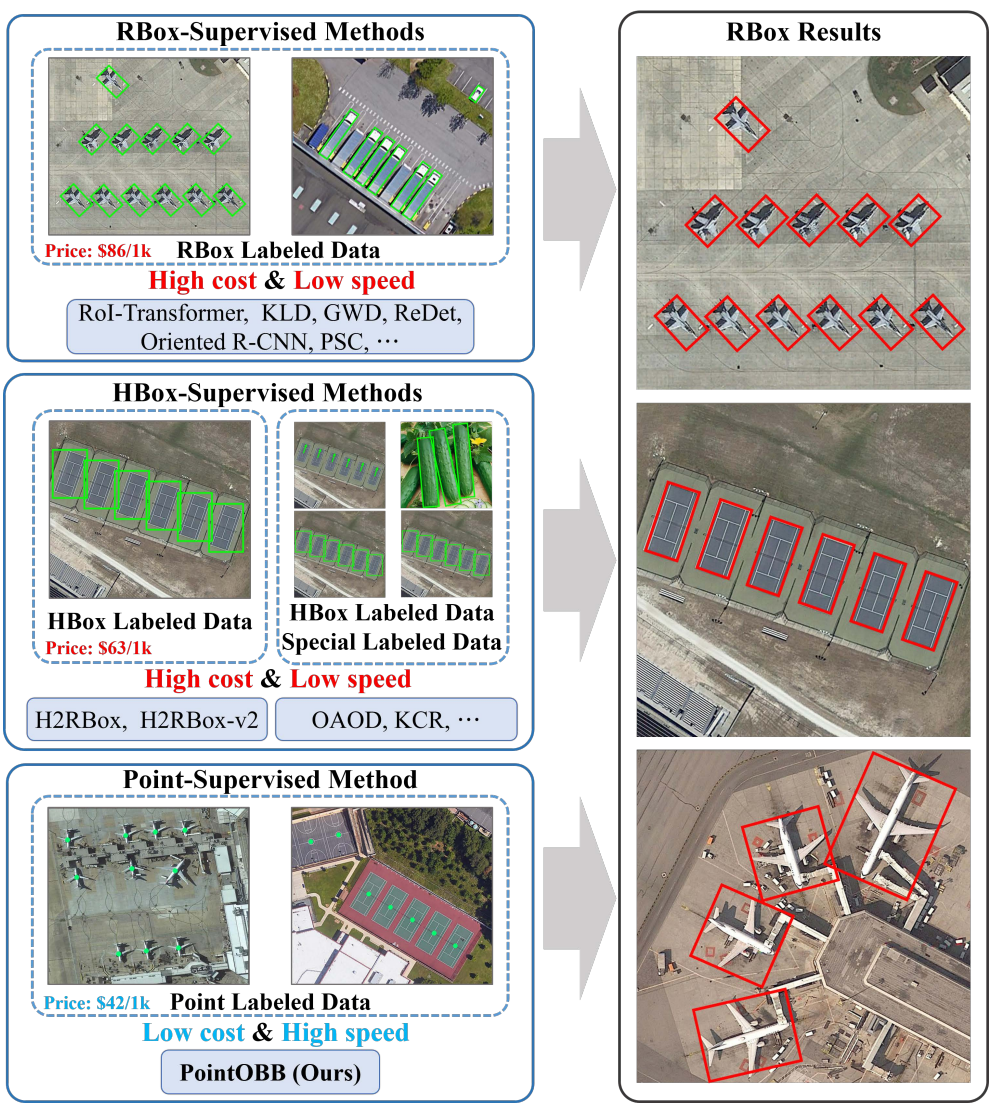
300 dpi PNG · 图注 · 源PDF
图1及引言比较旋转框、水平框和点标注的成本与效率,用问题设定对比引出点监督。
完整图注、版本和筛选证据
最早核实视觉日期:2023-11-23;arXiv v1:2023-11-23;CVPR 2024 fixed official PDF
PointOBB图1在v1上移10pt,校正历史裁剪坐标后图1和图2均像素完全一致;门槛作者改用Junchi Yan,固定PDF的SJTU与Scholar任职经历SJTU(18-)相符。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Junchi Yan;47501;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[308, 250, 547, 516],PDF点、左上角原点。
Figure 1. The main paradigmatic types of existing oriented ob-
ject detection. Existing methods are primarily divided into rotated
boxes (RBox)-supervised, horizontal boxes (HBox)-supervised,
and Point-supervised approaches. Compared to RBox and HBox
labels, point labels have lower costs and higher efficiency.
Search and Detect: Training-Free Long Tail Object Detection via Web-Image Retrieval
会议:CVPR 2025 · 主会论文
Figure 2 · PDF第3页 · P212
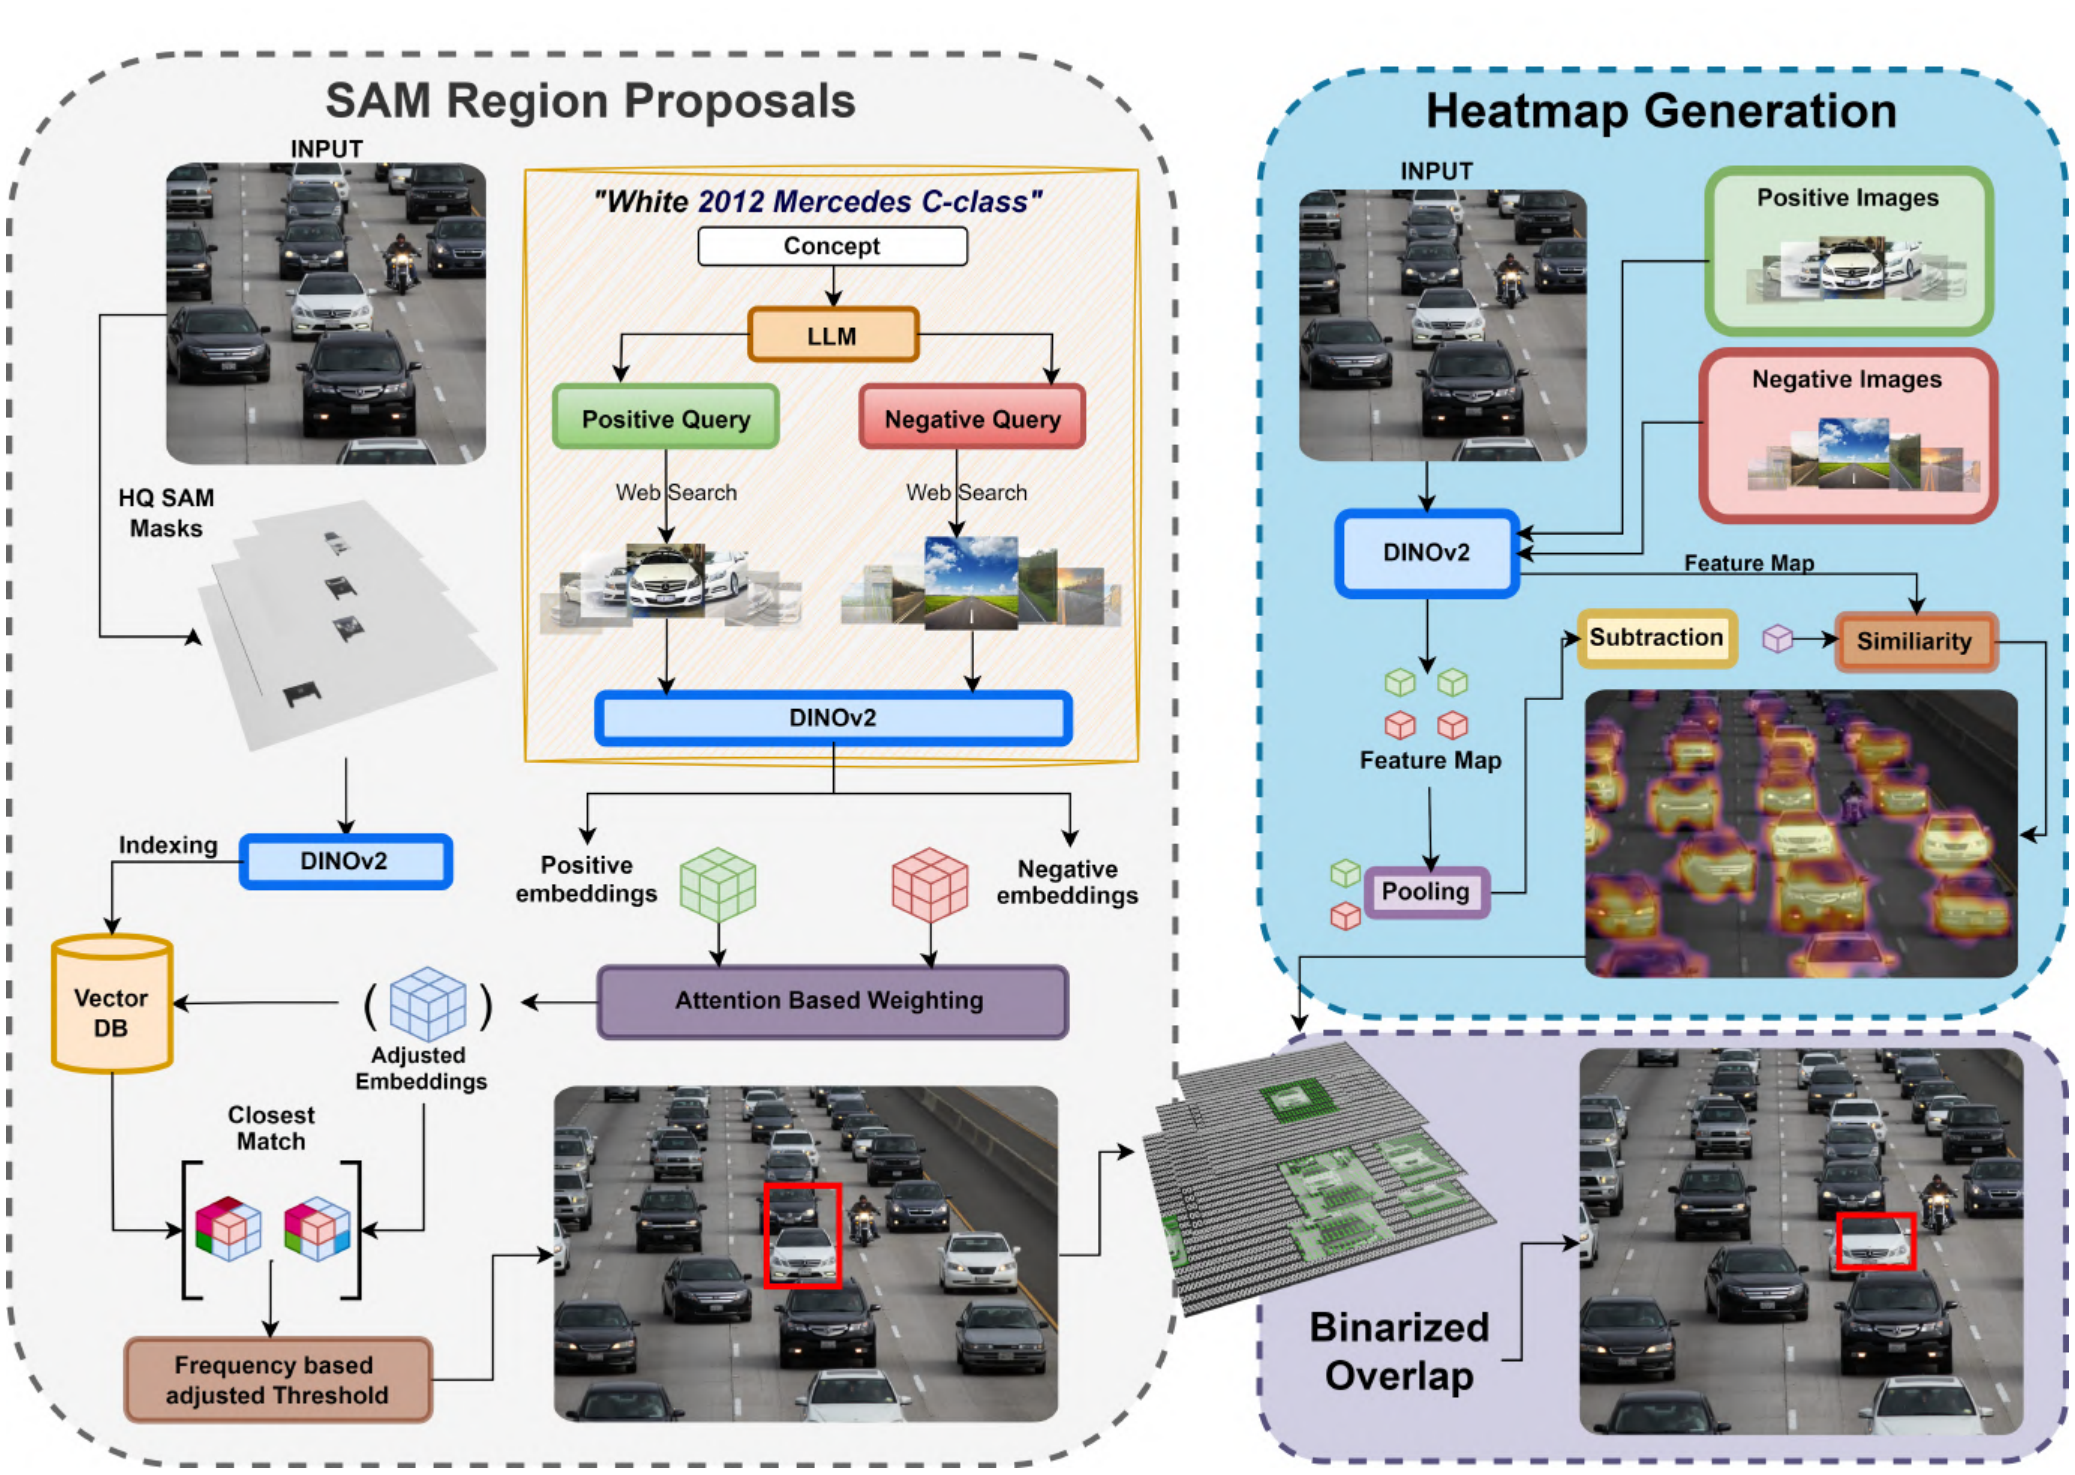
300 dpi PNG · 图注 · 源PDF
图2明确为entire architecture,保留网页支持图检索、正负查询、SAM候选、热力图及最终检测输出流程。
完整图注、版本和筛选证据
最早核实视觉日期:2025-06;arXiv v1:2024-09-26;CVPR 2025 fixed official PDF
已对照唯一arXiv v1及会议版:全局流程相似,但v1的Heatmap Generation分支中蓝色框为空,会议版加入DINOv2标签,并重新压缩图像。不能视为完全相同视觉版本。以CVF官方BibTeX的June 2025记录会议固定图的最早可核实公开月份,整月均在S2。历史PDF仅用于差异对照。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Heng Ji;43364;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[57, 70, 555, 424],PDF点、左上角原点。
Figure 2. The entire architecture of our method. We compare the adjusted embeddings, produced by the DINOv2 model, of the positive
and negative support images, with the relevant masks extracted using the SAM model to provide an initial estimate of our segmentation
BBox. We again use DINOv2 for generating pixel-precise heatmaps which provide another estimate for the segmentation. We combine
both these estimates using a binarized overlap to get the final segmentation mask.
Search and Detect: Training-Free Long Tail Object Detection via Web-Image Retrieval
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第1页 · P211
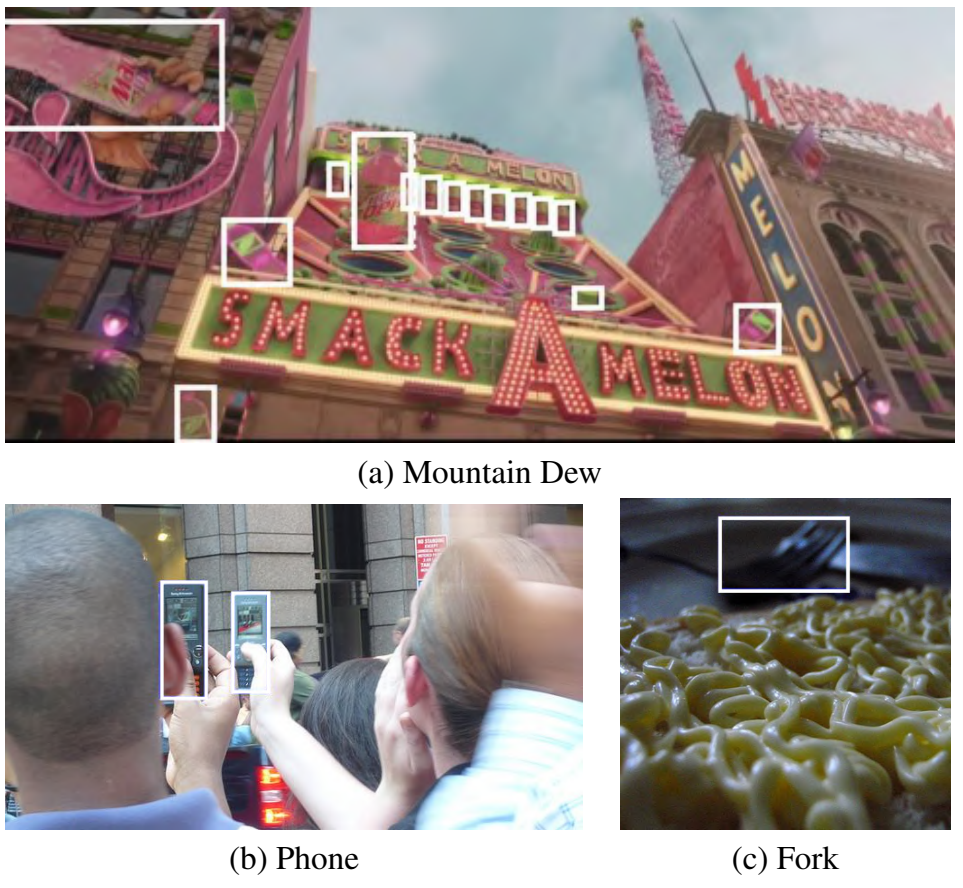
300 dpi PNG · 图注 · 源PDF
图1图注明确说明GroundingDINO漏检Mountain Dew瓶子的失败案例,配合品牌和长尾概念场景引出检索式检测需求。
完整图注、版本和筛选证据
最早核实视觉日期:2025-06;arXiv v1:2024-09-26;CVPR 2025 fixed official PDF
已对照唯一arXiv v1(2024-09-26):图1下排为Dog/Aerial Boat;会议版换为Phone/Fork并调整尺度,不能回填v1日期。固定会议图的可核实公开时间为CVF官方BibTeX注明的June 2025,保留月份精度及整月范围;该范围完全位于S2。历史PDF仅作非匹配版本对照。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Heng Ji;43364;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[316, 230, 547, 443],PDF点、左上角原点。
Figure 1. Detection results for label “Mountain Dew”. While the
GroundingDINO, one of the state-of-the-art grounded object de-
tection methods, fails to capture the Mountain Dew bottles in the
image displayed in the figure, SearchDet manages to ground every
instance of Mountain Dew that appears in the image. Detection
results for other classes “Phone” and “Fork”.
Beyond Background Shift: Rethinking Instance Replay in Continual Semantic Segmentation
会议:CVPR 2025 · 主会论文
Figure 4 · PDF第5页 · P246
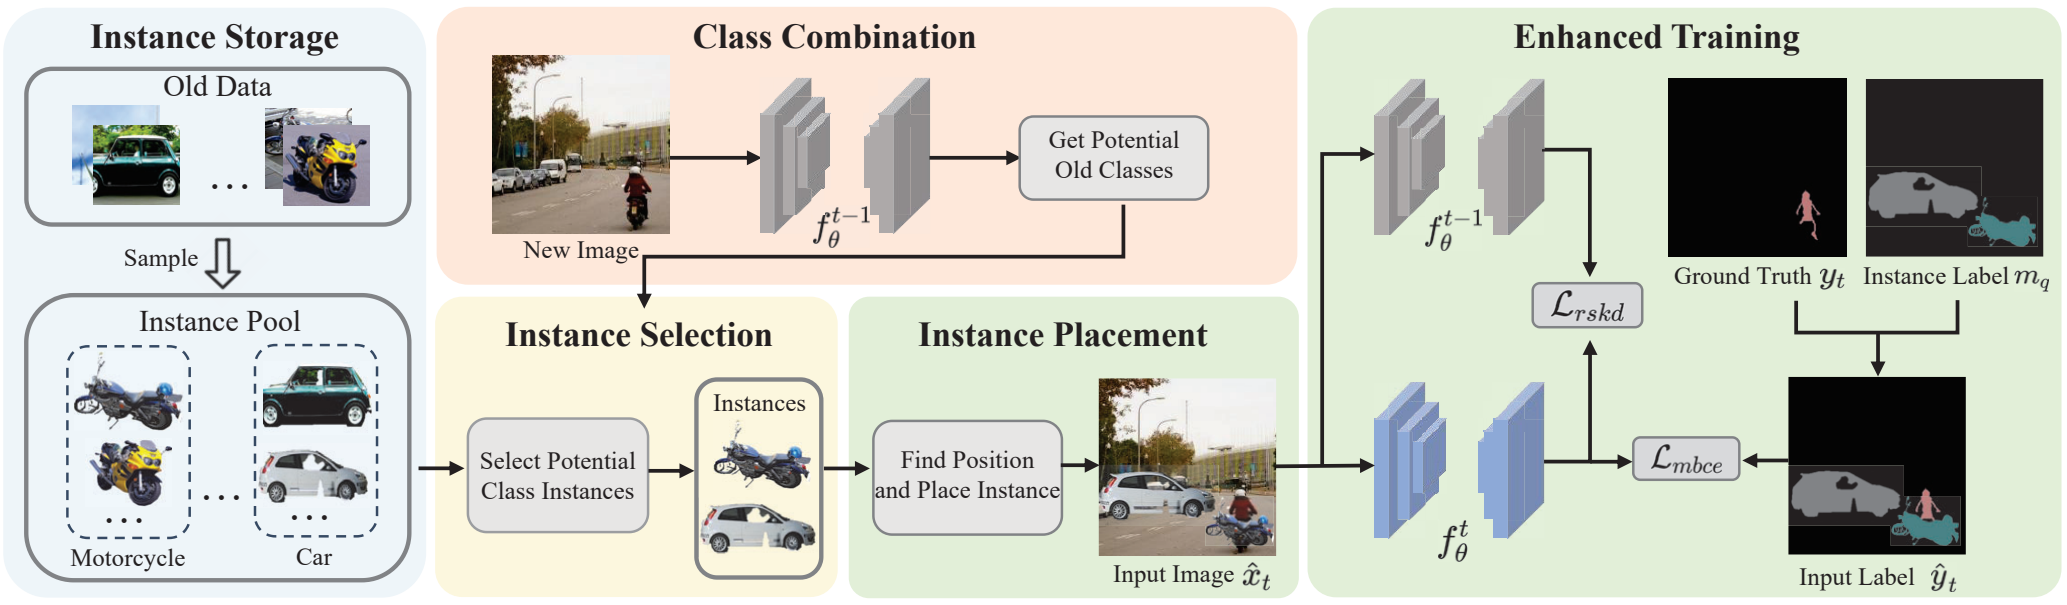
300 dpi PNG · 图注 · 源PDF
图4整体结构完整包含实例存储、类别组合、实例选择与放置、增强训练及蒸馏损失,正文第4节整体引用。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-28;arXiv v1:2025-03-28;CVPR 2025 fixed official PDF
已查看唯一arXiv v1(2025-03-28)和固定会议版目标图;构图、元素、连线、文字相同。PDF对象证据显示v1使用DeviceRGB,会议版使用DeviceCMYK/Indexed-CMYK,黑底及照片有出版色彩转换和压缩差异;不将此机械转换认定为重绘。保留两版完整裁图以供复核。作者Tianjin University身份匹配Wei Feng公开Scholar11058次。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Wei Feng;11058;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 61, 554, 206],PDF点、左上角原点。
Figure 4. The detailed architecture of our method. Initially, we sample instances from the old data according to their classes. Subsequently,
during the class combination, we identify the potential old classes through the old model. In the instance selection, we select the instances
of potential classes from the instance pool. After that, we calculate the position in new image to replay the instance and fuse them with the
new image to create a fused image. Finally, the fused image is trained in an enhanced way.
Beyond Background Shift: Rethinking Instance Replay in Continual Semantic Segmentation
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第1页 · P245
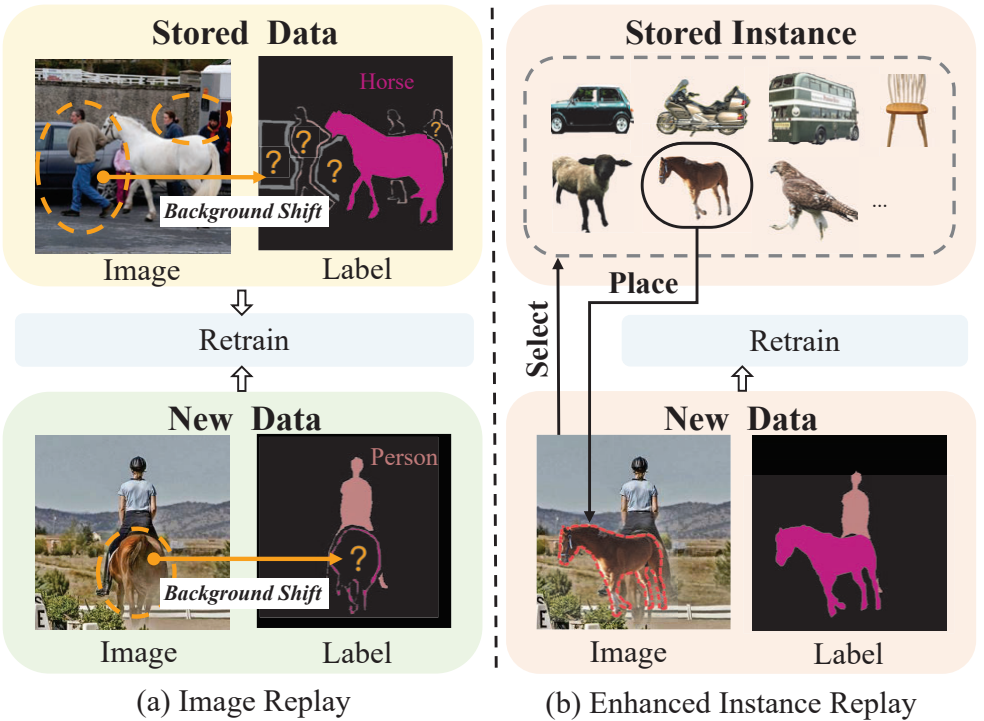
300 dpi PNG · 图注 · 源PDF
图1及引言明确展示部分标注将旧/未来类别错当背景的问题,与实例回放概念对比;不是普通结果展示。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-28;arXiv v1:2025-03-28;CVPR 2025 fixed official PDF
已查看唯一arXiv v1(2025-03-28)和固定会议版目标图;构图、元素、连线、文字相同。PDF对象证据显示v1使用DeviceRGB,会议版使用DeviceCMYK/Indexed-CMYK,黑底及照片有出版色彩转换和压缩差异;不将此机械转换认定为重绘。保留两版完整裁图以供复核。作者Tianjin University身份匹配Wei Feng公开Scholar11058次。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Wei Feng;11058;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[318, 263, 554, 436],PDF点、左上角原点。
Figure 1. Comparison of traditional image replay (a) and our re-
play methods (b). (a) shows that only the old class “horse” is la-
beled in stored image, while other classes (new class “person” and
old class “car”) are labeled as background. Both old (“horse”) and
future classes in new images are labeled as background. (b) Our
method avoids confusing information in stored image by retaining
instances and alleviates background shift by fusing these instances
in the new image.
DFormerv2: Geometry Self-Attention for RGBD Semantic Segmentation
会议:CVPR 2025 · 主会论文
Figure 4 · PDF第4页 · P180
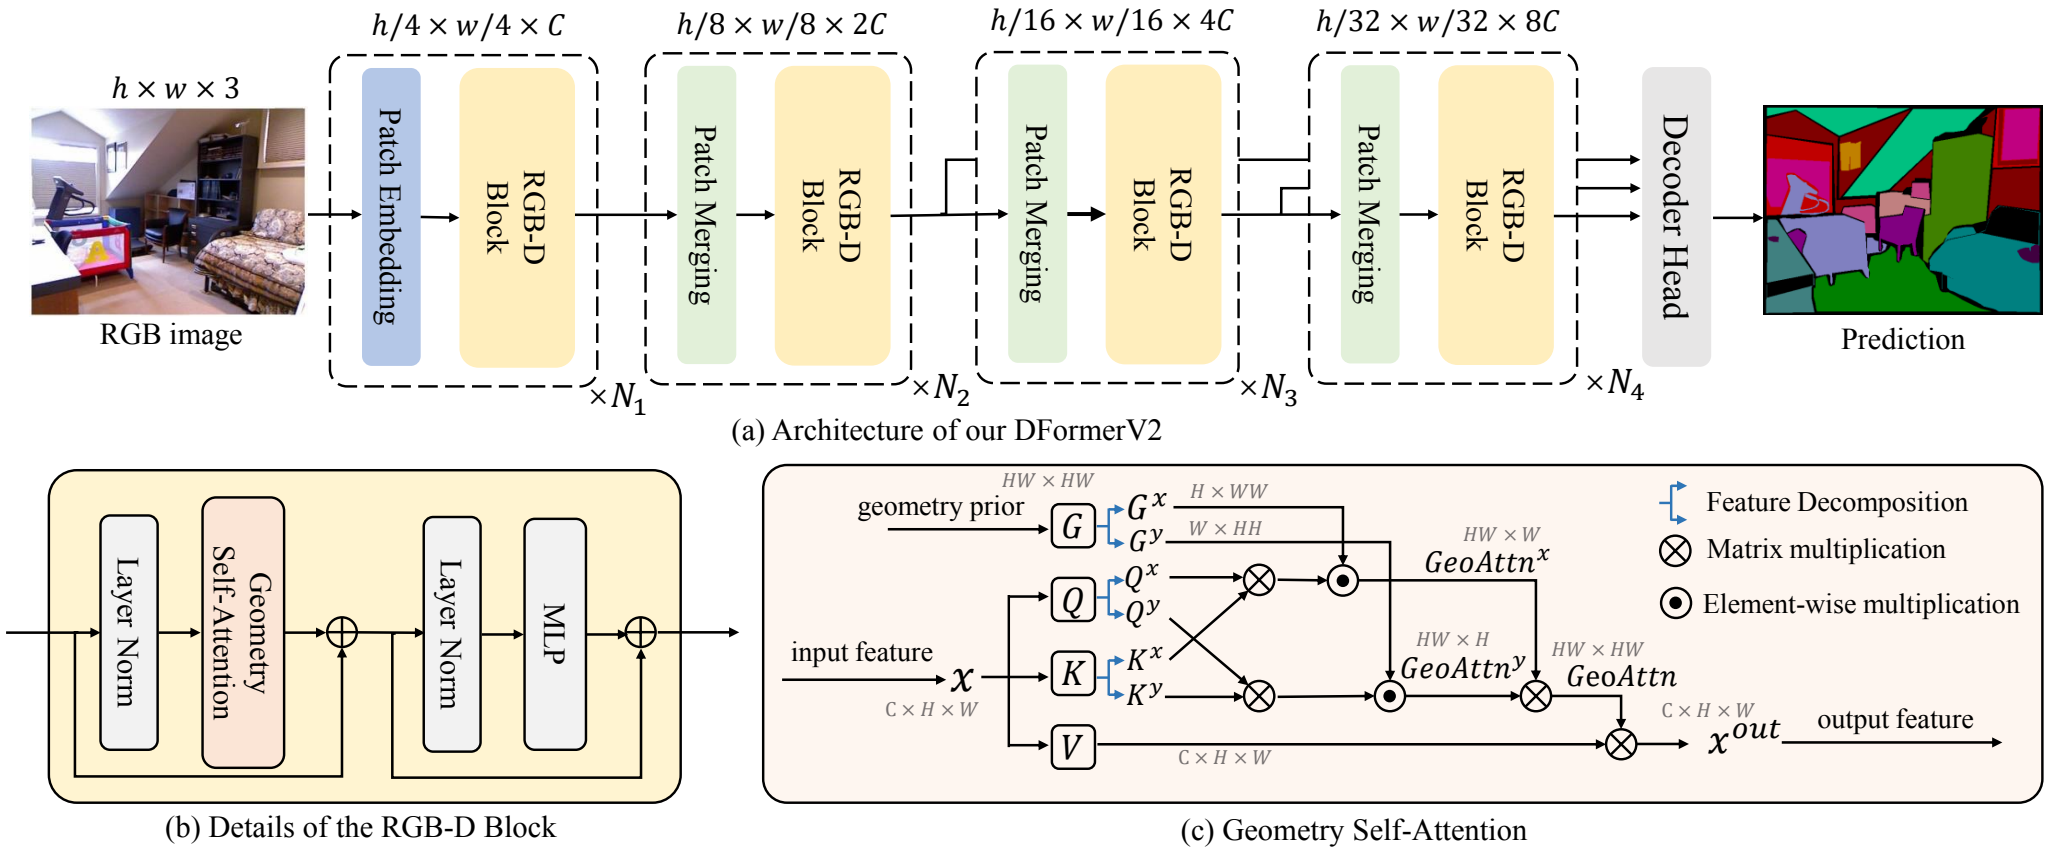
300 dpi PNG · 图注 · 源PDF
第3节及图4(a)明确为整体金字塔编码与解码架构,保留同图(b)(c)模块细节,完整展示预测路径。
完整图注、版本和筛选证据
最早核实视觉日期:2025-04-07;arXiv v1:2025-04-07;CVPR 2025 fixed official PDF
唯一arXiv版本v1与固定CVPR图同坐标300dpi裁剪完全一致(MAE=0);作者Ming-Ming Cheng的南开大学身份与引用主页一致。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Ming-Ming Cheng;85763;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[60, 70, 552, 274],PDF点、左上角原点。
Figure 4. Illustration of our DFormerv2. (a) Overall architecture of our DFormerv2, which contains an encoder with pyramid structure
and a decoder head that receives input from the last three stage features. (b) Detailed structure of the basic building block. (c) Detailed
illustration of the proposed geometry self-attention mechanism.
DFormerv2: Geometry Self-Attention for RGBD Semantic Segmentation
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第1页 · P179
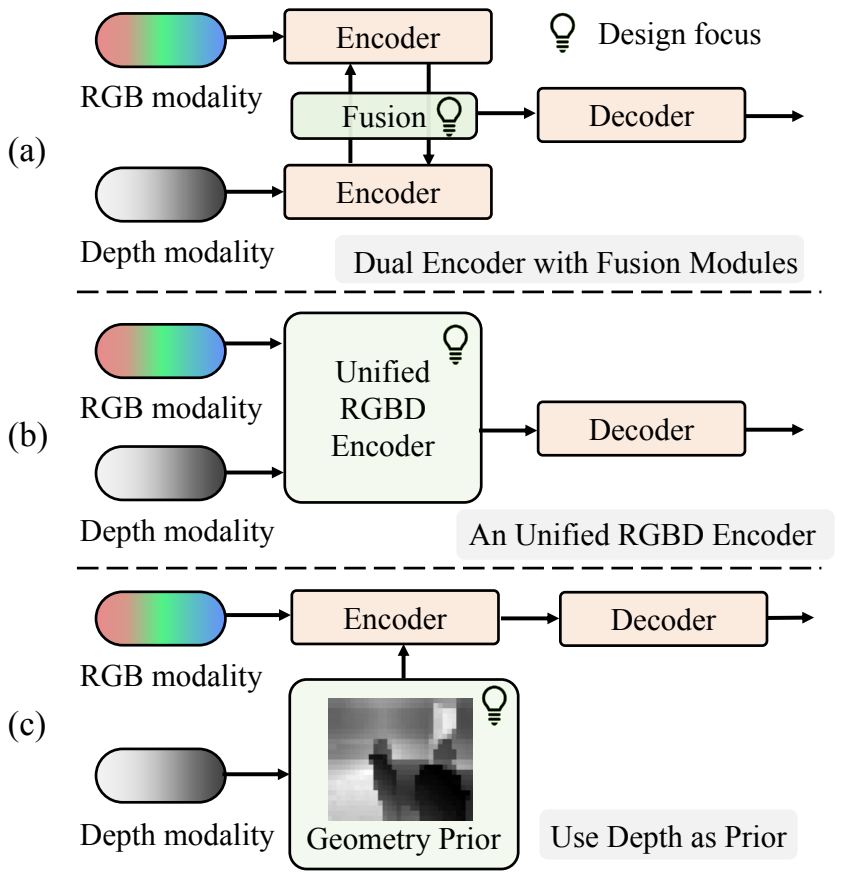
300 dpi PNG · 图注 · 源PDF
引言与图1比较双编码器、联合编码器与几何先验三种处理思路,指出深度与RGB模态差异被忽略的问题。
完整图注、版本和筛选证据
最早核实视觉日期:2025-04-07;arXiv v1:2025-04-07;CVPR 2025 fixed official PDF
唯一arXiv版本v1与固定CVPR图同坐标300dpi裁剪完全一致(MAE=0);作者Ming-Ming Cheng的南开大学身份与引用主页一致。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Ming-Ming Cheng;85763;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[333, 212, 535, 422],PDF点、左上角原点。
Figure 1. Comparisons among the main RGBD segmentation
pipelines and our approach. (a) Use dual encoders to encode
RGB and depth respectively and design fusion modules to fusion
them [28, 61]; (b) Adopt an unified RGBD encoder to extract and
fuseRGBDfeatures[1,59]; (c)OurDFormerv2usedepthtoform
ageometrypriorofthesceneandthenenhancethevisualfeatures.
DPSeg: Dual-Prompt Cost Volume Learning for Open-Vocabulary Semantic Segmentation
会议:CVPR 2025 · 主会论文
Figure 4 · PDF第4页 · P238
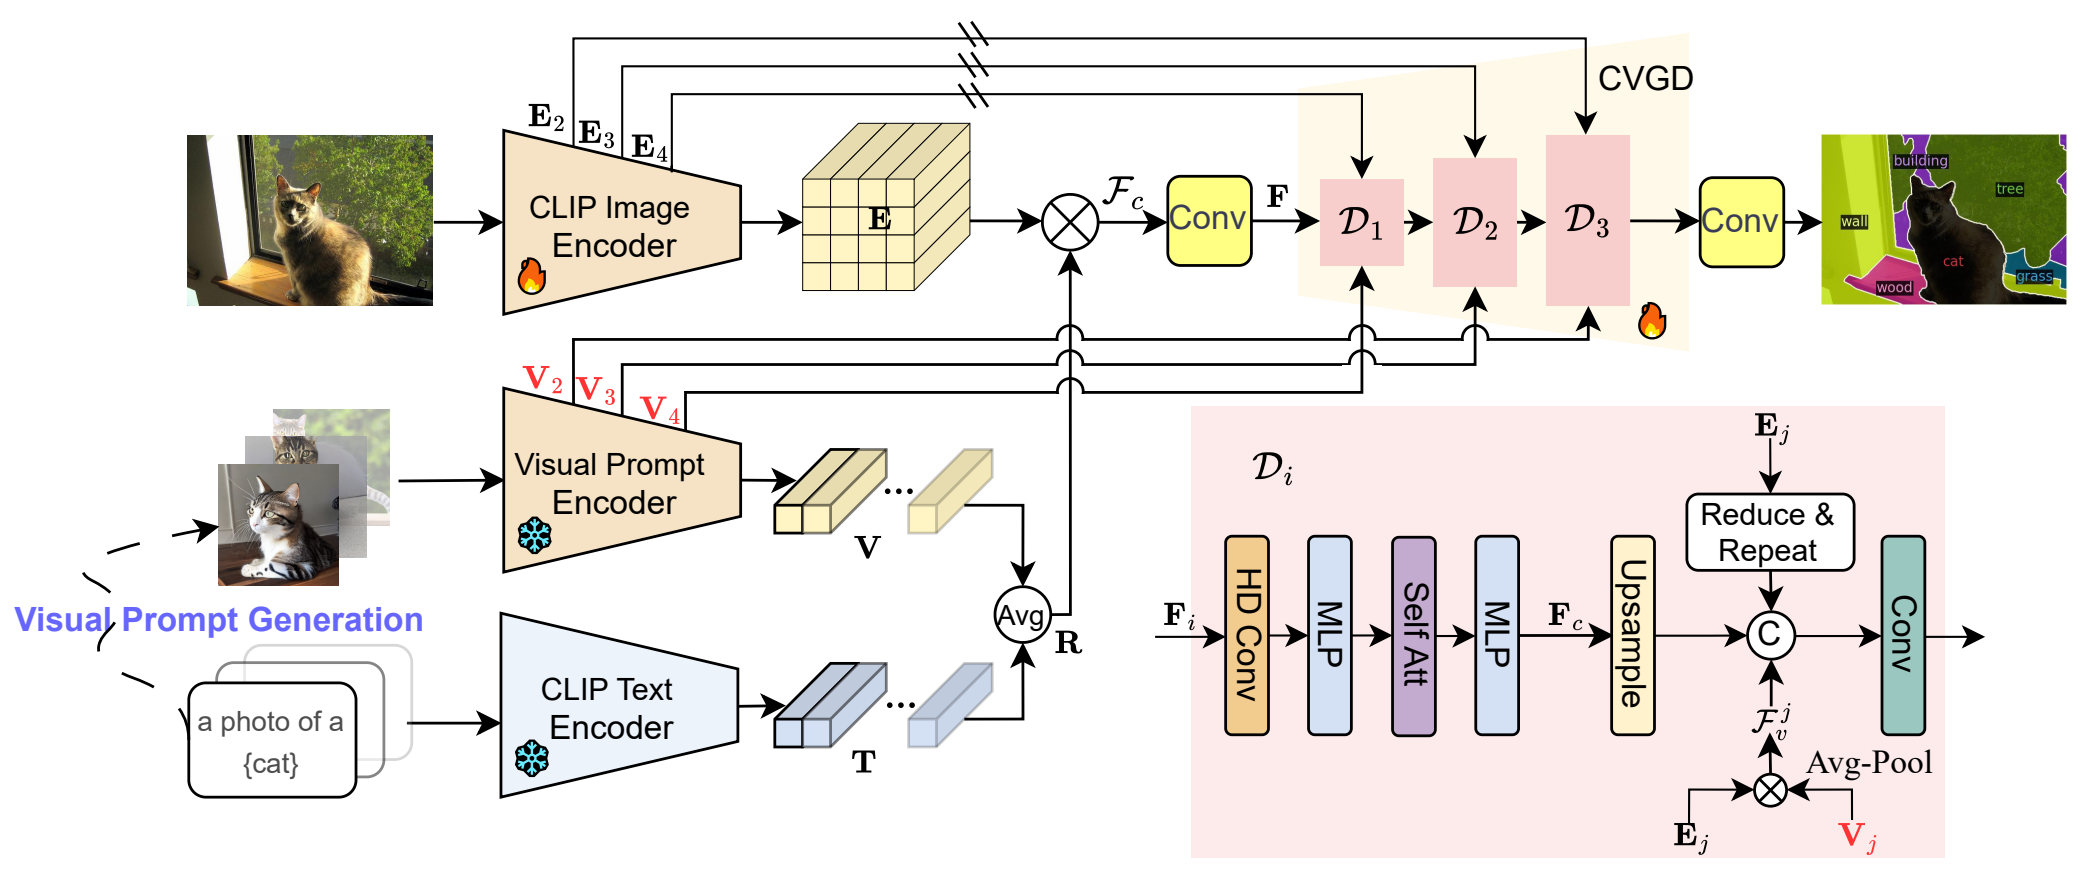
300 dpi PNG · 图注 · 源PDF
图4明确为DPSeg网络架构,完整展示图像/视觉提示/文本提示编码、代价体和解码器到分割输出。
完整图注、版本和筛选证据
最早核实视觉日期:2025-05-16;arXiv v1:2025-05-16;CVPR 2025 fixed official PDF
已查看唯一v1(2025-05-16)与会议版,完整框架一致。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Song Wang;16213;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[56, 68, 557, 277],PDF点、左上角原点。
Figure 4. Architecture of our DPSeg network. We begin by generating visual prompts based on text prompt templates, which are then
combined with text prompts to create the dual-prompt cost volume. Subsequently, we incorporate multi-scale image features and corre-
sponding visual prompt embeddings into the cost volume-guided decoder (CVGD) in a progressive manner.
DPSeg: Dual-Prompt Cost Volume Learning for Open-Vocabulary Semantic Segmentation
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第1页 · P237
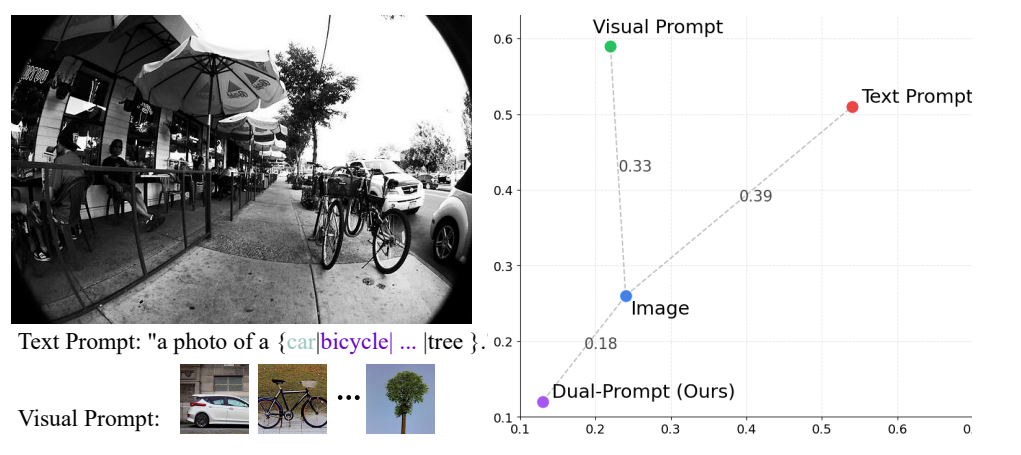
300 dpi PNG · 图注 · 源PDF
图1与摘要、引言及第3节Discussion and Motivation明确展示图像/文本嵌入模态间隙;图中距离用于解释问题,不是模型性能排行榜。
完整图注、版本和筛选证据
最早核实视觉日期:2025-05-16;arXiv v1:2025-05-16;CVPR 2025 fixed official PDF
已查看唯一v1(2025-05-16)与会议版,目标图构图和标签一致。右端坐标刻度在原PDF嵌入图中已不完整,扩大裁剪仍相同,保留原图,不补字。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Song Wang;16213;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[315, 230, 560, 339],PDF点、左上角原点。
Figure 1. T-SNE visualization of embeddings in CLIP feature
space, showing text prompt, visual prompt, target image, and
our dual-prompt for a street scene image. Numbers indicate dis-
tance to image feature, where our dual-prompt approach achieves
closest proximity (0.18).
Distilling Spectral Graph for Object-Context Aware Open-Vocabulary Semantic Segmentation
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第1页 · P128
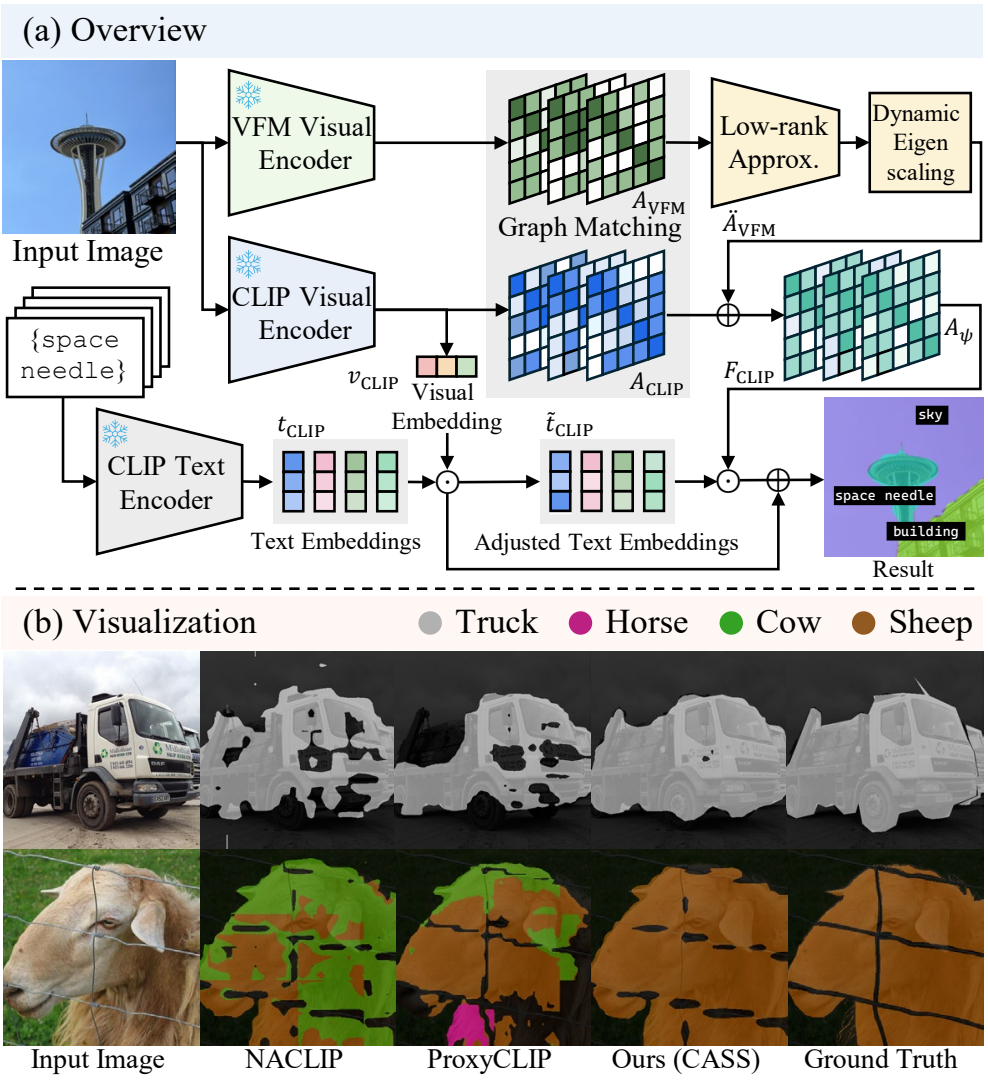
300 dpi PNG · 图注 · 源PDF
图1(a)明确为整体模型Overview,包含两类视觉编码器、图谱匹配、低秩近似及文本更新路径;完整保留同图(b)的示例,不拆分重复计数。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-16;arXiv v1:2024-11-26;CVPR 2025 fixed official PDF
v1图1尚使用Embedding文字且存在底纹等差异;v2完整图匹配会议版,逐像素一致,v3未改变。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Ming-Hsuan Yang;189781;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[317, 245, 554, 505],PDF点、左上角原点。
Figure 1. We present CASS, object-level Context-Aware
training-free open-vocabulary Semantic Segmentation model. (a)
Overview: Our method distills the vision foundation model’s
(VFM)object-levelcontextualspectralgraphintoCLIP’sattention
and refines query text embeddings towards object-specific seman-
tics. (b) Object-Level Context: This result illustrates how incor-
porating object-level context improves segmentation accuracy by
unifying object-wise components into a user-defined object class;
forexample,(toprow)ourapproachpreciselysegmentsthetruck’s
body, wheels, and cargo area and (bottom row) accurately groups
elements into a single object, such as the sheep, whereas base-
lines [16, 29] often fail to achieve this unified segmentation.
Distilling Spectral Graph for Object-Context Aware Open-Vocabulary Semantic Segmentation
会议:CVPR 2025 · 主会论文
Figure 3 · PDF第4页 · P127
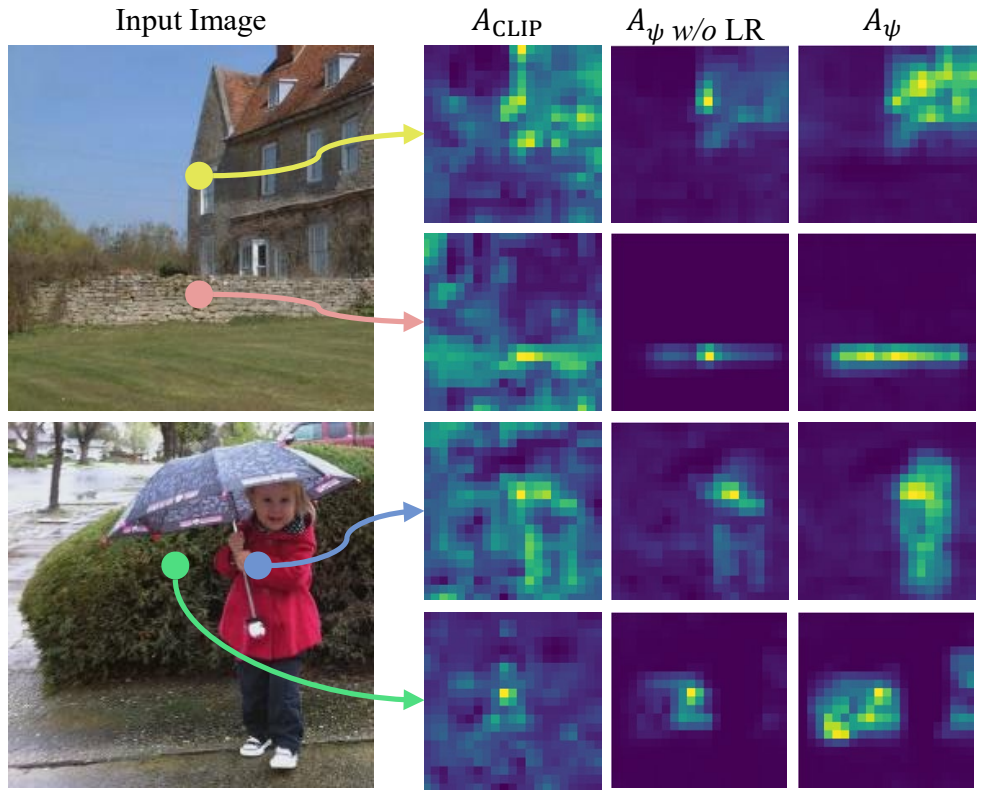
300 dpi PNG · 图注 · 源PDF
第3.2节以图3左列说明CLIP注意力不能捕获物体级上下文,中列说明直接迁移引入噪声,据此引出图谱蒸馏和低秩设计;保留三列完整诊断图。
完整图注、版本和筛选证据
最早核实视觉日期:2024-11-26;arXiv v1:2024-11-26;CVPR 2025 fixed official PDF
v1图3与会议图逐像素一致。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Ming-Hsuan Yang;189781;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 71, 294, 262],PDF点、左上角原点。
Figure 3. Attention score visualization for various query points.
Left: Vanilla CLIP (A ) shows noisy, unfocused attention.
CLIP
Center: VFM-to-CLIP distillation without low-rank eigenscaling
shows partial object grouping with limited detail. Right: Incor-
porating our low-rank eigenscaling (Eq. (7)) captures object-level
context, improving grouping within a single object.
Frozen CLIP: A Strong Backbone for Weakly Supervised Semantic Segmentation
会议:CVPR 2024 · 主会论文
Figure 2 · PDF第3页 · P280
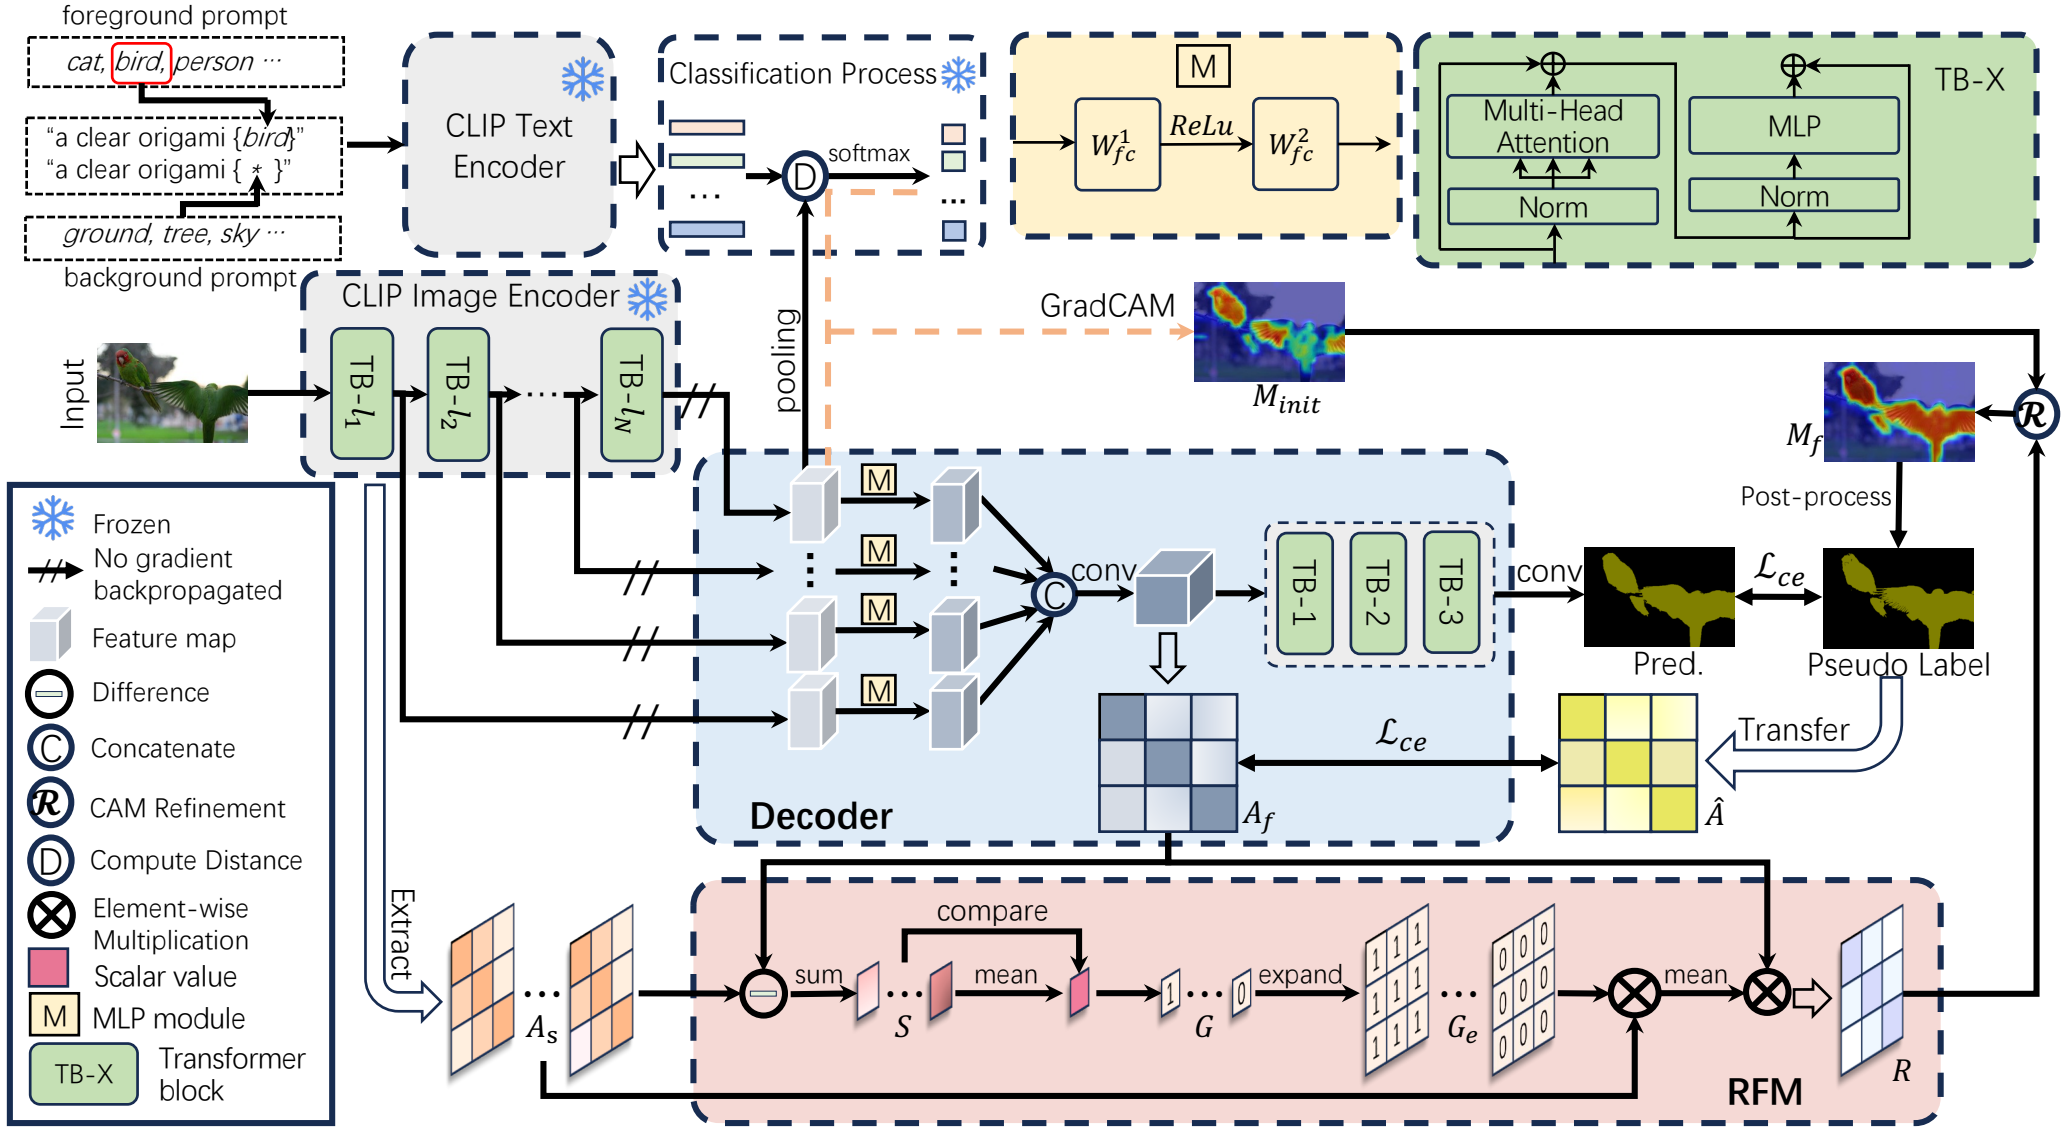
300 dpi PNG · 图注 · 源PDF
图2及3.1节明确为完整WeCLIP,涵盖冻结骨干、分类CAM、分割解码及精炼模块。
完整图注、版本和筛选证据
最早核实视觉日期:2024-06-17;arXiv v1:2024-06-17;CVPR 2024 fixed official PDF
已读源PDF图注与正文并查看图页;作者单位核验一致。已逐张查看300dpi完整导出;对应arXiv v1视觉像素一致。实际作图日期未知。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yunchao Wei;37025;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[50, 72, 547, 344],PDF点、左上角原点。
Figure 2. Framework of our WeCLIP. The image is input to the Frozen CLIP image encoder to generate the image features, and class
labels are used to build text prompts and then input to the Frozen CLIP text encoder to generate the text features. The classification scores
are generated based on the distance between the pooled image and text features. Using GradCAM, we can generate the initial CAM
M . Then, the frozen image features from the last layer of each transformer block are input to our decoder to generate the final semantic
init
segmentation predictions. Meanwhile, the affinity map A from our decoder and the multi-head attention maps A from CLIP are input to
f s
our RFM to establish refining maps R to refine M as M . After post-processing, it will be used as the supervision to train our decoder.
init f
Frozen CLIP: A Strong Backbone for Weakly Supervised Semantic Segmentation
会议:CVPR 2024 · 主会论文
Figure 1 · PDF第1页 · P279
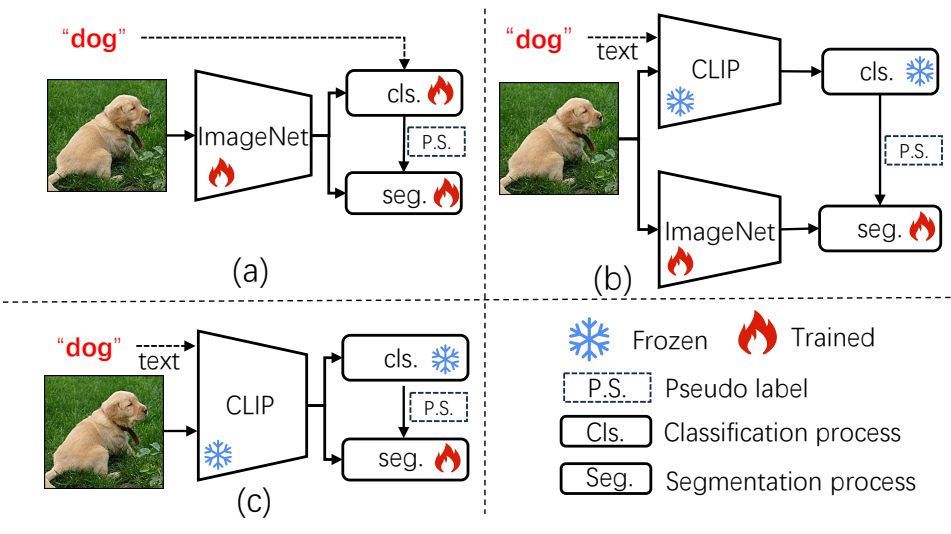
300 dpi PNG · 图注 · 源PDF
图1及引言比较三种监督训练范式,说明既有多阶段/可训练骨干的复杂度与训练成本。
完整图注、版本和筛选证据
最早核实视觉日期:2024-06-17;arXiv v1:2024-06-17;CVPR 2024 fixed official PDF
已读源PDF图注与正文并查看图页;作者单位核验一致。已逐张查看300dpi完整导出;对应arXiv v1视觉像素一致。实际作图日期未知。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yunchao Wei;37025;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[308, 230, 536, 358],PDF点、左上角原点。
Figure 1. Comparisons between our approach and other single-
stage or CLIP-based approaches. (a) Previous single-stage ap-
proach, which uses a trainable ImageNet [11] pre-trained back-
bone with trainable classification and segmentation process. (b)
Previous CLIP-based approach, which is a multi-stage approach
that uses the Frozen CLIP model to produce pseudo labels and
trains an individual ImageNet pre-trained segmentation model. (c)
Our approach. Our approach is a single-stage approach that uses
a frozen CLIP model as the backbone with a trainable segmenta-
tion process, significantly reducing the training cost.
Hunting Attributes: Context Prototype-Aware Learning for Weakly Supervised Semantic Segmentation
会议:CVPR 2024 · 主会论文
Figure 2 · PDF第4页 · P278
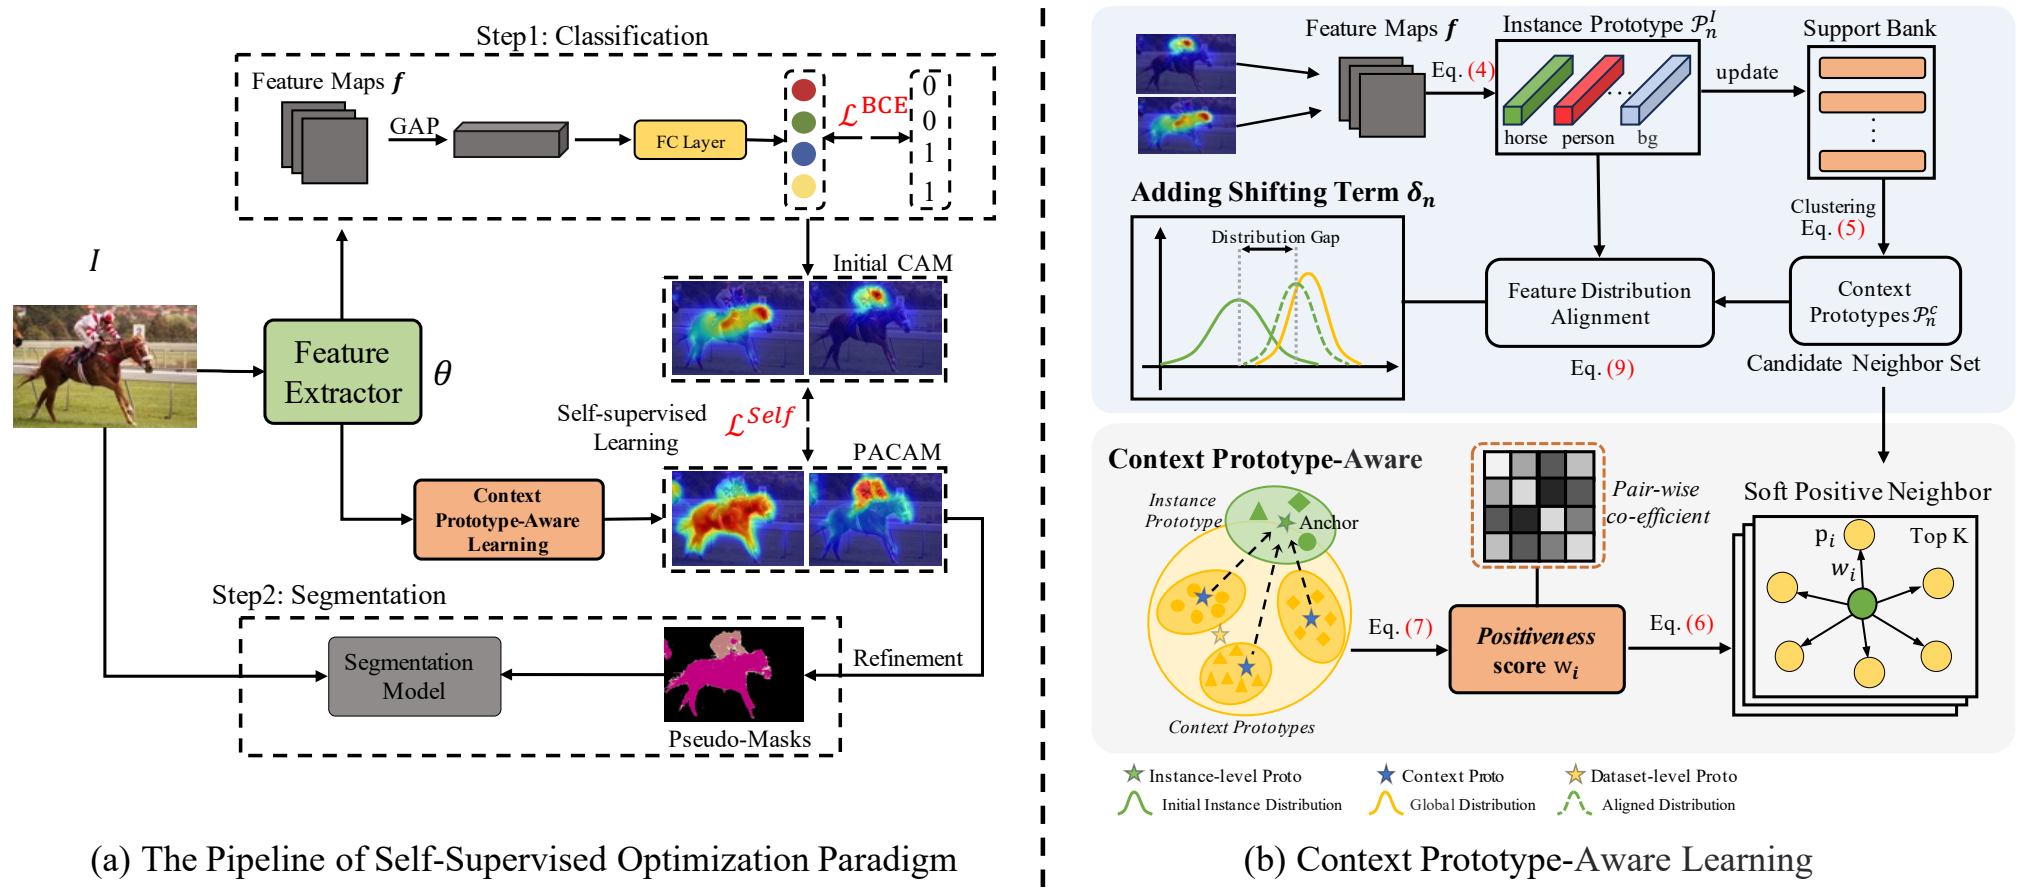
300 dpi PNG · 图注 · 源PDF
图2(a)是完整分类到分割训练流程,(b)是原型感知学习,全部保留。
完整图注、版本和筛选证据
最早核实视觉日期:2024-03-12;arXiv v1:2024-03-12;CVPR 2024 fixed official PDF
已读源PDF图注与正文并查看图页;作者单位核验一致。已逐张查看300dpi完整导出;对应arXiv v1视觉像素一致。实际作图日期未知。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Zongyuan Ge;23901;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[53, 72, 539, 286],PDF点、左上角原点。
Figure 2. Overview of the proposed unified learning framework. (a) shows image label-guided WSSS (from classification to segmentation).
The upper branch describes the classification network θ identifying object regions corresponding to each category to minimize LBC E .
Introduce a self-supervised learning paradigm using context prototype-aware learning to provide a more complete CAM, supervising the
initial CAM and minimizing LS elf . The lower branch refines these CAMs (e.g., DenceCRF [26]) to form pseudo-labels for supervising the
semantic segmentation network. (b) outlines our strategy based on context prototype-aware learning. In mini-batches, instance prototypes
P I are generated using CAM and extracted features f , updating the support bank. Then, the bank is used to construct a context prototype
n
set P c . Feature distribution alignment is then applied to the current instance features, adding a shift term δ to guide them toward clusters of
n n
dense features in the bank. Next, soft neighbors are softly measured for P I based on P c , with P I serving as anchors. Finally, positiveness
n n n
value w can be computed between two specific attributes. This mechanism selects K soft positive neighbors P˜ c to generate PACAM.
i n
Hunting Attributes: Context Prototype-Aware Learning for Weakly Supervised Semantic Segmentation
会议:CVPR 2024 · 主会论文
Figure 1 · PDF第1页 · P277
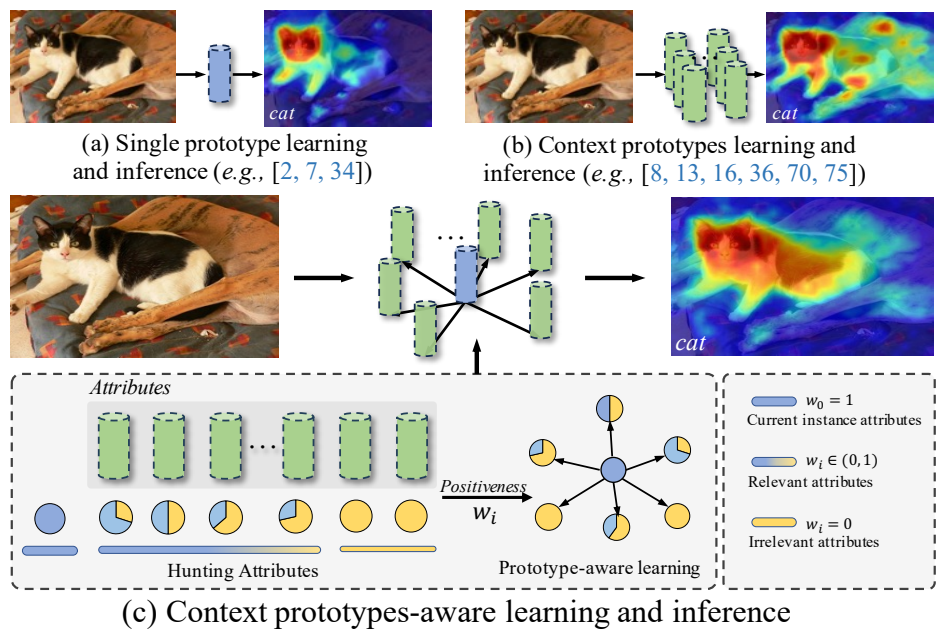
300 dpi PNG · 图注 · 源PDF
图1以猫狗错误激活解释单原型和普通上下文原型局限,用属性概念对比引出CPAL。
完整图注、版本和筛选证据
最早核实视觉日期:2024-03-12;arXiv v1:2024-03-12;CVPR 2024 fixed official PDF
已读源PDF图注与正文并查看图页;作者单位核验一致。已逐张查看300dpi完整导出;对应arXiv v1视觉像素一致。实际作图日期未知。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Zongyuan Ge;23901;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[313, 285, 540, 436],PDF点、左上角原点。
Figure 1. The main idea promoted throughout the paper is that
semantic context prototype-aware underpins localization of indi-
vidual objects in WSSS. Our CPAL performs adaptive perception
of diverse attributes (e.g., cat) with attribute hunting (c) rather
than from single prototype (a) and plain context prototypes (b).
This attribute-specific adaptation not only mitigates the risk of er-
rors where (b) mistakenly identifies similar categories (e.g., dog)
but also ensures accurate activation of the complete object region.
Image-to-Image Matching via Foundation Models: A New Perspective for Open-Vocabulary Semantic Segmentation
会议:CVPR 2024 · 主会论文
Figure 2 · PDF第4页 · P276
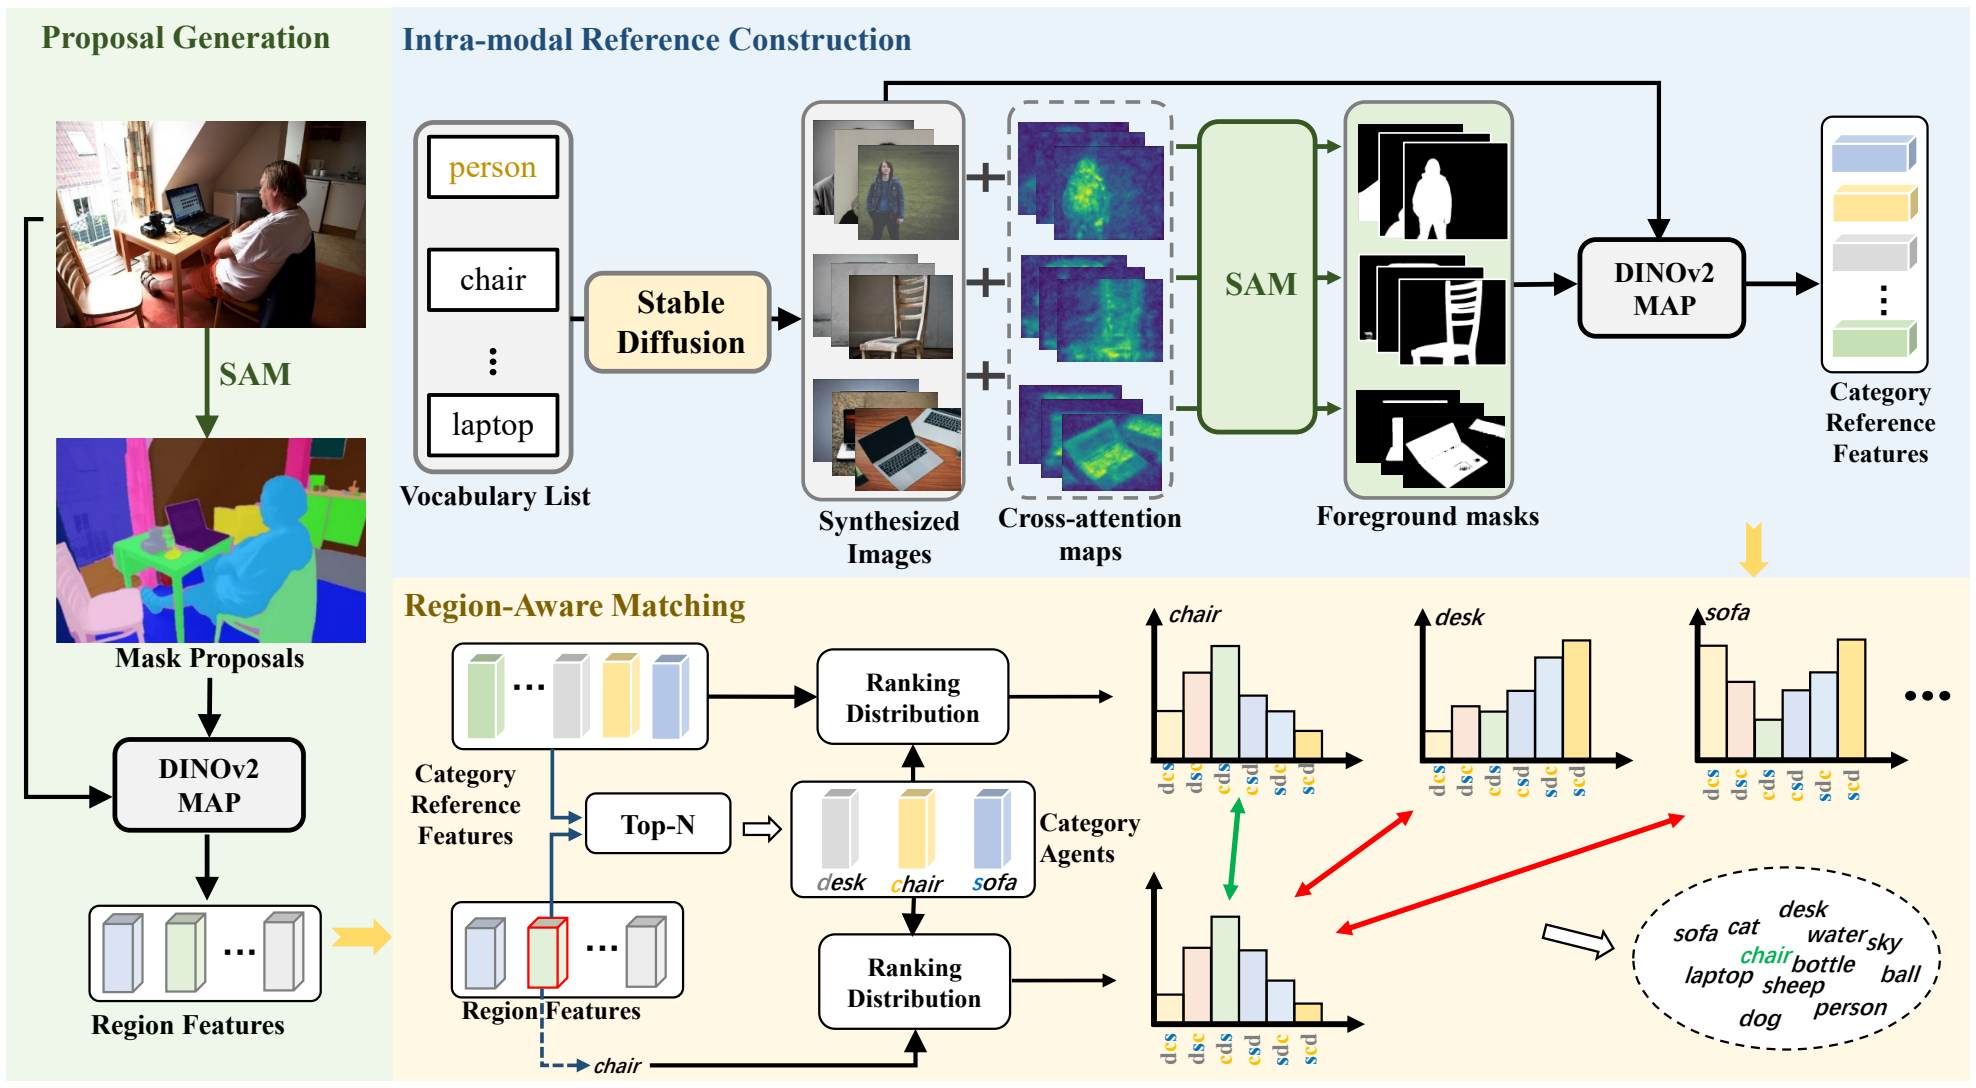
300 dpi PNG · 图注 · 源PDF
图2为完整RIM框架,涵盖候选掩码生成、同模态参考构建和关系匹配。
完整图注、版本和筛选证据
最早核实视觉日期:2024-03-30;arXiv v1:2024-03-30;CVPR 2024 fixed official PDF
已读源PDF图注与正文并查看图页;作者单位核验一致。已逐张查看300dpi完整导出;对应arXiv v1视觉像素一致。实际作图日期未知。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Tianzhu Zhang;23149;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[60, 75, 534, 336],PDF点、左上角原点。
Figure 2. Framework of our proposed Relation-aware Intra-modal Matching (RIM) Network. We first explore Stable Diffusion model and
SAM to construct image-modal reference features, then we conduct relation-aware matching between region features and reference features
based on ranking distribution. The matching is established in the all-purpose feature spaces of DINOv2.
Image-to-Image Matching via Foundation Models: A New Perspective for Open-Vocabulary Semantic Segmentation
会议:CVPR 2024 · 主会论文
Figure 1 · PDF第1页 · P275
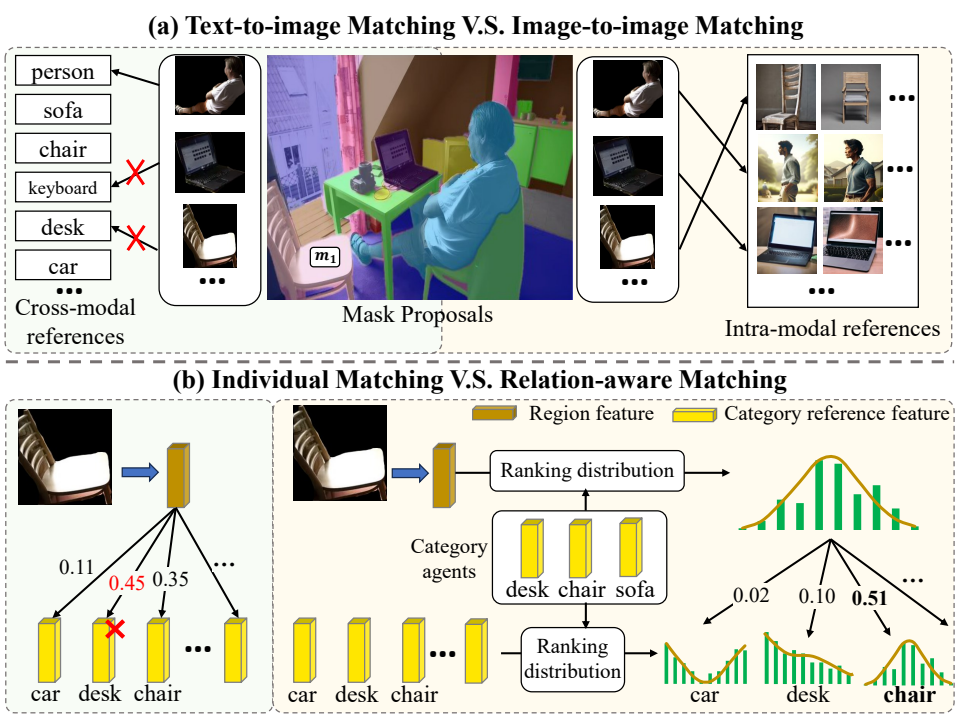
300 dpi PNG · 图注 · 源PDF
图1图注明确为motivation:跨模态匹配错误及独立匹配易受干扰,用概念对比引出同模态关系匹配。
完整图注、版本和筛选证据
最早核实视觉日期:2024-03-30;arXiv v1:2024-03-30;CVPR 2024 fixed official PDF
已读源PDF图注与正文并查看图页;作者单位核验一致。已逐张查看300dpi完整导出;对应arXiv v1视觉像素一致。实际作图日期未知。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Tianzhu Zhang;23149;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[314, 245, 545, 418],PDF点、左上角原点。
Figure 1. Motivation of our method. (a) False matches tend to
occur in cross-modal features. We establish well-aligned image-
modal reference features thus transit the text-to-image matching to
image-to-image matching. (b) Indivdual matching tends to suffer
from disturbances. We propose a novel relation-aware matching
strategy for more robust region classification.
MaSS13K: A Matting-level Semantic Segmentation Benchmark
会议:CVPR 2025 · 主会论文
Figure 3 · PDF第5页 · P52
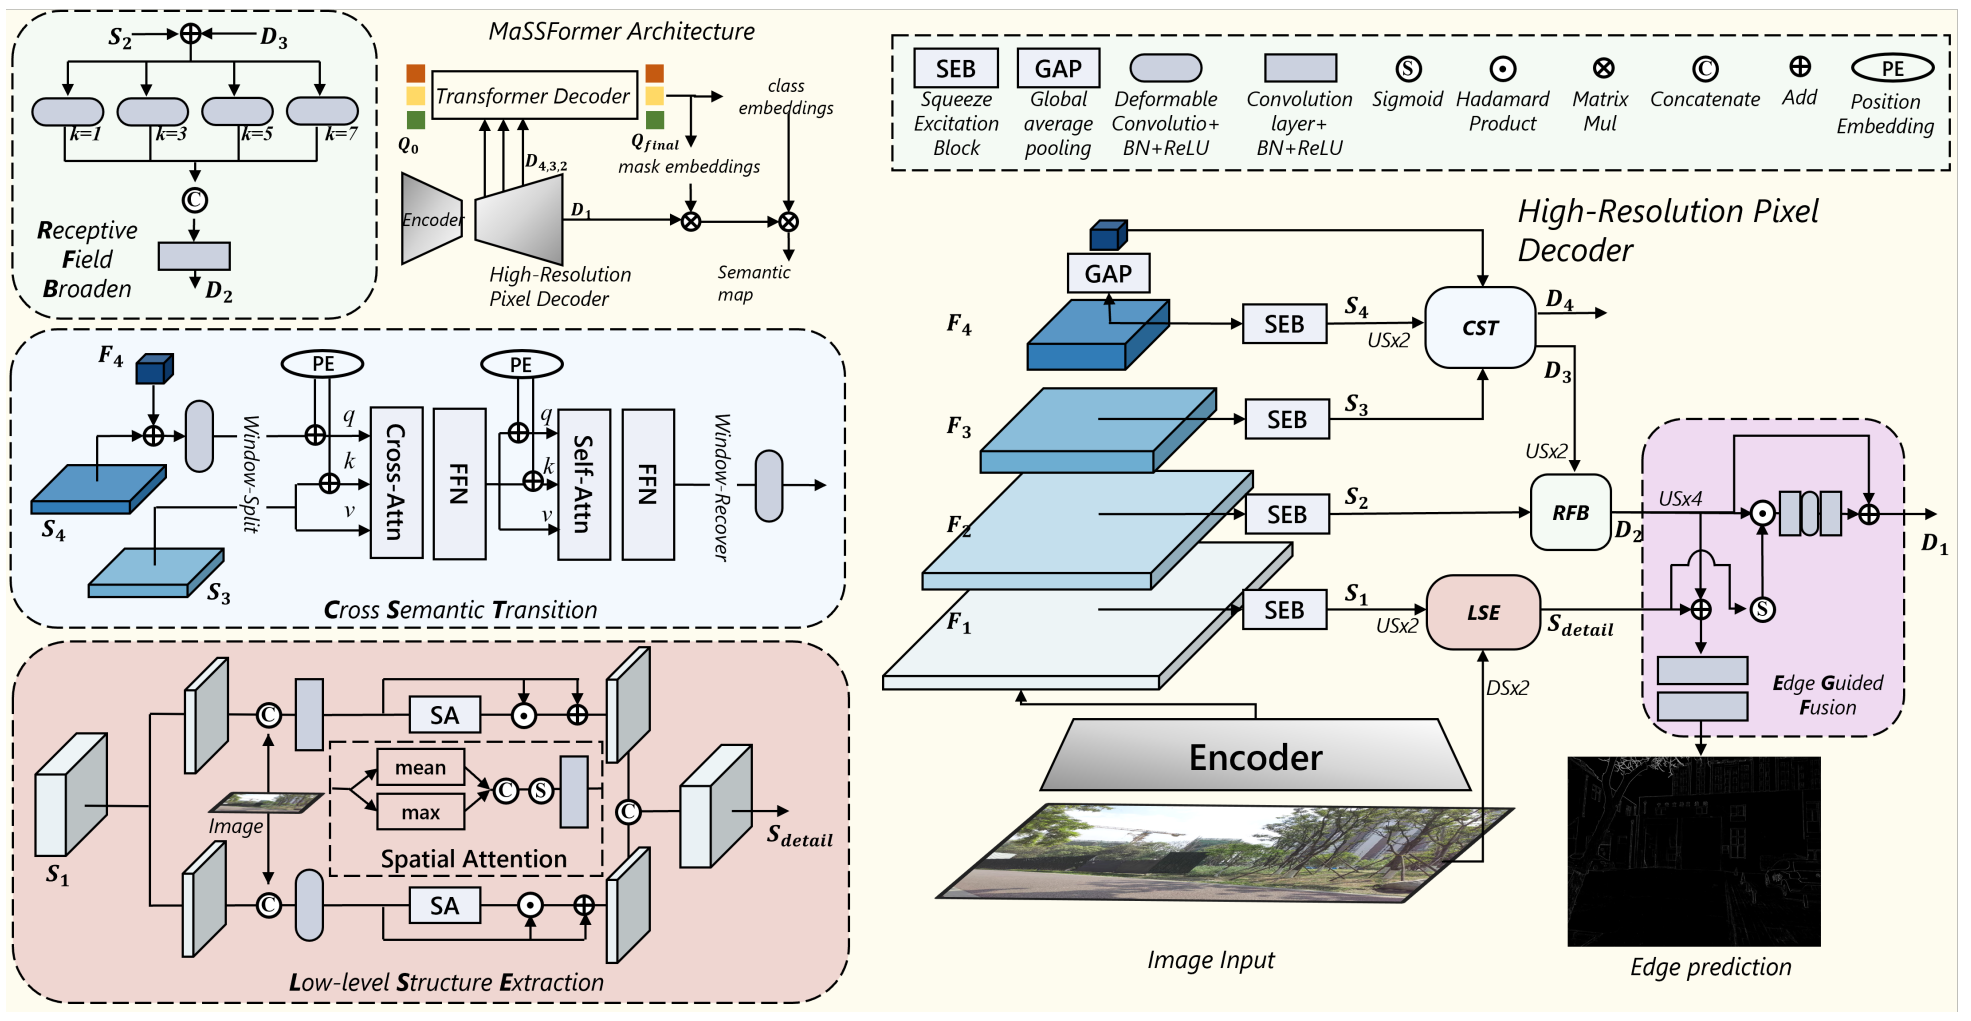
300 dpi PNG · 图注 · 源PDF
第4.1节与图3给出MaSSFormer整体编码器、像素解码器、Transformer解码器及输出;保留整体框架与所有细节子图。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-24;arXiv v1:2025-03-24;CVPR 2025 fixed official PDF
已逐页查看会议版与arXiv v1;图区设计一致,保留移动/缩放及PDF压缩差异,不声称像素完全一致。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[61, 70, 534, 315],PDF点、左上角原点。
Figure 3. Architecture of MaSSFormer. The model architecture is shown on the top left corner, including the image encoder, pixel decoder
and transformer decoder. The detailed structure of the high-resolution pixel decoder is shown on the right of this figure.
MaSS13K: A Matting-level Semantic Segmentation Benchmark
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第1页 · P51
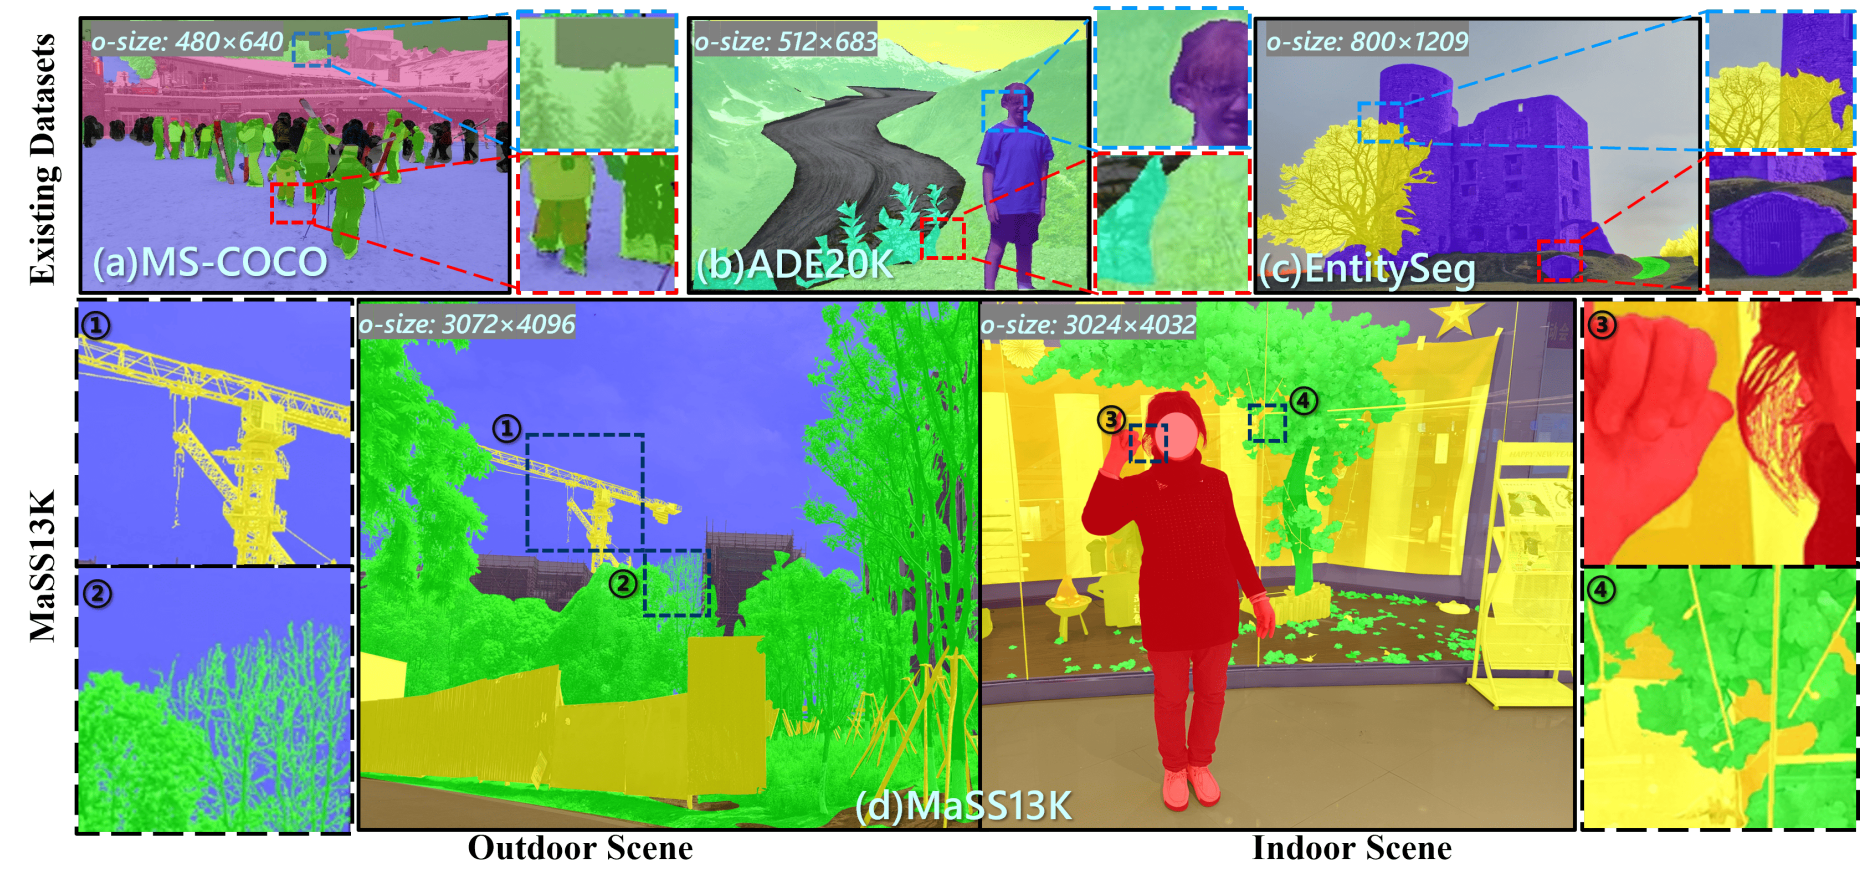
300 dpi PNG · 图注 · 源PDF
引言第2页以图1指出现有语义分割数据集分辨率和精细边界标注不足;展示标注问题而非模型普通结果对比。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-24;arXiv v1:2025-03-24;CVPR 2025 fixed official PDF
已逐页查看会议版与arXiv v1;图区设计一致,保留移动/缩放及PDF压缩差异,不声称像素完全一致。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[73, 191, 522, 400],PDF点、左上角原点。
Figure 1. Comparisons on the resolution and annotation quality between existing semantic segmentation datasets (a) COCO, (b) ADE20K,
(c) EntitySeg and (d) our established dataset MaSS13K. Note that the ‘others’ category, which is highlighted in yellow, in our MaSS13K
actually contains a group of well-segmented objects without specific class names. Please zoom-in for a better view.
Mamba as a Bridge: Where Vision Foundation Models Meet Vision Language Models for Domain-Generalized Semantic Segmentation
会议:CVPR 2025 · 主会论文
Figure 2 · PDF第4页 · P56
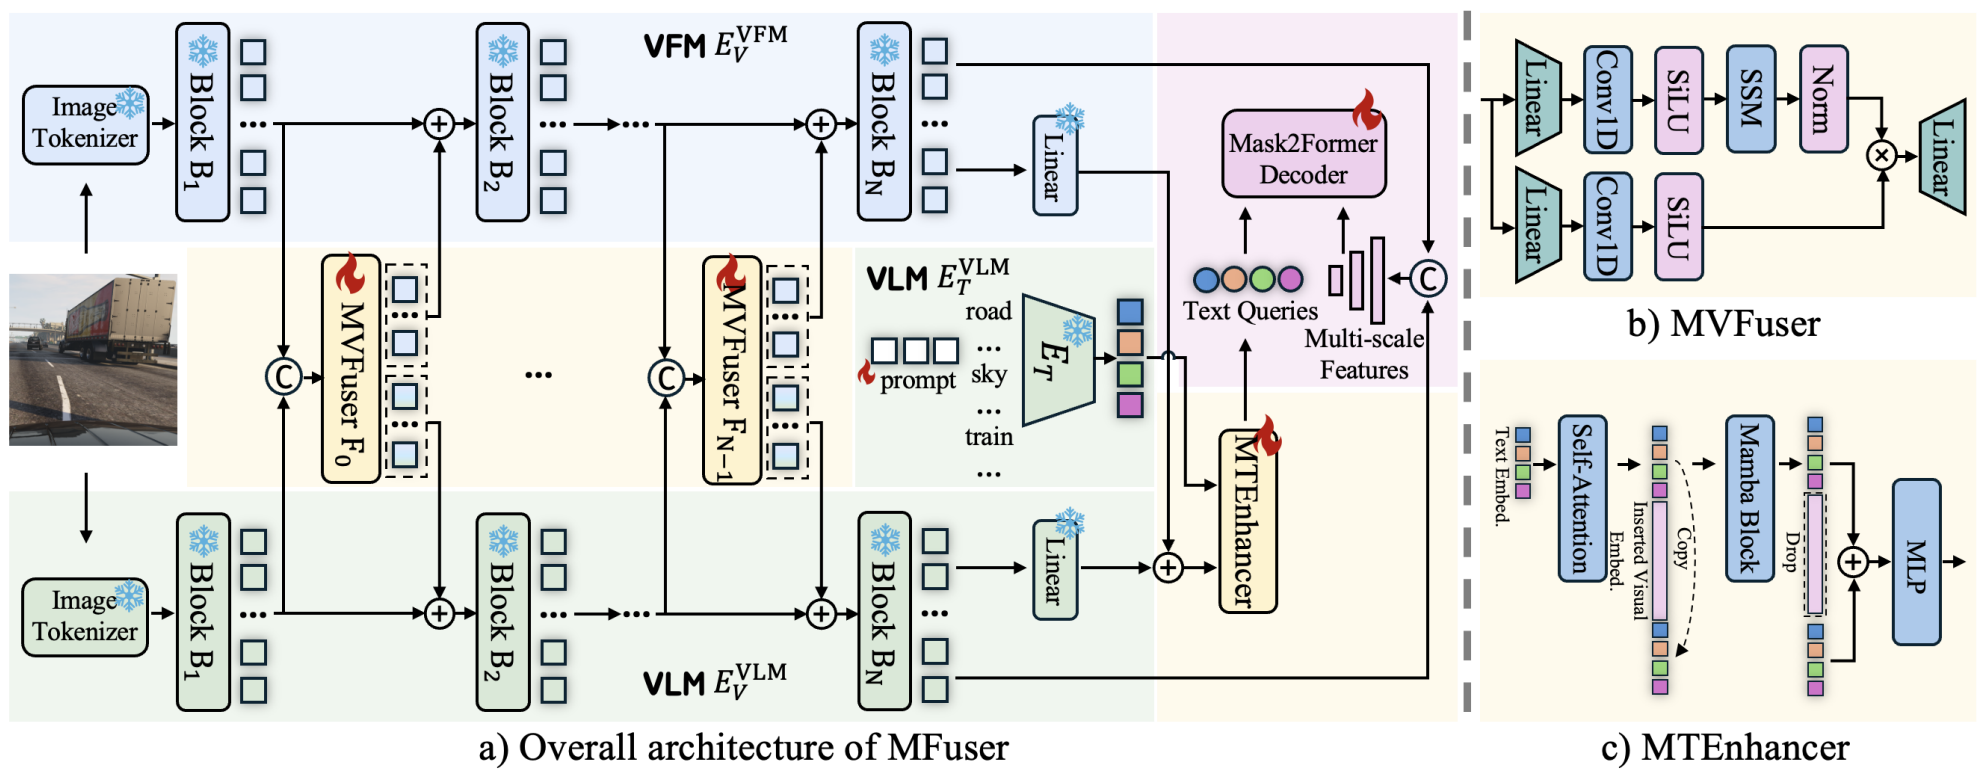
300 dpi PNG · 图注 · 源PDF
第4节及图2明确给出MFuser的双编码器、跨层融合、文本增强和Mask2Former解码完整架构,并保留两个模块子图。
完整图注、版本和筛选证据
最早核实视觉日期:2025-04-04;arXiv v1:2025-04-04;CVPR 2025 fixed official PDF
已查看v1、v2及会议PDF,整体图形一致;F的固定区域三版像素一致。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Robby T. Tan;18517;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[68, 71, 545, 259],PDF点、左上角原点。
Figure 2. Overall architecture of MFuser. MFuser takes inputs through both VFM and VLM visual encoders. Features from each encoder
layer are concatenated and refined in MVFuser, which captures sequential and spatial dependencies in parallel. The refined features are
then added back to the original features and passed to the next layer. MTEnhancer strengthens text embeddings of each class by integrating
visualfeaturesthroughahybridattention-Mambamechanism. TheenhancedtextembeddingsserveasobjectqueriesfortheMask2Former
decoder, alongside multi-scale visual features. During training, only MVFusers, MTEnhancers, and the segmentation decoder are trainable
while the VFM and VLM remain frozen, preserving their generalization ability and enabling efficient training. Note that skip connections
between each block of MTEnhancer are omitted for clarity.
Mamba as a Bridge: Where Vision Foundation Models Meet Vision Language Models for Domain-Generalized Semantic Segmentation
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第1页 · P55
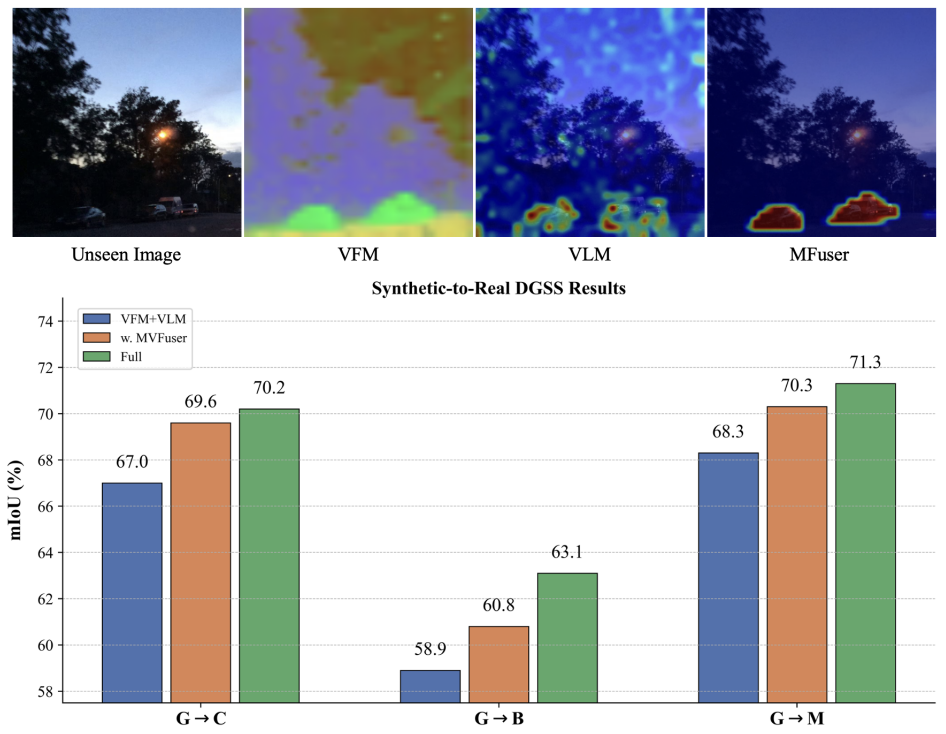
300 dpi PNG · 图注 · 源PDF
引言第2页借图1分析VFM细节强但缺少文本对齐、VLM对齐强但定位粗糙的互补局限;不是仅性能柱状图。保留整图中的定量柱状附图。
完整图注、版本和筛选证据
最早核实视觉日期:2025-04-04;arXiv v1:2025-04-04;CVPR 2025 fixed official PDF
已查看v1、v2及会议PDF,整体图形一致;F的固定区域三版像素一致。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Robby T. Tan;18517;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[322, 231, 549, 407],PDF点、左上角原点。
Figure 1. Comparative analysis of the VFM and the VLM fea-
tures. VFM: Visualization of PCA-computed features from DI-
NOv2 (the first three components of PCA, computed on the image
features, serve as color channels), displaying fine-grained details
but lacking text alignment. VLM: Image-text similarity map from
EVA02-CLIPusingthequery‘car’,demonstratinggoodalignment
with text but insufficient localization of queried objects. MFuser:
OurproposedfusionframeworkintegratesVFMandVLM,result-
ing in unified features that exhibit both precise locality and robust
text alignment. Quantitative results on synthetic-to-real DGSS
benchmarks further validate our approach, with MFuser consis-
tently achieving the highest mIoU scores across all tasks.
SegMAN: Omni-scale Context Modeling with State Space Models and Local Attention for Semantic Segmentation
会议:CVPR 2025 · 主会论文
Figure 3 · PDF第4页 · P54
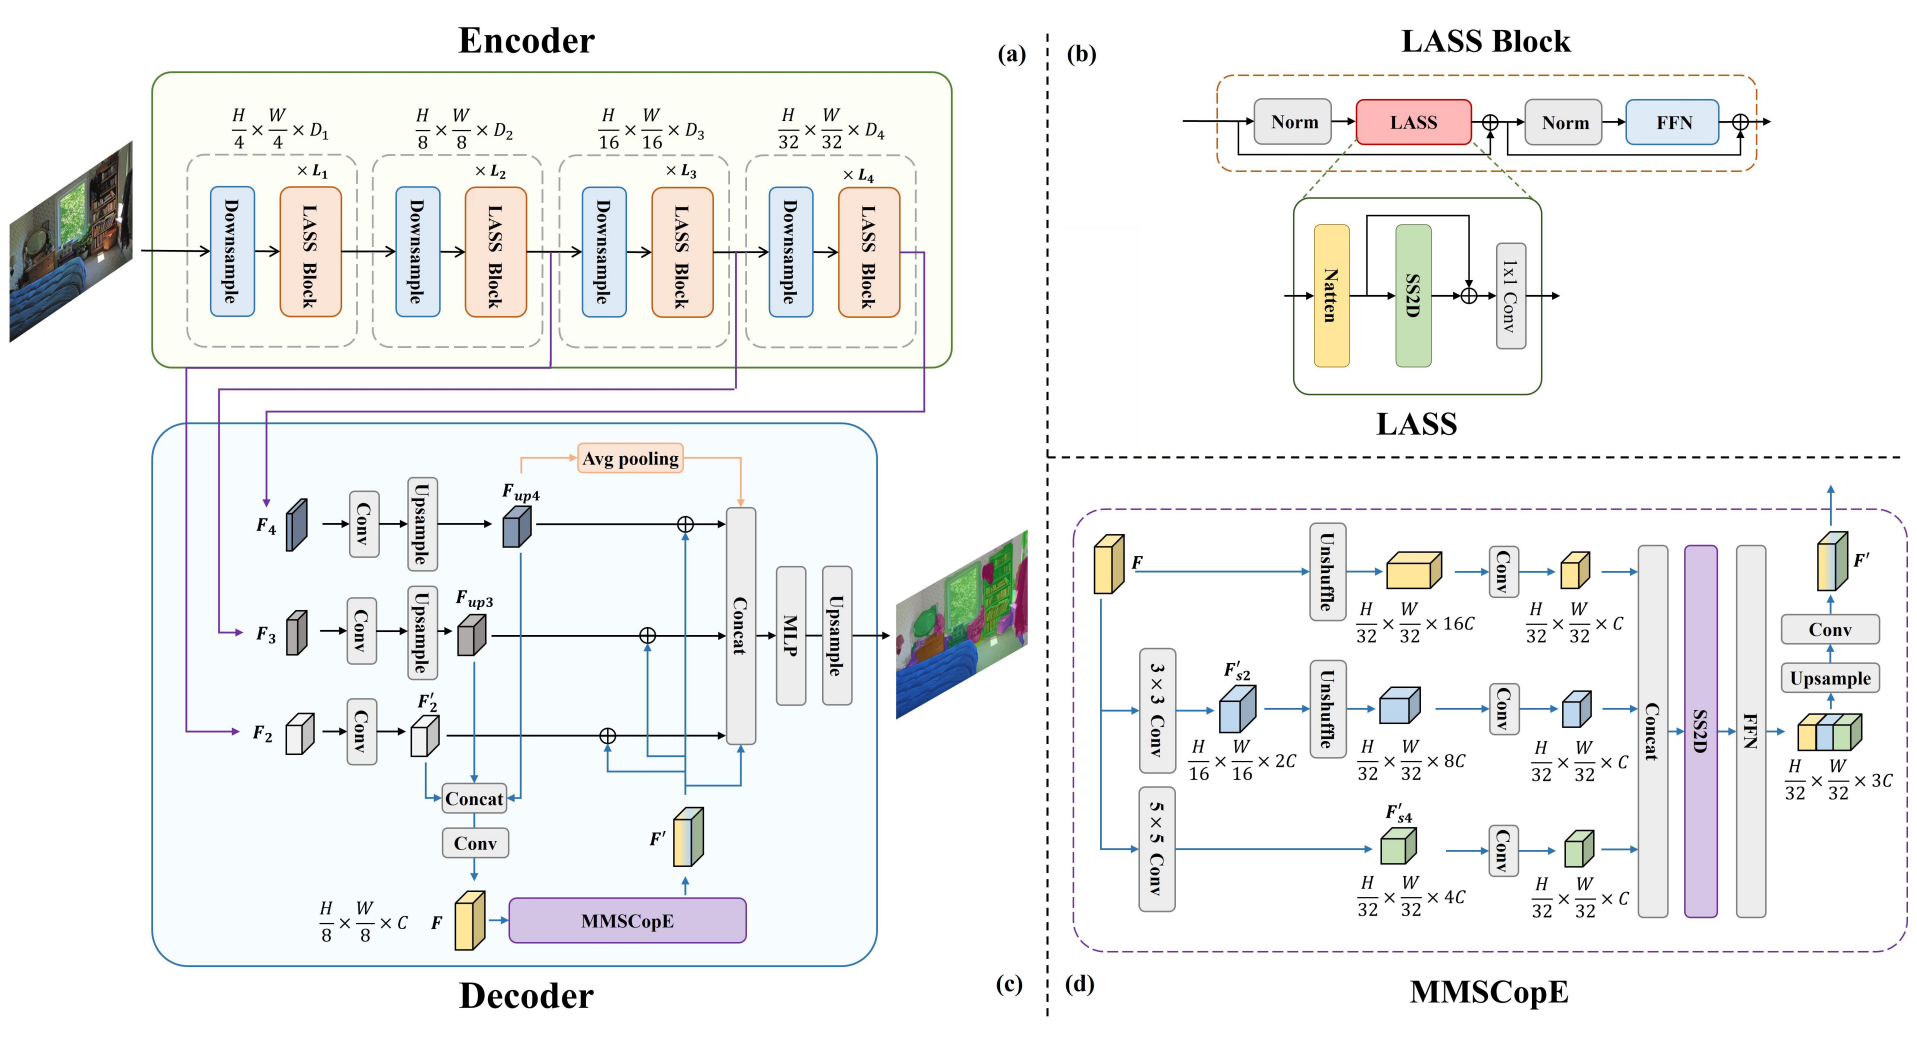
300 dpi PNG · 图注 · 源PDF
第3.1节Overall Architecture将编码器与解码器及其模块串联,图3完整展示四个子图,属于全方法框架。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-27;arXiv v1:2024-12-16;CVPR 2025 fixed official PDF
已查看v1、v2及会议版。F的LASS和归一化等模块连线/文字发生变化,会议图3匹配v2;不得套用v1日期。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Yizhou Yu;35607;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[76, 71, 536, 322],PDF点、左上角原点。
Figure 3. Overall Architecture of SegMAN. (a) Hierarchical SegMAN Encoder. (b) LASS for modeling global contexts and local details
with linear complexity. (c) The SegMAN Decoder. (d) The MMSCopE module for multi-scale contexts extraction.
SegMAN: Omni-scale Context Modeling with State Space Models and Local Attention for Semantic Segmentation
会议:CVPR 2025 · 主会论文
Figure 2 · PDF第2页 · P53
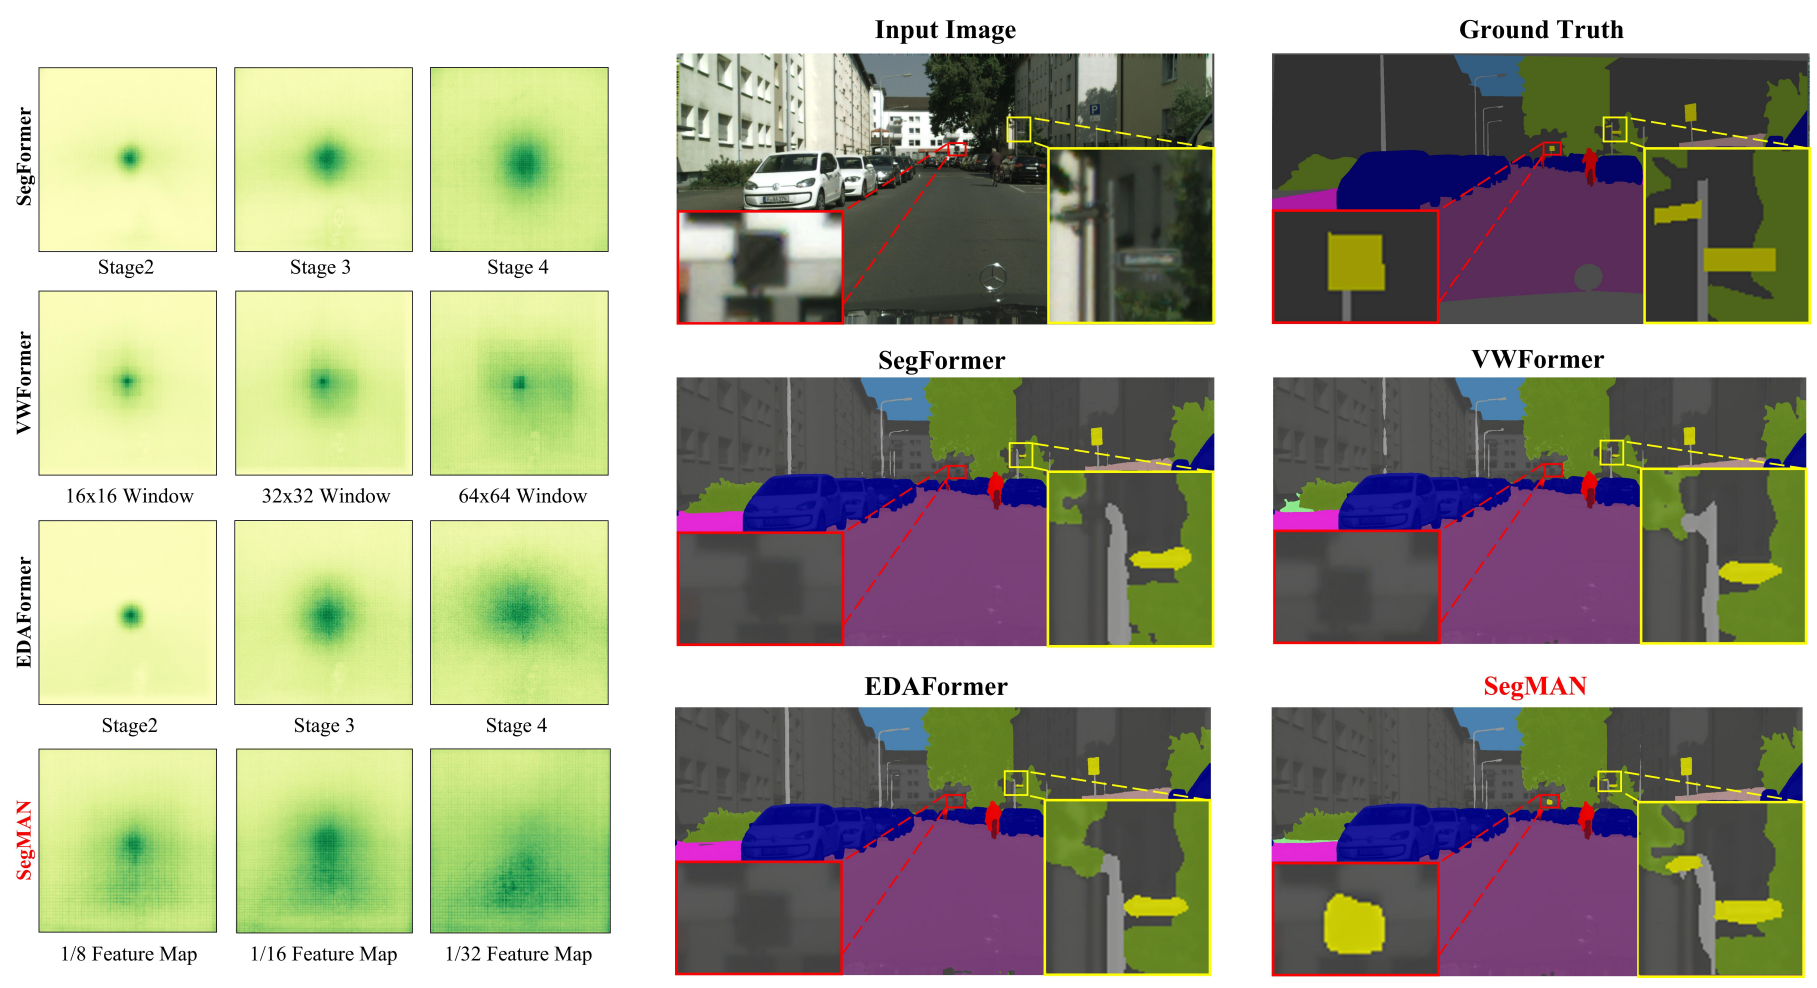
300 dpi PNG · 图注 · 源PDF
引言第2页明确以有效感受野覆盖不足及小物体边界错误解释现有模型局限;会议图1为纯性能曲线,按规则跳过,取图2的诊断示例。
完整图注、版本和筛选证据
最早核实视觉日期:2024-12-16;arXiv v1:2024-12-16;CVPR 2025 fixed official PDF
已查看v1、v2及会议版。M在v1为图1,会议版改号图2并等比例缩放;问题图的内容和设计一致。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Yizhou Yu;35607;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[87, 71, 523, 308],PDF点、左上角原点。
Figure 2. Qualitative analysis of receptive field patterns and segmentation performance for small-sized models (27M-29M parameters).
Left: Visualization of effective receptive fields (ERF) on the Cityscapes validation set at 1024×1024 resolution, illustrating SegMAN’s
stronger global context modeling capacity in comparison to existing state-of-the-art models. Right: Segmentation maps highlighting
SegMAN’s superior capacity to encode fine-grained local details that are often missed by existing approaches.
Adversarial Diffusion Compression for Real-World Image Super-Resolution
会议:CVPR 2025 · 主会论文
Figure 3 · PDF第4页 · P102
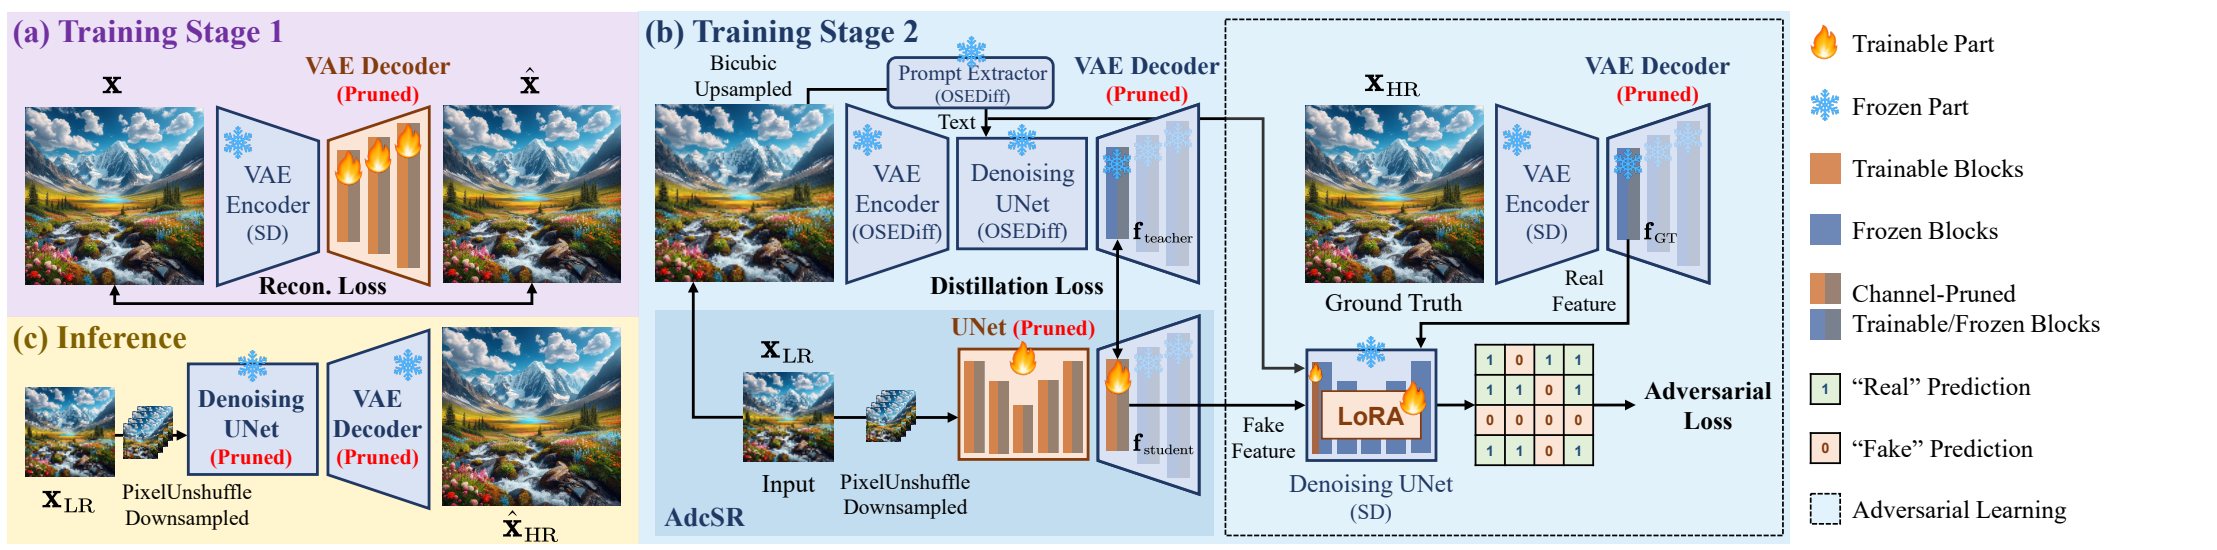
300 dpi PNG · 图注 · 源PDF
第3.3节及图3展示两阶段训练与推理、教师学生判别器及各损失的完整流程。
完整图注、版本和筛选证据
最早核实视觉日期:2024-11-20;arXiv v1:2024-11-20;CVPR 2025 fixed official PDF
已阅读固定版本图注和正文;与arXiv历史对应视觉比较,具体差异记入逐图核查记录。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 65, 590, 197],PDF点、左上角原点。
Figure3. IllustrationofthetrainingandinferenceprocessesofAdcSR,aninstantiationofourADCframeworkappliedtoOSEDiff.
(a)InStage1,wepretrainaprunedVAEdecoderthatsharesthelatentspacewithSDandOSEDiff. (b)InStage2,wedistilltheknowledge
from OSEDiff (ADC-teacher) into AdcSR (ADC-student) by aligning features in the pretrained decoder. An adversarial loss encourages
the student to generate features that can fool a LoRA-finetuned SD UNet (ADC-discriminator), utilizing the corresponding real features
of GT images. Since all supervisions perform in the feature space, there is no need to decode images as in previous approaches [96, 112].
(c) During inference, the LR image is directly fed into our trained compressed UNet and VAE decoder to obtain the super-resolution result.
Adversarial Diffusion Compression for Real-World Image Super-Resolution
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第1页 · P101
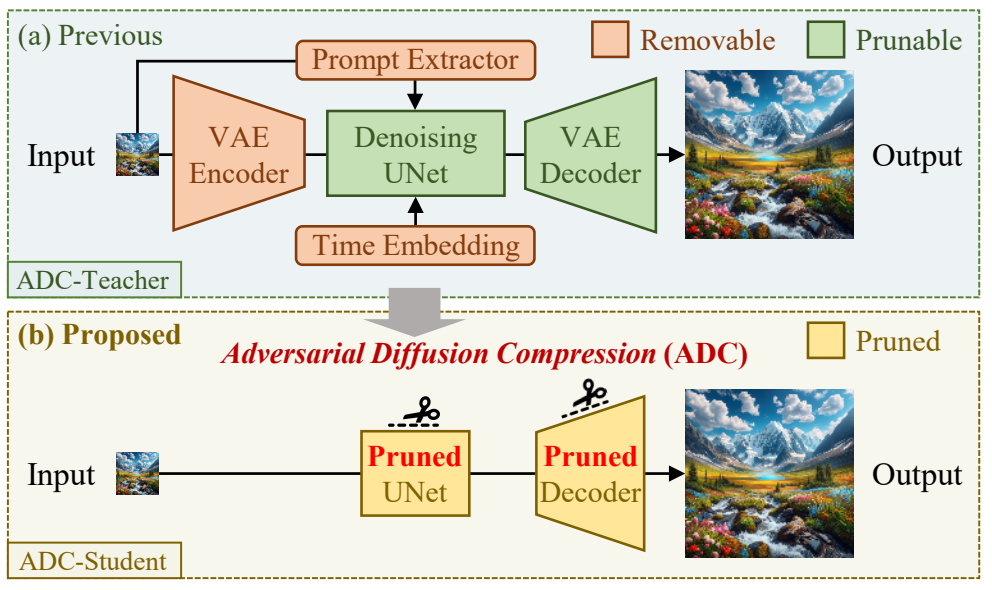
300 dpi PNG · 图注 · 源PDF
引言和图1对比完整扩散模型与压缩模型的计算路径,指出冗余模块带来的高计算开销,为ADC设计引出问题。
完整图注、版本和筛选证据
最早核实视觉日期:2024-11-20;arXiv v1:2024-11-20;CVPR 2025 fixed official PDF
v1与会议图的构图、标签、颜色与箭头匹配,仅整体纵向排版移动19.925pt;采用v1日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[317, 260, 555, 401.5],PDF点、左上角原点。
Figure 1. Comparison between our proposed AdcSR and typ-
ical one-step diffusion-based Real-ISR methods. (a) The state-
of-the-art one-step diffusion network OSEDiff [96] employs com-
plete SD [80] models for Real-ISR, suffering from high computa-
tional costs. (b) We distill OSEDiff (ADC-teacher) into a smaller
diffusion-GAN hybrid model, AdcSR (ADC-student), under the
proposed ADC framework, achieving significantly improved effi-
ciency while maintaining competitive recovery performance.
Complexity Experts are Task-Discriminative Learners for Any Image Restoration
会议:CVPR 2025 · 主会论文
Figure 2 · PDF第3页 · P68
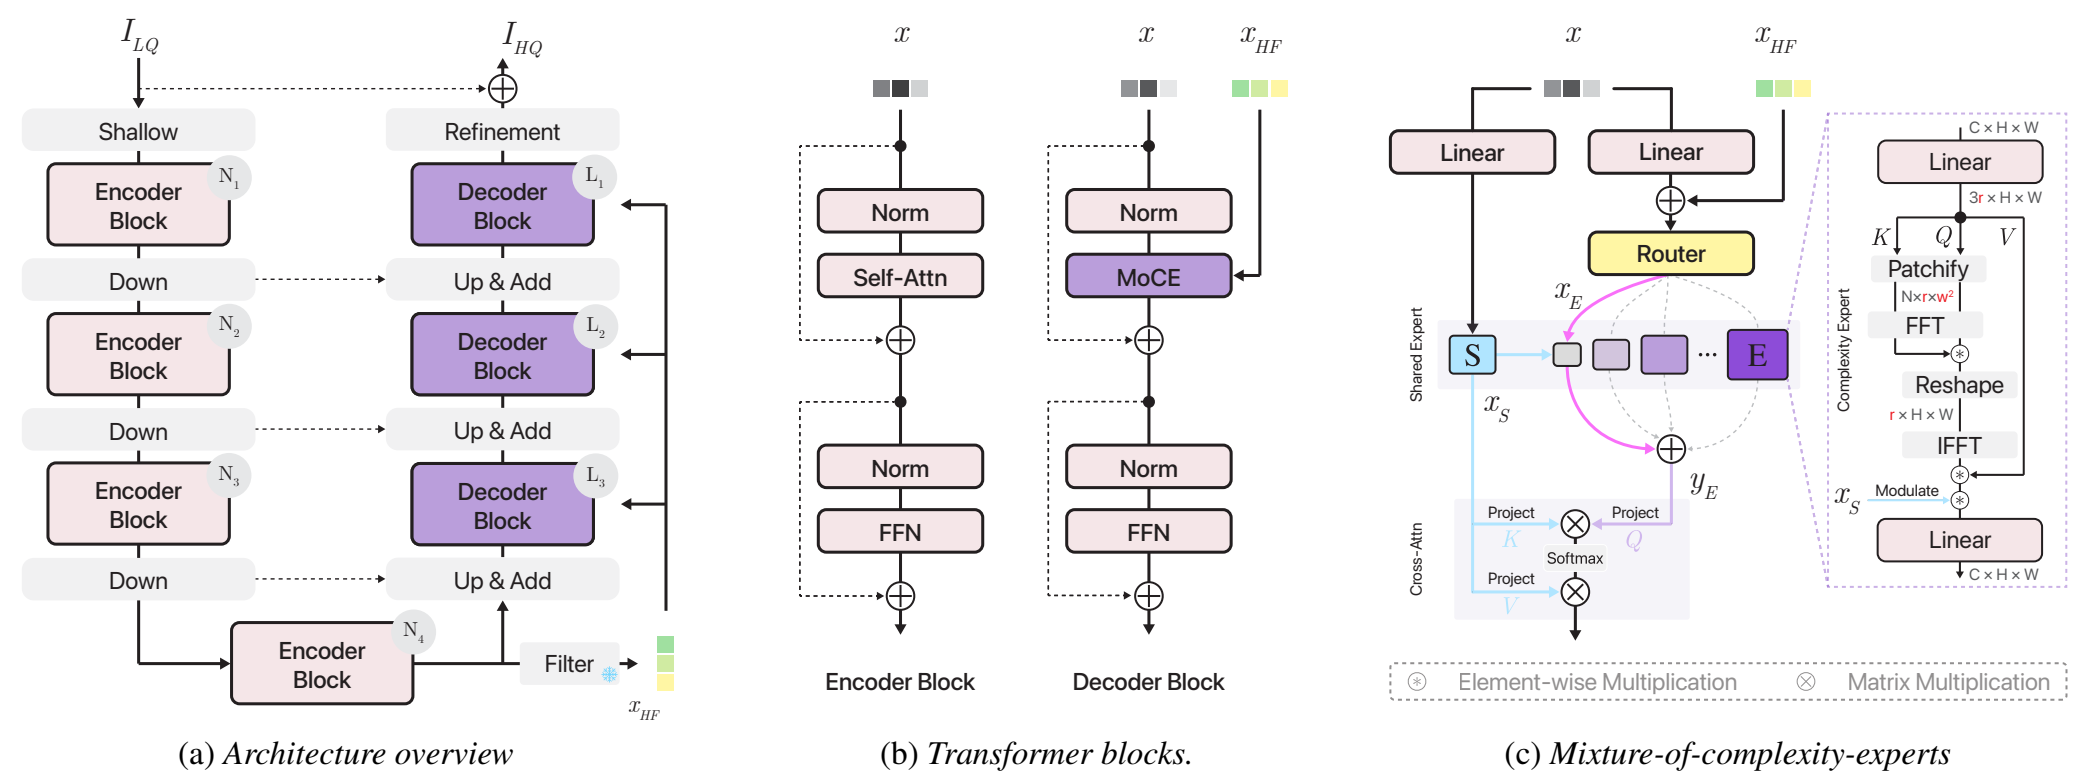
300 dpi PNG · 图注 · 源PDF
第3节明确引用图2展示U形编码解码器、模块和复杂度专家全框架;完整保留三个子图。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-13;arXiv v1:2024-11-27;CVPR 2025 fixed official PDF
已逐项比对v1、v2和会议版:v1专家模块结构和文字不同;v2(2025-03-13)构图、配色、连线及标签与会议版一致,不套用v1日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yulun Zhang;40552;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[57, 70, 555, 257],PDF点、左上角原点。
Figure 2. Proposed MoCE-IR framework. Despite recent advances in MoE-based image restoration [57, 62, 63], inconsistent expert
behavior—where some experts over-generalize while others underperform—limits their computational efficiency. We address this through
complexity experts: flexible blocks with varying computational capacity and receptive fields. Our MoCE-IR employs an asymmetric
encoder-decoder architecture where each decoder block contains a mixture-of-complexity-experts layer for adaptive capacity routing.
Complexity Experts are Task-Discriminative Learners for Any Image Restoration
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第1页 · P67
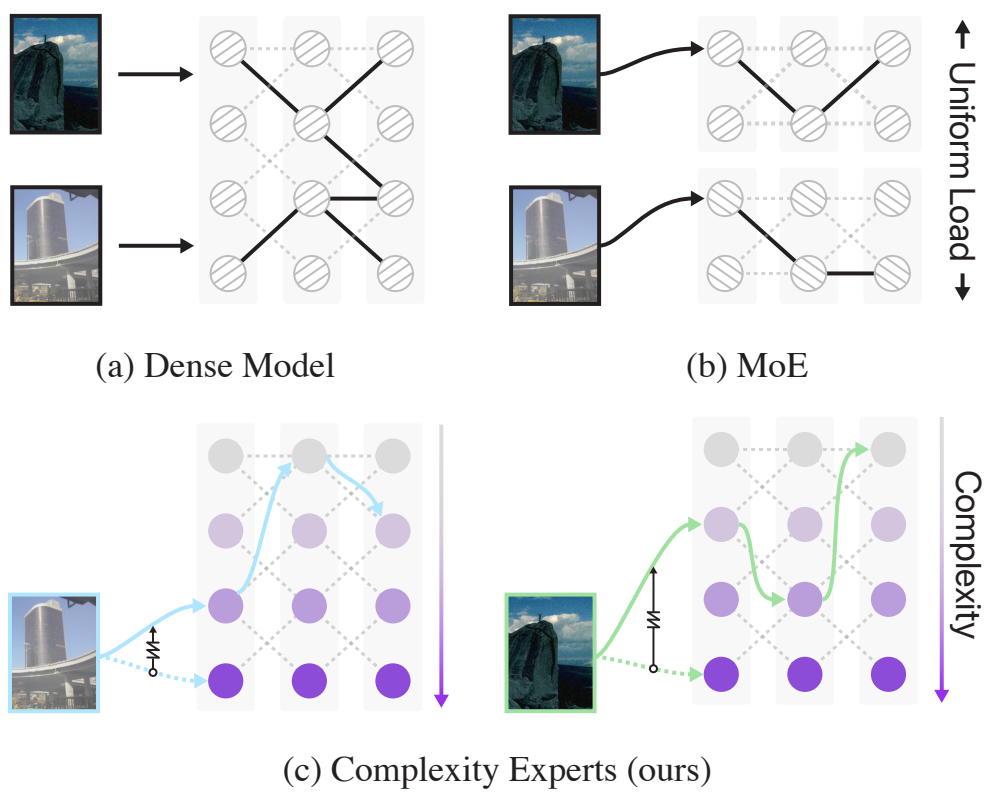
300 dpi PNG · 图注 · 源PDF
引言图1比较稠密网络、刚性MoE与复杂度专家,说明不合理参数分配和固定路由的局限。
完整图注、版本和筛选证据
最早核实视觉日期:2024-11-27;arXiv v1:2024-11-27;CVPR 2025 fixed official PDF
已查看固定PDF及目标图;以最早已核实匹配版本日期作时间代理,不声称实际作图日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yulun Zhang;40552;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[316, 225, 555, 416],PDF点、左上角原点。
Figure 1. Motivation. (a) Dense all-in-one restoration meth-
ods [24, 57] often inefficiently allocate parameters when handling
multiple degradation types. (b) While recent Mixture-of-Experts
(MoE) approaches [61, 62] address this through sparse computa-
tion, their rigid routing mechanisms uniformly distribute inputs
across experts without considering the natural relationships be-
tween degradations. (c) To overcome these limitations, we intro-
duce Complexity Experts - adaptive processing blocks with size-
varying computational units. Our framework dynamically allocates
model capacity using a spring-inspired force mechanism that con-
tinuously guides routing decisions toward simpler experts when
possible, with the force proportional to the complexity of the input
degradation. While initially designed for computational efficiency,
this approach naturally emerges as a task-discriminative learning
framework, assigning degradations to the most suitable experts.
This makes it particularly effective for all-in-one restoration meth-
ods, where both task-specific processing and cross-degradation
knowledge sharing are crucial.
DORNet: A Degradation Oriented and Regularized Network for Blind Depth Super-Resolution
会议:CVPR 2025 · 主会论文
Figure 3 · PDF第3页 · P174
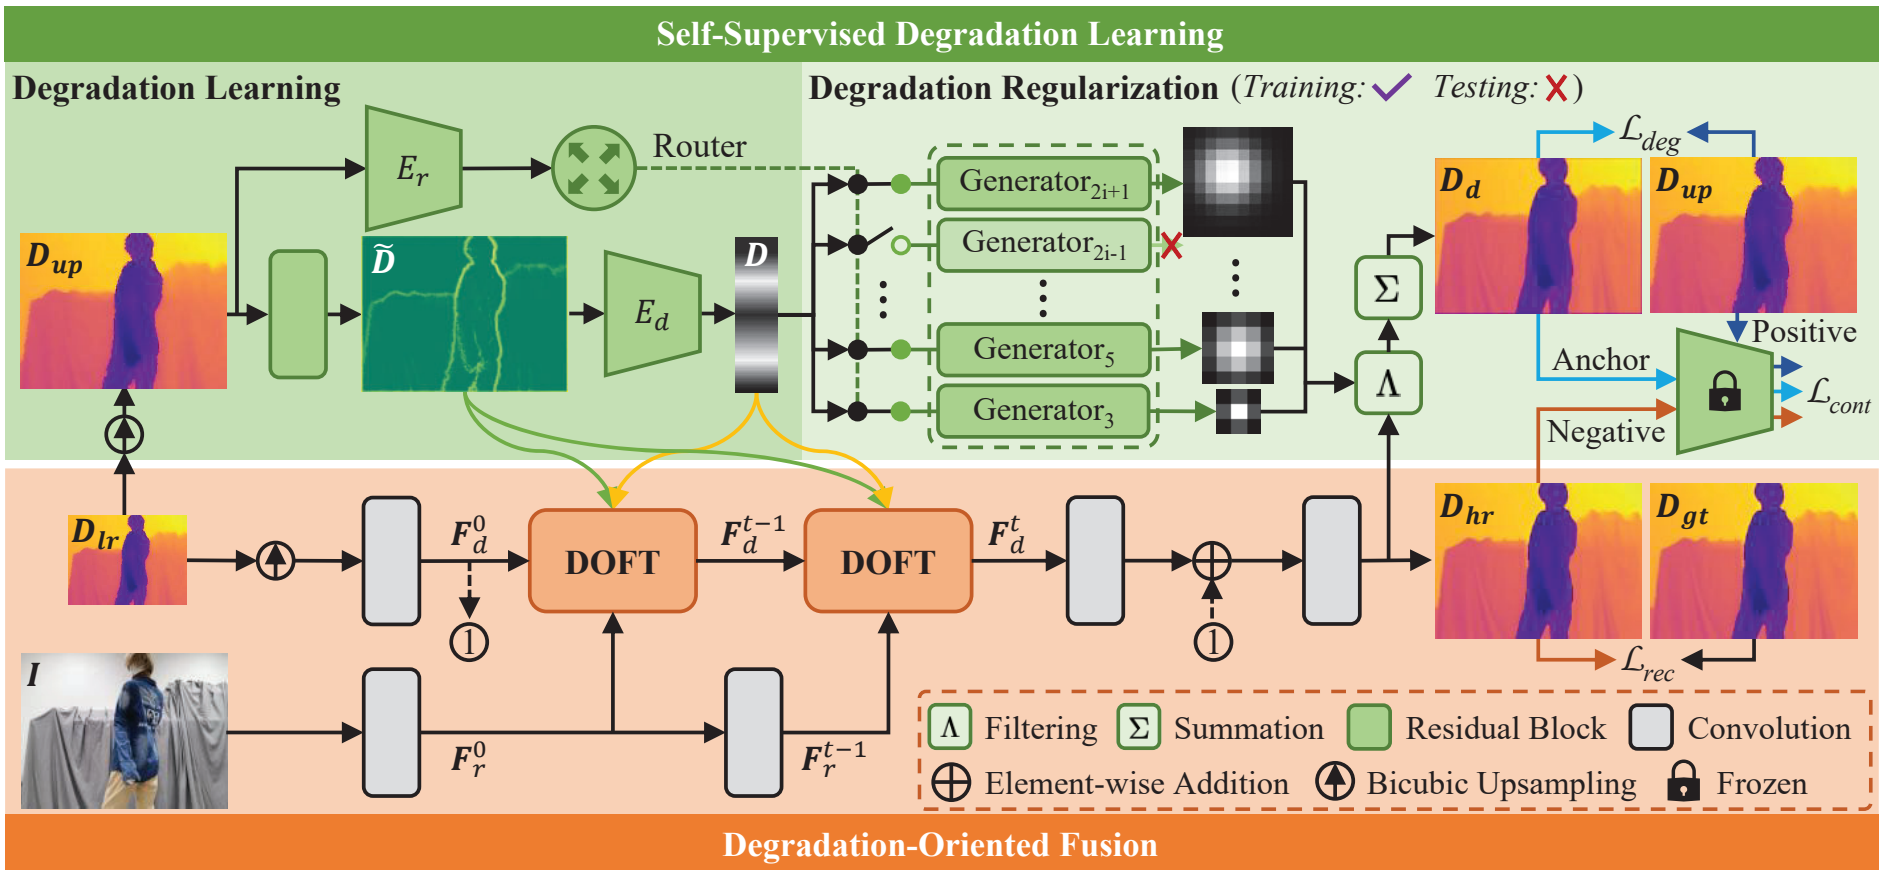
300 dpi PNG · 图注 · 源PDF
图3为完整DORNet,包括退化表示、核正则、RGB引导融合及深度图重建的端到端路径。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-19;arXiv v1:2024-10-15;CVPR 2025 fixed official PDF
逐一查看v1(2024-10-15)、v2(10-30)、v3(11-06)、v4(2025-03-19)。v1底色及模块布局不同;v2/v3采用新布局但残差块配色等细节仍不同。v4与固定会议图同坐标300dpi裁剪像素完全一致(MAE=0),故使用v4日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jinshan Pan;26700;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[80, 73, 532, 284],PDF点、左上角原点。
Figure 3. Overview of DORNet. Given D as input, the degradation learning first encodes it to produce degradation representations D˜
up
and D. Then, D˜, D, D , and I are fed into multiple degradation-oriented feature transformation (DOFT) modules, generating the HR
lr
depth D . Finally, D and D are sent to the degradation regularization to obtain D , which is used as input for the degradation loss
hr hr d
L and the contrastive loss L . The degradation regularization only applies during training and adds no extra overhead in testing.
deg cont
DORNet: A Degradation Oriented and Regularized Network for Blind Depth Super-Resolution
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第1页 · P173
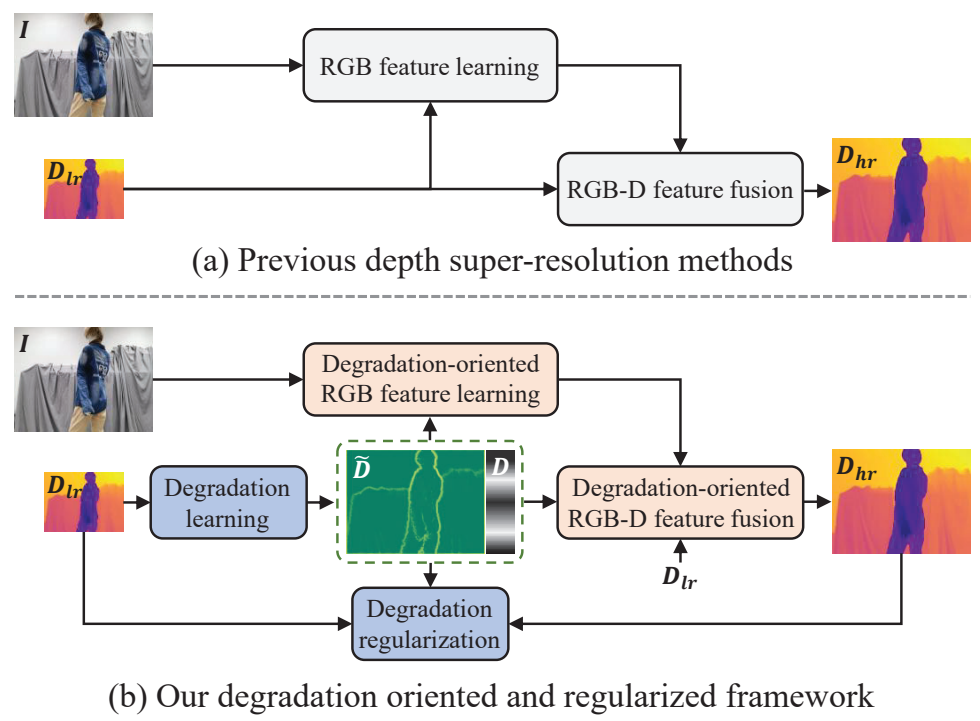
300 dpi PNG · 图注 · 源PDF
图1概念对比现有RGB融合与未知退化的冲突,说明引入退化学习及正则的动机。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-19;arXiv v1:2024-10-15;CVPR 2025 fixed official PDF
逐一查看v1(2024-10-15)、v2(10-30)、v3(11-06)、v4(2025-03-19)。v1/v2缺少底部退化正则回路;v3增加回路但标签/文字视觉仍不同。v4与固定会议图同坐标300dpi裁剪像素完全一致(MAE=0),故使用v4日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jinshan Pan;26700;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[317, 244, 552, 417],PDF点、左上角原点。
Figure 1. Previous methods (a) directly fuse the RGB information
aligned with the LR depth, while our method (b) focuses more on
modeling the degradation representation of the LR depth to pro-
vide targeted guidance for HR depth recovery.
FaithDiff: Unleashing Diffusion Priors for Faithful Image Super-resolution
会议:CVPR 2025 · 主会论文
Figure 2 · PDF第3页 · P172
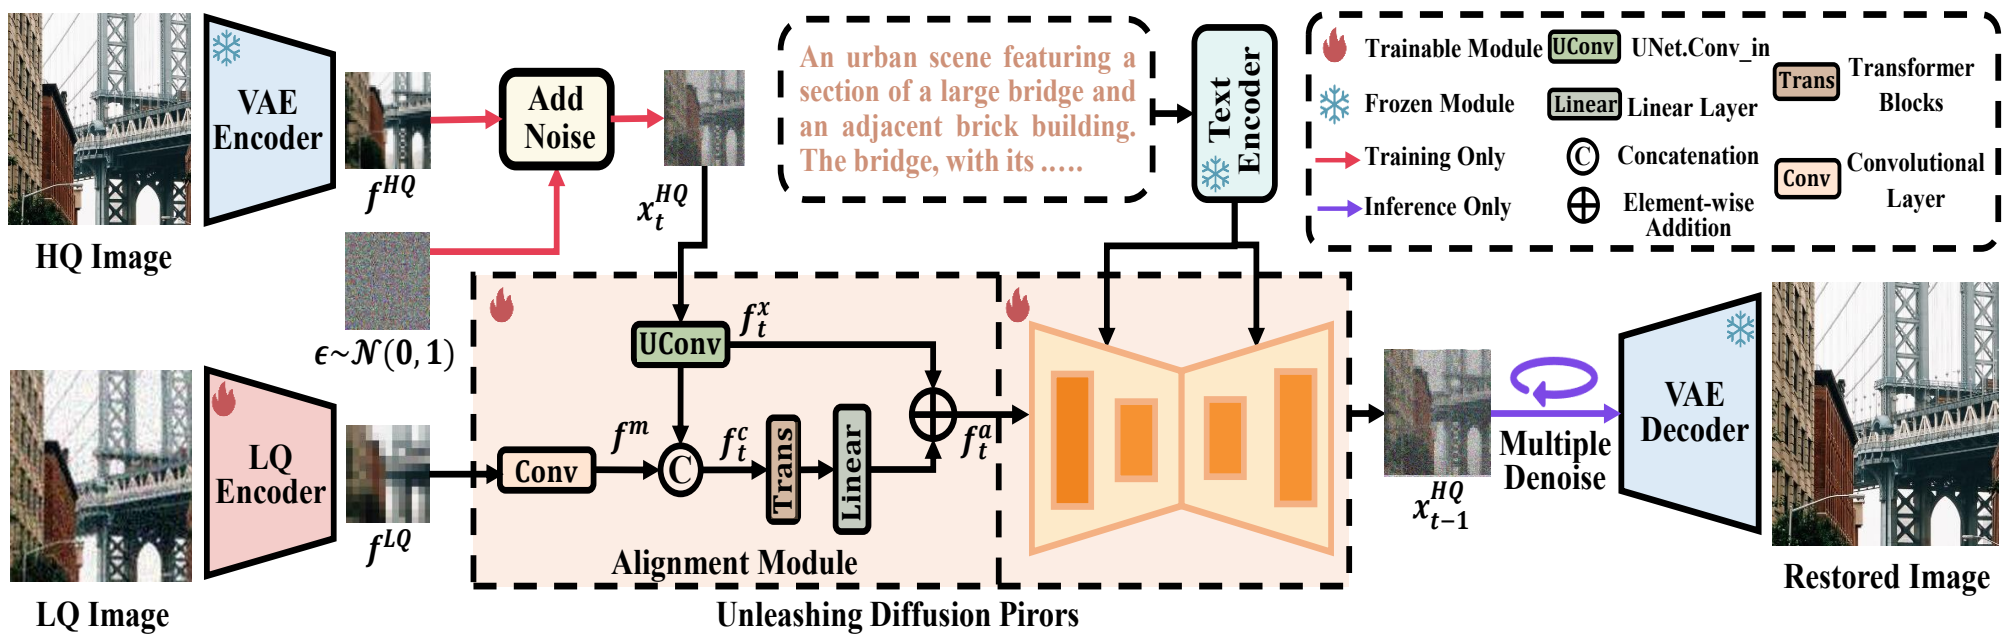
300 dpi PNG · 图注 · 源PDF
图2明确为FaithDiff整体概览,包含高低质量分支、特征对齐、扩散去噪、文本条件和解码输出。
完整图注、版本和筛选证据
最早核实视觉日期:2025-06;arXiv v1:2024-11-27;CVPR 2025 fixed official PDF
仅有arXiv v1(2024-11-27),已查看。会议图与v1不完全相同:框架重绘,改变模块位置、训练噪声分支和图例排布。不把会议视觉版本回溯到v1。使用CVF官方BibTeX明确的2025年6月出版月份作为当前最早已核实证据;精度为月,不声称首次绘制日。历史PDF及图仅供差异对照。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jinshan Pan;26700;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[65, 72, 548, 226],PDF点、左上角原点。
Figure 2. An overview of the FaithDiff, which takes LQ images and image descriptions as inputs and restores HQ images via diffusion
process. To fully leverage the power of LDMs, we propose to unleash diffusion priors. An alignment module is developed to effectively
incorporate the features extracted from LQ images with the noisy latent of the diffusion model. We jointly optimize the encoder, the
alignment module, and the diffusion model, which can benefit from their interplay and lead to faithful SR images with high visual quality.
FaithDiff: Unleashing Diffusion Priors for Faithful Image Super-resolution
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第2页 · P171
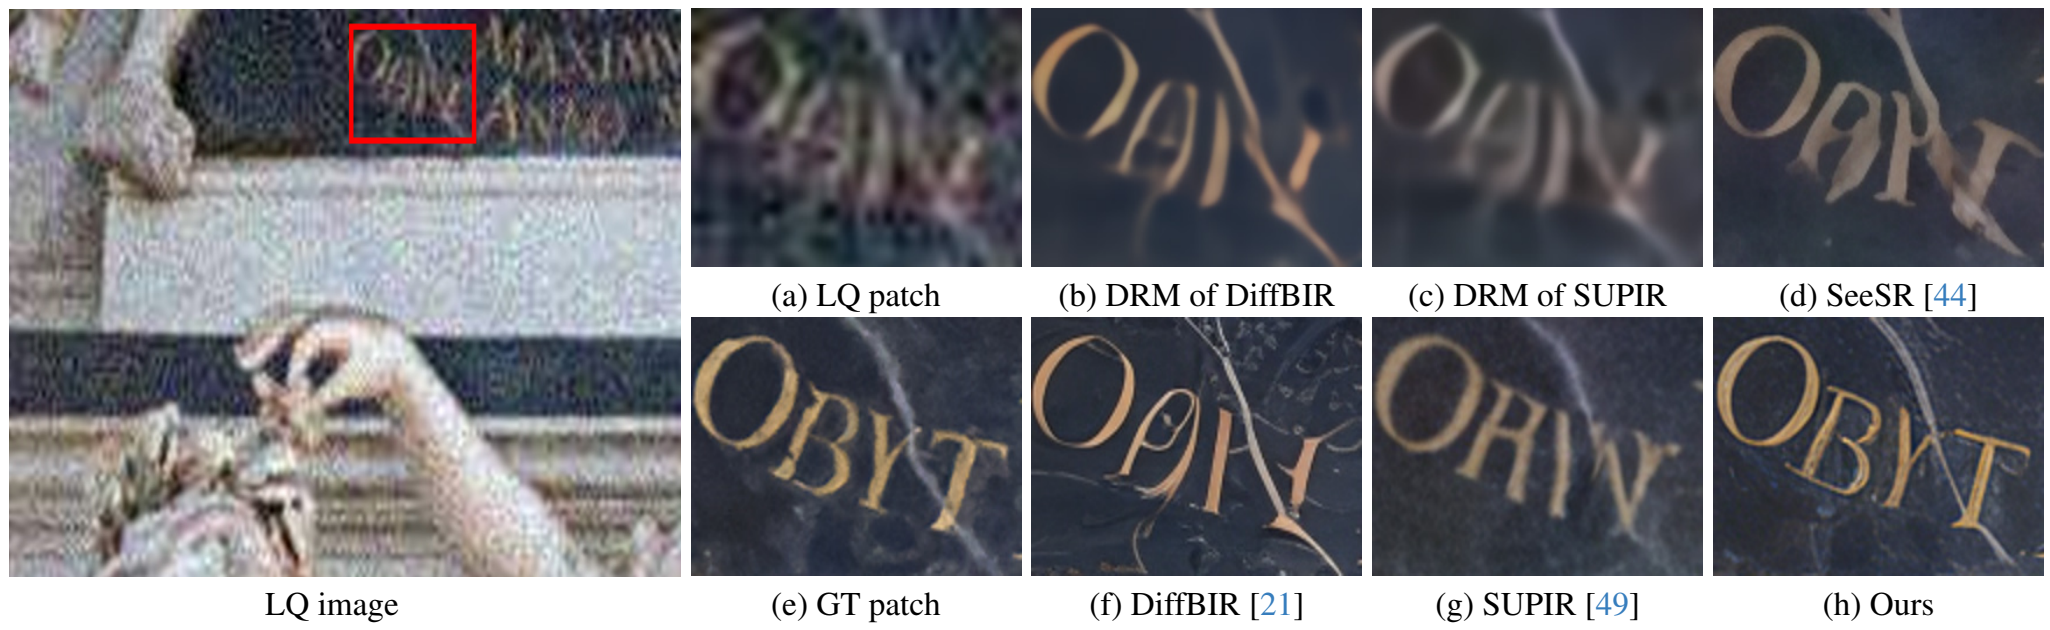
300 dpi PNG · 图注 · 源PDF
引言结合图1中间输出解释退化消除模块损坏文字结构后,冻结扩散模型无法纠正并产生错误字符;是具体失败诊断。
完整图注、版本和筛选证据
最早核实视觉日期:2025-06;arXiv v1:2024-11-27;CVPR 2025 fixed official PDF
仅有arXiv v1(2024-11-27),已查看。会议图与v1不完全相同:图内SeeSR/SUPIR引文编号从41/44更新为44/49;其他构图相同。不把会议视觉版本回溯到v1。使用CVF官方BibTeX明确的2025年6月出版月份作为当前最早已核实证据;精度为月,不声称首次绘制日。历史PDF及图仅供差异对照。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jinshan Pan;26700;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[59, 70, 551, 221],PDF点、左上角原点。
Figure 1. Visual comparison with state-of-the-art SR methods. (b) and (c) are the intermediate results of the degradation removal module
(DRM) by DiffBIR [21] and SUPIR [49]. The competing methods [21, 49] do not effectively restore faithful structures based on the
degradation removal results in (b)-(c). In contrast to the results in (d) and (f)-(g), our approach can recover more realistic high-quality
results with faithful contents (e.g., the characters in (h)).
From Zero to Detail: Deconstructing Ultra-High-Definition Image Restoration from Progressive Spectral Perspective
会议:CVPR 2025 · 主会论文
Figure 3 · PDF第3页 · P170
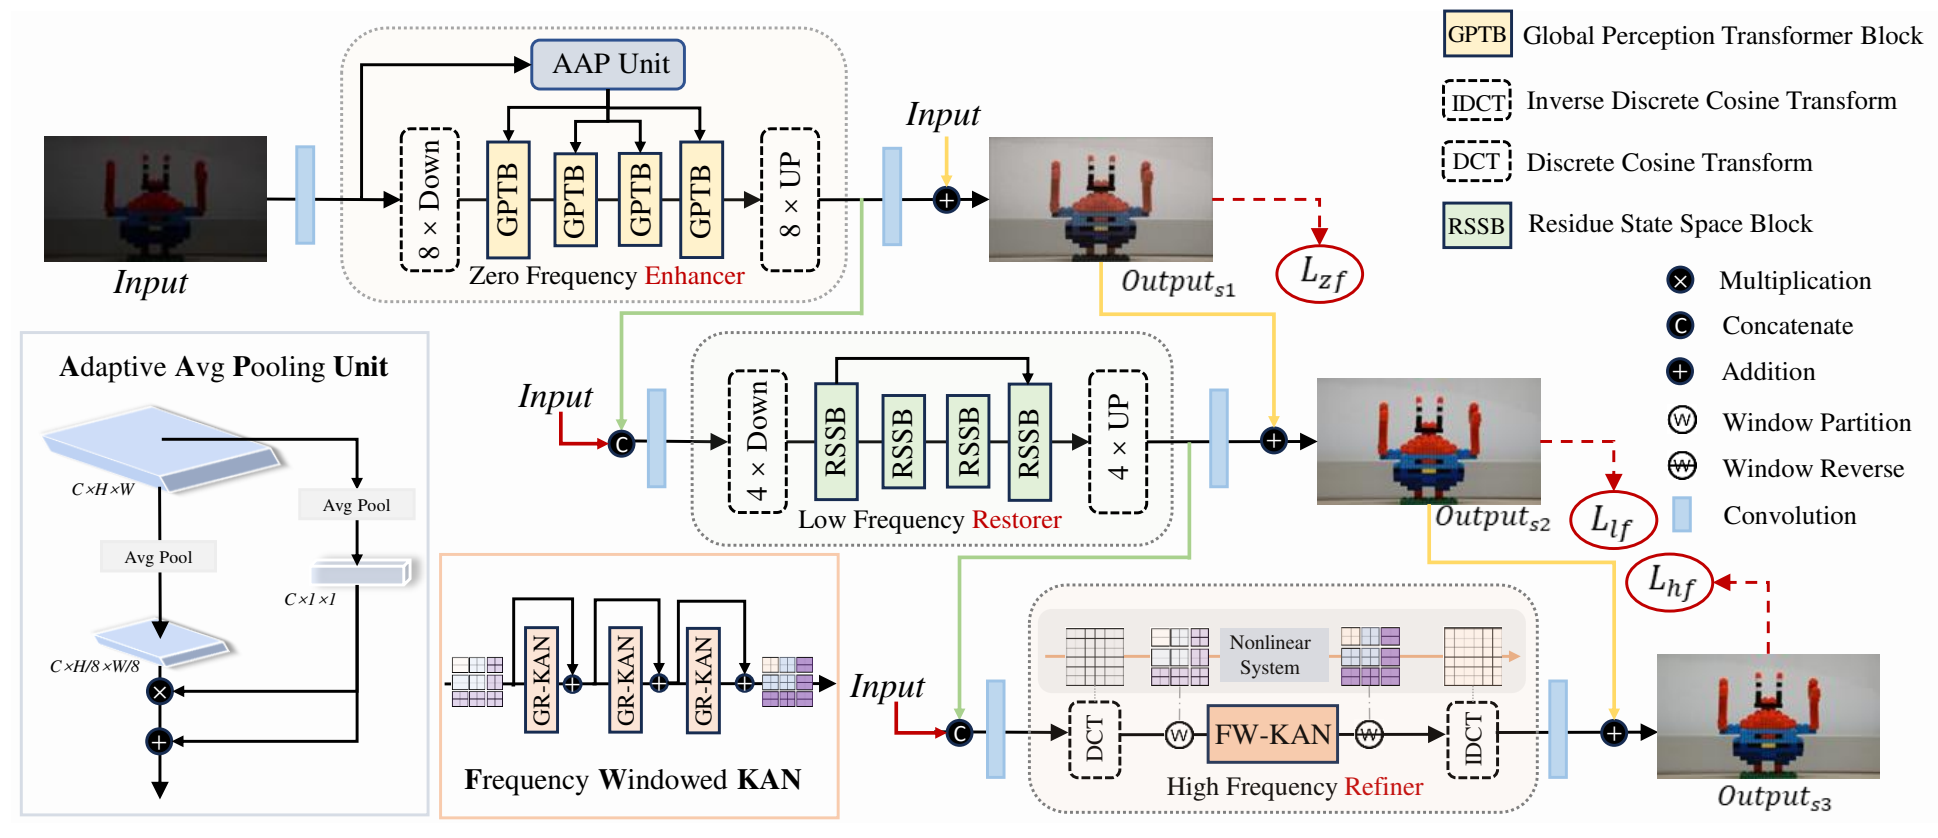
300 dpi PNG · 图注 · 源PDF
图3明确为整体ERR,展示零频增强、低频复原、高频细化的完整三阶段路径和训练损失。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-17;arXiv v1:2025-03-17;CVPR 2025 fixed official PDF
核对arXiv v1(2025-03-17)和CVPR固定版本:布局、配色、连线、子图和文字匹配;栅格压缩/渲染有轻微像素差异。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Ying Tai;19268;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[70, 72, 535, 273],PDF点、左上角原点。
Figure 3. Overall framework of our proposed ERR. Building on the insight from progressive spectral perspective, ERR consists of three
collaborative sub-networks: the zero-frequency enhancer (ZFE), the low-frequency restorer (LFR), and the high-frequency refiner (HFR).
From Zero to Detail: Deconstructing Ultra-High-Definition Image Restoration from Progressive Spectral Perspective
会议:CVPR 2025 · 主会论文
Figure 2 · PDF第2页 · P169
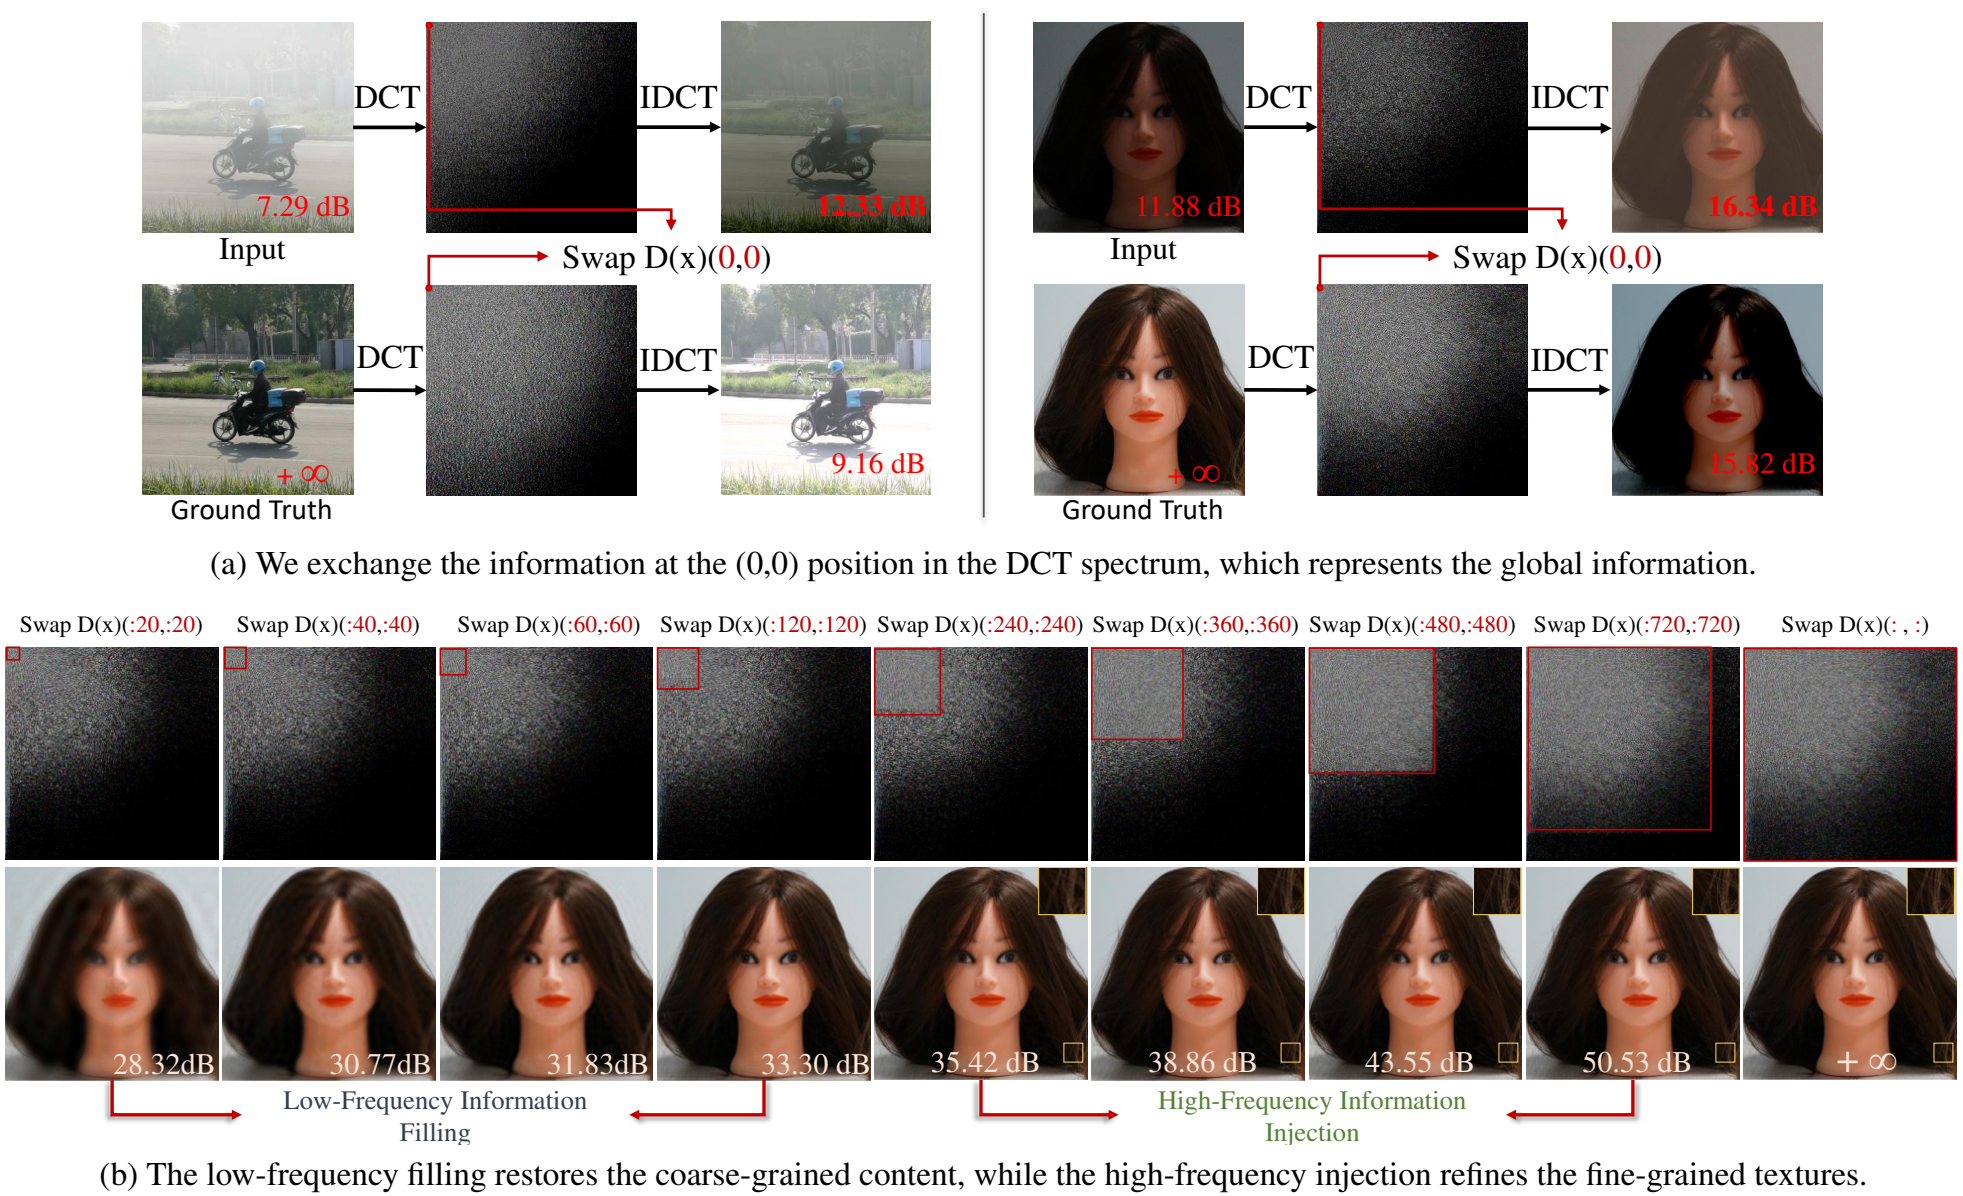
300 dpi PNG · 图注 · 源PDF
引言以图2频率交换及逐步填充的概念实验解释UHD复原的频谱难点,明确称为core motivation;图1仅为普通结果比较。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-17;arXiv v1:2025-03-17;CVPR 2025 fixed official PDF
核对arXiv v1(2025-03-17)和CVPR固定版本:布局、配色、连线、子图和文字匹配;栅格压缩/渲染有轻微像素差异。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Ying Tai;19268;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[70, 70, 541, 357],PDF点、左上角原点。
Figure 2. Our core motivation. Based on the observations in (a) and (b), we deconstruct the complex UHD restoration problem into three
progressive stages: zero-frequency enhancement, low-frequency restoration, and high-frequency refinement.
GenDeg: Diffusion-based Degradation Synthesis for Generalizable All-In-One Image Restoration
会议:CVPR 2025 · 主会论文
Figure 4 · PDF第4页 · P104
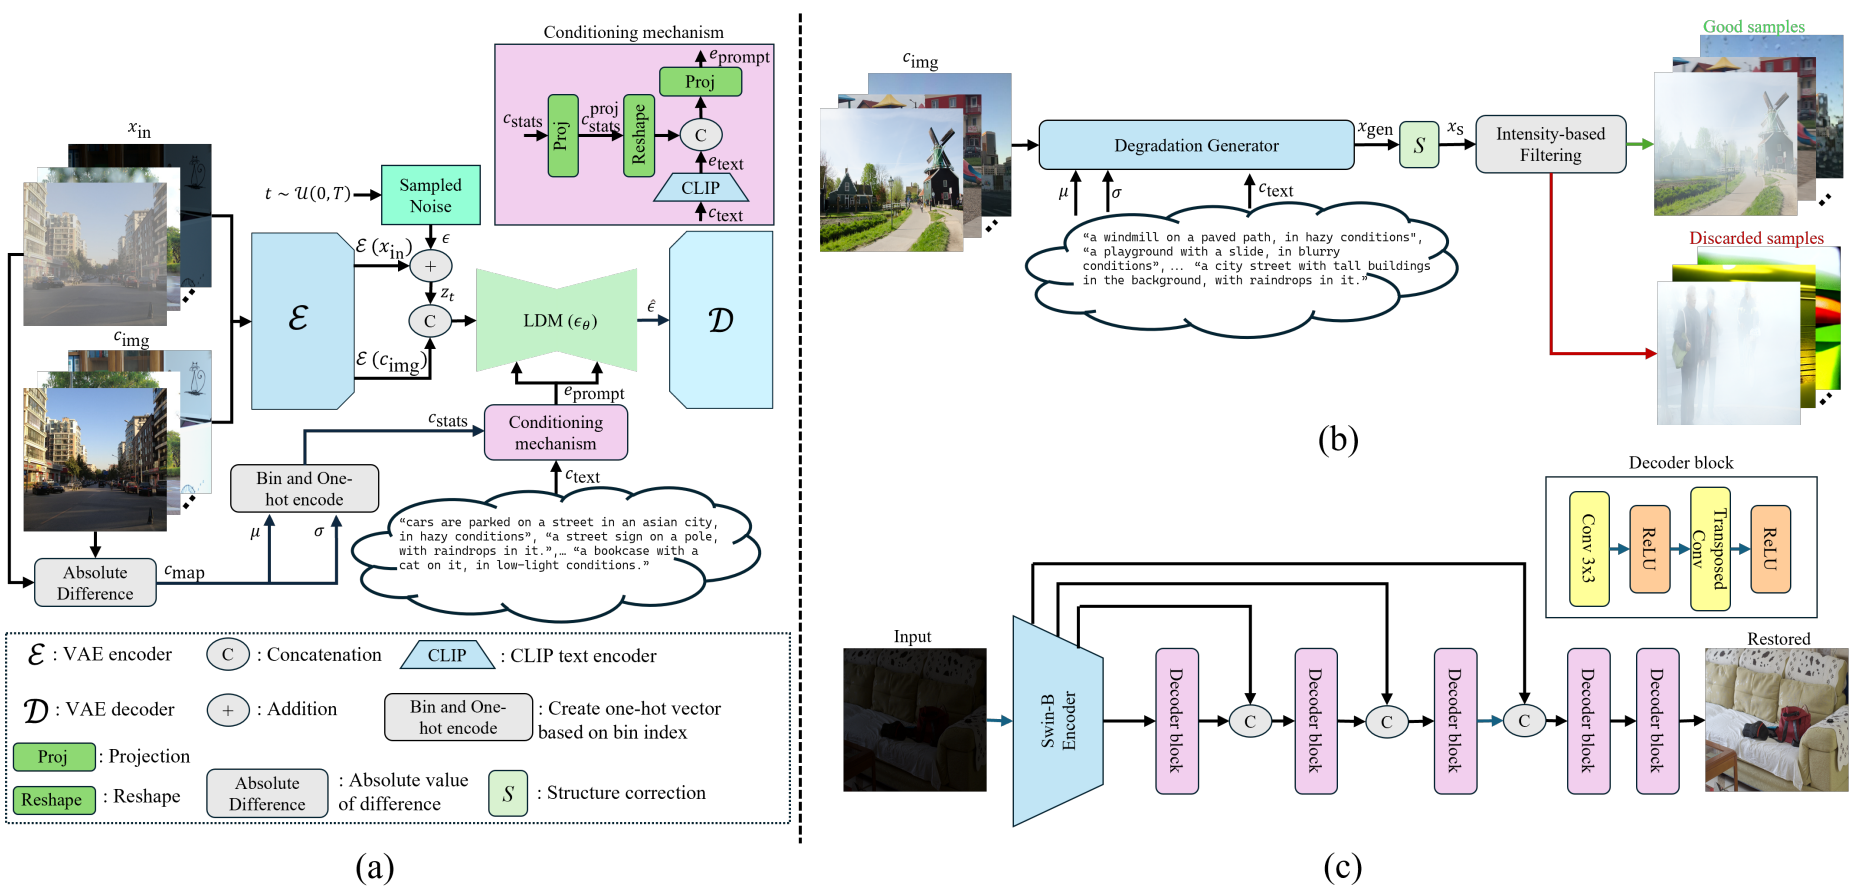
300 dpi PNG · 图注 · 源PDF
正文GenDeg方法与图4展示退化生成器训练、合成数据筛选及复原网络的完整路径,保留全部三面板和图例。
完整图注、版本和筛选证据
最早核实视觉日期:2024-11-26;arXiv v1:2024-11-26;CVPR 2025 fixed official PDF
已阅读固定版本图注和正文;与arXiv历史对应视觉比较,具体差异记入逐图核查记录。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Vishal M. Patel;48975;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[82, 70, 530, 283],PDF点、左上角原点。
Figure 4. (a) Illustrates the training stage of the GenDeg model where it is trained to condition on the clean image, text prompt and mean
intensity (µ) and variation (σ) of the degradation pattern. (b) Shows the inference stage where the model generates a degraded image based
on these conditions; and (c) Depicts the architecture of the Swin-transformer-based restoration network.
GenDeg: Diffusion-based Degradation Synthesis for Generalizable All-In-One Image Restoration
会议:CVPR 2025 · 主会论文
Figure 2 · PDF第2页 · P103
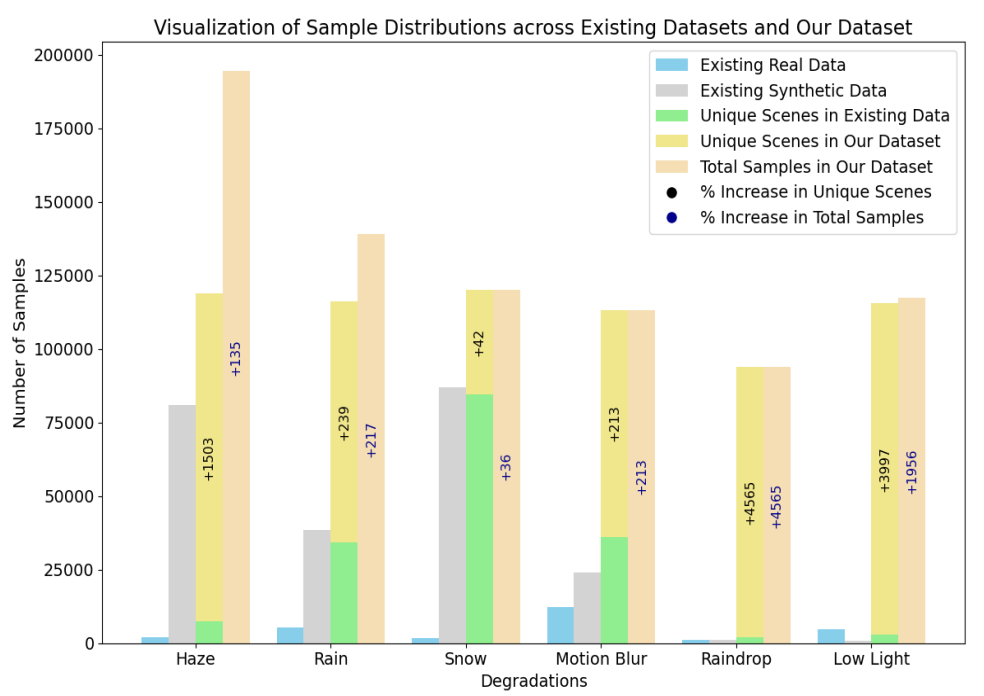
300 dpi PNG · 图注 · 源PDF
引言第2页以图2说明现有退化数据集规模小、场景种类少、退化间不平衡;图为数据局限分析而非性能排行。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-22;arXiv v1:2024-11-26;CVPR 2025 fixed official PDF
v1图2与会议图2的柱高及百分比标注不同,如Haze +1619/+139改为+1503/+135;v2图2逐像素匹配会议图,采用2025-03-22,不回填v1日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Vishal M. Patel;48975;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[318, 72, 554, 239],PDF点、左上角原点。
Figure 2. Analysis of real and synthetic image restoration datasets
for various degradations. Existing datasets are small and less di-
verse, especially for haze, low-light, and raindrop. Our diffusion-
generated synthetic data substantially increases the number of
samples as well as scene diversity.
PassionSR: Post-Training Quantization with Adaptive Scale in One-Step Diffusion based Image Super-Resolution
会议:CVPR 2025 · 图源:存档 arXiv v1
Figure 4 · PDF第4页 · P22
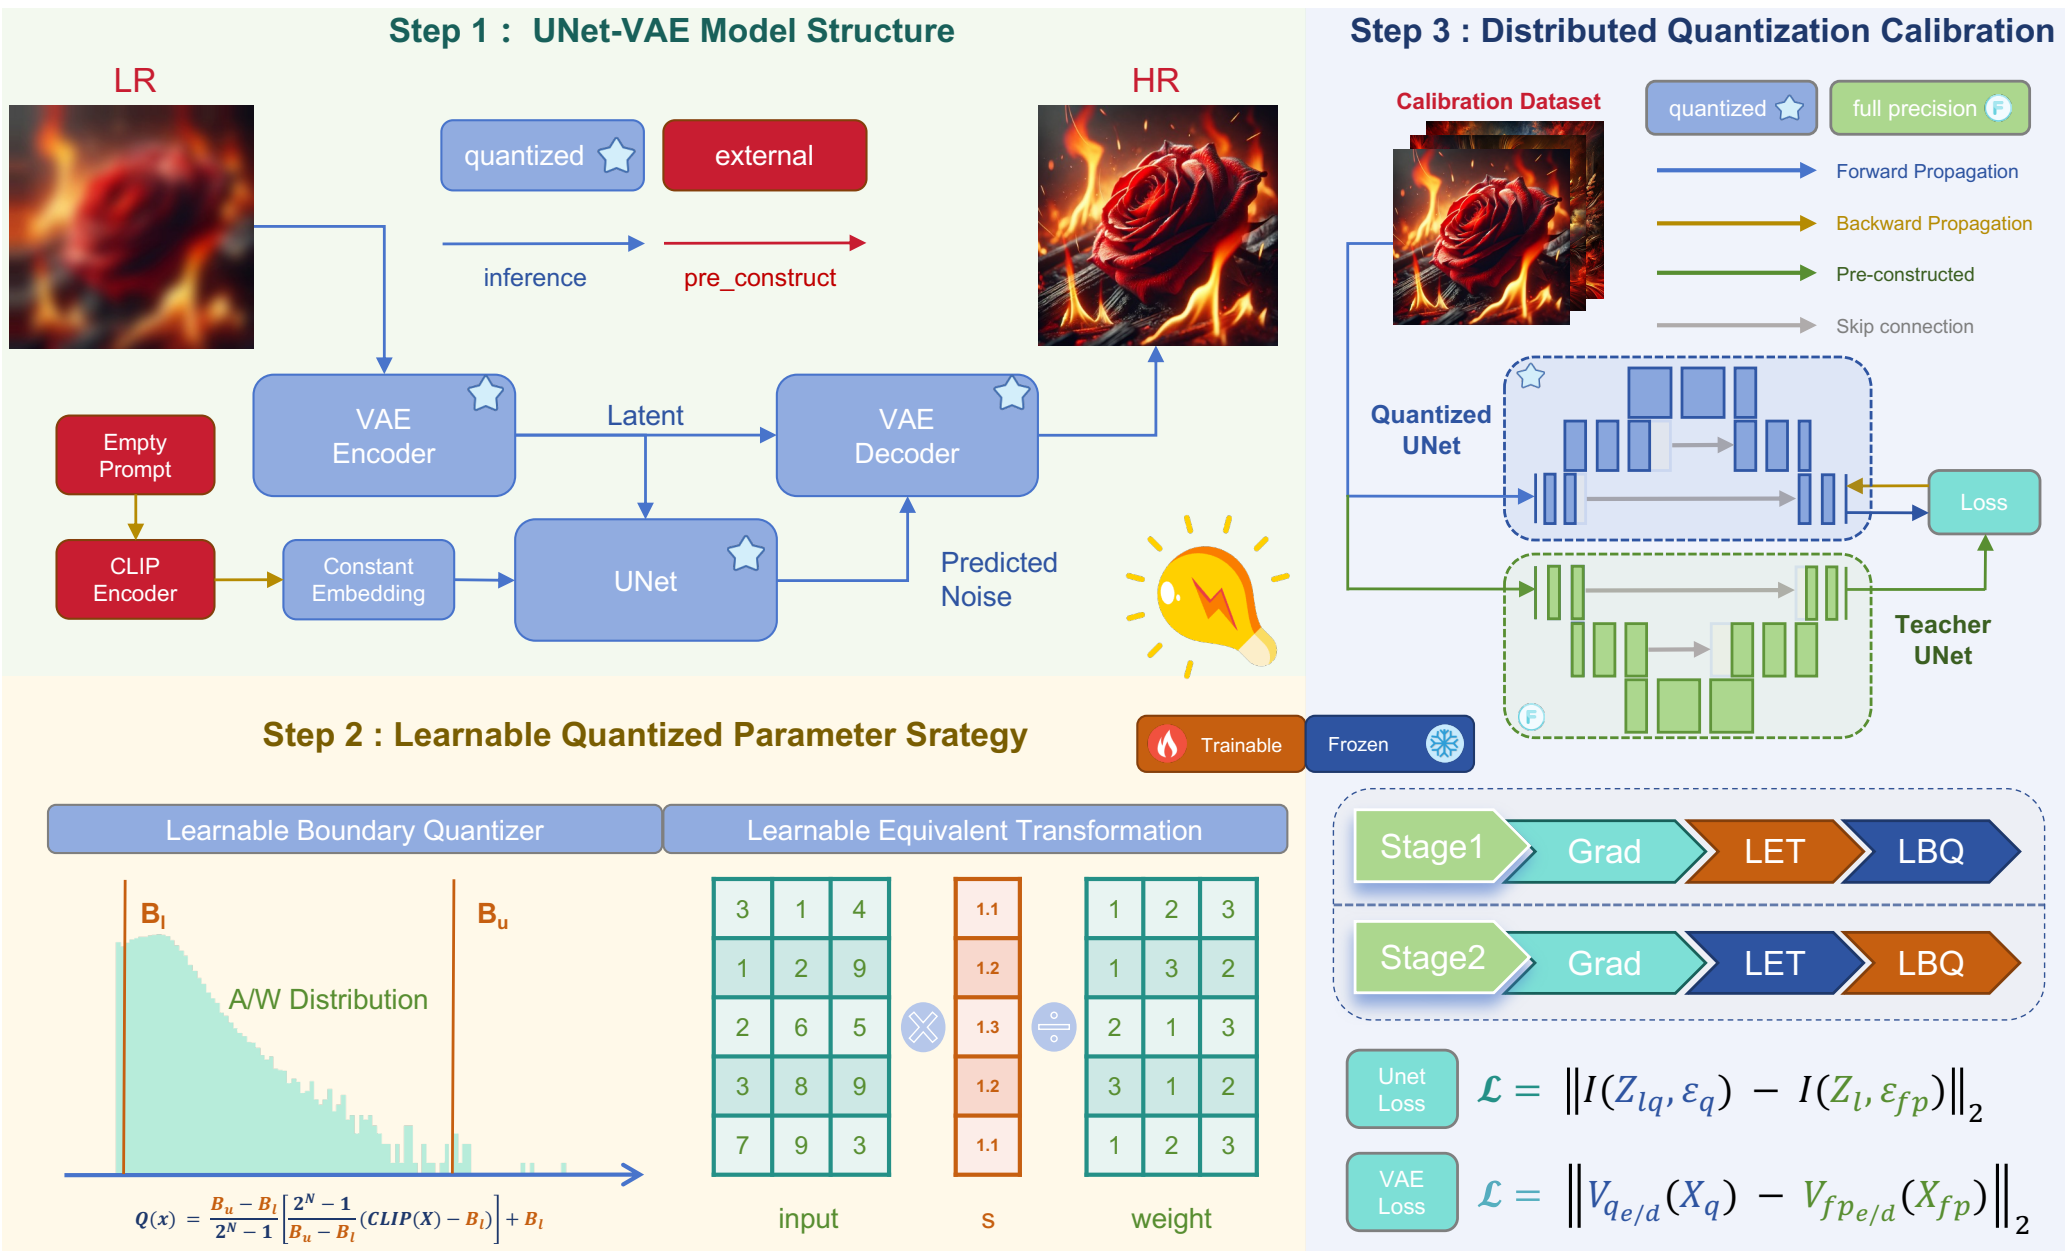
300 dpi PNG · 图注 · 源PDF
图4 Overview完整串联UNet–VAE简化、LBQ/LET可学习量化参数和分布量化校准三步骤;第3节逐项对应,属于全方法流程。
完整图注、版本和筛选证据
最早核实视觉日期:2024-11-26;arXiv v1:2024-11-26;arXiv v1 fixed source
固定arXiv v1原件;会议视觉与早期版本存在差异,未给新版图套用v1日期。TARS已查看v1/v2及会议版;PassionSR已查看v1/v2/v3及会议版;具体差异保留在review页图中。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Yulun Zhang;40552;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[58, 70, 554, 372],PDF点、左上角原点。
Figure 4. Overview of our PassionSR. Step 1: we simplify OSEDiff [42] by removing DAPE and CLIP Encoder, obtaining PassionSR-
FP. Step 2: the quantizer we use has two key trainable parts, consisting of the Learnable Boundary Quantizer and Learnable Equivalent
Transformation. Step 3: we design a distributed calibration strategy and special loss function to accelerate convergence of calibration.
PassionSR: Post-Training Quantization with Adaptive Scale in One-Step Diffusion based Image Super-Resolution
会议:CVPR 2025 · 图源:存档 arXiv v1
Figure 2 · PDF第2页 · P21
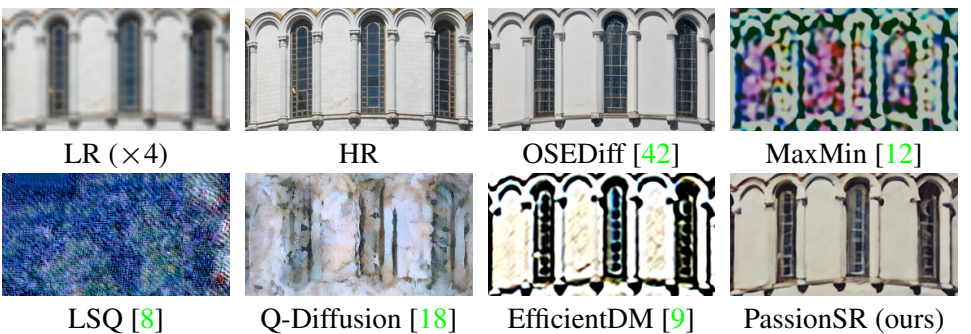
300 dpi PNG · 图注 · 源PDF
引言第2页列举从多步转为单步的量化挑战,明确引用图2说明现有量化方法产生噪声和结构破坏,属于失败案例。图1主要展示性能与模型规模,不作M。
完整图注、版本和筛选证据
最早核实视觉日期:2024-11-26;arXiv v1:2024-11-26;arXiv v1 fixed source
固定arXiv v1原件;会议视觉与早期版本存在差异,未给新版图套用v1日期。TARS已查看v1/v2及会议版;PassionSR已查看v1/v2/v3及会议版;具体差异保留在review页图中。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Yulun Zhang;40552;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[318, 70, 551, 150],PDF点、左上角原点。
Figure 2. Visual comparison (×4) of one-step diffusion SR models. We use OSEDiff as a 32-bit full-precision (FP) reference and provide 6-bit quantized version with different methods.
QMambaBSR: Burst Image Super-Resolution with Query State Space Model
会议:CVPR 2025 · 主会论文
Figure 2 · PDF第4页 · P178
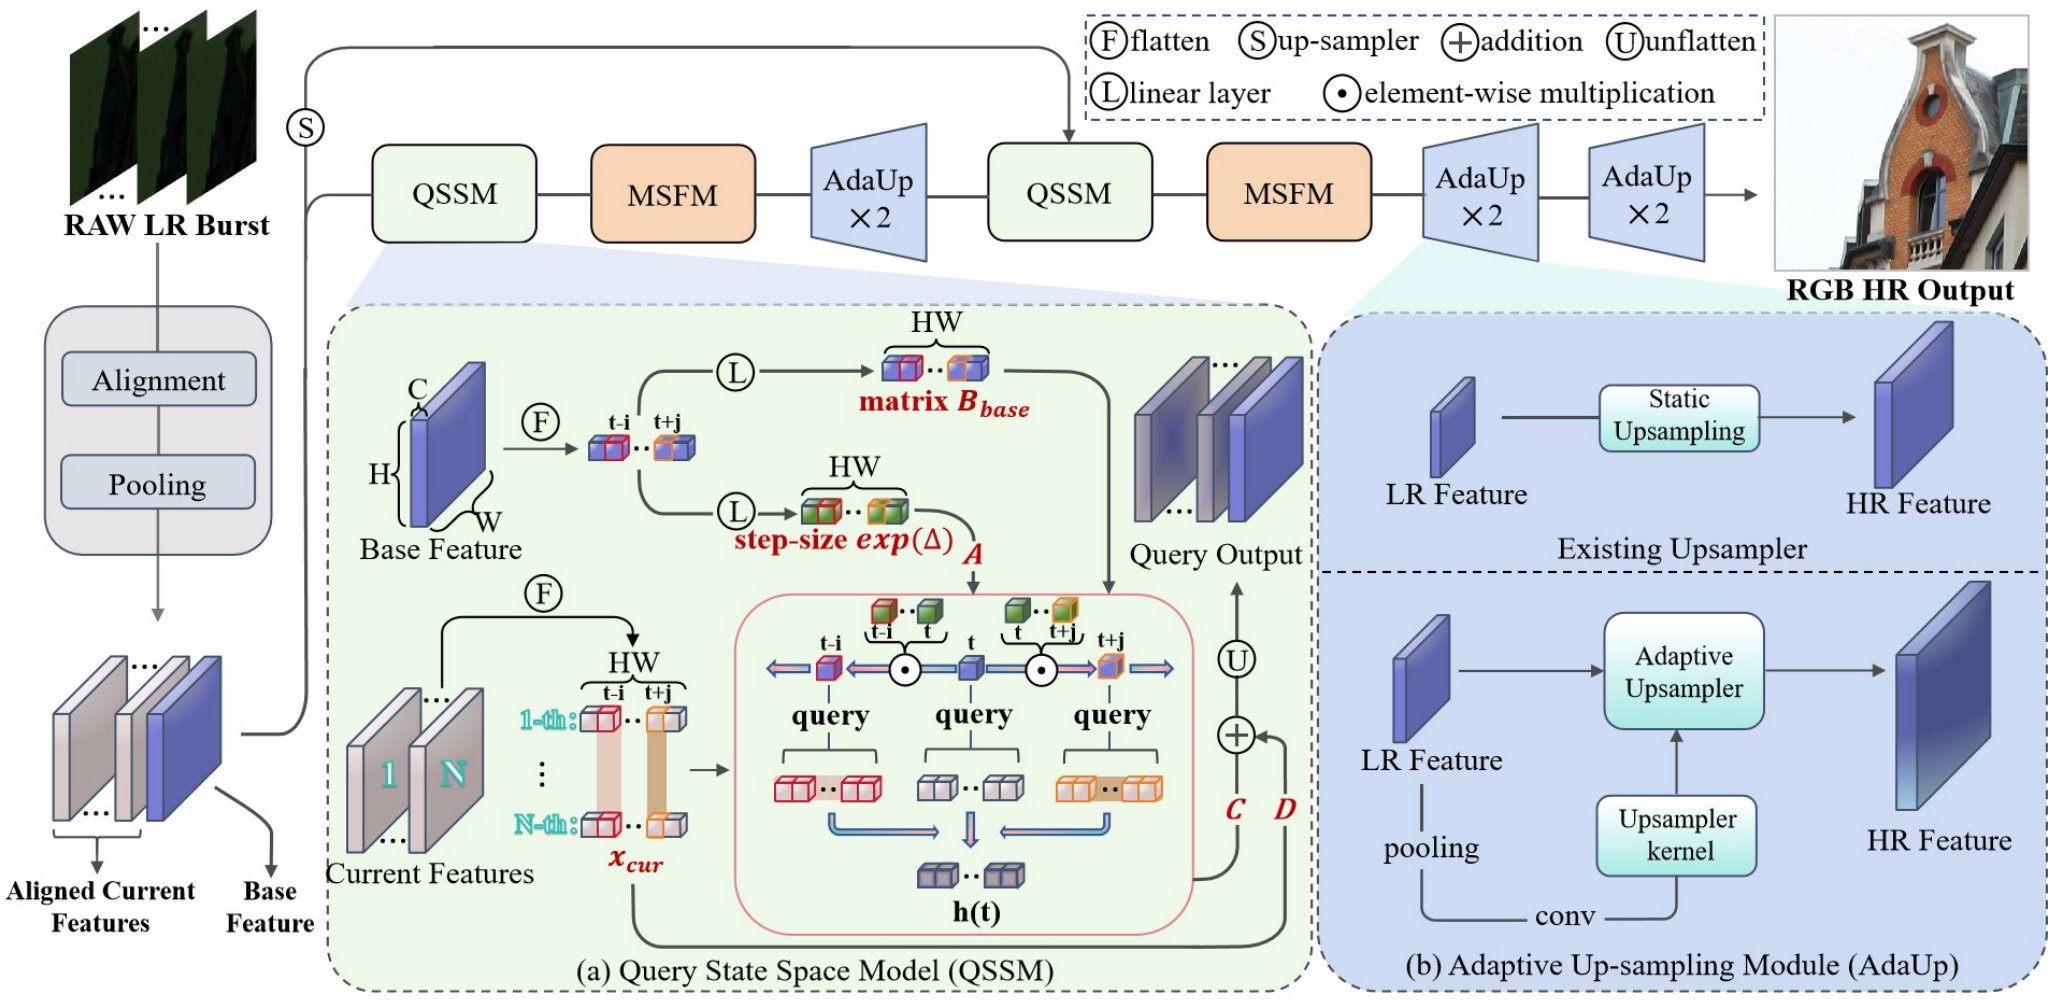
300 dpi PNG · 图注 · 源PDF
图2为QMambaBSR整体框架,保留RAW连拍输入、对齐、QSSM、MSFM、AdaUp以及RGB高分辨率输出。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-10;arXiv v1:2024-08-16;CVPR 2025 fixed official PDF
已查看v1(2024-08-16)和v2(2025-03-10)。v1整体图右侧含MSFM分图,AdaUp及查询模块布局亦不同。v2与会议目标图同坐标300dpi裁剪完全一致(MAE=0);不沿用v1日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Zheng-Jun Zha;30479;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[62, 73, 555, 314],PDF点、左上角原点。
Figure 2. The overall framework of our proposed QMambaBSR, primarily includes the novel Query State Space Model (QSSM), Multi-
scale Fusion Module (MSFM), and the Adaptive Up-sampling Module (AdaUp).
QMambaBSR: Burst Image Super-Resolution with Query State Space Model
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第1页 · P177
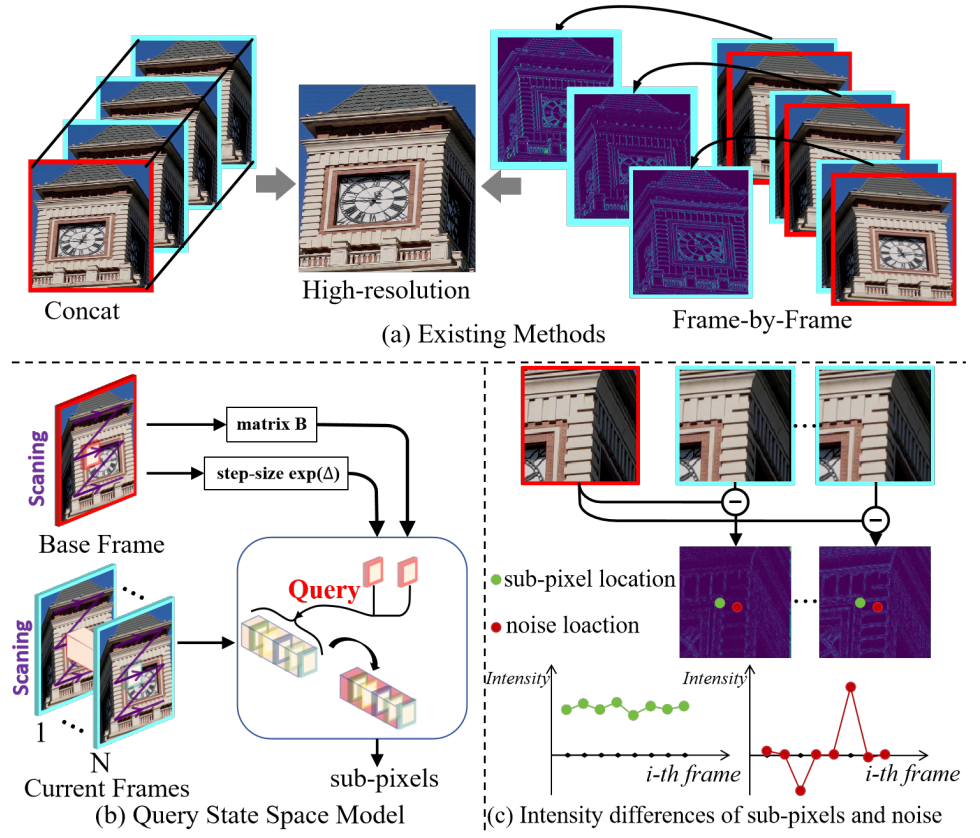
300 dpi PNG · 图注 · 源PDF
引言和图1解释拼接/逐帧融合难分辨稳定亚像素与随机噪声,并用跨帧强度关系说明问题;是概念对比。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-10;arXiv v1:2024-08-16;CVPR 2025 fixed official PDF
已查看v1(2024-08-16)和v2(2025-03-10)。v1图1在第2页,强度曲线的数字/标记与目标图不同。v2与会议目标图同坐标300dpi裁剪完全一致(MAE=0);不沿用v1日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Zheng-Jun Zha;30479;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[317, 213, 552, 414],PDF点、左上角原点。
Figure 1. The concat and frame-by-frame operations in exist-
ing methods struggle to efficiently extract sub-pixels and suppress
noise, leading to remaining artifacts and over-smoothed details, as
shown in (a). We observe that noise randomly appears on several
frames, while effective sub-pixels have consistent intensity at cor-
responding positions in all frames, as shown in (c). Based on this,
a novel inter-frame query and intra-frame scanning-based QMam-
baBSR is proposed to extract more accurate sub-pixels while mit-
igating noise interference simultaneously, as shown in (b).
Rotation-Equivariant Self-Supervised Method in Image Denoising
会议:CVPR 2025 · 主会论文
Figure 3 · PDF第6页 · P176
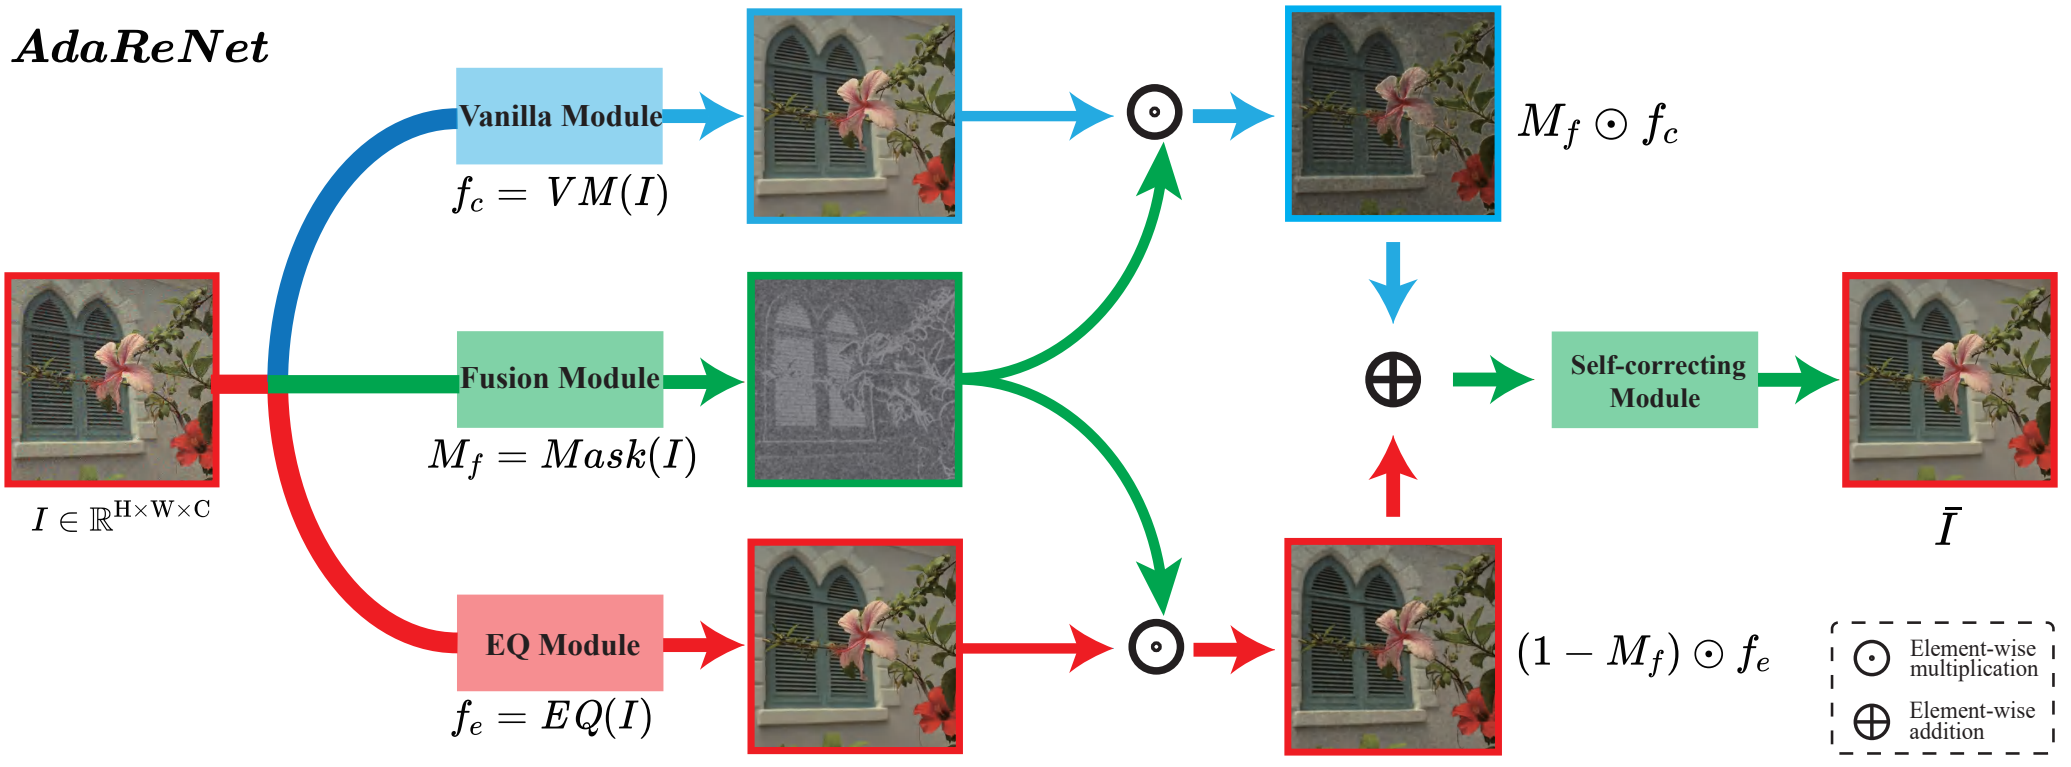
300 dpi PNG · 图注 · 源PDF
第3.2节明确图3为完整AdaReNet,展示Vanilla、EQ、Fusion与Self-correcting四模块共同产生最终去噪图像。
完整图注、版本和筛选证据
最早核实视觉日期:2025-05-26;arXiv v1:2025-05-26;CVPR 2025 fixed official PDF
arXiv v1(2025-05-26)为唯一历史版本,与会议目标图同坐标300dpi裁剪像素完全相同(MAE=0)。作者Deyu Meng的西安交大身份与公开引用主页一致。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Deyu Meng;49595;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 71, 555, 255],PDF点、左上角原点。
Figure3. IllustrationsofourproposedadaptivenetworkAdaReNet. Specifically, I ∈ RH×W×C representsanoisyimage, whereH andW
represent the spatial dimensions, and C denotes the channel dimension. The Vanilla Module and EQ Module each produce their respective
preliminary denoising results, denoted as f and f . The Fusion Module Mask(·) automatically decides which areas of the image to use
c e
moreEQModulewouldgainmorebenefit. AfteradaptivefusionbyMask(·)andcorrectionbytheSelf-correctingModuleS (·), thefinal
c
denoised image I¯is output.
Rotation-Equivariant Self-Supervised Method in Image Denoising
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第1页 · P175
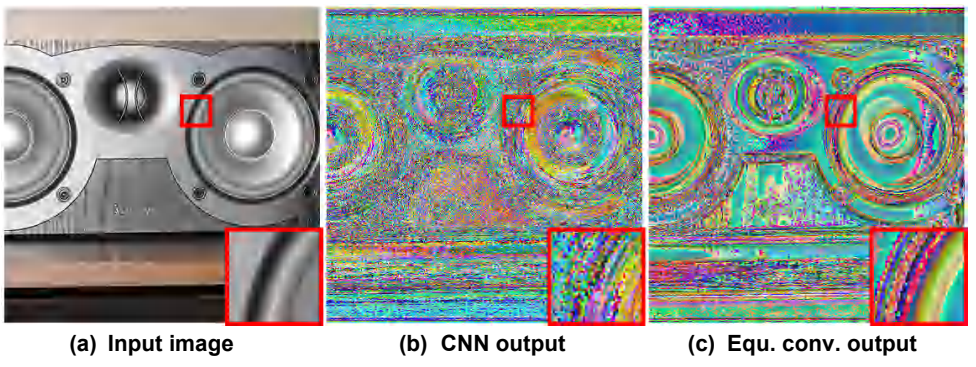
300 dpi PNG · 图注 · 源PDF
引言及图1以随机初始化网络说明普通CNN与旋转等变网络的特征差异,引出自监督去噪对结构先验的需求。
完整图注、版本和筛选证据
最早核实视觉日期:2025-05-26;arXiv v1:2025-05-26;CVPR 2025 fixed official PDF
arXiv v1(2025-05-26)为唯一历史版本,与会议目标图同坐标300dpi裁剪像素完全相同(MAE=0)。作者Deyu Meng的西安交大身份与公开引用主页一致。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Deyu Meng;49595;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[319, 229, 553, 317],PDF点、左上角原点。
Figure 1. Illustration of the output feature map of a typical image
obtained by standard CNN and our used rotation equivariant con-
volution neural network. Both networks are initialized randomly.
The Power of Context: How Multimodality Improves Image Super-Resolution
会议:CVPR 2025 · 主会论文
Figure 3 · PDF第3页 · P70
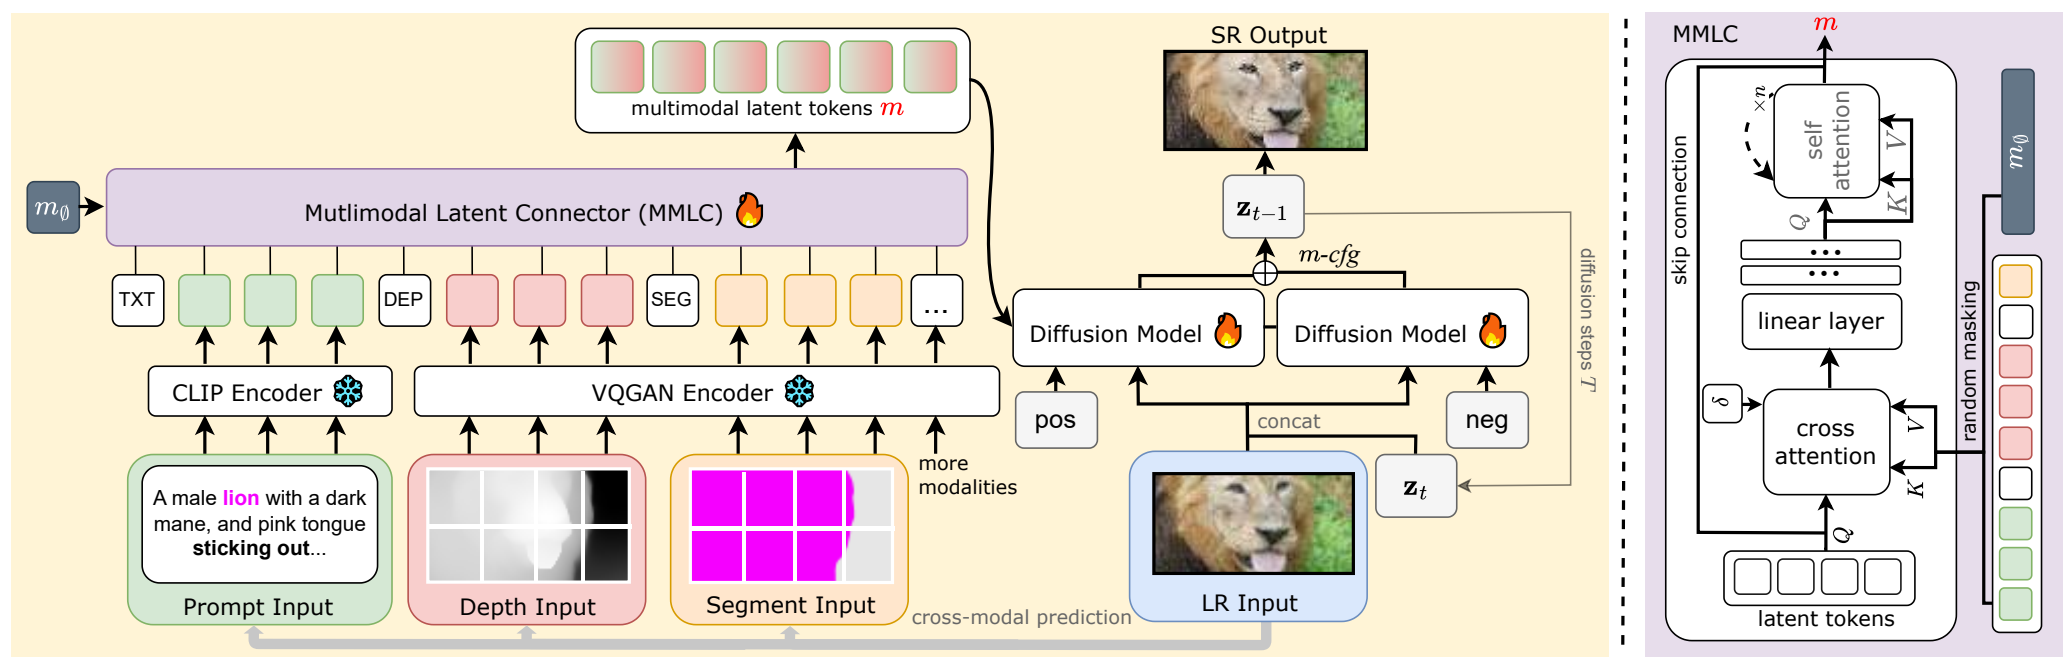
300 dpi PNG · 图注 · 源PDF
第3.1节和图3描述从低分辨率输入、跨模态先验提取、潜空间连接到扩散超分的完整流程。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-18;arXiv v1:2025-03-18;CVPR 2025 fixed official PDF
已查看固定PDF及目标图;以最早已核实匹配版本日期作时间代理,不声称实际作图日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Vishal M. Patel;48975;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 70, 555, 230],PDF点、左上角原点。
Figure 3. This diagram illustrates our multimodal super-resolution pipeline. Starting with a low-resolution (LR) image, we extract modalities
like depth and semantic segmentation maps. These modalities are encoded into tokens and transformed into multimodal latent tokens (m).
Our diffusion model uses these tokens and the LR input to generate a high-resolution (SR) output. A multimodal classifier-free guidance
(m-cfg) refines the SR image for enhanced quality.
The Power of Context: How Multimodality Improves Image Super-Resolution
会议:CVPR 2025 · 主会论文
Figure 2 · PDF第2页 · P69
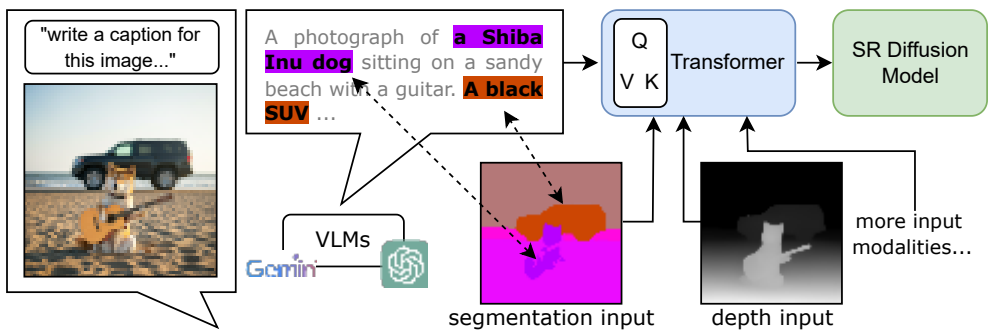
300 dpi PNG · 图注 · 源PDF
引言和图2指出语言描述无法精确表达空间位置,导致粗糙和不精确超分;图1是方法输出概览,因此采用明确解释问题的图2。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-18;arXiv v1:2025-03-18;CVPR 2025 fixed official PDF
已查看固定PDF及目标图;以最早已核实匹配版本日期作时间代理,不声称实际作图日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Vishal M. Patel;48975;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[316, 70, 555, 150],PDF点、左上角原点。
Figure 2. Language models struggle to accurately represent spa-
tial information, leading to coarse and imprecise image super-
resolution. To overcome this limitation, we incorporate additional
spatialmodalitieslikedepthmapsandsemanticsegmentationmaps.
These modalities provide detailed spatial context, allowing our
model to implicitly align language descriptions with individual pix-
els through a transformer network. This enriched understanding of
theimagesignificantlyenhancestherealismofoursuper-resolution
results and minimizes distortion.
A Lightweight UDF Learning Framework for 3D Reconstruction Based on Local Shape Functions
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第3页 · P218
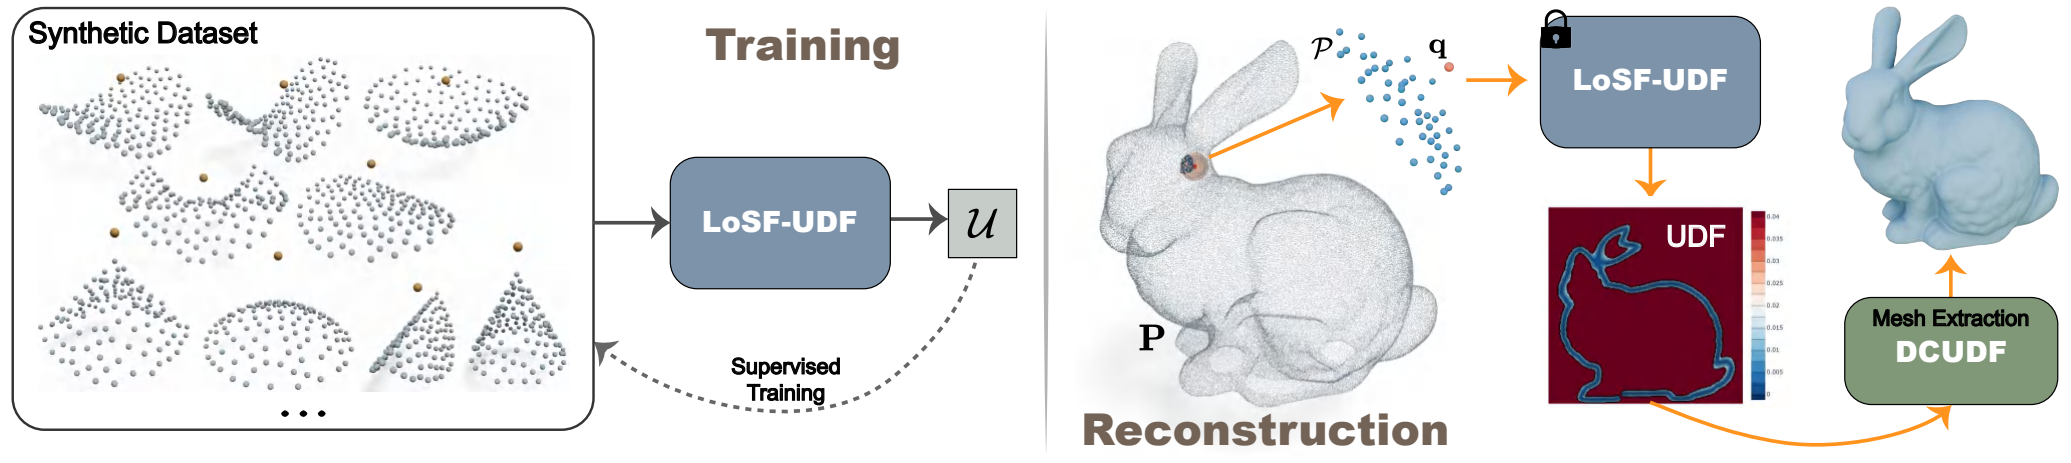
300 dpi PNG · 图注 · 源PDF
图1Pipeline及正文给出完整训练与重建路径:合成局部数据、UDF网络训练、查询点预测与DCUDF网格提取。
完整图注、版本和筛选证据
最早核实视觉日期:2024-07-01;arXiv v1:2024-07-01;CVPR 2025 fixed official PDF
已打开v1第3页及v2第3页。v1图1整体随版心均匀缩放;合成点云、UDF预测、网格提取及所有文字、连线一致。按对应图元坐标反算历史裁剪;最早匹配v1(2024-07-01)。图像压缩与缩放差异不视为重绘。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Junhui Hou;21404;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 73, 555, 184],PDF点、左上角原点。
Figure 1. Pipeline. First, we train a UDF prediction network U on a synthetic dataset, which contains a series of local point cloud patches
Θ
that are independent of specific shapes. Given a global point cloud P, we then extract a local patch P assigned to each query point q within
a specified radius, and obtain the corresponding UDF values U (P , q). Finally, we extract the mesh corresponding to the input point cloud
Θˆ
by incorporating the DCUDF [18] framework.
A Lightweight UDF Learning Framework for 3D Reconstruction Based on Local Shape Functions
会议:CVPR 2025 · 主会论文
Figure 2 · PDF第3页 · P217
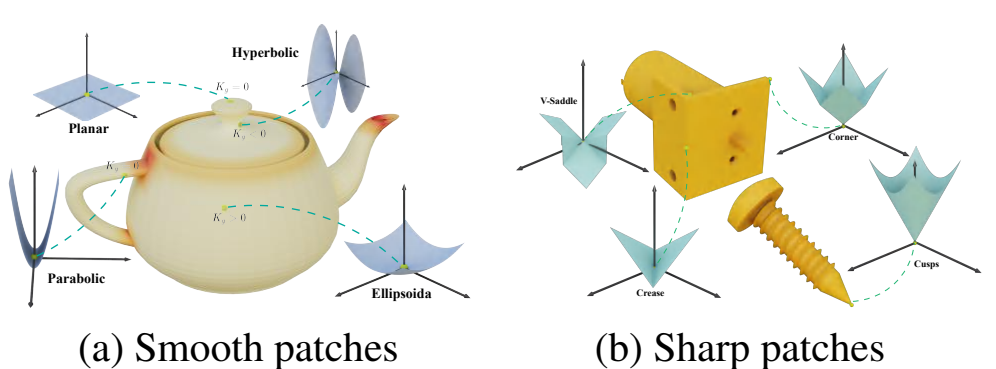
300 dpi PNG · 图注 · 源PDF
图2及第3节Motivation/3.1说明一般形状在局部可分解为平滑与尖锐几何模式,通过茶壶和立方体对比引出局部形状训练数据的概念依据;不是局部网络模块。
完整图注、版本和筛选证据
最早核实视觉日期:2025-05-10;arXiv v1:2024-07-01;CVPR 2025 fixed official PDF
核查v1(2024-07-01)与v2(2025-05-10):v1图2位于第4页、图内分组标签相对几何示意的比例不同;固定会议图的分组文字排布首次在v2第3页匹配。几何内容未改变;以v2视觉排布为保守公开代理,仍在S2。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Junhui Hou;21404;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 590, 297, 678.5],PDF点、左上角原点。
Figure 2. Local geometries. (a) For points on a geometry that are
differentiable, the local shape at these points can be approximated
by quadratic surfaces. (b) For points that are non-differentiable, we
can also construct locally approximated surfaces using functions.
Carve3D: Improving Multi-view Reconstruction Consistency for Diffusion Models with RL Finetuning
会议:CVPR 2024 · 主会论文
Figure 2 · PDF第3页 · P336
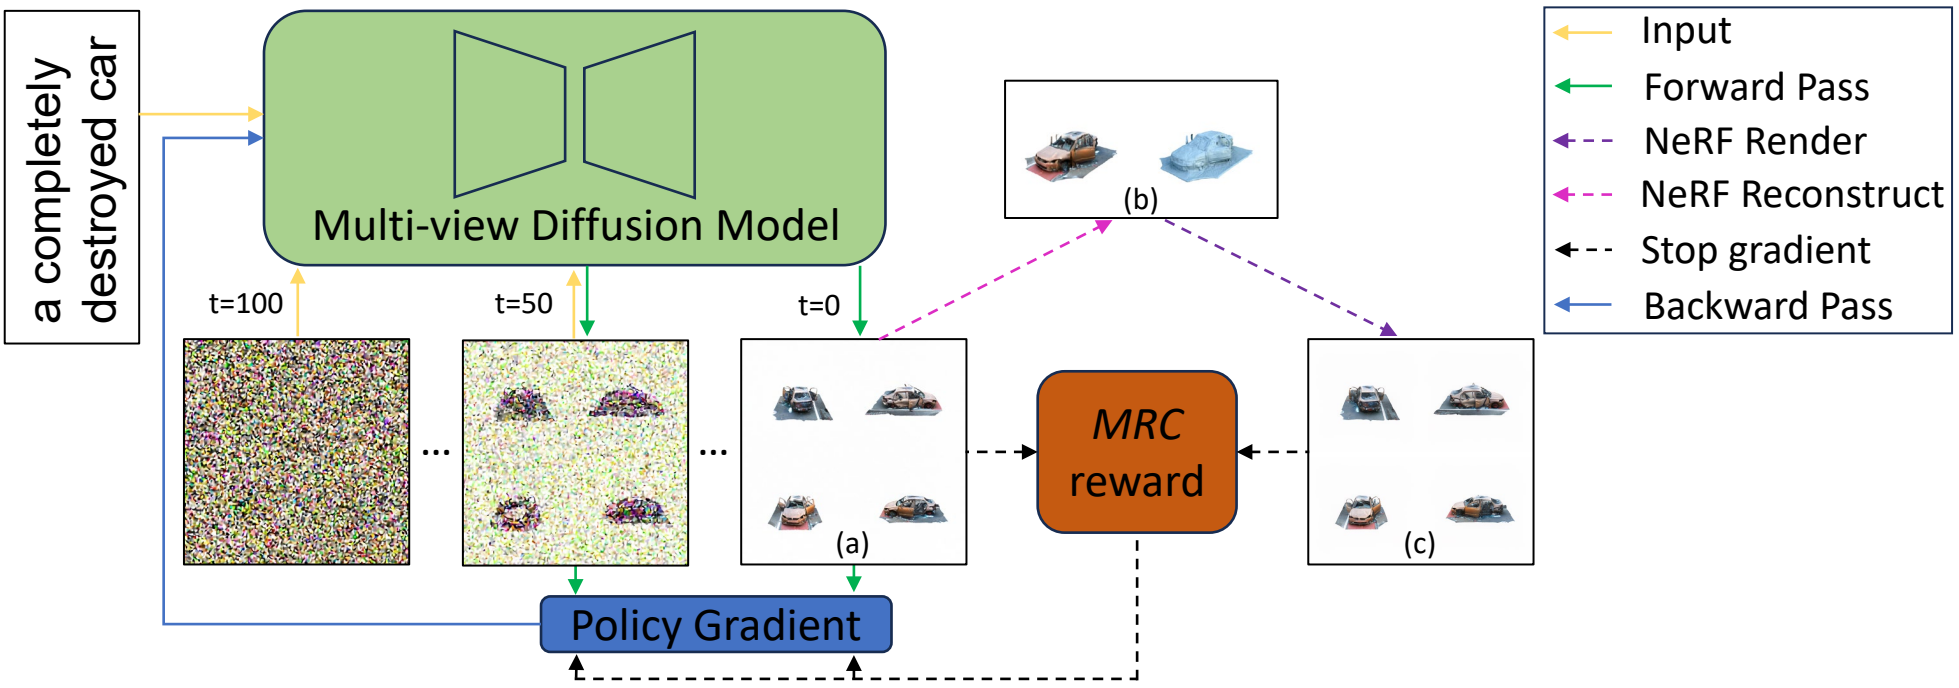
300 dpi PNG · 图注 · 源PDF
图2明确为Carve3D整体框架,包含文本条件去噪、NeRF重建与渲染、MRC奖励和梯度更新。
完整图注、版本和筛选证据
最早核实视觉日期:2023-12-21;arXiv v1:2023-12-21;CVPR 2024 fixed official PDF
会议F2与v1 p3图形完全匹配(MAE0)。会议M1与v2 p2完全匹配(MAE0);v1 p2缺少MV/TP/RM行标签,且子图排版不同,故M不回溯v1。已实际查看两历史PDF、会议版图注与正文及导出。Hao Tan与Adobe作者身份一致;真实绘图日期未知。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Hao Tan;12273;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[64, 72, 534, 237],PDF点、左上角原点。
Figure 2. Overview of Carve3D. Given a prompt sampled from our curated prompt set and a initial noisy image, we iteratively denoise
the image using the UNet. The final, clean image contains four multi-view images tiled in a 2-by-2 grid. MRC reward is computed by
comparing (a) the generated multi-view images with (c) the corresponding multi-view images rendered at the same camera viewpoints
from (b) the reconstructed NeRF. Then, we train the model with policy gradient loss function, where the loss is derived from the reward
and log probabilities of the UNet’s predictions, accumulated over all denoising timesteps. By using only a set of training text prompts, our
RLFT algorithm finetunes the diffusion model by evaluating its own generated outputs, without relying on ground truth multi-view images.
Carve3D: Improving Multi-view Reconstruction Consistency for Diffusion Models with RL Finetuning
会议:CVPR 2024 · 主会论文
Figure 1 · PDF第2页 · P335
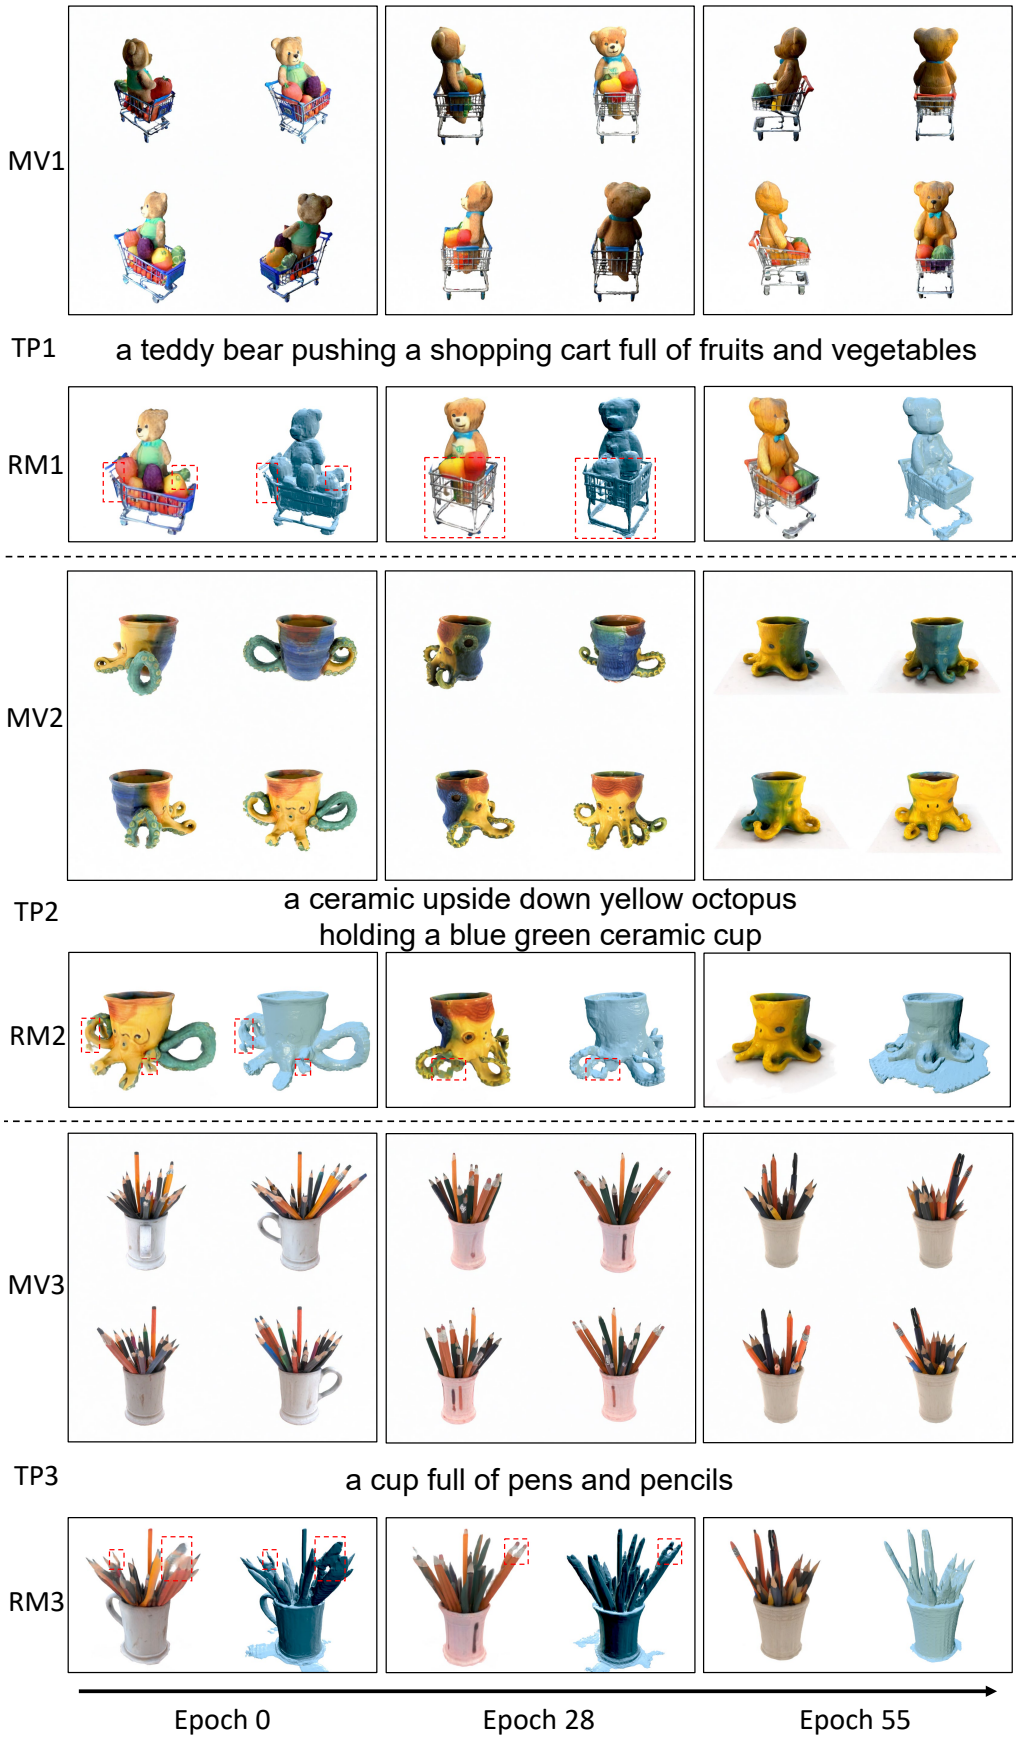
300 dpi PNG · 图注 · 源PDF
图1以红框明确指出多视图不一致造成的购物车朝向、章鱼腕及铅笔位置重建伪影,图注和引言用于解释问题;包含训练改善对比但非普通无解释结果拼图。
完整图注、版本和筛选证据
最早核实视觉日期:2024-04-09;arXiv v1:2023-12-21;CVPR 2024 fixed official PDF
会议F2与v1 p3图形完全匹配(MAE0)。会议M1与v2 p2完全匹配(MAE0);v1 p2缺少MV/TP/RM行标签,且子图排版不同,故M不回溯v1。已实际查看两历史PDF、会议版图注与正文及导出。Hao Tan与Adobe作者身份一致;真实绘图日期未知。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Hao Tan;12273;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[49, 72, 294, 490],PDF点、左上角原点。
Figure 1. Our Carve3D algorithm steadily improves the 3D con-
sistency of a multi-view diffusion model and the resulting quality
of the NeRF and the mesh, without sacrificing its image-prompt
alignment, texture details, or realism. Here, we show 3 testing-
set results (in 3 rows, numbered as 1-3, separated by dotted lines)
from the finetuning process (epoch 0, 28, and 55 in 3 columns).
Each row includes the generated multi-view images (denoted as
MV), the reconstructed NeRF and extracted mesh (denoted as RM)
and the text prompt (denoted as TP). The inconsistencies in the
multi-view images, e.g. the facing direction of the shopping cart,
the position of the octopus arms, and the position of the pencils,
lead to artifacts in the NeRF and the mesh (highlighted in red).
CrossSDF: 3D Reconstruction of Thin Structures From Cross-Sections
会议:CVPR 2025 · 主会论文
Figure 2 · PDF第3页 · P222
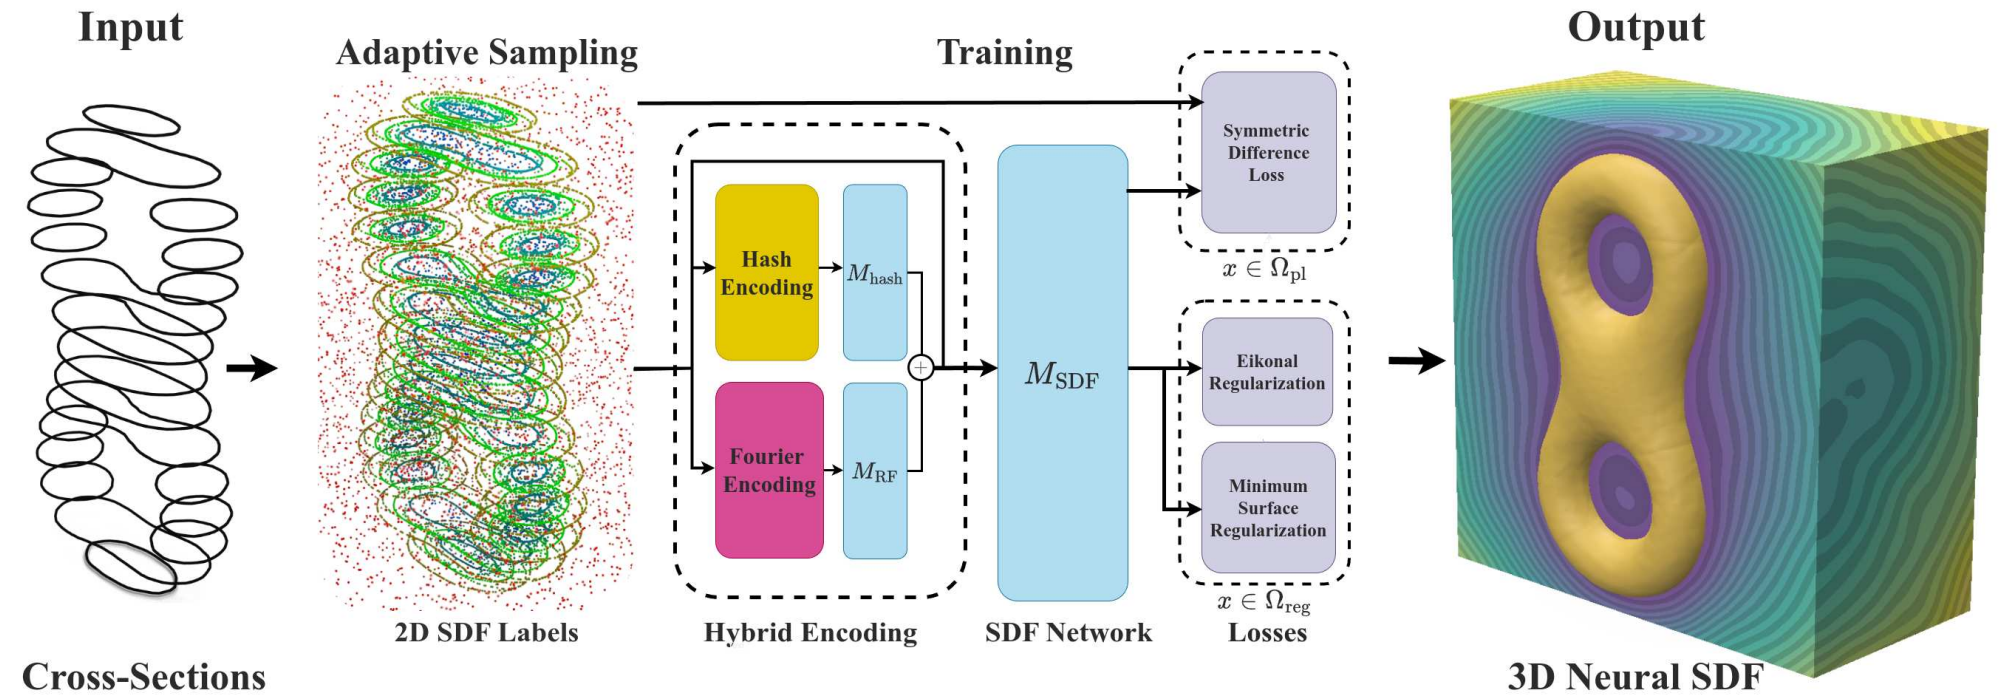
300 dpi PNG · 图注 · 源PDF
图2及3.1节明确为完整pipeline,含截面输入、自适应采样、混合编码、SDF网络、损失及三维输出。
完整图注、版本和筛选证据
最早核实视觉日期:2024-12-05;arXiv v1:2024-12-05;CVPR 2025 fixed official PDF
已打开arXiv v1(2024-12-05)第3页。图2主图对象坐标及原始像素尺寸相同;所有模块、连线、文字和输出相同,差异图为压缩/栅格化误差(MAE=2.285),不是新增图形内容。最早匹配v1。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Oisin Mac Aodha;18397;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[68, 74, 550, 242],PDF点、左上角原点。
Figure 2. CrossSDF takes a set of planar cross-sections as input. These cross-sections result in contours which denote the surface
boundaries of the target geometry of interest (left, black lines) and each induces a 2D signed distance field (SDF) in its respective plane.
From this, we generate a set of planar sample points Ω and their 2D SDF labels. During training, points are encoded using our hybrid
pl
encoder before being passed to the SDF network M for prediction. At each iteration we create a set of 3D samples Ω to apply
SDF reg
volumetric regularization. The combination of our novel sampling, loss function, and hybrid encoding results in a high quality 3D SDF.
CrossSDF: 3D Reconstruction of Thin Structures From Cross-Sections
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第1页 · P221
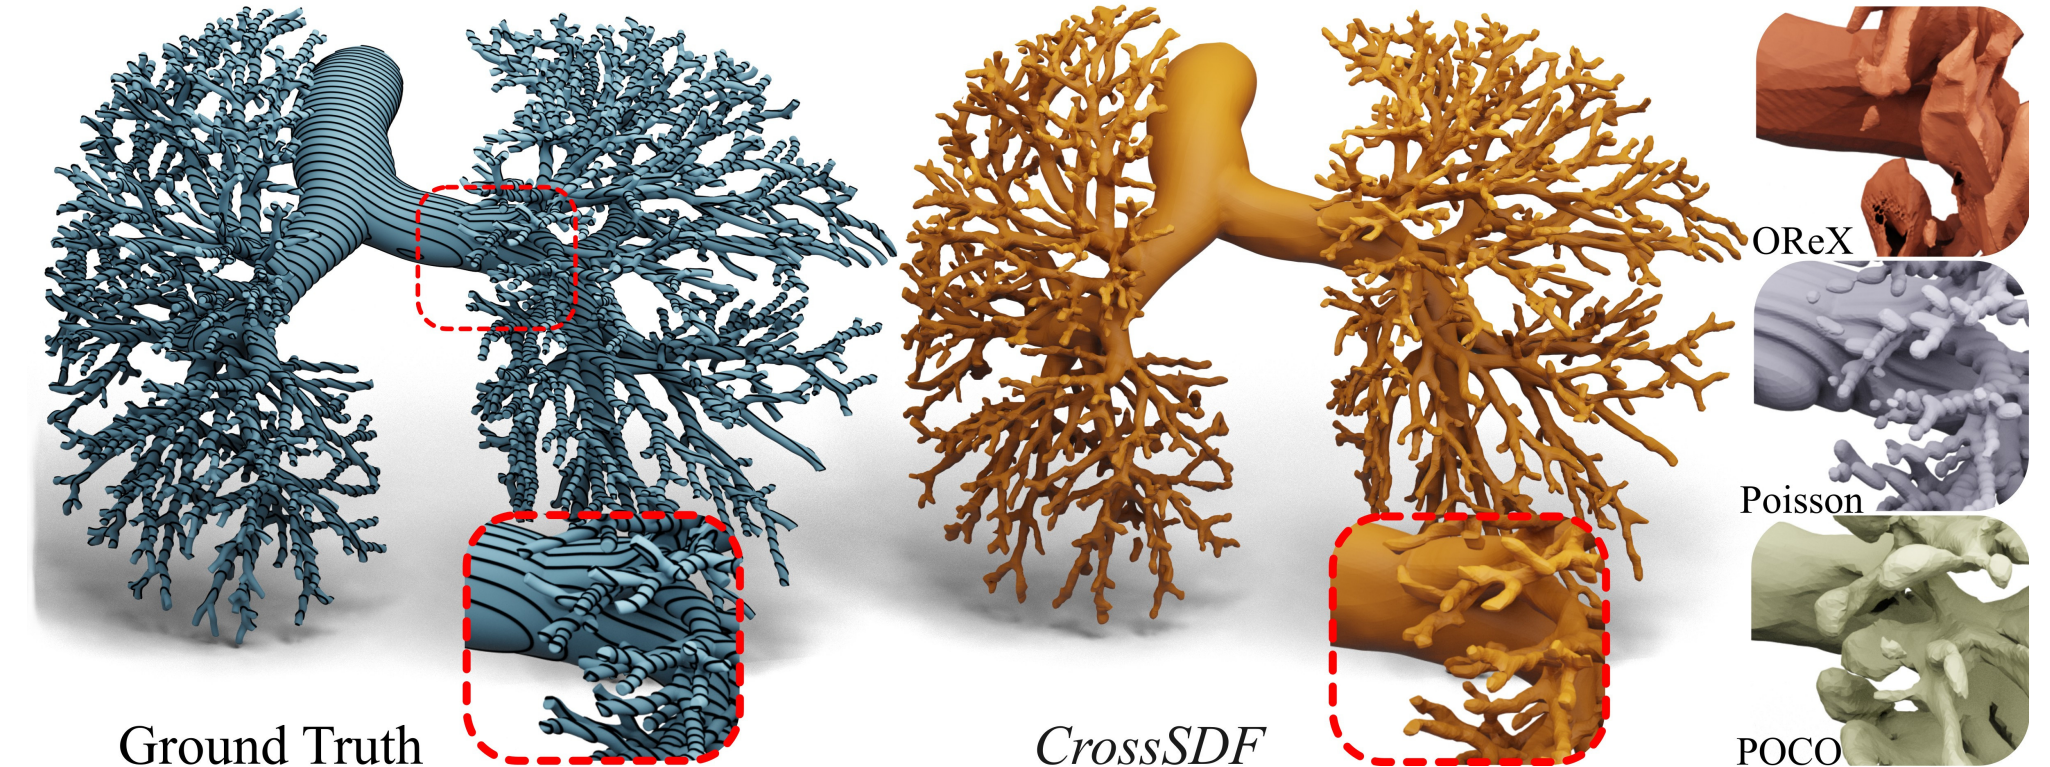
300 dpi PNG · 图注 · 源PDF
图1及引言明确指出现有OReX/Poisson/POCO在稀疏截面上产生断裂、阶梯伪影和过平滑,局部放大框用于解释薄结构重建失败。
完整图注、版本和筛选证据
最早核实视觉日期:2024-12-05;arXiv v1:2024-12-05;CVPR 2025 fixed official PDF
已打开arXiv v1(2024-12-05)第1页并比较固定会议图1,完整图区域逐像素一致(MAE=0)。后续v2/v3不改变最早匹配时间。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Oisin Mac Aodha;18397;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 218, 550, 402],PDF点、左上角原点。
Figure 1. We propose CrossSDF, a novel approach for reconstructing a 3D signed-distance field from 2D cross-sections. The input is a
set of 2D cross-sections that sample an unobserved ground-truth geometric object by planar intersection (denoted as black lines overlayed
on the ground truth Alveolis structure on the left). CrossSDF (middle) accurately reconstructs thin structures without breakages, over-
smoothing, or cross-sectional artifacts observed in competing methods (right).
DiffHuman: Probabilistic Photorealistic 3D Reconstruction of Humans
会议:CVPR 2024 · 主会论文
Figure 2 · PDF第2页 · P286
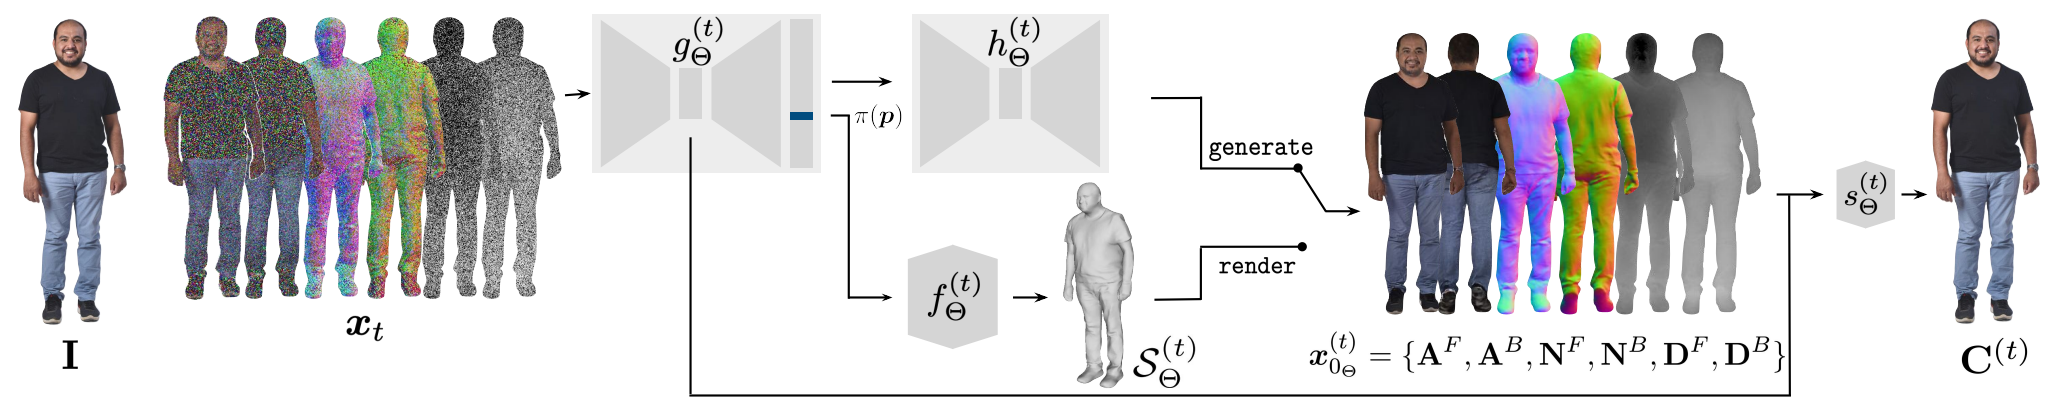
300 dpi PNG · 图注 · 源PDF
图2明确为方法总览,包含条件扩散、隐式表面渲染、加速生成器和阴影输出完整路径。
完整图注、版本和筛选证据
最早核实视觉日期:2024-03-30;arXiv v1:2024-03-30;CVPR 2024 fixed official PDF
已读正文/图注、查看固定源PDF,并核对作者单位。 已逐张查看完整源页、历史目标图与导出图;GenNBV首图历史页位置下移5点已对应;DiffHuman首图选择明确诊断失败的Fig3并保留全部列标签;图内元素完整、图外正文未混入。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Cristian Sminchisescu;24653;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[51, 62, 542, 158],PDF点、左上角原点。
Figure 2. Method overview. We use a diffusion probabilistic model [18] to predict a distribution over plausible 3D reconstructions
conditioned on a single RGB image. During training, we predict noise-dependent pixel-aligned features g (t) (x , I) given a noisy observation
Θ t
set x consisting of front/back albedo, depth and normal renders, and an RGB image I. These features condition an SDF f (t) , which is
t Θ
dependent on both x and I. f (t) and g (t) are neural networks that define an implicit surface S (t) (x , I). Then, we obtain an estimate of the
t Θ Θ Θ t
denoised observation set x(t) by rendering S (t) . We may additionally produce a shaded image C(t) by applying a pixel-wise noise-dependent
0Θ Θ
shading network s(t) . During inference, we can sample trajectories over observation sets x ∼ p (x |I) by computing and rendering
Θ 0:T Θ 0:T
S (t) (x , I) in each denoising step. Our final 3D samples S ∼ p (S |I) are obtained as the final reconstruction S = S (1) (x , I). To mitigate
Θ t Θ Θ 1
the computational cost of rendering an implicit surface in every step, we train a “generator” network h(t) that imitates rendering by directly
Θ
mapping g (t) (x , I) to x(t) . During inference, we denoise using h(t) and only explicitly compute the 3D reconstruction in the last step.
Θ t 0Θ Θ
DiffHuman: Probabilistic Photorealistic 3D Reconstruction of Humans
会议:CVPR 2024 · 主会论文
Figure 3 · PDF第4页 · P285
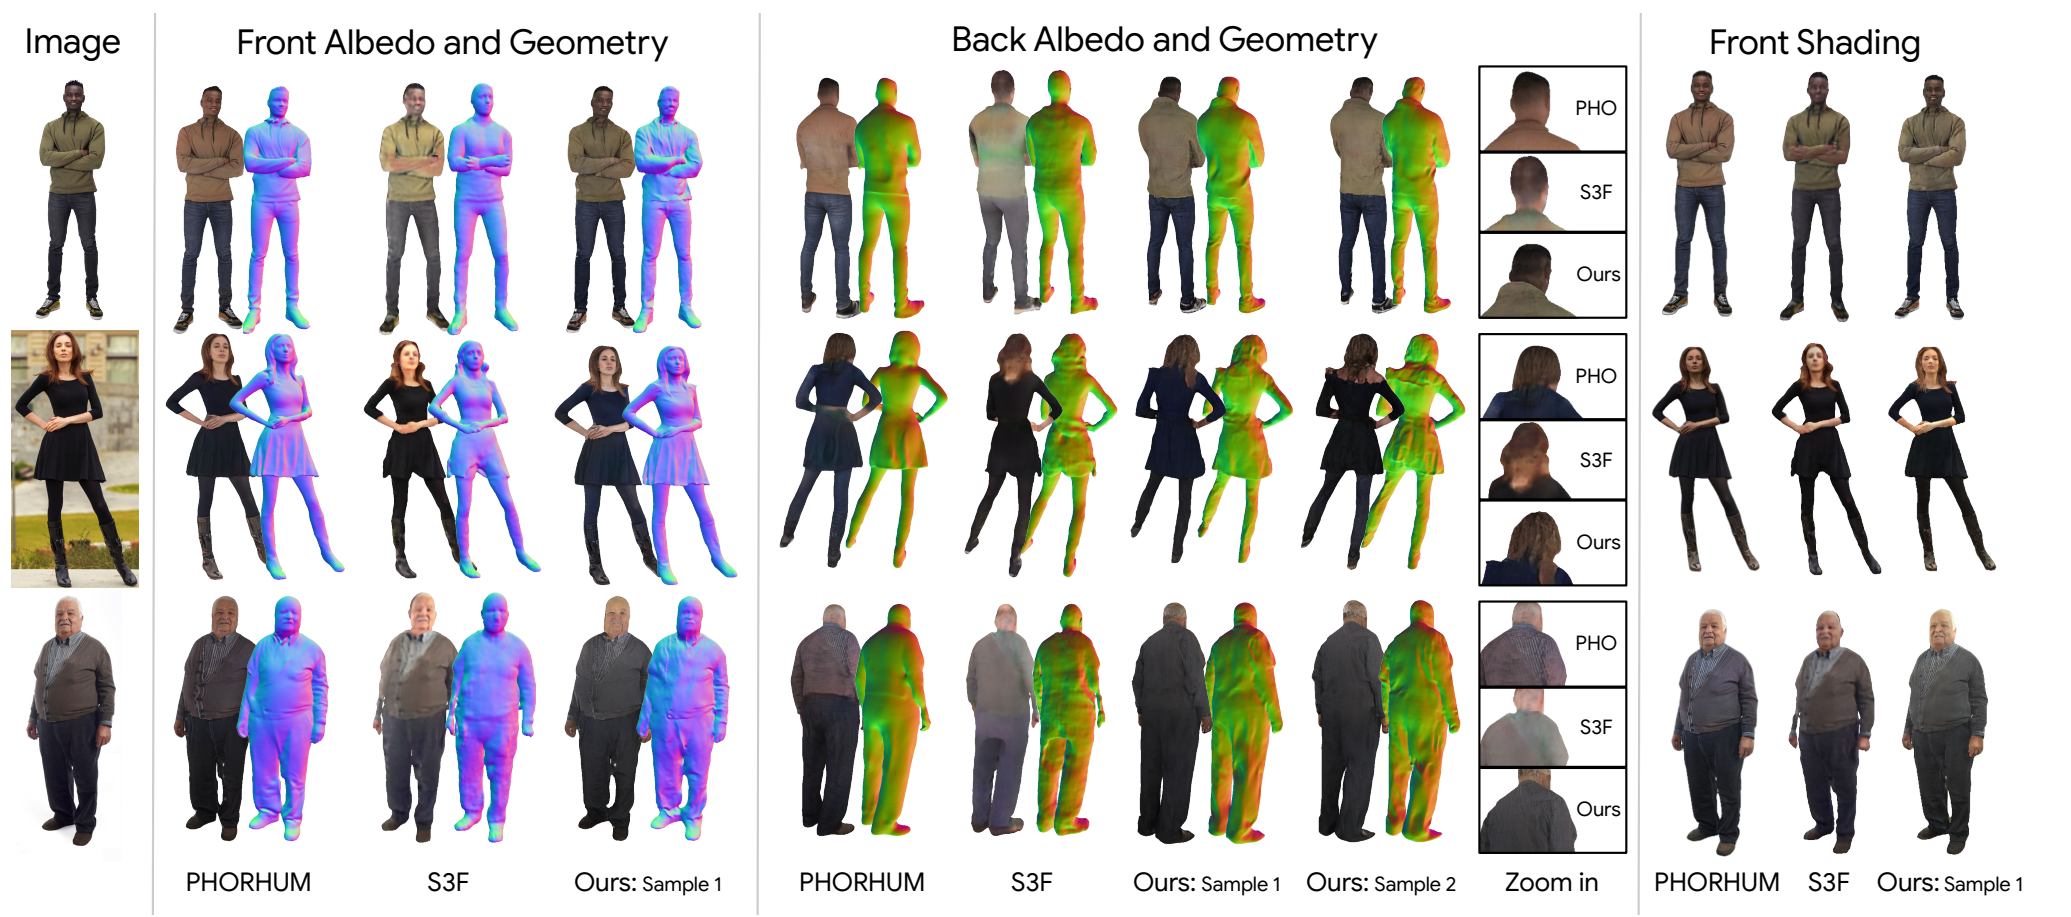
300 dpi PNG · 图注 · 源PDF
图3图注明确诊断既有确定性方法背面过平、颜色模糊以及把正面纹理错误贴到背面的失败;对应实验讨论不可见区域的歧义。登记为既有方法失败案例,不把图1普通成功输出计M。
完整图注、版本和筛选证据
最早核实视觉日期:2024-03-30;arXiv v1:2024-03-30;CVPR 2024 fixed official PDF
已读正文/图注、查看固定源PDF,并核对作者单位。 已逐张查看完整源页、历史目标图与导出图;GenNBV首图历史页位置下移5点已对应;DiffHuman首图选择明确诊断失败的Fig3并保留全部列标签;图内元素完整、图外正文未混入。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Cristian Sminchisescu;24653;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[50, 56, 547, 276],PDF点、左上角原点。
Figure 3. Qualitative comparison against deterministic monocular 3D human reconstruction methods [5, 10] that predict geometry,
surface albedo and shaded colour. PHORHUM [5] (retrained on our dataset) outputs good front predictions, but exhibits over-smooth, flat
geometry and blurry colours on the back. S3F [10] yields more detailed geometry, but colours are still often blurry. Moreover, both these
methods occasionally paste the front colour predictions onto the back incorrectly (see row 3). Our method outputs multiple diverse samples,
with a greater level of geometric detail and colour sharpness in uncertain regions, that are consistent with the input image after shading.
GenNBV: Generalizable Next-Best-View Policy for Active 3D Reconstruction
会议:CVPR 2024 · 主会论文
Figure 2 · PDF第3页 · P282
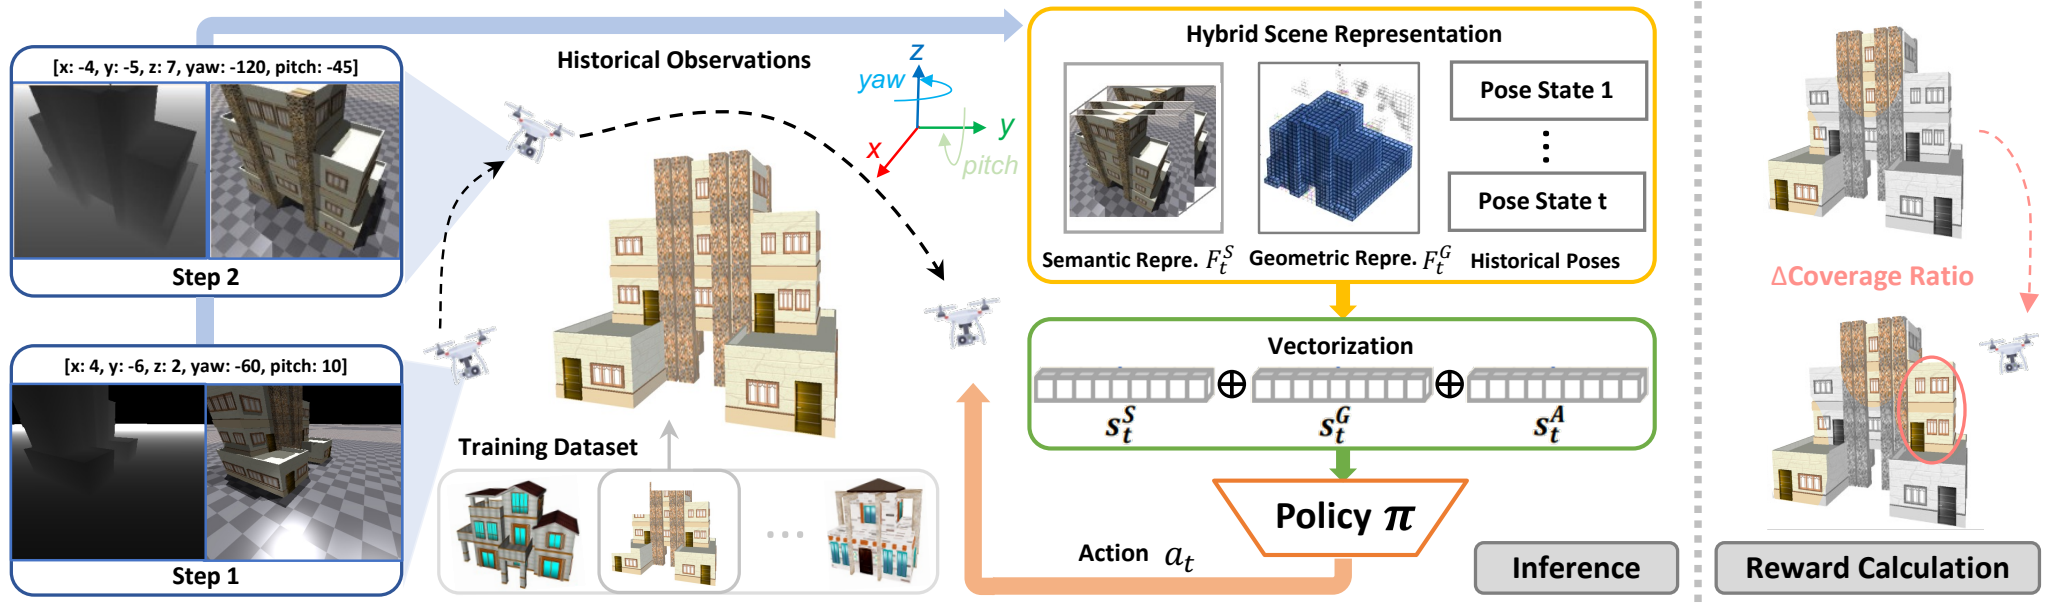
300 dpi PNG · 图注 · 源PDF
图2及第3节明确为整体GenNBV主动重建策略,展示历史观测、混合表示、策略、动作、奖励闭环。
完整图注、版本和筛选证据
最早核实视觉日期:2024-02-25;arXiv v1:2024-02-25;CVPR 2024 fixed official PDF
已读正文/图注、查看固定源PDF,并核对作者单位。 已逐张查看完整源页、历史目标图与导出图;GenNBV首图历史页位置下移5点已对应;DiffHuman首图选择明确诊断失败的Fig3并保留全部列标签;图内元素完整、图外正文未混入。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jiangmiao Pang;26222;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[50, 74, 542, 219],PDF点、左上角原点。
Figure 2. Overview of our proposed framework GenNBV. Our end-to-end policy takes the historical multi-source observations as input,
transforms them into a more informative scene representation, and produces the next viewpoint position. A reward signal will be returned
at training time to optimize the end-to-end policy for maximizing the expected cumulative reward in one episode. Specifically, the signal
is the increased coverage ratio after collecting a new viewpoint.
GenNBV: Generalizable Next-Best-View Policy for Active 3D Reconstruction
会议:CVPR 2024 · 主会论文
Figure 1 · PDF第1页 · P281
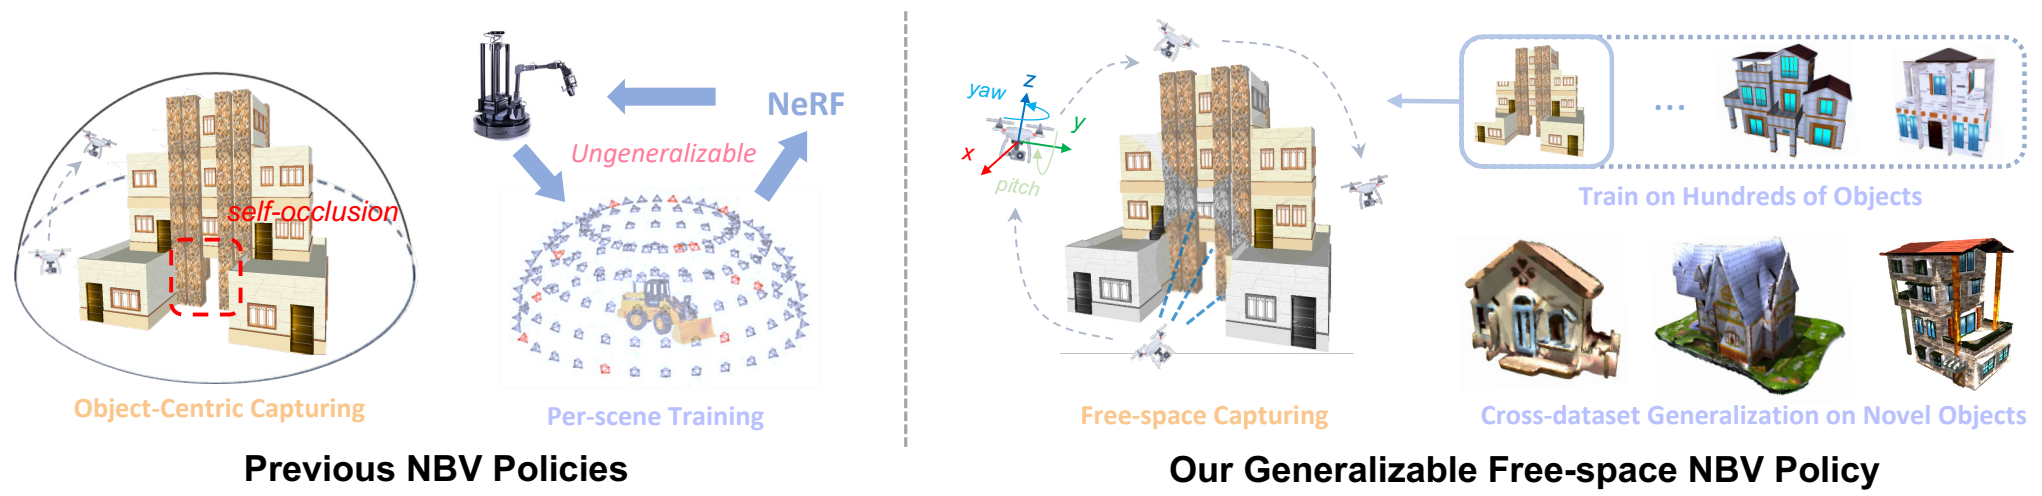
300 dpi PNG · 图注 · 源PDF
图1及引言指出物体中心采集的自遮挡与逐场景训练的泛化限制,概念对比自由空间采集。
完整图注、版本和筛选证据
最早核实视觉日期:2024-02-25;arXiv v1:2024-02-25;CVPR 2024 fixed official PDF
已读正文/图注、查看固定源PDF,并核对作者单位。 已逐张查看完整源页、历史目标图与导出图;GenNBV首图历史页位置下移5点已对应;DiffHuman首图选择明确诊断失败的Fig3并保留全部列标签;图内元素完整、图外正文未混入。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jiangmiao Pang;26222;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[49, 201, 539, 320],PDF点、左上角原点。
Figure 1. To determine the best view for 3D reconstruction, previous methods only chose from hand-crafted action space or based on
object-centric capturing, lacking the ability to generalize to unforeseen scenes (Left). With our end-to-end trained, generalized free-space
policy, it can generalize to unseen objects, enabling the captured drone to image from any viewpoint (Right).
Generative Multiview Relighting for 3D Reconstruction under Extreme Illumination Variation
会议:CVPR 2025 · 主会论文
Figure 2 · PDF第4页 · P24
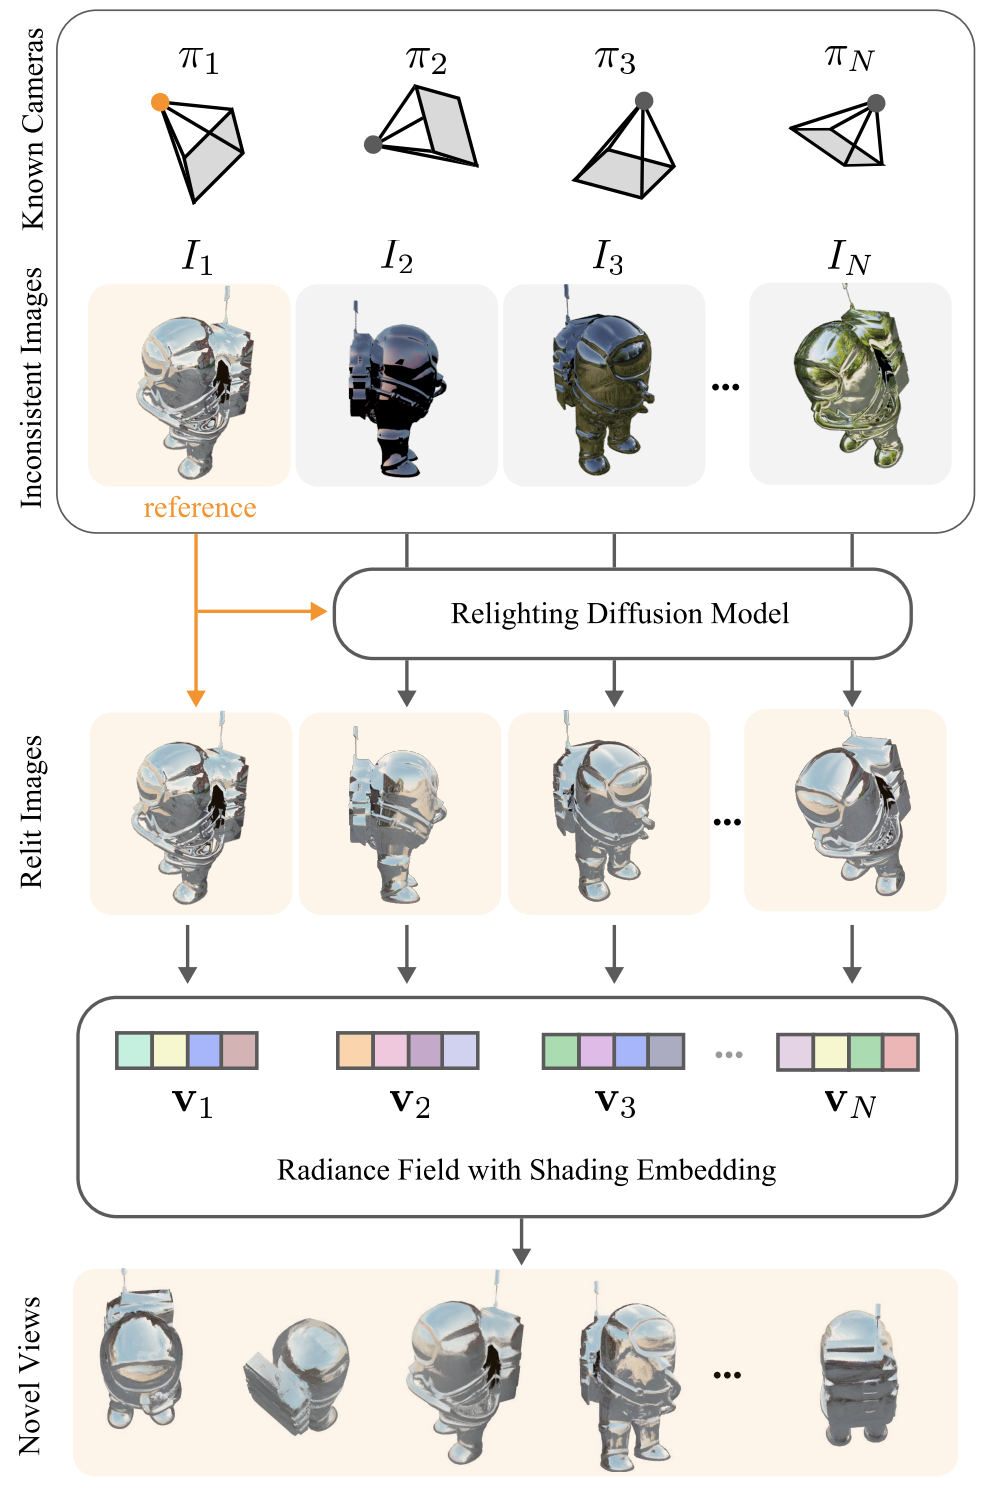
300 dpi PNG · 图注 · 源PDF
图2 Method overview及第3节展示已知相机和不一致光照输入、联合重光照、带shading embedding的辐射场与新视角输出的完整流程。
完整图注、版本和筛选证据
最早核实视觉日期:2024-12-19;arXiv v1:2024-12-19;CVPR 2025 fixed official PDF
会议图区与arXiv v1按同坐标裁剪并比较;正文和图注参考文献编号变化不被复制到图内。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Jia-Bin Huang;38451;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[58, 75, 294, 432],PDF点、左上角原点。
Figure 2. Method overview. We first apply a relighting diffusion
modelthatconvertsN imagesI ,...,I withknowncameraposes
1 N
π , ..., π , captured under extremely different illuminations, to a
1 N
set of images with the same poses, but rendered under the illumi-
nation of the reference image I (highlighted in orange). We then
1
optimize a neural radiance field to obtain a consistent 3D repre-
sentation with a novel per-image shading embedding, which can
be used to render new views of the scene from unobserved poses.
Generative Multiview Relighting for 3D Reconstruction under Extreme Illumination Variation
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第1页 · P23
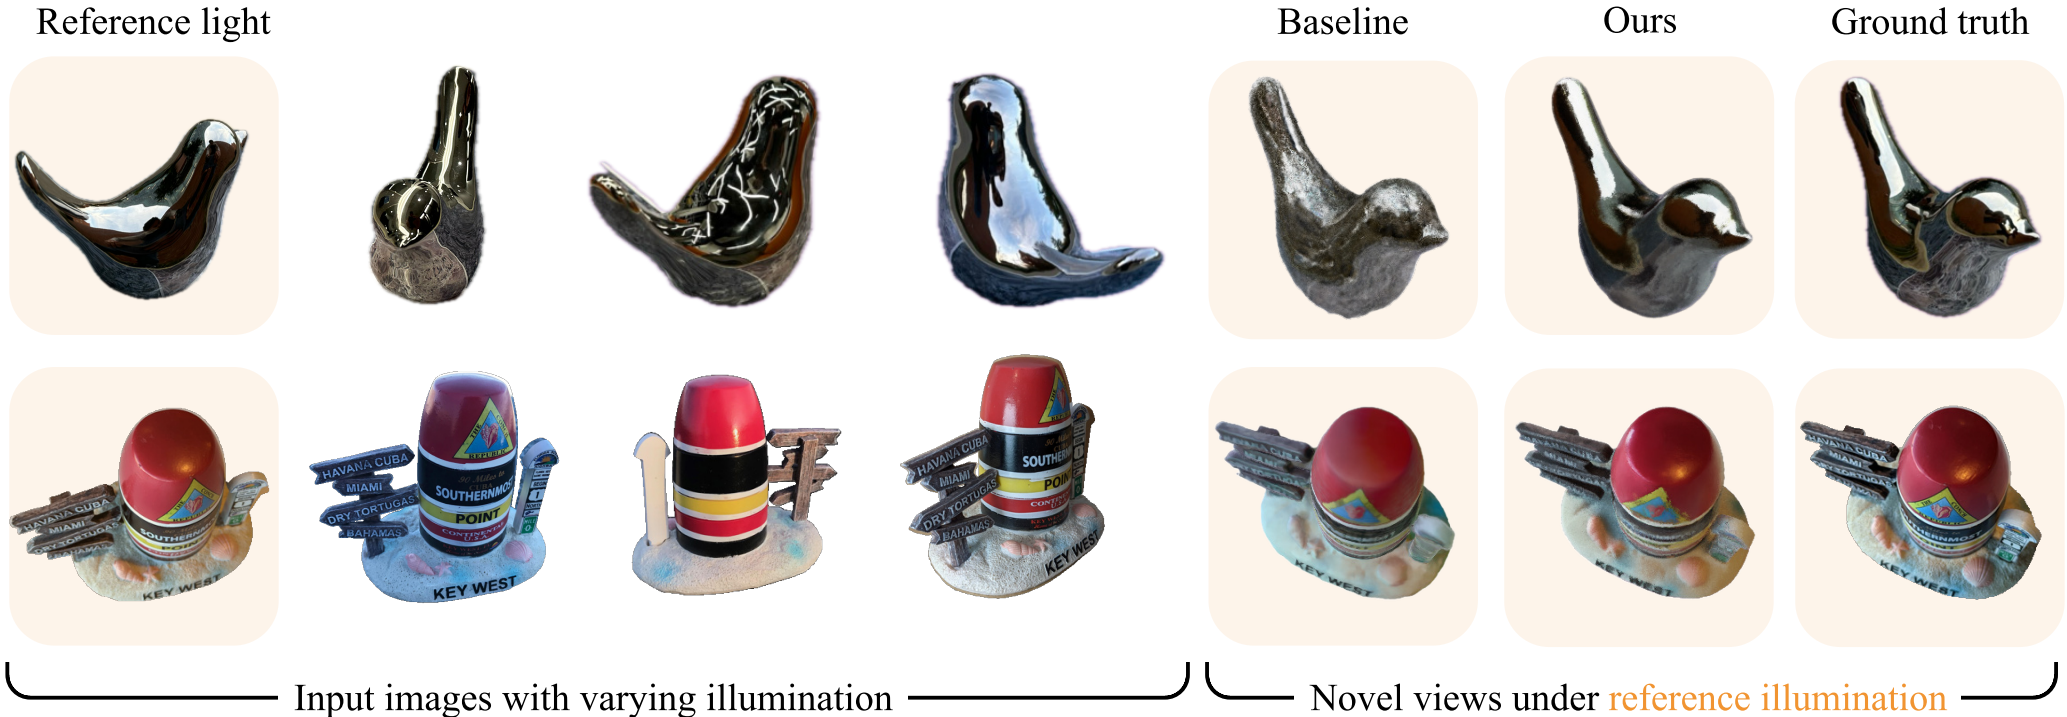
300 dpi PNG · 图注 · 源PDF
引言第2页以图1说明跨环境拍摄造成的光照不一致,并解释既有方法把镜面反射错误归因于外观变化;图注点明两种基线无法恢复高光,按特定失败案例收录。
完整图注、版本和筛选证据
最早核实视觉日期:2024-12-19;arXiv v1:2024-12-19;CVPR 2025 fixed official PDF
会议图区与arXiv v1按同坐标裁剪并比较;正文和图注参考文献编号变化不被复制到图内。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Jia-Bin Huang;38451;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[58, 273, 554, 445],PDF点、左上角原点。
Figure 1. 3D reconstruction under extreme illumination variation. We propose a method for 3D reconstruction from a set of images
captured under strongly varying illumination. Our method recovers high-fidelity appearance details including specular highlights that prior
state-of-the-artapproachescannotrecover(topbaseline: NeRF-Casting[47]withappearanceembeddings,bottombaseline: NeROIC[25]).
NeRSP: Neural 3D Reconstruction for Reflective Objects with Sparse Polarized Images
会议:CVPR 2024 · 主会论文
Figure 4 · PDF第5页 · P284
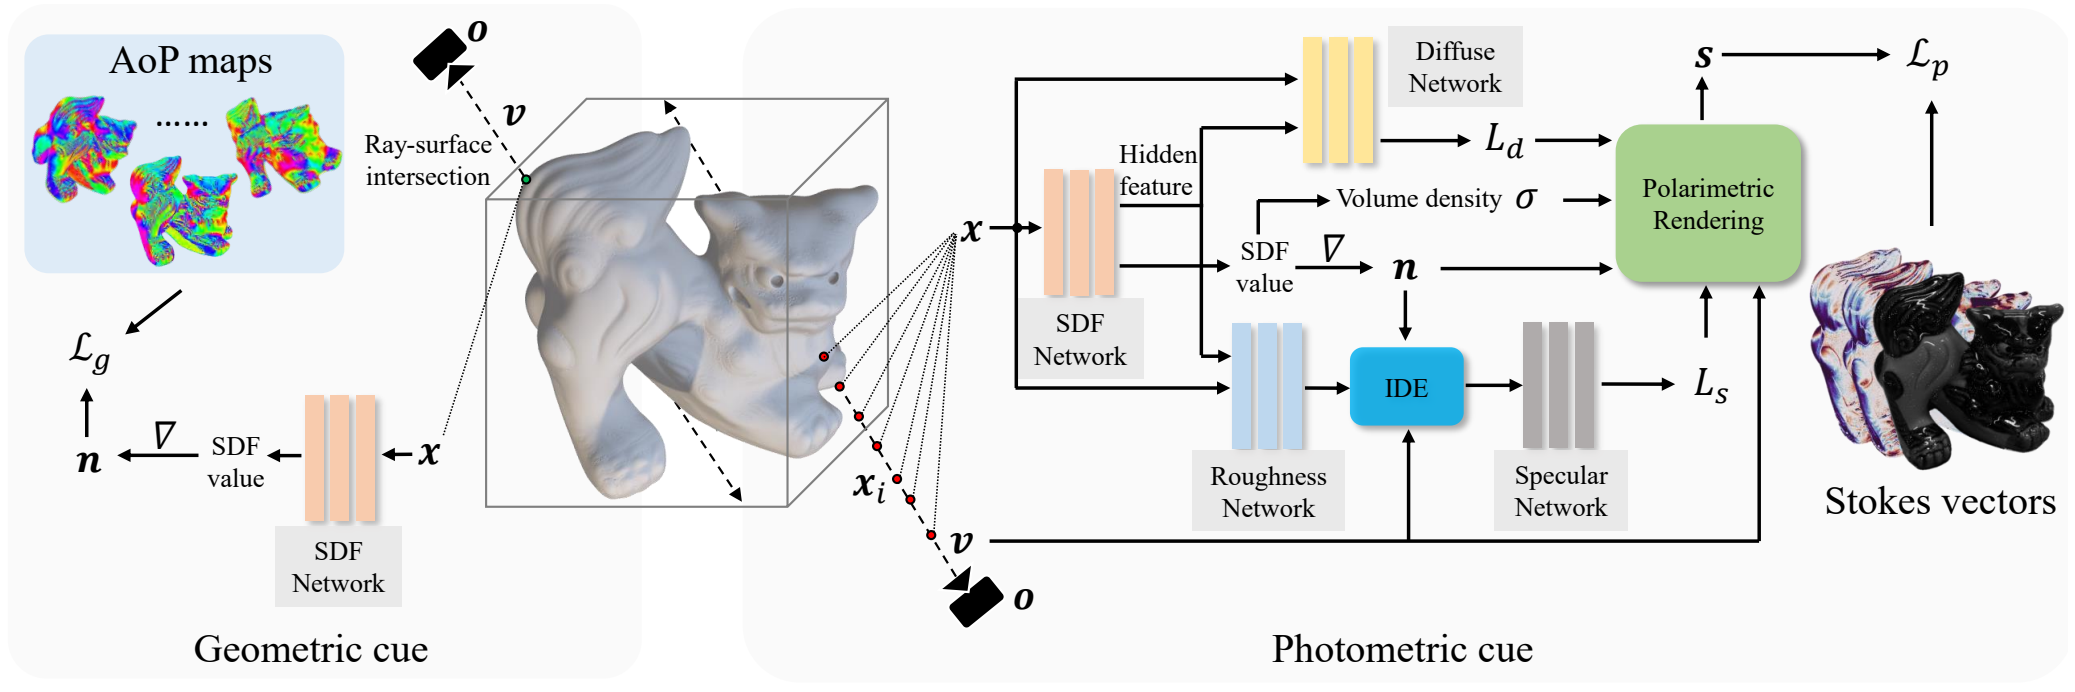
300 dpi PNG · 图注 · 源PDF
图4及4.2节展示完整NeRSP几何与光度分支、隐式表面和偏振渲染及损失。
完整图注、版本和筛选证据
最早核实视觉日期:2024-06-11;arXiv v1:2024-06-11;CVPR 2024 fixed official PDF
已读正文/图注、查看固定源PDF,并核对作者单位。 已逐张查看完整源页、历史目标图与导出图;GenNBV首图历史页位置下移5点已对应;DiffHuman首图选择明确诊断失败的Fig3并保留全部列标签;图内元素完整、图外正文未混入。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Zhanyu Ma;11953;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[49, 71, 547, 237],PDF点、左上角原点。
Figure 4. Pipeline of our NeRSP.
NeRSP: Neural 3D Reconstruction for Reflective Objects with Sparse Polarized Images
会议:CVPR 2024 · 主会论文
Figure 3 · PDF第4页 · P283
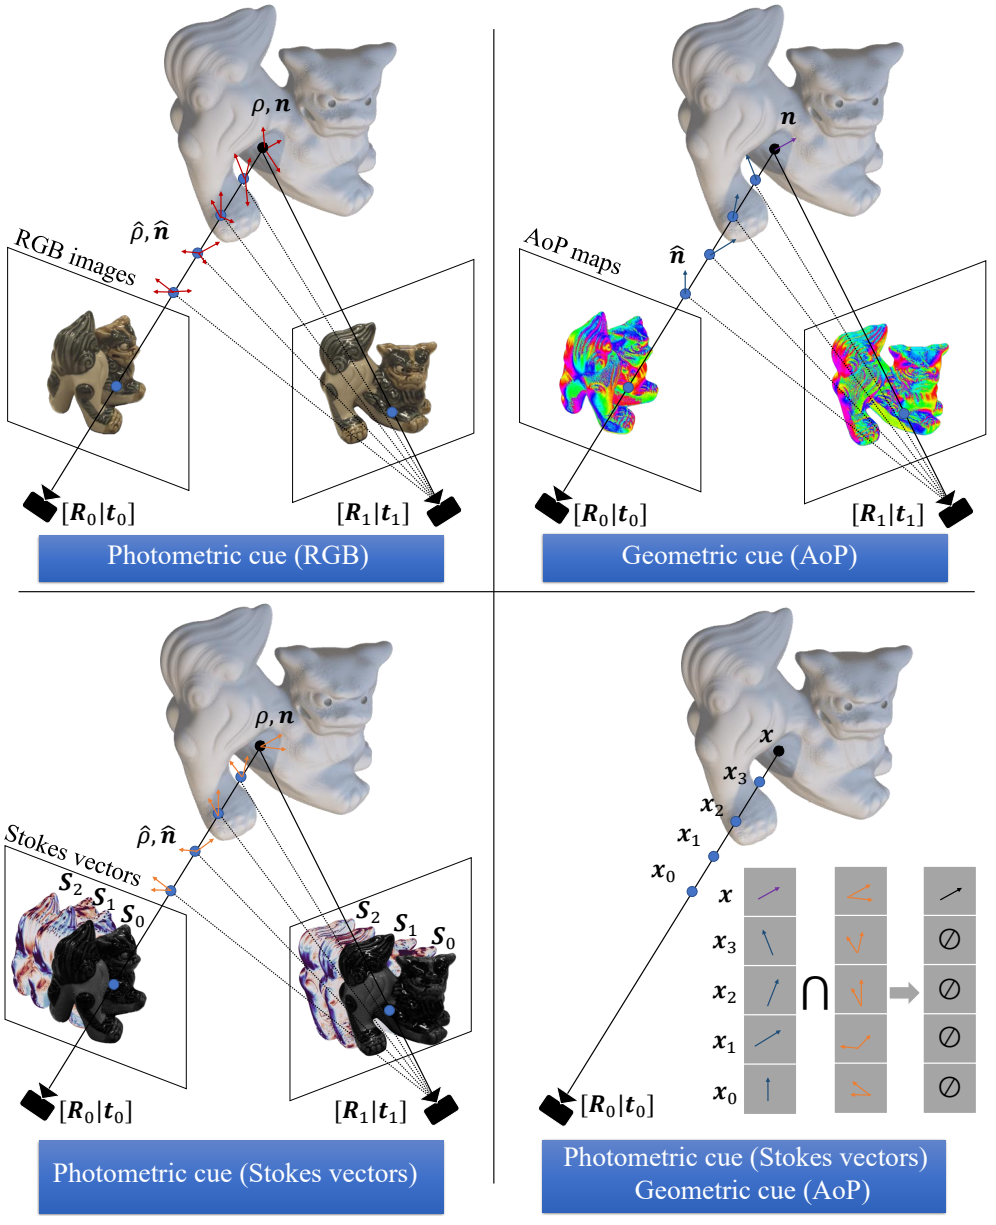
300 dpi PNG · 图注 · 源PDF
图3及4.1节专门解释稀疏视角下单独光度/几何线索的三维位置歧义,并用概念对比说明联合线索消歧动机;图1是普通结果展示,图2是输入数据说明。
完整图注、版本和筛选证据
最早核实视觉日期:2024-06-11;arXiv v1:2024-06-11;CVPR 2024 fixed official PDF
已读正文/图注、查看固定源PDF,并核对作者单位。 已逐张查看完整源页、历史目标图与导出图;GenNBV首图历史页位置下移5点已对应;DiffHuman首图选择明确诊断失败的Fig3并保留全部列标签;图内元素完整、图外正文未混入。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Zhanyu Ma;11953;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[308, 72, 547, 366],PDF点、左上角原点。
Figure 3. Ambiguity of determining 3D postions under sparse
views with geometric and photometric cues.
Parametric Point Cloud Completion for Polygonal Surface Reconstruction
会议:CVPR 2025 · 主会论文
Figure 2 · PDF第3页 · P236
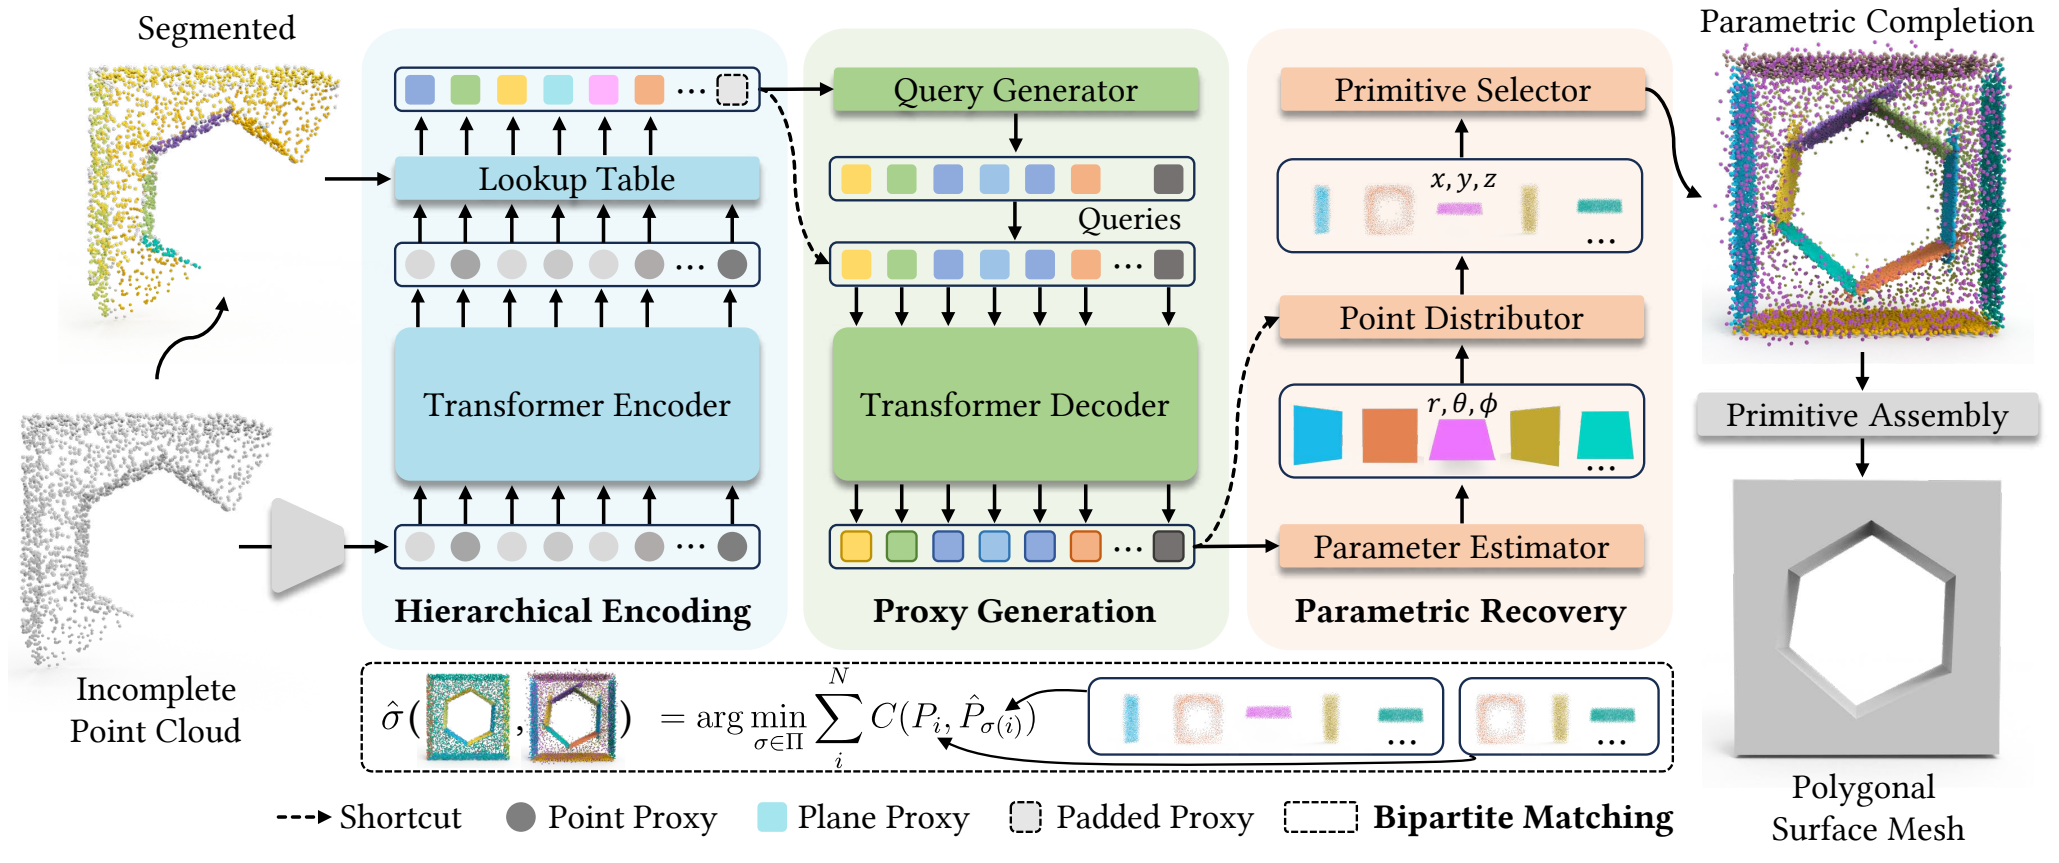
300 dpi PNG · 图注 · 源PDF
图2完整呈现PaCo编码、代理点生成、参数恢复及基元组装到补全点云与表面的计算路径。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-11;arXiv v1:2025-03-11;CVPR 2025 fixed official PDF
已查看唯一v1(2025-03-11)与会议版整体框架,布局、配色和标签一致;轻微栅格差异。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Xiao Xiang Zhu;51863;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[59, 71, 553, 278],PDF点、左上角原点。
Figure 2. Architecture of PaCo. Starting from an incomplete point cloud, we hierarchically encode the points into plane proxies with a
lookup table from segmentation. These proxies inform the proxy generator in producing a set of proxy proposals. The generated proxies
are then passed to the parameter estimator and the point distributor for primitive estimation. Finally, the primitive selector identifies a
subset of primitives to form the parametric completion, with selection optimized via bipartite matching. The resulting primitives enable
direct assembly for polygonal surface reconstruction. Points are colored according to their planar primitives.
Parametric Point Cloud Completion for Polygonal Surface Reconstruction
会议:CVPR 2025 · 主会论文
Figure 1 · PDF第1页 · P235
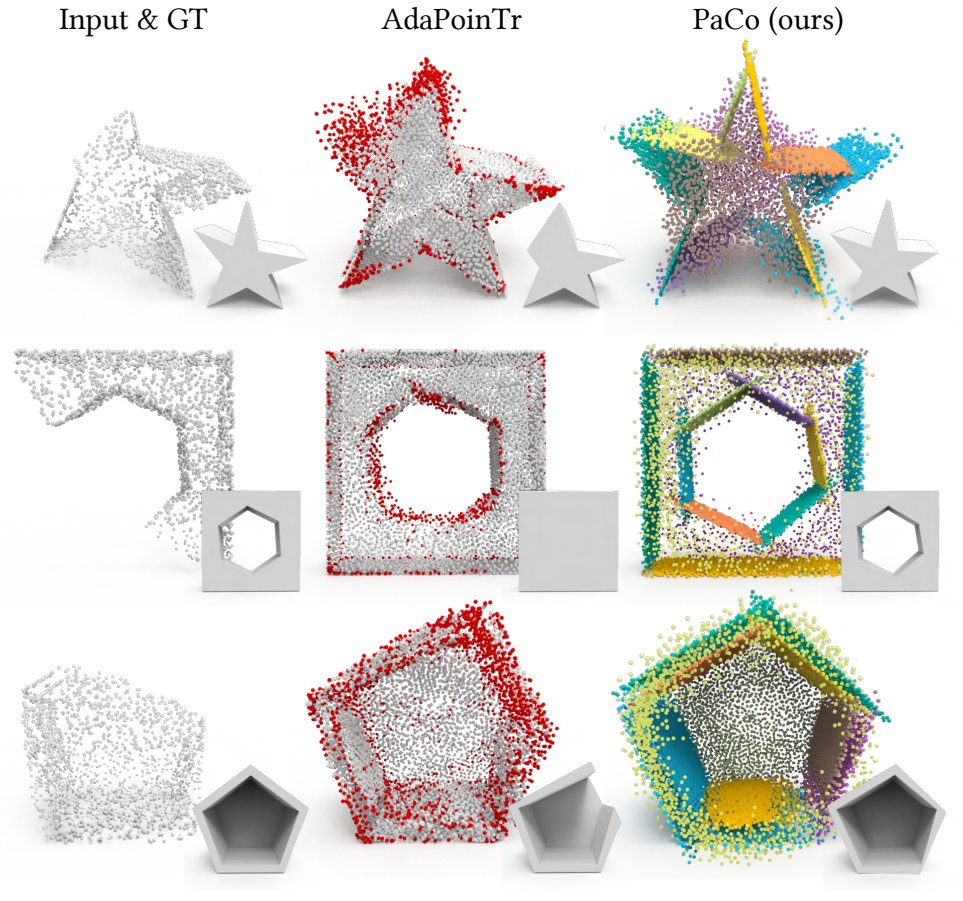
300 dpi PNG · 图注 · 源PDF
图1及引言标出既有补全方法产生的非平面点,说明点云补全不能直接保证可恢复多边形表面的局限。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-11;arXiv v1:2025-03-11;CVPR 2025 fixed official PDF
已查看唯一v1(2025-03-11)与会议版目标图,元素、构图和标签一致;轻微栅格压缩差异。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Xiao Xiang Zhu;51863;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[322, 203, 553, 419],PDF点、左上角原点。
Figure 1. Unlike conventional point cloud completion that aims
to recover individual points (middle, non-planar points shown in
red), parametric completion recovers primitive parameters along
with corresponding inlier points. PaCo recovers planar structures
(right, each color denoting a planar primitive), directly enabling
high-quality polygonal surface reconstruction.
PlanarSplatting: Accurate Planar Surface Reconstruction in 3 Minutes
会议:CVPR 2025 · 主会论文
Figure 3 · PDF第4页 · P220
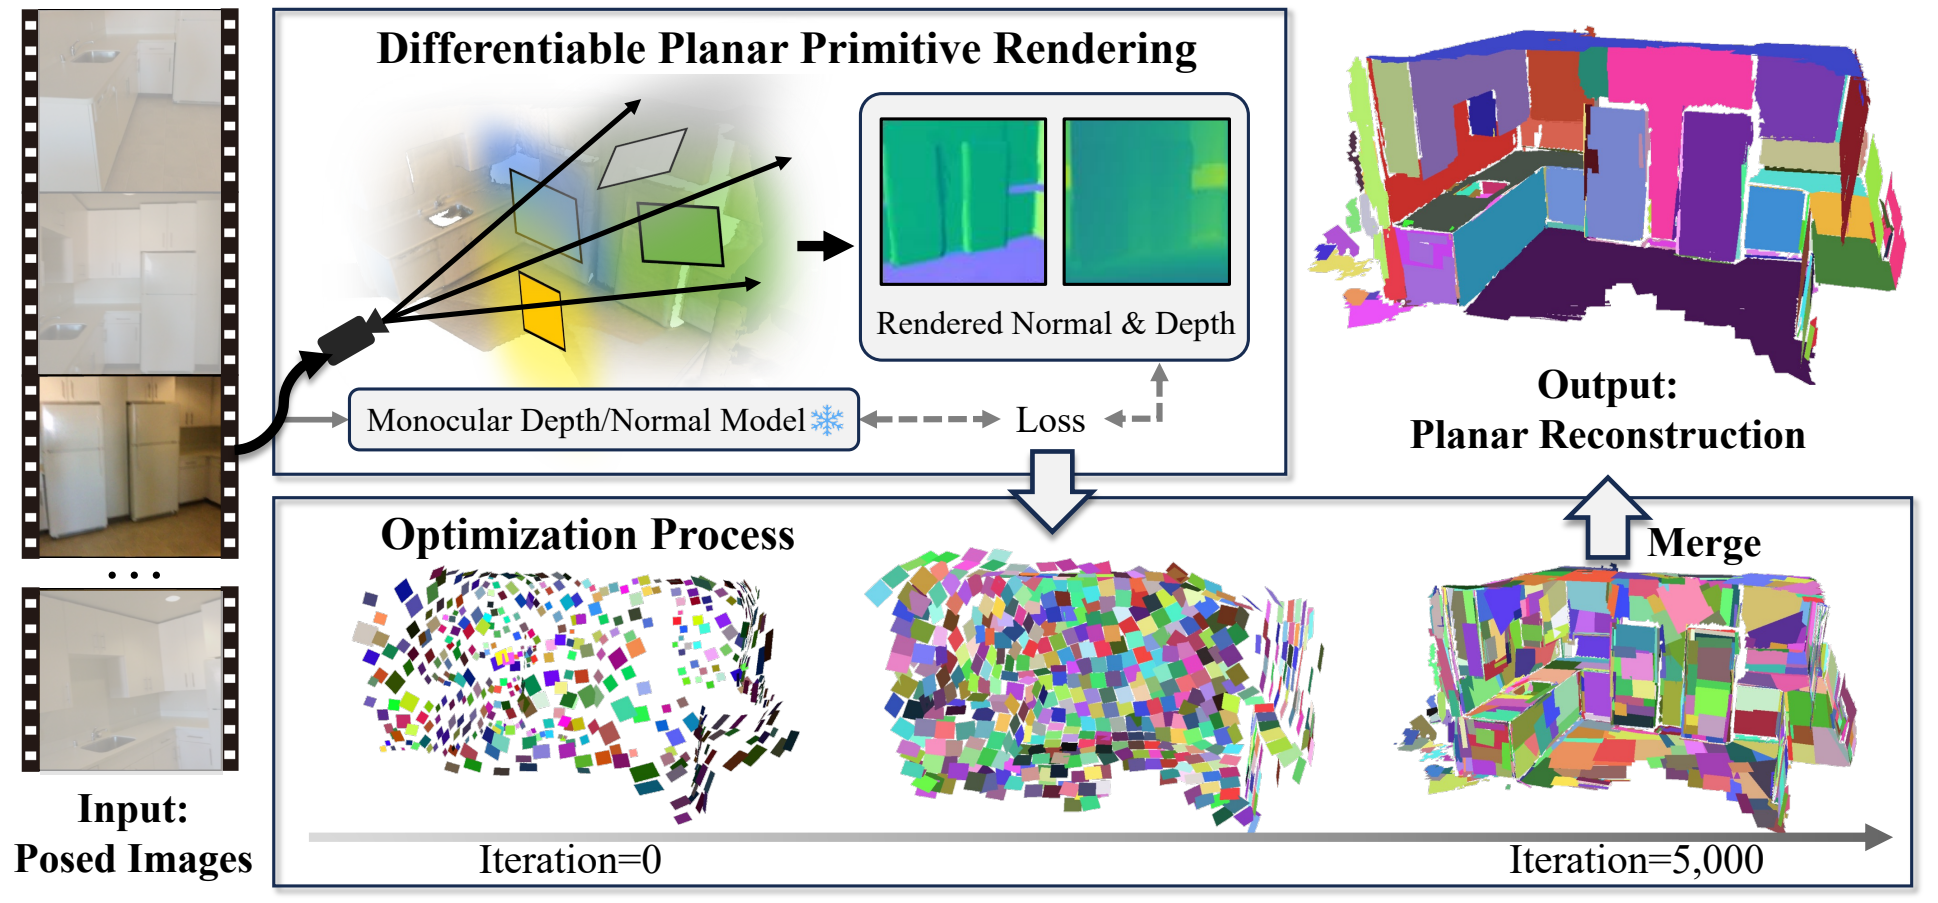
300 dpi PNG · 图注 · 源PDF
图3给出从多视角图像、可微平面渲染、单目监督、优化迭代到平面合并重建的整体流程。
完整图注、版本和筛选证据
最早核实视觉日期:2024-12-04;arXiv v1:2024-12-04;CVPR 2025 fixed official PDF
已打开仅有的arXiv v1(2024-12-04)第4页。图3经统一比例缩放后,所有模块、箭头、渲染图与输入照片一致;该页23个共享嵌入图像解码像素相同,归一化裁图差异仅边缘栅格化,未发现场景替换。最早匹配v1。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yujun Shen;15694;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[75, 86, 540, 302.5],PDF点、左上角原点。
Figure 3. Illustration of our proposed PlanarSplatting. Given a set of posed multi-view images of indoor scenes, our method renders
depth and normal maps from 3D plane primitives. Then, with the supervision of monocular cues, these 3D plane primitives are gradually
optimized to recover the scene geometry and finally merged to get the planar reconstruction result.
PlanarSplatting: Accurate Planar Surface Reconstruction in 3 Minutes
会议:CVPR 2025 · 主会论文
Figure 5 · PDF第4页 · P219
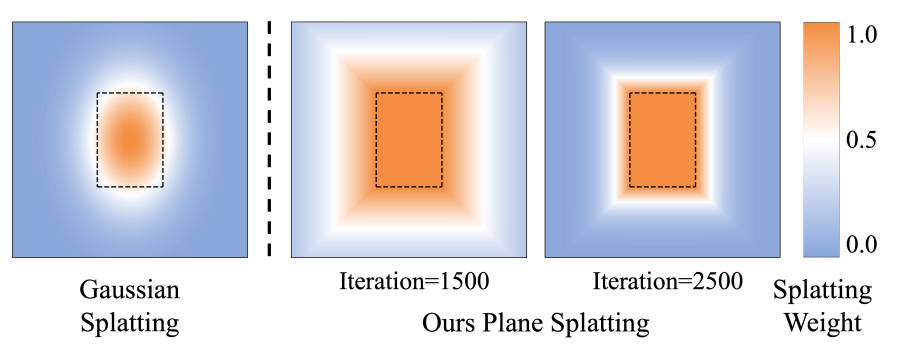
300 dpi PNG · 图注 · 源PDF
图5和第3.2节以高斯权重无法逼近矩形边界的概念对比说明已有表示的局限;图1/2为普通重建/渲染结果,因此选这张首个明确问题对比图。
完整图注、版本和筛选证据
最早核实视觉日期:2024-12-04;arXiv v1:2024-12-04;CVPR 2025 fixed official PDF
已打开仅有的arXiv v1(2024-12-04)第4页,历史图4对应会议图5。高斯/平面权重图、迭代标签、颜色图例均一致,只随版式缩放并改图号。保存完整历史图区域。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yujun Shen;15694;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[325, 350, 543, 435.5],PDF点、左上角原点。
Figure 5. Illustration of the proposed plane splatting function.
Naive Gaussian Splatting can not effectively approximate the
boundary of our rectangular plane primitive (shown in black
dashed border). In contrast, our proposed plane splatting function
can approximate the boundary of the rectangle as the number of
iterations increases, allowing our 3D planar primitives to better fit
the surface of the scene.
Pow3R: Empowering Unconstrained 3D Reconstruction with Camera and Scene Priors
会议:CVPR 2025 · 主会论文
Figure 2 · PDF第3页 · P192
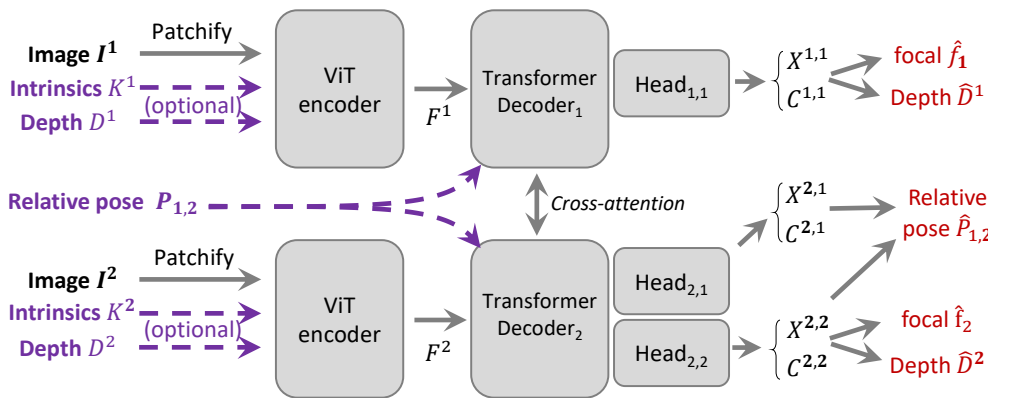
300 dpi PNG · 图注 · 源PDF
第3.1节明确图2为overall architecture,包含双图编码、交叉解码、点图输出及相机/场景先验的完整路径。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-21;arXiv v1:2025-03-21;CVPR 2025 fixed official PDF
已对照固定会议版本与arXiv v1,完整布局、标签、元素与连线匹配;v1为目前最早可核实的该视觉版本。已在PDF首页核对作者及单位。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jerome Revaud;13410;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 70, 300, 166],PDF点、左上角原点。
Figure 2. Overview of the model architecture. Following
DUSt3R [75], images are encoded then decoded with a ViT back-
bone into pointmaps, from which focals, depthmaps and relative
pose can be extracted. Pow3R introduces optional inputs to guide
the regression with prior knowledge about the camera intrinsics
and depth (fed into the encoder) and the pose (into the decoder).
Pow3R: Empowering Unconstrained 3D Reconstruction with Camera and Scene Priors
会议:CVPR 2025 · 主会论文
Figure 4 · PDF第5页 · P191
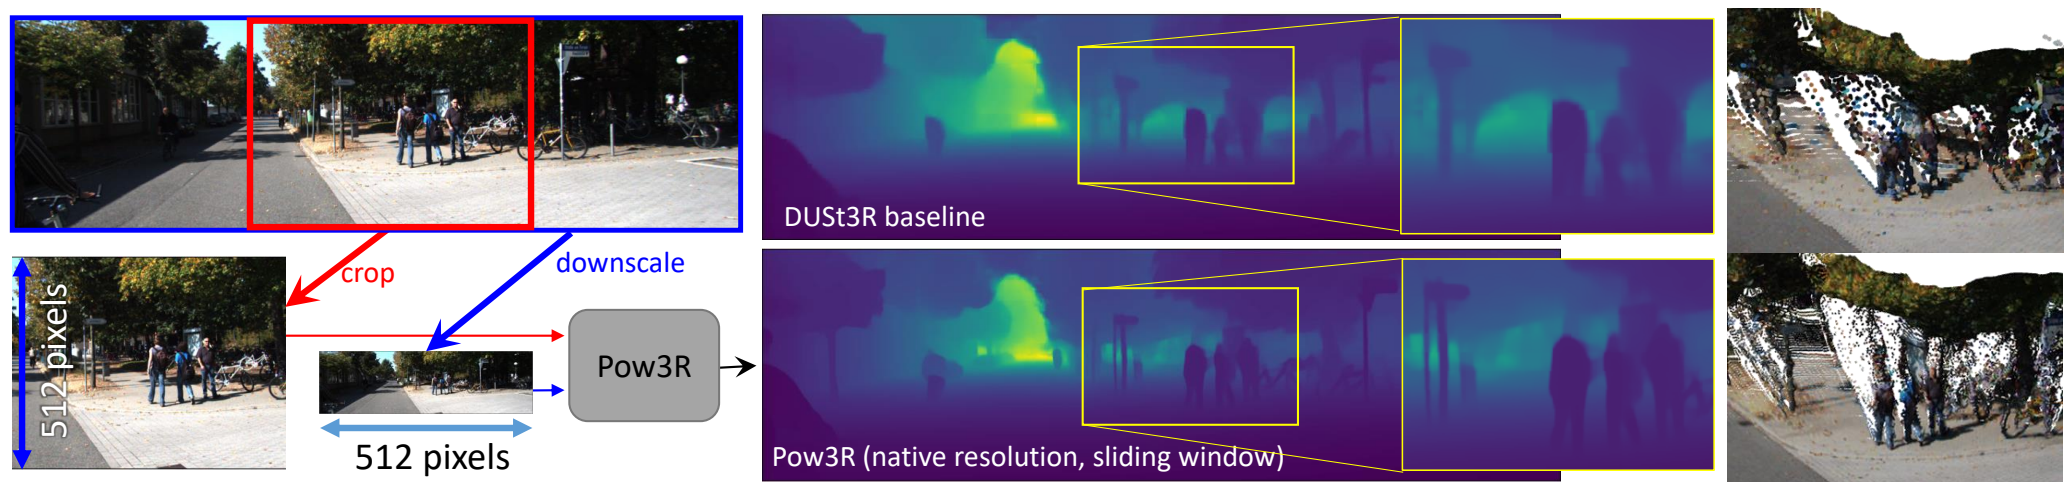
300 dpi PNG · 图注 · 源PDF
图4与第3.3节解释中心主点和固定训练分辨率导致降采样模糊的限制,比较裁块与缩放路径;图1仅是整体重建结果比较。
完整图注、版本和筛选证据
最早核实视觉日期:2025-03-21;arXiv v1:2025-03-21;CVPR 2025 fixed official PDF
已对照固定会议版本与arXiv v1,完整布局、标签、元素与连线匹配;v1为目前最早可核实的该视觉版本。已在PDF首页核对作者及单位。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jerome Revaud;13410;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 70, 555, 186],PDF点、左上角原点。
Figure 4. Native resolution example. Methods like DUSt3R require centered principal point and would thus downscale the image to its
training resolution, leading to blurry prediction (top). With camera intrinsics input, we can process any crop in the image leading to native
resolution prediction (bottom row), for example by dividing the image into 4 crops, that are independently process as the first input image,
while the second input image of the network is set to the downscaled image.
Beyond Prompt Degradation: Prototype-guided Dual-pool Prompting for Incremental Object Detection
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第3页 · P244
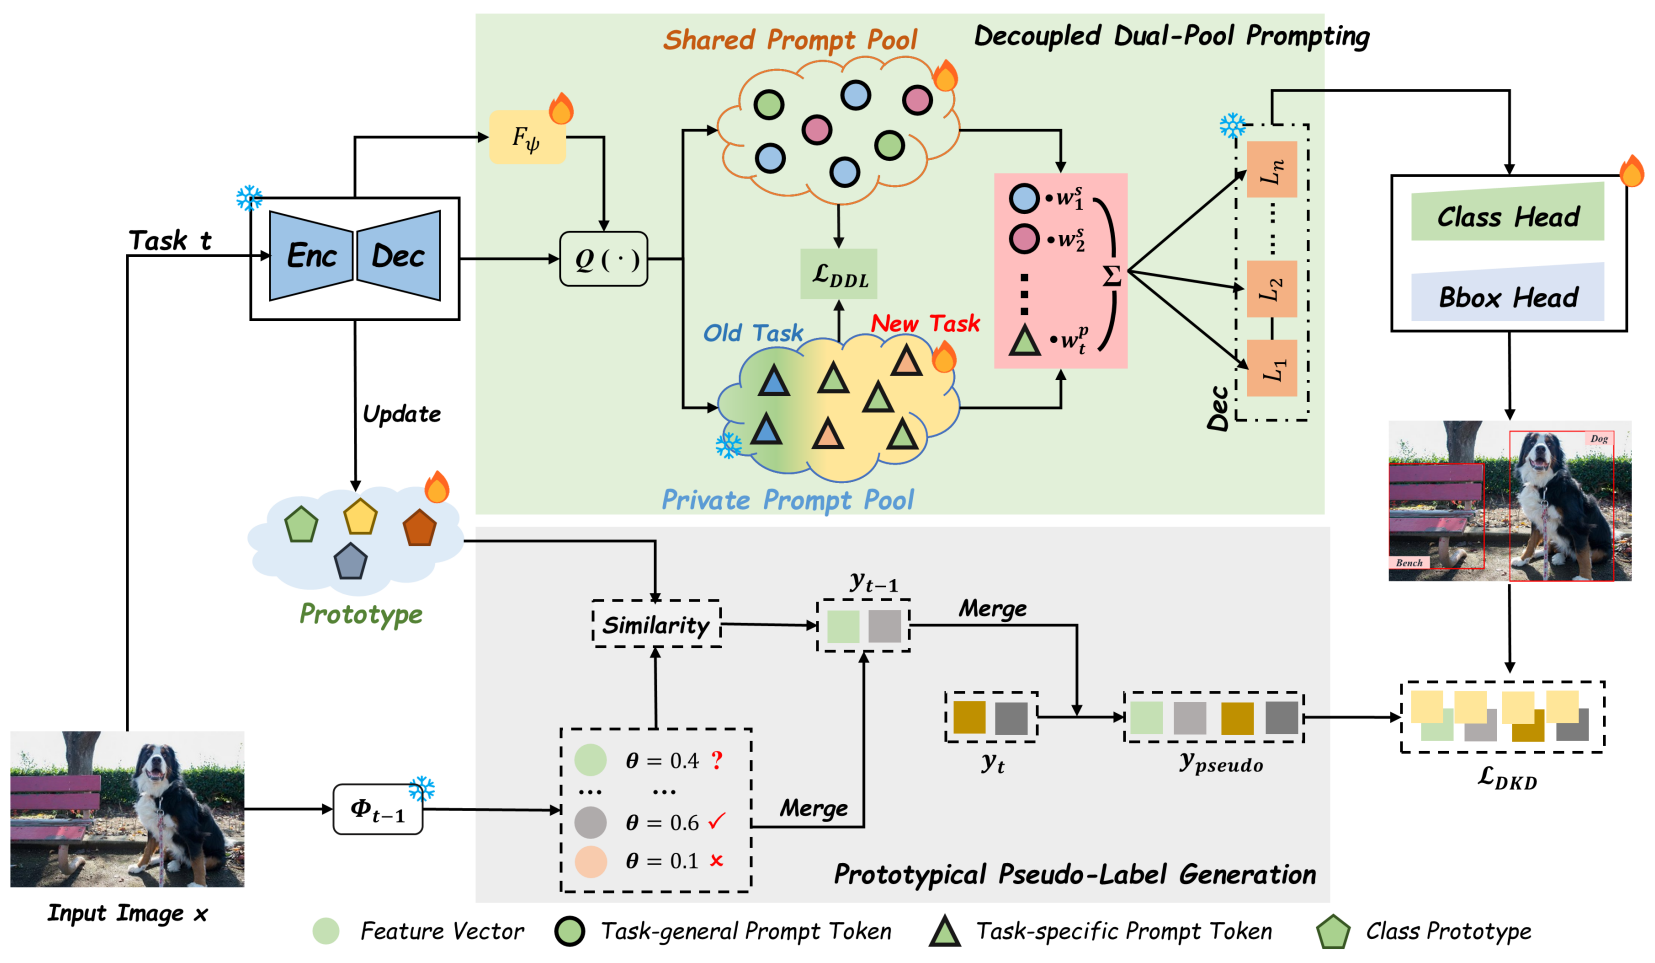
300 dpi PNG · 图注 · 源PDF
图2整体框架展示图像输入、查询、双提示池、伪标签生成、师生训练与检测输出;正文明确为overview。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-02;arXiv v1:2026-03-02;CVPR 2026 fixed official PDF
已查看固定会议PDF、图注和相关正文,核对唯一/最早v1目标图;源裁图与v1逐像素一致,MAE=0。保存v1及对应完整裁图。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Qi Wang;21434;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[108, 72, 505, 303],PDF点、左上角原点。
Figure 2. Overview of our framework at incremental step t. Given an image x, the query function generates a content-aware query
representation by adaptively computing query weights via a ranking function F and performing weighted aggregation. Subsequently,
ψ
prompts are retrieved from both the shared and private pool and injected into the decoder layer. In parallel, the teacher model Φ
t−1
generates a set of candidate bounding boxes, where potentially valuable ones are projected into the feature space to compute their similarity
with class prototypes. This process yields a set of refined, high-quality pseudo-labels to guide the training of the student model Φ .
t
Beyond Prompt Degradation: Prototype-guided Dual-pool Prompting for Incremental Object Detection
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第1页 · P243
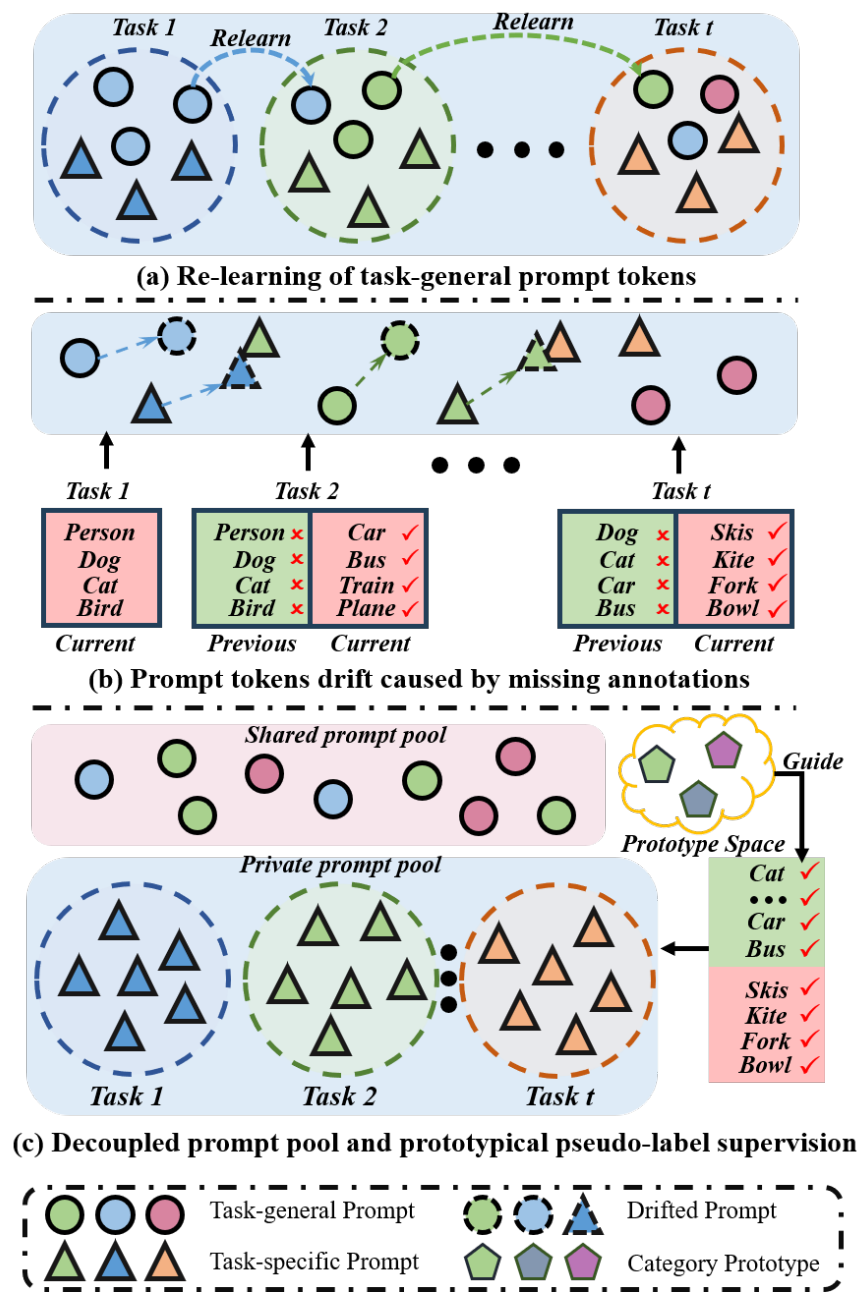
300 dpi PNG · 图注 · 源PDF
图1及引言展示旧方法提示耦合、缺失标注导致漂移,与解耦概念作对比,是问题解释。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-02;arXiv v1:2026-03-02;CVPR 2026 fixed official PDF
已查看固定会议PDF、图注和相关正文,核对唯一/最早v1目标图;源裁图与v1逐像素一致,MAE=0。保存v1及对应完整裁图。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Qi Wang;21434;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[331, 232, 539, 545],PDF点、左上角原点。
Figure 1. Comparison of prompt-based methods. (a) Use task
ID to isolate prompt, which forces task-general prompt to be re-
learned at each task. (b) Missing annotations cause prompt tokens
to drift. (c) The shared prompt pool continuously optimizes task-
general prompt, and category prototypes guide the generation of
pseudo labels for old categories.
EW-DETR: Evolving World Object Detection via Incremental Low-Rank DEtection TRansformer
会议:CVPR 2026 · 主会论文
Figure 3 · PDF第4页 · P198
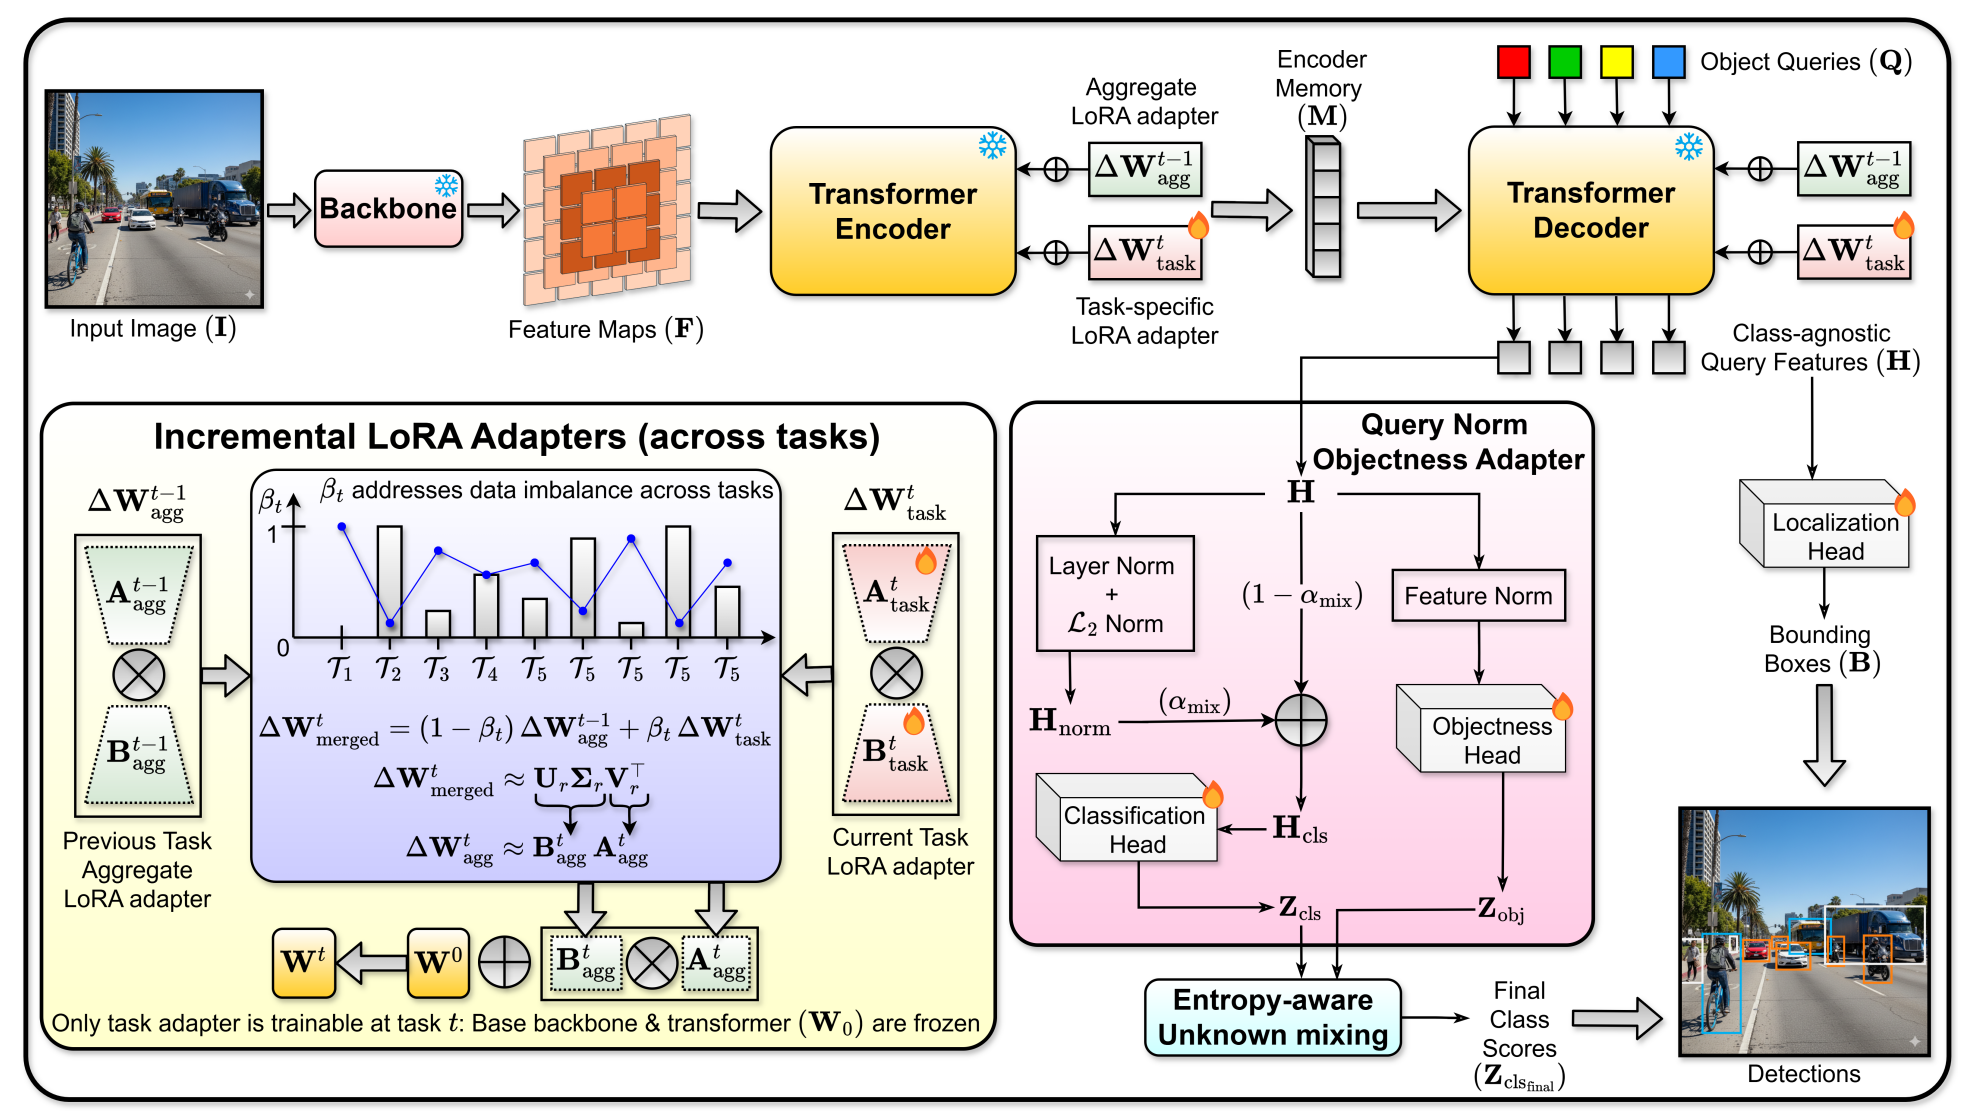
300 dpi PNG · 图注 · 源PDF
图3展示完整的EW-DETR主干、LoRA、查询标准化、未知类别混合及检测输出;图2含概念与简略流程,图3为正文完整框架。
完整图注、版本和筛选证据
最早核实视觉日期:2026-02-24;arXiv v1:2026-02-24;CVPR 2026 fixed official PDF
已核对固定会议PDF和arXiv v1的完整目标图;构图、文字、配色、元素和连线一致,v1为目前最早可核实的视觉版本。作者和机构已在PDF首页与公开引用主页交叉核对。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:C. V. Jawahar;32310;快照2026-10-21。
绘图工具:Gemini 2.5 Pro(仅图中说明性场景图像;不推断整图布局制作工具)。固定会议PDF第2页脚注1明确:“Images are generated using Gemini 2.5 Pro for illustration purposes.” 图1、图3图注带脚注1;只将披露归于说明性图像,不推断整张框架图由生成模型制作。证据:papers/2602.20985_conference.pdf,第2页;quota_review/text/2602.20985_conference.txt。
裁剪坐标:[69, 69, 541, 336.5],PDF点、左上角原点。
Figure 3. EW-DETR framework for Evolving-World Object Detection. An input image is processed by a frozen backbone and
transformer encoder–decoder equipped with aggregate (cid:0) ∆Wt−1 (cid:1) and task-specific (cid:0) ∆Wt (cid:1) LoRA adapters, yielding class-agnostic
agg task
query features. These queries are reparameterised by the Query-Norm Objectness Adapter and passed through a classification head and
an objectness head, whose outputs are combined by Entropy-aware Unknown Mixing module to produce calibrated class scores, while a
localisation head predicts bounding boxes to form final detections across tasks1 .
EW-DETR: Evolving World Object Detection via Incremental Low-Rank DEtection TRansformer
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第1页 · P197
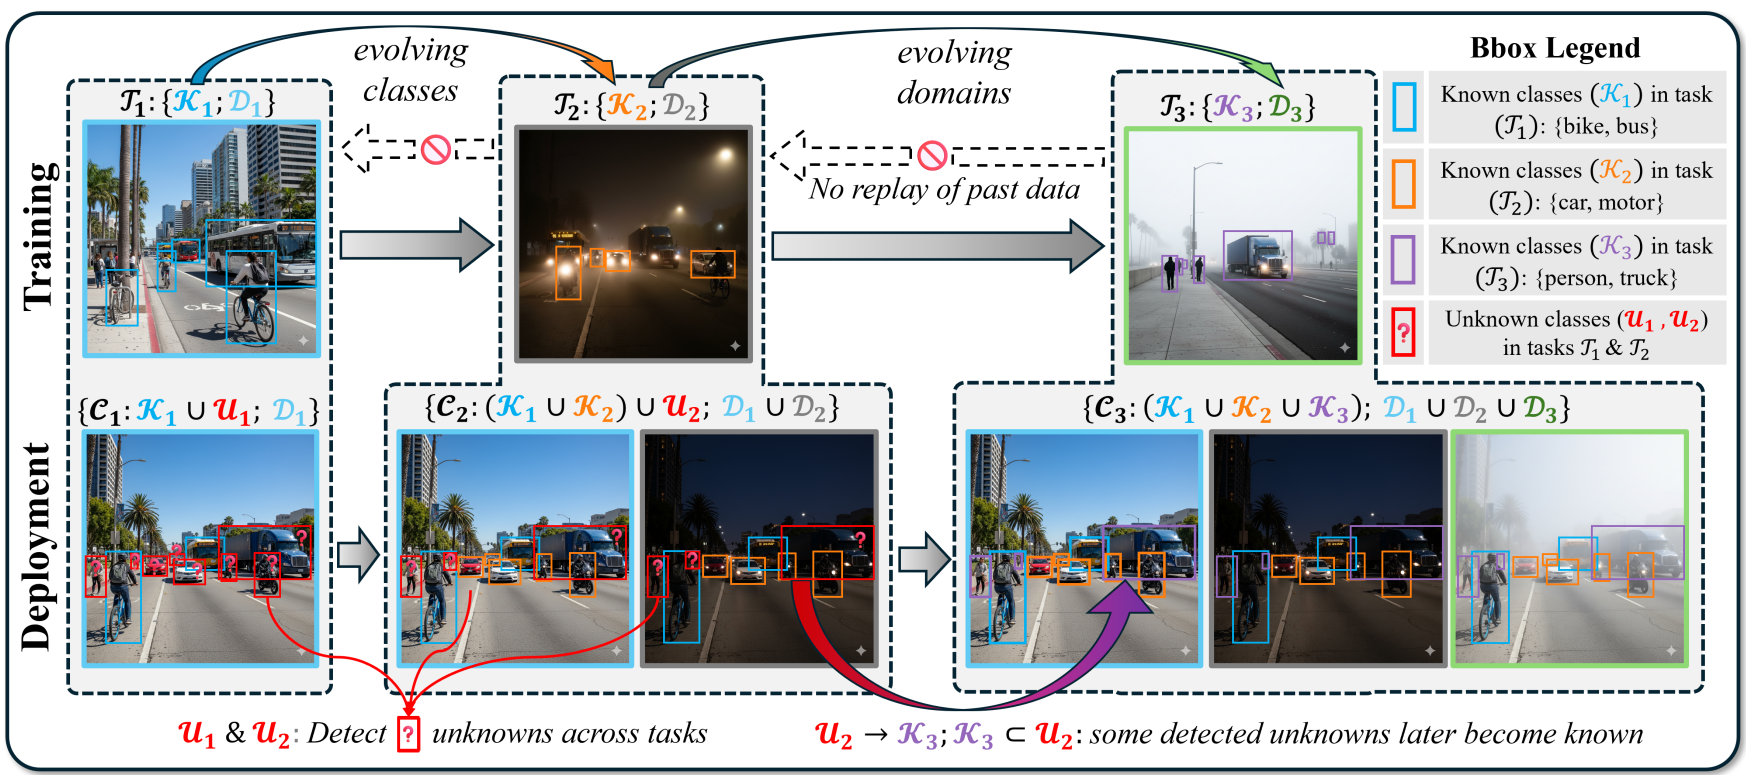
300 dpi PNG · 图注 · 源PDF
图1以训练类别及昼夜/雾天域变化和部署未知类别解释演化世界检测的问题设置,属于应用场景与任务动机。
完整图注、版本和筛选证据
最早核实视觉日期:2026-02-24;arXiv v1:2026-02-24;CVPR 2026 fixed official PDF
已核对固定会议PDF和arXiv v1的完整目标图;构图、文字、配色、元素和连线一致,v1为目前最早可核实的视觉版本。作者和机构已在PDF首页与公开引用主页交叉核对。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:C. V. Jawahar;32310;快照2026-10-21。
绘图工具:Gemini 2.5 Pro(仅图中说明性场景图像;不推断整图布局制作工具)。固定会议PDF第2页脚注1明确:“Images are generated using Gemini 2.5 Pro for illustration purposes.” 图1、图3图注带脚注1;只将披露归于说明性图像,不推断整张框架图由生成模型制作。证据:papers/2602.20985_conference.pdf,第2页;quota_review/text/2602.20985_conference.txt。
裁剪坐标:[95, 184, 514, 370],PDF点、左上角原点。
Figure 1. Overview of Evolving World Object Detection (EWOD). Top (Training): Sequential tasks introduce disjoint classes K across
t
shifting domains D (Day → Night → Fog). Bottom (Deployment): The detector must (i) identify unseen objects U without supervision;
t t
(ii) retain knowledge of all prior classes across all domains; (iii) incrementally learn former unknowns when their labels are revealed later
(e.g., U → K ) and (iv) achieve all these objectives without revisiting any previous data. Best viewed in colour with zoom1 .
2 3
Fourier Angle Alignment for Oriented Object Detection in Remote Sensing
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第1页 · P154
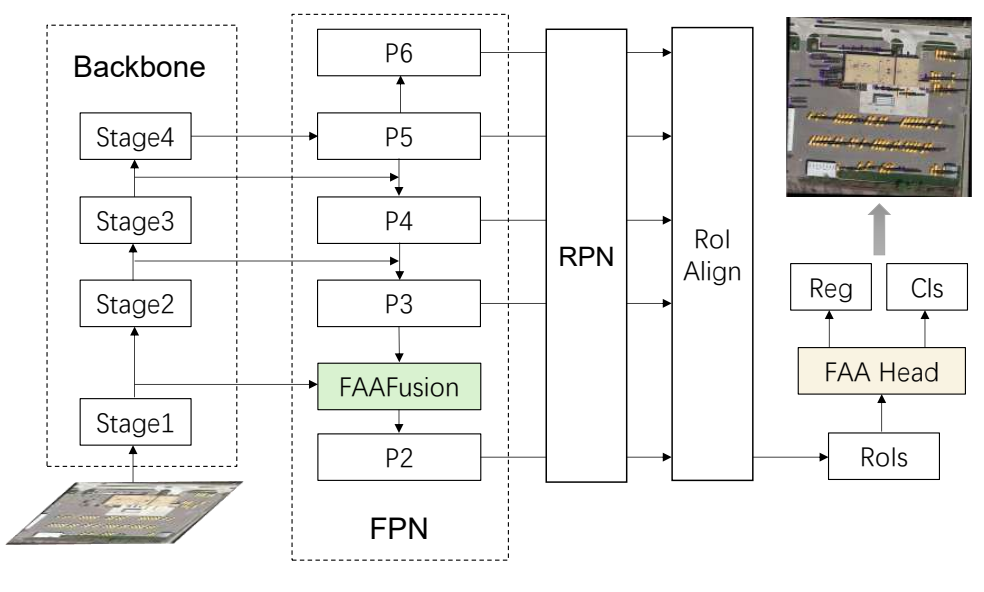
300 dpi PNG · 图注 · 源PDF
图1完整显示骨干、FPN、RPN、RoI Align、分类回归和两个FAA插入位置,正文明确其在主流旋转检测架构中的整体路径。
完整图注、版本和筛选证据
最早核实视觉日期:2026-02-27;arXiv v1:2026-02-27;CVPR 2026 fixed official PDF
已对照会议固定PDF与arXiv v1目标图,构图、文字和连线一致,导出像素一致;未发现更早公开版本。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Ying Fu;11391;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[317, 242, 553, 384],PDF点、左上角原点。
Figure 1. The position of FAAFusion and FAA Head.
Fourier Angle Alignment for Oriented Object Detection in Remote Sensing
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第2页 · P153
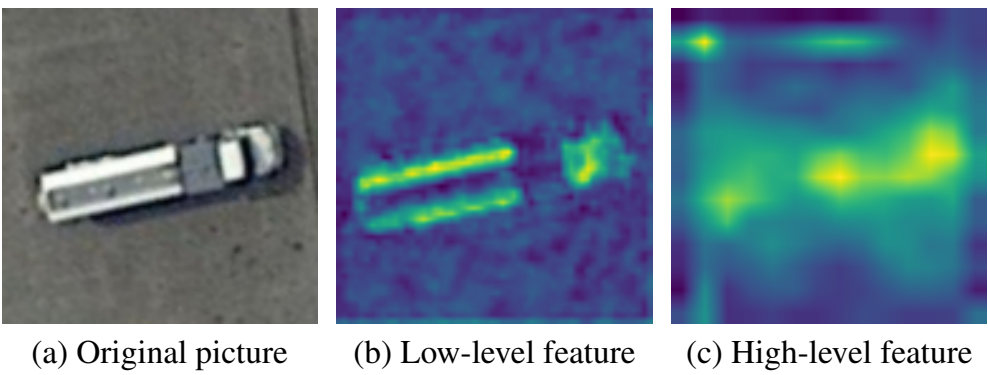
300 dpi PNG · 图注 · 源PDF
引言用图2说明高层粗方向与低层精细方向的不一致,使直接融合产生方向冲突;这是具体特征失配问题的诊断。
完整图注、版本和筛选证据
最早核实视觉日期:2026-02-27;arXiv v1:2026-02-27;CVPR 2026 fixed official PDF
已对照会议固定PDF与arXiv v1目标图,构图、文字和连线一致,导出像素一致;未发现更早公开版本。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Ying Fu;11391;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 70, 295, 160],PDF点、左上角原点。
Figure 2. Directional incoherence. High-level feature (c) has
strong semantics and large receptive fields but captures the coarse
orientation. Forexample,from(c)wecanonlyinferthattheobject
lieshorizontally. Yetmanydown-samplingsblurspatialdetails, so
the orientation signal is low-frequency and vague. Low-level fea-
ture (b) keeps rich edges, corners, and textures, giving clear and
high-frequency orientation cues.
Heuristic-inspired Reasoning Priors Facilitate Data-Efficient Referring Object Detection
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第4页 · P112
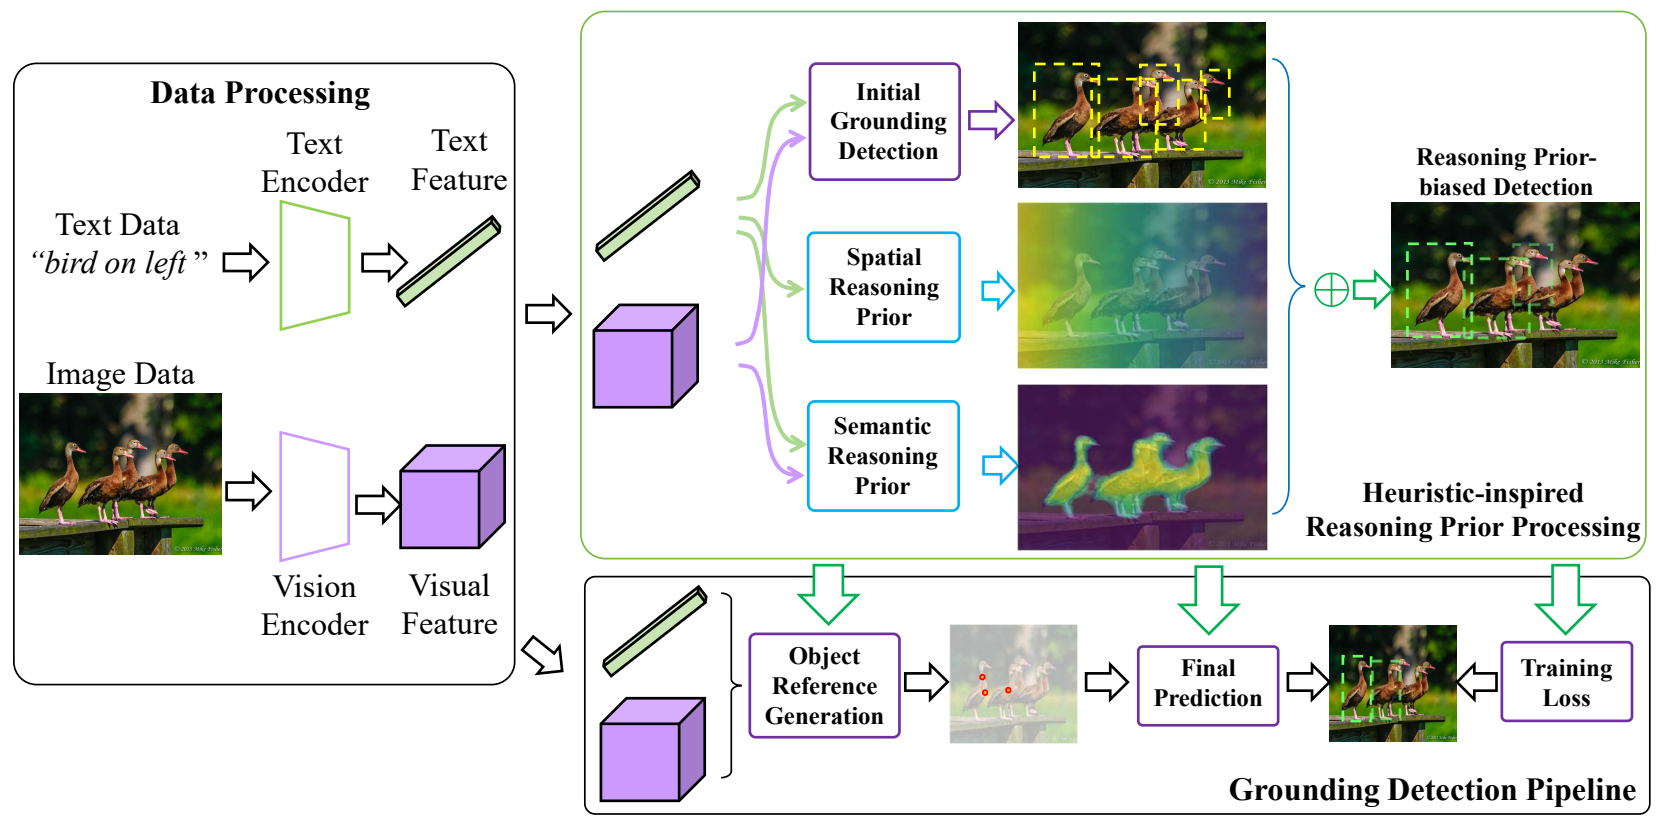
300 dpi PNG · 图注 · 源PDF
方法第3节及图2展示文本和图像编码、空间/语义先验、参考点生成、最终预测及训练损失的完整HeROD流程。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-25;arXiv v1:2026-03-25;CVPR 2026 fixed official PDF
v1与会议版框架的全部模块、图例、字体及连线对应;会议版整体缩小并居中,未发现视觉重绘。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Dacheng Tao;205014;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[106, 72, 504, 268],PDF点、左上角原点。
Figure 2. HeROD pipeline. Text and image features are encoded, and spatial/semantic reasoning priors are derived from the phrase and
image. These priors are injected into reference generation, final prediction, and training loss, guiding the detector toward plausible regions
for more data-efficient learning.
Heuristic-inspired Reasoning Priors Facilitate Data-Efficient Referring Object Detection
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第1页 · P111
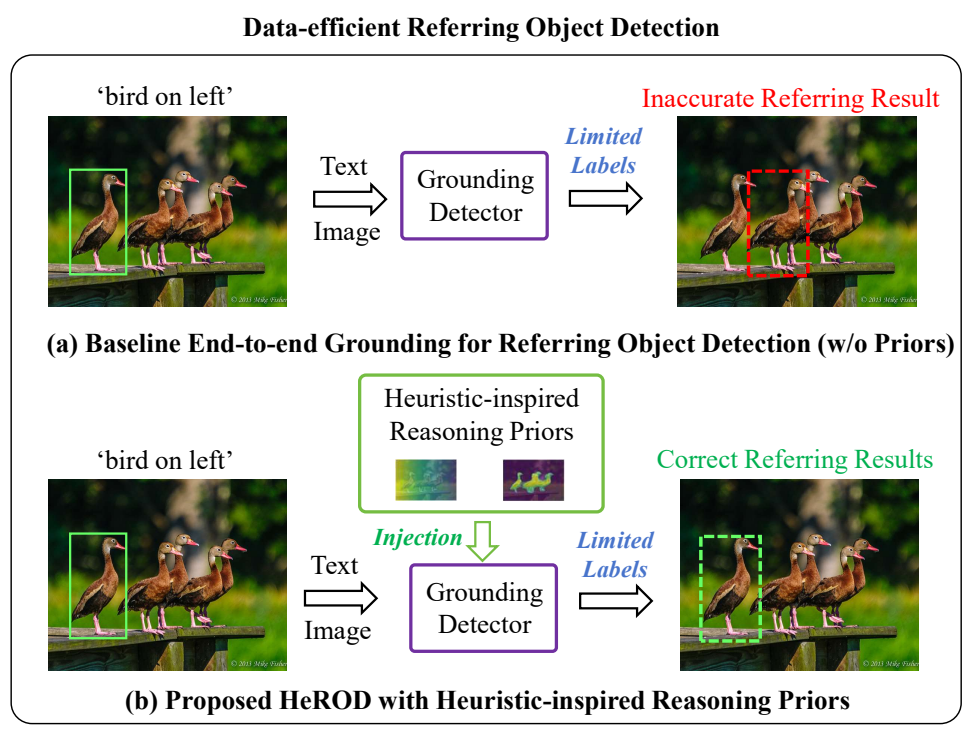
300 dpi PNG · 图注 · 源PDF
引言和图1对比无先验模型忽略空间语义提示的定位失败,以及加入推理先验的概念,主要用于解释少样本检测问题。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-25;arXiv v1:2026-03-25;CVPR 2026 fixed official PDF
v1与会议图的完整裁剪像素一致;采用v1公开日期2026-03-25。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Dacheng Tao;205014;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[317, 245, 551, 420],PDF点、左上角原点。
Figure 1. Conceptual illustration. (a) Without priors, grounding
detectors trained with limited labels often ignore spatial/semantic
cues (e.g., “on the left”). (b) HeROD injects heuristic-inspired
reasoning priors (spatial + semantic), guiding the detector toward
correct localization and improving data-efficient learning.
Instance-Free Domain Adaptive Object Detection
来源:arXiv 2026 · 图源:存档 arXiv v1
Figure 2 · PDF第3页 · P288
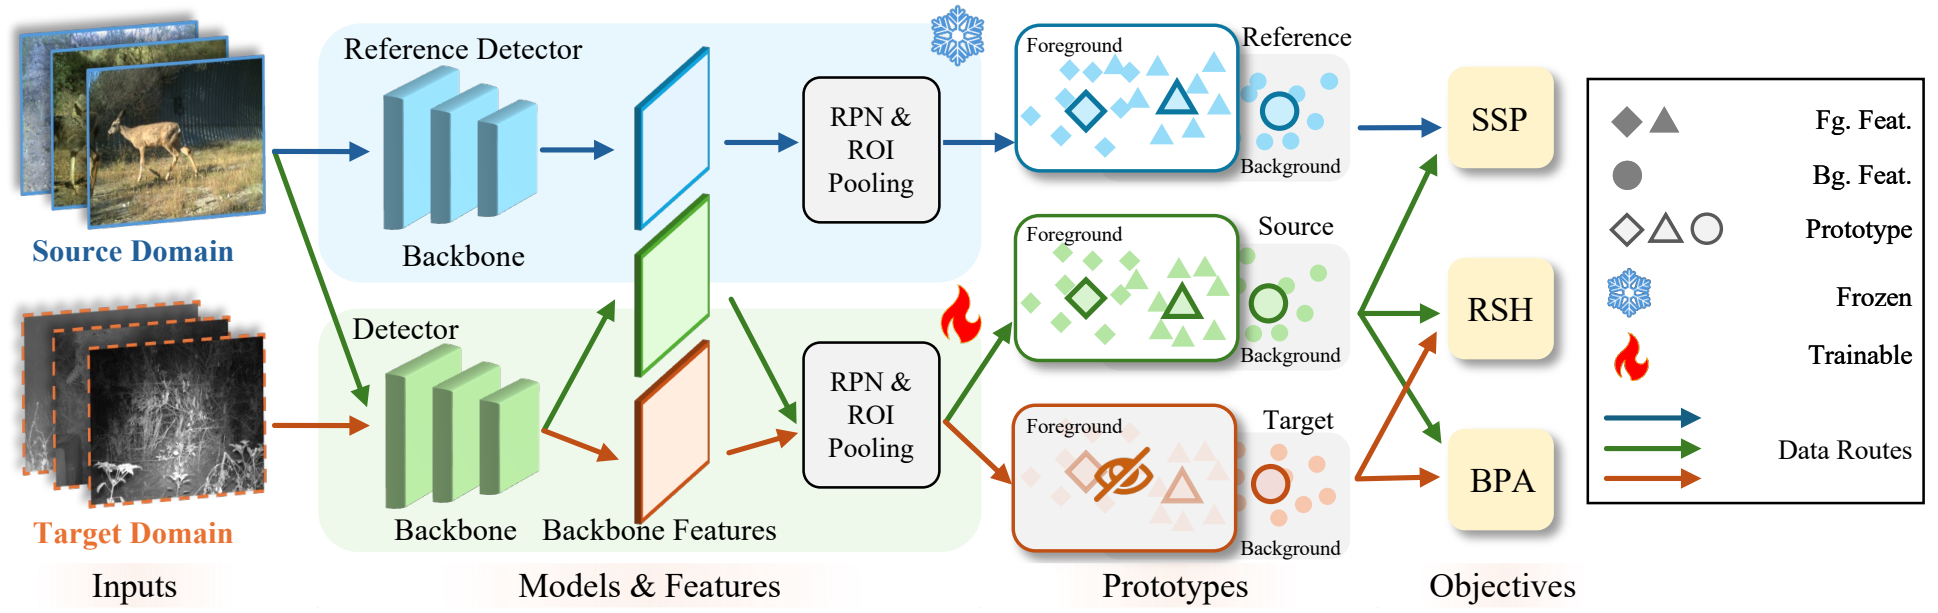
300 dpi PNG · 图注 · 源PDF
图2为RSCN完整框架,展示冻结参考网络、背景原型对齐和关系/结构一致性学习。
完整图注、版本和筛选证据
最早核实视觉日期:2026-02-06;arXiv v1:2026-02-06;arXiv v1 fixed
已读固定v1图注及引用正文,查看完整页面与300dpi导出;首版包含同一图,v1早于S4。LAB-Det作者Dacheng Tao同名及邮箱由其共同作者公开论文核对(https://gcatnjust.github.io/ChenGong/paper/luo_tpami24.pdf)。SeSAM作者机构页面登记2026预印本,TMLR公开周报出现于2026-05-10,未发现早于v1版本;不将后续审稿时间代替图公开日期。实际创作日期unknown。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Wen Li;14507;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[66, 67, 531, 214],PDF点、左上角原点。
Figure 2. An overview of the proposed RSCN. For every batch, source-domain images with labeled foreground objects and target-domain
images without foreground objects are fed to the detector. The background prototypes are aligned with the BPA objective in Eq. 5. RSH in
Eq. 6 keeps the relative geometric relationship for the source and target background prototypes to the shared foreground prototype anchors.
A frozen reference detector is utilized to maintain the source-domain structure in order to avoid the feature collapse with SSP in Eq. 7.
Instance-Free Domain Adaptive Object Detection
来源:arXiv 2026 · 图源:存档 arXiv v1
Figure 1 · PDF第1页 · P287
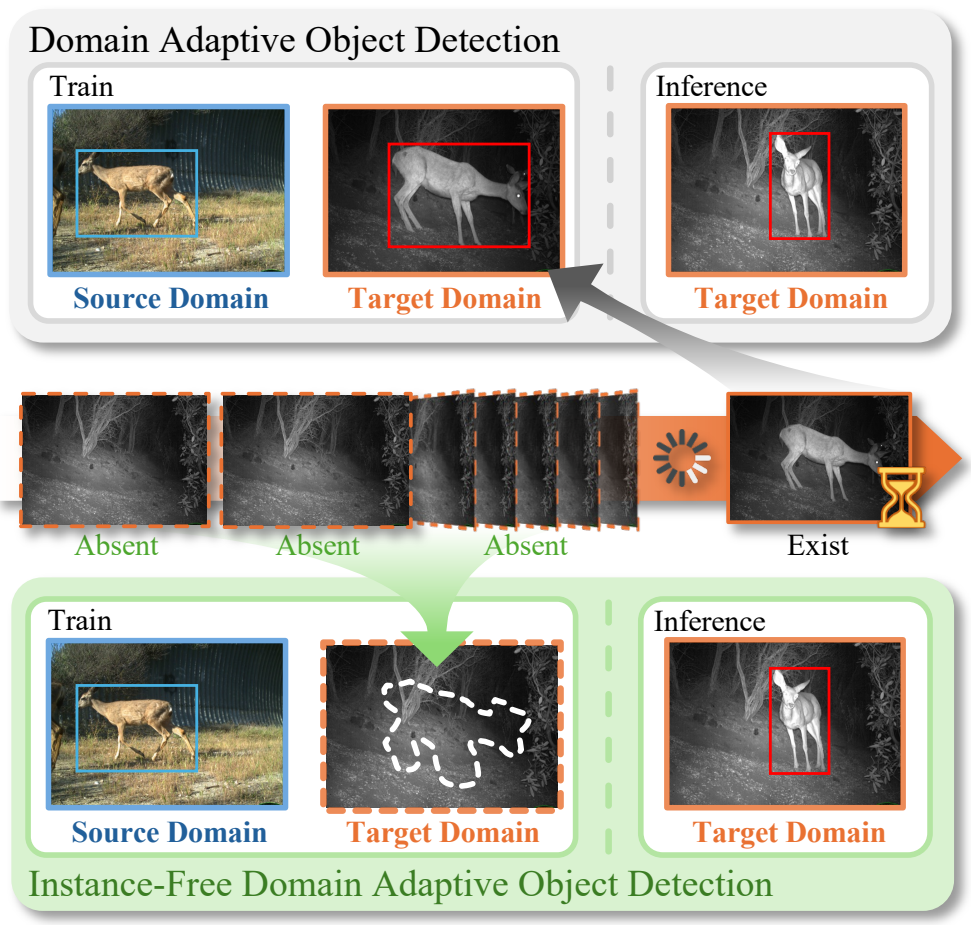
300 dpi PNG · 图注 · 源PDF
图1及引言以野生动物采集场景说明获取目标实例成本高,而背景图易得,概念对比传统DAOD与无实例设置。
完整图注、版本和筛选证据
最早核实视觉日期:2026-02-06;arXiv v1:2026-02-06;arXiv v1 fixed
已读固定v1图注及引用正文,查看完整页面与300dpi导出;首版包含同一图,v1早于S4。LAB-Det作者Dacheng Tao同名及邮箱由其共同作者公开论文核对(https://gcatnjust.github.io/ChenGong/paper/luo_tpami24.pdf)。SeSAM作者机构页面登记2026预印本,TMLR公开周报出现于2026-05-10,未发现早于v1版本;不将后续审稿时间代替图公开日期。实际创作日期unknown。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Wen Li;14507;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[308, 174, 541, 397],PDF点、左上角原点。
Figure 1. Illustration of Instance-Free DAOD. The orange time-
line indicates that target-domain instances appear only after a
long waiting period and require costly manual screening. Tradi-
tional DAOD (top) relies on target images containing foreground
instances, whereas Instance-Free DAOD (bottom) enables transfer-
ring using only background-only target images.
IoUCert: Robustness Verification for Anchor-based Object Detectors
会议:ECCV 2026 · 主会论文
Figure 2 · PDF第5页 · P32
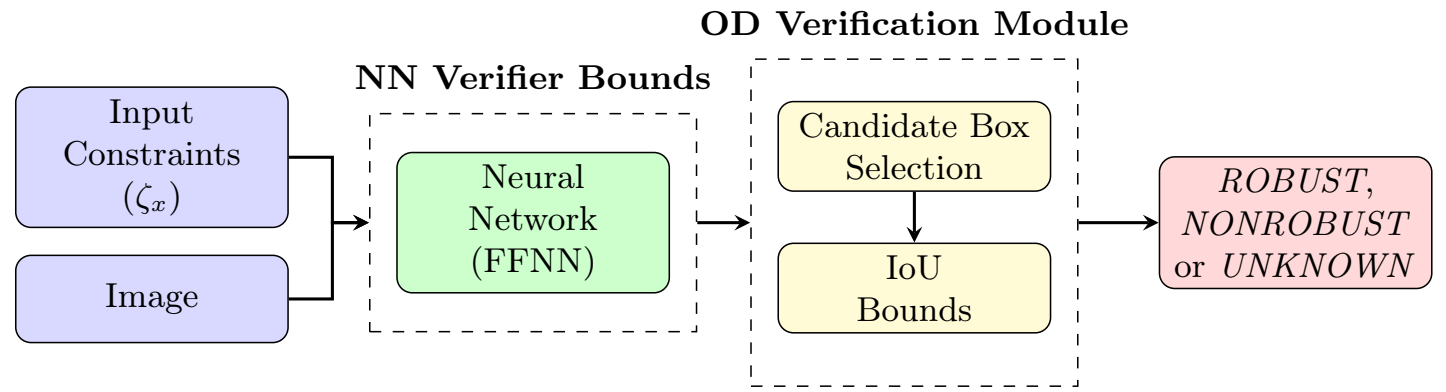
300 dpi PNG · 图注 · 源PDF
图2及第4节串联输入约束/图像、神经网络验证界、候选框选择、IoU界和最终鲁棒性结论,是完整对象检测验证流程。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-03;arXiv v1:2026-03-03;ECCV 2026 fixed official PDF
已查看arXiv v1和会议版的两张目标图;F由第6页移至第5页,构图/文字/连线未见变化。历史提交记录另含v2/v3,当前视觉已在v1存在。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Alessio R Lomuscio;11623;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[134, 116, 481, 210],PDF点、左上角原点。
Fig.2: Pipeline of our object detection (OD) verification framework, combining verifier
bounds, candidate selection, and optimal IoU bound derivation to reach ROBUST,
NONROBUST or UNKNOWN conclusions.
IoUCert: Robustness Verification for Anchor-based Object Detectors
会议:ECCV 2026 · 主会论文
Figure 1 · PDF第2页 · P31
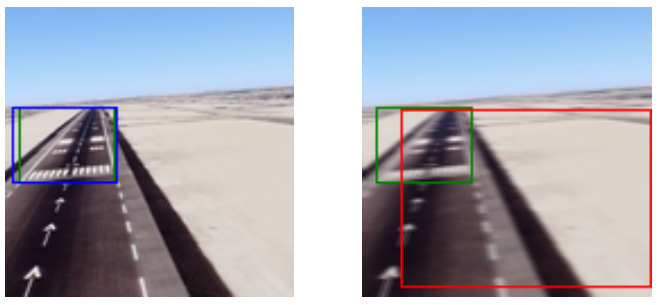
300 dpi PNG · 图注 · 源PDF
引言在第2页引用图1展示微小扰动导致YOLOv3跑道检测框从IoU0.89降到0.11的反例;明确指认鲁棒性失败,而非一般结果拼图。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-03;arXiv v1:2026-03-03;ECCV 2026 fixed official PDF
已查看arXiv v1和会议版的两张目标图;F由第6页移至第5页,构图/文字/连线未见变化。历史提交记录另含v2/v3,当前视觉已在v1存在。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Alessio R Lomuscio;11623;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[229, 114, 387, 187],PDF点、左上角原点。
Fig.1: A counterexample from robustness verification of a YOLOv3 model on a runway
detection task. Left: original image; right: perturbed image. Green boxes: ground truth,
blue box: original model prediction (IoU = 0.89), red box: prediction on the perturbed
image (IoU = 0.11).
LAB-Det: Language as a Domain-Invariant Bridge for Training-Free One-Shot Domain Generalization in Object Detection
来源:arXiv 2026 · 图源:存档 arXiv v1
Figure 2 · PDF第4页 · P290
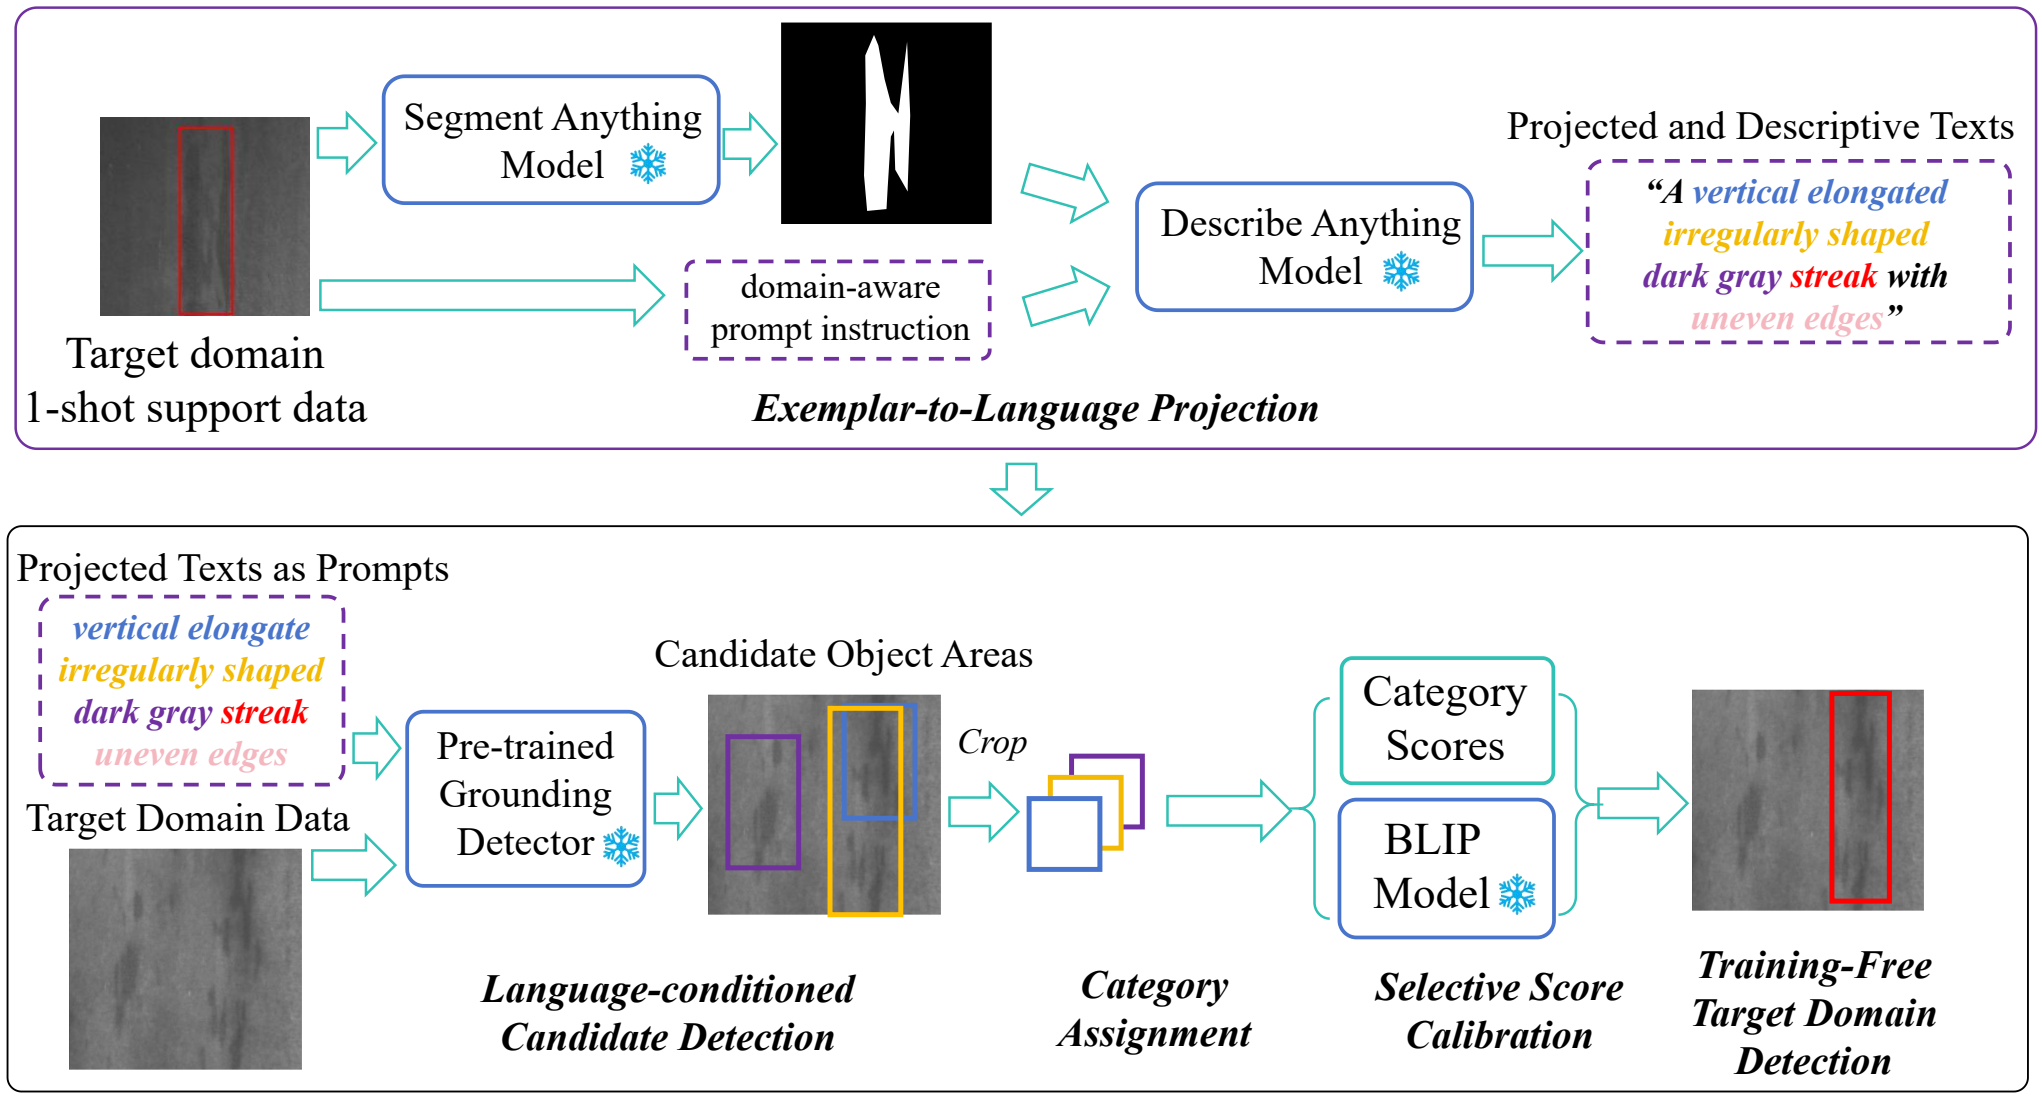
300 dpi PNG · 图注 · 源PDF
图2是完整LAB-Det流程,从示例解析、文本构造、冻结检测到分数校准。
完整图注、版本和筛选证据
最早核实视觉日期:2026-02-06;arXiv v1:2026-02-06;arXiv v1 fixed
已读固定v1图注及引用正文,查看完整页面与300dpi导出;首版包含同一图,v1早于S4。LAB-Det作者Dacheng Tao同名及邮箱由其共同作者公开论文核对(https://gcatnjust.github.io/ChenGong/paper/luo_tpami24.pdf)。SeSAM作者机构页面登记2026预印本,TMLR公开周报出现于2026-05-10,未发现早于v1版本;不将后续审稿时间代替图公开日期。实际创作日期unknown。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Dacheng Tao;205014;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[62, 74, 552, 337],PDF点、左上角原点。
Figure 2. Overview of LAB-Det. Top: exemplar-to-language projection. A single annotated exemplar is segmented by SAM and described
by DAM under a domain-aware prompt, yielding natural-language phrases (e.g., “rough texture”). Bottom: these phrases condition a
frozen detector (e.g., Grounding DINO) to generate candidate boxes and phrase scores. Category scores are obtained by averaging phrase
scores, and an optional BLIP-based calibration refines small or ambiguous detections. The entire pipeline is training-free and interpretable.
LAB-Det: Language as a Domain-Invariant Bridge for Training-Free One-Shot Domain Generalization in Object Detection
来源:arXiv 2026 · 图源:存档 arXiv v1
Figure 1 · PDF第1页 · P289
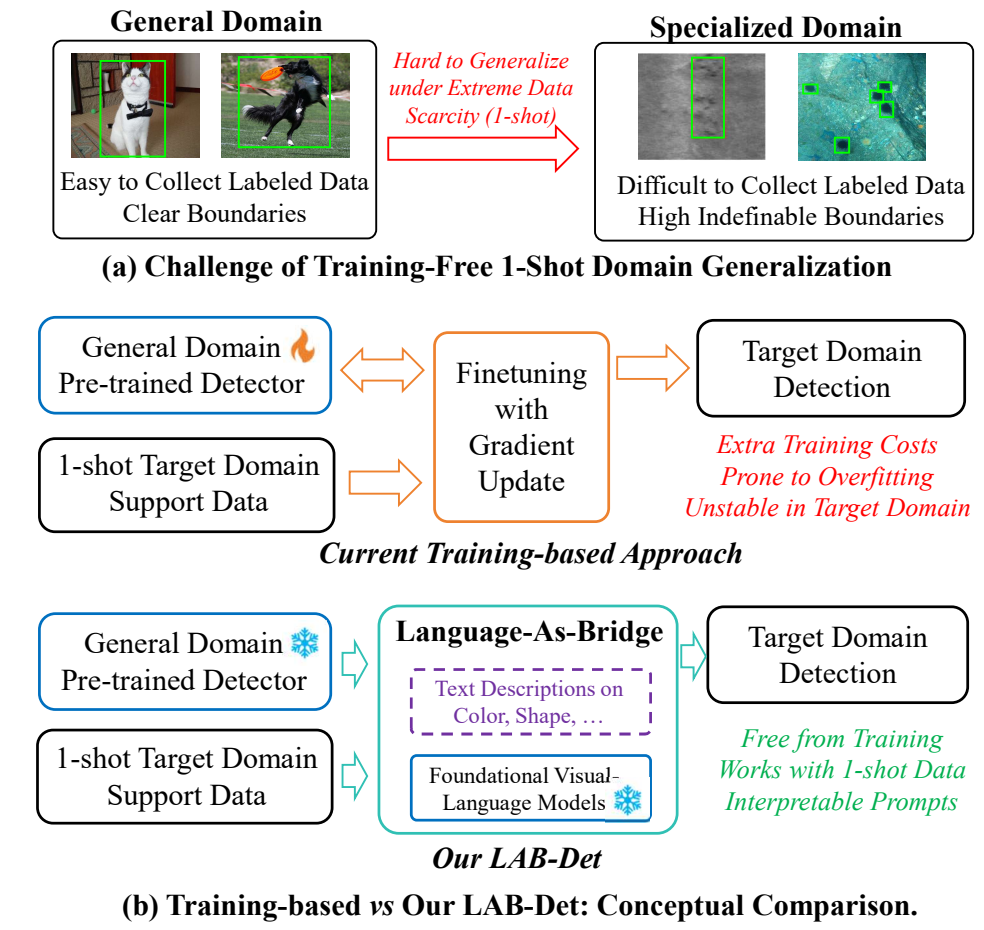
300 dpi PNG · 图注 · 源PDF
图1及引言解释专域单样本稀缺、歧义与微调过拟合,概念对比语言域桥接路径。
完整图注、版本和筛选证据
最早核实视觉日期:2026-02-06;arXiv v1:2026-02-06;arXiv v1 fixed
已读固定v1图注及引用正文,查看完整页面与300dpi导出;首版包含同一图,v1早于S4。LAB-Det作者Dacheng Tao同名及邮箱由其共同作者公开论文核对(https://gcatnjust.github.io/ChenGong/paper/luo_tpami24.pdf)。SeSAM作者机构页面登记2026预印本,TMLR公开周报出现于2026-05-10,未发现早于v1版本;不将后续审稿时间代替图公开日期。实际创作日期unknown。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Dacheng Tao;205014;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[317, 248, 553, 471],PDF点、左上角原点。
Figure 1. Challenge and conceptual comparison of training-free 1-
shot domain generalization for object detection. (a) In specialized
domains (e.g., underwater or industrial), data can be very scarce
(e.g., only one labeled exemplar per class) and object boundaries
are ambiguous, making general-domain detectors fail under severe
domain gaps. (b) Training-based approaches rely on fine-tuning
with gradient updates, which incur extra cost, overfit under 1-shot
supervision, and remain unstable in high-IB domains. In contrast,
LAB-Det leverages language as a domain-invariant bridge: sup-
port exemplars are re-expressed as descriptive text and injected
into frozen vision–language models, enabling training-free, inter-
pretable, and robust target-domain detection.
NoOVD: Novel Category Discovery and Embedding for Open-Vocabulary Object Detection
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第3页 · P248
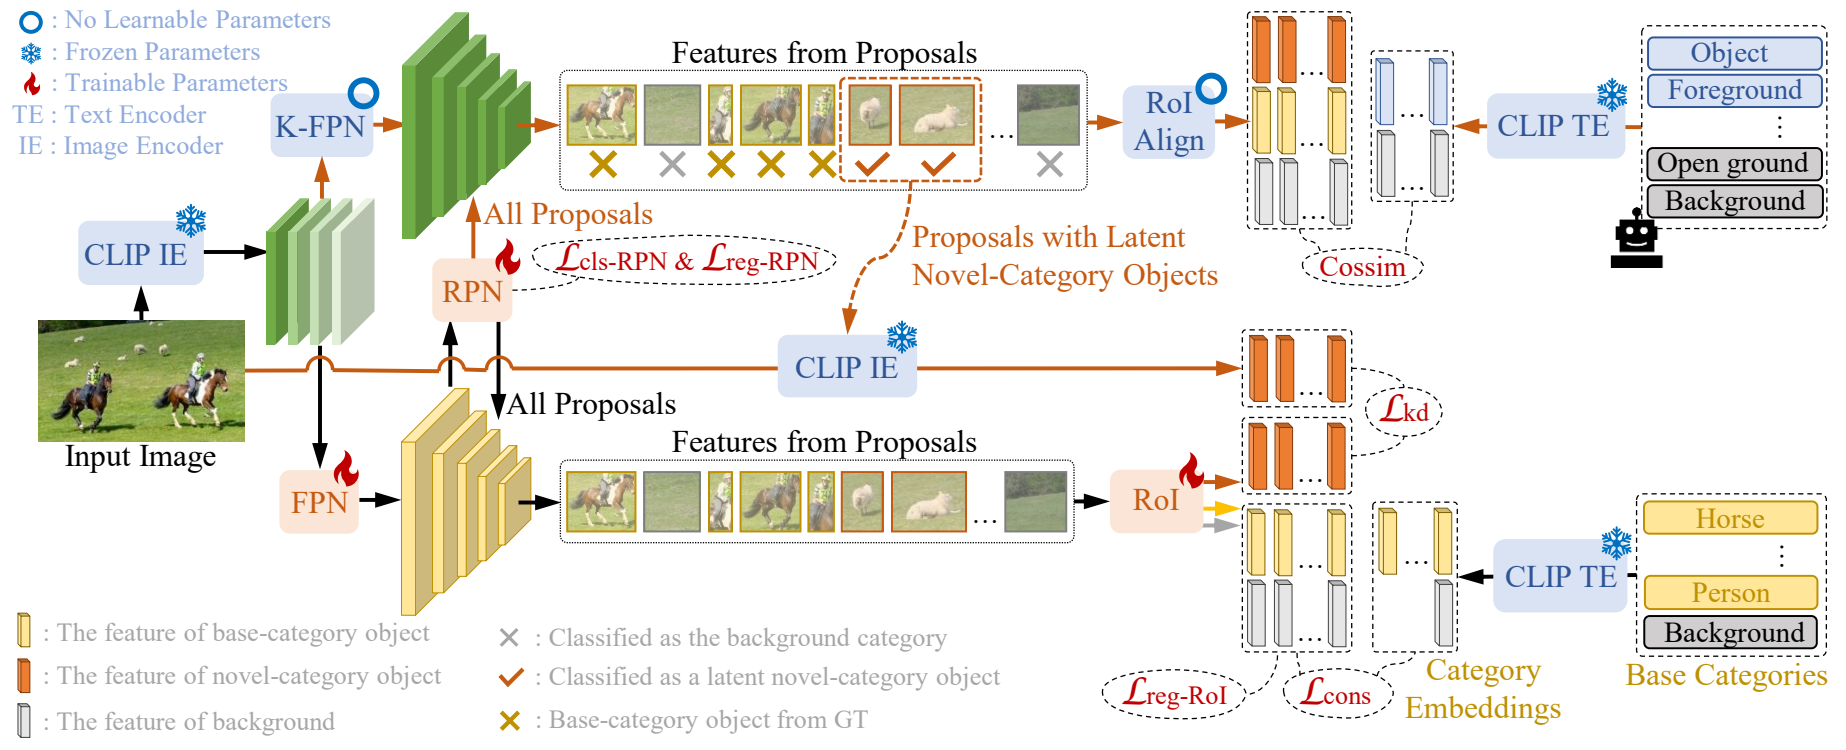
300 dpi PNG · 图注 · 源PDF
图2完整训练流程包含CLIP、K-FPN与FPN双分支、RPN、RoI、类别嵌入及自蒸馏损失;正文明确整体overview。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-22;arXiv v1:2026-03-22;CVPR 2026 fixed official PDF
已打开会议PDF,阅读图注及引言/方法,查看完整源页及300dpi输出。唯一v1公开于2026-03-22;源图与v1完整裁图逐像素相同(MAE=0)。作者Tianjin University身份匹配Wei Feng公开Scholar11058次。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Wei Feng;11058;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[82, 72, 525, 252],PDF点、左上角原点。
Figure 2. Illustration of the training process of NoOVD. We use K-FPN to extract the pyramid embeddings from frozen CLIP to identify
latent novel-category objects. Besides the image-text alignment with L , we also align the features of the RoI head with the features
cons
from K-FPN via knowledge self-distillation with L .
kd
NoOVD: Novel Category Discovery and Embedding for Open-Vocabulary Object Detection
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第1页 · P247
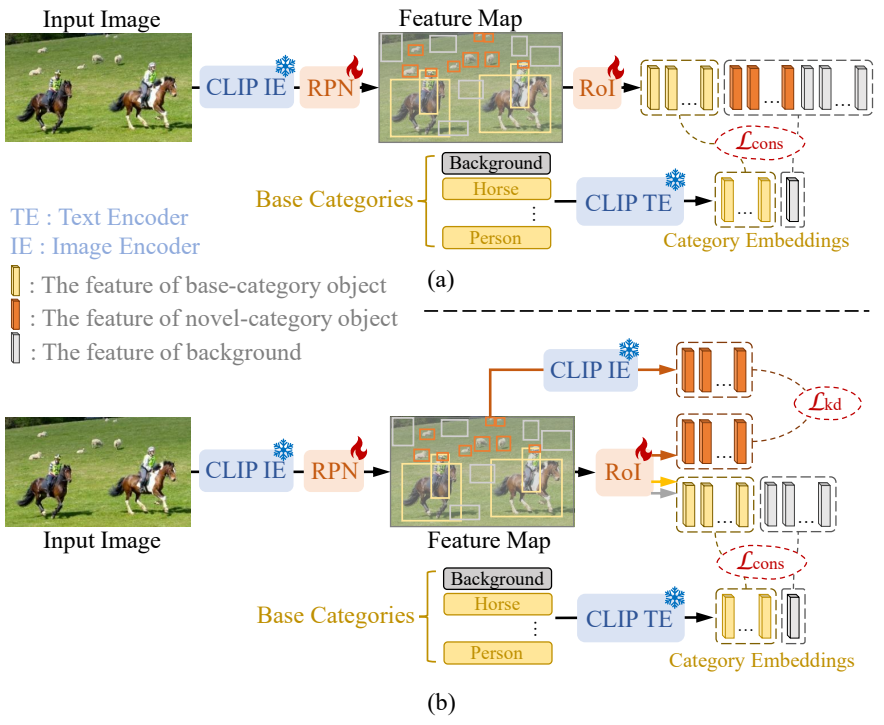
300 dpi PNG · 图注 · 源PDF
图1对比常用训练范式与新范式;引言第2页明确引用(a)解释新类别被迫对齐背景及漏检问题,(b)为概念解决路径,主功能为问题对比。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-22;arXiv v1:2026-03-22;CVPR 2026 fixed official PDF
已打开会议PDF,阅读图注及引言/方法,查看完整源页及300dpi输出。唯一v1公开于2026-03-22;源图与v1完整裁图逐像素相同(MAE=0)。作者Tianjin University身份匹配Wei Feng公开Scholar11058次。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Wei Feng;11058;快照2026-10-22。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[329, 276, 541, 450],PDF点、左上角原点。
Figure 1. Training process for OVD using frozen CLIP. (a) Com-
monly used training process, (b) Our training process.
RiO-DETR: DETR for Real-time Oriented Object Detection
来源:arXiv 2026 · 图源:存档 arXiv v1 · ECCV 2026 — 另有会议版本
Figure 2 · PDF第5页 · P194
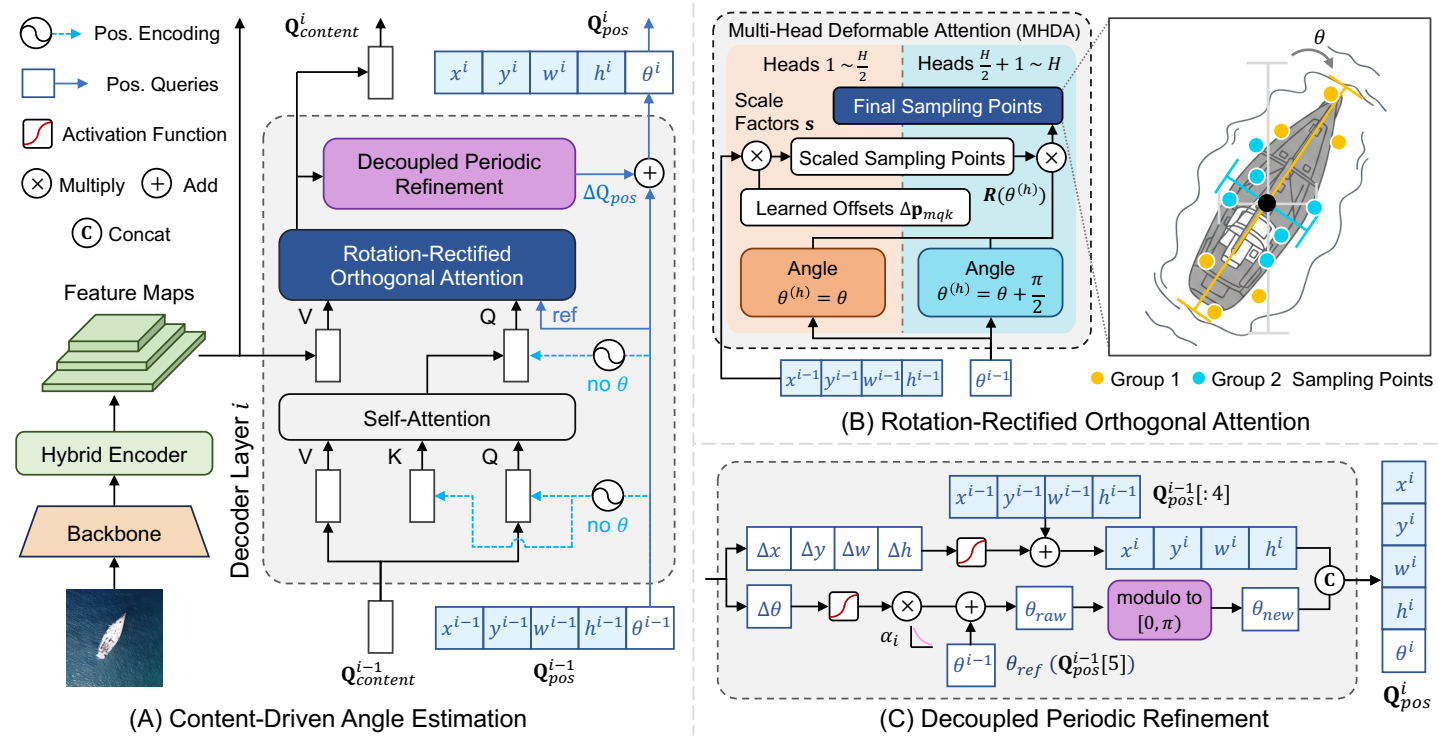
300 dpi PNG · 图注 · 源PDF
图2为RiO-DETR整体架构,含内容/角度查询、旋转注意力及周期角度精修的主要计算路径。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-10;arXiv v1:2026-03-10;arXiv v1 fixed
已查看v1、v2及会议版:会议图3相对v1等比放大,会议图2相对v1/v2更改了连接节点等细节;本条采集的是原始v1视觉,不给会议重绘版使用旧日期。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Xiaoyan Sun;15442;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[134, 116, 479, 294],PDF点、左上角原点。
Fig. 2: The main architecture of our proposed RiO-DETR. The framework highlights
three key components: (A) Content-Driven Angle Estimation, (B) Rotation-Rectified
Orthogonal Attention, and (C) Decoupled Periodic Refinement.
RiO-DETR: DETR for Real-time Oriented Object Detection
来源:arXiv 2026 · 图源:存档 arXiv v1 · ECCV 2026 — 另有会议版本
Figure 3 · PDF第7页 · P193
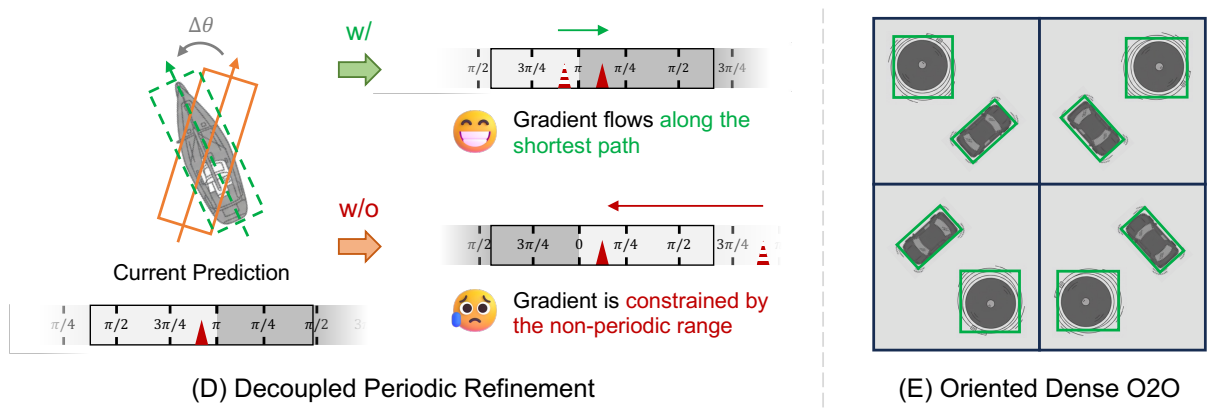
300 dpi PNG · 图注 · 源PDF
第3.3节与图3通过周期/非周期梯度路径和旋转分配的概念对比解释角度周期性不匹配;图1仅为性能比较。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-10;arXiv v1:2026-03-10;arXiv v1 fixed
已查看v1、v2及会议版:会议图3相对v1等比放大,会议图2相对v1/v2更改了连接节点等细节;本条采集的是原始v1视觉,不给会议重绘版使用旧日期。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Xiaoyan Sun;15442;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[161, 115, 453, 215],PDF点、左上角原点。
Fig. 3: An intuitive illustration of (D) Decoupled Periodic Refinement and (E) Oriented
Dense O2O.
VLOD-TTA: Test-Time Adaptation of Vision-Language Object Detectors
会议:ECCV 2026 · 主会论文
Figure 3 · PDF第5页 · P34
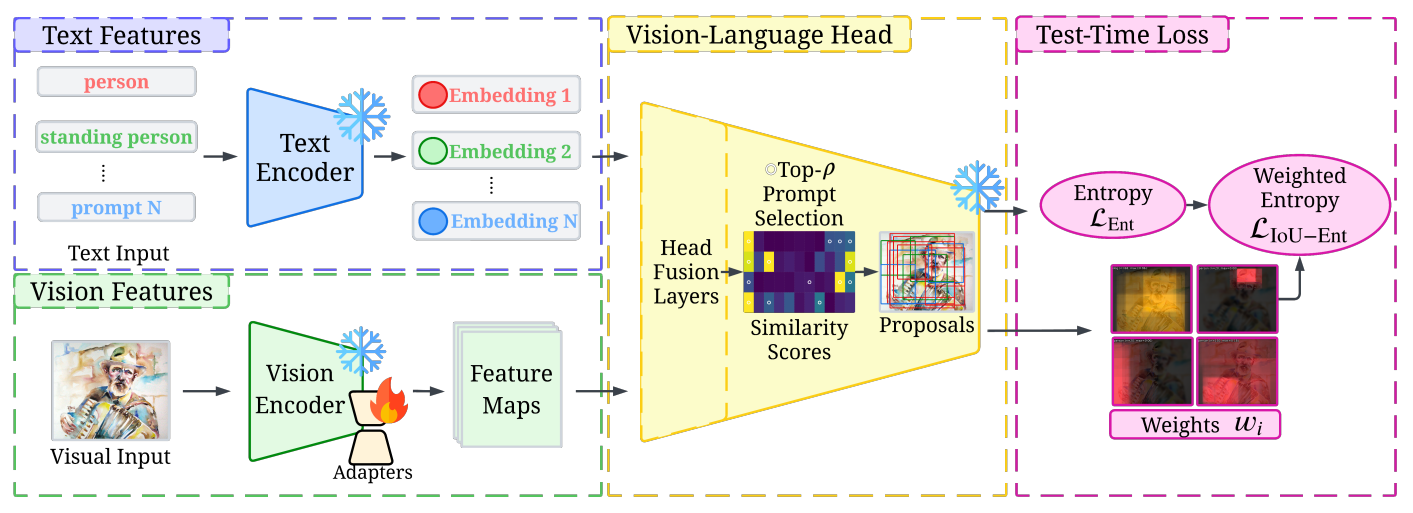
300 dpi PNG · 图注 · 源PDF
第3节与图3 Overview完整连接文本编码、视觉编码及适配器、提示选择、检测头和测试时损失,是整体测试时自适应计算路径。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-17;arXiv v1:2025-10-01;ECCV 2026 fixed official PDF
已查看v1、v2及会议版;v1图1检测标签较小,v1框架的提示选择区域/标注与会议版不同。v2已包含会议版的标签与框架设计,会议版F仅排版缩放;以v2的2026-03-17日期登记当前视觉,不套用v1日期。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Eric Granger;14279;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[137, 114, 476, 237],PDF点、左上角原点。
Fig.3: Overview of VLOD-TTA. Given an input image and a pool of class
prompts, the text encoder produces embeddings that interact with region proposals
through the vision–language head to compute similarity scores. IPS selects the top-ρ
prompts and averages their scores to obtain per-proposal class scores. IWE then com-
bines per-proposal entropy with IoU-based weights to form the adaptation objective.
VLOD-TTA: Test-Time Adaptation of Vision-Language Object Detectors
会议:ECCV 2026 · 主会论文
Figure 1 · PDF第2页 · P33
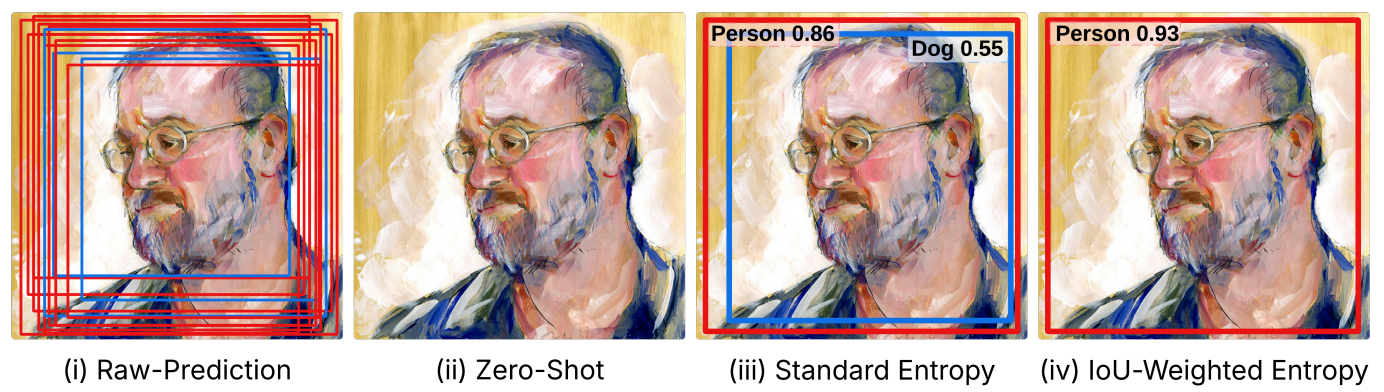
300 dpi PNG · 图注 · 源PDF
引言图1对照原始预测、零样本、常规熵优化与IoU加权熵,指出漏检及把人物误检成狗的确认偏差;两幅M均符合时按较小图号选图1。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-17;arXiv v1:2025-10-01;ECCV 2026 fixed official PDF
已查看v1、v2及会议版;v1图1检测标签较小,v1框架的提示选择区域/标注与会议版不同。v2已包含会议版的标签与框架设计,会议版F仅排版缩放;以v2的2026-03-17日期登记当前视觉,不套用v1日期。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Eric Granger;14279;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[142, 114, 474, 208],PDF点、左上角原点。
Fig.1: Motivation for IWE. Left→right: (i) Raw predictions before thresholding
for two classes — a true positive Person (red) (bbox cluster size = 167, max score
= 0.14) and a false positive Dog (blue) (bbox cluster size = 45, max score = 0.15);
(ii) In ZS, all scores remain below the detection threshold, causing a missed detection;
(iii) Standard entropy minimization over-confidently sharpens scores, resulting in a dog
false positive; and (iv) IWE focuses updates on dense bbox clusters and suppresses
isolated boxes, producing only the correct person detection.
Direct Segmentation without Logits Optimization for Training-Free Open-Vocabulary Semantic Segmentation
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第3页 · P44
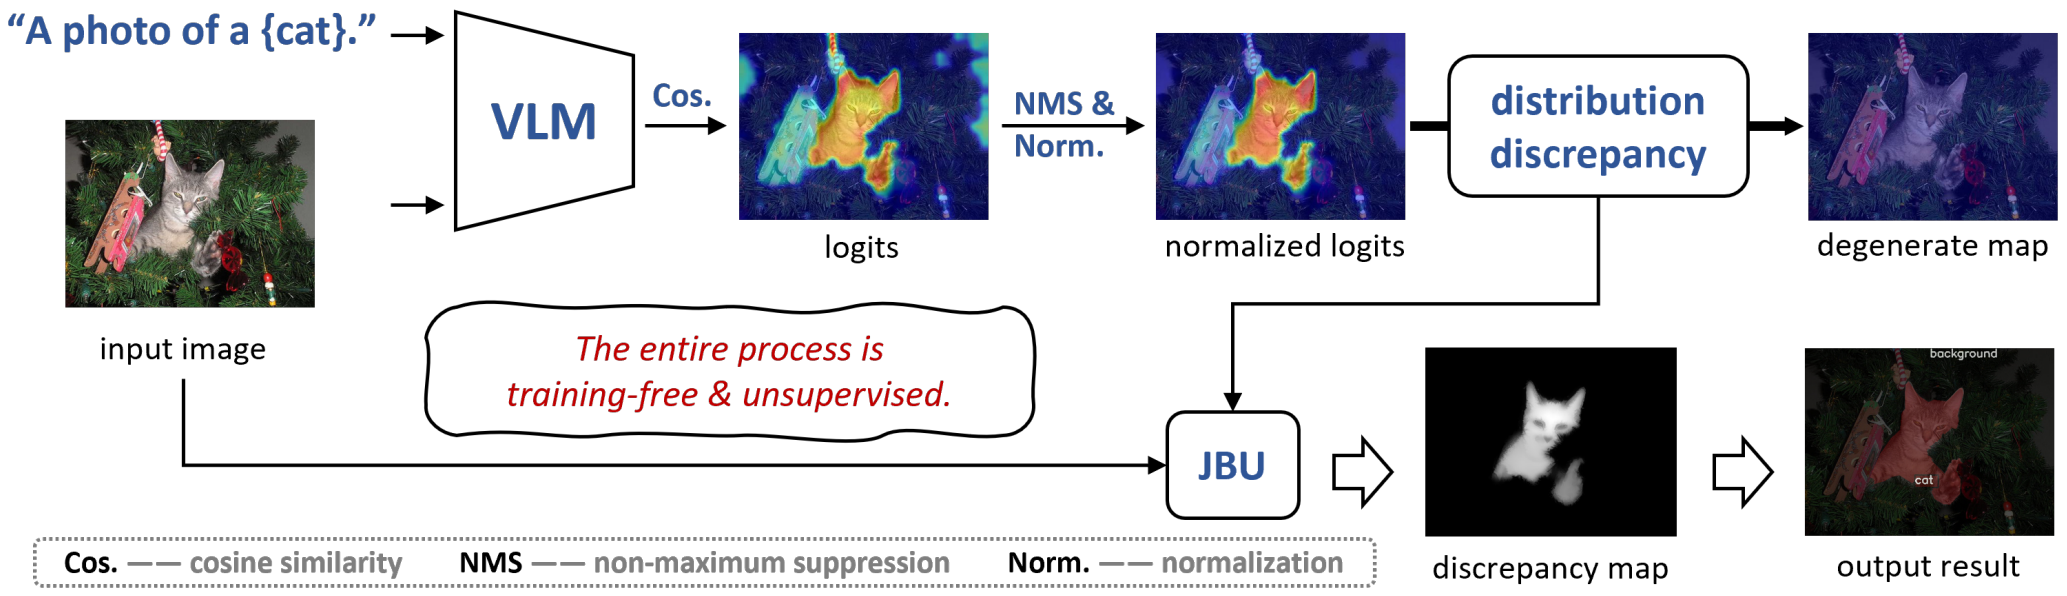
300 dpi PNG · 图注 · 源PDF
第3.2节Overview及图2将视觉语言特征、归一化、分布差异、联合双边上采样及输出串成完整推理链路,是总体框架。
完整图注、版本和筛选证据
最早核实视觉日期:2026-04-09;arXiv v1:2026-04-09;CVPR 2026 fixed official PDF
已逐张查看arXiv v1和会议PDF,两张视觉一致;保存原始PDF与匹配裁图。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Yanyun Qu;11764;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[58, 71, 554, 214],PDF点、左上角原点。
Figure 2. Overview of the proposed method. The pipeline begins by computing the cosine similarity (Cos.) between vision-language
features to obtain logits, followed by non-maximum suppression (NMS) and normalization (Norm.) to filter low-confidence patches. The
core step involves calculating the distribution discrepancy between the normalized logits and the degenerate distribution map. This solved
discrepancy is then upsampled to the original image resolution via joint bilateral upsampling (JBU) to obtain the discrepancy map. Finally,
the semantic map is generated by applying an argmax operation to the discrepancy map.
Direct Segmentation without Logits Optimization for Training-Free Open-Vocabulary Semantic Segmentation
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第1页 · P43
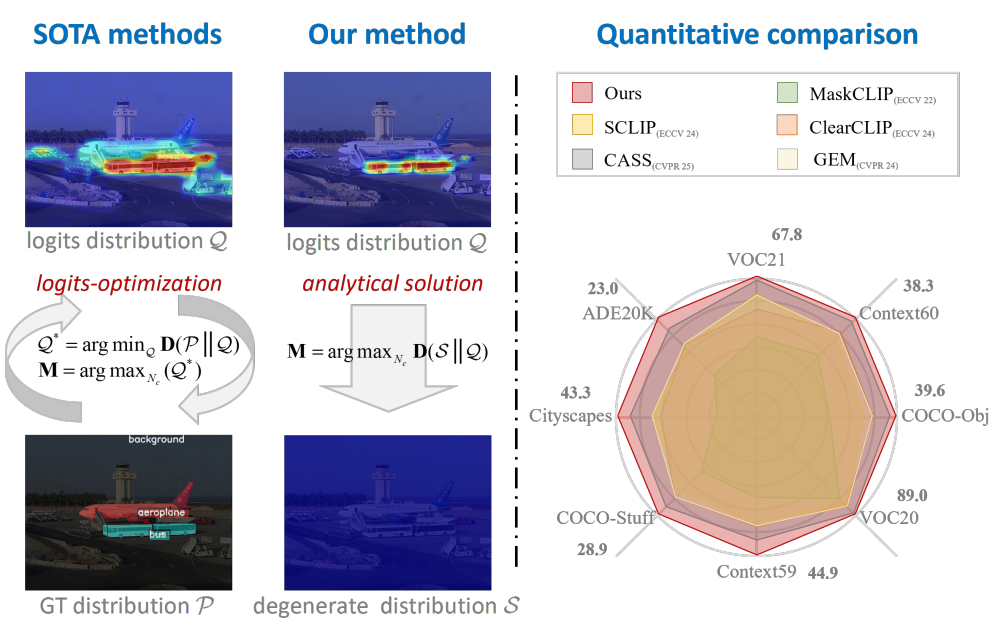
300 dpi PNG · 图注 · 源PDF
引言第2页引用图1对比迭代优化与直接解析解范式,说明训练耗时与模型专用调制的局限。整图含附属性能雷达图,主要功能为概念对比;不拆除雷达图。
完整图注、版本和筛选证据
最早核实视觉日期:2026-04-09;arXiv v1:2026-04-09;CVPR 2026 fixed official PDF
已逐张查看arXiv v1和会议PDF,两张视觉一致;保存原始PDF与匹配裁图。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Yanyun Qu;11764;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[316, 241, 555, 391],PDF点、左上角原点。
Figure 1. Compared with the logits-optimization methods seeking
optimal solutions, we reformulate the problem as an analytical so-
lution form. This reformulation confers three key advantages: in-
dependence from GT annotations, elimination of time-consuming
training, and freedom from model-specific modulation.
Do Instance Priors Help Weakly Supervised Semantic Segmentation?
来源:arXiv 2026 · 图源:存档 arXiv v1
Figure 3 · PDF第4页 · P292
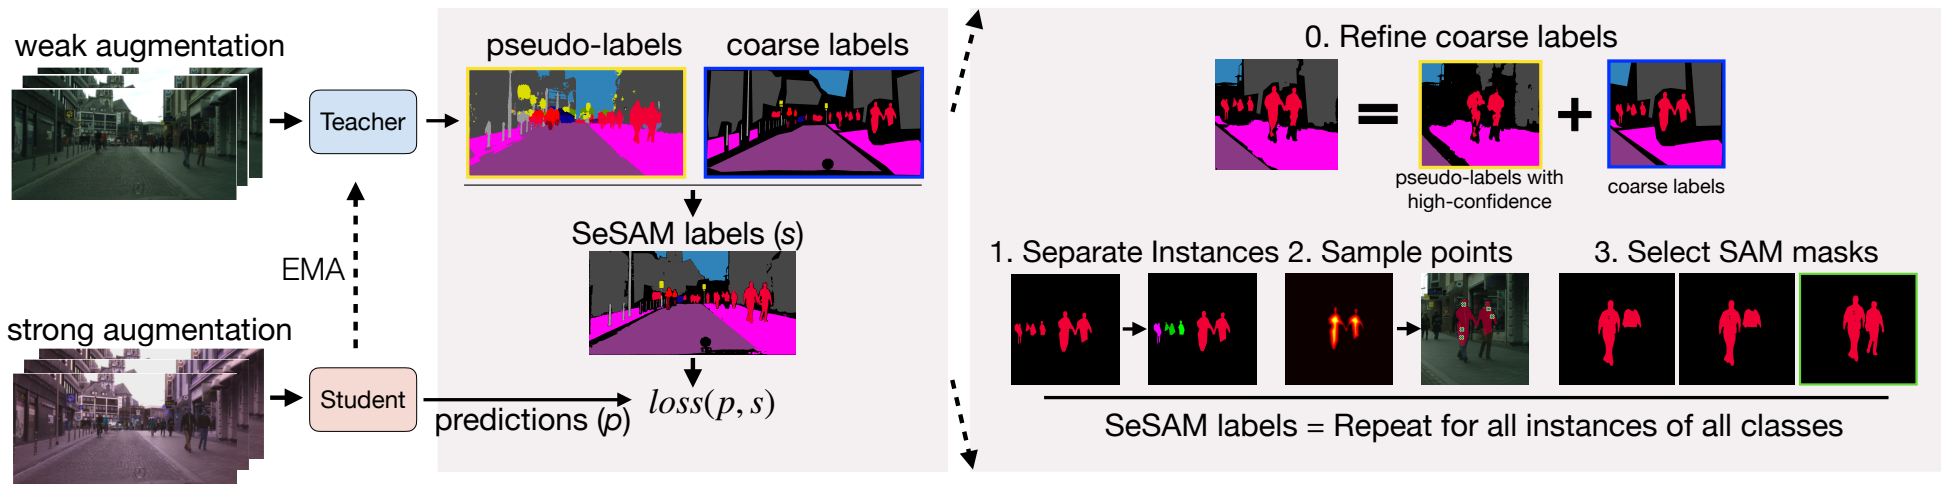
300 dpi PNG · 图注 · 源PDF
图3是SeSAM完整训练框架,结合弱标注、SAM候选掩码和伪标签监督。
完整图注、版本和筛选证据
最早核实视觉日期:2026-04-13;arXiv v1:2026-04-13;arXiv v1 fixed
已读固定v1图注及引用正文,查看完整页面与300dpi导出;首版包含同一图,v1早于S4。LAB-Det作者Dacheng Tao同名及邮箱由其共同作者公开论文核对(https://gcatnjust.github.io/ChenGong/paper/luo_tpami24.pdf)。SeSAM作者机构页面登记2026预印本,TMLR公开周报出现于2026-05-10,未发现早于v1版本;不将后续审稿时间代替图公开日期。实际创作日期unknown。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Bernt Schiele;131438;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[73, 82, 540, 200],PDF点、左上角原点。
Figure 3: SeSAM framework for coarse sup ervision. First, pseudo-labels for training images are
generated by the teacher model. Next, these pseudo-labels are then refined following the key steps 1-3,
namely instance separation, point sampling and mask selection (see Section 3). To improve mask quality,
we augment coarse labels with high-confidence pseudo-labels before applying SAM (step 0). The resulting
refined labels, called SeSAM labels, are then used to train the student network.
Do Instance Priors Help Weakly Supervised Semantic Segmentation?
来源:arXiv 2026 · 图源:存档 arXiv v1
Figure 2 · PDF第3页 · P291
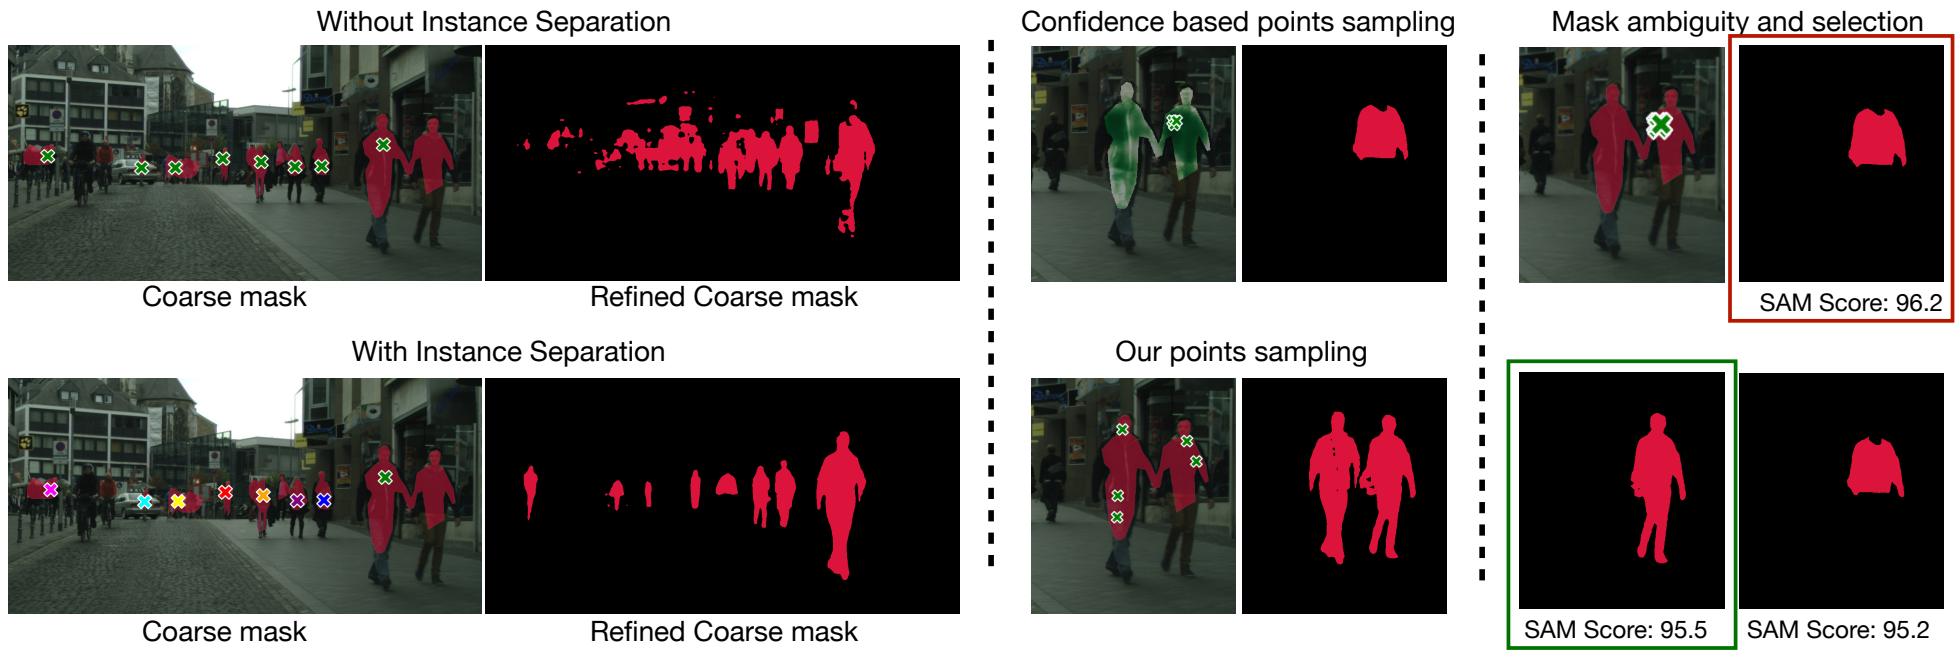
300 dpi PNG · 图注 · 源PDF
图2及第3节诊断SAM不能直接适配语义弱标注的实例/类别合并、掩码选择等问题;图1普通效果与成本图不计M。
完整图注、版本和筛选证据
最早核实视觉日期:2026-04-13;arXiv v1:2026-04-13;arXiv v1 fixed
已读固定v1图注及引用正文,查看完整页面与300dpi导出;首版包含同一图,v1早于S4。LAB-Det作者Dacheng Tao同名及邮箱由其共同作者公开论文核对(https://gcatnjust.github.io/ChenGong/paper/luo_tpami24.pdf)。SeSAM作者机构页面登记2026预印本,TMLR公开周报出现于2026-05-10,未发现早于v1版本;不将后续审稿时间代替图公开日期。实际创作日期unknown。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Bernt Schiele;131438;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[70, 91, 540, 249],PDF点、左上角原点。
Figure 2: SAM challenges. Left: As an instance-based model, SAM performs poorly when segmenting a
class comprising multiple instances, see the class “person”. Splitting the class mask into individual instances
addresses this challenge. Middle: Confidence-based sampling (Kweon & Yoon, 2024) yields a suboptimal
mask; in contrast, our proposed sampling strategy achieves comprehensive mask coverage, resulting in im-
proved segmentation. Right: SAM score-based mask selection may not give the best desired segmentation
(see mask in red box). Our mask selection strategy using intersection with the coarse mask determines the
desired mask granularity (see mask in green box).
Generalizable Knowledge Distillation from Vision Foundation Models for Semantic Segmentation
会议:CVPR 2026 · 图源:存档 arXiv v1
Figure 4 · PDF第4页 · P14
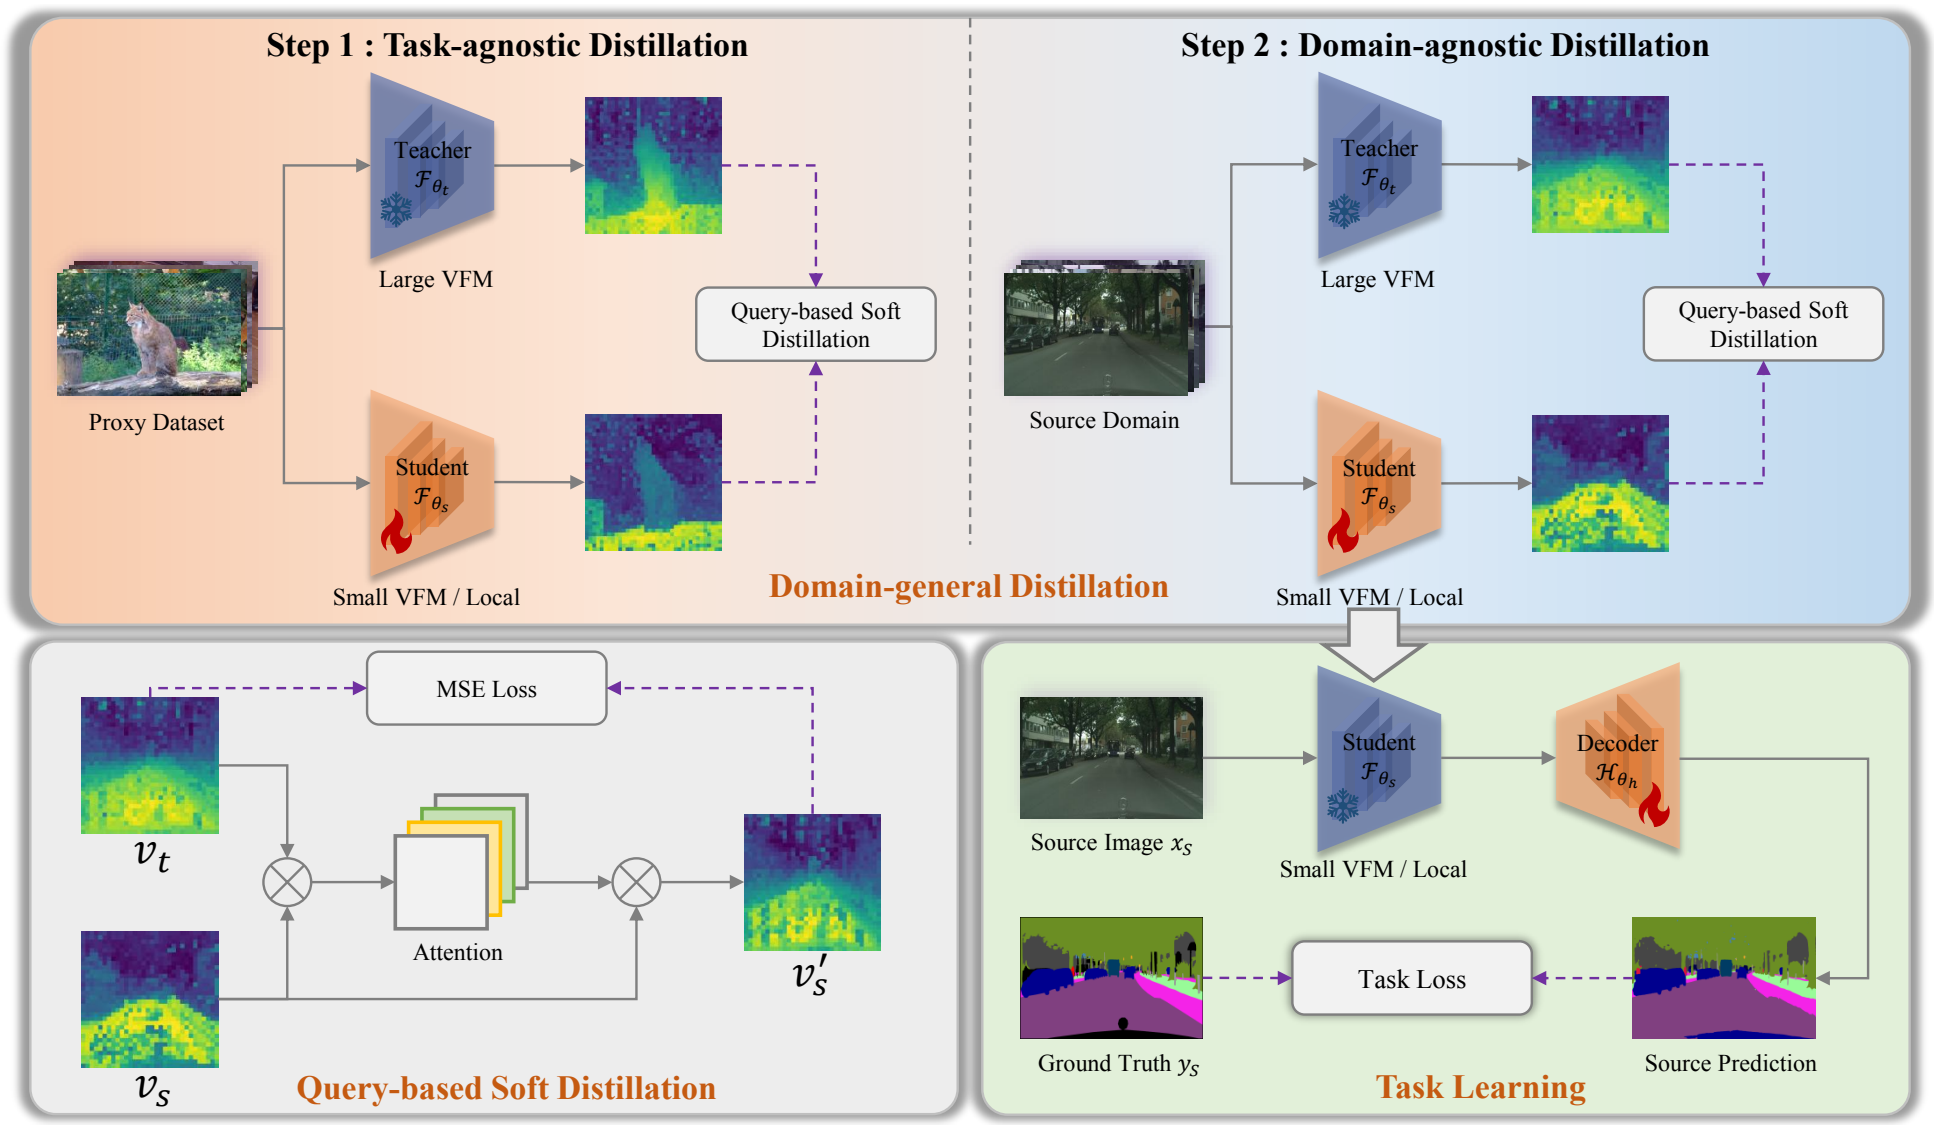
300 dpi PNG · 图注 · 源PDF
图4及方法3.3明确给出GKD整体框架,包括两步蒸馏、QSD和任务学习的完整关系。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-03;arXiv v1:2026-03-03;arXiv v1 fixed source
固定arXiv v1作为本次采集原件;v1图形直接取自该版本。保留会议版差异与既知S3投稿记录,不把会议日期隐藏或修改。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Nicu Sebe;59898;快照2026-10-21。
绘图工具:unknown。已读图注、引言和方法;未获得插图制作工具声明。
裁剪坐标:[72, 71, 536, 341],PDF点、左上角原点。
Figure 4. Overview of the proposed GKD framework. GKD comprises two major parts: domain-general distillation and task learning. In
the domain-general distillation stage, the student sequentially performs task-agnostic and domain-agnostic distillation, both via the Query-
based Soft Distillation mechanism. In the task learning stage, only the decoder is trained on source annotations, while the student encoder
is frozen to preserve the domain-general representations.
Generalizable Knowledge Distillation from Vision Foundation Models for Semantic Segmentation
会议:CVPR 2026 · 图源:存档 arXiv v1
Figure 1 · PDF第1页 · P13
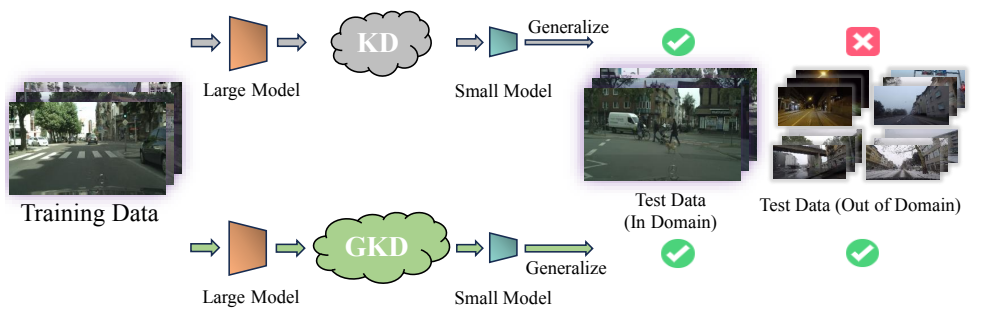
300 dpi PNG · 图注 · 源PDF
图1和引言对比KD/GKD在域内与域外数据的泛化能力,以叉号示意原方法局限;不是性能统计图2/3。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-03;arXiv v1:2026-03-03;arXiv v1 fixed source
固定arXiv v1作为本次采集原件;v1图形直接取自该版本。保留会议版差异与既知S3投稿记录,不把会议日期隐藏或修改。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Nicu Sebe;59898;快照2026-10-21。
绘图工具:unknown。已读图注、引言和方法;未获得插图制作工具声明。
裁剪坐标:[316, 260, 555, 335],PDF点、左上角原点。
Figure 1. Comparison of Knowledge Distillation (KD) and our
proposed generalizable KD (GKD). Conventional KD preserves
accuracy within the same domain but overlooks generalization to
unseen domains.
MARIS: Marine Open-Vocabulary Instance Segmentation with Geometric Enhancement and Semantic Alignment
会议:CVPR 2026 · 主会论文
Figure 3 · PDF第4页 · P114
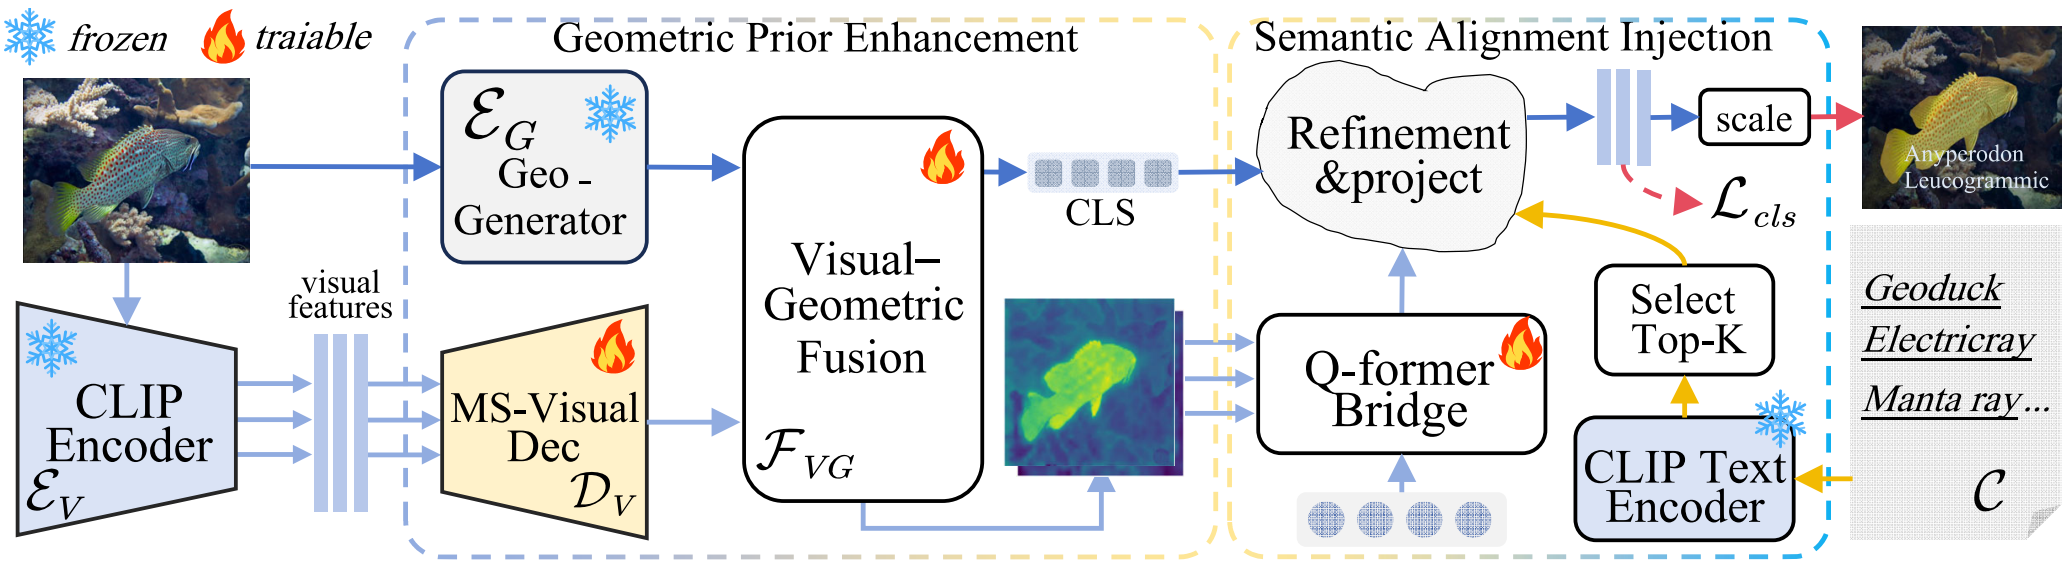
300 dpi PNG · 图注 · 源PDF
第4.2节与图3明确称整体架构,覆盖几何及视觉双编码、融合、查询细化、语义对齐与预测。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-17;arXiv v1:2025-10-17;CVPR 2026 fixed official PDF
v1/v2框架使用无衬线字体,v3改为与会议版相同的衬线字体并调整细节;采用v3公开日期2026-03-17。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Xuelong Li;102448;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 70, 554, 205.5],PDF点、左上角原点。
Figure 3. Overall framework of the proposed Method. The Geometric Prior Enhancement module strengthens structural representa-
tions via visual–geometric fusion and transformer-based query refinement. The Semantic Alignment Injection mechanism align category
semantics with degraded underwater conditions.
MARIS: Marine Open-Vocabulary Instance Segmentation with Geometric Enhancement and Semantic Alignment
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第1页 · P113
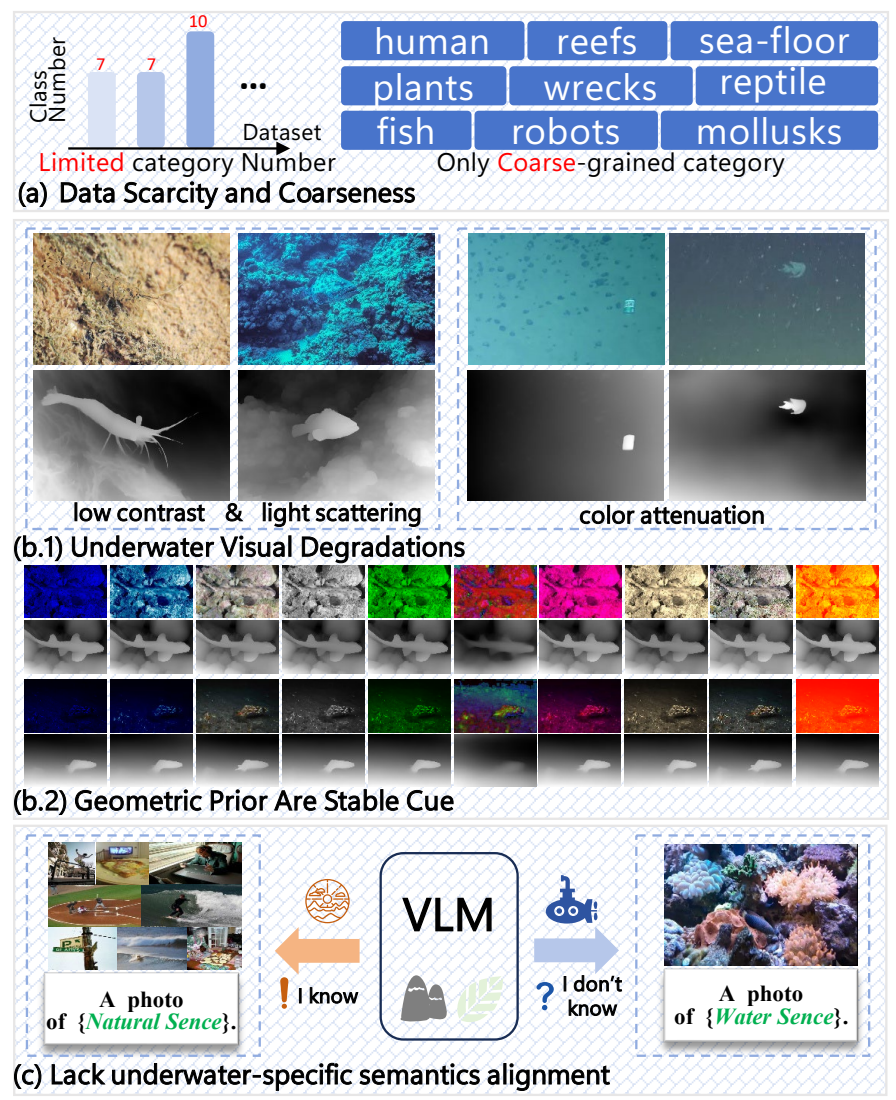
300 dpi PNG · 图注 · 源PDF
引言和图1分别解释数据稀缺、视觉退化、几何稳定性和水下语义错配,是引出研究问题的首张图。
完整图注、版本和筛选证据
最早核实视觉日期:2025-10-17;arXiv v1:2025-10-17;CVPR 2026 fixed official PDF
已比对v1、v2、v3;M图元素、字体、颜色与布局在v1已出现,仅在页面中纵向移动23.942pt;保存v1对应裁图,F则另用v3。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Xuelong Li;102448;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[326, 240, 541, 504],PDF点、左上角原点。
Figure 1. The challenges of transferring OV instance segmen-
tation to underwater scenarios in terms of (a) datasets and (b-c)
methods, which have motivated the contributions of this study.
Make It Up: Fake Images, Real Gains in Generalized Few-shot Semantic Segmentation
来源:arXiv 2026 · 图源:存档 arXiv v1
Figure 2 · PDF第4页 · P296
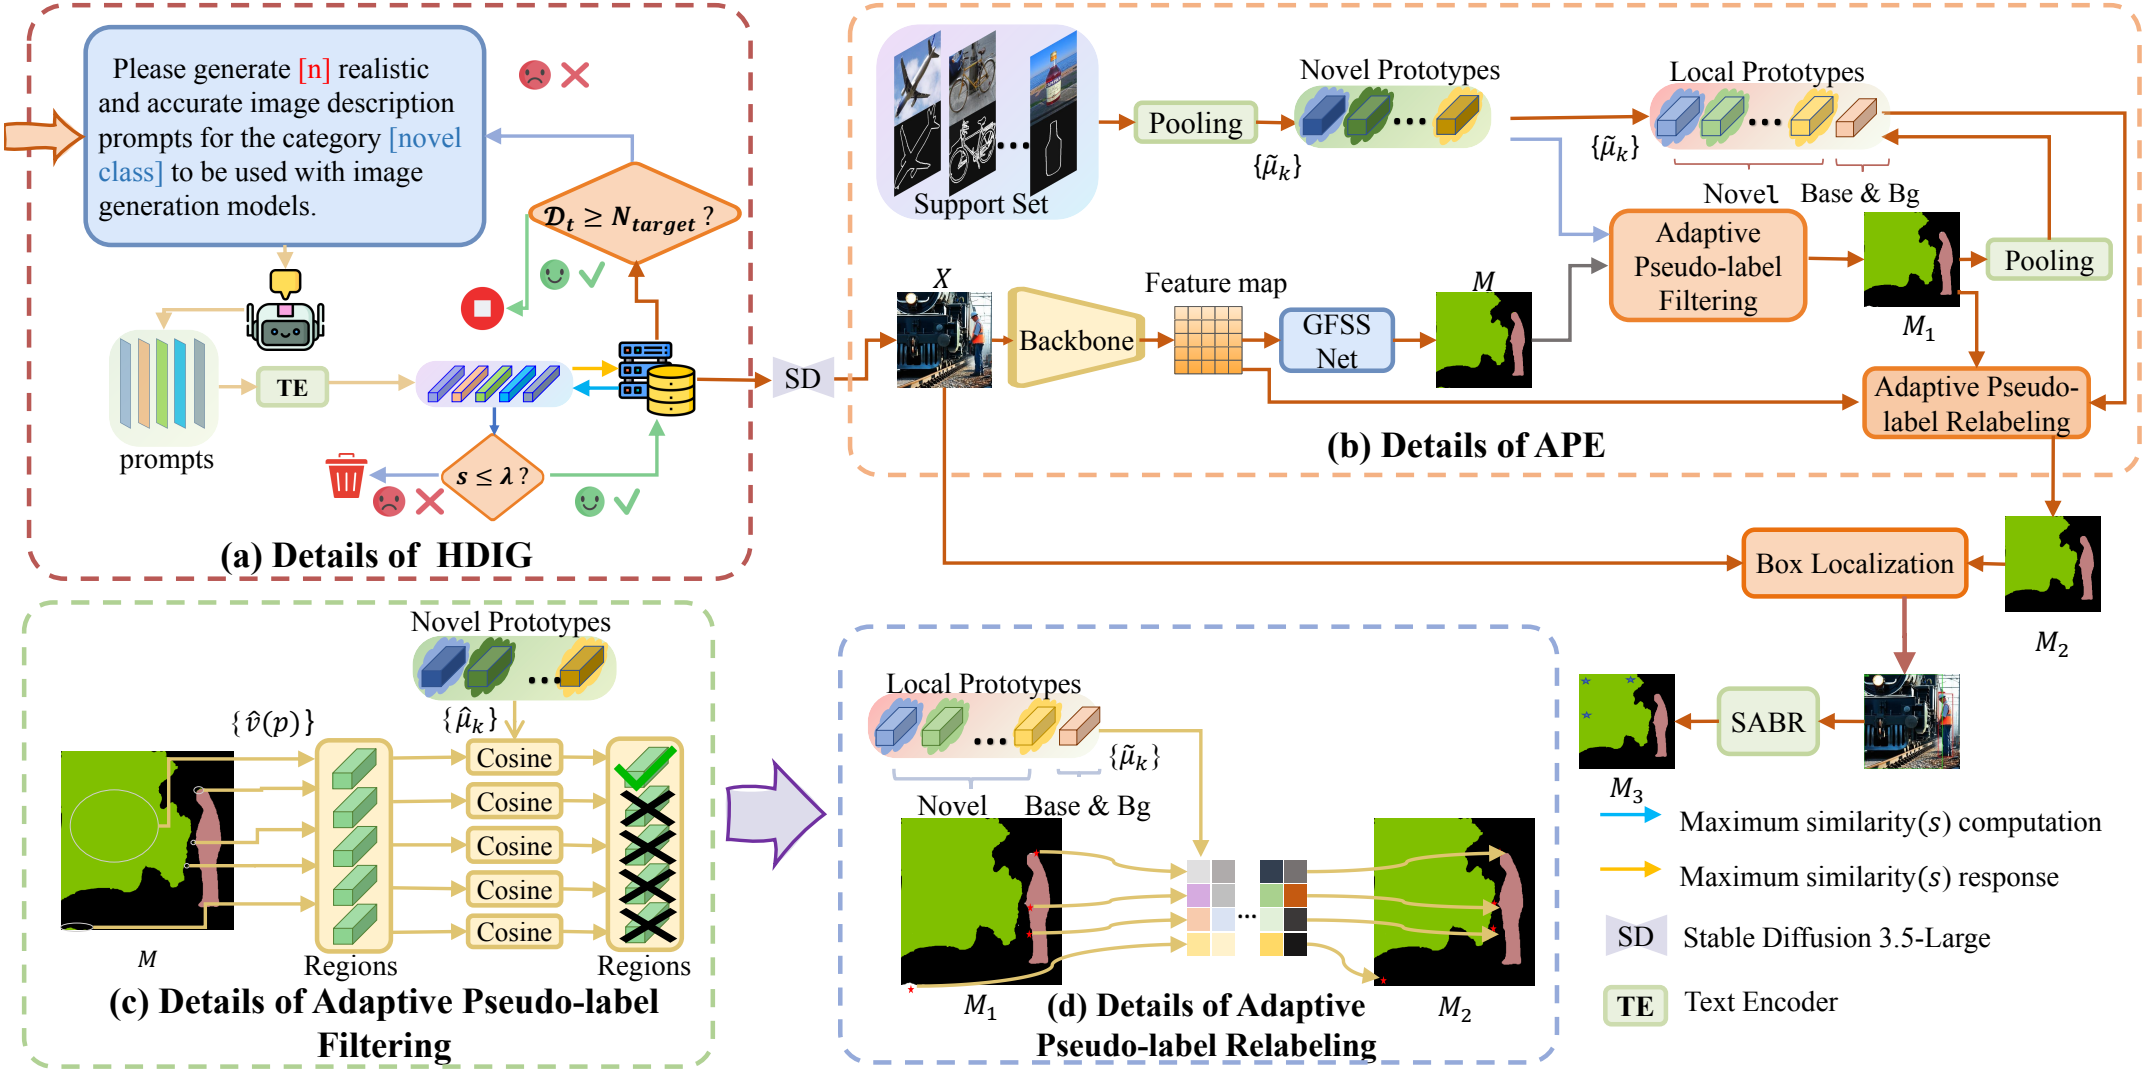
300 dpi PNG · 图注 · 源PDF
图2覆盖Syn4Seg的完整核心计算路径:HDIG图像生成、APE伪标注过滤/重标、SAM边界精修;保留四个子图,不仅截单个模块。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-28;arXiv v1:2026-03-28;arXiv v1 fixed
已打开完整v1源PDF并读图注、引言和方法引用段;逐张检查导出图。SegEarth-OV3固定2025-12-09 v1,后续2026-04-22 v2不用于本样本;作者Deyu Meng的西安交大身份与公开引用主页一致。Syn4Seg作者Ming-Ming Cheng的南开身份与公开引用主页一致。实际作图日期unknown。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Ming-Ming Cheng;85763;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[48, 56, 565, 313],PDF点、左上角原点。
Fig. 2. (a), (b) Given several novel classes and their support set, we first use HDIG to synthesize high-quality, diverse novel class images proportional to the
base class images. Guided by support images, APE refines these synthesized images to generate accurate masks through two stages: Adaptive Pseudo-label
Filtering (APF) and Adaptive Pseudo-label Relabeling (APR). Specifically, APF filters noisy regions in the initial mask M to obtain M1 ; APR relabels these
unlabeled regions to yield M2 . Finally, SAM-based Boundary Refinement (SABR) further refines the mask boundaries, yielding the final M3 . (c), (d) illustrate
the details of APF and APR.
Make It Up: Fake Images, Real Gains in Generalized Few-shot Semantic Segmentation
来源:arXiv 2026 · 图源:存档 arXiv v1
Figure 1 · PDF第1页 · P295
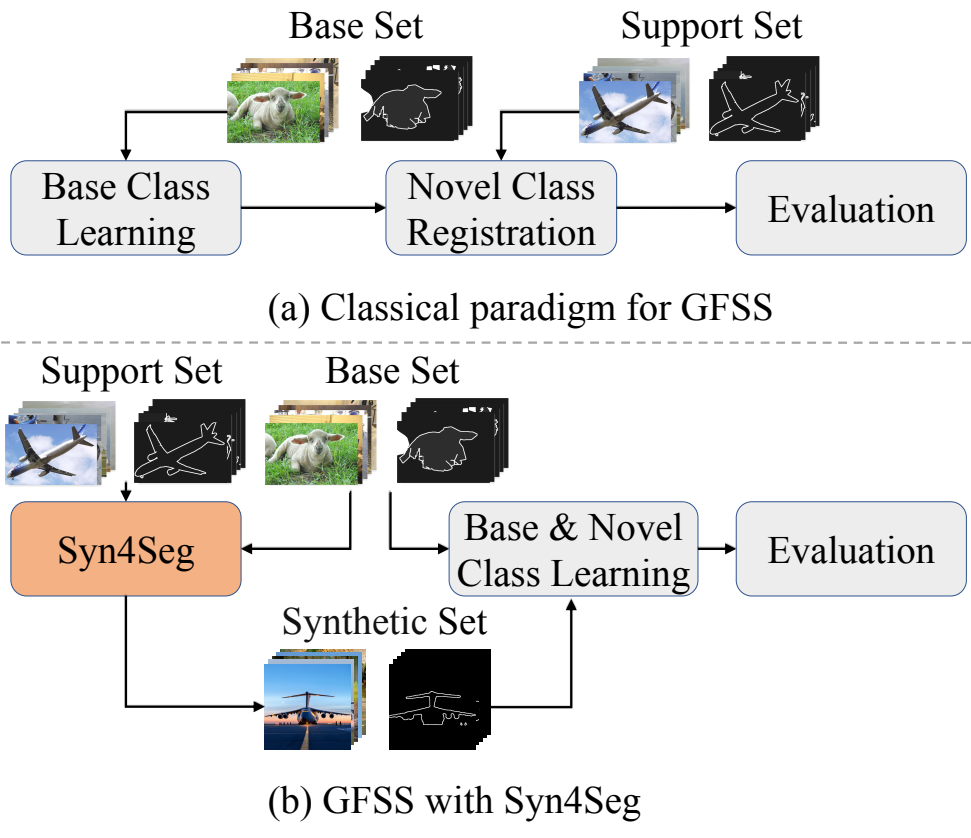
300 dpi PNG · 图注 · 源PDF
图1及引言概念对比旧GFSS依赖少量手工新类标注的多样性局限,与合成数据扩充的动机。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-28;arXiv v1:2026-03-28;arXiv v1 fixed
已打开完整v1源PDF并读图注、引言和方法引用段;逐张检查导出图。SegEarth-OV3固定2025-12-09 v1,后续2026-04-22 v2不用于本样本;作者Deyu Meng的西安交大身份与公开引用主页一致。Syn4Seg作者Ming-Ming Cheng的南开身份与公开引用主页一致。实际作图日期unknown。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Ming-Ming Cheng;85763;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[321, 176, 554, 377],PDF点、左上角原点。
Fig. 1. Pipelines of classical GFSS works and our Syn4Seg framework.
(a) Classical GFSS methods follow three stages: base class learning, novel
class registration, and evaluation, where novel classes rely on limited manual
annotations, resulting in low diversity and constrained performance. (b) Our
Syn4Seg framework synthesizes diverse, realistic novel class images and
pseudo labels guided by support annotations. These synthesized samples,
together with base data, are used to train a semantic segmentation model,
enabling robust recognition of both base and novel classes during evaluation.
PEARL: Geometry Aligns Semantics for Training-Free Open-Vocabulary Semantic Segmentation
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第4页 · P12
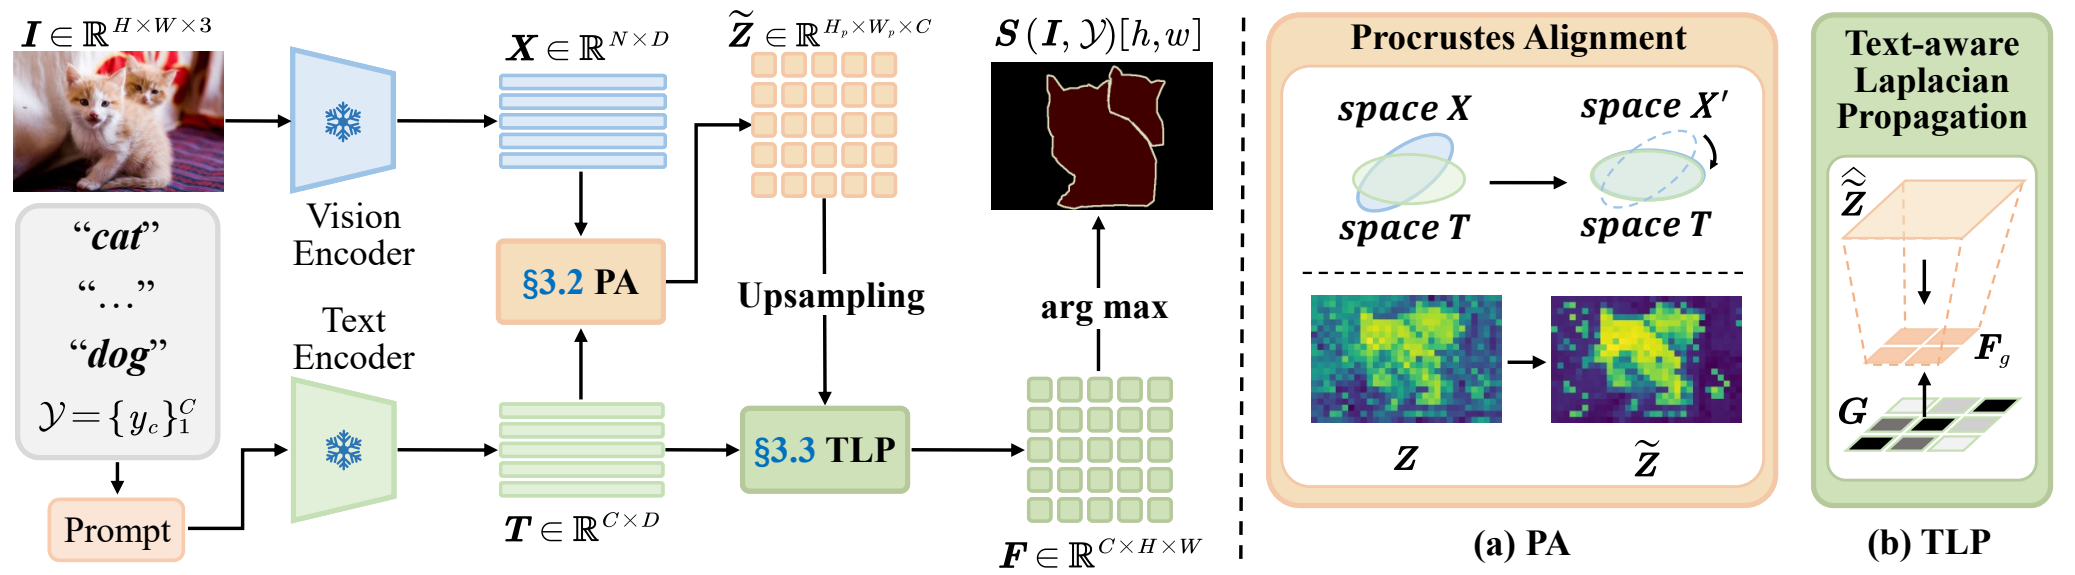
300 dpi PNG · 图注 · 源PDF
图2明确为PEARL framework,完整展示图像/文本编码、PA、TLP、上采样和argmax,含两个细节子图。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-23;arXiv v1:2026-03-23;CVPR 2026 fixed official PDF
已打开arXiv v1(2026-03-23)及固定CVPR 2026图2。完整裁图逐像素匹配(MAE=0),主流程及PA/TLP子图均一致。已核查CVPR 2026投稿窗口同为S3。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Byeungwoo Jeon;11367;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[57, 70, 555, 208],PDF点、左上角原点。
Figure 2. Our PEARL framework with align-then-propagate. Given an image I and a label set Y , a frozen ViT vision encoder yields
patch tokens. Procrustes alignment is inserted in the last self-attention block: for each head (J heads), queries and keys are weighted-
centered and the keys are orthogonally rotated toward the query subspace, producing geometry-corrected patch features. A frozen text
encoder maps Y to unit-norm prototypes T . Patch-text cosine similarity gives initial logits Z(cid:101) . Text-aware Laplacian propagation then
refines Z(cid:101) on a compact grid using a class graph G induced by T and confidence weights, and the refined scores are upsampled to full
resolution F . The final segmentation S is obtained by selecting, at each pixel, the class with the highest score.
PEARL: Geometry Aligns Semantics for Training-Free Open-Vocabulary Semantic Segmentation
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第1页 · P11
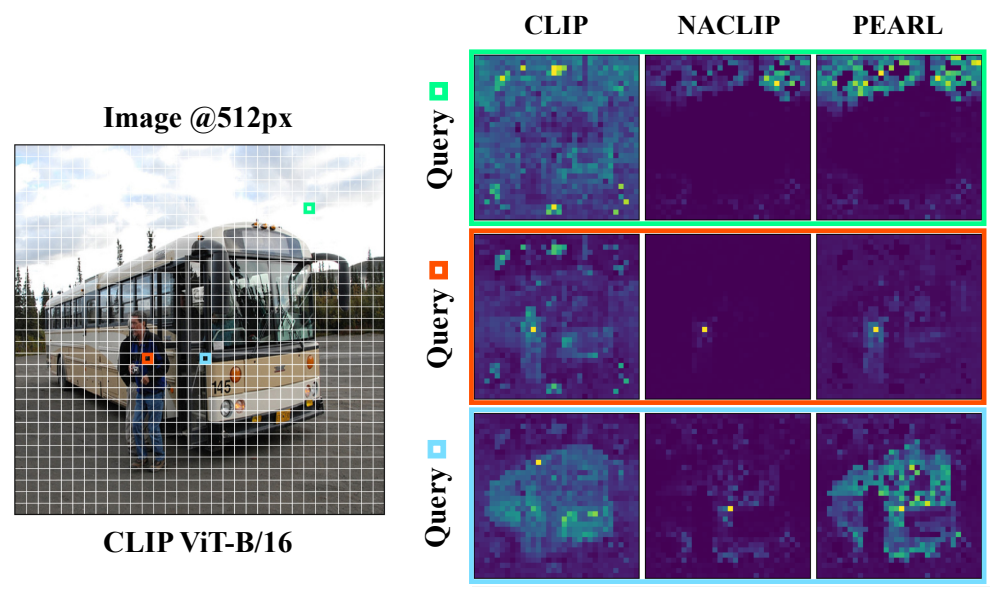
300 dpi PNG · 图注 · 源PDF
图1及引言说明CLIP背景偏置和NACLIP将目标分裂为孤立峰值的失败机制,用注意力图引出跨模态几何问题;不是普通最终分割结果。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-23;arXiv v1:2026-03-23;CVPR 2026 fixed official PDF
已打开arXiv v1(2026-03-23)及固定CVPR 2026图1。完整裁图逐像素匹配(MAE=0),注意力图及所有标签一致。已核查CVPR 2026投稿窗口2025-10-16至2025-11-14 UTC,均为S3。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Byeungwoo Jeon;11367;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[316, 258, 555, 400],PDF点、左上角原点。
Figure 1. Attention visualization at selected query points. We
show an input resized to 512 × 512 using the CLIP ViT-B/16 vi-
sion encoder. For each colored query, we compare the attention
maps produced by CLIP [51], NACLIP [26], and our PEARL.
CLIP exhibits diffuse and background-biased responses, while
NACLIP improves localization but often fragments objects into
isolated peaks. By performing Procrustes alignment in the last
self-attention block, PEARL yields compact and object-consistent
attention, suppresses background spill, and better preserves thin
parts, resulting in stable focus with reduced grid artifacts.
REL-SF4PASS: Panoramic Semantic Segmentation with REL Depth Representation and Spherical Fusion
来源:arXiv 2026 · 图源:存档 arXiv v1 · CVPR 2026 — 另有会议版本
Figure 2 · PDF第3页 · P224
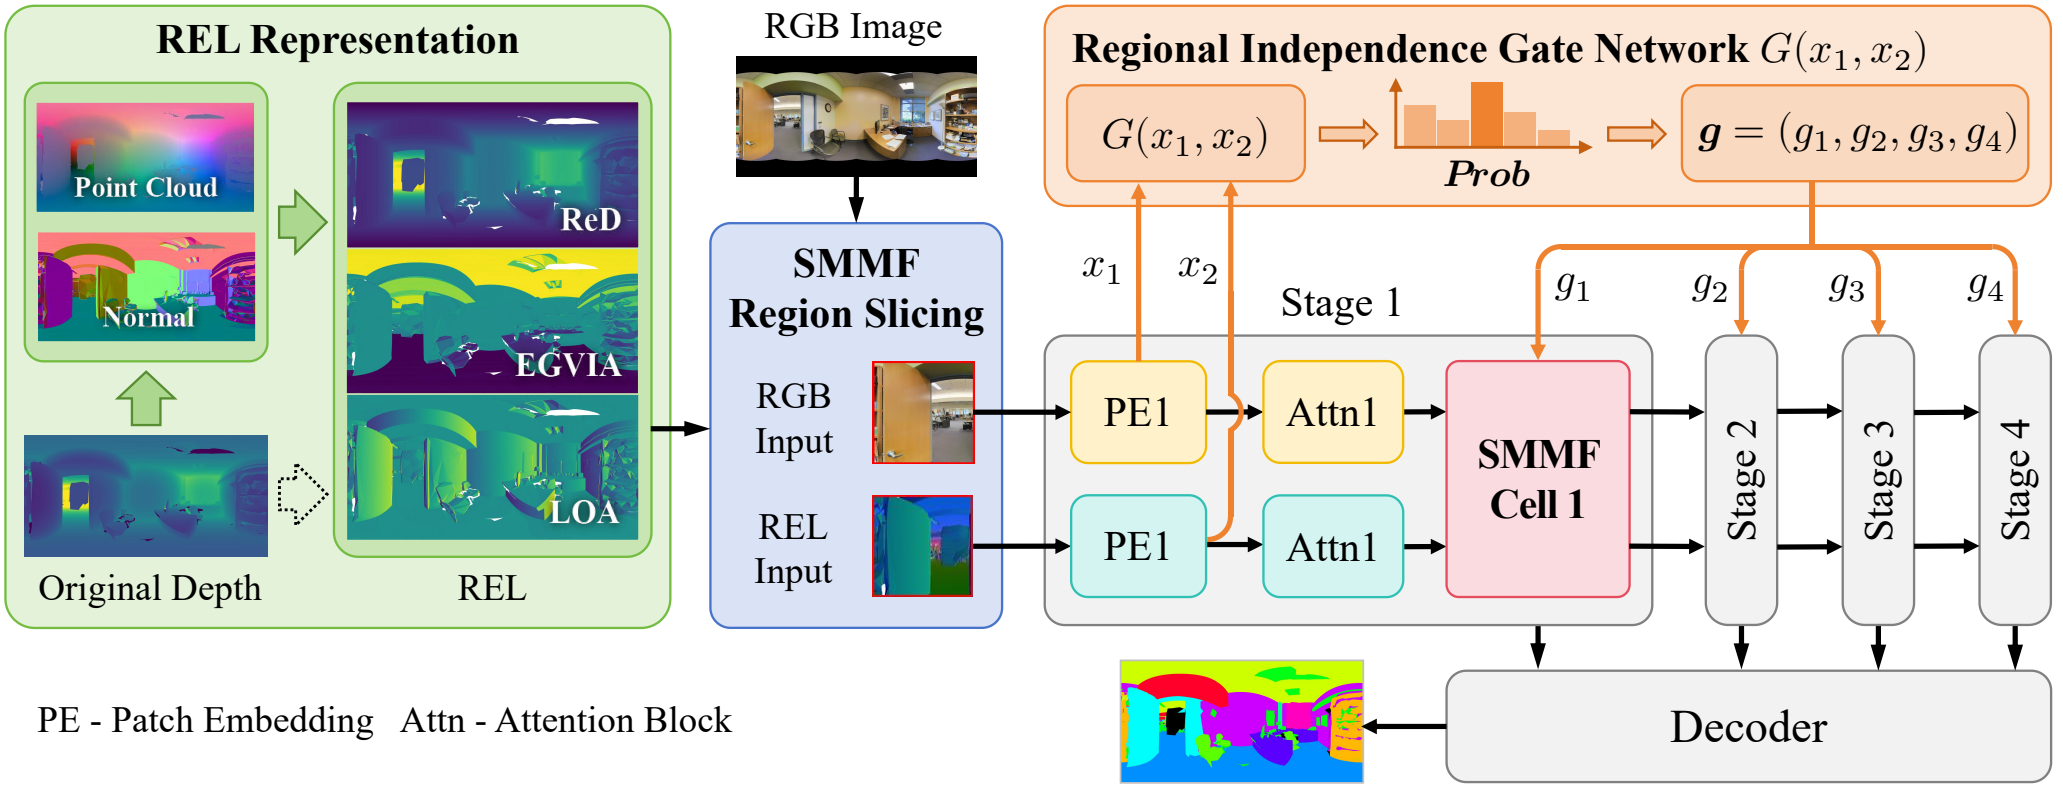
300 dpi PNG · 图注 · 源PDF
图2与第3节明确为overall pipeline,含REL表示、区域切片、门控网络、多阶段融合和解码输出。
完整图注、版本和筛选证据
最早核实视觉日期:2026-01-23;arXiv v1:2026-01-23;arXiv v1 fixed
固定采用2026-01-23 arXiv v1;会议图1把Roughly Collinearity改为Rough Collinearity并微调子图比例,故不把会议视觉套用v1时间。v1两图已逐张对照,完整矢量裁剪与300dpi PNG已目检。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Xi Li;19440;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[59, 74, 554, 263],PDF点、左上角原点。
Figure 2. The overview of REL-SF4PASS. Firstly, REL representation effectively represents the depth information by using ReD, EGVIA,
and LOA, which contains the 3D location and surface normal direction. Secondly, Our SMMF to get image regions from cylinder side
surface and uses a Gate Network to independently determine the fusion used in each region.
REL-SF4PASS: Panoramic Semantic Segmentation with REL Depth Representation and Spherical Fusion
来源:arXiv 2026 · 图源:存档 arXiv v1 · CVPR 2026 — 另有会议版本
Figure 1 · PDF第1页 · P223
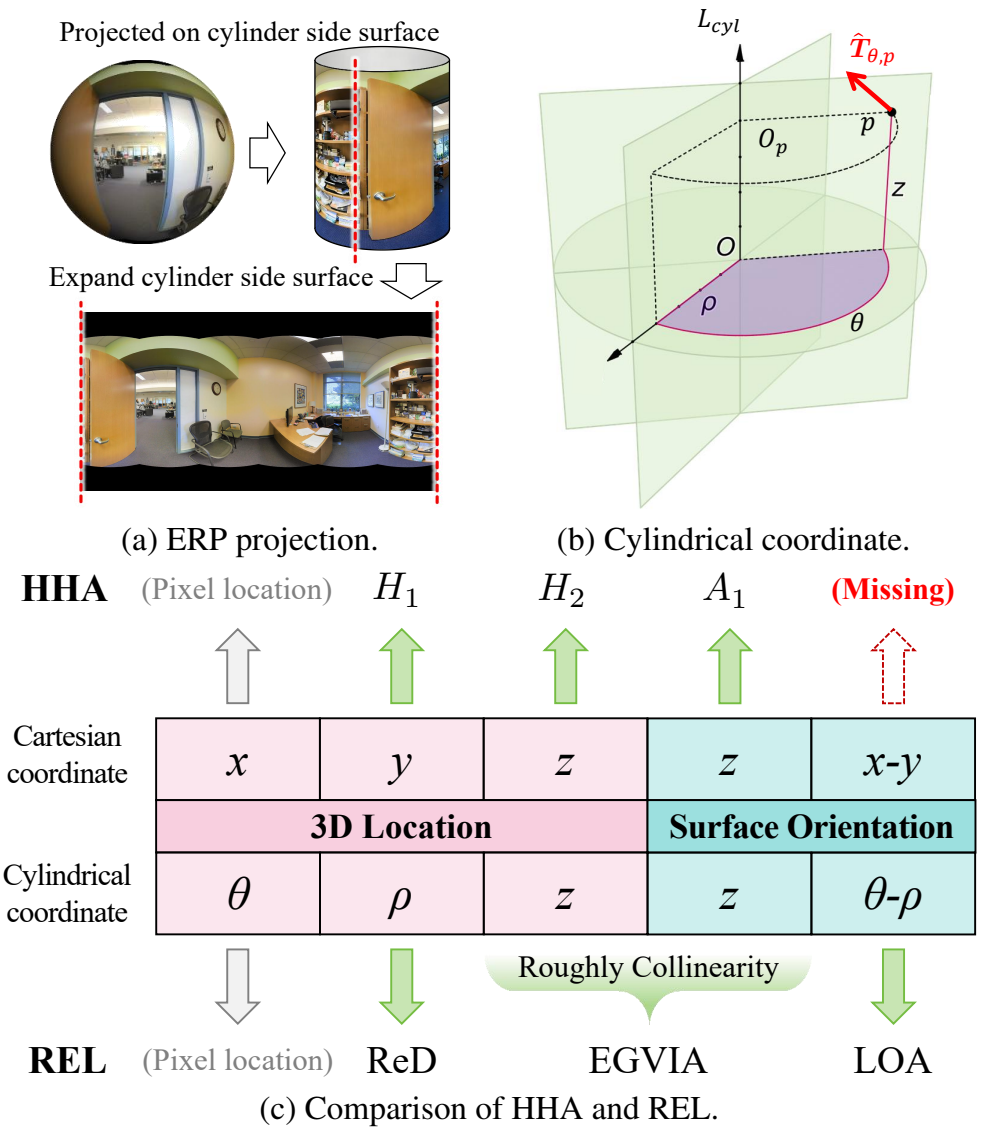
300 dpi PNG · 图注 · 源PDF
图1和引言对比HHA与REL的信息表示,红色Missing指出HHA缺少表面法线一个自由度,结合ERP及柱坐标示意引出全景表示问题。
完整图注、版本和筛选证据
最早核实视觉日期:2026-01-23;arXiv v1:2026-01-23;arXiv v1 fixed
固定采用2026-01-23 arXiv v1;会议图1把Roughly Collinearity改为Rough Collinearity并微调子图比例,故不把会议视觉套用v1时间。v1两图已逐张对照,完整矢量裁剪与300dpi PNG已目检。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Xi Li;19440;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[318, 231, 554, 504],PDF点、左上角原点。
Figure 1. Overview of ERP projection, cylindrical coordinate and
comparison of HHA and REL. Tˆ is the tangent line to circle O
θ,p p
at point p. Circle O lies in the plane perpendicular to gravity,
p
passes through point p, and its center lies on the cylindrical axis
L of ρθz . In (c), we compared how different structure informa-
cyl
tion are represented in REL and HHA.
Rewis3d: Reconstruction Improves Weakly-Supervised Semantic Segmentation
会议:CVPR 2026 · 主会论文
Figure 3 · PDF第3页 · P06
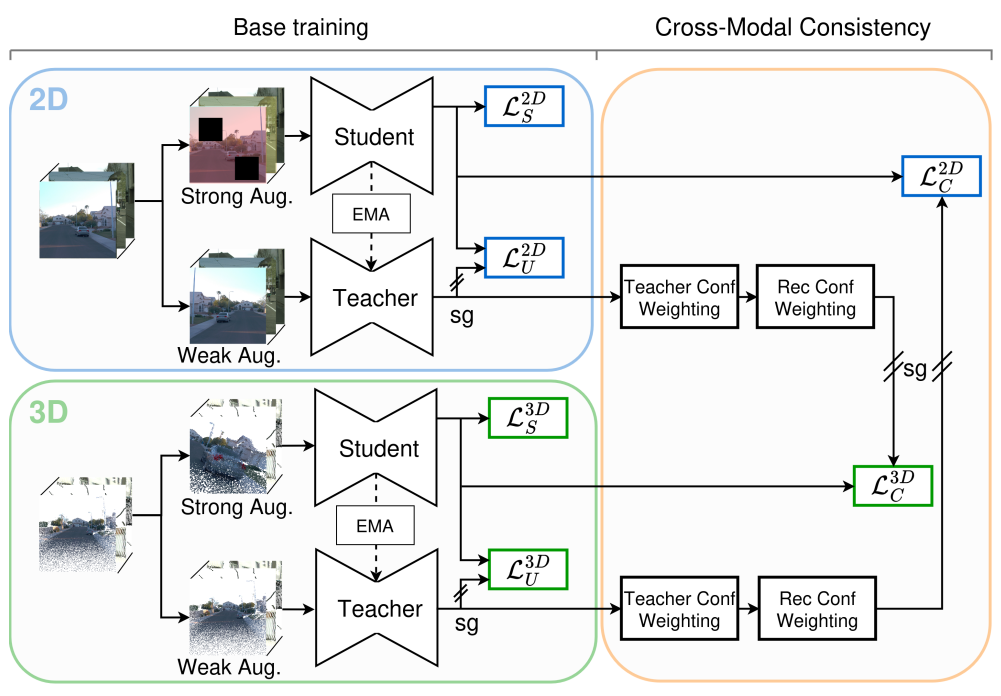
300 dpi PNG · 图注 · 源PDF
图注及正文 3.1 Framework Overview 明确描述二维/三维双师生分支和跨模态一致性训练,是整体训练流程。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-06;arXiv v1:2026-03-06;CVPR 2026 main-conference fixed open-access version
arXiv历史仅列v1;第3页图3与CVPR固定版相同区域渲染逐像素一致(MAE=0)。原PDF该完整框架本身为位图,裁剪PDF保留原位图,未声称将其矢量化。 日期字段采用arXiv提交历史中的版本日期;精确公开公告时刻未单独核查,距分界均有余量。仅指已核查来源中最早证据,不证明全网首次。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Bernt Schiele;131438;快照2026-10-21。
绘图工具:unknown。已读图注和相关正文;未获得明确的该论文插图制作工具声明。方法中使用生成模型不等于制图工具披露。
裁剪坐标:[315, 72, 555, 239],PDF点、左上角原点。
Figure 3. Overview of the training pipeline. Our framework operates in two stages. Base Training (blue and green) establishes independent student-teacher setups for each modality using sparse supervision. Cross-Modal Consistency (orange) introduces our core contribution: bidirectional knowledge transfer where the teacher of one modality supervises the student of the other, weighted by our dual confidence mechanism leveraging prediction certainty and reconstruction quality.
Rewis3d: Reconstruction Improves Weakly-Supervised Semantic Segmentation
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第2页 · P05
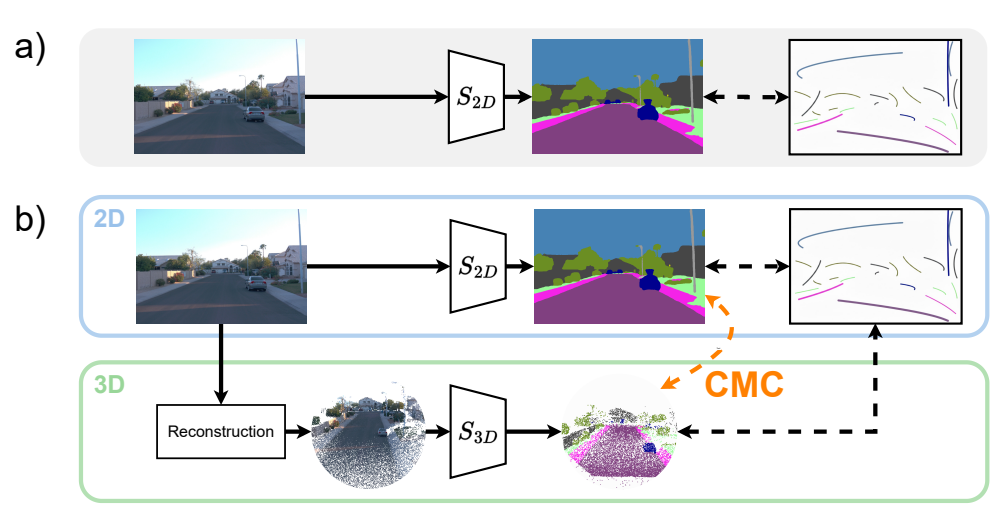
300 dpi PNG · 图注 · 源PDF
引言引用该概念对比解释纯二维稀疏监督传播受限及增加三维一致性的动机;具体训练框架另在图3,因此归 M。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-06;arXiv v1:2026-03-06;CVPR 2026 main-conference fixed open-access version
arXiv历史仅列v1;第2页图2与CVPR固定版相同区域渲染逐像素一致(MAE=0)。检查了目录、摘要历史及完整v1/会议PDF。 日期字段采用arXiv提交历史中的版本日期;精确公开公告时刻未单独核查,距分界均有余量。仅指已核查来源中最早证据,不证明全网首次。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Bernt Schiele;131438;快照2026-10-21。
绘图工具:unknown。已读图注和相关正文;未获得明确的该论文插图制作工具声明。方法中使用生成模型不等于制图工具披露。
裁剪坐标:[315, 72, 555, 195],PDF点、左上角原点。
Figure 2. Conceptual overview of weakly-supervised segmentation approaches. (a) Traditional methods rely solely on sparse 2D annotations, limiting supervision propagation. (b) Our proposed method Rewis3d introduces a 3D branch, enforcing cross-modal consistency (CMC) between 2D predictions and 3D predictions from reconstructed geometry.
SAGE: Style-Adaptive Generalization for Privacy-Constrained Semantic Segmentation Across Domains
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第4页 · P156
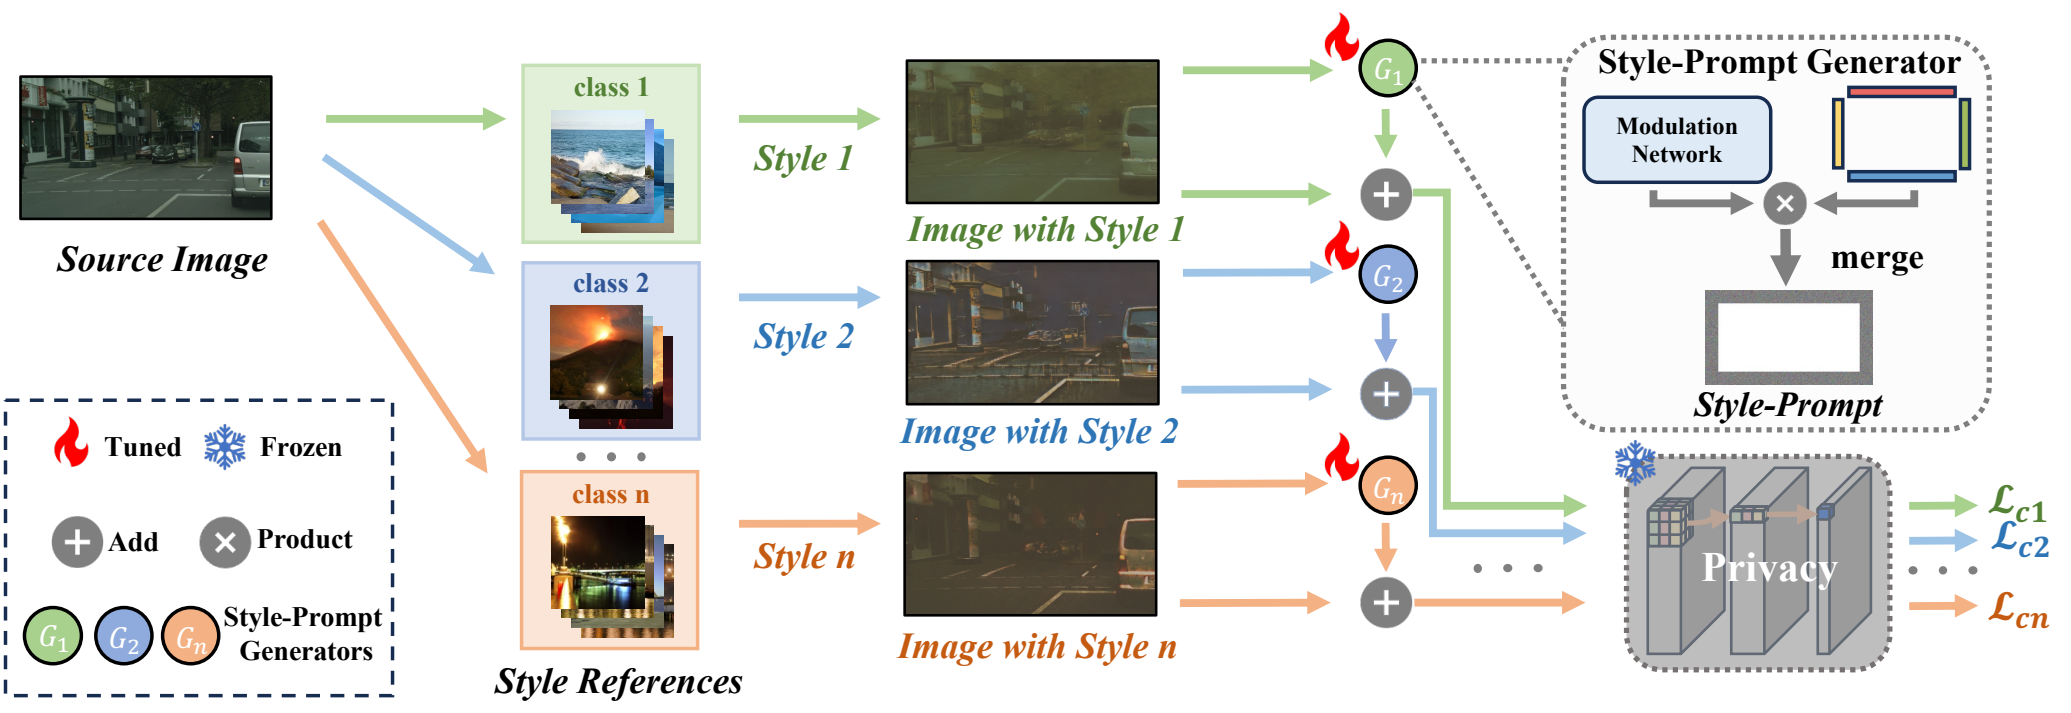
300 dpi PNG · 图注 · 源PDF
图2展示完整风格提示训练过程,从源图和多风格参考到生成器、提示融合、冻结分割模型和训练损失;右侧保留生成器内部关系。
完整图注、版本和筛选证据
最早核实视觉日期:2025-12-02;arXiv v1:2025-12-02;CVPR 2026 fixed official PDF
已对照会议固定PDF与arXiv v1目标图,构图、文字和连线一致,导出像素一致;未发现更早公开版本。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Haohuan Fu;14800;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 70, 555, 241],PDF点、左上角原点。
Figure 2. The training process of SPG: each style reference guides the source image through a dedicated generator G to produce a style-
i
aware prompt. Prompts are merged and used to optimize a frozen privacy model. Each style-prompt generator consists of a modulation
network and a learnable prompt template, producing the final style-prompt via element-wise modulation.
SAGE: Style-Adaptive Generalization for Privacy-Constrained Semantic Segmentation Across Domains
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第2页 · P155
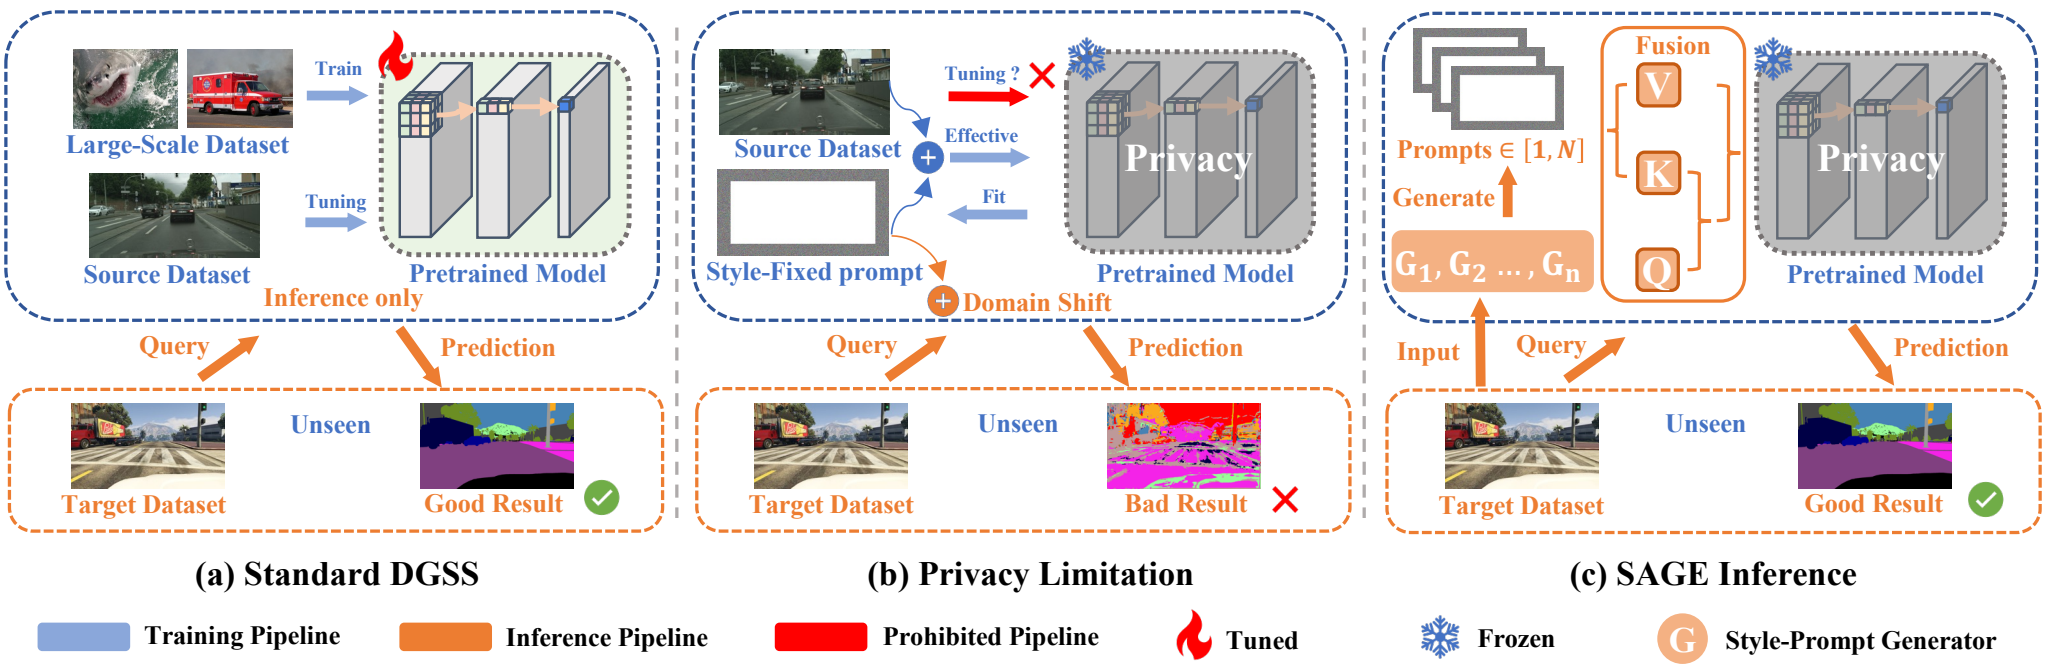
300 dpi PNG · 图注 · 源PDF
引言以图1对比标准DGSS、隐私禁止调参及固定风格提示失败,明确问题约束;不是仅报告准确率的结果图。
完整图注、版本和筛选证据
最早核实视觉日期:2025-12-02;arXiv v1:2025-12-02;CVPR 2026 fixed official PDF
已对照会议固定PDF与arXiv v1目标图,构图、文字和连线一致,导出像素一致;未发现更早公开版本。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Haohuan Fu;14800;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 70, 552, 231],PDF点、左上角原点。
Figure 1. Overview of domain generalization settings under privacy constraints. (a) Standard DGSS requires backbone tuning. (b) Style-
fixed prompting is ineffective on unseen domains. (c) SAGE inference overcomes privacy limitations.
SegEarth-OV3: Exploring SAM 3 for Open-Vocabulary Semantic Segmentation in Remote Sensing Images
来源:arXiv 2025 · 图源:存档 arXiv v1
Figure 2 · PDF第3页 · P294
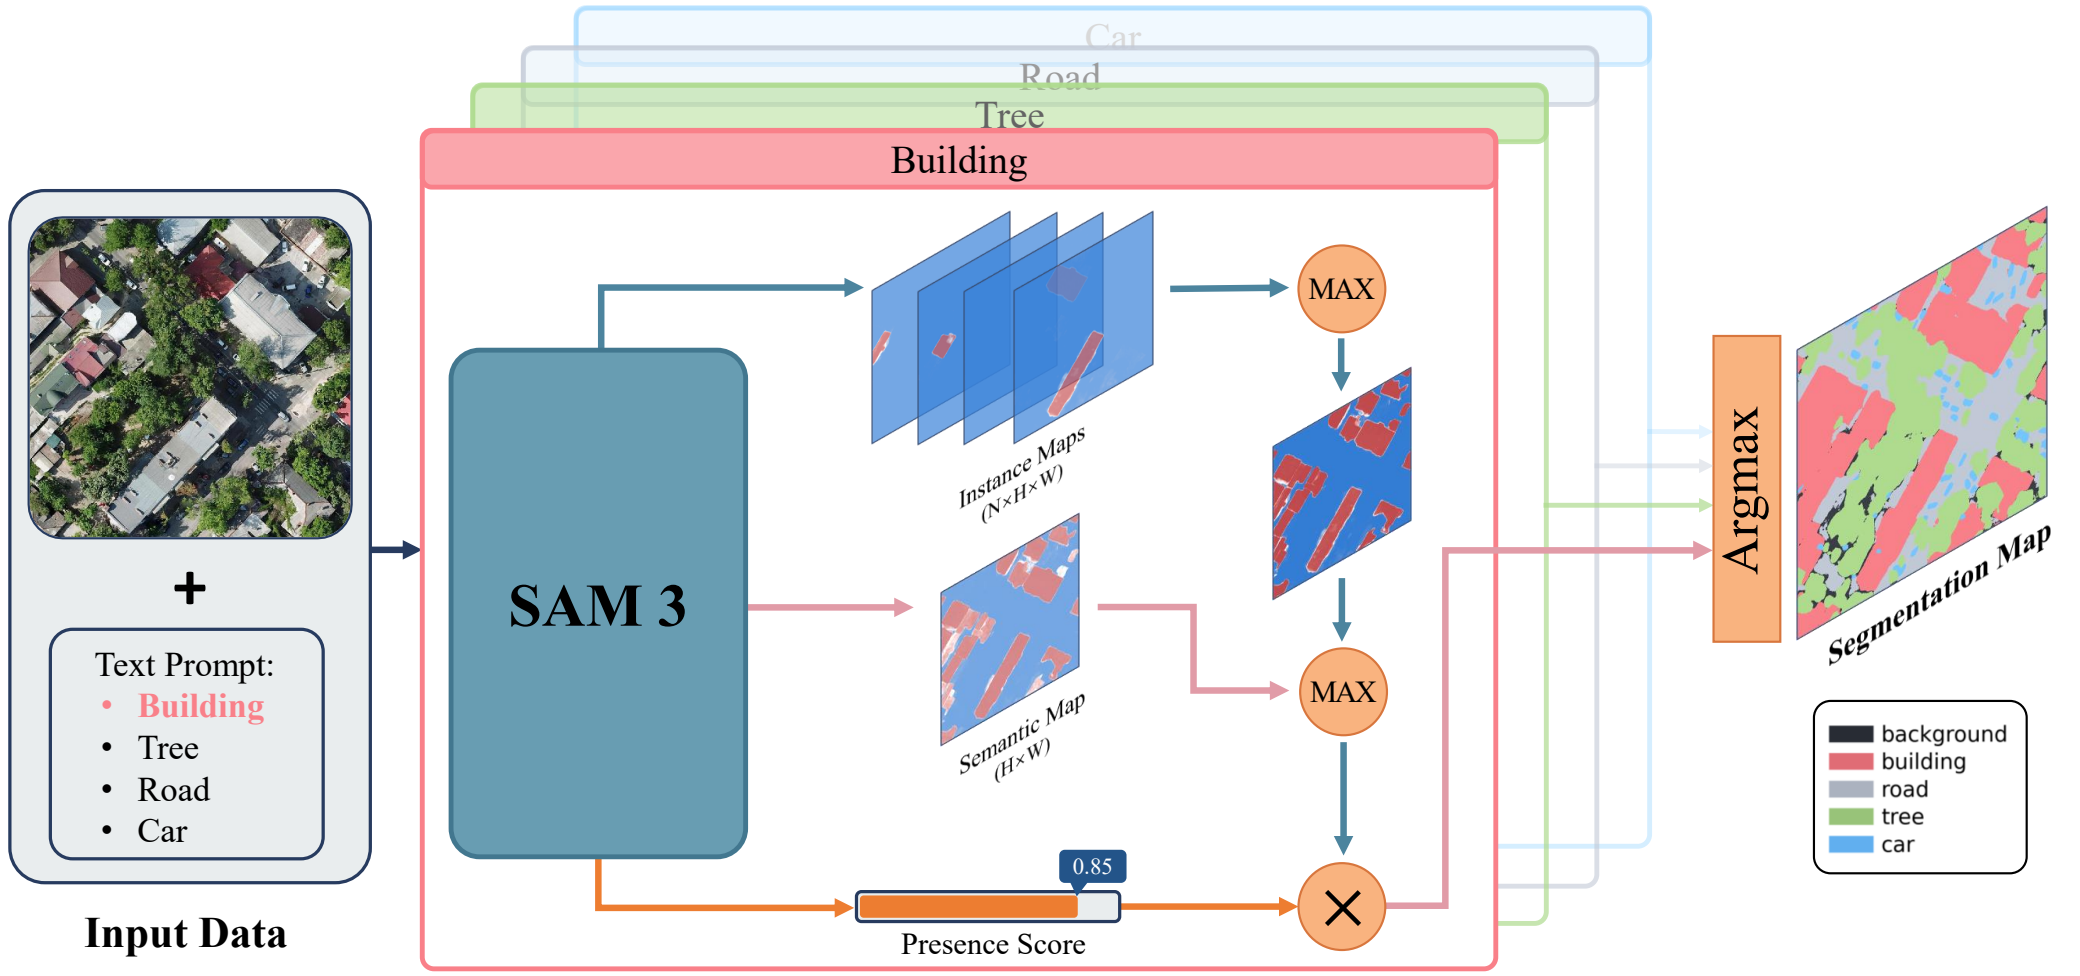
300 dpi PNG · 图注 · 源PDF
图2明确为整体推理管线,包含实例聚合、双头融合和存在分数过滤。
完整图注、版本和筛选证据
最早核实视觉日期:2025-12-09;arXiv v1:2025-12-09;arXiv v1 fixed
已打开完整v1源PDF并读图注、引言和方法引用段;逐张检查导出图。SegEarth-OV3固定2025-12-09 v1,后续2026-04-22 v2不用于本样本;作者Deyu Meng的西安交大身份与公开引用主页一致。Syn4Seg作者Ming-Ming Cheng的南开身份与公开引用主页一致。实际作图日期unknown。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Deyu Meng;49595;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[59, 73, 558, 307],PDF点、左上角原点。
Figure 2. The overall inference pipeline of SegEarth-OV3. Given an input image and a list of text prompts, we leverage SAM 3’s decoupled
outputs. The pipeline involves: (1) instance aggregation to consolidate sparse object queries; (2) dual-head mask fusion to combine the
fine-grained instance details with the global coverage of the semantic head; and (3) presence-guided filtering (using the presence score) to
suppress false positives from absent categories. denotes the element-wise maximum operation, and denotes multiplication.
SegEarth-OV3: Exploring SAM 3 for Open-Vocabulary Semantic Segmentation in Remote Sensing Images
来源:arXiv 2025 · 图源:存档 arXiv v1
Figure 1 · PDF第2页 · P293
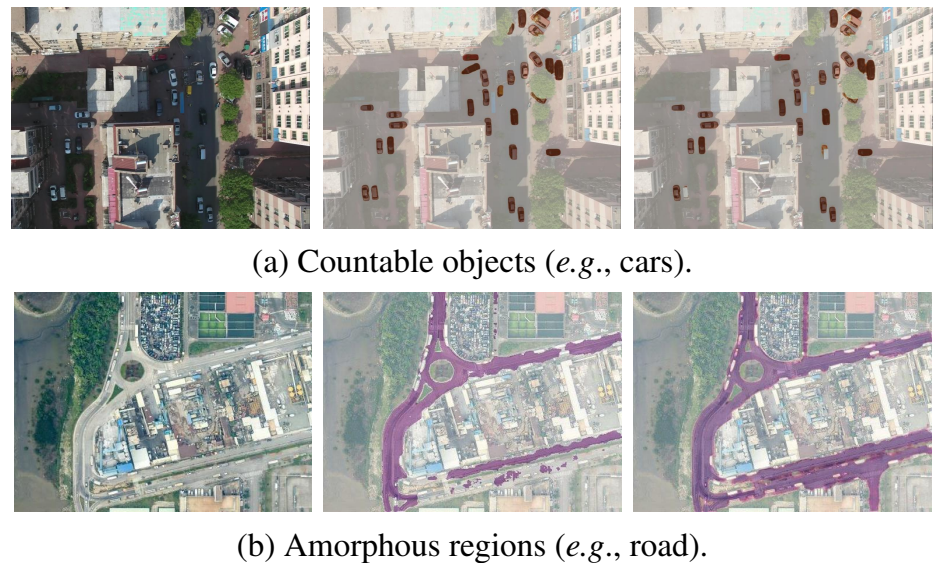
300 dpi PNG · 图注 · 源PDF
图1及引言专门诊断SAM3实例头对无定形区域碎片化、语义头对小物体边界不准的局限。
完整图注、版本和筛选证据
最早核实视觉日期:2025-12-09;arXiv v1:2025-12-09;arXiv v1 fixed
已打开完整v1源PDF并读图注、引言和方法引用段;逐张检查导出图。SegEarth-OV3固定2025-12-09 v1,后续2026-04-22 v2不用于本样本;作者Deyu Meng的西安交大身份与公开引用主页一致。Syn4Seg作者Ming-Ming Cheng的南开身份与公开引用主页一致。实际作图日期unknown。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Deyu Meng;49595;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[322, 71, 548, 206],PDF点、左上角原点。
Figure 1. The Transformer decoder of SAM 3 excels at delineat-
ing countable objects but produces fragmented masks for amor-
phous regions, while the semantic head preserves continuity for
amorphous regions but lacks boundary precision for small targets.
(Left: Remote sensing image. Middle: Prediction of Transformer
Decoder. Right: Prediction of semantic segmentation head.)
Beyond the Ground Truth: Enhanced Supervision for Image Restoration
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第3页 · P42
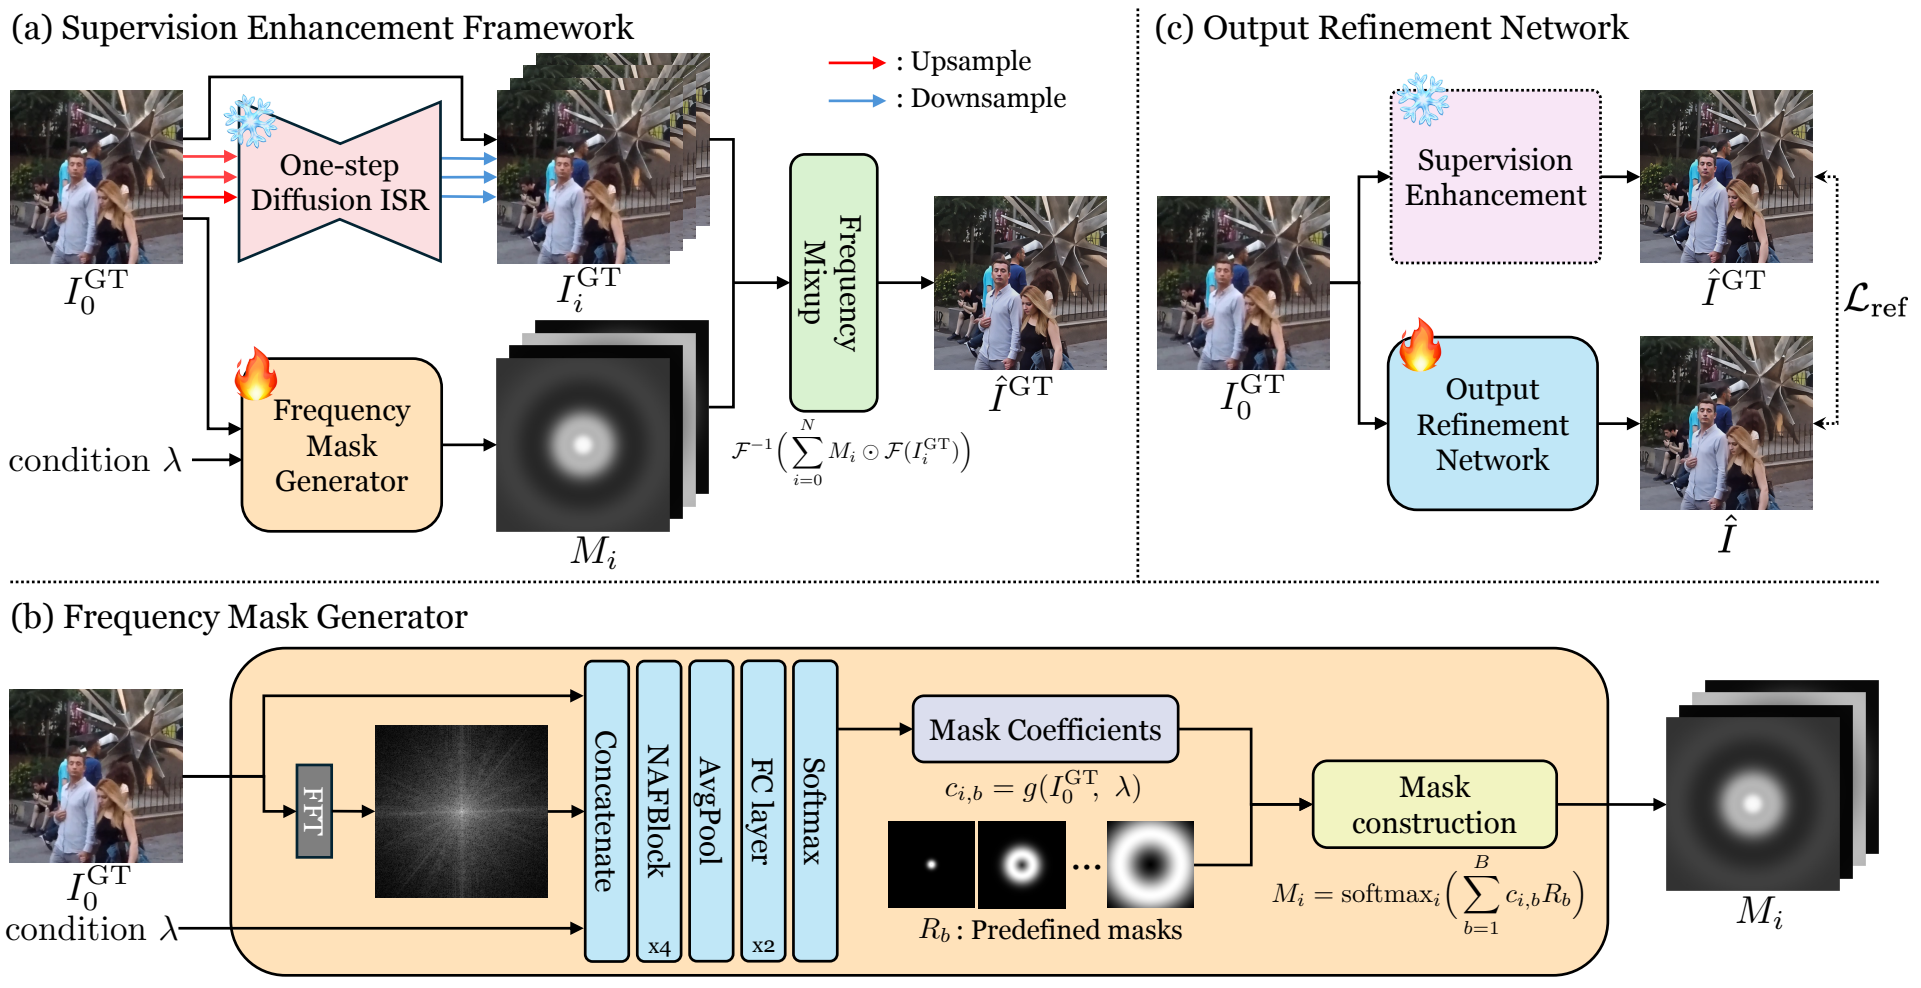
300 dpi PNG · 图注 · 源PDF
第3节及图2明确展示supervision enhancement整体框架;完整保留监督增强、频率掩码生成和输出细化三个子图。
完整图注、版本和筛选证据
最早核实视觉日期:2025-12-04;arXiv v1:2025-12-03;CVPR 2026 fixed official PDF
已查看v1、v2、v3和会议PDF:M与v1相同,仅整体下移13.948 PDF点;F在v1的公式/标签不同,v2已匹配会议视觉,使用v2日期。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Bohyung Han;31556;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[77, 73, 538, 310],PDF点、左上角原点。
Figure 2. Overview of our framework. (a) The supervision enhancement framework produces enhanced ground truth images by fusing frequency components from the original ground truth I_0^GT and its super-resolved variants I_i^GT using adaptive frequency masks M_i. (b) The conditional frequency mask generator constructs M_i by combining predefined masks R_b weighted with predicted coefficients c_{i,b}, followed by a softmax function. (c) The output refinement network (ORNet) is trained with this enhanced supervision to improve perceptual quality.Beyond the Ground Truth: Enhanced Supervision for Image Restoration
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第1页 · P41
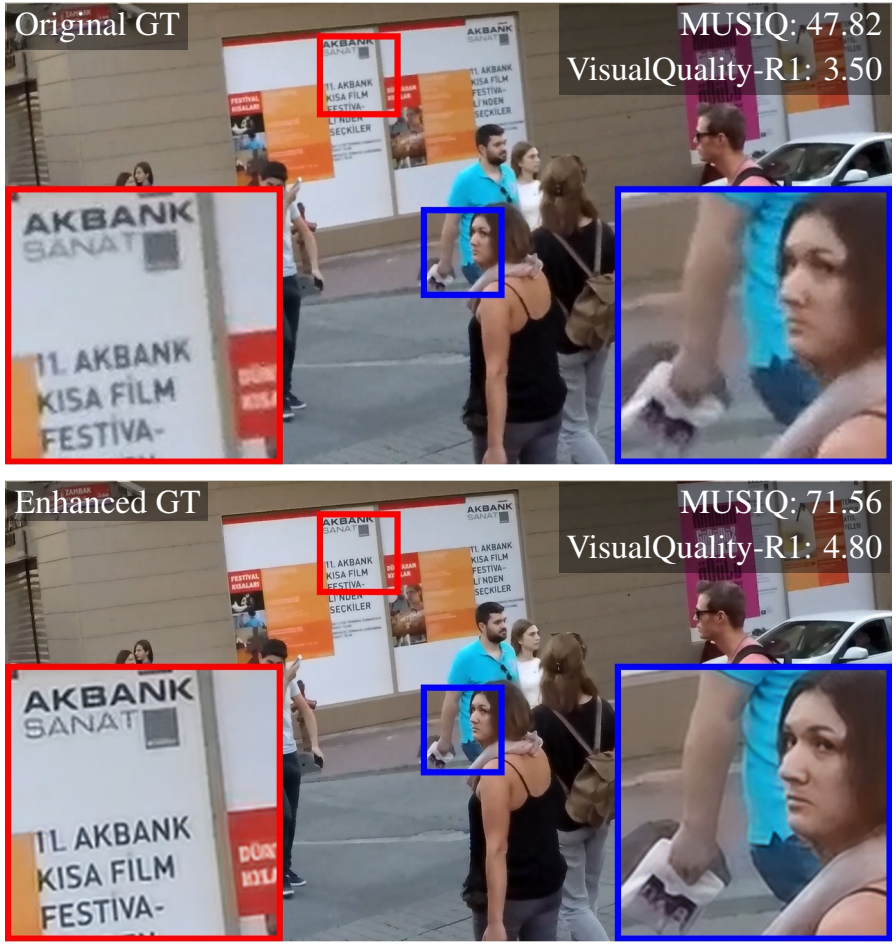
300 dpi PNG · 图注 · 源PDF
首图对照原始训练真值中的模糊文字/人脸与增强真值,结合引言明确的“原始GT质量限制复原”论证,属于监督数据局限的问题示例,不是常规多个模型结果拼图。
完整图注、版本和筛选证据
最早核实视觉日期:2025-12-03;arXiv v1:2025-12-03;CVPR 2026 fixed official PDF
已查看v1、v2、v3和会议PDF:M与v1相同,仅整体下移13.948 PDF点;F在v1的公式/标签不同,v2已匹配会议视觉,使用v2日期。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Bohyung Han;31556;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[330, 227, 545, 454],PDF点、左上角原点。
Figure 1. Visualization of our enhanced ground truth (GT). Our
enhanced GT not only demonstrates sharper text and superior per-
ceptualqualitybutalsomaintainssemanticconsistencywithrespect
to the original GT. Zoom in for better visualization.
Enhancing Unregistered Hyperspectral Image Super-Resolution via Unmixing-based Abundance Fusion Learning
会议:CVPR 2026 · 主会论文
Figure 3 · PDF第3页 · P150
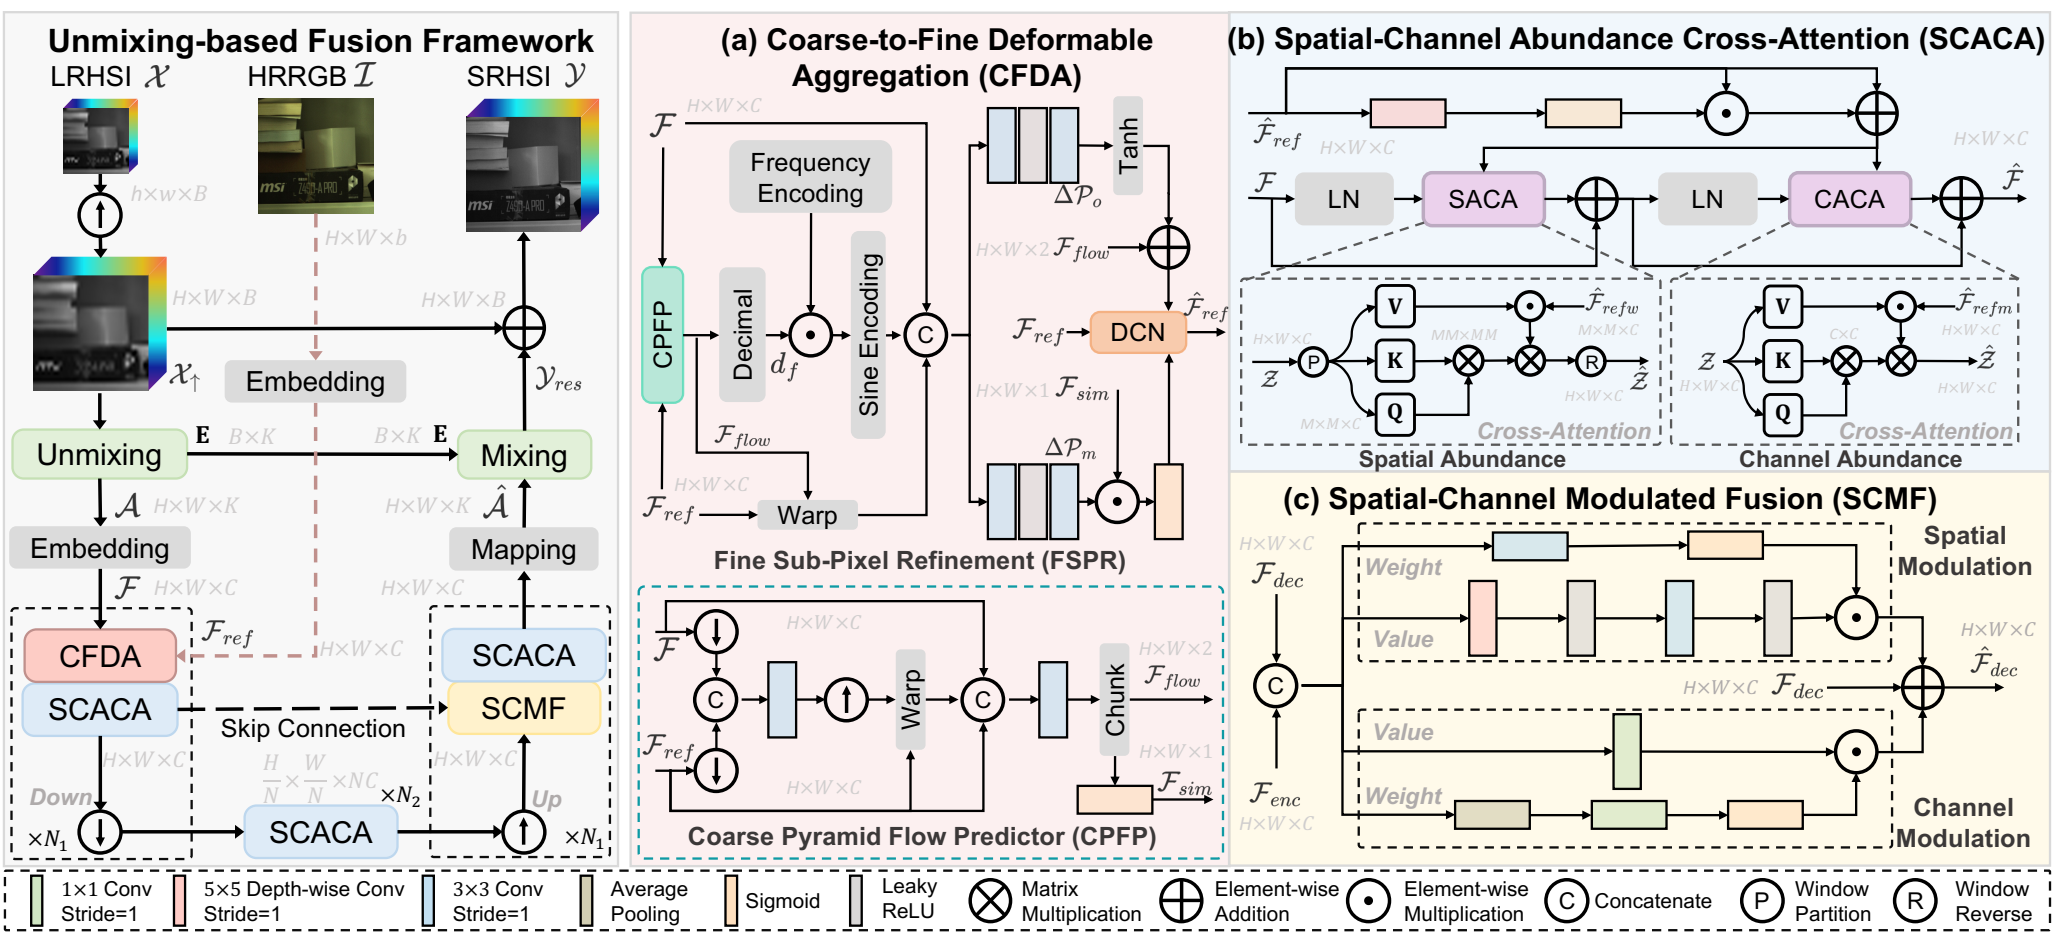
300 dpi PNG · 图注 · 源PDF
图3明确为overall architecture,包含高光谱/RGB输入、解混、编码解码、CFDA、SCACA与SCMF,以及完整图例。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-09;arXiv v1:2026-03-09;CVPR 2026 fixed official PDF
已对照会议固定PDF与arXiv v1目标图,构图、文字和连线一致,导出像素一致;未发现更早公开版本。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Ying Fu;11391;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 70, 554, 296],PDF点、左上角原点。
Figure 3. The overall architecture. We adopt a multi-scale encoder-decoder based on unmixing with several key modules: (a) Coarse-
to-Fine Deformable Aggregation module, (b) Spatial-Channel Abundance Cross-Attention module, and (c) Spatial-Channel Modulation
Fusion module to super-resolve high-quality HR HSI.
Enhancing Unregistered Hyperspectral Image Super-Resolution via Unmixing-based Abundance Fusion Learning
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第2页 · P149
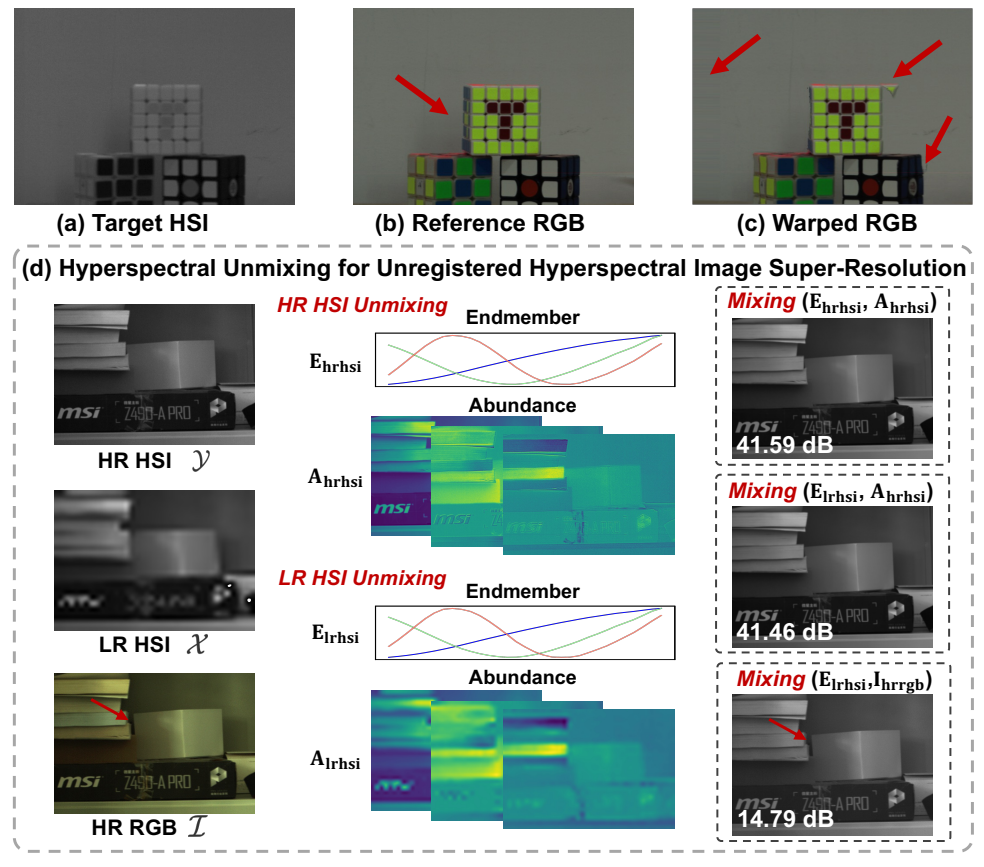
300 dpi PNG · 图注 · 源PDF
图2明确标为The motivation,展示显式配准造成的空间失真与纹理伪影,并以解混分析说明丰度对齐的意义。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-09;arXiv v1:2026-03-09;CVPR 2026 fixed official PDF
已对照会议固定PDF与arXiv v1目标图,构图、文字和连线一致,导出像素一致;未发现更早公开版本。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Ying Fu;11391;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 70, 294, 278],PDF点、左上角原点。
Figure 2. The motivation. (c) The explicit alignment within the
SSCH [53] is prone to introducing spatial distortions and textural
artifacts into the warped image. (d) The result validates the princi-
plethatleveragingawell-aligned, high-fidelityabundanceenables
the reconstruction of the HR HSI from its LR counterpart.
FinPercep-RM: A Fine-grained Reward Model and Co-evolutionary Curriculum for RL-based Real-world Super-Resolution
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第4页 · P120
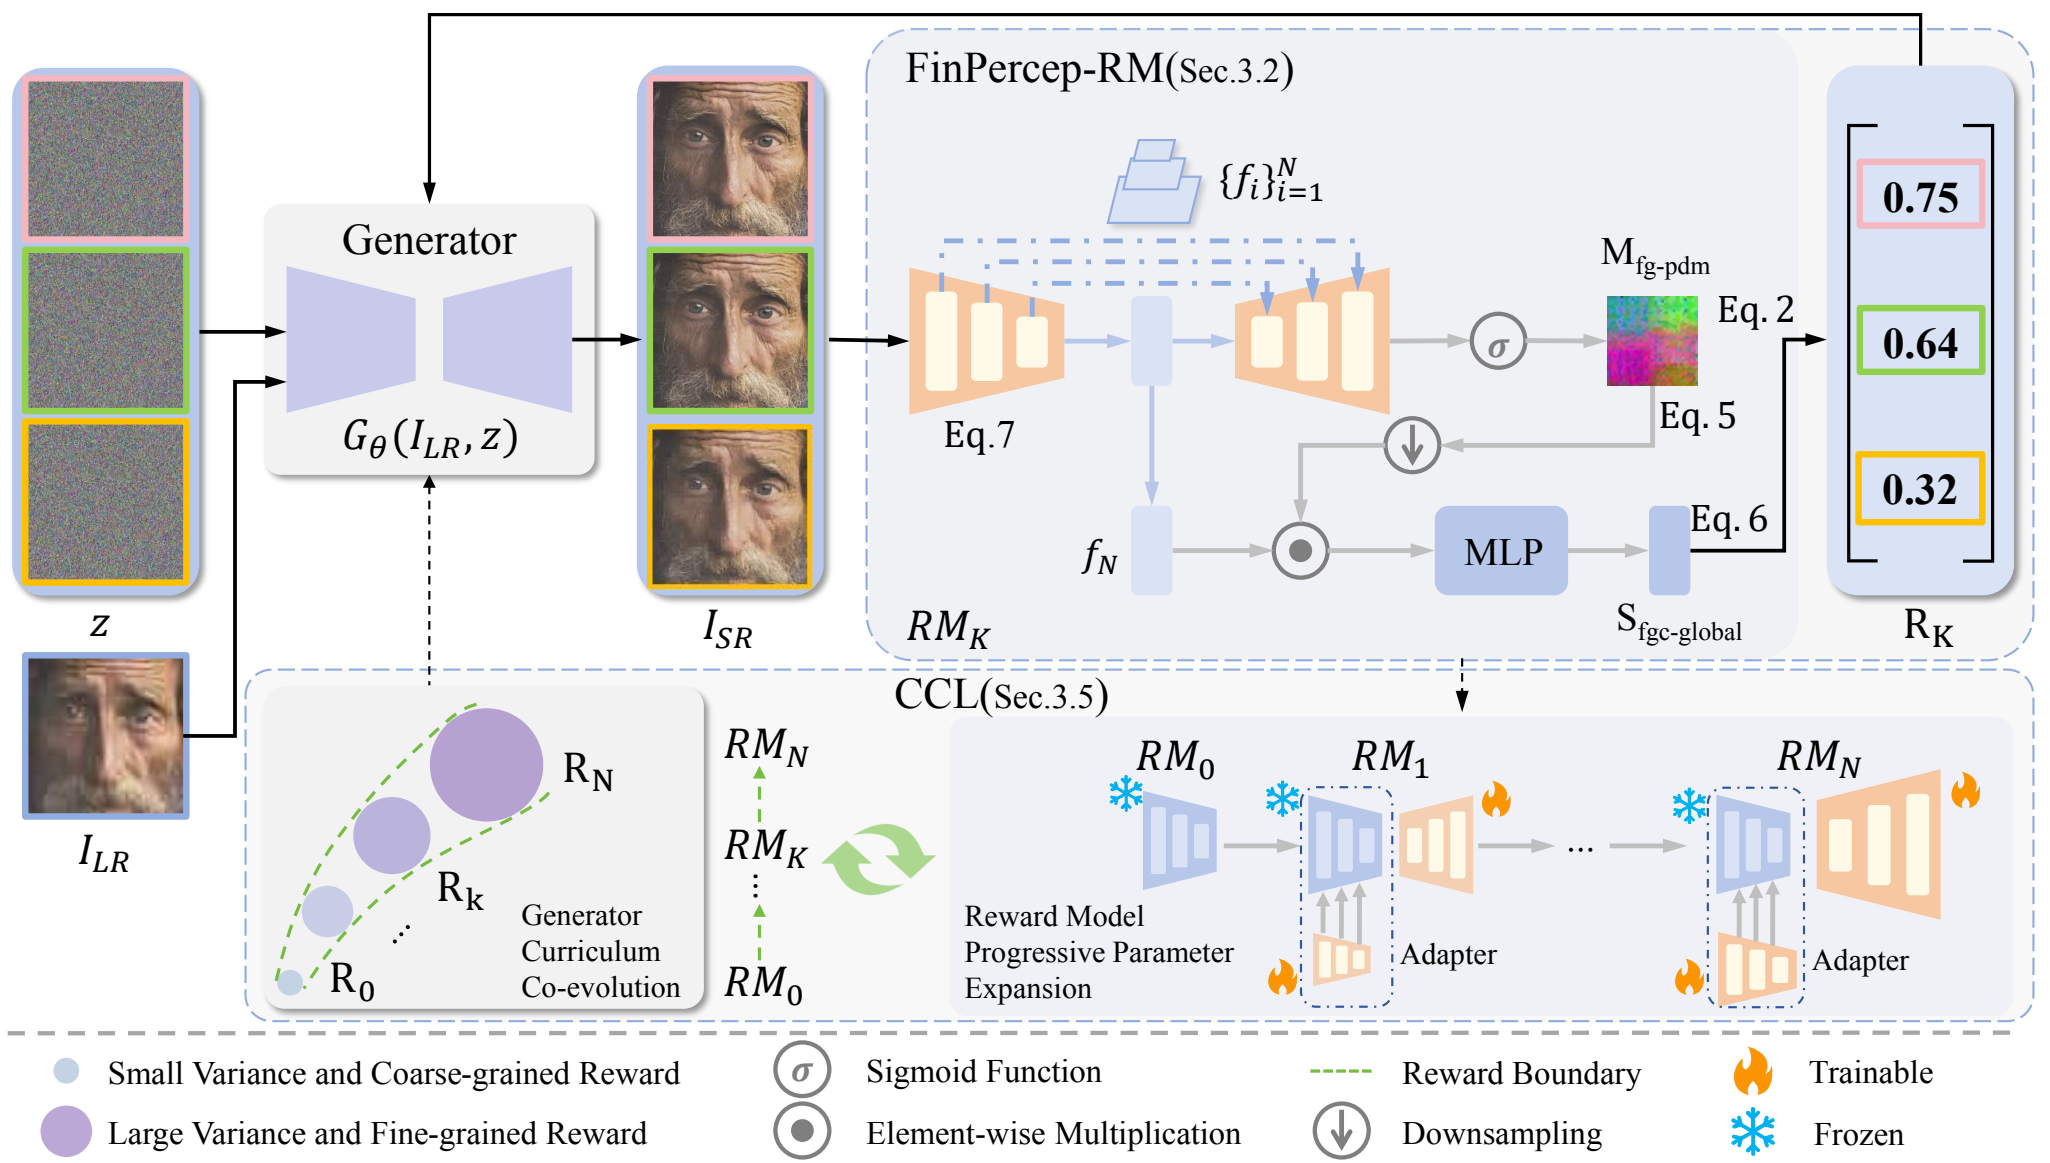
300 dpi PNG · 图注 · 源PDF
方法及图2展示生成器、细粒度奖励模型、感知退化图与课程协同训练的完整流程,包含全部图例。
完整图注、版本和筛选证据
最早核实视觉日期:2026-04-06;arXiv v1:2025-12-27;CVPR 2026 fixed official PDF
核查v1与v2:v1奖励输出为5.64/7.89/3.25,图例火/雪与文字关系、模块边框及CCL标题位置不同;会议图匹配2026-04-06 v2,不套用v1日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Zheng-Jun Zha;30479;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[63, 71, 555, 350],PDF点、左上角原点。
Figure2. TheoverallpipelineoftheproposedFinPercep-RMandCo-evolutionaryCurriculumLearning(CCL)framework. FinPercep-RM
producesaFine-grainedPerceptualDegradationMapthatcapturesspatiallylocalizeddefectlikelihoodandintensity, andtherewardmodel
is progressively expanded from small-variance, coarse-grained rewards to large-variance, fine-grained signals. During training, under the
CCL mechanism, the Generator first learns with the coarse global reward from RM for a stable and easy initialization, and is then co-
0
evolutionarily guided by increasingly strict RM versions to enhance local fidelity and suppress reward hacking.
k
FinPercep-RM: A Fine-grained Reward Model and Co-evolutionary Curriculum for RL-based Real-world Super-Resolution
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第1页 · P119
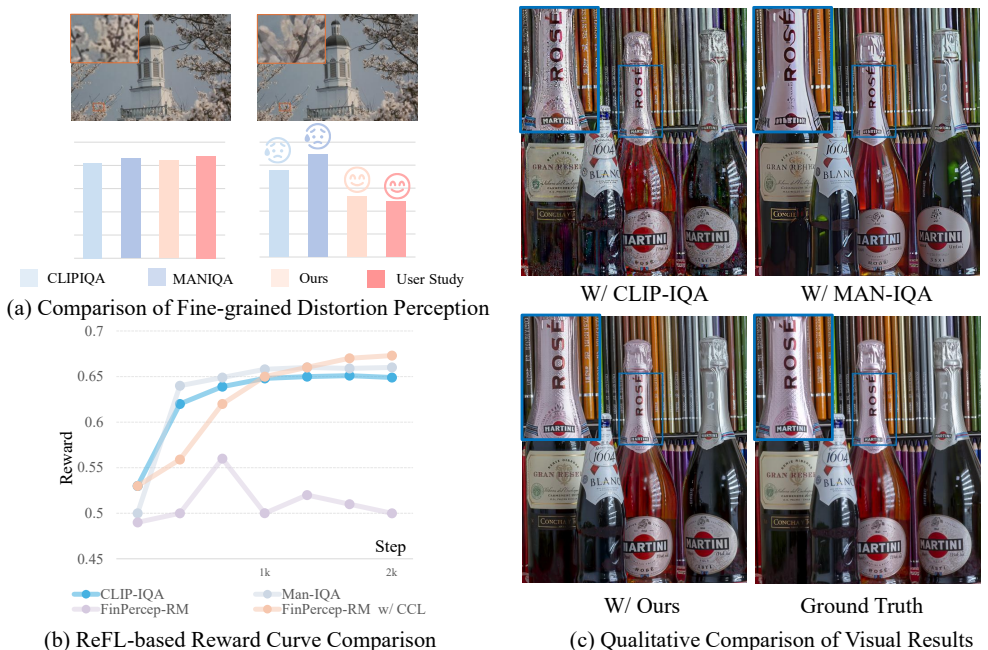
300 dpi PNG · 图注 · 源PDF
引言及图1明确以局部失真、奖励投机和训练稳定性困境引出问题;保留失真示例与诊断曲线的全部三面板,不属于单纯性能榜。
完整图注、版本和筛选证据
最早核实视觉日期:2025-12-27;arXiv v1:2025-12-27;CVPR 2026 fixed official PDF
v1与v2/会议版图1的视觉内容相同;v1整图页面纵坐标下移9.962pt,按对应坐标核对全部子图与文字;排版位置变化不改变图形时间。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Zheng-Jun Zha;30479;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[317, 260, 554, 416],PDF点、左上角原点。
Figure 1. Motivation for FinPercep-RM and CCL. (a) Standard
IQAs lack fine-grained perception and struggle to penalize lo-
cal distortions, while Ours aligns with human judgment (User
Study). (b) The training curves illustrate the stability-robustness
dilemma: baseline IQA rewards (blue/purple) converge quickly,
while FinPercep-RM (light blue) is oscillatory and unstable. Our
completemethod(FinPercep-RMw/CCL,orange)achievesstable
and optimal convergence. (c) Visualization of Reward Hacking:
baseline rewards (W/ CLIP-IQA, W/ MAN-IQA) produce local
artifacts, whereas our results are faithful to the Ground Truth.
GDPO-SR: Group Direct Preference Optimization for One-Step Generative Image Super-Resolution
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第4页 · P76
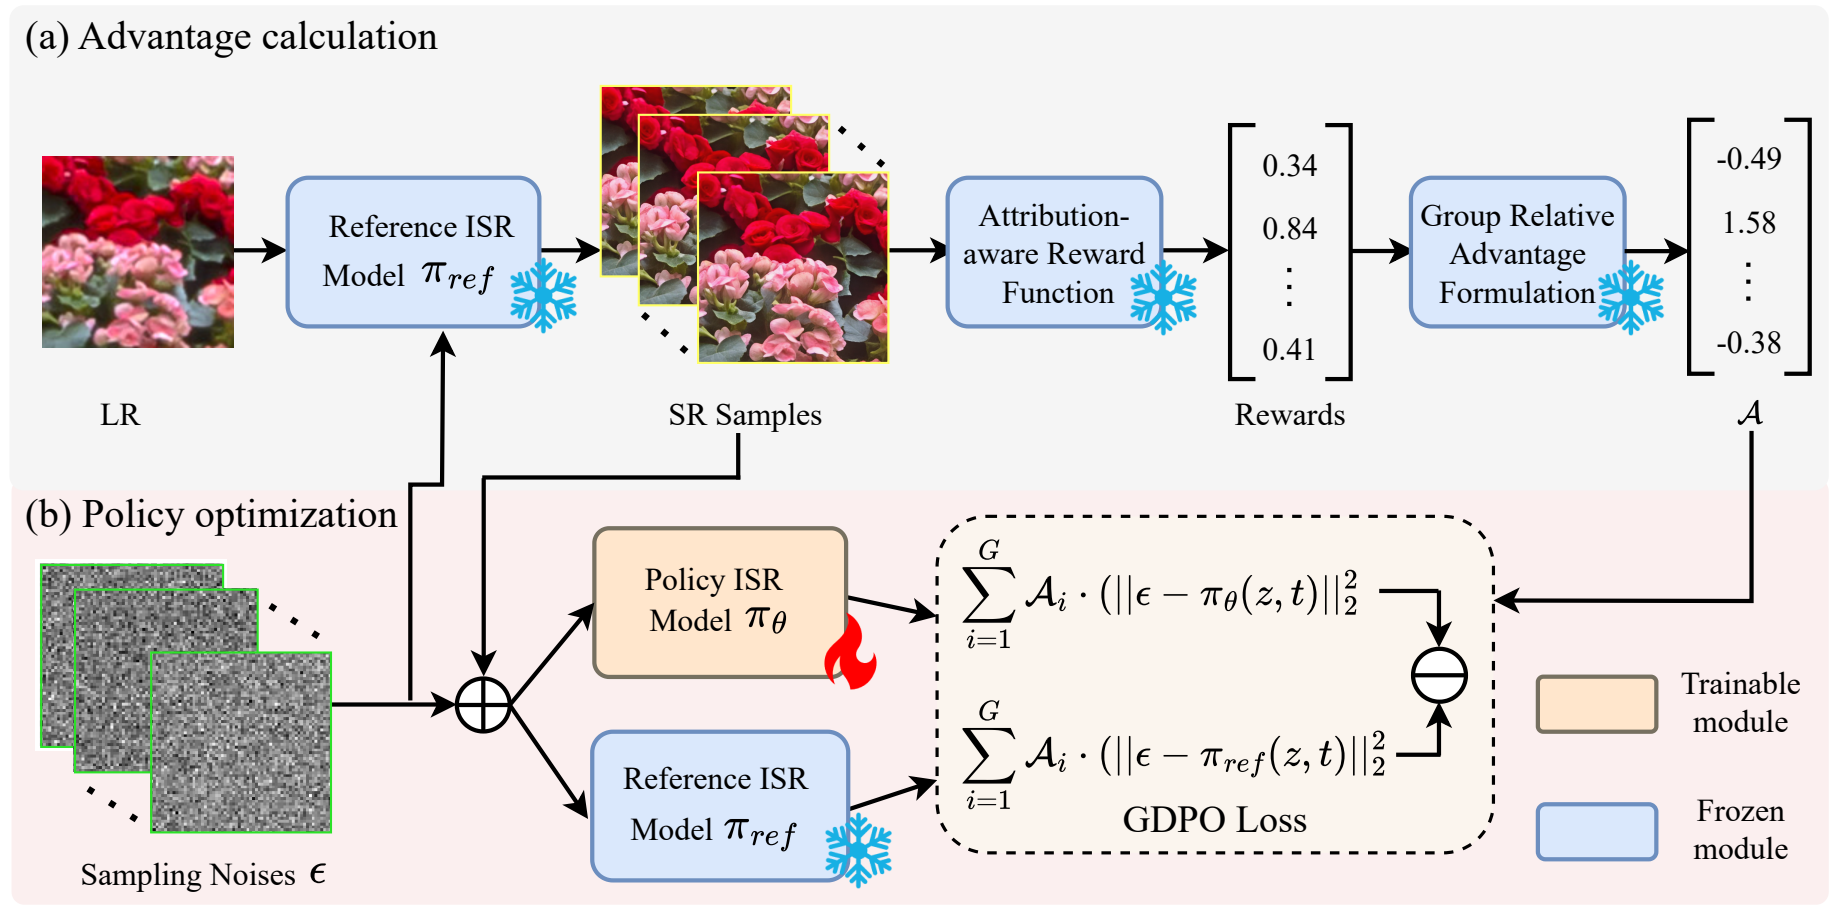
300 dpi PNG · 图注 · 源PDF
第3节及图2完整展示参考模型生成样本、奖励优势计算、策略模型优化两阶段训练框架。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-16;arXiv v1:2026-03-16;CVPR 2026 fixed official PDF
已查看固定PDF及目标图;以最早已核实匹配版本日期作时间代理,不声称实际作图日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[80, 71, 521, 289],PDF点、左上角原点。
Figure 2. The framework of GDPO, which consists of two core stages: (a) advantage calculation and (b) policy optimization. Firstly, we
employ a pre-trained one-step Real-ISR model as the reference model to generate a group of diverse outputs by injecting different random
noises. Subsequently, we compute the advantage A for each sample by evaluating its reward with our designed attribute-aware reward
functions and converting these rewards into group-relative advantages. In the policy optimization stage, we feed these samples along with
noises into both the policy model and the reference ISR model, and update the parameters of the policy ISR model by minimizing the
proposed GDPO loss, steering it to favor generating high-reward samples.
GDPO-SR: Group Direct Preference Optimization for One-Step Generative Image Super-Resolution
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第2页 · P75
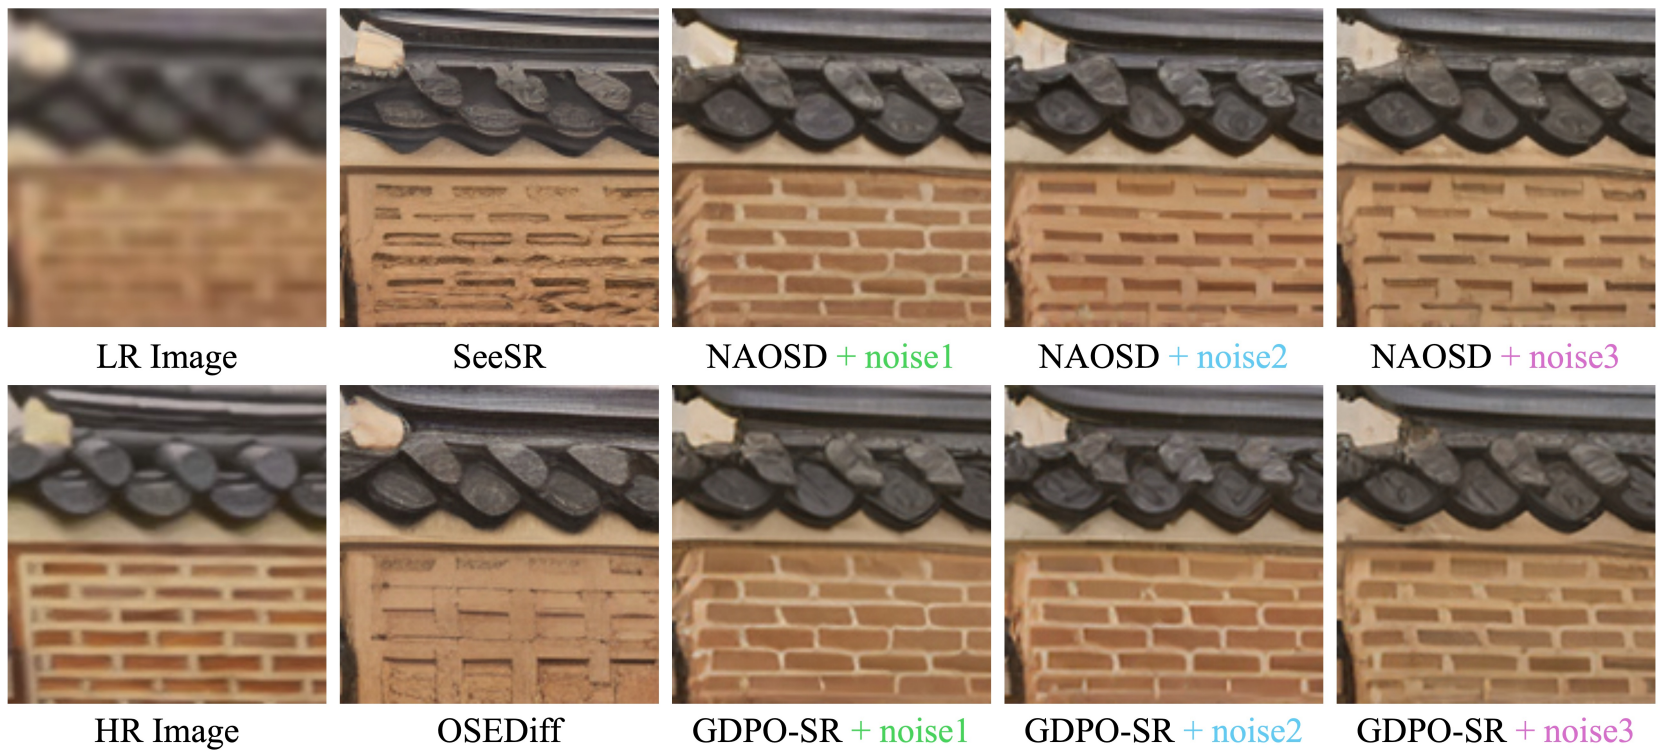
300 dpi PNG · 图注 · 源PDF
引言图1说明注入不同噪声既产生高质量结果也产生错误砖块纹理,具体呈现随机性带来的失败问题。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-16;arXiv v1:2026-03-16;CVPR 2026 fixed official PDF
已查看固定PDF及目标图;以最早已核实匹配版本日期作时间代理,不声称实际作图日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[105, 70, 505, 250],PDF点、左上角原点。
Figure 1. Noise regulates the diversity of generated samples. Different noise inputs yield both high-quality samples (e.g., noise1) and
low-quality ones (e.g., noise2 and noise3). After preference learning, the model produces more visually pleasing results.
One-Step Diffusion Transformer for Controllable Real-World Image Super-Resolution
会议:CVPR 2026 · 主会论文
Figure 3 · PDF第4页 · P200
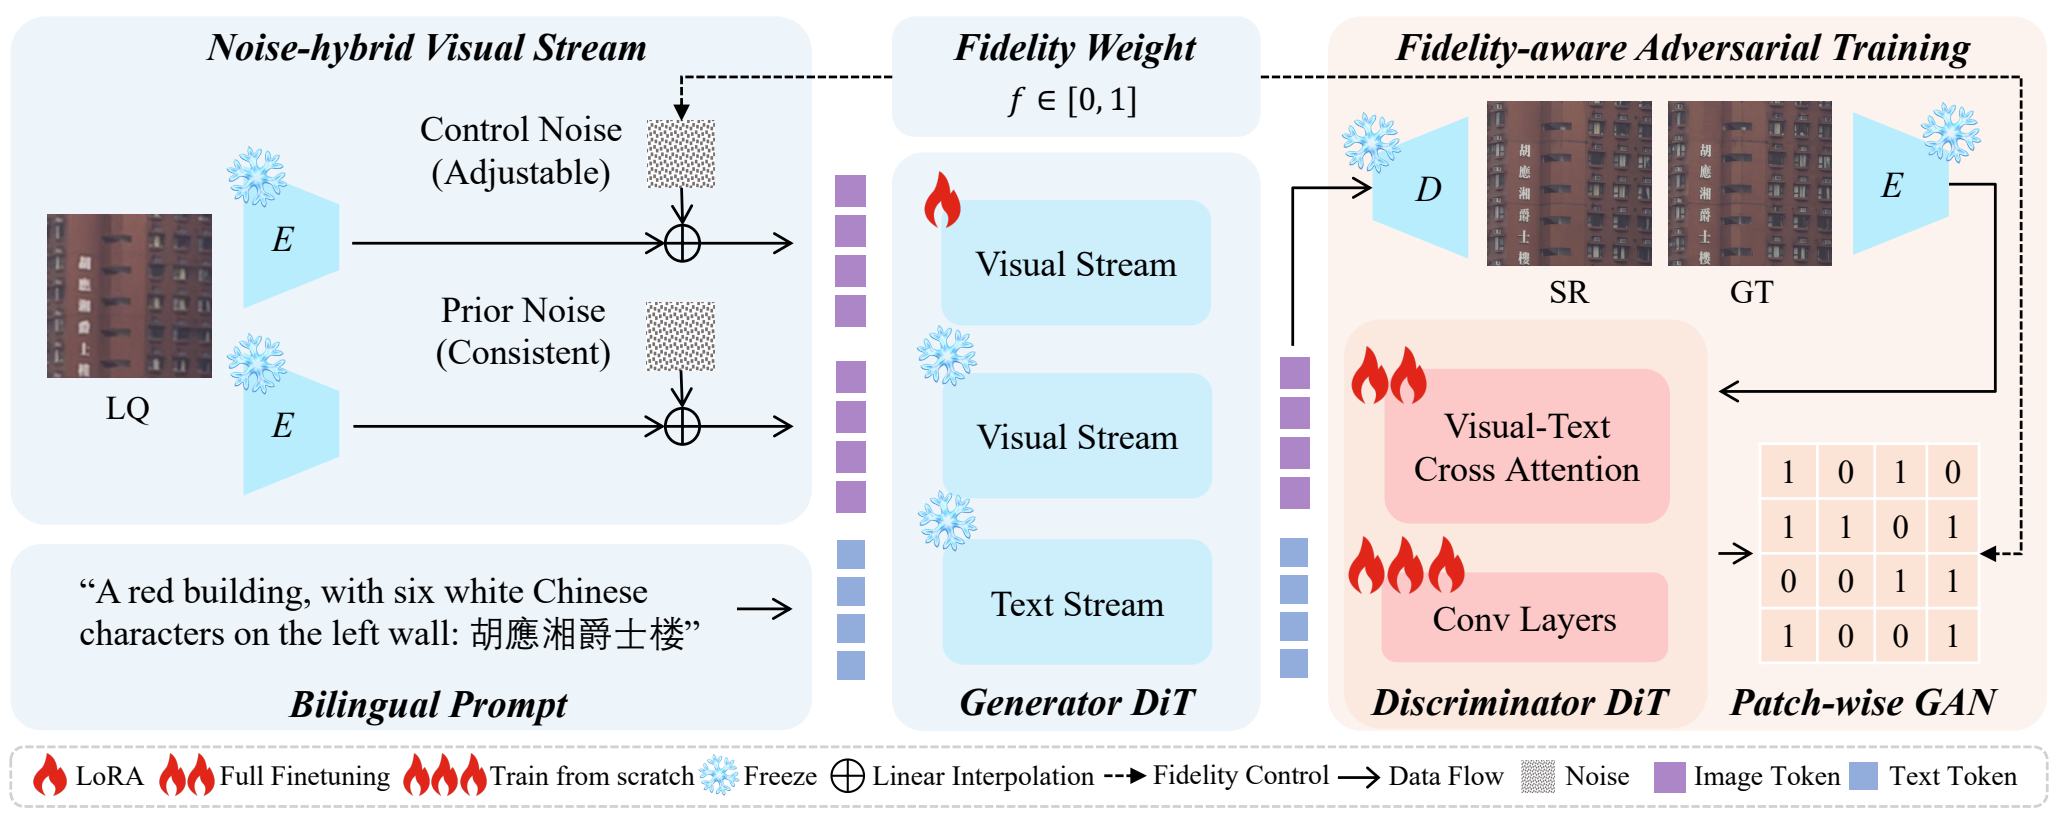
300 dpi PNG · 图注 · 源PDF
图3为整体噪声混合视觉流与保真感知对抗训练框架,保留完整主路径及图例。
完整图注、版本和筛选证据
最早核实视觉日期:2025-11-21;arXiv v1:2025-11-21;CVPR 2026 fixed official PDF
已核对固定会议PDF和arXiv v1的完整目标图;构图、文字、配色、元素和连线一致,v1为目前最早可核实的视觉版本。作者和机构已在PDF首页与公开引用主页交叉核对。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Ya Zhang;25506;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[59, 70, 555, 265],PDF点、左上角原点。
Figure 3. Overall framework. We extend the visual stream into a frozen Prior Noise stream that preserves the pretrained diffusion prior
and a Control Noise stream that adaptively modulates noise based on the Fidelity Weight to restore fine details, forming a Noise-hybrid
Visual Stream. Leveraging the Fidelity Weight to adjust adversarial signals adaptively, Fidelity-aware Adversarial Training enhances
controllability and achieves one-step inference.
One-Step Diffusion Transformer for Controllable Real-World Image Super-Resolution
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第3页 · P199
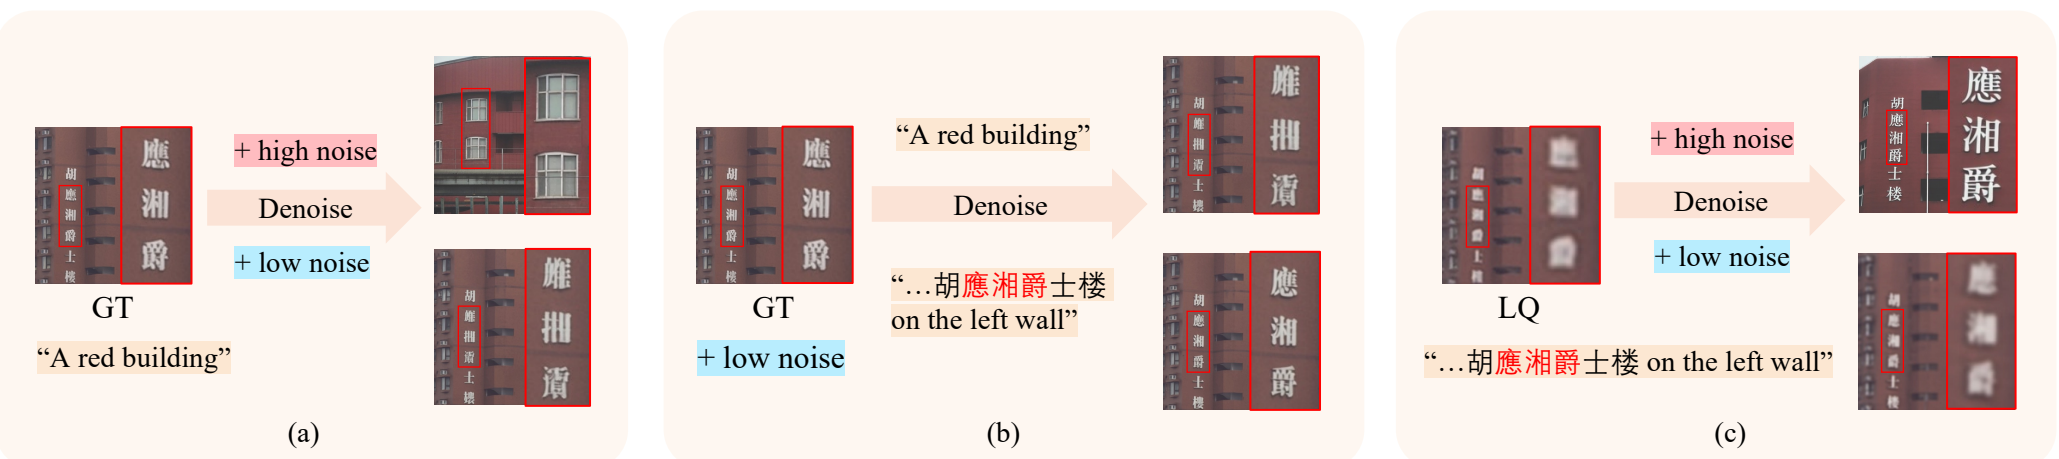
300 dpi PNG · 图注 · 源PDF
第3.2节以图2噪声提示控制实验说明质量、保真和可控性之间的矛盾,引出噪声混合设计;图1是普通结果展示。
完整图注、版本和筛选证据
最早核实视觉日期:2025-11-21;arXiv v1:2025-11-21;CVPR 2026 fixed official PDF
已核对固定会议PDF和arXiv v1的完整目标图;构图、文字、配色、元素和连线一致,v1为目前最早可核实的视觉版本。作者和机构已在PDF首页与公开引用主页交叉核对。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Ya Zhang;25506;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[60, 70, 554, 180],PDF点、左上角原点。
Figure 2. Effects of Noise on Fidelity and Controllability. Based on pretrained Qwen-Image, (a) shows the denoising results of ground-
truth (GT) under the same prompt and different levels of noise. (b) adopts low noise level and different prompts (with Chinese annotation).
(c) studies the effects of noise on LQ with the same prompt. High-noise inputs improve perceptual quality and controllability but reduce
fidelity, whereas low-noise inputs preserve original details yet fail to deliver enhanced super-resolution effects.
RefReward-SR: LR-Conditioned Reward Modeling for Preference-Aligned Super-Resolution
会议:ECCV 2026 · 主会论文
Figure 2 · PDF第6页 · P196
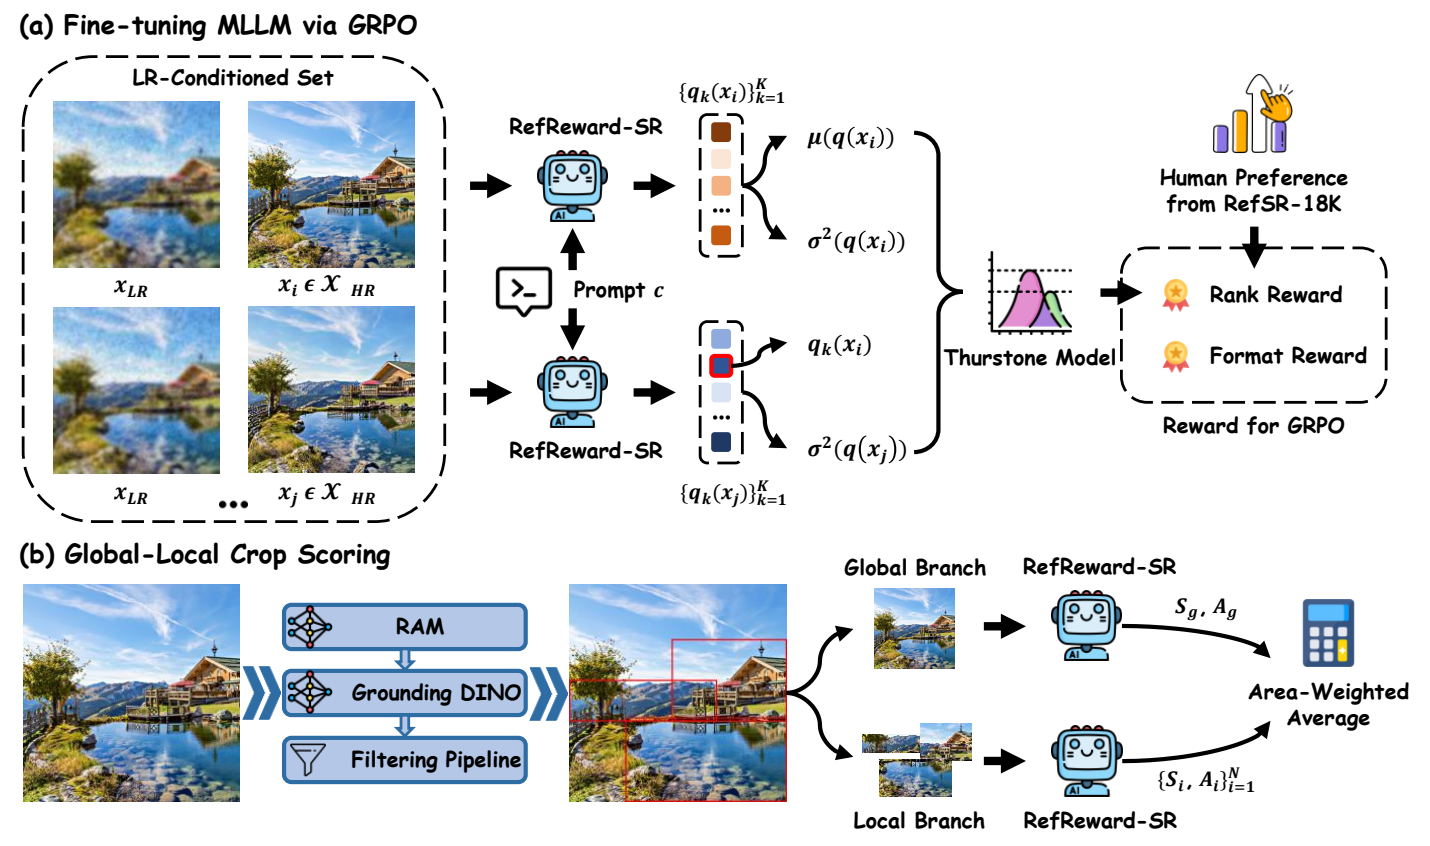
300 dpi PNG · 图注 · 源PDF
图2展示完整的MLLM奖励模型训练、GRPO以及全局/局部评分流程,服务于超分辨率优化。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-25;arXiv v1:2026-03-25;ECCV 2026 fixed official PDF
已核对固定会议PDF和arXiv v1的完整目标图;构图、文字、配色、元素和连线一致,v1为目前最早可核实的视觉版本。作者和机构已在PDF首页与公开引用主页交叉核对。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jing Liu;22235;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[135, 116, 478, 319],PDF点、左上角原点。
Fig. 2: The proposed RefReward-SR framework. (a) MLLM Fine-tuning:
Fine-tuning via GRPO with format and LR-conditioned rank rewards from RefSR-
18K for human preference alignment. (b) Global-Local Crop Scoring: Extracting
representative local crops via RAM and Grounding DINO, then fusing multi-scale
MLLM scores via area-weighted averaging for comprehensive evaluation.
RefReward-SR: LR-Conditioned Reward Modeling for Preference-Aligned Super-Resolution
会议:ECCV 2026 · 主会论文
Figure 1 · PDF第3页 · P195
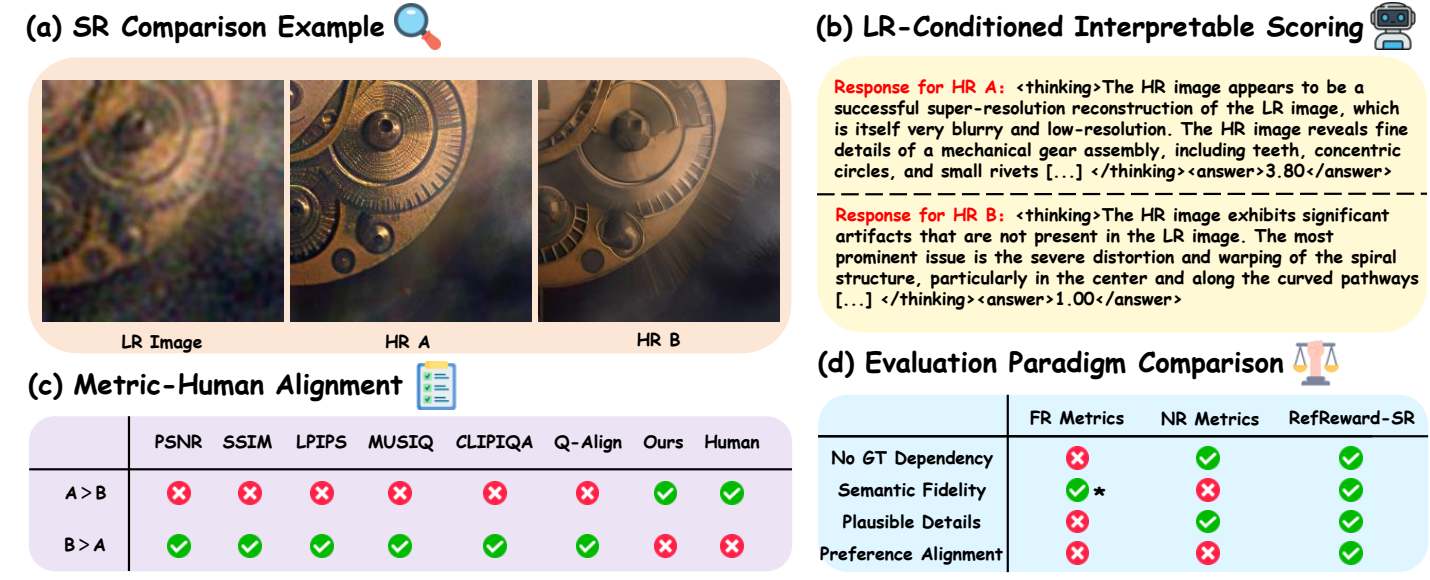
300 dpi PNG · 图注 · 源PDF
图1显示既有质量指标偏好失真输出而非感知更自然的重建,正文据此引出LR条件奖励与人类偏好的对齐问题。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-25;arXiv v1:2026-03-25;ECCV 2026 fixed official PDF
已核对固定会议PDF和arXiv v1的完整目标图;构图、文字、配色、元素和连线一致,v1为目前最早可核实的视觉版本。作者和机构已在PDF首页与公开引用主页交叉核对。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jing Liu;22235;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[135, 116, 478, 255],PDF点、左上角原点。
Fig. 1: Overview of our proposed evaluation paradigm. (a) HR A preserves structures,
while HR B shows severe distortions. (b) RefReward-SR uses an MLLM for inter-
pretable, LR-conditioned semantic scoring. (c) Existing metrics wrongly favor the dis-
torted HR B, whereas ours aligns with human perception. (d) RefReward-SR uniquely
ensures semantic fidelity and preference alignment without GT dependency. The as-
terisk(*) indicates that FR metrics evaluate high-level semantics only passively via
low-level correspondence.
Residual Diffusion Bridge Model for Image Restoration
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第3页 · P148
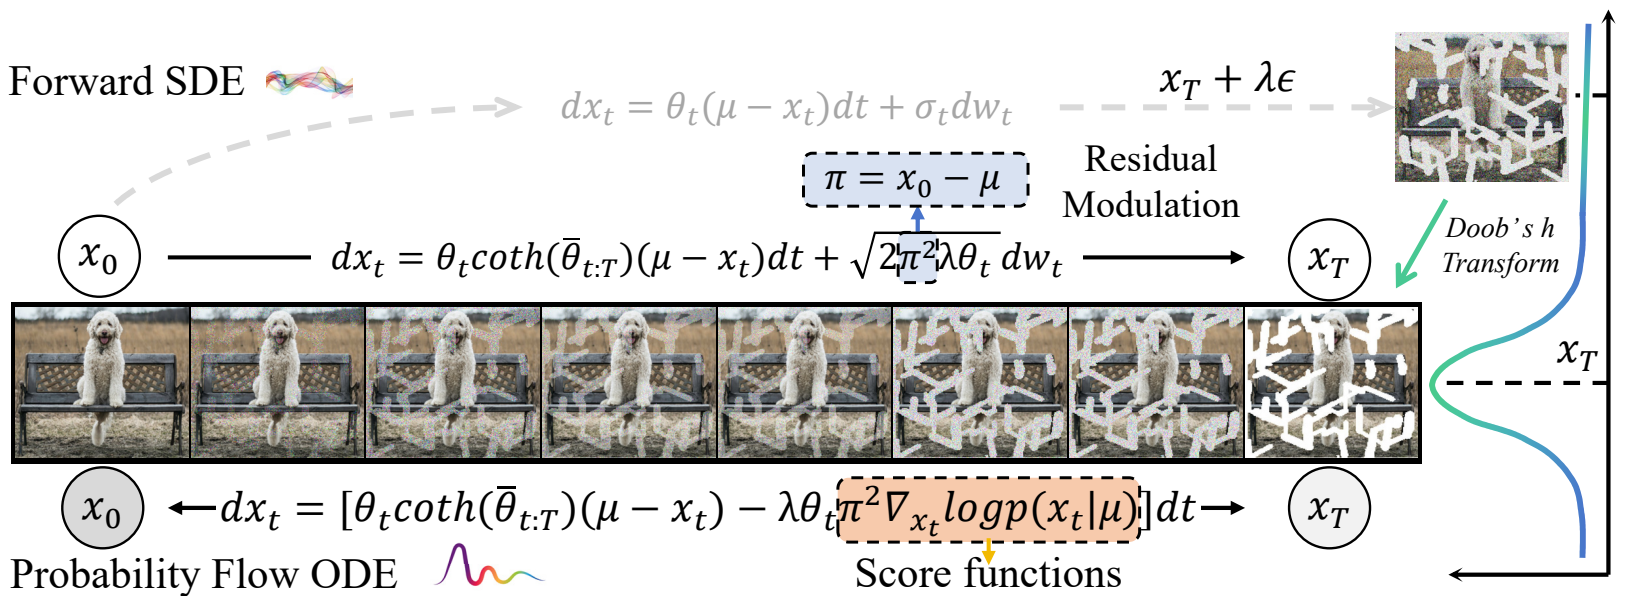
300 dpi PNG · 图注 · 源PDF
图2展示残差桥的完整前向SDE与反向ODE计算路径、终点约束及分数函数;为本文核心计算框架。
完整图注、版本和筛选证据
最早核实视觉日期:2026-04-18;arXiv v1:2025-10-27;CVPR 2026 fixed official PDF
已核查v1(2025-10-27)、v2(2025-11-06)、v3(2026-04-18):早期图1(c)绿色概率路径及底部域图形位置不同,图2分数函数标签与公式的相对位置改变;v3与会议目标图像素一致。因此不回填v1日期,最早核实匹配版本为v3。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Bo Du;50901;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[110, 70, 502, 213],PDF点、左上角原点。
Figure 2. A schematic of Residual Diffusion Bridge Models. RDBM utilizes a diffusion process guided by Doob’s h-transform towards an endpoint xT = µ free from stationary noise λϵ. Modulated by the residual component π = x0 − xT , the noise perturbation is selectively imposed on different regions with diverse degradation levels, thereby constructing probabilistic paths. Besides, it learns to reverse the process by matching the residual bridge score functions, facilitating an adaptive inversion from xT ∼ pprior(x) to x0 ∼ pdata(x).
Residual Diffusion Bridge Model for Image Restoration
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第1页 · P147
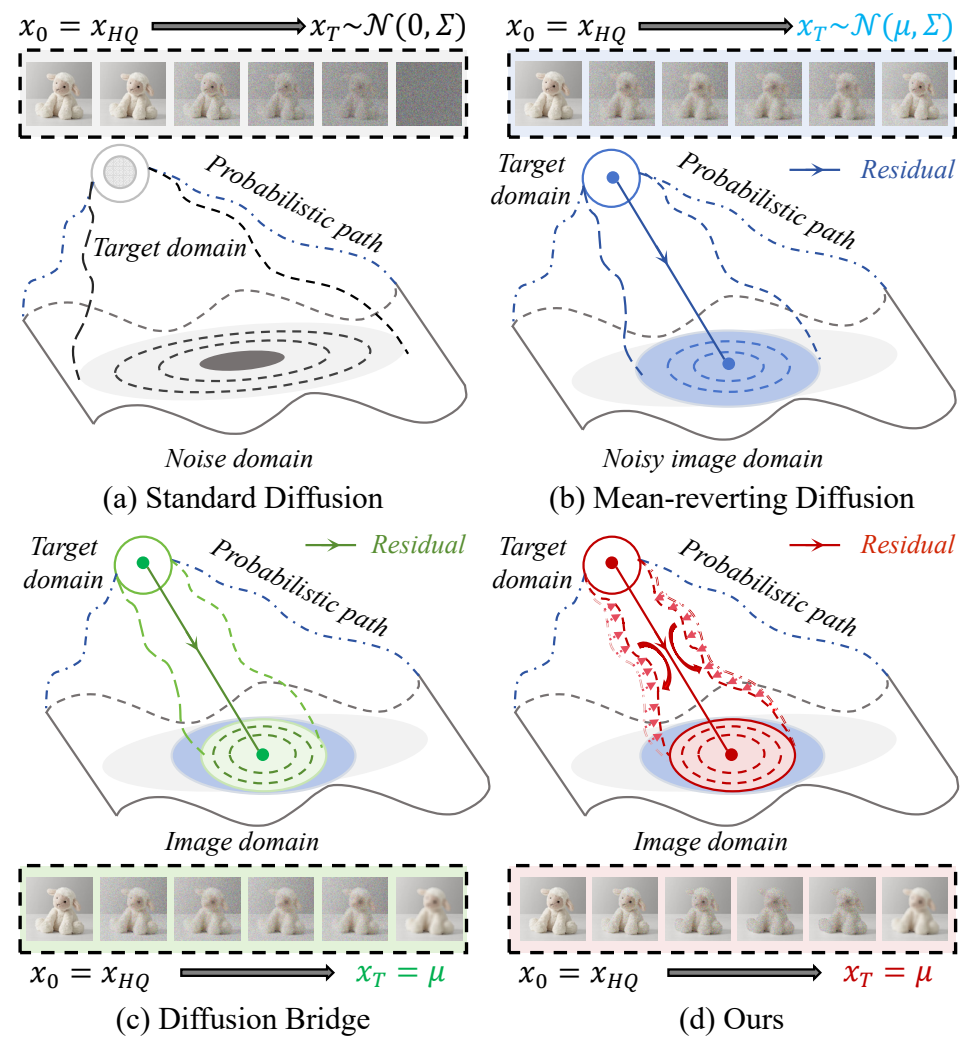
300 dpi PNG · 图注 · 源PDF
引言和图1比较四类扩散过程,明确指出全局注噪破坏完好区域,从而引出残差调制;属于概念对比和方法局限示意。
完整图注、版本和筛选证据
最早核实视觉日期:2026-04-18;arXiv v1:2025-10-27;CVPR 2026 fixed official PDF
已核查v1(2025-10-27)、v2(2025-11-06)、v3(2026-04-18):早期图1(c)绿色概率路径及底部域图形位置不同,图2分数函数标签与公式的相对位置改变;v3与会议目标图像素一致。因此不回填v1日期,最早核实匹配版本为v3。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Bo Du;50901;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[317, 295, 552, 543.7],PDF点、左上角原点。
Figure 1. Typical diffusion processes. (a) Standard diffusion maps high-quality images to Gaussian noise domain. (b) Mean-reverting diffusion drives terminal state toward a low-quality domain with stationary noise. (c) Diffusion bridge establishes direct probabilistic transitions between known distributions. All inject noise globally, disrupting overall structures and constraining transitions. (d) In contrast, our RDBM selectively reconstructs degraded regions (e.g., the doll) while preserving intact areas (e.g., the background).
Statistical Characteristic-Guided Denoising for Rapid High-Resolution Transmission Electron Microscopy Imaging
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第3页 · P146
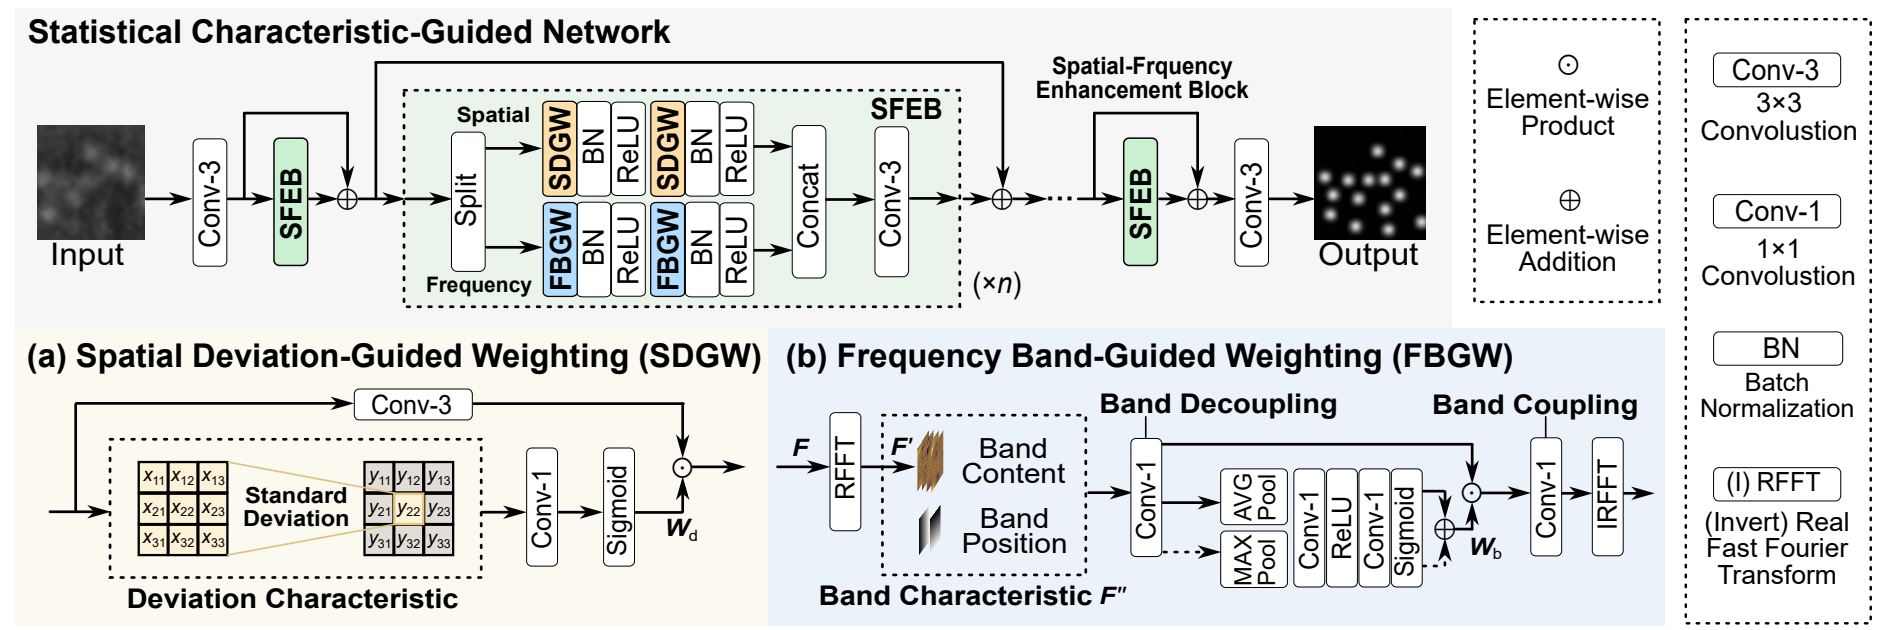
300 dpi PNG · 图注 · 源PDF
图2及第3.2节为整体统计特征引导网络,完整保留输入输出、空间频率增强块、SDGW、FBGW及符号图例。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-19;arXiv v1:2026-03-19;CVPR 2026 fixed official PDF
已对照会议固定PDF与arXiv v1目标图,构图、文字和连线一致,导出像素一致;未发现更早公开版本。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Ying Fu;11391;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[70, 70, 522, 221],PDF点、左上角原点。
Figure 2. The framework of our statistical-characteristic guided network. It enhances signals and suppresses noise in the spatial and
frequency domains using spatial deviation-guided weighting and frequency band-guided weighting, respectively.
Statistical Characteristic-Guided Denoising for Rapid High-Resolution Transmission Electron Microscopy Imaging
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第2页 · P145
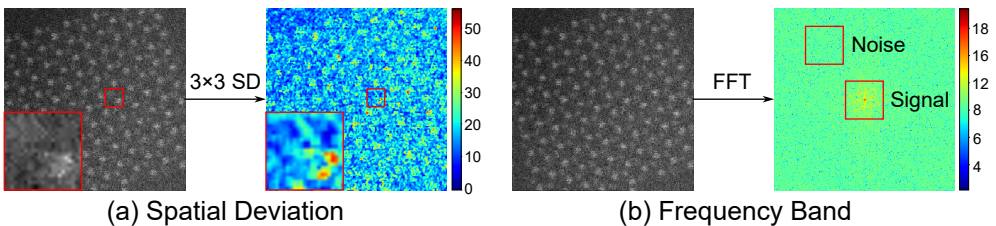
300 dpi PNG · 图注 · 源PDF
第3.1节Formulation and Motivation结合图1说明不同空间位置的波动及信号/噪声频带分离,解释普通卷积难以分辨原子信号的问题;图为输入噪声特性示意。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-19;arXiv v1:2026-03-19;CVPR 2026 fixed official PDF
已对照会议固定PDF与arXiv v1目标图,构图、文字和连线一致,导出像素一致;未发现更早公开版本。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Ying Fu;11391;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[308, 70, 547, 124],PDF点、左上角原点。
Figure 1. Visualization of the two kinds of statistical characteris-
tics that we used to guide the denoising process. (a) The spatial
deviation characteristic obtained by calculating the pixel standard
deviation (SD) within 3 × 3 windows. It reflects the fluctuation
conditions of different spatial positions in the image. (b) The fre-
quencybandcharacteristicobtainedbytheFastFourierTransform
(FFT). Signal and noise are distributed at different frequency band
positions and have different patterns.
TIR-Agent: Training an Explorative and Efficient Agent for Image Restoration
会议:ECCV 2026 · 主会论文
Figure 3 · PDF第6页 · P80
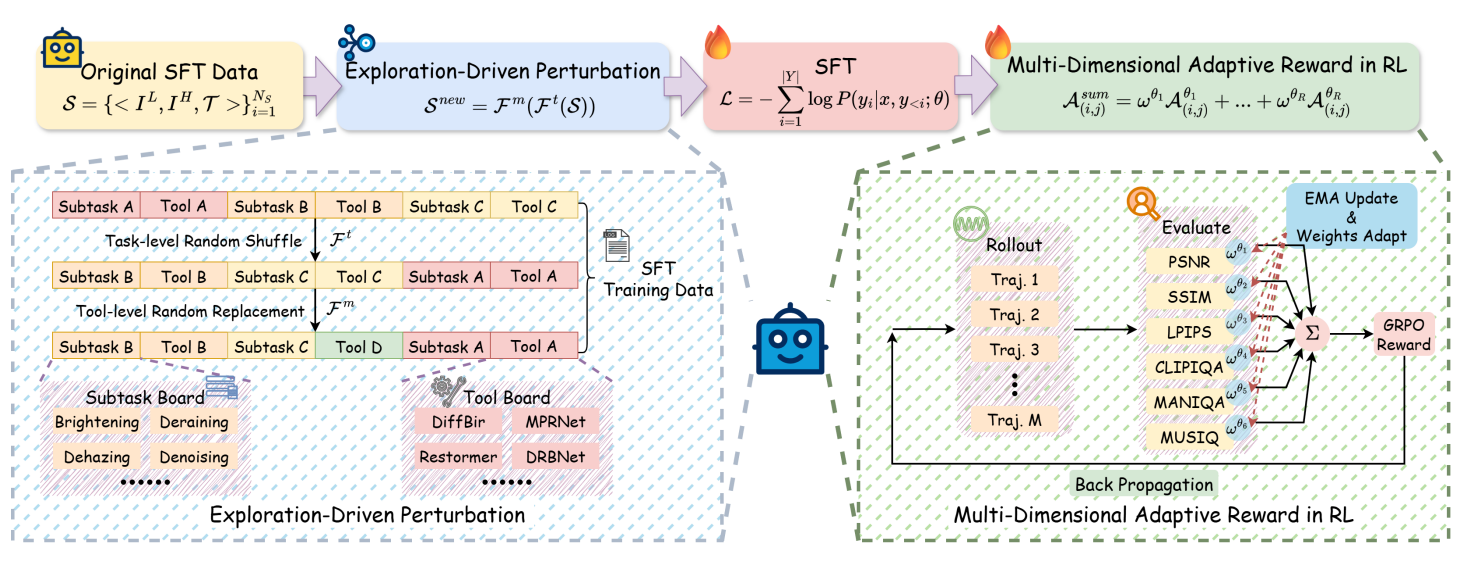
300 dpi PNG · 图注 · 源PDF
图3和第3节说明数据生成、探索扰动、监督微调和奖励驱动强化学习的全部训练阶段。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-29;arXiv v1:2026-03-29;ECCV 2026 fixed official PDF
已查看会议版和arXiv v1:图内构图、图标、颜色、模块文字和连线一致;会议排版缩小并将框架图编号由2改为3,分别保存坐标,不将图号变化视作重绘。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Bowen Zhou;32977;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[132, 112, 484, 248],PDF点、左上角原点。
Fig.3: Training pipeline of TIR-Agent. The process begins with SFT Data Gen-
eration, followed by Exploration-Driven Perturbation to enhance data diversity
via shuffled task sequences and tool substitutions. Following SFT, the agent undergoes
RL with a Multi-Dimensional Adaptive Reward mechanism, which dynamically
balances metric weights based on their EMA trends to optimize the restoration policy.
TIR-Agent: Training an Explorative and Efficient Agent for Image Restoration
会议:ECCV 2026 · 主会论文
Figure 1 · PDF第2页 · P79
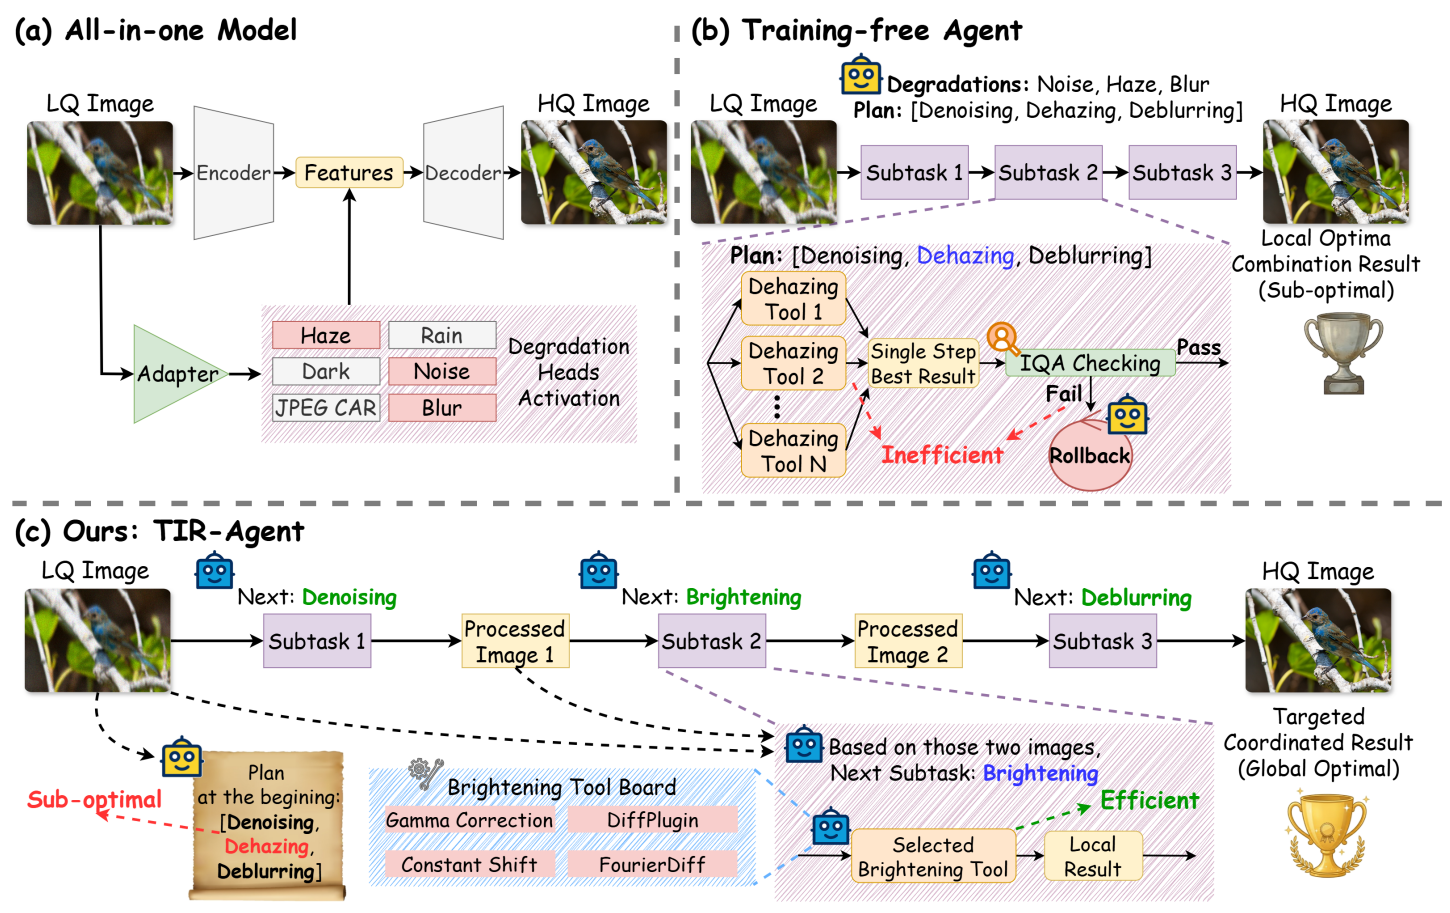
300 dpi PNG · 图注 · 源PDF
引言图1比较整合模型、无需训练的智能体与可训练智能体,明确标注次优任务规划和冗余调用问题。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-29;arXiv v1:2026-03-29;ECCV 2026 fixed official PDF
已查看会议版和arXiv v1:图内构图、图标、颜色、模块文字和连线一致;会议排版缩小并将框架图编号由2改为3,分别保存坐标,不将图号变化视作重绘。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Bowen Zhou;32977;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[134, 113, 482, 332],PDF点、左上角原点。
Fig.1: Comparison of restoration paradigms. (a) All-in-one model: Uses
a single network with specialized heads to inject various degradation features. (b)
Training-free Agent: Uses VLMs for static task planning, executing sub-tasks se-
quentially via exhaustive tool traversal. (c) TIR-Agent (Ours): A trainable agent
that dynamically decides the next sub-task based on current results and learns to di-
rectly select the optimal tool, avoiding redundant execution.
UARE: A Unified Vision-Language Model for Image Quality Assessment, Restoration, and Enhancement
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第3页 · P38
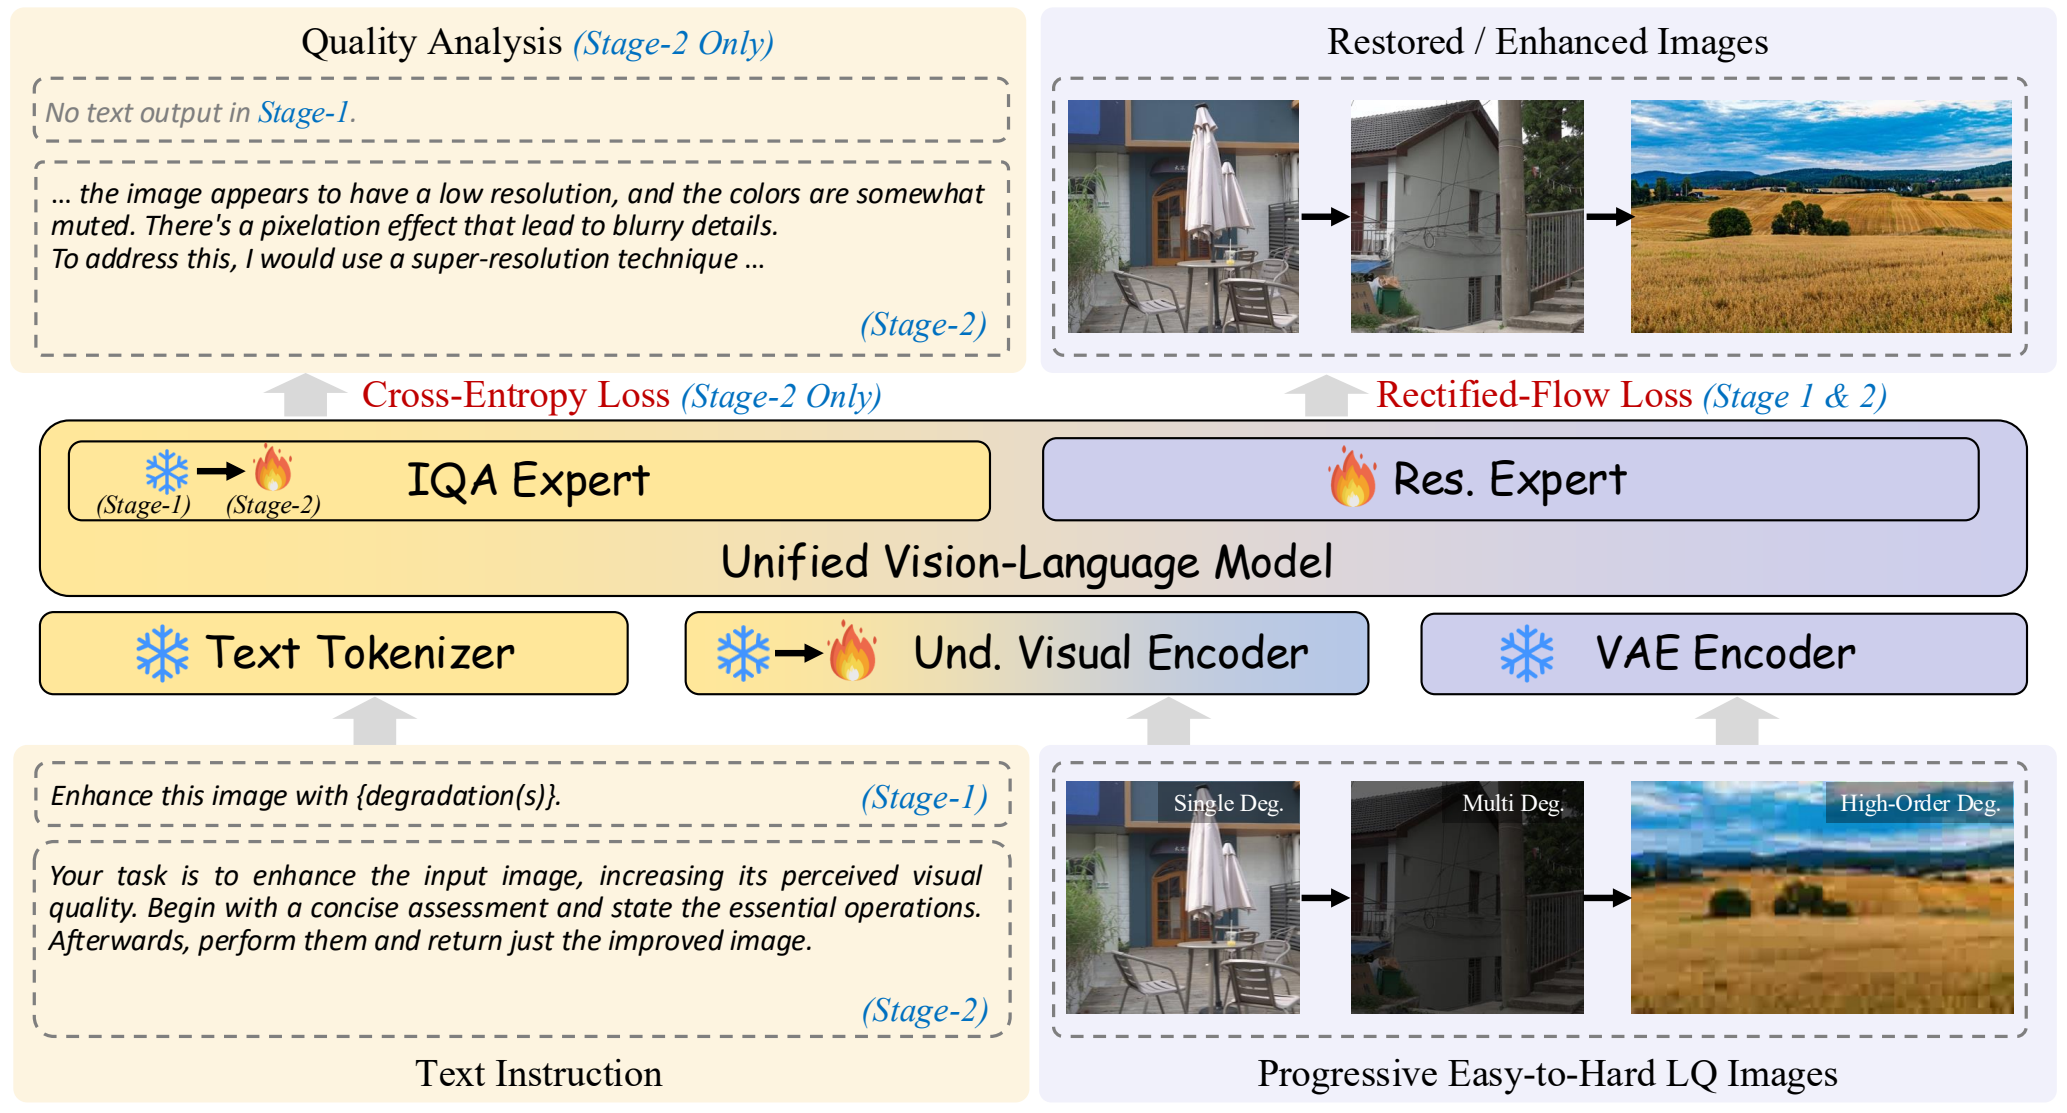
300 dpi PNG · 图注 · 源PDF
第3.2节明确称图2为overview,图中完整给出文本/图像编码、IQA与复原双专家、两阶段训练损失及输出,属于总体架构和训练流程。
完整图注、版本和筛选证据
最早核实视觉日期:2025-12-07;arXiv v1:2025-12-07;CVPR 2026 fixed official PDF
已逐张查看会议版与arXiv v1:图1因作者行排版整体下移9.963 PDF点,设计/文本/布局一致;图2位置及设计一致。记录v1公开时间,未用会议录用时间。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Jian Zhang(张健);21725;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[58, 71, 554, 338],PDF点、左上角原点。
Figure2. Illustrationofthearchitectureandtwo-stagetrainingframeworkofUARE.TwotransformerexpertsareusedtoprocessIQA
and restoration, respectively. Training stages include (1) a progressive, easy-to-hard schedule that moves from single-type to high-order
degradations. In this stage, only the restoration expert is trained to make UARE handle multiple degradations. (2) Unified fine-tuning of
the entire model to strengthen the IQA ability and align the IQA signals with restoration objectives through interleaved data.
UARE: A Unified Vision-Language Model for Image Quality Assessment, Restoration, and Enhancement
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第1页 · P37
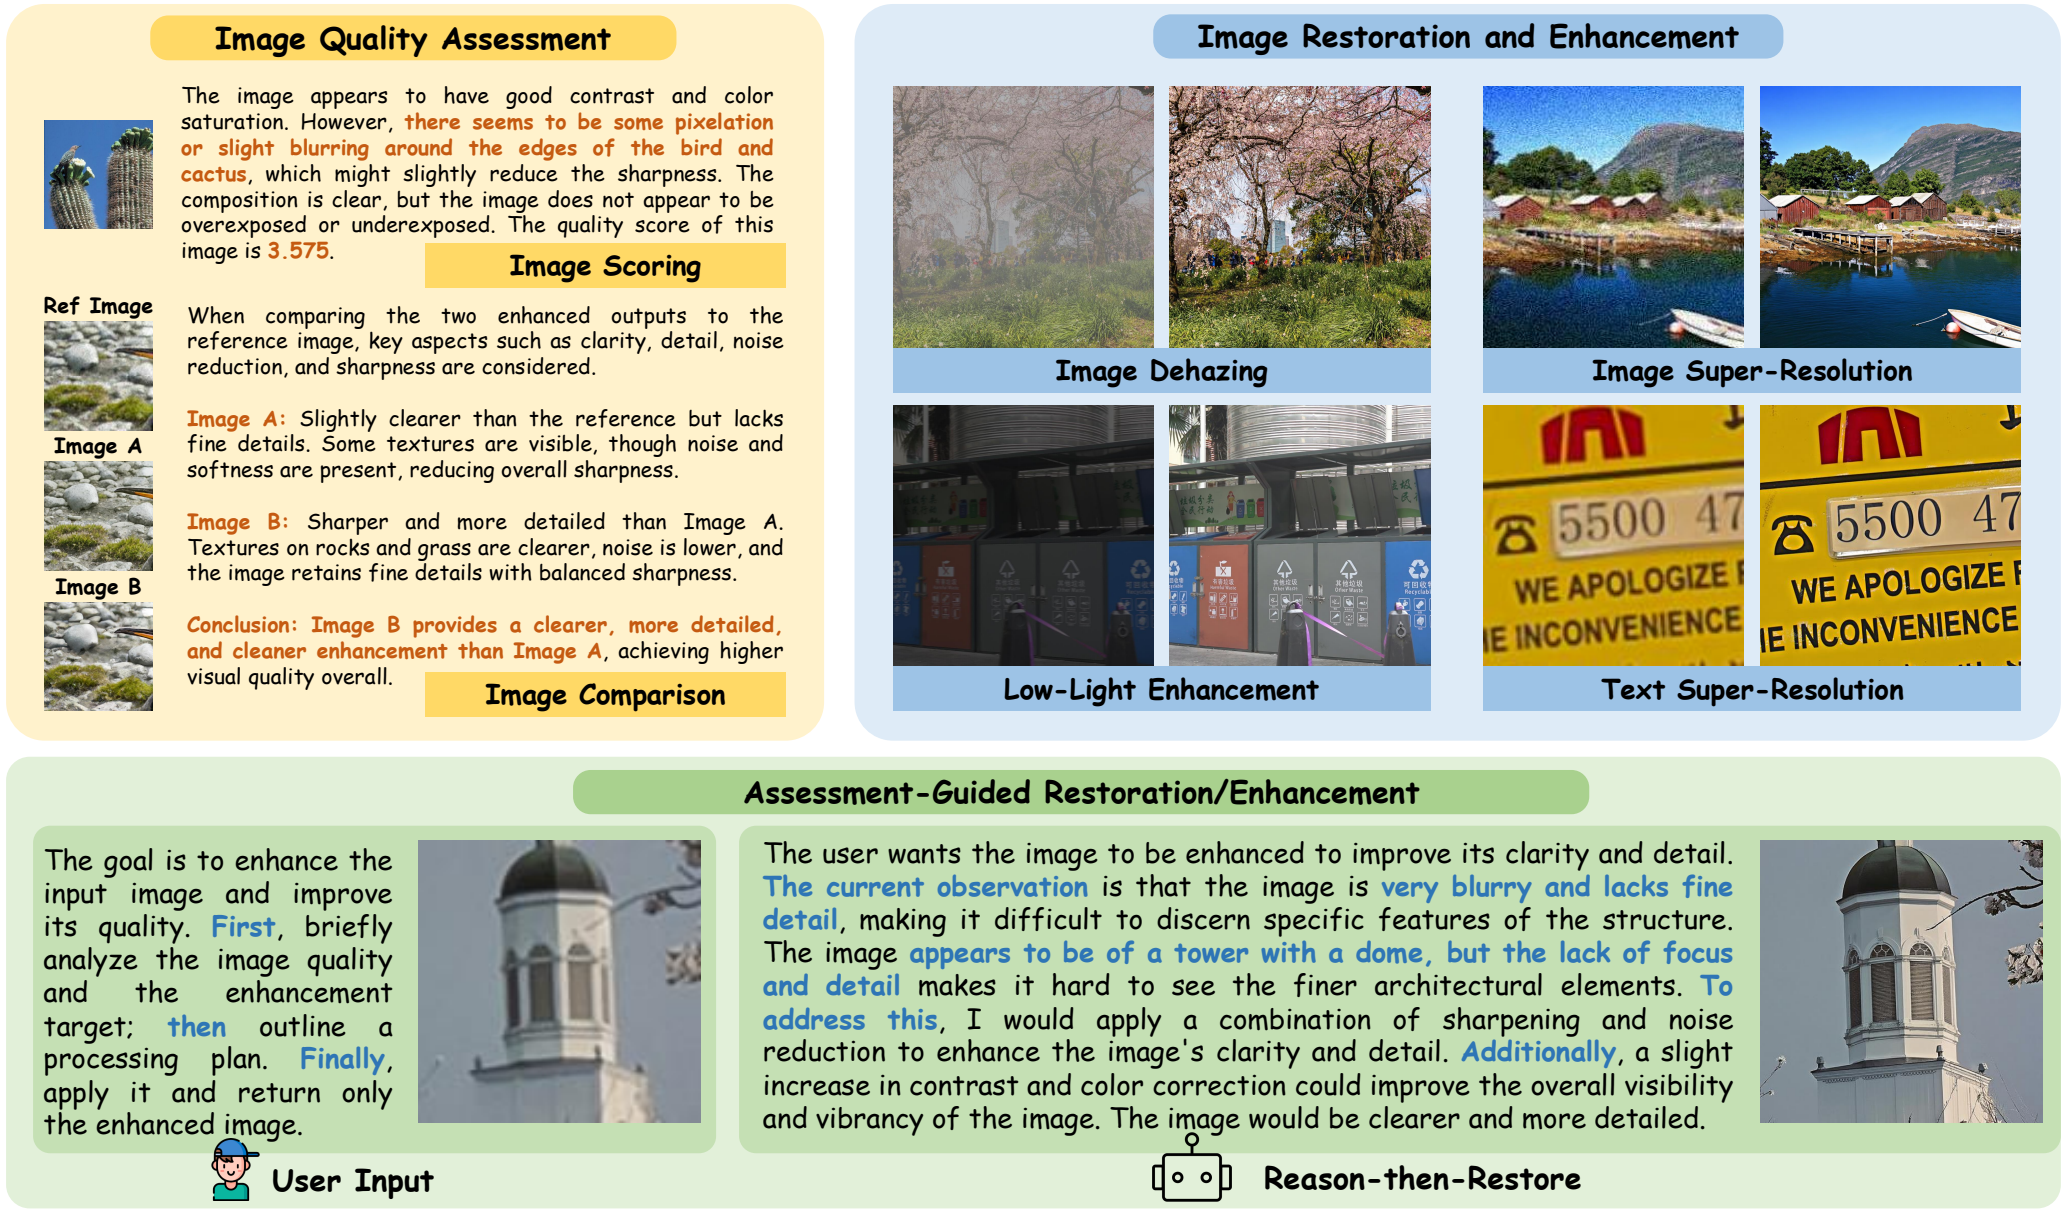
300 dpi PNG · 图注 · 源PDF
引言第2页用图1说明质量评估与复原原本分离、需要在同一模型中联合处理的应用场景;图含用户请求、质量分析和reason-then-restore交互,按应用场景M收录,不作为普通跨方法结果拼图。
完整图注、版本和筛选证据
最早核实视觉日期:2025-12-07;arXiv v1:2025-12-07;CVPR 2026 fixed official PDF
已逐张查看会议版与arXiv v1:图1因作者行排版整体下移9.963 PDF点,设计/文本/布局一致;图2位置及设计一致。记录v1公开时间,未用会议录用时间。
历史PDF · 下载引用证据快照 · 公开日期
作者引用:Jian Zhang(张健);21725;快照2026-10-21。
绘图工具:unknown。已读图注与相关正文;未找到该插图实际制作工具声明。
裁剪坐标:[58, 237, 554, 528],PDF点、左上角原点。
Figure 1. Showcase of UARE. It supports image quality assessment (image scoring and comparison), image restoration/enhancement
(super-resolution, dehazing, and low-light enhancement, etc.), and assessment-guided restoration and enhancement in one unified model.
CUPID: Generative 3D Reconstruction via Joint Object and Pose Modeling
会议:CVPR 2026 · 主会论文
Figure 3 · PDF第4页 · P158
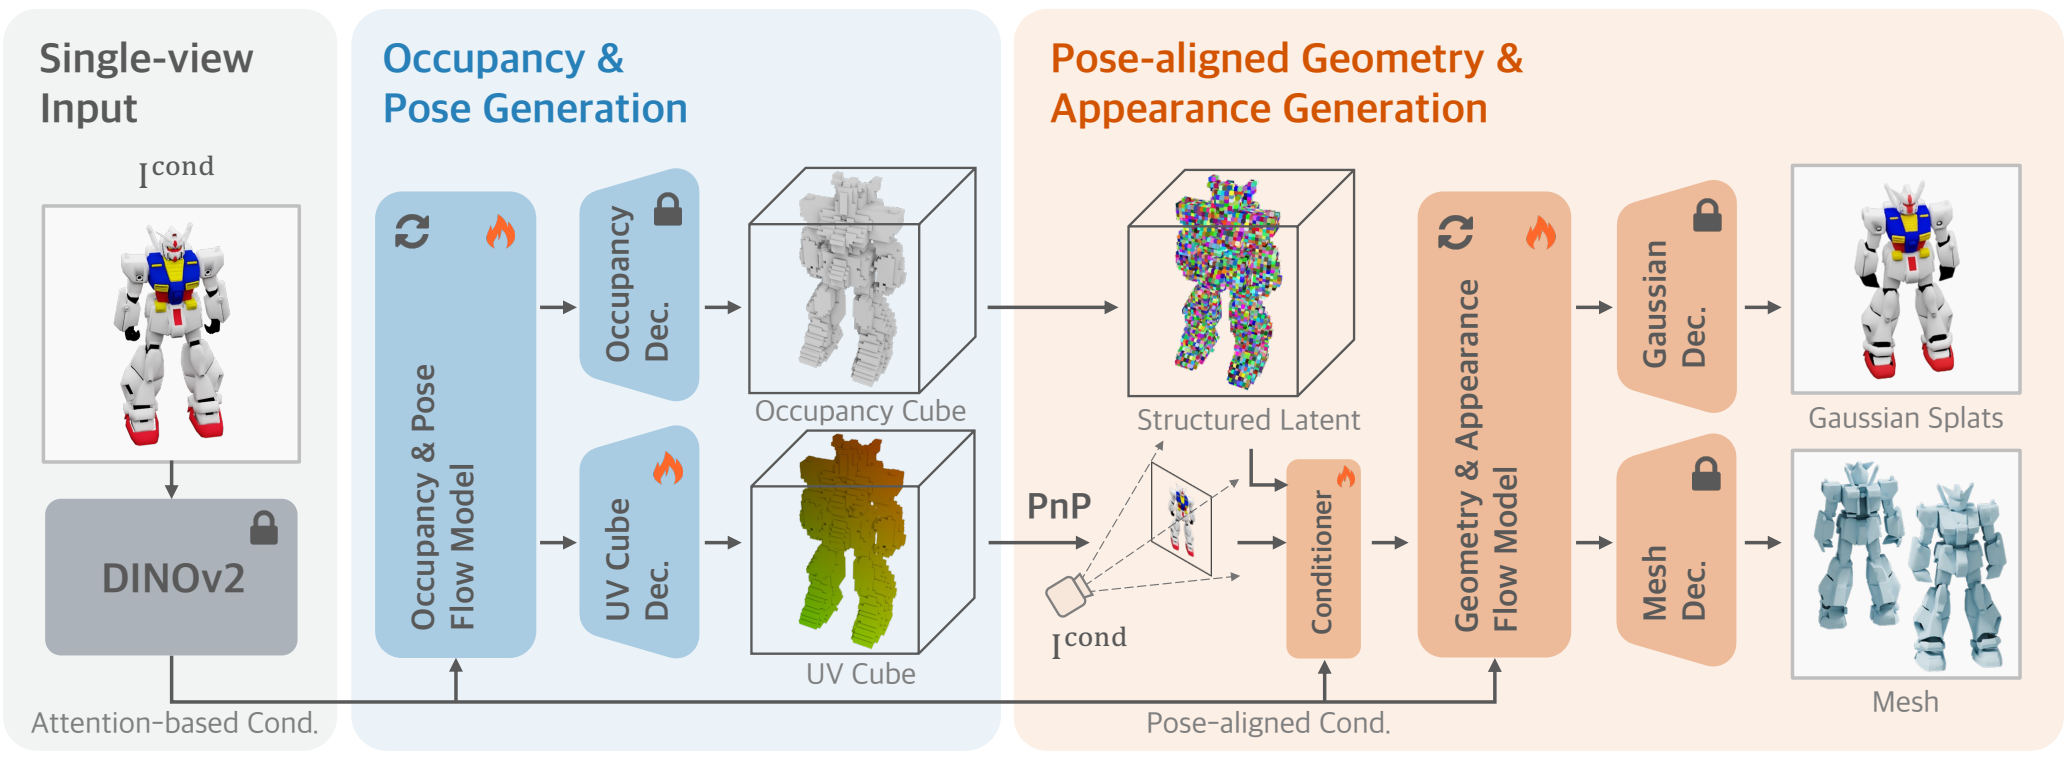
300 dpi PNG · 图注 · 源PDF
图3明确为整体CUPID流程:占据与姿态生成、PnP相机恢复、姿态对齐条件以及几何外观输出。
完整图注、版本和筛选证据
最早核实视觉日期:2025-10-23;arXiv v1:2025-10-23;CVPR 2026 fixed official PDF
v1(2025-10-23)第4页图2已具有同一完整框架;会议版编号改为3并整体等比放大,模块、连线、配色、内容一致。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Shenghua Gao;29917;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 70, 554, 253],PDF点、左上角原点。
Figure 3. Overview of CUPID’s pipeline. From a single input image, CUPID first generates an occupancy and a UV cube in canonical
space. Then, a Perspective-n-Point (PnP) solver (i.e., Eq. 2) recovers the camera pose. Using this recovered camera pose, we extract pose-
aligned conditioning latents and visual features (i.e., Eq. 3), along with noisy structured latents, to generate the geometry and appearance
features, which will be decoded to the 3D Gaussian splats and mesh.
CUPID: Generative 3D Reconstruction via Joint Object and Pose Modeling
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第1页 · P157
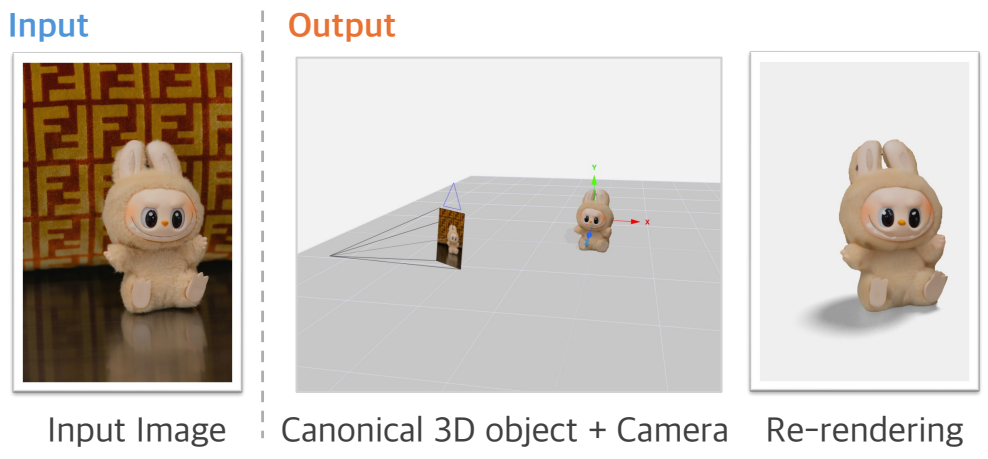
300 dpi PNG · 图注 · 源PDF
引言及第3页以图1解释从单张图像解耦规范物体与相机姿态的联合问题,并联系人类的视点无关物体表征;图为任务与概念示意。
完整图注、版本和筛选证据
最早核实视觉日期:2025-11-24;arXiv v1:2025-10-23;CVPR 2026 fixed official PDF
v1第2页为大幅多样本结果拼图,尚无目标图1;v2(2025-11-24)第1页出现与会议版一致的联合物体/相机任务图,故按v2日期,不回填v1。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Shenghua Gao;29917;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[317, 228, 554, 338],PDF点、左上角原点。
Figure 1. Generative 3D reconstruction from a single image.
Left: Input image. Middle: Our method recovers a canonical 3D
model (intrinsic properties such as shape and texture) along with
theexactcamerapose(extrinsicproperty)thatgeneratedtheinput.
Right: Re-rendering the 3D model from the estimated pose faith-
fully reproduces the input.
E-RayZer: Self-supervised 3D Reconstruction as Spatial Visual Pre-training
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第4页 · P188
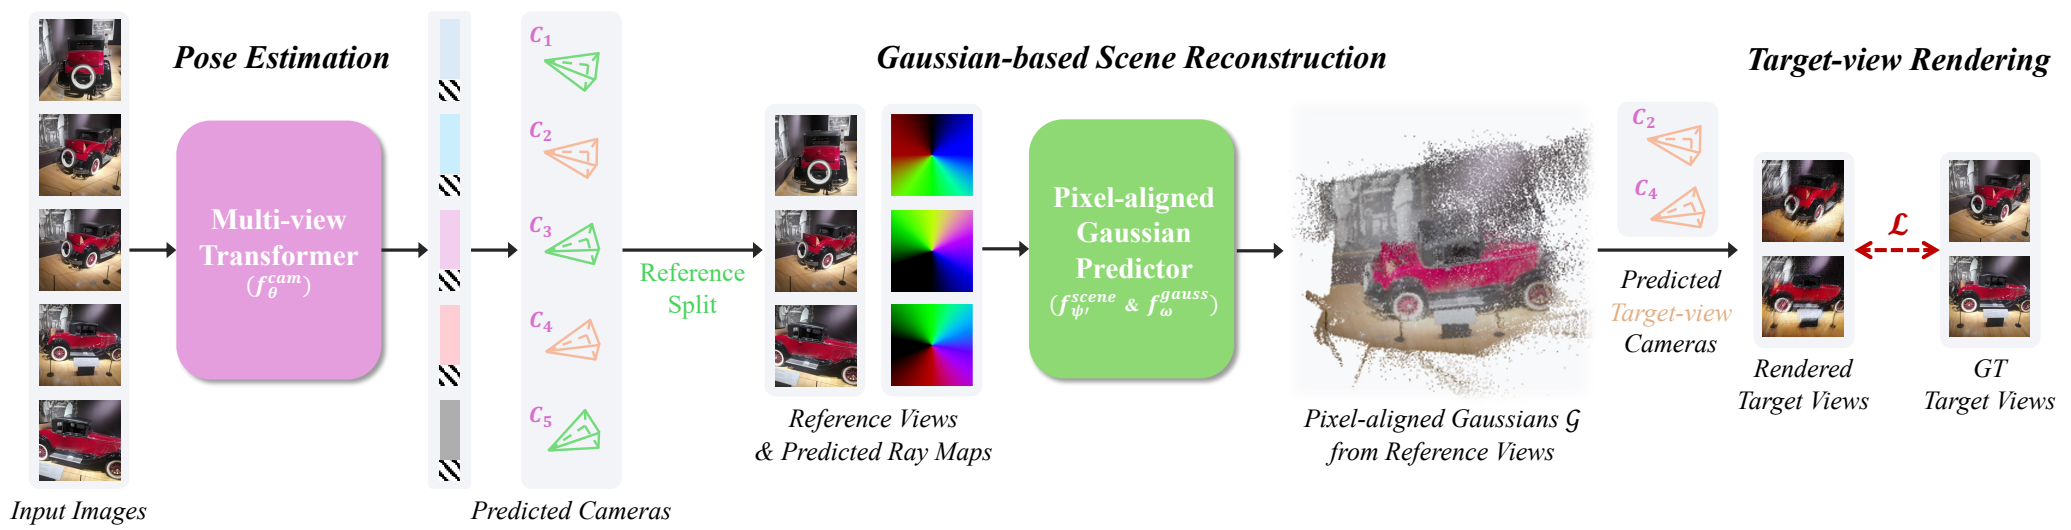
300 dpi PNG · 图注 · 源PDF
第3.2节明确图2为整体Overview,保留相机估计、参考/目标划分、三维高斯重建及目标视图渲染监督。
完整图注、版本和筛选证据
最早核实视觉日期:2025-12-11;arXiv v1:2025-12-11;CVPR 2026 fixed official PDF
已对照固定会议版本与arXiv v1,完整布局、标签、元素与连线匹配;v1为目前最早可核实的该视觉版本。已在PDF首页核对作者及单位。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Shubham Tulsiani;13507;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 70, 555, 197],PDF点、左上角原点。
Figure 2. E-RayZer Model & Training. E-RayZer first predicts camera poses and intrinsics for all images. Then it follows RayZer [25] to
split images into two sets. E-RayZer predicts explicit 3D Gaussians as scene representation from the reference views (I ), and renders the
ref
scene using self-predicted target-view (I ) cameras. Finally, E-RayZer is trained with self-supervised photometric losses on target views.
tgt
E-RayZer: Self-supervised 3D Reconstruction as Spatial Visual Pre-training
会议:CVPR 2026 · 主会论文
Figure 3 · PDF第5页 · P187
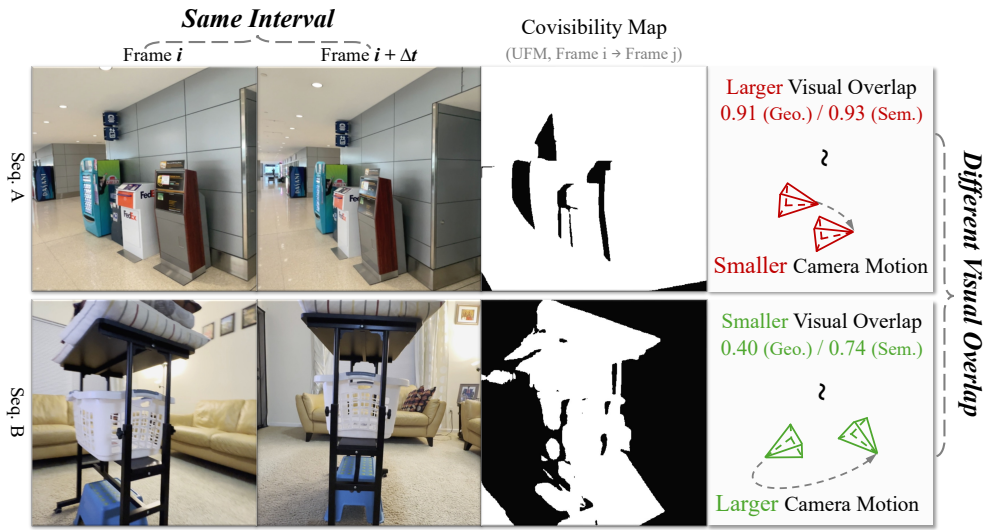
300 dpi PNG · 图注 · 源PDF
第3.3节以相同帧间隔却不同视野重叠的反例解释既有采样策略不准确、不可扩展的局限;图1是模型能力与性能汇总。
完整图注、版本和筛选证据
最早核实视觉日期:2025-12-11;arXiv v1:2025-12-11;CVPR 2026 fixed official PDF
已对照固定会议版本与arXiv v1,完整布局、标签、元素与连线匹配;v1为目前最早可核实的该视觉版本。已在PDF首页核对作者及单位。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Shubham Tulsiani;13507;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 70, 296, 197],PDF点、左上角原点。
Figure 3. Different Visual Overlaps under the Same Frame In-
terval. Two sequences from DL3DV [34] share the same frame in-
terval yet exhibit drastically different levels of visual overlap. Our
proposed semantic and geometric overlap metrics more accurately
capture the true difficulty (or camera motion) of each sequence.
EMGauss: Continuous Slice-to-3D Reconstruction via Dynamic Gaussian Modeling in Volume Electron Microscopy
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第3页 · P186
300 dpi PNG · 图注 · 源PDF
图2明确为EMGauss整体pipeline,包含已知切片、标准高斯、连续变形、可微渲染和光度监督。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-13;arXiv v1:2025-12-07;CVPR 2026 fixed official PDF
已查看v1(2025-12-07)图1第2页与图2第6页:图1重新布局、配色和标注;图2字体及标签排布改变。v2(2026-03-13)两图与会议版匹配(MAE 0),采用v2日期。两版均在S3,不将重绘风格回溯v1。历史对照另见quota_review/EM_v1p2.png与EM_v1_F.png。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Xiaokang Yang;50795;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[317, 70, 554, 336],PDF点、左上角原点。
Figure 2. Overview of the pipeline of EMGauss. Given a vol-
ume EM dataset (top), the gray-shaded regions denote the miss-
ing intermediate slices to be interpolated, while the visible regions
represent the available anisotropic training data. We interpret the
low-resolution z -axis as a temporal dimension and employ a de-
formable 2D Gaussian splatting representation to model the ge-
ometric evolution of 2D structures along depth. During inference,
the model synthesizes the target slice by directly conditioning on
the relative temporal coordinate corresponding to the desired in-
terpolation position.
EMGauss: Continuous Slice-to-3D Reconstruction via Dynamic Gaussian Modeling in Volume Electron Microscopy
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第2页 · P185
300 dpi PNG · 图注 · 源PDF
引言与图1对比插帧及超分辨率两种既有范式,解释跨轴各向同性假设导致域不匹配的局限。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-13;arXiv v1:2025-12-07;CVPR 2026 fixed official PDF
已查看v1(2025-12-07)图1第2页与图2第6页:图1重新布局、配色和标注;图2字体及标签排布改变。v2(2026-03-13)两图与会议版匹配(MAE 0),采用v2日期。两版均在S3,不将重绘风格回溯v1。历史对照另见quota_review/EM_v1p2.png与EM_v1_F.png。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Xiaokang Yang;50795;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 70, 298, 309],PDF点、左上角原点。
Figure 1. Different paradigms of isotropic reconstruction from
anisotropic datasets. Existing approaches typically extract vol-
ume features from abundant xy-plane images. After stacking
anisotropic slices along the z-axis (top), they: (a) Video inter-
polation along the z-axis: models are trained along the x or y
direction, where adjacent frames are input to synthesize the inter-
mediate frame; during inference, the trained model is repurposed
to interpolate along the z-axis, generating intermediate slices cor-
responding to continuous temporal coordinates (τ ∈ [0, 1]). (b)
Image super-resolution on xz/yz planes: Since the xy-plane im-
ages are of much higher resolution, a low-resolution counterpart
can be generated either by manual downsampling [21] or by learn-
ing a degradation model [6], forming paired HR–LR supervision
for training; during inference, the resulting super-resolution model
is then applied along the z-axis to enhance xz/yz slices. Both
paradigms implicitly assume spatial isotropy. In contrast, our
method directly performs inference in continuous 3D space, with-
out relying on such isotropic assumptions.
From None to All: Self-Supervised 3D Reconstruction via Novel View Synthesis
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第4页 · P184
300 dpi PNG · 图注 · 源PDF
图2明确为NAS3R完整训练路径,包含上下文/目标视图、编码、掩码解码、相机/深度/Gaussian预测及渲染监督。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-29;arXiv v1:2026-03-29;CVPR 2026 fixed official PDF
已对照固定会议版本与arXiv v1,完整布局、标签、元素与连线匹配;v1为目前最早可核实的该视觉版本。已在PDF首页核对作者及单位。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Krystian Mikolajczyk;49785;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 70, 554, 196],PDF点、左上角原点。
Figure 2. Training pipeline of NAS3R. Subscripts “C ” and “T ” denote context and target views, respectively. Unconstrained images are
patchified into visual tokens and concatenated with a learnable camera token for camera prediction. A masked decoder regulates cross-view
interactions and prevents target-to-context leakage. Refined context tokens are then processed by the Gaussian head to predict Gaussian
parameters, while a depth head estimates depth maps that are lifted into 3D Gaussian centers using the predicted context poses. The
predicted target poses are finally used to render novel views, providing photometric supervision for end-to-end training.
From None to All: Self-Supervised 3D Reconstruction via Novel View Synthesis
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第1页 · P183
300 dpi PNG · 图注 · 源PDF
引言说明三维标注获取成本及相机/结构相互依赖问题,图1用划去点云、深度、相机和预训练先验的要求示意,界定自监督问题设定;并非性能排行榜。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-29;arXiv v1:2026-03-29;CVPR 2026 fixed official PDF
已对照固定会议版本与arXiv v1,完整布局、标签、元素与连线匹配;v1为目前最早可核实的该视觉版本。已在PDF首页核对作者及单位。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Krystian Mikolajczyk;49785;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 214, 554, 403],PDF点、左上角原点。
Figure 1. NAS3R is a self-supervised framework that requires no ground-truth annotations and no pretrained priors during training, and
jointly infers 3D Gassian parameters, camera intrinsics and extrinsics and depth maps, also enabling high-quality novel view synthesis.
G$^2$VLM: Geometry Grounded Vision Language Model with Unified 3D Reconstruction and Spatial Reasoning
会议:CVPR 2026 · 主会论文
Figure 3 · PDF第3页 · P190
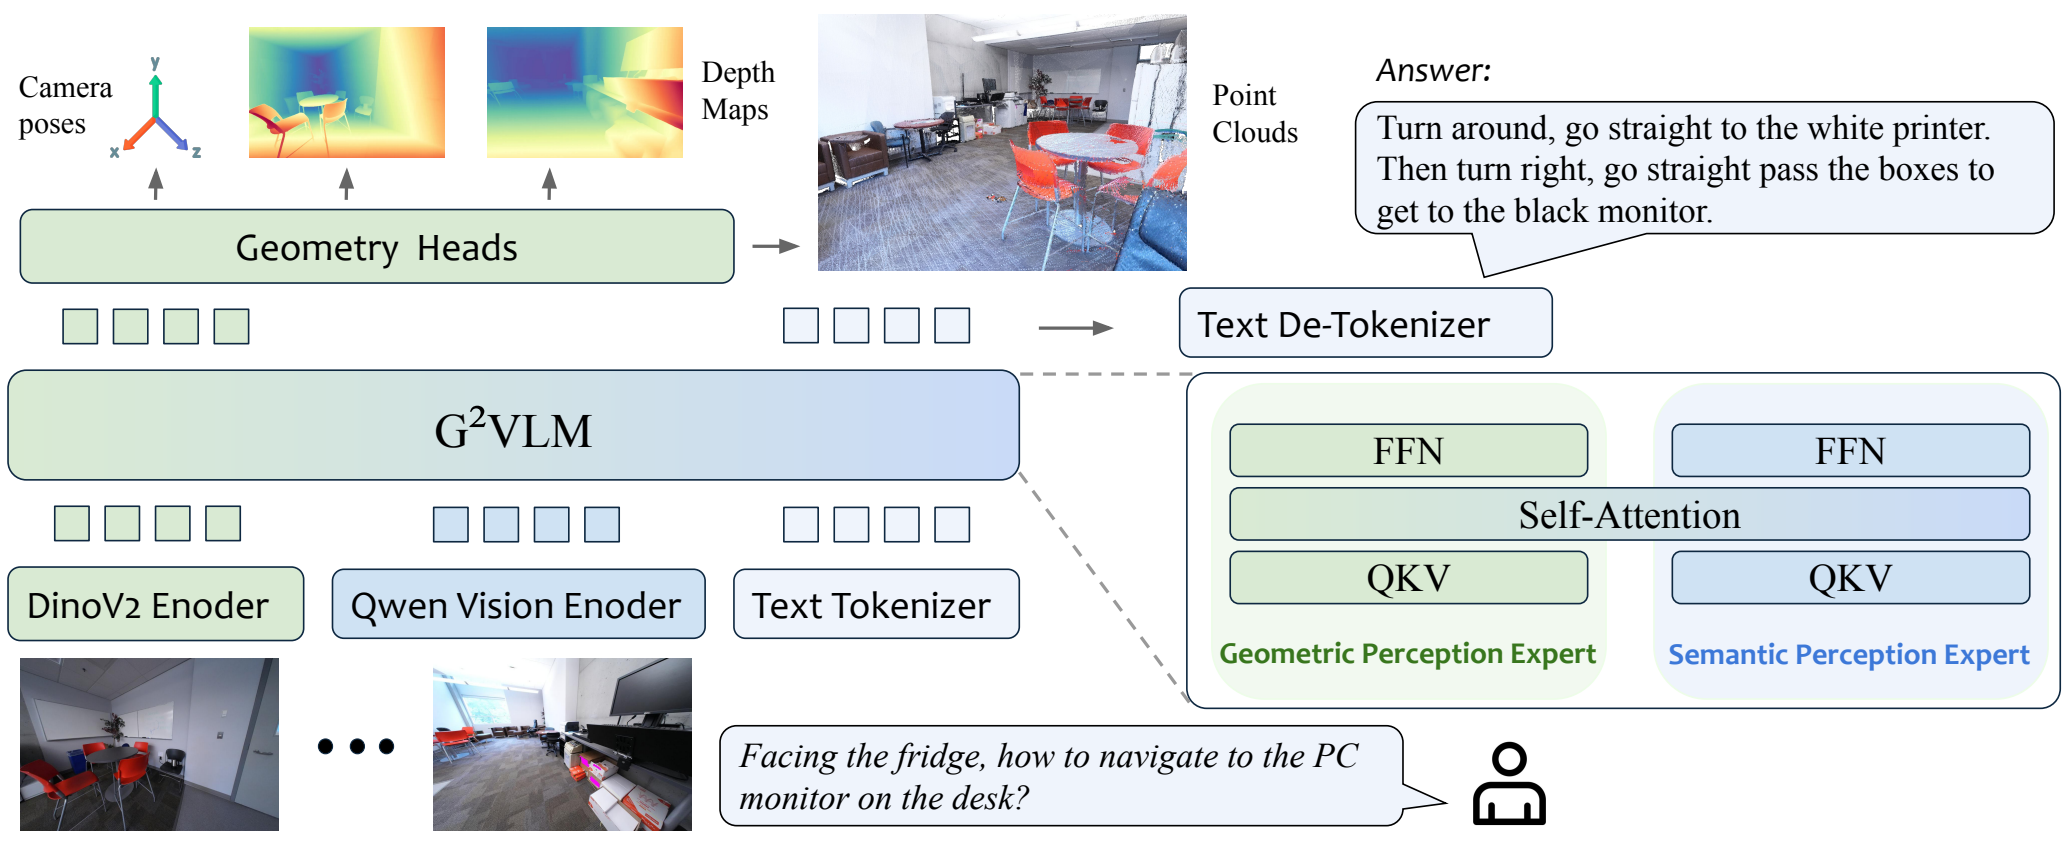
300 dpi PNG · 图注 · 源PDF
第3节Model Architecture引用图3展示整个输入编码、双专家、几何输出及语言输出路径;图2只概括双流专家关系。
完整图注、版本和筛选证据
最早核实视觉日期:2025-11-26;arXiv v1:2025-11-26;CVPR 2026 fixed official PDF
已对照固定会议版本与arXiv v1,完整布局、标签、元素与连线匹配;v1为目前最早可核实的该视觉版本。已在PDF首页核对作者及单位。 作者Jiangmiao Pang个人主页oceanpang.github.io写明Shanghai AI Lab,且链接至与引用快照相同的Scholar ID ssSfKpAAAAAJ;Scholar单位字段较旧。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jiangmiao Pang;26222;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 70, 555, 274],PDF点、左上角原点。
Figure 3. We present G²VLM, a unified model that integrates both a geometric perception expert for 3D reconstruction and a semantic
perception expert for multimodal understanding and spatial reasoning tasks. All tokens can do shared multi-modal self attention in each
transformer block.
G$^2$VLM: Geometry Grounded Vision Language Model with Unified 3D Reconstruction and Spatial Reasoning
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第1页 · P189
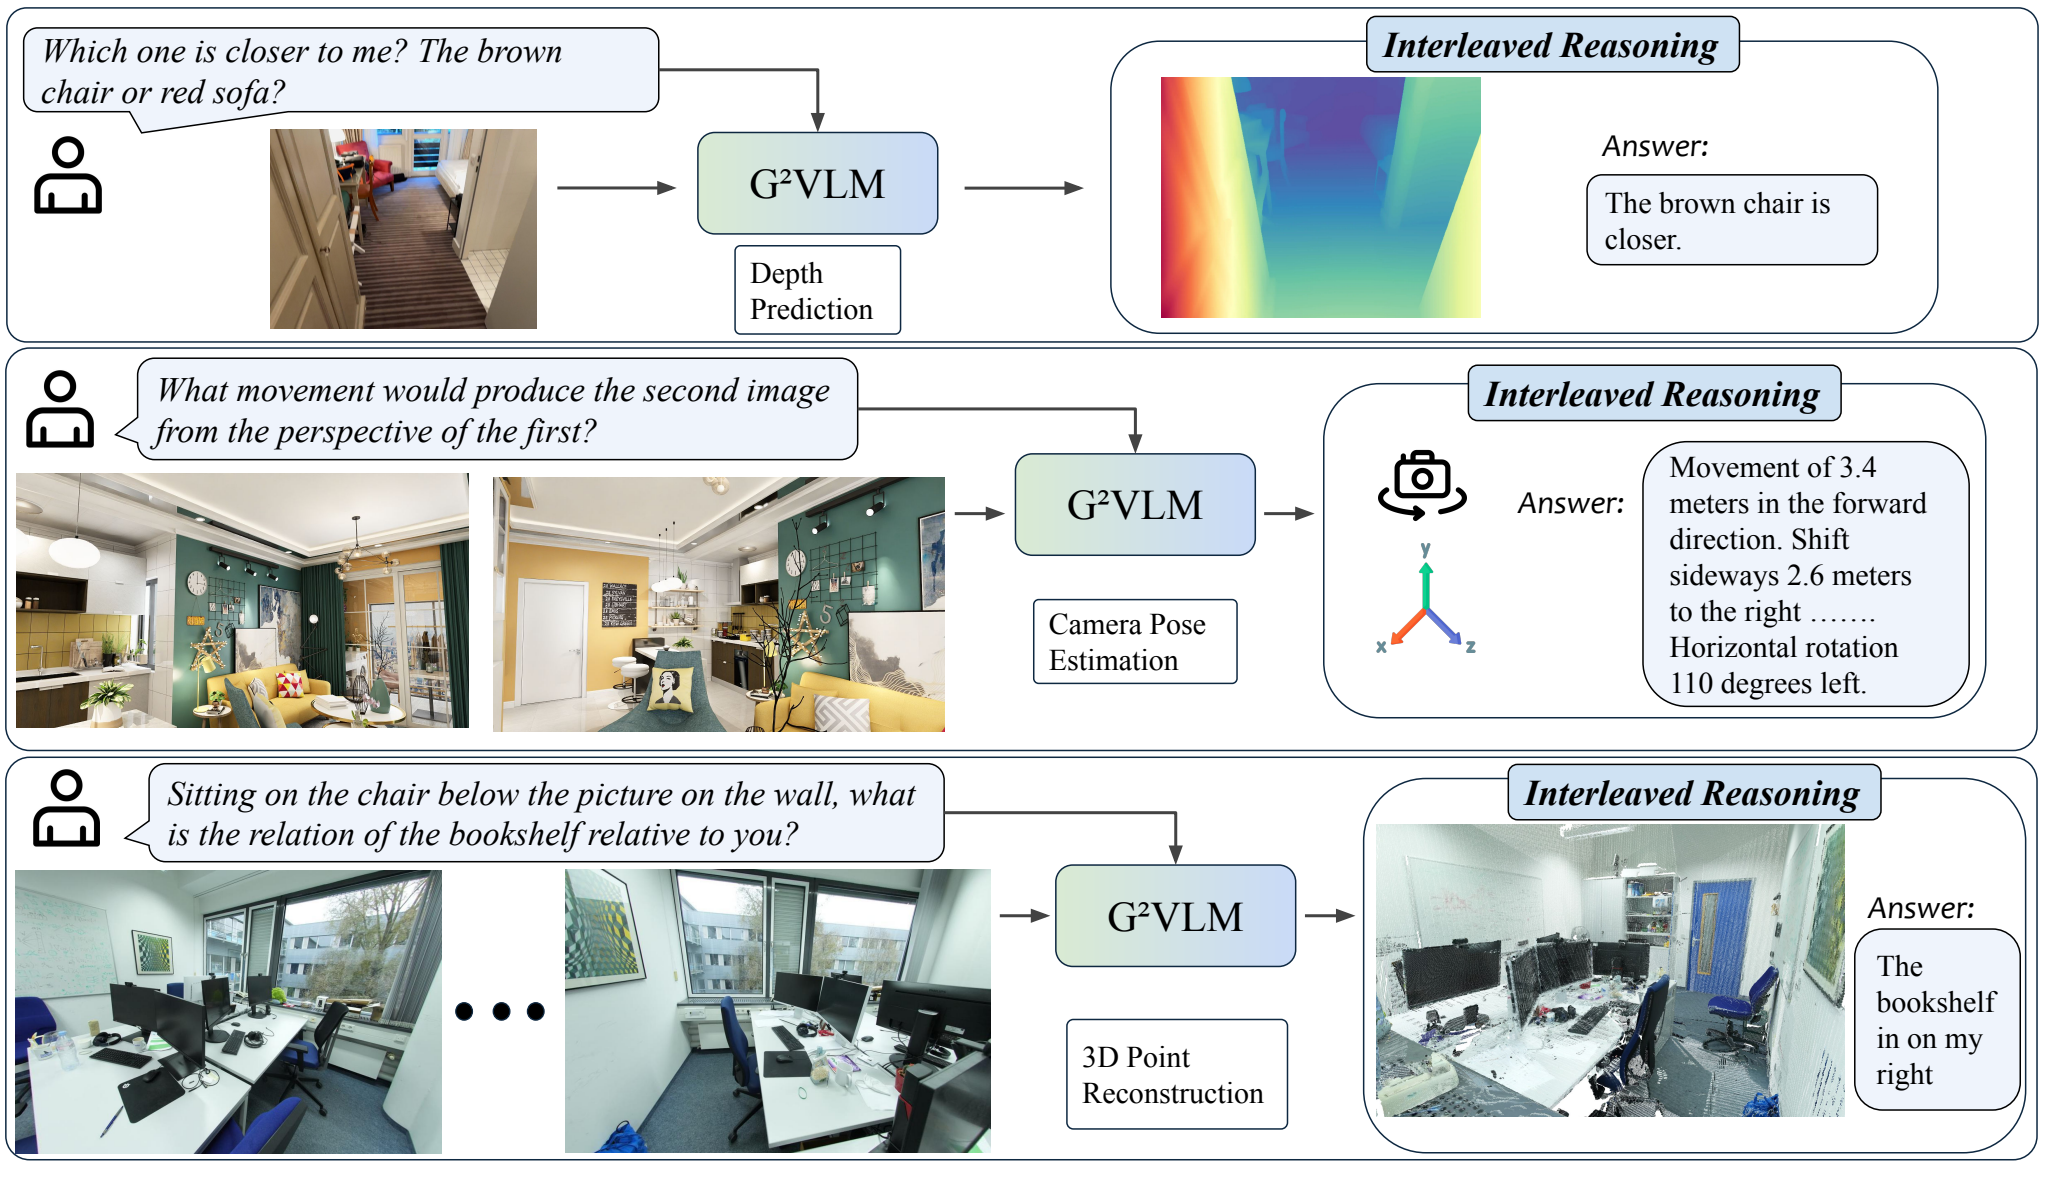
300 dpi PNG · 图注 · 源PDF
图1用距离判断、相机运动和物体方位三个应用情境解释三维几何对空间理解的需求;属于应用场景动机。
完整图注、版本和筛选证据
最早核实视觉日期:2025-11-26;arXiv v1:2025-11-26;CVPR 2026 fixed official PDF
已对照固定会议版本与arXiv v1,完整布局、标签、元素与连线匹配;v1为目前最早可核实的该视觉版本。已在PDF首页核对作者及单位。 作者Jiangmiao Pang个人主页oceanpang.github.io写明Shanghai AI Lab,且链接至与引用快照相同的Scholar ID ssSfKpAAAAAJ;Scholar单位字段较旧。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jiangmiao Pang;26222;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 254, 550, 537],PDF点、左上角原点。
Figure 1. We present G²VLM, a geometry grounded vision-language model proficient in both spatial 3D reconstruction and spatial
understanding tasks. For spatial reasoning questions, G²VLM can predict 3D geometry and employ interleaved reasoning for an answer.
PanoVGGT: Feed-Forward 3D Reconstruction from Panoramic Imagery
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第4页 · P204
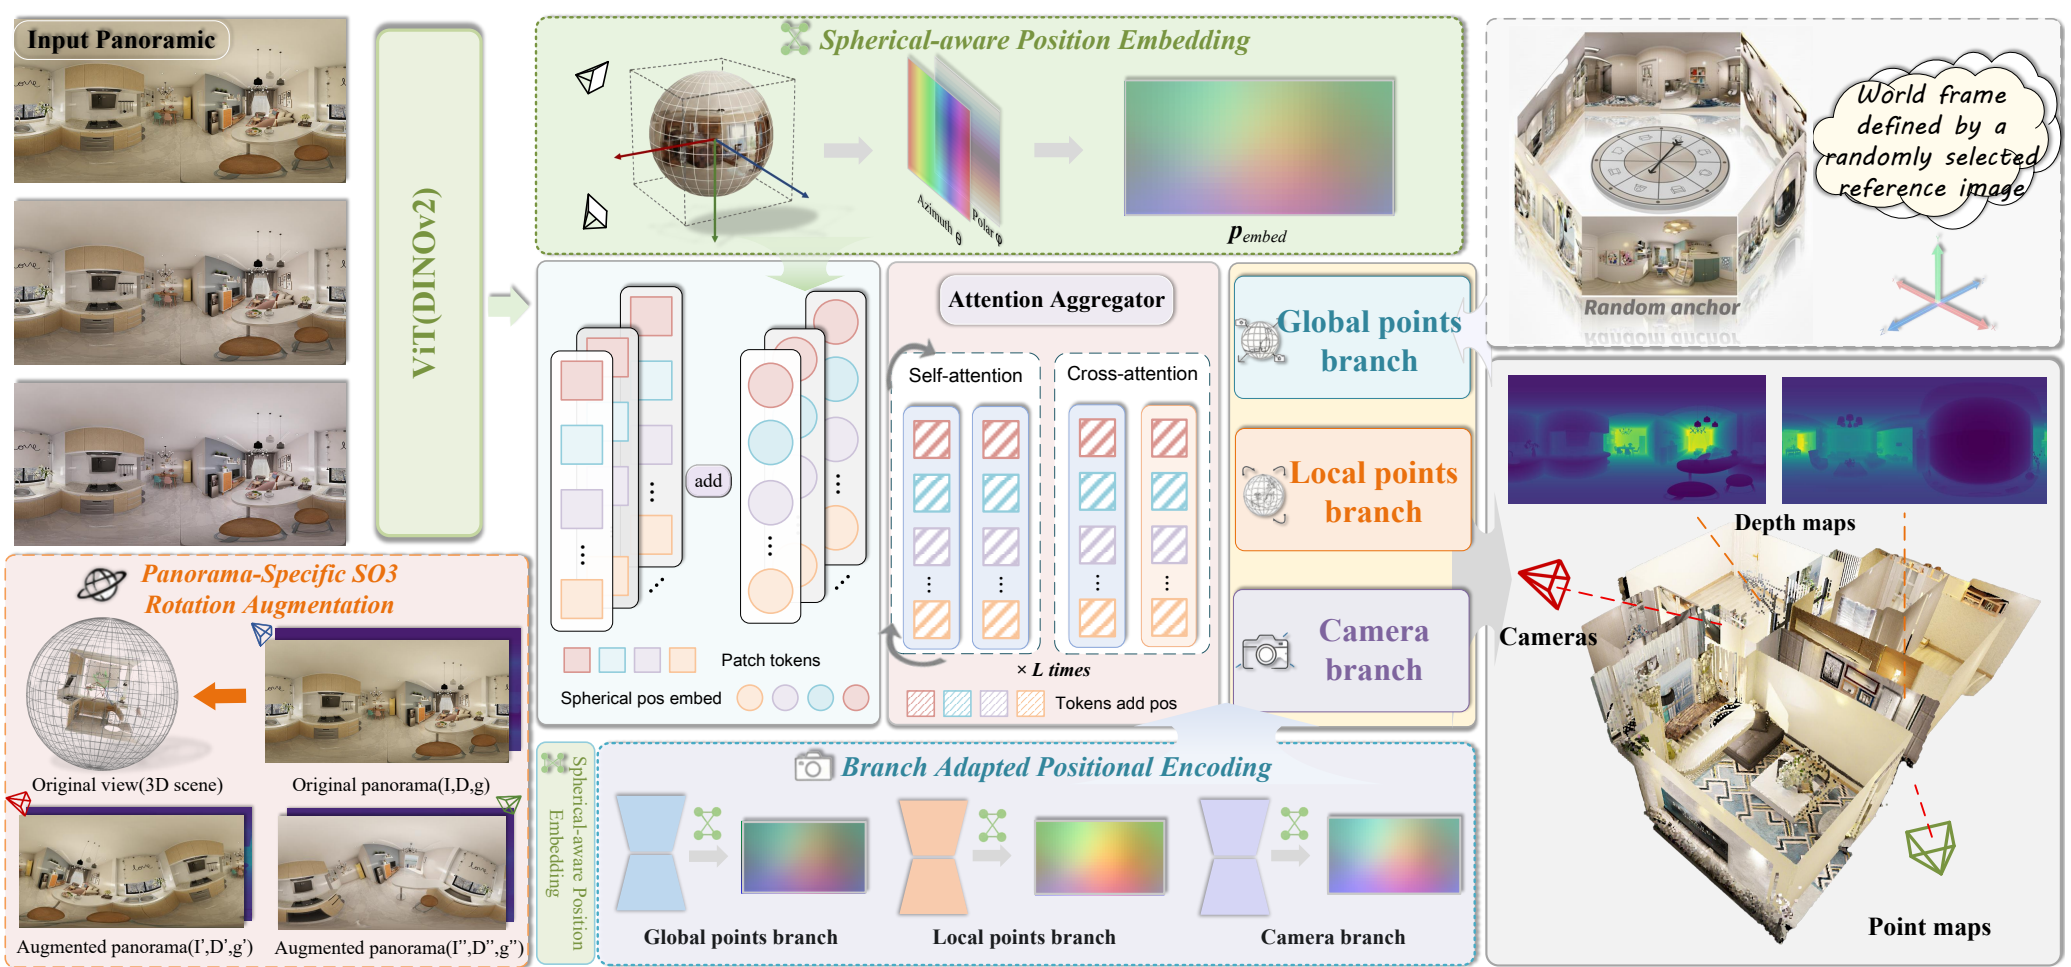
300 dpi PNG · 图注 · 源PDF
图2明确为PanoVGGT整体模型,保留图像编码、聚合、几何输出与完整图例。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-18;arXiv v1:2026-03-18;CVPR 2026 fixed official PDF
已核对固定会议PDF和arXiv v1的完整目标图;构图、文字、配色、元素和连线一致,v1为目前最早可核实的视觉版本。作者和机构已在PDF首页与公开引用主页交叉核对。 图1在会议版整体下移8.28 PDF点,平移对齐后像素平均差0.015/255;图2平均差小于0.001,未发现重绘。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jingyi Yu;24450;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 70, 555, 302],PDF点、左上角原点。
Figure 2. Overview of the proposed PanoVGGT framework. Given one or multiple panoramic images, PanoVGGT extracts spherical
patch tokens using a ViT backbone, augments them via S O(3) geometric augmentation, and encodes them with shared and branch-adapted
positional embeddings. A multi-branch attention aggregator jointly reasons about local geometry, global structure, and camera motion.
The model outputs dense depth maps, camera poses (under a randomly selected global anchor), and local/global point maps for final 3D
reconstruction.
PanoVGGT: Feed-Forward 3D Reconstruction from Panoramic Imagery
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第1页 · P203
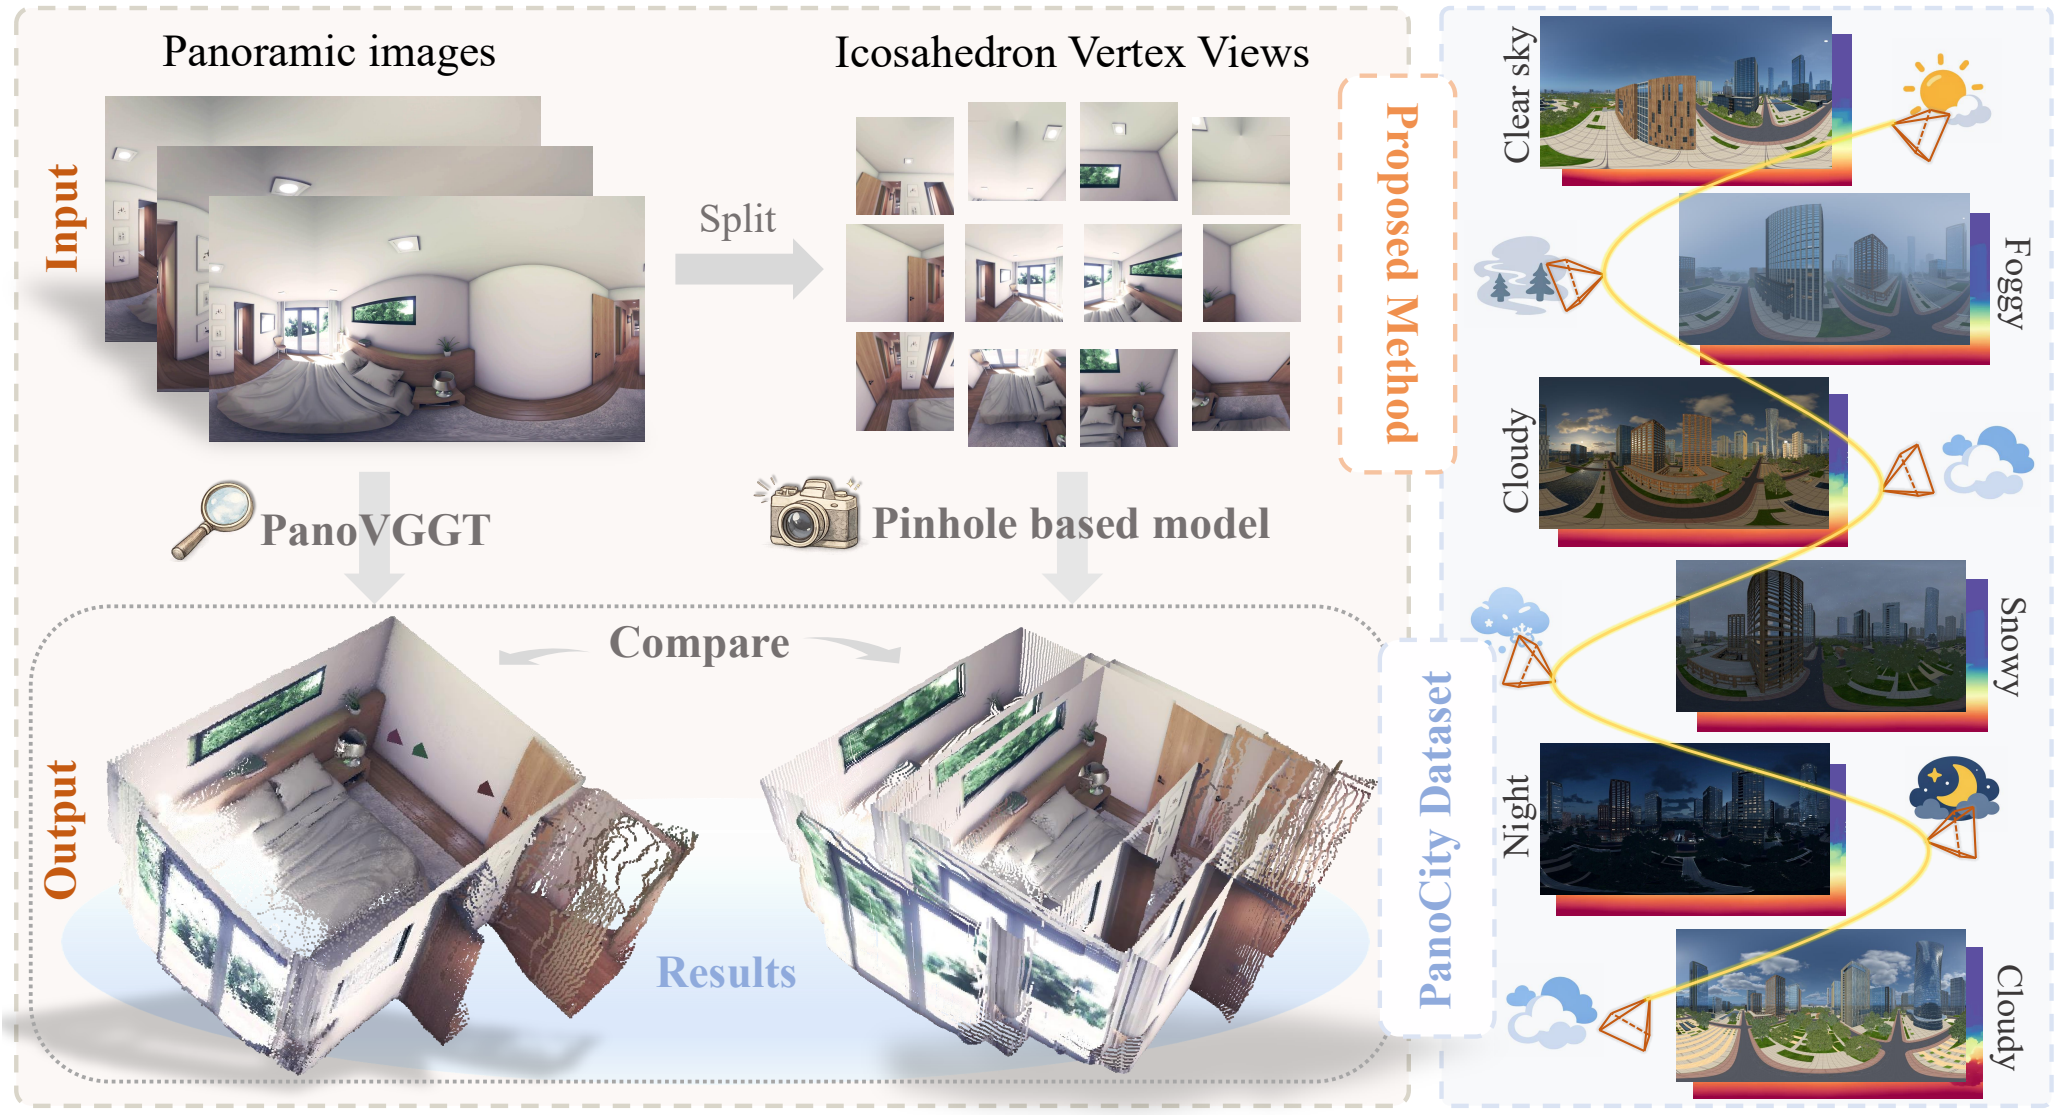
300 dpi PNG · 图注 · 源PDF
图1通过全景图与针孔切分的概念对比说明几何畸变和覆盖局限,并展示不同天气下的应用情境。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-18;arXiv v1:2026-03-18;CVPR 2026 fixed official PDF
已核对固定会议PDF和arXiv v1的完整目标图;构图、文字、配色、元素和连线一致,v1为目前最早可核实的视觉版本。作者和机构已在PDF首页与公开引用主页交叉核对。 图1在会议版整体下移8.28 PDF点,平移对齐后像素平均差0.015/255;图2平均差小于0.001,未发现重绘。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jingyi Yu;24450;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[58, 211, 555, 479],PDF点、左上角原点。
Figure 1. Overview of PanoVGGT and the PanoCity dataset. PanoVGGT predicts camera poses, dense depth, and consistent 3D point
clouds from unordered panoramas. Compared with perspective-based pipelines that split panoramas into pinhole views, it yields more
accurate 3D reconstructions. PanoCity contains over 120k outdoor panoramas under diverse urban scenes and weather conditions.
PoInit-of-View: Poisoning Initialization of Views Transfers Across Multiple 3D Reconstruction Systems
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第3页 · P78
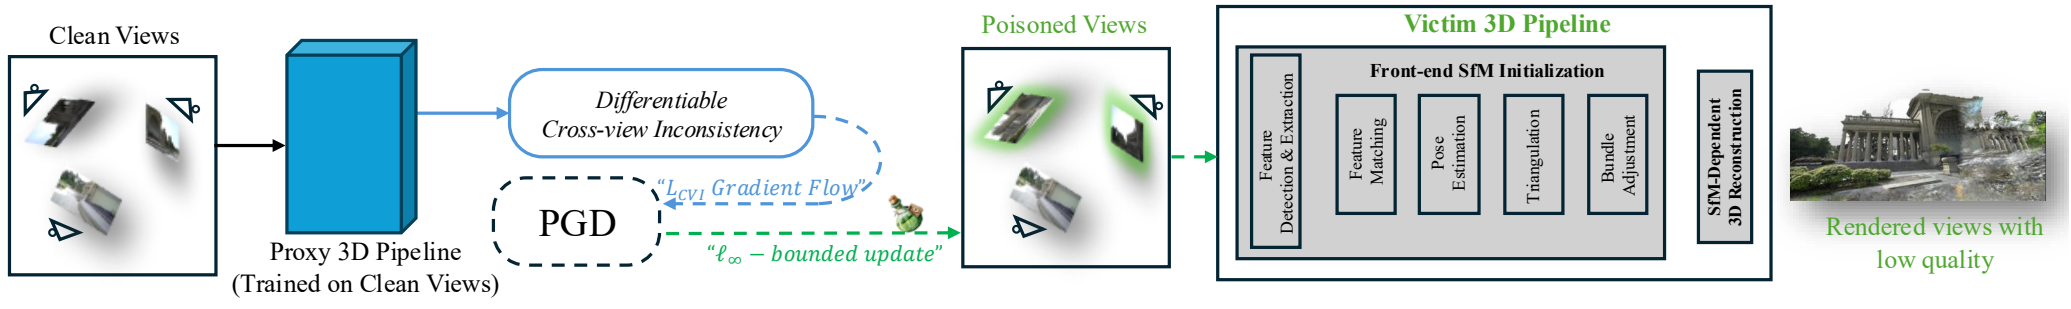
300 dpi PNG · 图注 · 源PDF
第3.2节和图2给出从代理重建、跨视图梯度、扰动生成到目标三维重建系统的整体计算路径。
完整图注、版本和筛选证据
最早核实视觉日期:2026-04-17;arXiv v1:2026-04-17;CVPR 2026 fixed official PDF
已查看固定PDF及目标图;以最早已核实匹配版本日期作时间代理,不声称实际作图日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Nicu Sebe;59898;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[57, 72, 554, 146],PDF点、左上角原点。
Figure 2. Framework of PoInit-of-View.
PoInit-of-View: Poisoning Initialization of Views Transfers Across Multiple 3D Reconstruction Systems
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第1页 · P77
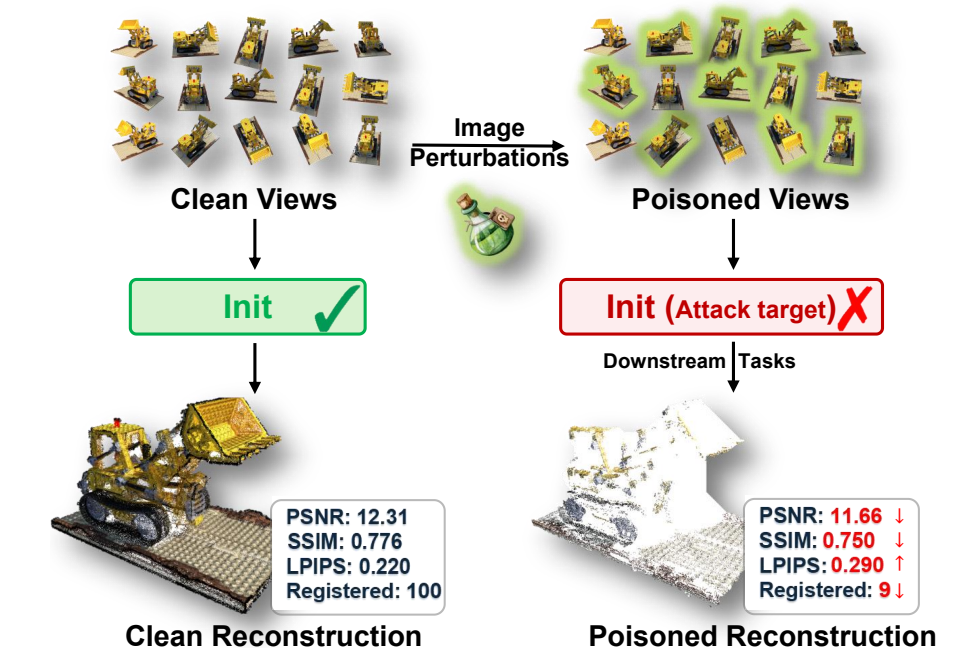
300 dpi PNG · 图注 · 源PDF
引言图1比较干净与扰动视图,解释SfM初始化脆弱性如何传播为三维重建失败。
完整图注、版本和筛选证据
最早核实视觉日期:2026-04-17;arXiv v1:2026-04-17;CVPR 2026 fixed official PDF
已查看固定PDF及目标图;以最早已核实匹配版本日期作时间代理,不声称实际作图日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Nicu Sebe;59898;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[317, 232, 551, 390],PDF点、左上角原点。
Figure1. OurPoInit-of-Viewmethodinjectsimperceptiblepertur-
bations into input views (top) to induce cross-view inconsistency
(seedetailsinFigure3)inthefoundationalStructure-from-Motion
(SfM)initializationratherthanthesingle-view-basedlossinexist-
ing attacks. The corrupted feature correspondences propagate to
inaccurate point triangulation, leading to erroneous camera poses
and severely degraded 3D reconstruction results (bottom). Com-
paredtocleanviews,ourpoisonedinputsyieldfarfewerregistered
images, and as a result, lower quality of rendered views.
RayMap3R: Inference-Time RayMap for Dynamic 3D Reconstruction
会议:ECCV 2026 · 主会论文
Figure 4 · PDF第7页 · P202
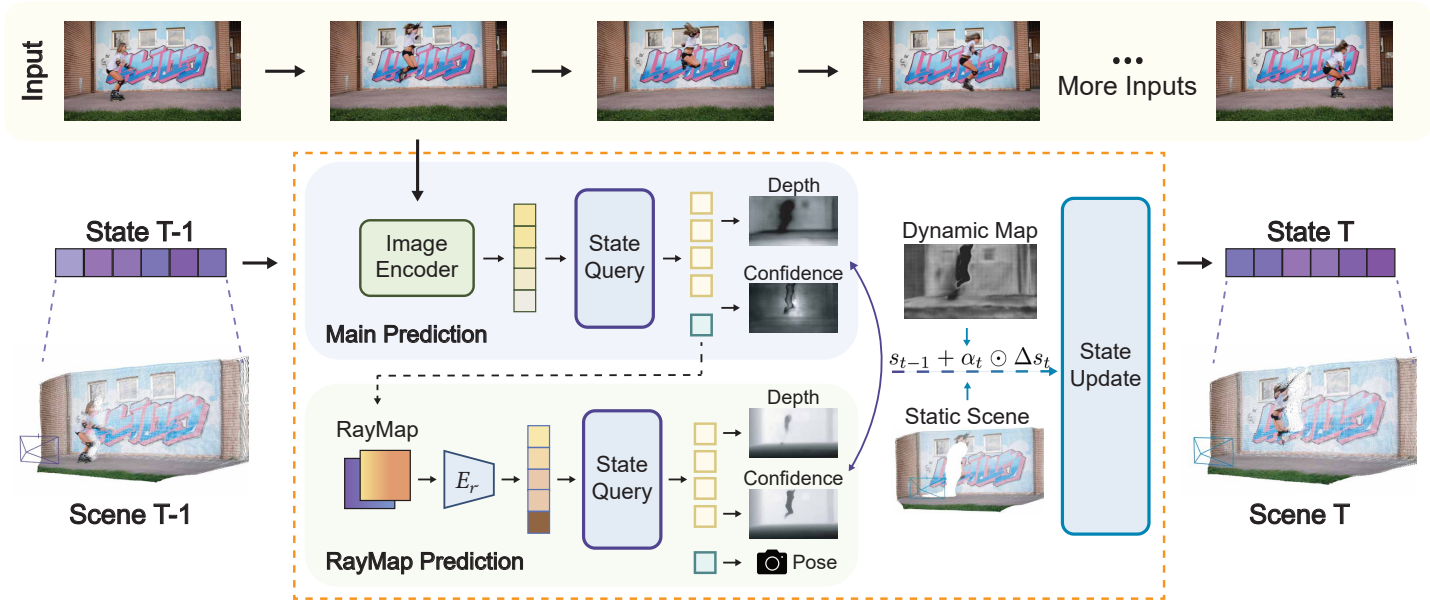
300 dpi PNG · 图注 · 源PDF
图4为RayMap3R总体架构,展示双分支、RayMap生成、融合与三维预测的主要计算路径。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-21;arXiv v1:2026-03-21;ECCV 2026 fixed official PDF
已核对固定会议PDF和arXiv v1的完整目标图;构图、文字、配色、元素和连线一致,v1为目前最早可核实的视觉版本。作者和机构已在PDF首页与公开引用主页交叉核对。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yan Yan;13225;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[135, 116, 478, 262],PDF点、左上角原点。
Fig. 4: Method Overview. Our method performs streaming 3D reconstruction via
dual-branch inference. At time step t, the main branch predicts depth and pose from
state s using both image and RayMap features. The predicted pose Tˆ is remapped
t−1 t
into RayMap and encoded into tokens r′ , then queried against the frozen state s
t t−1
by the RayMap branch to obtain a static-biased prediction. The depth difference
between branches is pro jected via image-state attention to form staticness weights α
t
that suppress dynamic regions during state update (s = s + α ⊙ ∆s ). This dual-
t t−1 t t
branch scheme identifies and suppresses dynamic regions at inference time.
RayMap3R: Inference-Time RayMap for Dynamic 3D Reconstruction
会议:ECCV 2026 · 主会论文
Figure 2 · PDF第6页 · P201
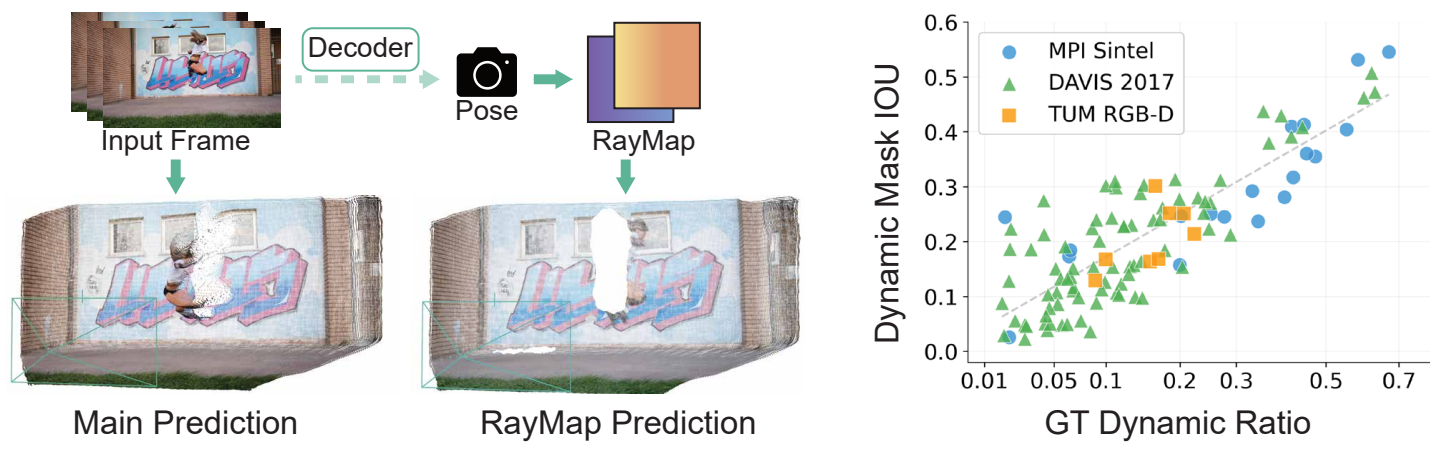
300 dpi PNG · 图注 · 源PDF
图2的静态偏差可视化与动态占比关联构成正文核心观察,解释静态先验在动态场景下的局限;图1是重建结果比较。
完整图注、版本和筛选证据
最早核实视觉日期:2026-03-21;arXiv v1:2026-03-21;ECCV 2026 fixed official PDF
已核对固定会议PDF和arXiv v1的完整目标图;构图、文字、配色、元素和连线一致,v1为目前最早可核实的视觉版本。作者和机构已在PDF首页与公开引用主页交叉核对。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yan Yan;13225;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[135, 116, 478, 227],PDF点、左上角原点。
Fig. 2: RayMap Static Bias. Left: The main prediction and RayMap prediction pro-
duce differing depth estimates in dynamic regions, suggesting a static bias in RayMap
predictions. Right: The depth discrepancy correlates with ground-truth dynamic ratio
across multiple datasets, suggesting a consistent signal for dynamic identification.
Seeing through Light and Darkness: Sensor-Physics Grounded Deblurring HDR NeRF from Single-Exposure Images and Events
会议:CVPR 2026 · 主会论文
Figure 3 · PDF第4页 · P10
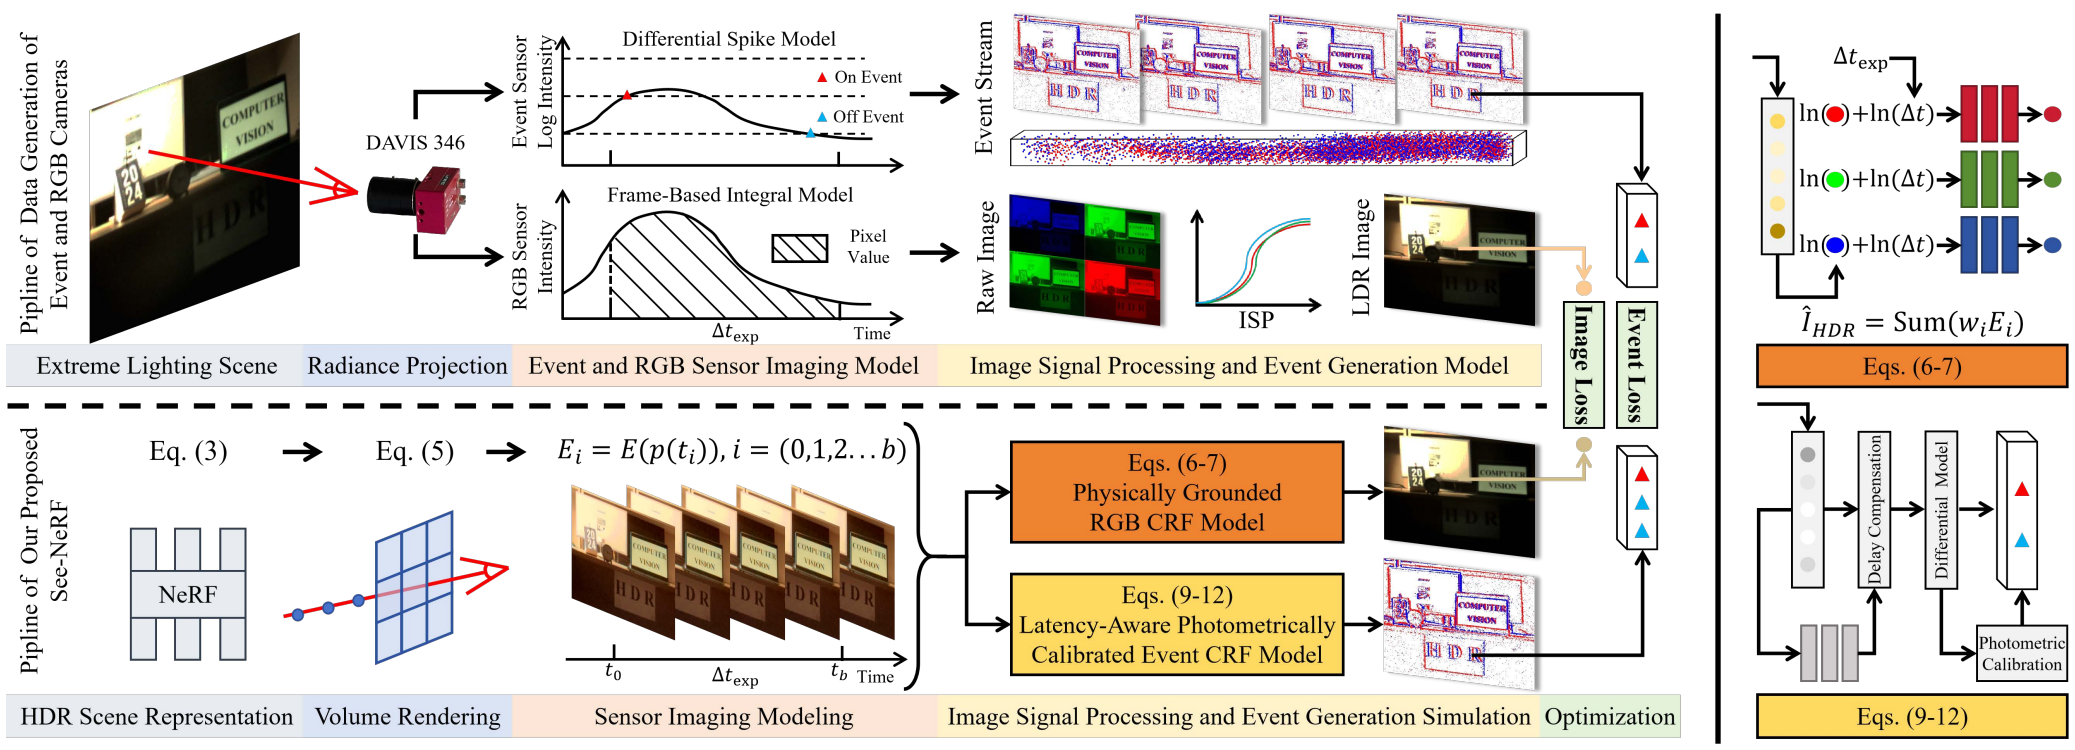
300 dpi PNG · 图注 · 源PDF
图注与第4节说明从真实相机成像到NeRF、体渲染、RGB/事件CRF及两路监督的完整训练流程;不是单独CRF模块图4。
完整图注、版本和筛选证据
最早核实视觉日期:2026-04-02;arXiv v1:2026-01-21;CVPR 2026 fixed official open-access version
核查v1(2026-01-21)、v2(2026-02-02)、v3(2026-03-13)、v4(2026-04-02)及会议固定版;v1-v3使用Mapping Field标签,v4改为RGB CRF Model/Event CRF Model并与会议目标图匹配。不能套用v1日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jia Li;12248;快照2026-10-21。
绘图工具:unknown。已读图注、引言和方法段落;未获得插图制作工具声明。
裁剪坐标:[57, 70, 555, 250],PDF点、左上角原点。
Figure 3. The data generation process of event and RGB cameras (upper parts) and the pipeline of See-NeRF (lower parts) are shown in the
figure. We use NeRF to represent the actual radiance of an extreme lighting scene in the HDR domain. The volume rendering simulates the
raw scene radiance rays hitting the sensor and obtaining the raw sensor values. The predicted LDR images and events are generated with our
proposed sensor-physics grounded RGB and event CRF models (details are shown in the right part of the figure). The image loss and event
loss are employed to jointly supervise the optimization of the two CRF models and the NeRF network.
Seeing through Light and Darkness: Sensor-Physics Grounded Deblurring HDR NeRF from Single-Exposure Images and Events
会议:CVPR 2026 · 主会论文
Figure 1 · PDF第1页 · P09
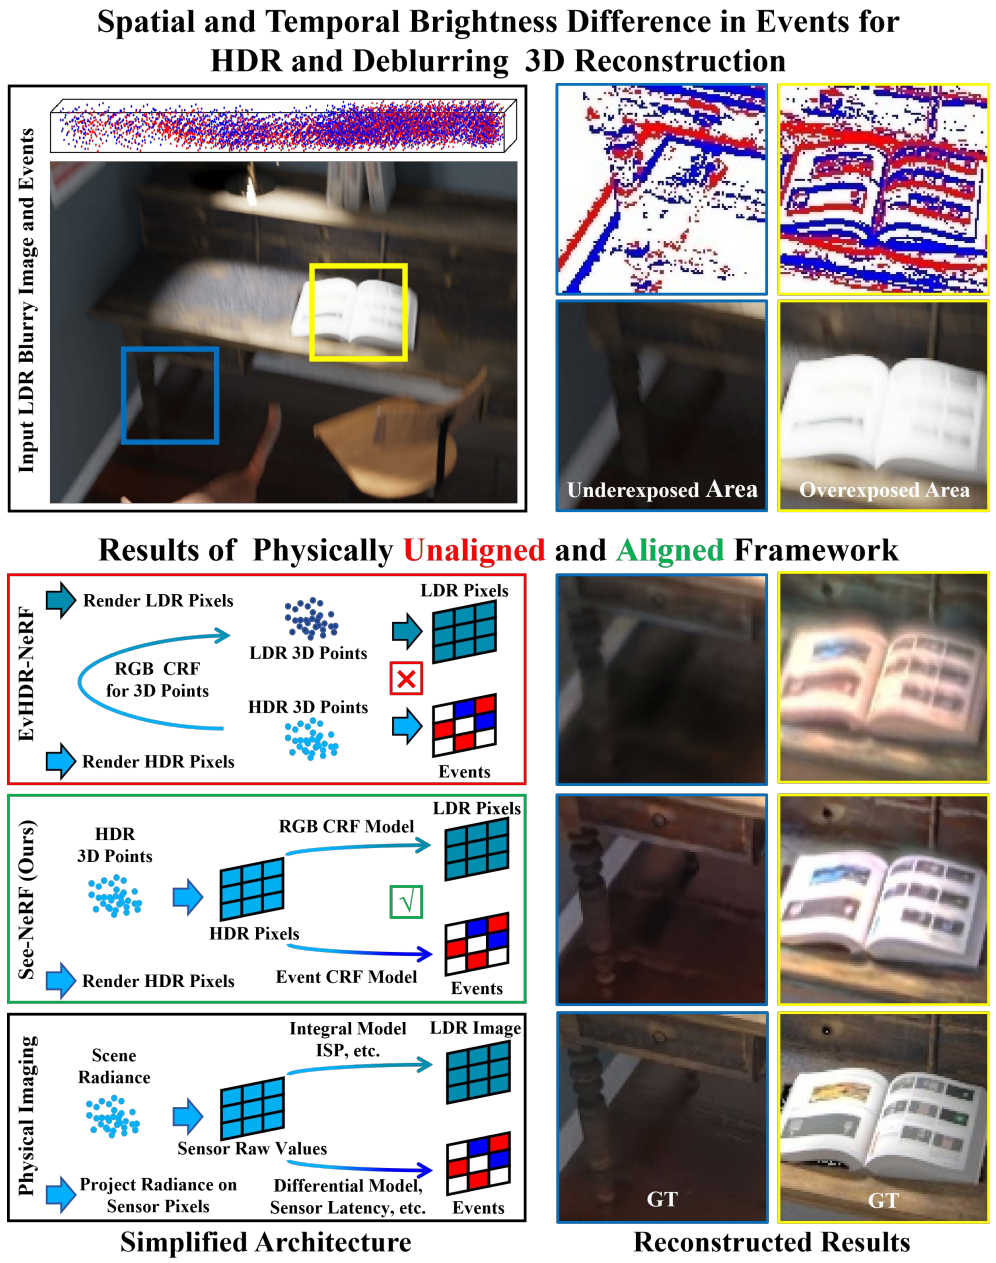
300 dpi PNG · 图注 · 源PDF
引言第2页以事件信息对比解释暗部/亮部和运动模糊信息丢失,并用未物理对齐方法的失败案例引出问题。图内简化结构用于概念比较;整体框架另见图3。
完整图注、版本和筛选证据
最早核实视觉日期:2026-04-02;arXiv v1:2026-01-21;CVPR 2026 fixed official open-access version
核查v1(2026-01-21)、v2(2026-02-02)、v3(2026-03-13)、v4(2026-04-02)及会议固定版;v1-v3使用Mapping Field标签,v4改为RGB CRF Model/Event CRF Model并与会议目标图匹配。不能套用v1日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jia Li;12248;快照2026-10-21。
绘图工具:unknown。已读图注、引言和方法段落;未获得插图制作工具声明。
裁剪坐标:[316, 255, 555, 558],PDF点、左上角原点。
Figure 1. Events corresponding to a blurry LDR image contain
spatial difference (High Dynamic Range) and temporal difference
(High Temporal Resolution) information of the scene radiance,
making it an ideal data for enhancing HDR sharp 3D scene recon-
struction. See-NeRF models the physical imaging process with
proposed RGB and event CRF models to bridge the sensor-physics
discrepancy, leveraging events to infer scene dynamics and achiev-
ing sharper and better HDR novel view synthesis results compared
to the physical unaligned method EvHDR-NeRF [5].
SplatSuRe: Selective Super-Resolution for Multi-view Consistent 3D Gaussian Splatting
会议:CVPR 2026 · 主会论文
Figure 2 · PDF第3页 · P118
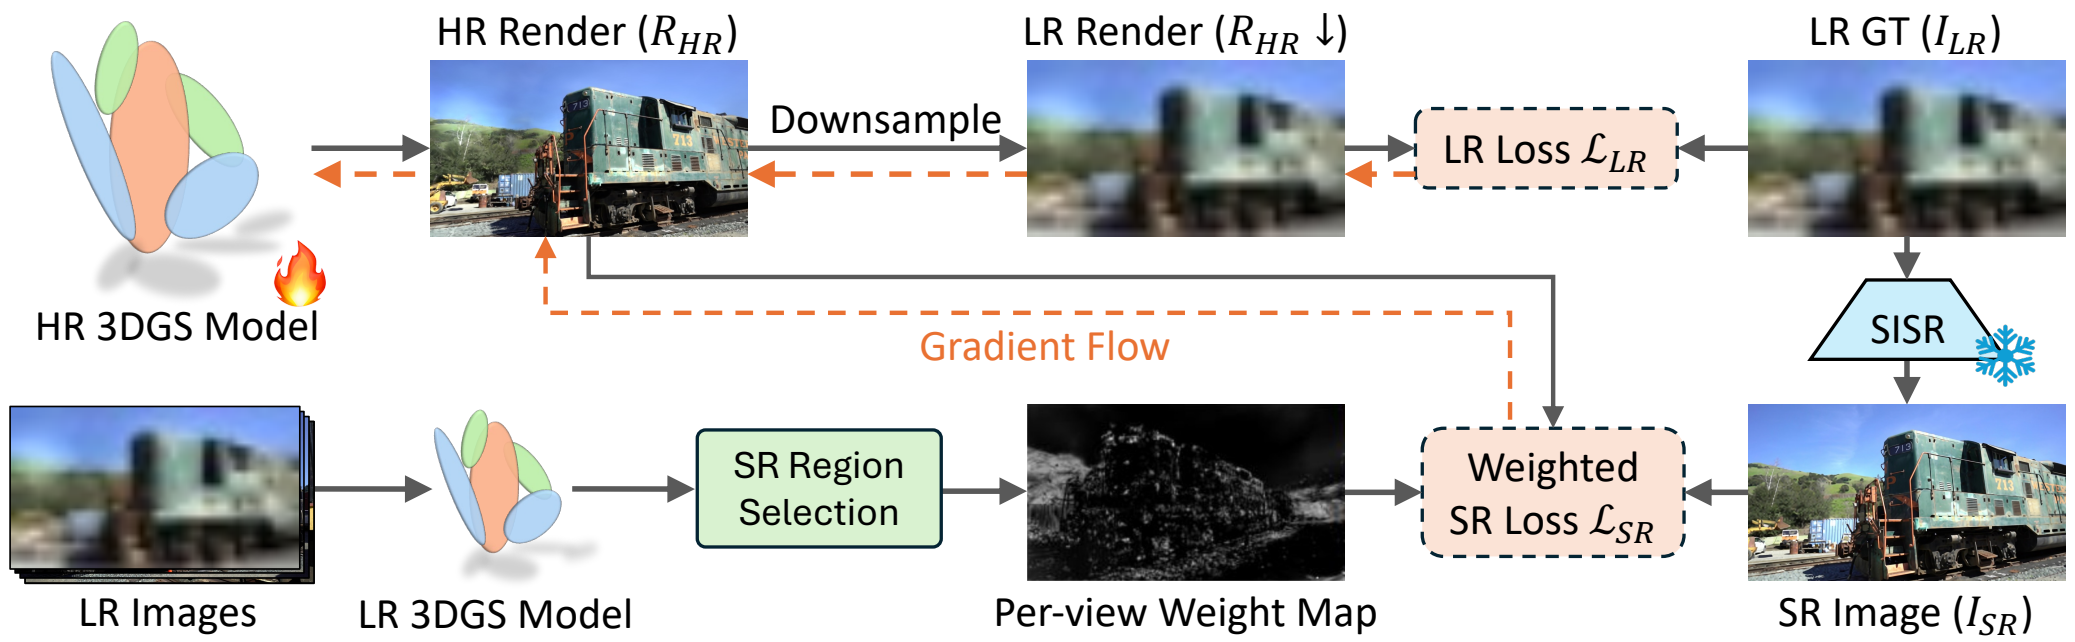
300 dpi PNG · 图注 · 源PDF
图2及方法部分给出LR三维模型、区域选择、SR模型与HR三维模型及两种损失的整体训练关系;主要任务为场景三维重建。
完整图注、版本和筛选证据
最早核实视觉日期:2025-12-01;arXiv v1:2025-12-01;CVPR 2026 fixed official PDF
固定会议PDF与arXiv v1目标图按对应坐标逐图比对;像素均差为0;arXiv v1与已知会议投稿均在指定阶段。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Matthias Zwicker;17011;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[57, 71, 555, 225],PDF点、左上角原点。
Figure 2. Overview of our SplatSuRe framework. A high-resolution (HR) 3D Gaussian Splatting (3DGS) model is trained using low-
resolution (LR) and super-resolution (SR) inputs. We first train a 3DGS model on LR inputs to identify undersampled regions and render
per-view weight maps that indicate where SR is needed. During training of the HR 3DGS model, the images produced by the frozen
single-image super-resolution (SISR) model are spatially weighted by these maps to form the SR loss L . A complementary LR loss
SR
L compares the downsampled HR render against the original LR ground truth to provide consistent supervision across the entire image.
LR
SplatSuRe: Selective Super-Resolution for Multi-view Consistent 3D Gaussian Splatting
会议:CVPR 2026 · 主会论文
Figure 3 · PDF第4页 · P117
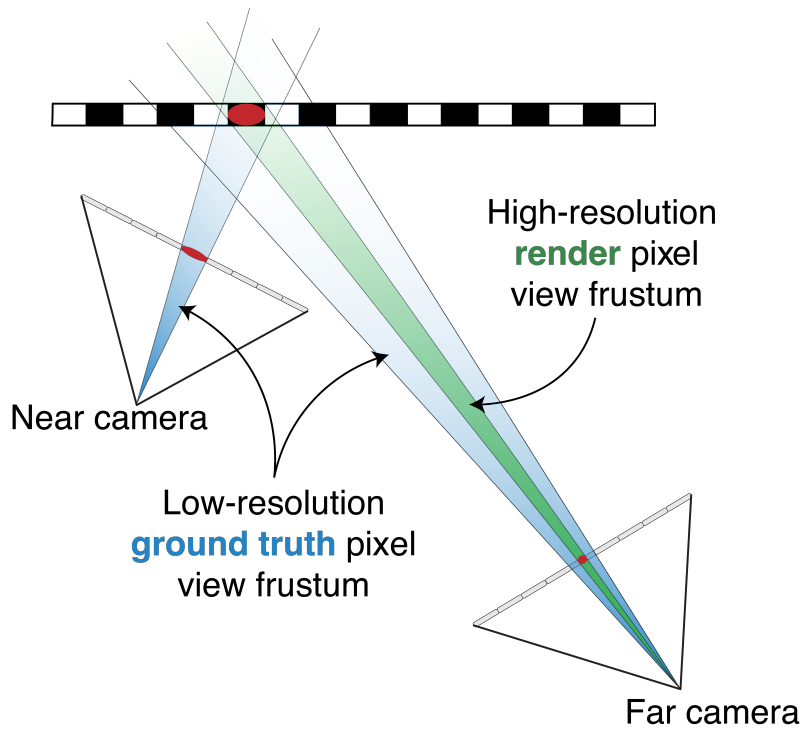
300 dpi PNG · 图注 · 源PDF
第3.2节和图3说明不同距离视图对高频细节的约束不同,统一施加二维超分辨率会引入多视图不一致;此为几何问题示意,图1的结果展示不计M。
完整图注、版本和筛选证据
最早核实视觉日期:2025-12-01;arXiv v1:2025-12-01;CVPR 2026 fixed official PDF
固定会议PDF与arXiv v1目标图按对应坐标逐图比对;像素均差为0;arXiv v1与已知会议投稿均在指定阶段。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Matthias Zwicker;17011;快照2026-10-21。
绘图工具:unknown。未发现可核实的绘图工具披露;不根据外观猜测。
裁剪坐标:[337, 70, 531, 249],PDF点、左上角原点。
Figure 3. Disparity in high-frequency ground truth informa-
tion across different views. Low-resolution ground truth from
near cameras provides high-resolution information for rendering
distant views, reducing the need for additional generated detail
in those views. Conversely, super-resolution is needed in views
where no other camera provides higher-resolution information.
AnyDepth-DETR/-YOLO: Any-depth object detection with a single network
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_8qFCNFz8Tq_F
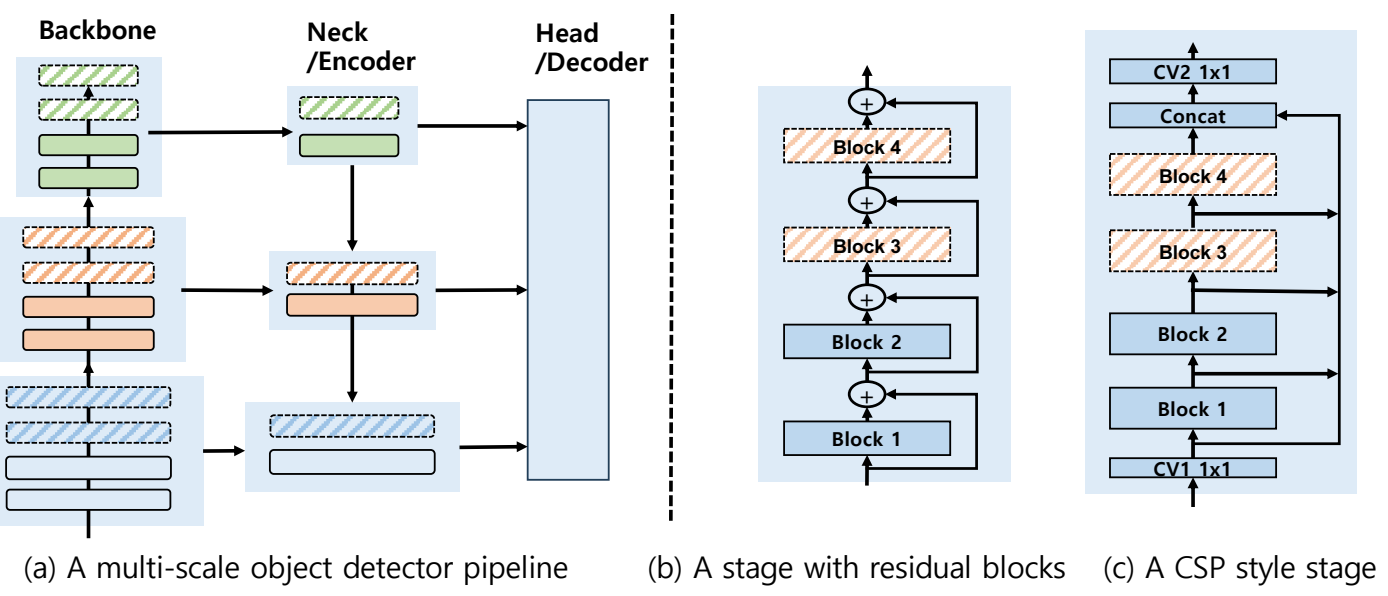
300 dpi PNG · 图注 · 源PDF
图1(a)为整体backbone-neck-head路径,同图(b)(c)解释两类可跳过阶段,完整图保留全部子图。
完整图注、版本和筛选证据
最早核实视觉日期:2026-05-10;arXiv v1:2026-05-10;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
v1多尺度可变深度结构匹配,正文排版位置不同
历史PDF · 公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[144, 79, 477, 222],PDF点、左上角原点。
Figure 1: (a) Overall pipeline of our any-depth object detection network, following the standard
backbone–neck–head design common to modern detectors such as RT-DETR and YOLO, operating
on multi-scale features. Each stage in both the backbone and neck is divided into an essential path
(solid blocks) and a skippable refinement path (dashed blocks). At inference time, any combination
of essential and full paths across stages yields a valid sub-network, enabling a continuous range of
accuracy–efficiency trade-offs from a single set of weights. (b) A residual-block stage, as used in
RT-DETR. (c) A CSP-style stage, as used in the YOLO family. In both stage types, the essential and
full paths are jointly trained via self-distillation to produce aligned feature representations at each
stage boundary, so that downstream stages can process the output of either path reliably.
AnyDepth-DETR/-YOLO: Any-depth object detection with a single network
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第6页 · ICLR27_8qFCNFz8Tq_M
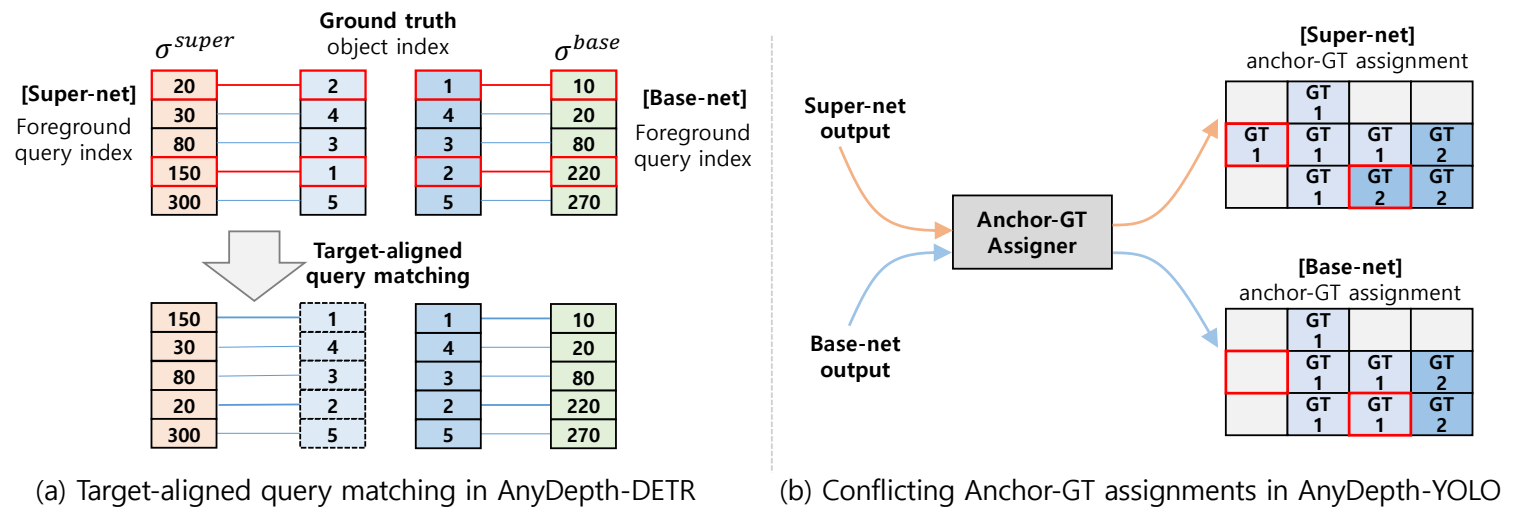
300 dpi PNG · 图注 · 源PDF
图2及3.2节具体示意不同路径将同一GT分配给不同查询/锚点的冲突,为目标对齐蒸馏提供问题依据。
完整图注、版本和筛选证据
最早核实视觉日期:2026-05-10;arXiv v1:2026-05-10;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
v1目标指派冲突示意匹配
历史PDF · 公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[124, 79, 491, 203],PDF点、左上角原点。
Figure 2: Conflicting target assignment in any-depth detectors. (a) In AnyDepth-DETR, the Hungarian
matcher can assign different queries to the same ground-truth objects across the two execution paths.
We reorder the super-net’s foreground queries to align with the base-net’s target-matched query
ordering before applying KD. (b) In AnyDepth-YOLO, the Task-Aligned Assigner (TAL) can assign
the super-net and base-net outputs to different anchors for the same ground-truth object. We exclude
conflicting anchor assignments (in red boxes) from the foreground distillation set.
CANDIDATE-BOX SELECTION MATTERS FOR CROSS- DOMAIN FEW-SHOT OBJECT DETECTION
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第5页 · ICLR27_6kDoAMVPn5_F
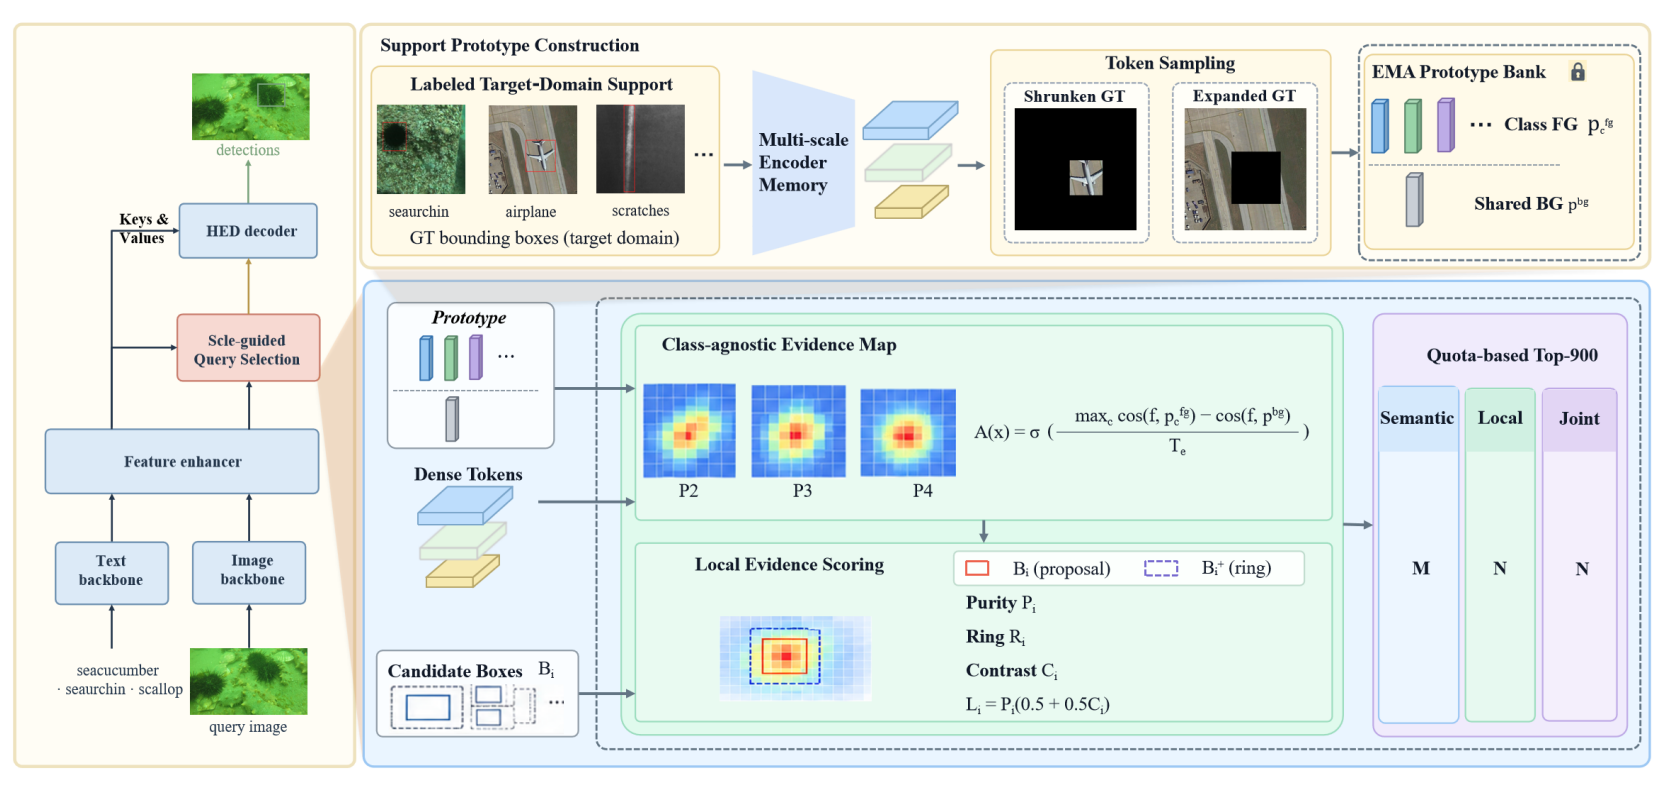
300 dpi PNG · 图注 · 源PDF
图2和5.1节包括完整检测管线、支持原型库、局部证据及候选配额选择。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 272],PDF点、左上角原点。
Figure 2: SCLE only modifies the pre-decoder selection stage of the language-guided detector. Left: detection pipeline, where SCLE-driven query selection replaces text-score ranking before the HED decoder. Upper right: class-wise foreground prototypes and one shared background prototype, updated by exponential moving average from labeled support samples. Lower right: the prototype bank produces a class-agnostic evidence map. Candidates are scored using interior purity P_i, ring evidence R_i, and contrast C_i. A quota divides the Top-900 budget into semantic, local-evidence and joint channels. Only the indices fed into the decoder are changed.
CANDIDATE-BOX SELECTION MATTERS FOR CROSS- DOMAIN FEW-SHOT OBJECT DETECTION
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_6kDoAMVPn5_M
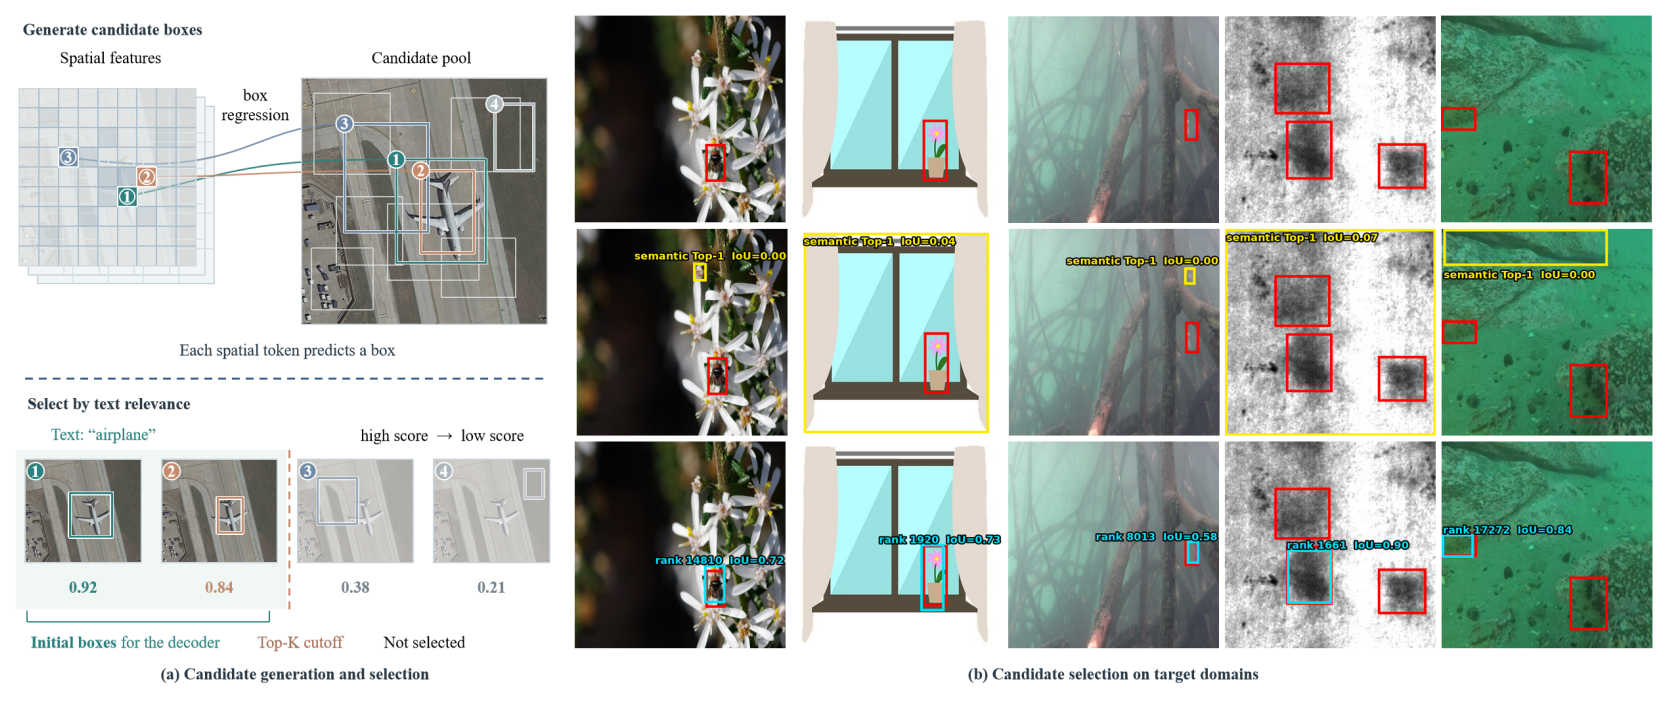
300 dpi PNG · 图注 · 源PDF
引言图1用红/黄/青框具体显示优质候选被Top-900语义排名排除的失败,指出候选选择瓶颈。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 252],PDF点、左上角原点。
Figure 1: (a) A brief illustration of the current Grounding-DINO-based works. (b) We find that
compared with the ground-truth bounding box (red), for target domains, the top-ranked candidate
boxes (yellow) are less likely to tightly bound the objects, where the better candidate boxes (cyan)
may be ranked outside the Top-900 quota. Unlike current work, we identify the selected candidate
boxes as another bottleneck for the CD-FSOD task, which we aim to address in this paper.
DCHA: Dynamic Compositional Adaptation with Hierarchical Drift Constraints for Incremental Vision-Language Object Detection
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页 · ICLR27_WrLCWdkY49_F
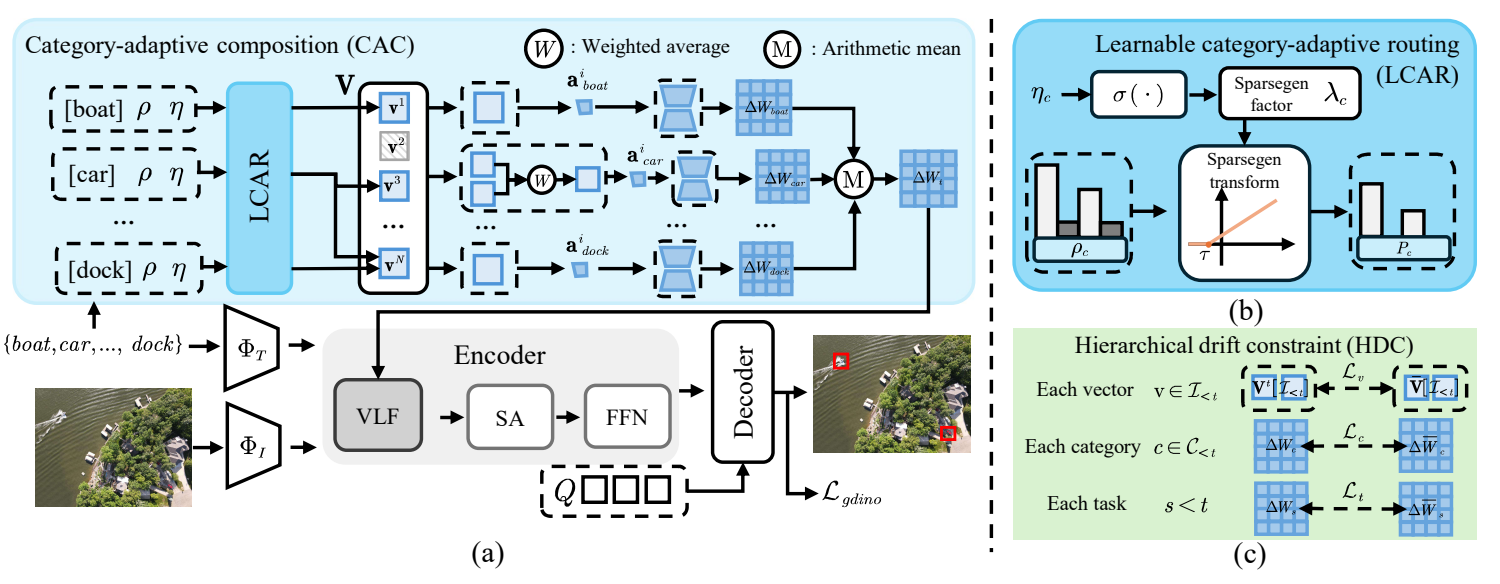
300 dpi PNG · 图注 · 源PDF
图2及3.2节为DCHA整体架构,包含视觉语言检测器、类别组合、稀疏路由和历史漂移约束。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[128, 79, 488, 219],PDF点、左上角原点。
Figure 2: Overview of the proposed DCHA framework. (a) DCHA constructs category-specific
LoRA by composing vectors from a shared bank and averages the resulting category updates to form
the task-level adaptation for the VLF layers. (b) LCAR transforms category-specific routing logits
into sparse composition weights using a learnable sparsity coefficient, enabling category-dependent
vector selection. (c) HDC preserves historical adaptation knowledge by constraining deviations at
the bank-vector, category-update, and task-update levels.
DCHA: Dynamic Compositional Adaptation with Hierarchical Drift Constraints for Incremental Vision-Language Object Detection
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_WrLCWdkY49_M
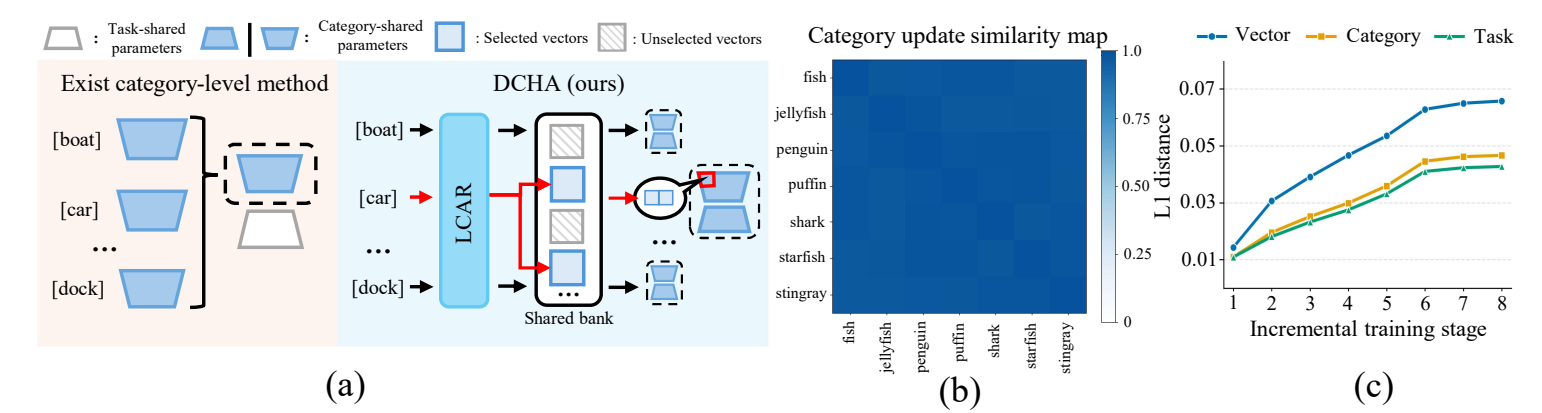
300 dpi PNG · 图注 · 源PDF
引言图1对比固定类别专家与动态组合,辅以更新同质性及逐层漂移,说明固定分配和遗忘问题。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[118, 79, 488, 178],PDF点、左上角原点。
Figure 1: Motivation of DCHA. (a) Existing category-level methods rigidly assign fixed experts
based on category, whereas DCHA dynamically selects and composes fine-grained parameter vec-
tors according to category demands. (b) Category-specific updates produced by existing category-
level methods exhibit uniformly high pairwise similarities within the same task. (c) Shared bank
parameter deviations progressively accumulate at the vector, category, and task levels during incre-
mental training, resulting in hierarchical drift.
DeCo: A Multimodal Detection Framework based on Density Consensus Learning
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页 · ICLR27_8P9XSKFW9N_F
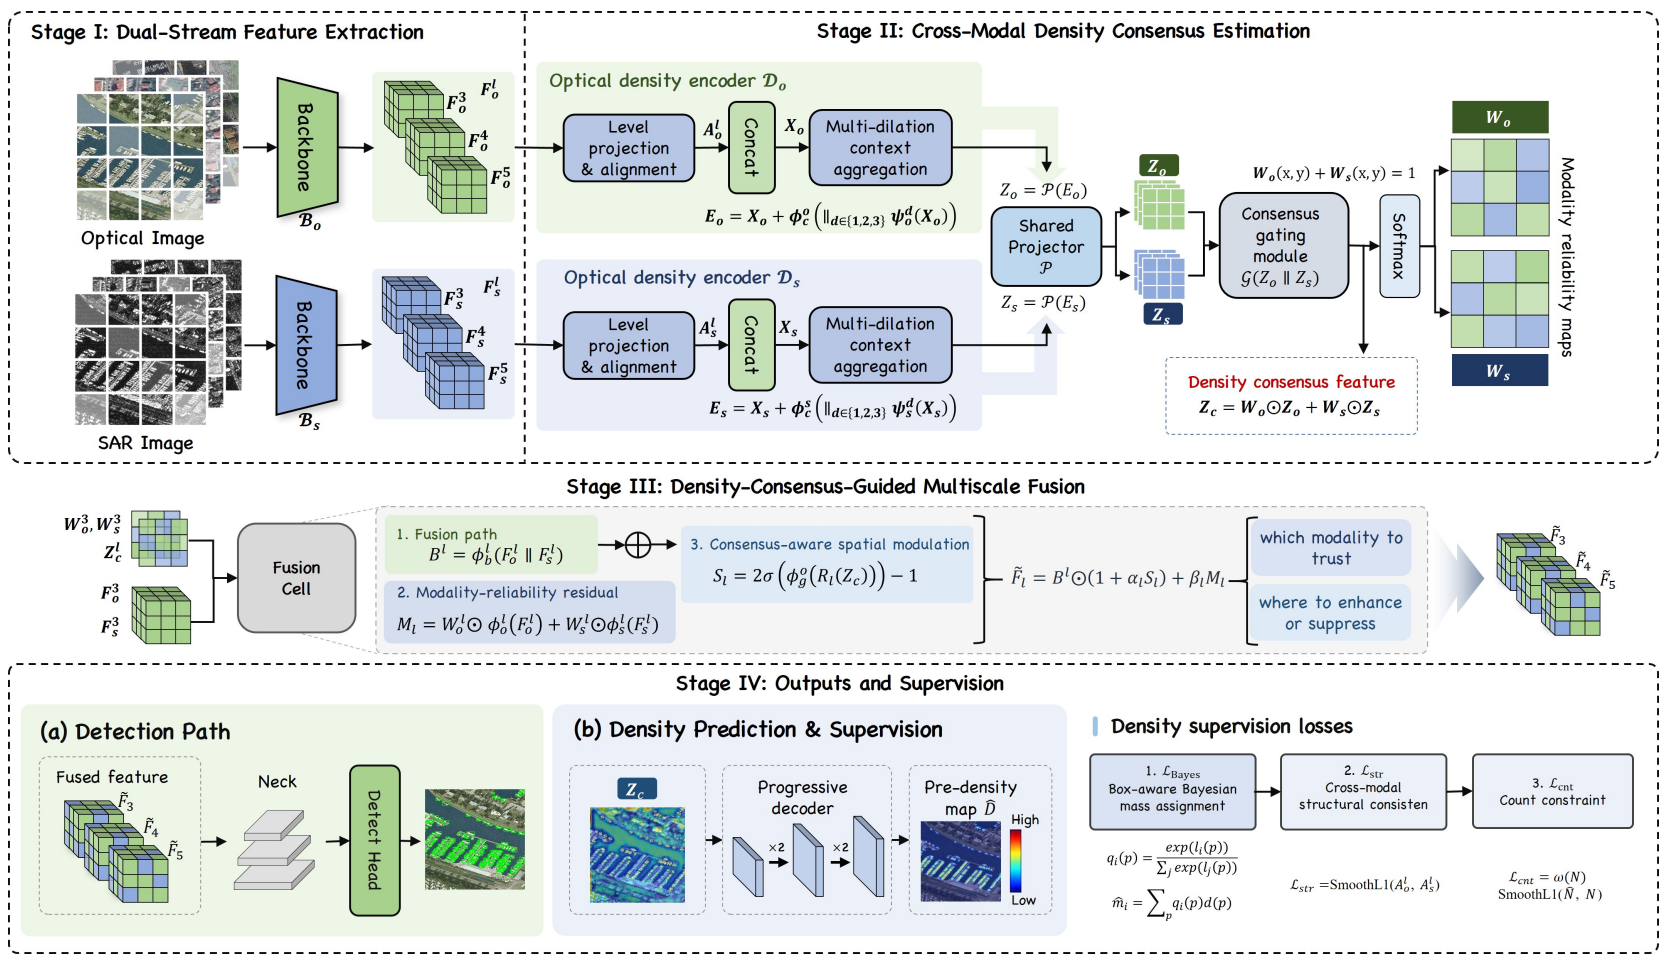
300 dpi PNG · 图注 · 源PDF
图2覆盖多尺度编码、密度共识估计、融合检测与密度监督完整路径,正文称为DeCo overview。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。作者声明AI编辑辅助分析及可视化代码;未披露所选M/F绘制工具。
裁剪坐标:[106, 79, 507, 311],PDF点、左上角原点。
Figure 2: Overview of DeCo. Independent backbones extract multimodal, multiscale features, which
are projected into a shared density space to estimate modality reliability and construct density con-
sensus. The resulting consensus guides multiscale feature fusion for detection and is simultaneously
decoded into a density map for density supervision.
DeCo: A Multimodal Detection Framework based on Density Consensus Learning
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_8P9XSKFW9N_M
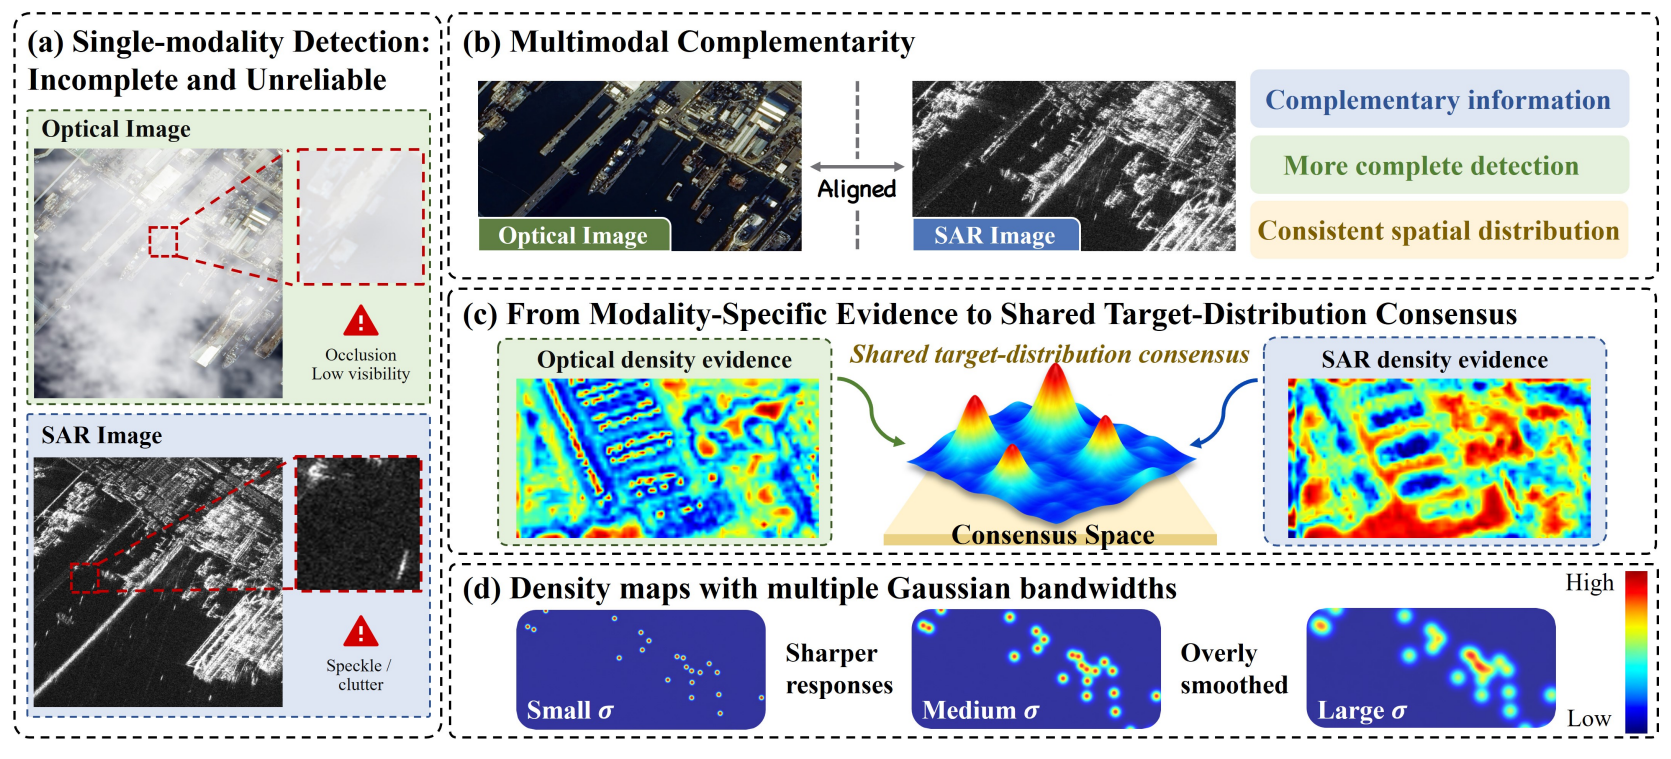
300 dpi PNG · 图注 · 源PDF
引言图1展示单模态不完整或不可靠证据、跨模态互补与固定高斯密度标签的局限,明确提出密度共识的动机。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。作者声明AI编辑辅助分析及可视化代码;未披露所选M/F绘制工具。
裁剪坐标:[106, 79, 507, 261],PDF点、左上角原点。
Figure 1: Motivation for density consensus learning. OPT and SAR observations provide heteroge-
neous and spatially varying evidence for the same underlying ship distribution. We establish their
agreement in a shared density space to preserve mutually supported target responses while suppress-
ing modality-specific interference. Different Gaussian bandwidths in (d) illustrate the dependence
of conventional pixel-wise density targets on predefined kernel shapes.
Different Instances, Different Supervision: Instance-Adaptive Point-Supervised Oriented Object Detection
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 3 · PDF第4页 · ICLR27_AUmtOiMvCa_F
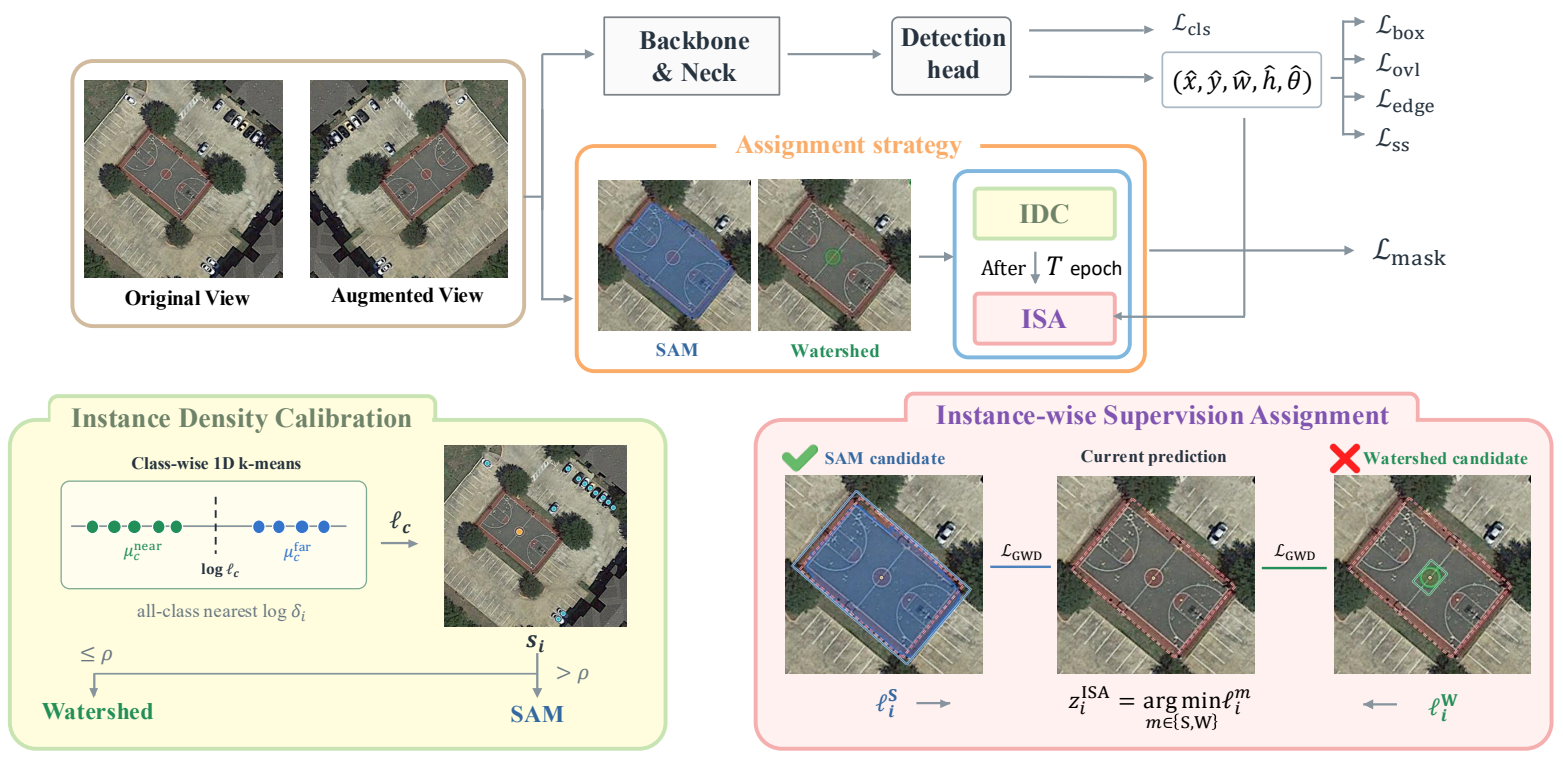
300 dpi PNG · 图注 · 源PDF
图3及3.1节为InstaPoint整体训练流程,包含检测主干、IDC、ISA、监督来源及全部损失连接。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[119, 77, 494, 263],PDF点、左上角原点。
Figure 3: Overview of InstaPoint. IDC initializes instance-wise assignments to SAM or watershed
using class-calibrated point spacing. ISA then makes a one-time selection of the source with the
lower GWD-based size loss relative to the detector’s current prediction.
Different Instances, Different Supervision: Instance-Adaptive Point-Supervised Oriented Object Detection
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_AUmtOiMvCa_M
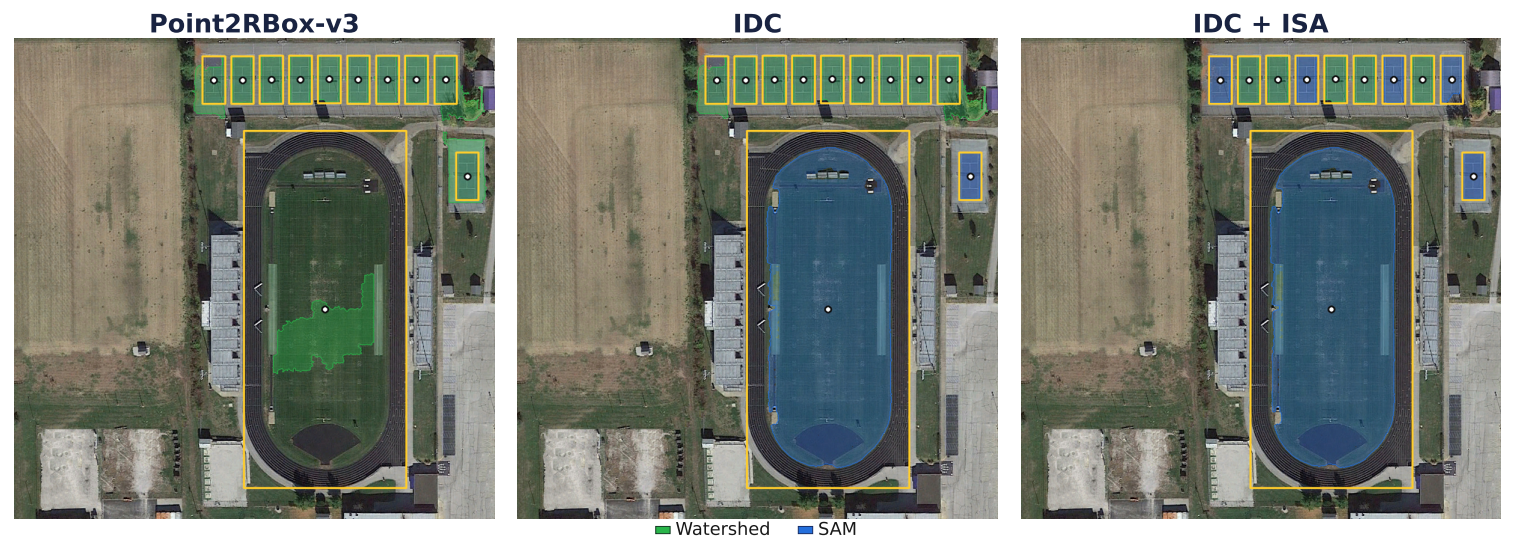
300 dpi PNG · 图注 · 源PDF
引言图1与对应段落以同图中稀疏和密集物体说明共享patch监督无法适应逐实例空间差异。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[123, 79, 486, 210],PDF点、左上角原点。
Figure 1: Qualitative comparison of supervision assignment. Point2RBox-v3 (Zhang et al., 2026)
uses a shared patch-wise supervision source, while our Instance Density Calibration (IDC) and
Instance-wise Supervision Assignment (ISA) perform instance-wise source assignment between
SAM (blue) and watershed (green) supervision. Yellow boxes denote the RBoxes and white dots
denote point annotations.
Imbalance-Adaptive Cross Consistency Learning for Semi-Supervised Oriented Object Detection
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 3 · PDF第4页 · ICLR27_0jbdTGiGaz_F
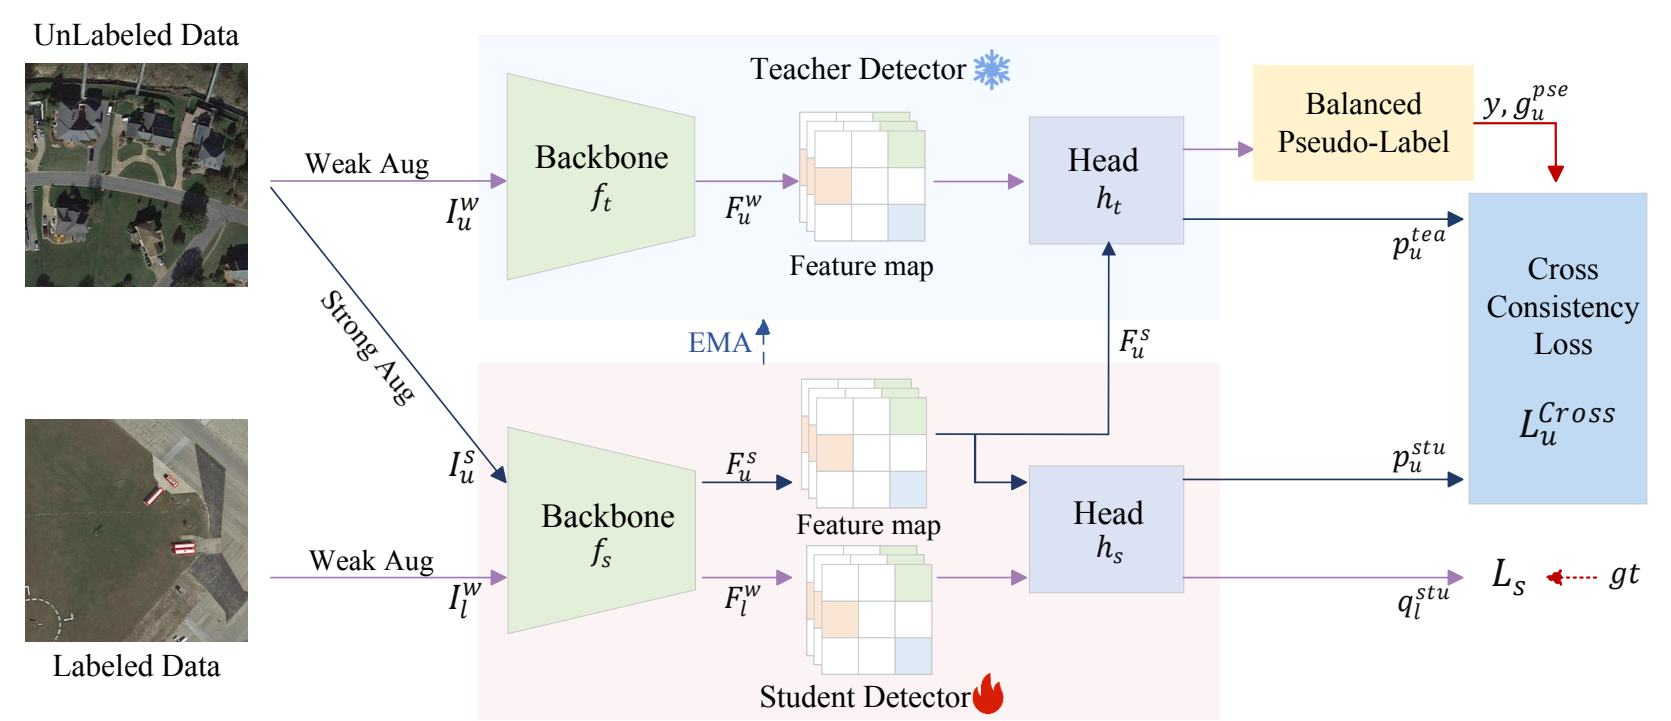
300 dpi PNG · 图注 · 源PDF
图3及3.1节为IACCL完整师生训练流程,显示两路增强、伪标签平衡、共享特征和交叉一致性损失。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 252],PDF点、左上角原点。
Figure 3: An illustration of our proposed IACCL
Imbalance-Adaptive Cross Consistency Learning for Semi-Supervised Oriented Object Detection
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_0jbdTGiGaz_M
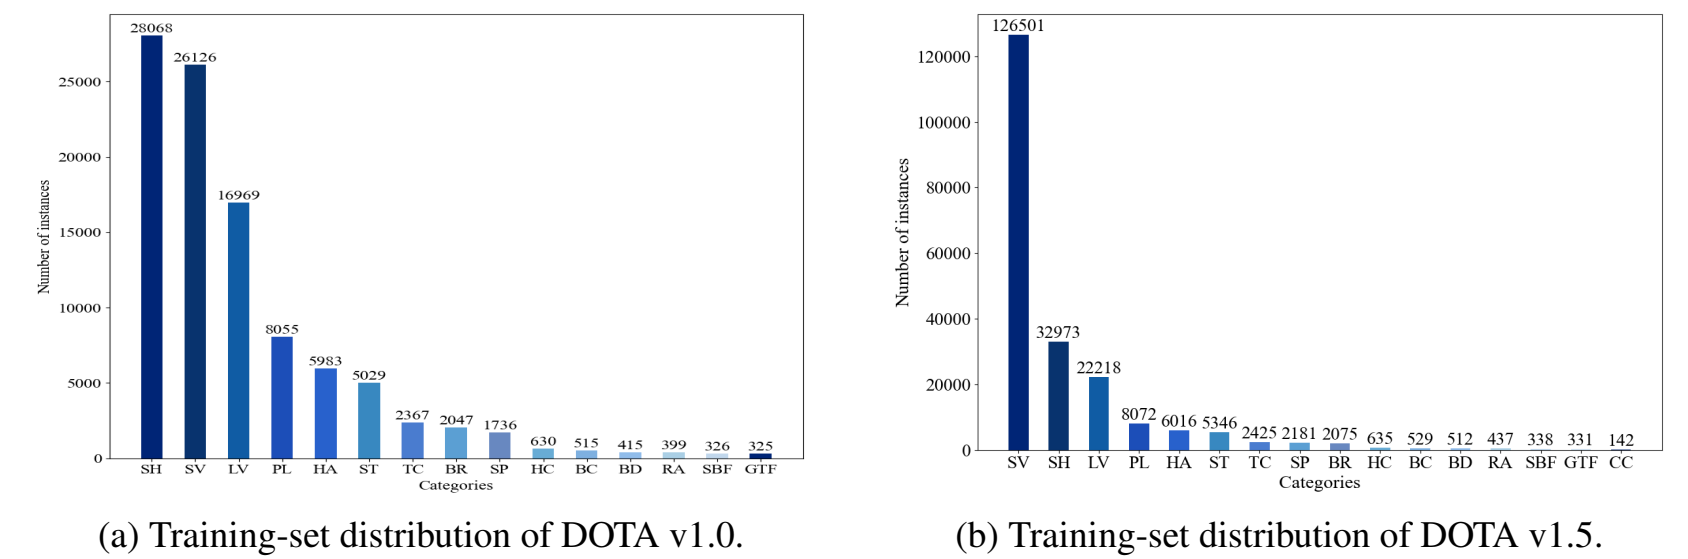
300 dpi PNG · 图注 · 源PDF
引言图1统计DOTA训练集长尾分布,用于解释头类伪标签偏置,属于问题分布示意而非检测性能柱状图。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[102, 79, 507, 213],PDF点、左上角原点。
Figure 1: Long-tailed category distributions in the DOTA v1.0 and DOTA v1.5 training sets.
PULSE: PERSISTENT UTILIZATION OF LIMITED SUPPORT EVIDENCE FOR CROSS-DOMAIN FEW-SHOT OBJECT DETECTION
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页 · ICLR27_ad0Os8QbxN_F
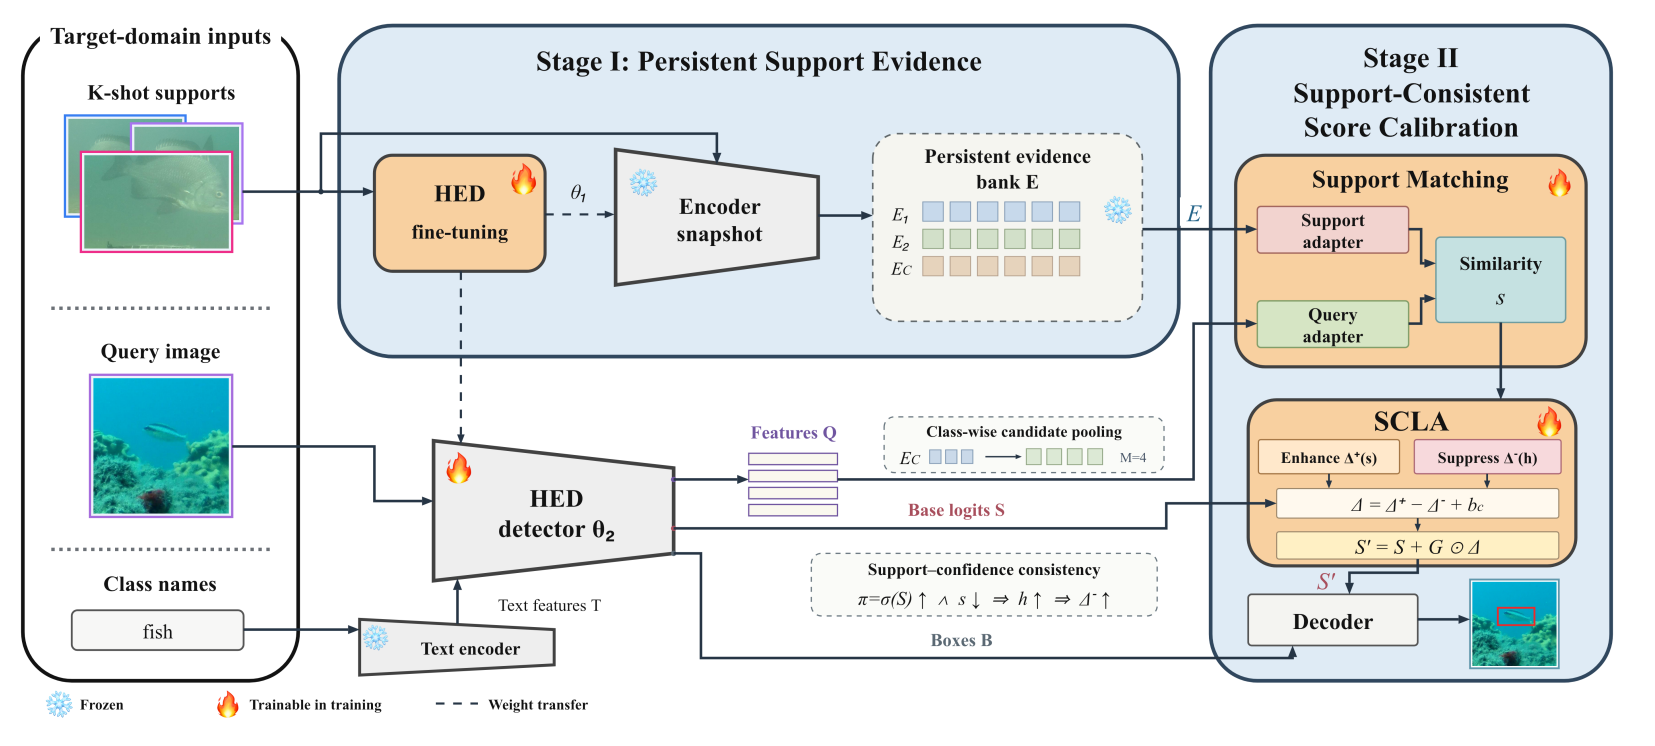
300 dpi PNG · 图注 · 源PDF
图2及3节展示PULSE两阶段训练、固定证据库、查询检测及分数校准完整路径。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:generative_AI_figure_preparation_unspecified_tool。作者声明生成式AI用于figure preparation;工具名及逐图对应未披露。
裁剪坐标:[110, 169, 507, 348],PDF点、左上角原点。
Figure 2: Persistent support evidence and SSCA-centered calibration in PULSE. In Stage I, HED
is fine-tuned on the target support set, and the resulting encoder snapshot is frozen to construct the
evidence bank E. In Stage II, the query detector is initialized with the Stage I weights and produces
query features Q, base class logits S, and predicted boxes B. SSCA matches Q with the cached
evidence E to obtain support agreement s and refines the base logits as S′ = S + G ⊙ ∆, while the
box coordinates bypass score calibration and remain unchanged. The evidence bank remains fixed
throughout Stage II training and inference. Flames indicate trainable parameters during training,
whereas snowflakes indicate frozen modules or fixed evidence. All model parameters are fixed during
inference. Test images from the DeepFish dataset (Fu et al., 2024) are adopted for illustration and do
not correspond to the sampled adaptation episode; the displayed output box is schematic rather than
an actual model prediction.
PULSE: PERSISTENT UTILIZATION OF LIMITED SUPPORT EVIDENCE FOR CROSS-DOMAIN FEW-SHOT OBJECT DETECTION
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_ad0Os8QbxN_M
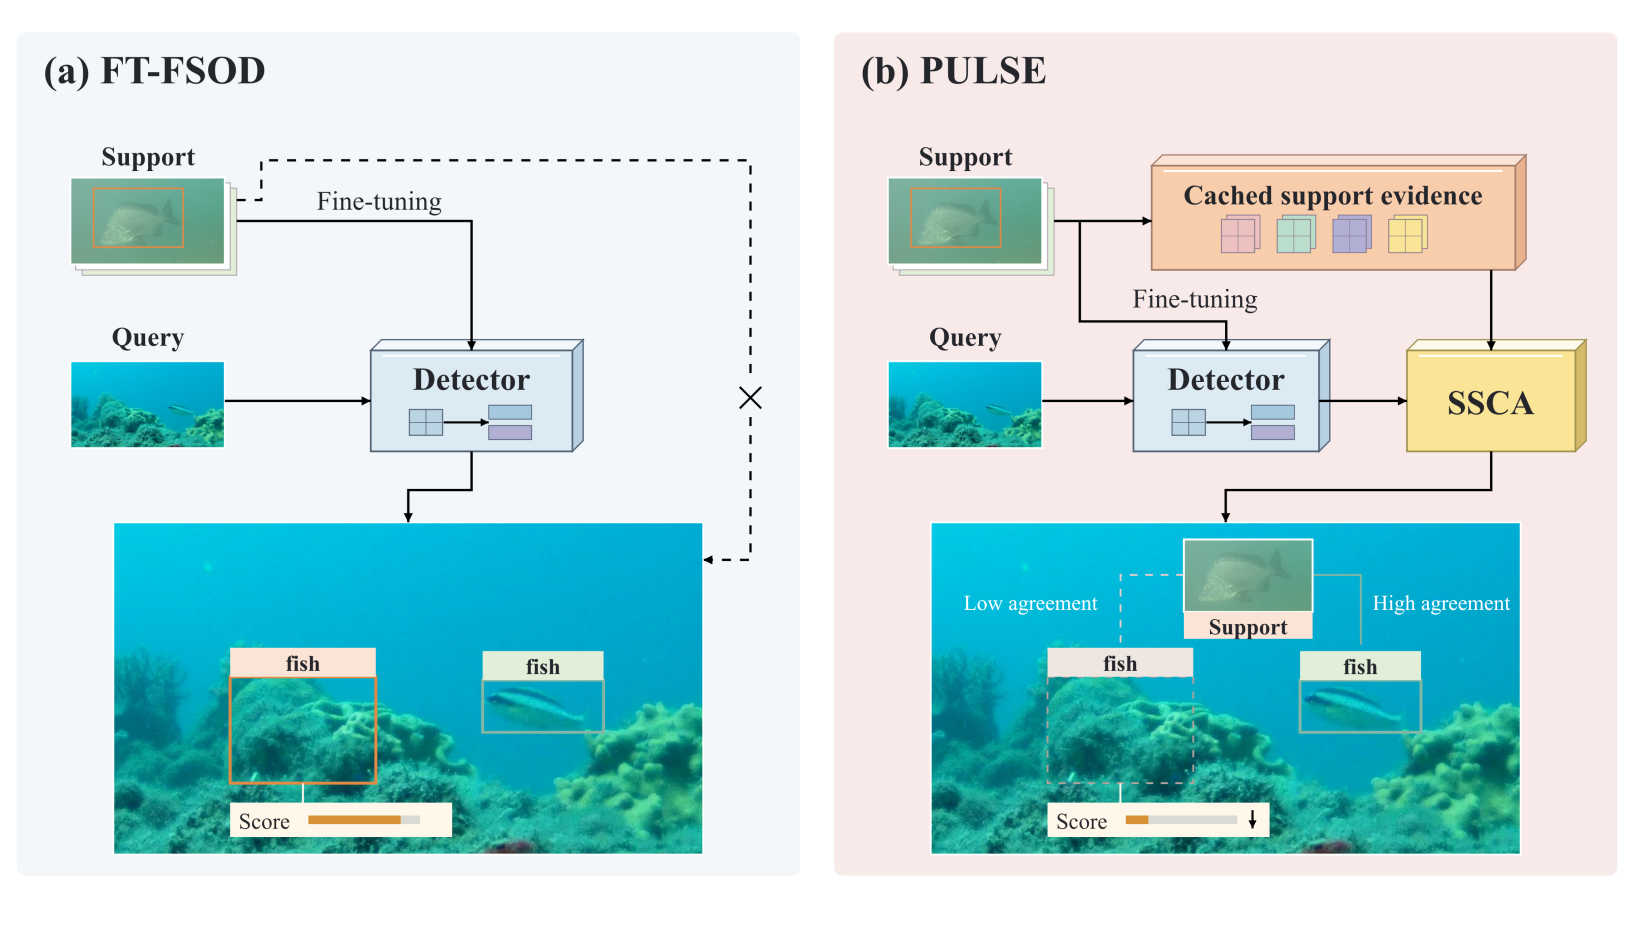
300 dpi PNG · 图注 · 源PDF
引言图1用示意检测框和支持集保留路径,对比微调后丢弃支持证据与持续利用支持证据的概念。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:generative_AI_figure_preparation_unspecified_tool。作者声明生成式AI用于figure preparation;工具名及逐图对应未披露。
裁剪坐标:[110, 79, 501, 301],PDF点、左上角原点。
Figure 1: Target-support use in FT-FSOD (Yu et al., 2026) and PULSE. (a) FT-FSOD uses support
annotations for target-domain fine-tuning and subsequently scores query predictions without explicitly
consulting the support examples. (b) PULSE retains cached support evidence and uses SSCA to
refine classification scores according to support–query agreement. Box tags denote predicted classes,
and bar lengths illustrate schematic confidence. The dashed candidate illustrates score suppression at
the same location. Test images from DeepFish (Fu et al., 2024) are used for illustration; the support
examples, bounding boxes, and score changes are schematic.
Rethinking Over-Segmentation in Few-Shot Object Detection with Vision Foundation Models: A Training-Free Prototype Refinement and Occlusion-Aware Discrimination Approach
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第3页 · ICLR27_V5RmhtXTMG_F
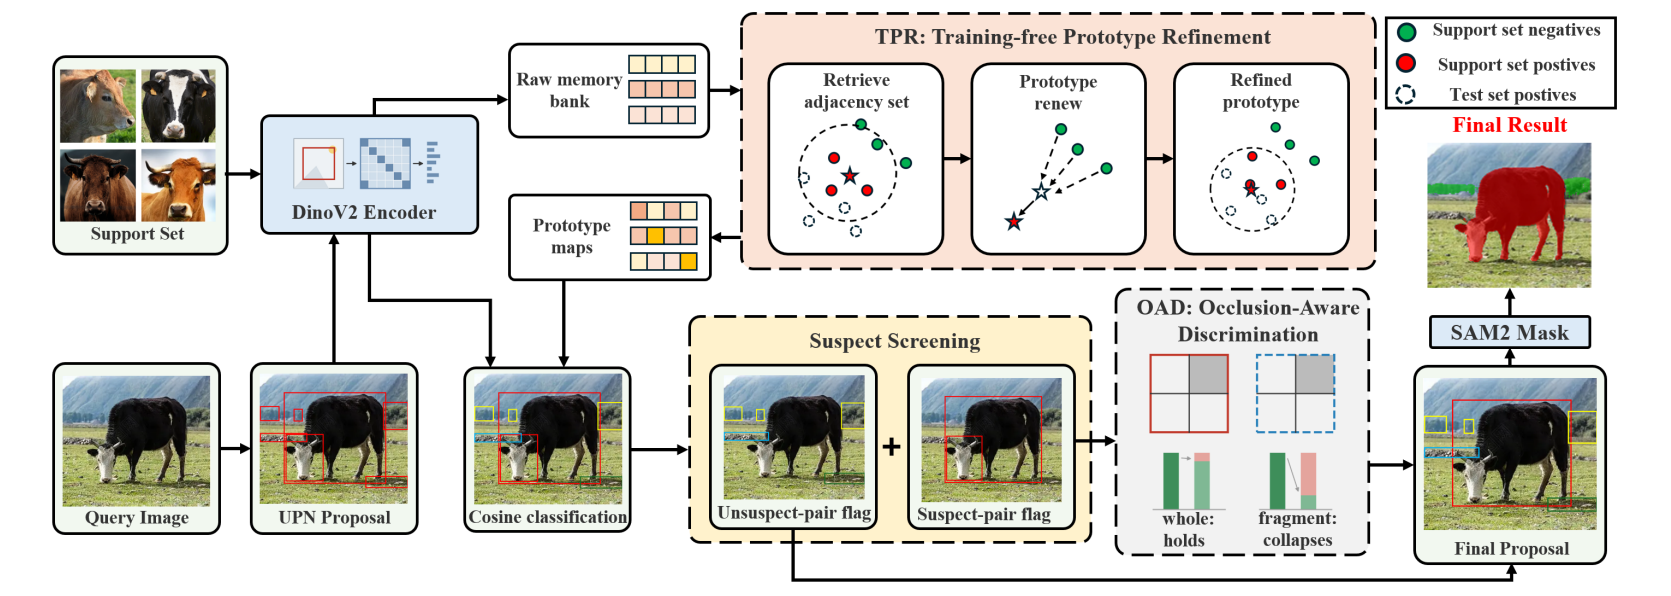
300 dpi PNG · 图注 · 源PDF
图1由3.1节明确称为POISE overview,呈现支持集编码、原型修正、候选评分和遮挡判别完整流程。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 222],PDF点、左上角原点。
Figure 1: POISE overview. The support set is encoded by a frozen DINOv2 encoder into a raw memory
bank and per-class prototype maps. TPR retrieves an adjacency set of hard negatives, renews each prototype
by a bounded one-step update, and writes the refined prototype back. UPN proposals are scored by cosine
classification against the refined prototypes; suspect screening flags nested same-class pairs and passes only
those to OAD, which separates whole objects from fragments.
Rethinking Over-Segmentation in Few-Shot Object Detection with Vision Foundation Models: A Training-Free Prototype Refinement and Occlusion-Aware Discrimination Approach
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页 · ICLR27_V5RmhtXTMG_M
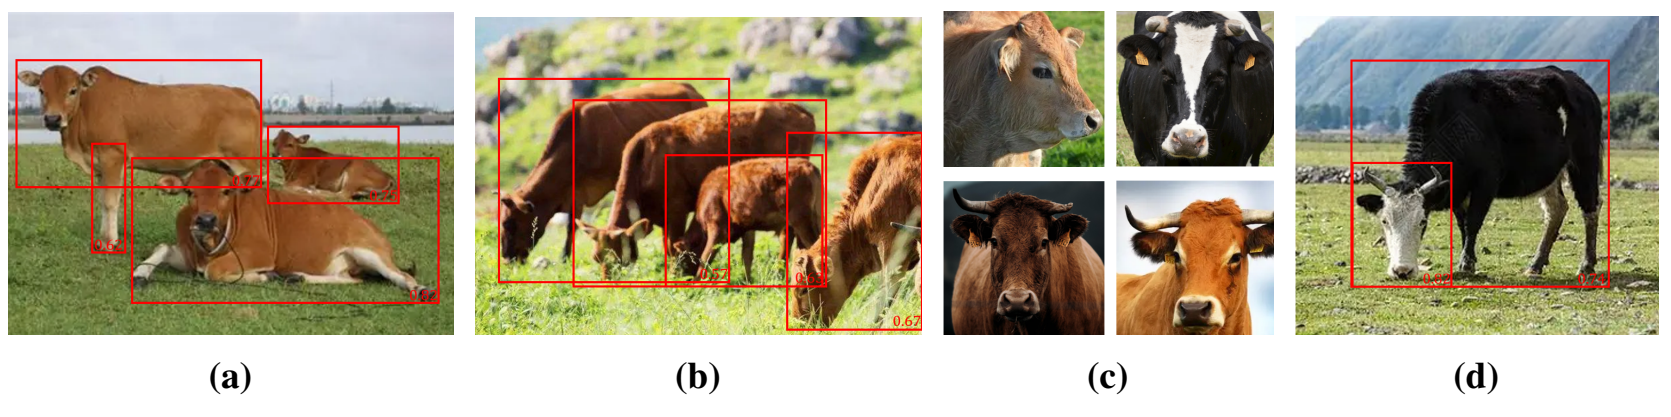
300 dpi PNG · 图注 · 源PDF
图2与3.2节具体诊断重叠物体、嵌套框及片段置信度更高导致过分割的失败机制,用于引出TPR和OAD设计。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 179],PDF点、左上角原点。
Figure 2: Why over-segmentation defeats confidence-based suppression in the few-shot regime. (a) Real
scenes contain multiple overlapping same-class instances, so class-agnostic proposal generators fragment ob-
jects into nested, mutually overlapping proposals that simple merging cannot consolidate. (b) The smaller
member of a nested pair is occasionally a genuine, distinct object, so the covered box cannot simply be dis-
carded. (c) Few-shot support sets are frequently biased: a handful of examples may emphasise part-views and
fail to represent the class as a whole. (d) Under such bias, the prototype shifts towards part-views, and an
over-segmentation fragment can attain higher classification confidence than the correct whole-object proposal.
Towards Trustworthy Object Detection: Adaptive Boundary Optimization with Joint Classification and Localization Risk Control
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_1I3yfptfr1_F
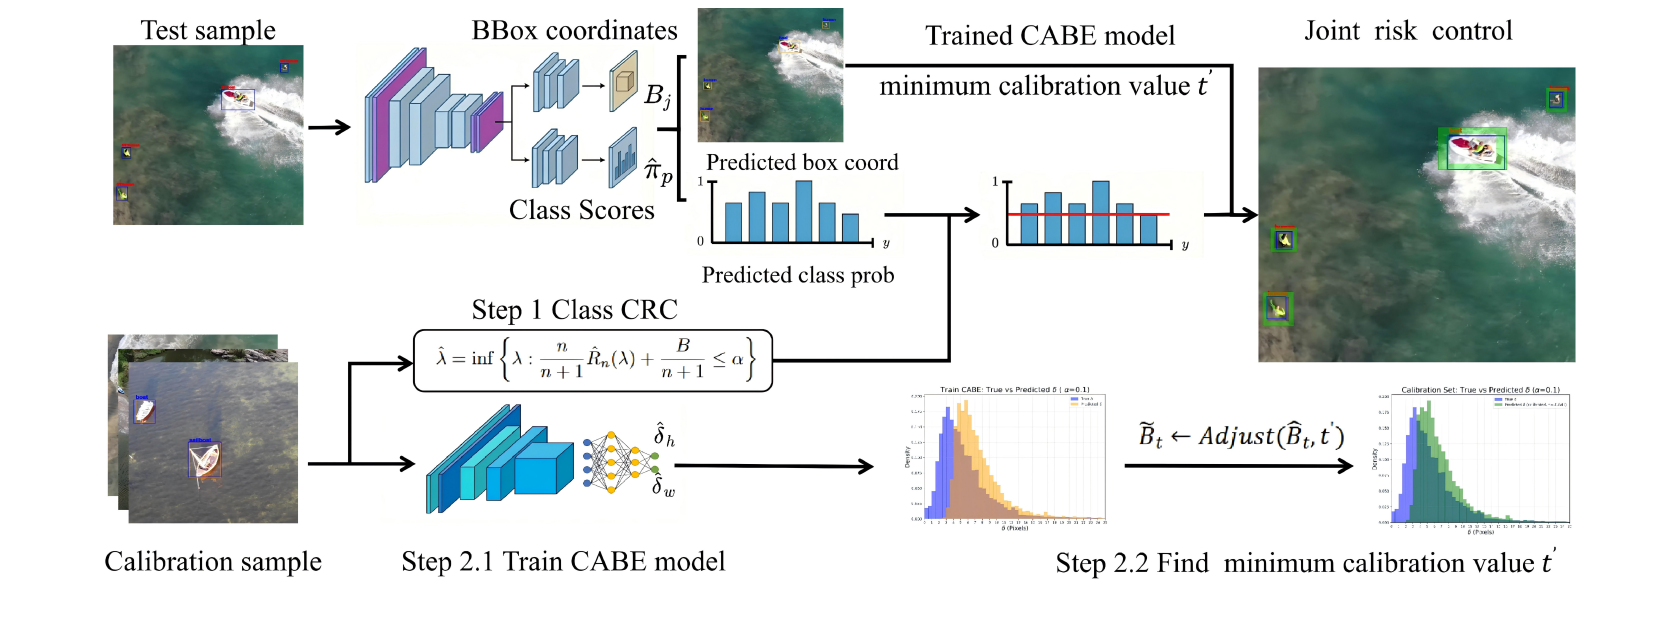
300 dpi PNG · 图注 · 源PDF
图1为CABE Framework Pipeline,包含校准样本、模型训练、阈值校准和测试时联合风险控制。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 564, 507, 713],PDF点、左上角原点。
Figure 1: Schematic Overview of the CABE Framework Pipeline
Towards Trustworthy Object Detection: Adaptive Boundary Optimization with Joint Classification and Localization Risk Control
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第5页 · ICLR27_1I3yfptfr1_M
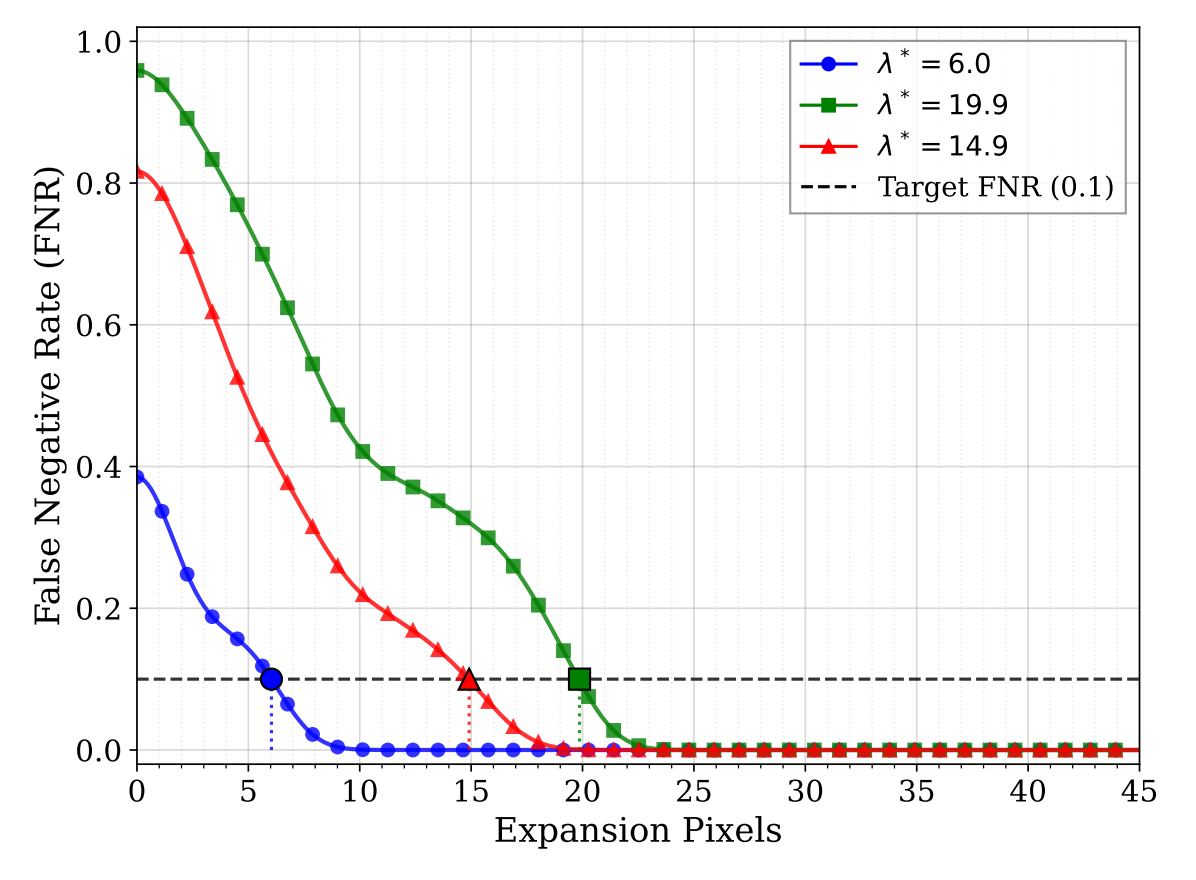
300 dpi PNG · 图注 · 源PDF
方法3.2节图2比较不同图像的边界扩张量与漏检率关系,诊断单一全局阈值不能保证条件风险控制;是问题机制图而非模型性能排名。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[163, 79, 450, 290],PDF点、左上角原点。
Figure 2: The relationship between Expansion pixels and the empirical FNR across different images.
UniOSE: Semantics-Enriched Object Queries for Open-Ended Detection and Segmentation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页 · ICLR27_vTYhIzoLzY_F
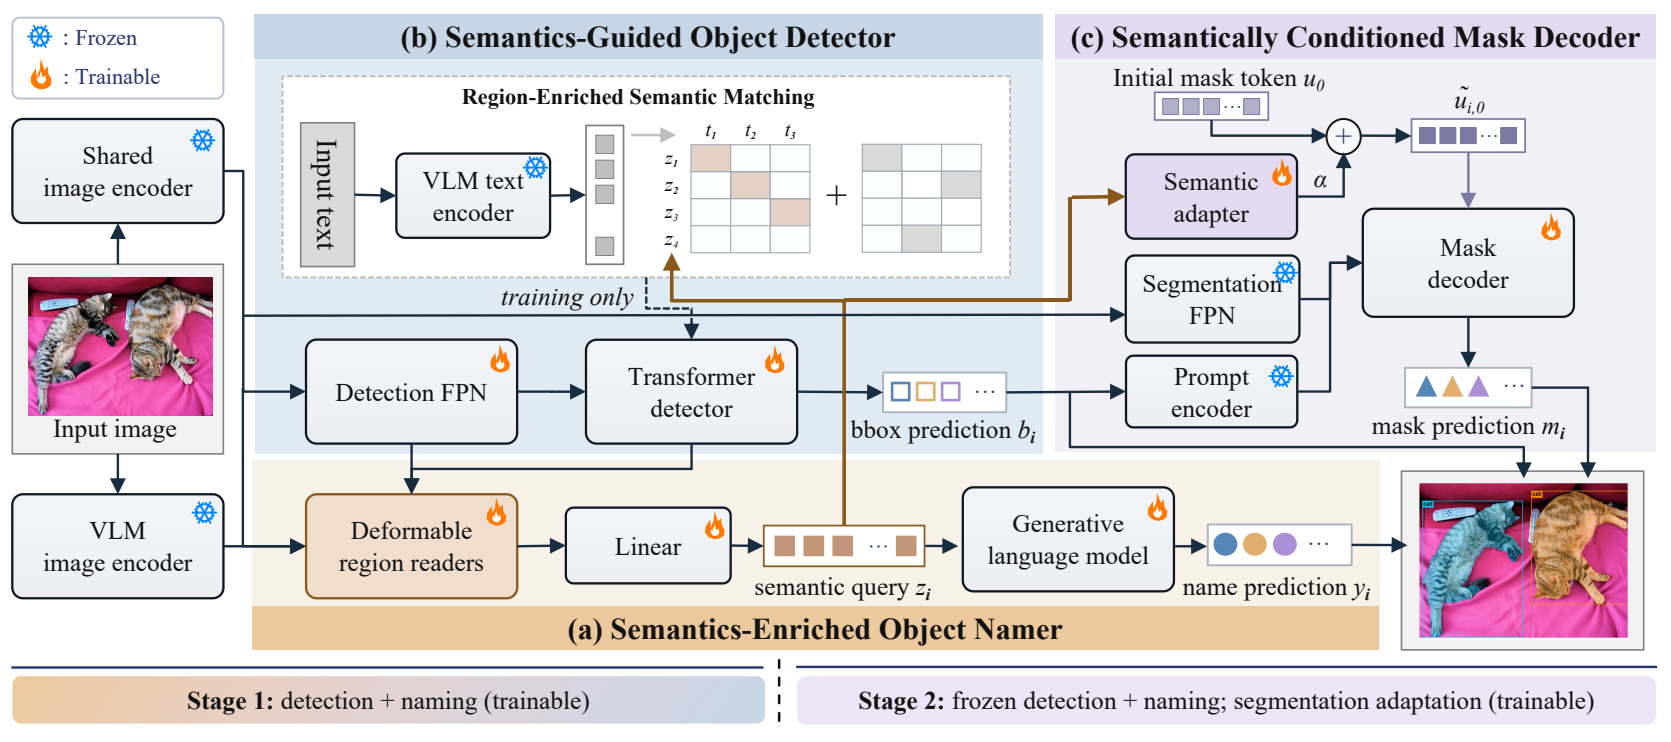
300 dpi PNG · 图注 · 源PDF
图2与3节明确展示UniOSE整体模型,完整包含对象命名、语义引导检测与条件掩码预测。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 257],PDF点、左上角原点。
Figure 2: Overview of the UniOSE model. (a) Semantics-Enriched Object Namer combines
Deformable region reader layer
detector features with region-level VLM semantics to construct queries z and generates category
i
names with a generative lang F uage model. (b) Semantics-Guided Object Dx2etector predicts candi-
q Deformable
date boxes and combines query–targ+et caLteaygeroNroyrmmatchFiFnNg cos+ts wiLtahyesrNpoarmtial costs for training-time
Cross-Attention
supervision assignment. (c) Semantically Conditioned Mask Decoder injects z into the first mask
i
token and combines it with image features and predicted boxes to generate masks.
UniOSE: Semantics-Enriched Object Queries for Open-Ended Detection and Segmentation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_vTYhIzoLzY_M
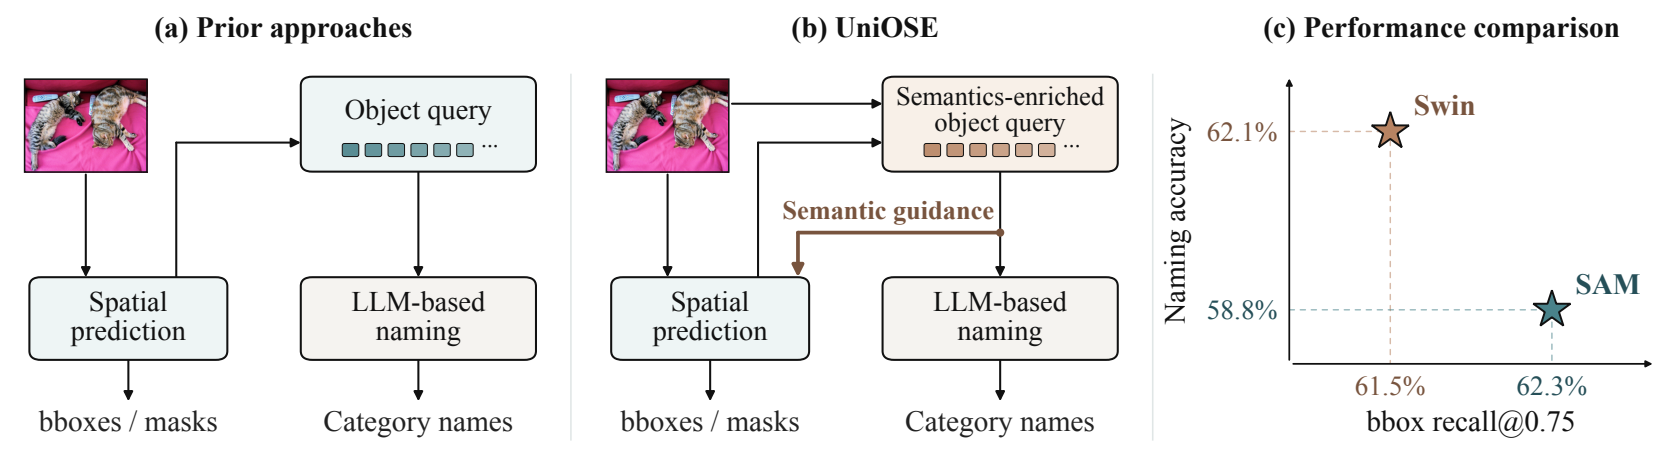
300 dpi PNG · 图注 · 源PDF
引言图1以旧范式与语义增强范式概念对比,并用更强定位却更弱命名的例子说明二者不等价;并非仅性能报告。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 191],PDF点、左上角原点。
Figure 1: Object semantics for open-ended naming and spatial prediction. (a) Spatial prediction produces object queries for LLM-based naming. (b) UniOSE enriches these queries with image-derived regional semantics and uses them for training-time detection matching and mask conditioning. Semantic guidance originates from the enriched query before LLM-based naming. (c) Comparison of box recall@0.75 and naming accuracy. Swin and SAM denote Open-Det Swin-T and its fully fine-tuned SAM2-T backbone variant, respectively. The protocol, metric definitions, and source results are provided in Appendix A.1.
Architectural Missing-Modality Robustness in Semantic Segmentation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第3页 · ICLR27_ymk7OpPLY8_F
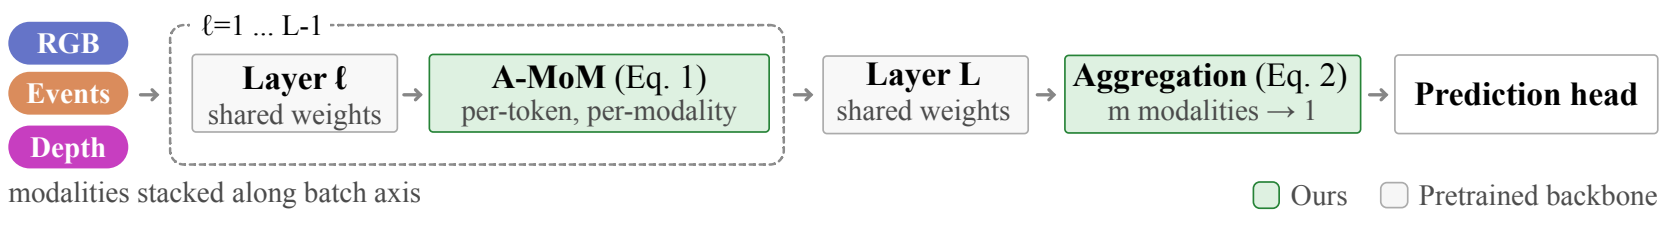
300 dpi PNG · 图注 · 源PDF
图2与3.1节呈现并行模态输入、共享Transformer、跨层A-MoM、聚合及预测头的完整计算路径。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 133],PDF点、左上角原点。
Figure 2: A-MoM integration with a Transformer. A single Transformer with shared weights
processes all modalities stacked along the batch dimension; A-MoM fuses them between layers,
independently at every token. A learned aggregation merges m tokens into 1 token at the stage output.
Architectural Missing-Modality Robustness in Semantic Segmentation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_ymk7OpPLY8_M
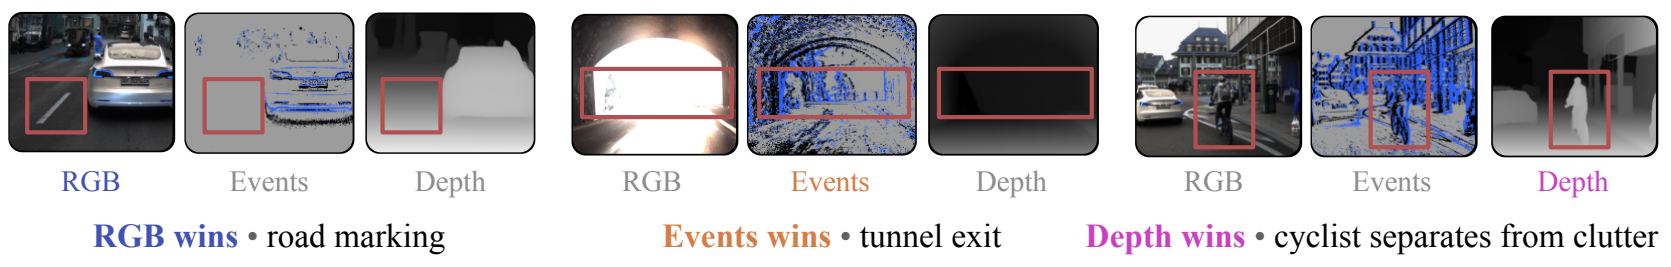
300 dpi PNG · 图注 · 源PDF
引言图1以道路标记、隧道出口与骑车人三个案例说明不同传感器的优势具有局部性,由此引出token级融合。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 143],PDF点、左上角原点。
Figure 1: Token-level motivation. Sensor advantages are local, so the fusion decision belongs at the
token level, illustrated by 1 case each for RGB, events, and depth.
Calibration-Guided State Selection and Class-Conditioned Fusion for Frozen Diffusion Segmentation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 3 · PDF第5页 · ICLR27_NYrrKvi2Dy_F
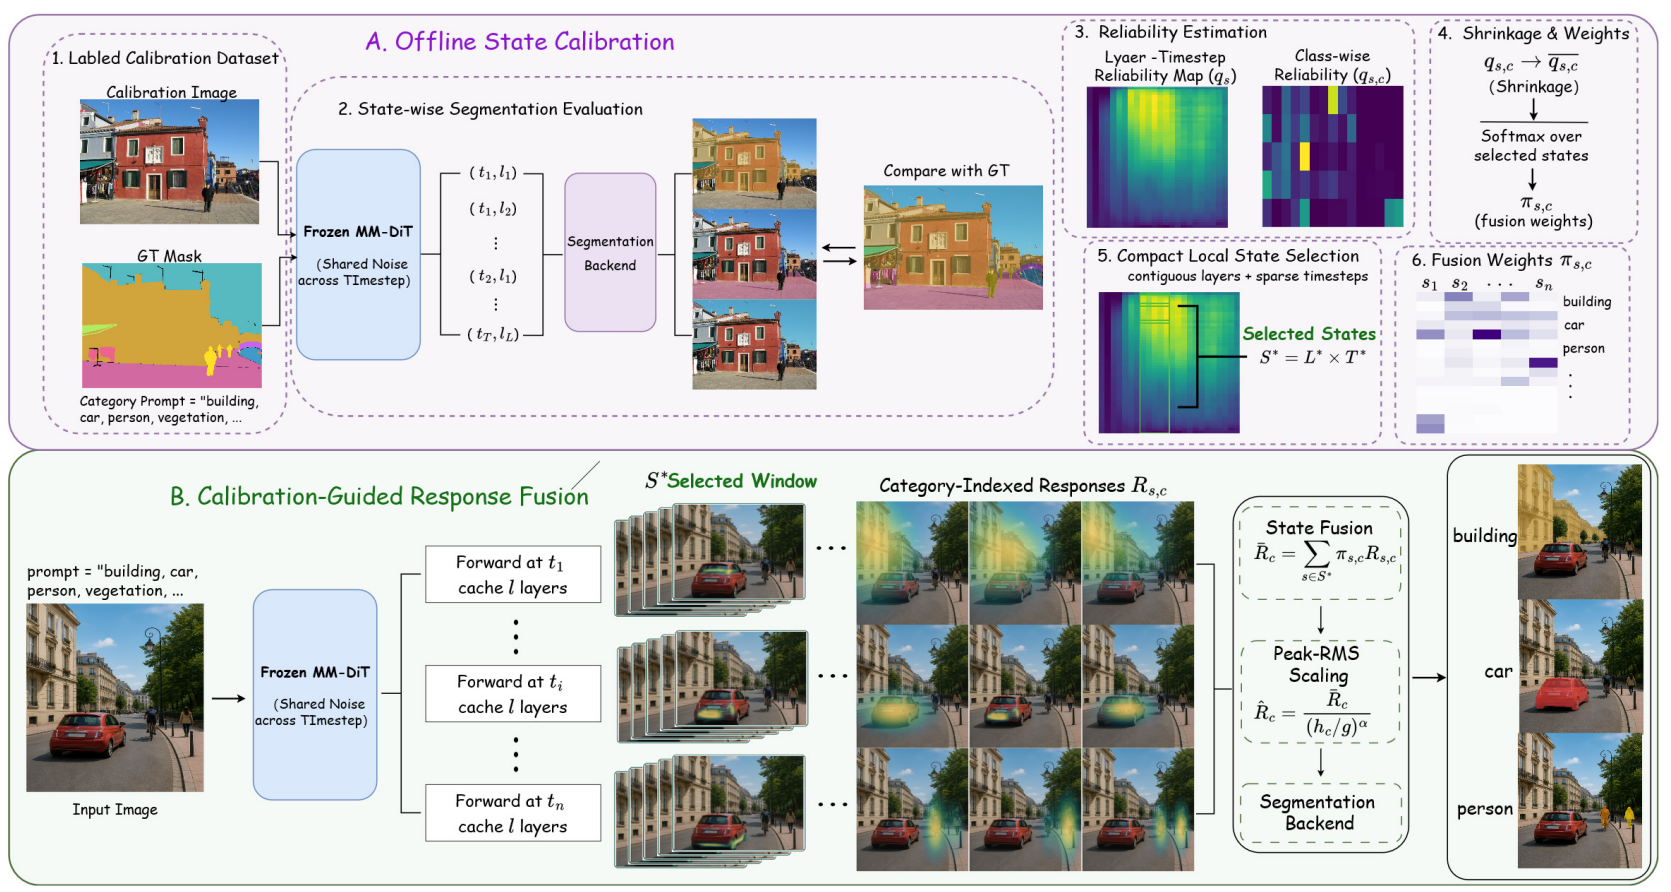
300 dpi PNG · 图注 · 源PDF
图3展示CSR完整离线校准、状态池选择和在线类别条件融合解码路径。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 293],PDF点、左上角原点。
Figure 3: Overview of Classwise State Routing. Top: A labeled calibration set estimates down-
stream class-by-state reliability, selects a compact shared state pool, and fixes class-conditioned
routing weights. Bottom: For a new image, the frozen backbone extracts selected-state responses,
which are fused and rescaled before unchanged backend-native decoding.
Calibration-Guided State Selection and Class-Conditioned Fusion for Frozen Diffusion Segmentation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第3页 · ICLR27_NYrrKvi2Dy_M
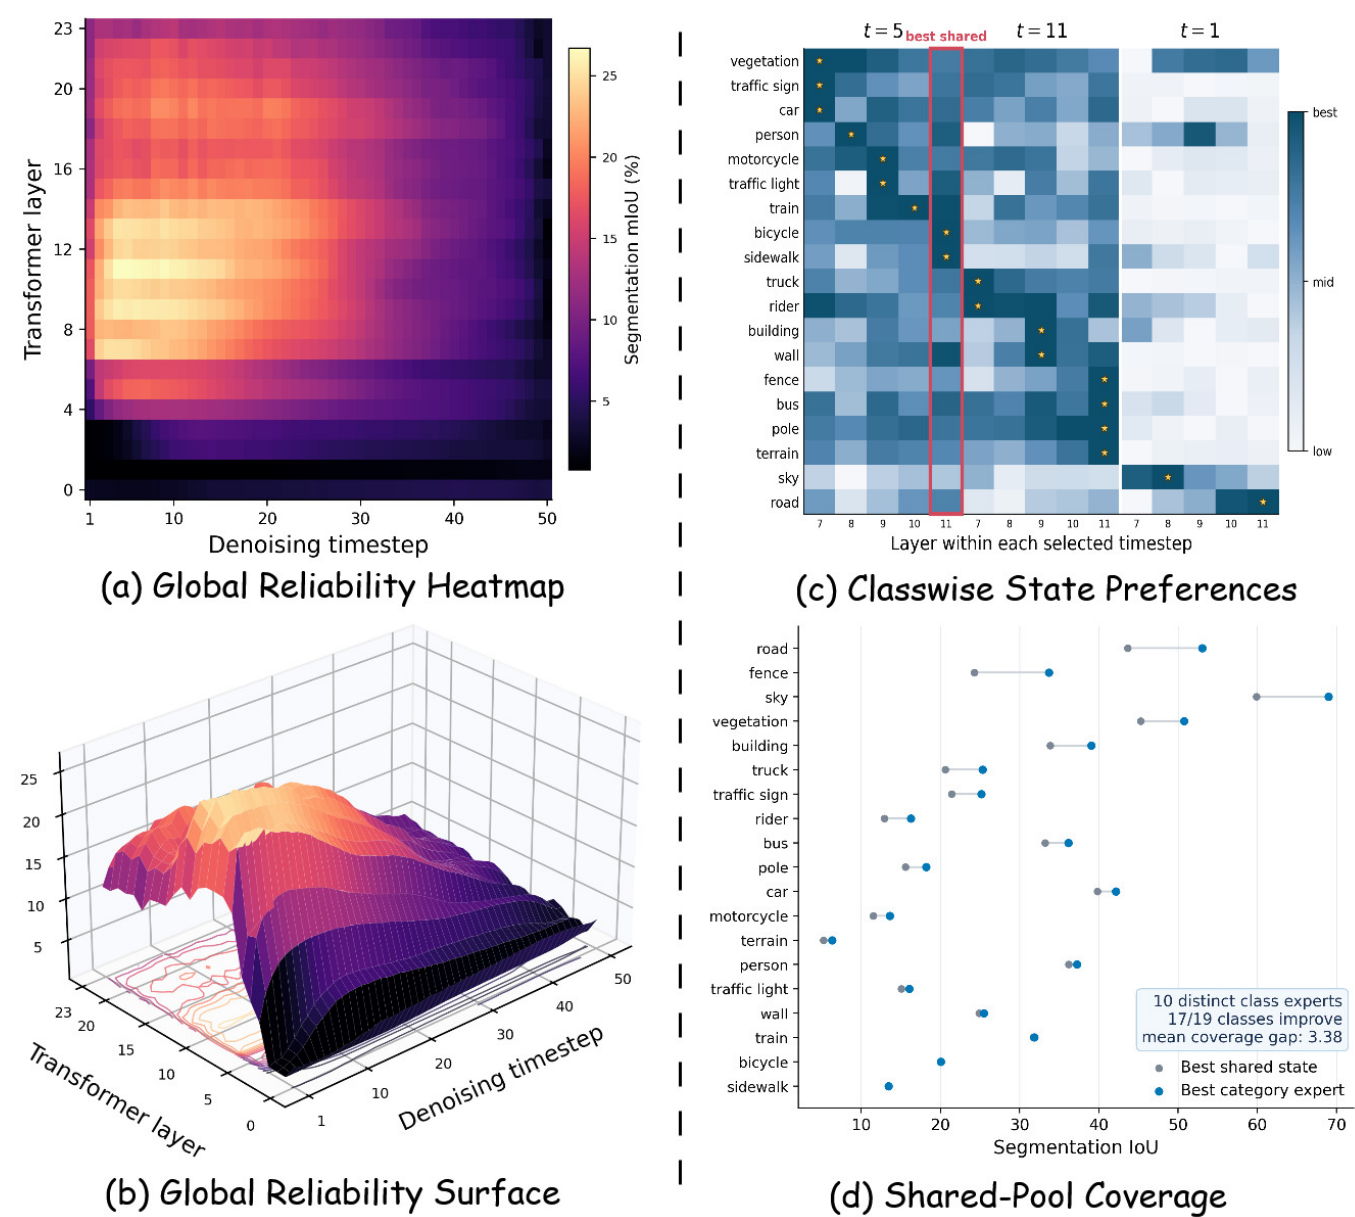
300 dpi PNG · 图注 · 源PDF
引言图2以层-时间步响应及类别最优状态不一致,诊断单一共享状态不是通用语义专家的局限;不是模型排行榜。图1普通结果不选。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[139, 80, 464, 372],PDF点、左上角原点。
Figure 2: (a) Segmentation mIoU over 1,200 layer–timestep states; (b) Three-dimensional view
of the same performance landscape. (c) Classwise reliability over the selected states; stars mark
classwise maxima and red marks the strongest shared state. (d) Class IoU of the strongest shared
state and each class’s preferred state.
DevoSeg: Budget-Aware Self-Evolving Semantic Segmentation under Visual Degradation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页 · ICLR27_8aErJ21sV6_F
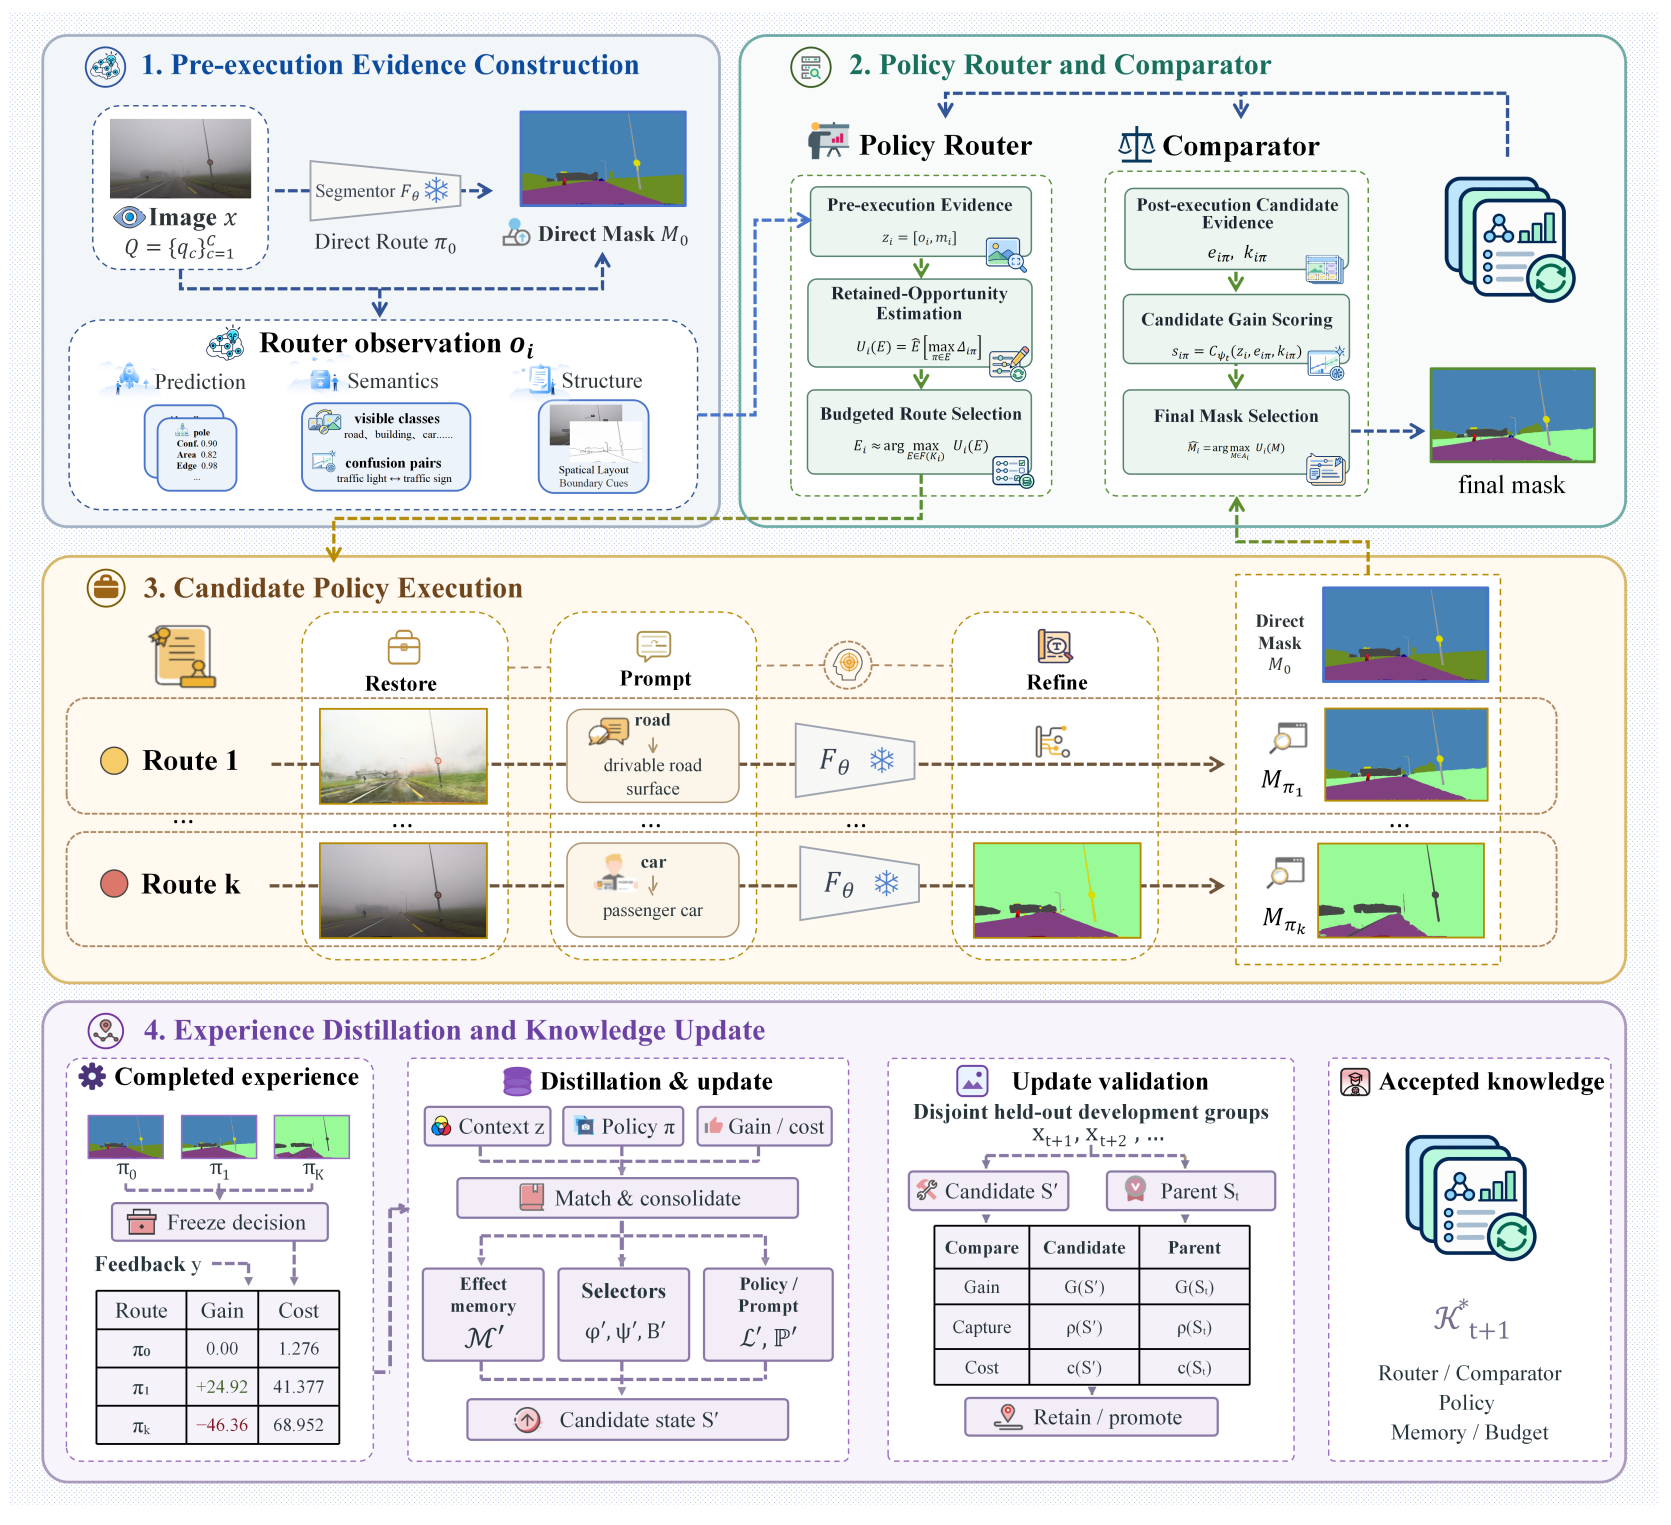
300 dpi PNG · 图注 · 源PDF
图2展示DevoSeg完整的执行前证据构造、路由和比较、候选执行及知识更新四阶段过程。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 445],PDF点、左上角原点。
Figure 2: DevoSeg’s decision process. The Router chooses policies before execution; the Compara-
tor selects among their masks and the independent Direct mask afterward. Completed outcomes
provide evidence for subsequent knowledge updates.
DevoSeg: Budget-Aware Self-Evolving Semantic Segmentation under Visual Degradation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_8aErJ21sV6_M
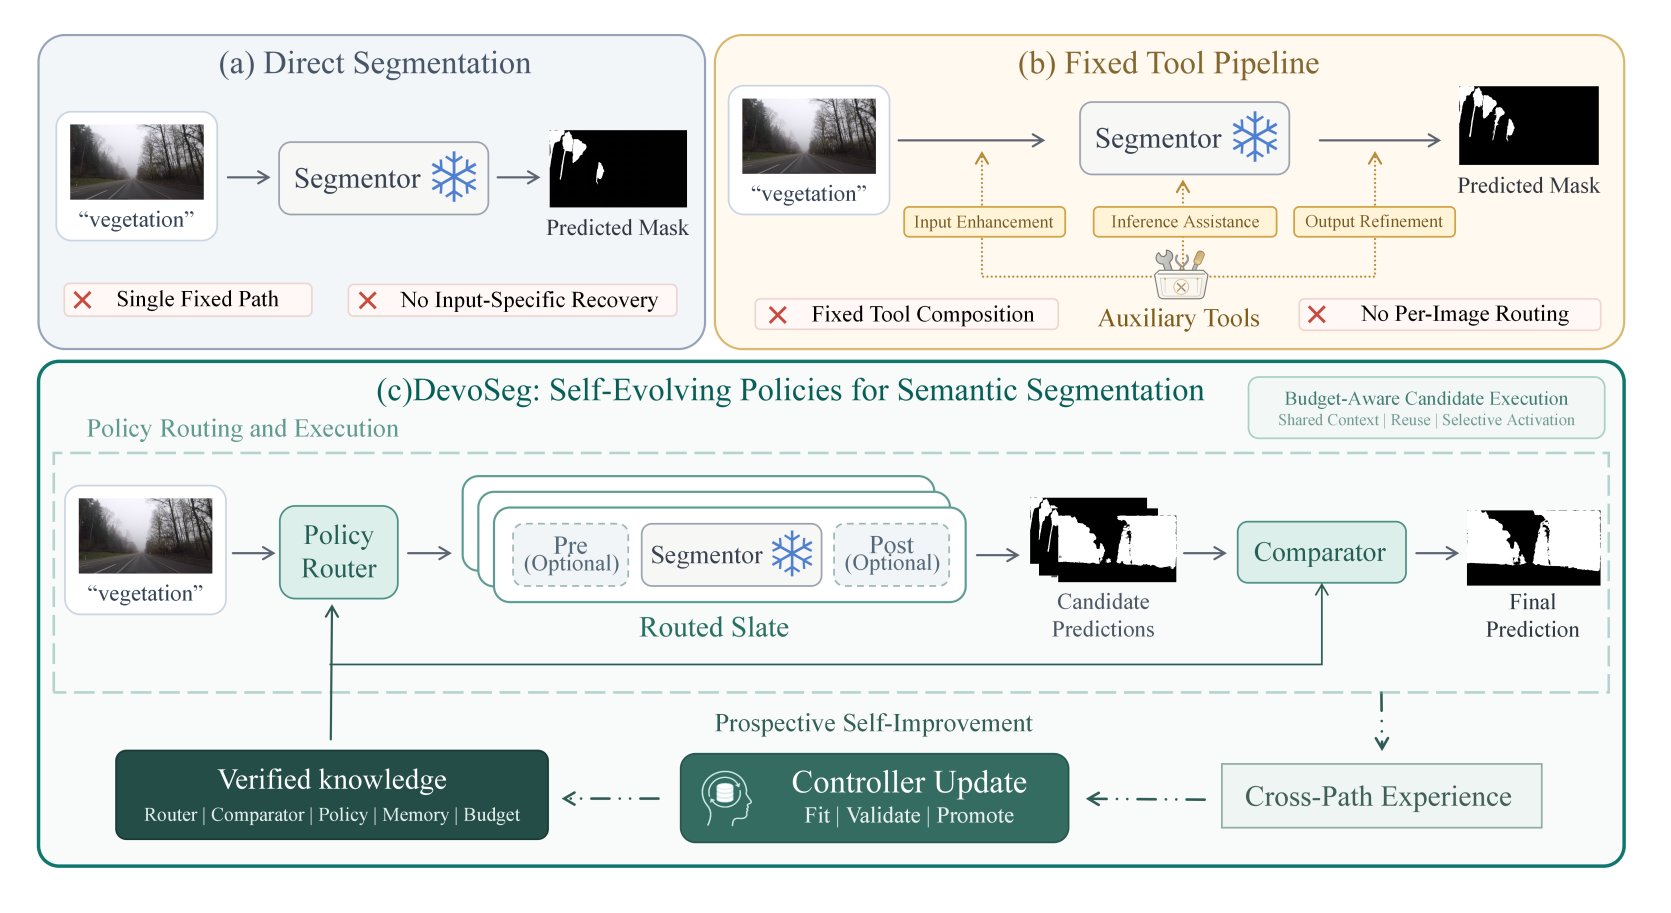
300 dpi PNG · 图注 · 源PDF
引言图1对比直接分割及固定工具路径的限制与按图像路由、比较和跨案例更新的概念,明确用于引出问题。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 298],PDF点、左上角原点。
Figure 1: Direct segmentation and a fixed tool pipeline follow predetermined paths. DevoSeg routes
policies per image, compares their masks, and uses completed cases to update its decision state.
HIVE: Holistic Image-Adaptive Vocabulary Evolution for Training-Free Dense Vision-Language Inference
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页 · ICLR27_kv0BeIZGMk_F
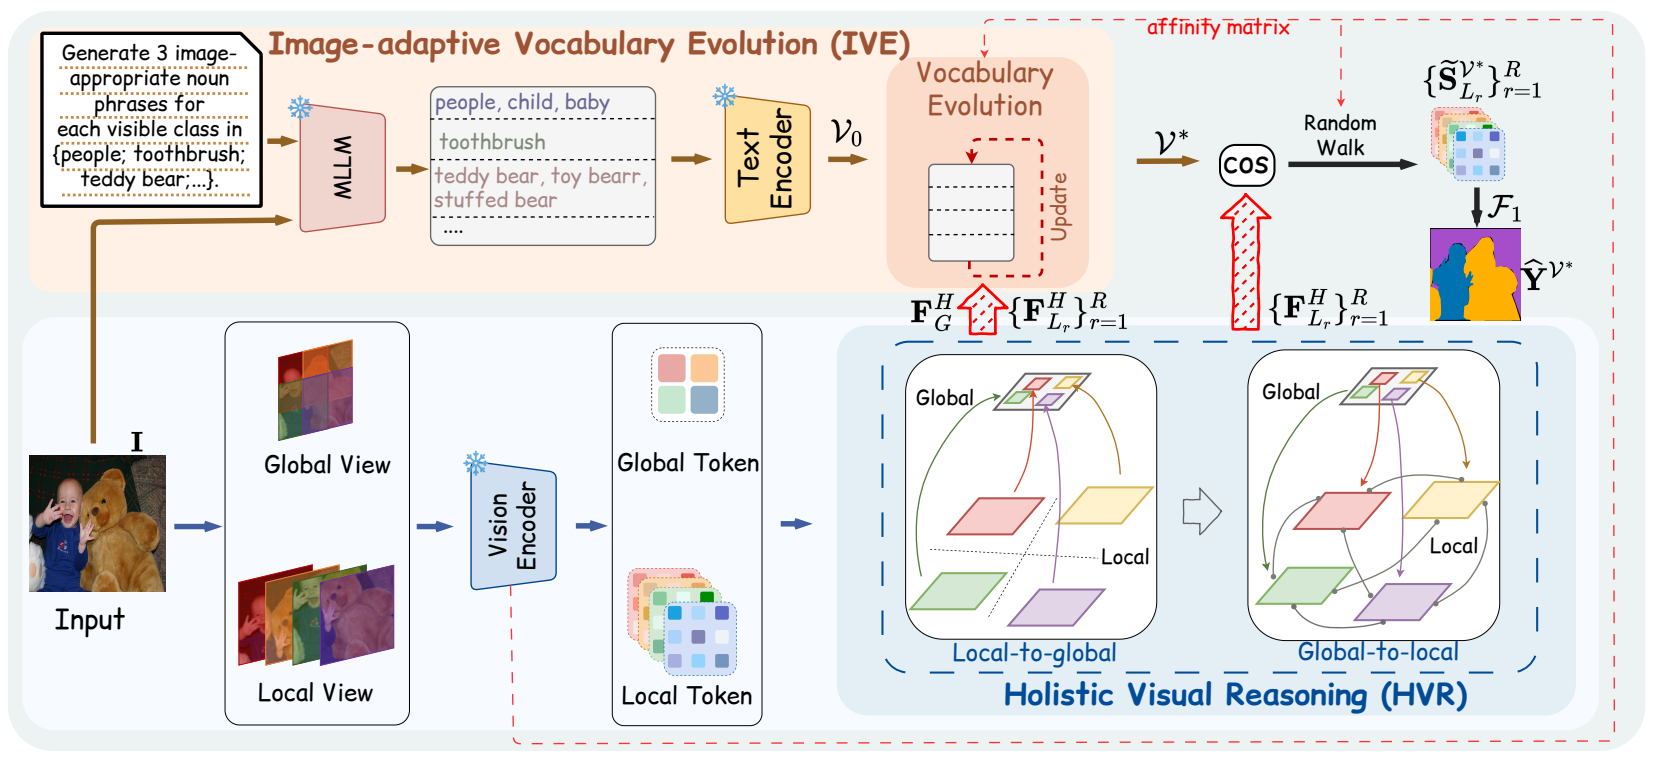
300 dpi PNG · 图注 · 源PDF
方法节与图2给出HVR与IVE两部分以及图像、词汇到稠密预测的整体关系。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[107, 80, 506, 263],PDF点、左上角原点。
Figure 2: Overview of HIVE. A frozen visual encoder processes a global view and multiple overlap-
ping local views. HVR refines local features through local-to-global-to-local interaction, producing
holistic local representations {FH }R . IVE iteratively evolves an image-specific vocabulary set
Lr r=1
V∗ under visual guidance. Finally, the local predictions derived from {ZV∗}R are refined and
Lr r=1
fused to produce the final segmentation Y˜︁ V∗.HIVE: Holistic Image-Adaptive Vocabulary Evolution for Training-Free Dense Vision-Language Inference
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第1页 · ICLR27_kv0BeIZGMk_M
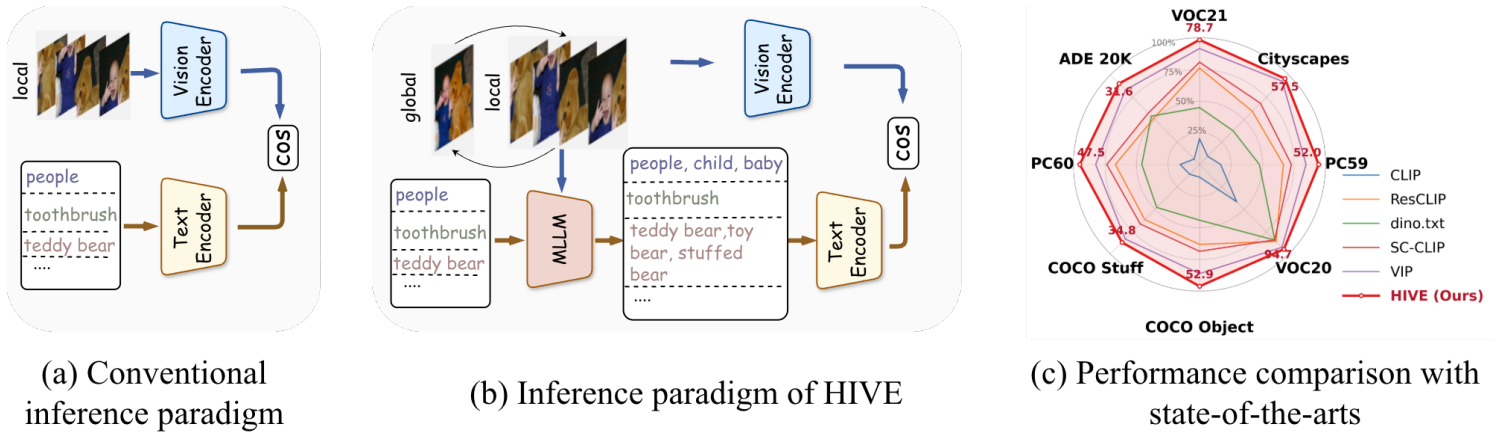
300 dpi PNG · 图注 · 源PDF
引言与图1(a)(b)对照固定类别名称和独立局部视图的现有范式,说明图像自适应词汇与全局上下文需求;保留同图(c)性能面板,整体并非仅性能报告。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[126, 216, 486, 322],PDF点、左上角原点。
Figure 1: Paradigm and performance comparison between conventional approach and our HIVE.
Past as Guidance, Not Just Constraint: Cross-Level Knowledge Reorganization for Class-Incremental Semantic Segmentation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 3 · PDF第5页 · ICLR27_9S1a6H8xUR_F
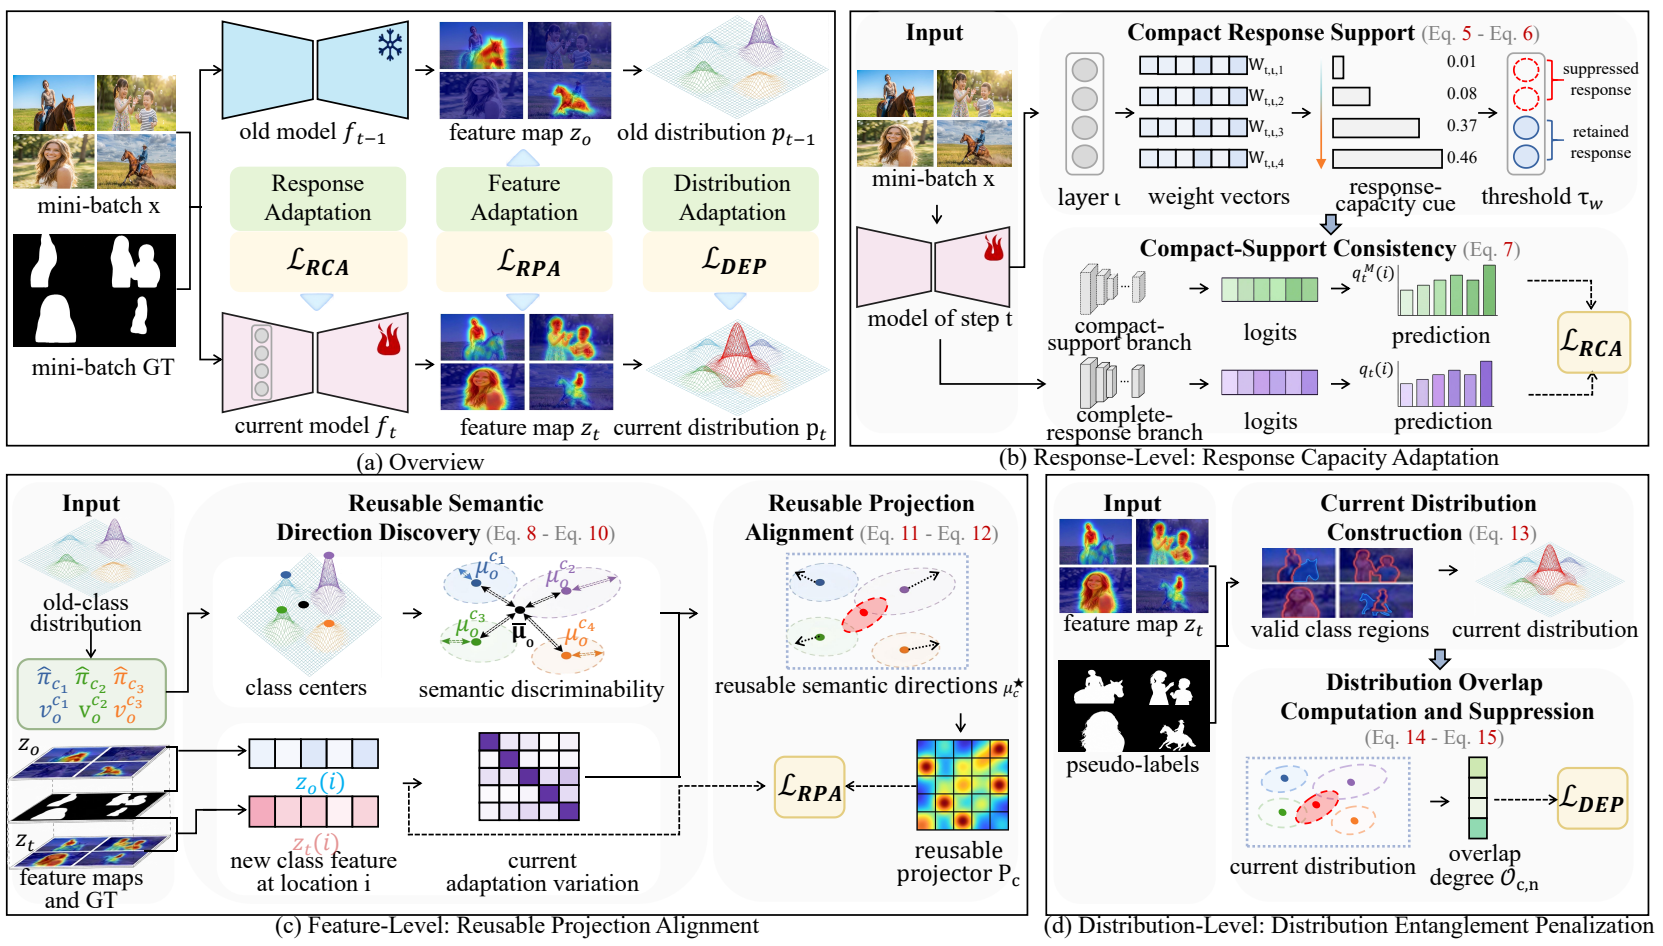
300 dpi PNG · 图注 · 源PDF
3.2节和图3给出AKI整体三层知识重组织,并完整展示RCA、RPA、DEP以及监督关系。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[107, 80, 506, 307],PDF点、左上角原点。
Figure 3: Overview of AKI. (a) Three-level knowledge reorganization. (b) RCA constructs compact
response support and enforces response consistency. (c) RPA discovers reusable semantic directions
for selective alignment. (d) DEP suppresses current old–new distribution overlap.
Past as Guidance, Not Just Constraint: Cross-Level Knowledge Reorganization for Class-Incremental Semantic Segmentation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_9S1a6H8xUR_M
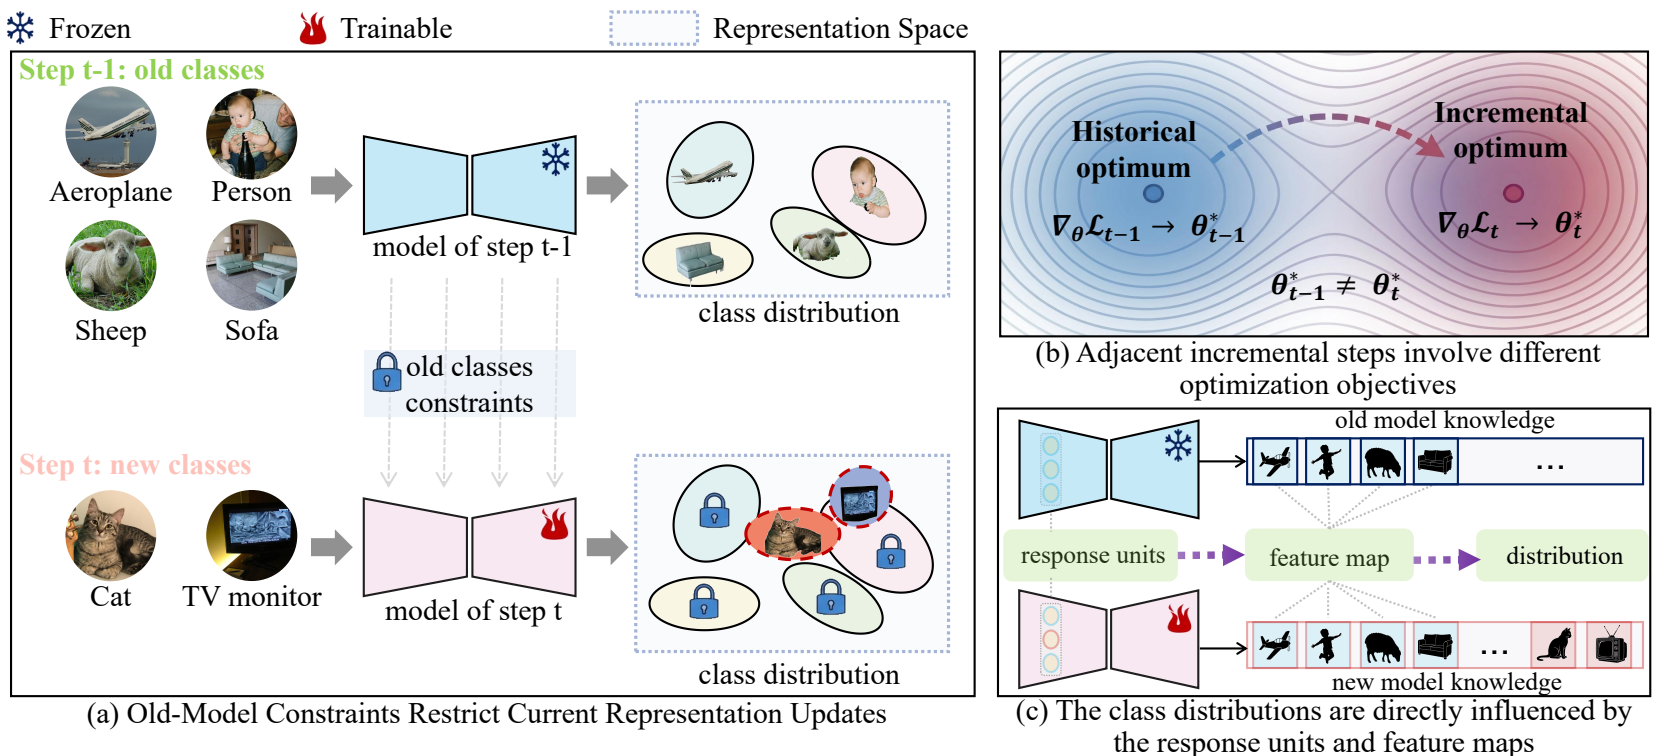
300 dpi PNG · 图注 · 源PDF
引言图1以旧模型约束、跨步最优点变化和跨层耦合三部分解释持续分割的旧新类别冲突与知识重组织需求。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[107, 80, 506, 261.4],PDF点、左上角原点。
Figure 1: Motivation of AKI. (a) Under fixed model capacity, inherited constraints can restrict the representation reorganization required by current supervision, increasing old–new distribution overlap. (b) Cross-step optimization analysis shows that adjacent incremental objectives generally correspond to different stationary states, θ*_(t−1) ≠ θ*_t, while inheritance constraints can restrict current-task-aligned adaptation. (c) Empirical analysis reveals cross-level coupling among response, feature, and distribution variations, motivating coordinated knowledge reorganization across three levels.
ReTax-Seg: Visually Grounded Reversible Taxonomy Transport for Image Segmentation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第6页 · ICLR27_dMBwWu68Lm_F
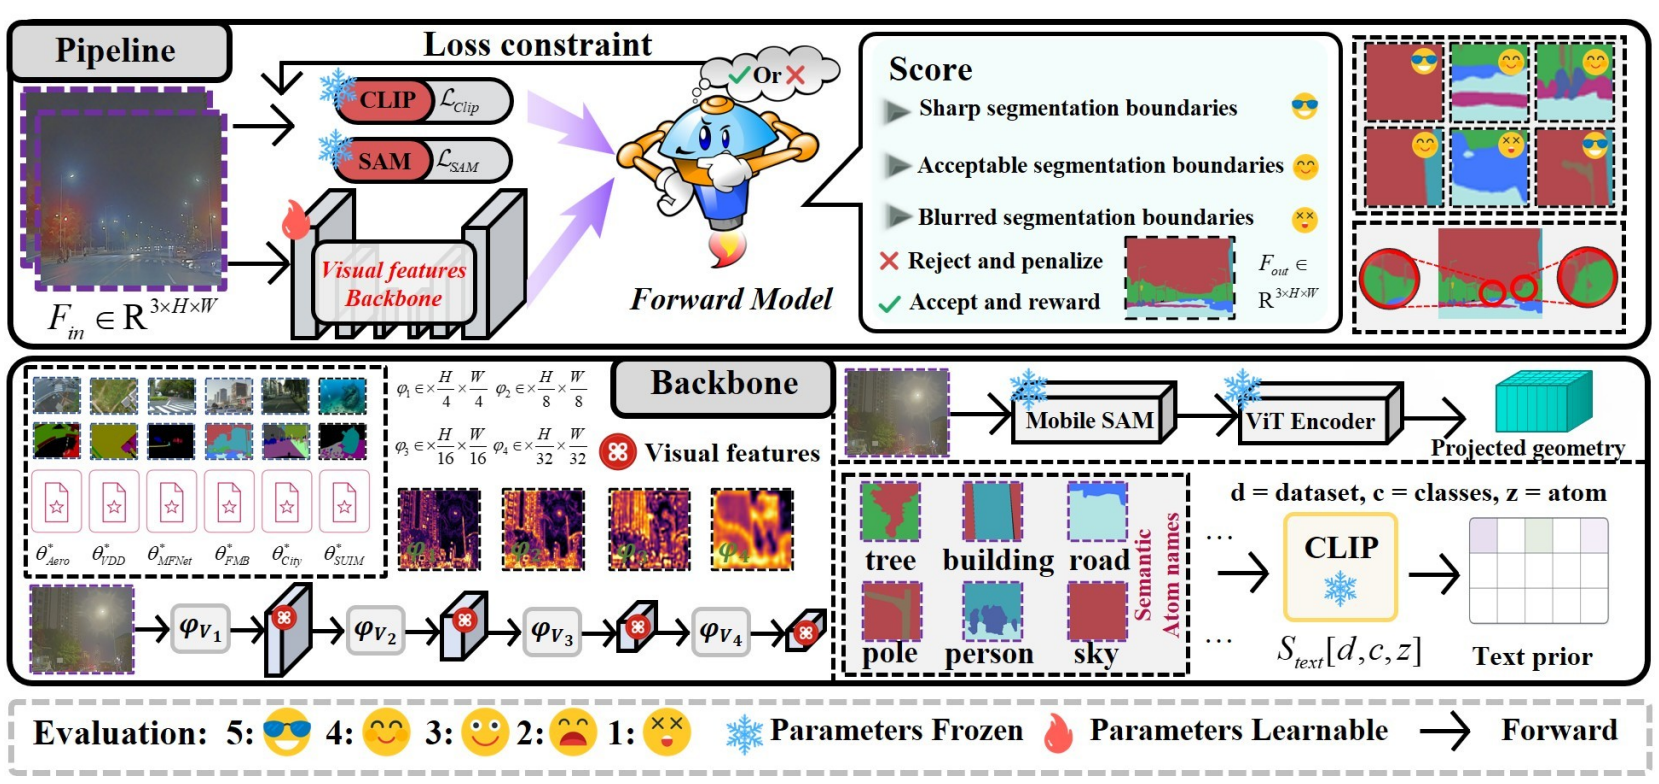
300 dpi PNG · 图注 · 源PDF
图2及方法节给出从多尺度骨干、MobileSAM原子、CLIP语义到分类体系传输及监督的整体训练框架。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown; authors_deny_generative_AI_assistance。第9页AI use statement明确表示未使用生成式AI辅助;具体绘图软件未知。
裁剪坐标:[107, 80, 505, 268],PDF点、左上角原点。
Figure 2: Overview of ReTax-Seg. The upper panel summarizes the training pipeline. The visual
backbone and forward model are learnable. CLIP and SAM remain frozen. Boundary quality scores
the segmentation outputs. The lower panel details the multiscale visual backbone, the frozen Mobile-
SAM geometry branch, representative semantic atoms, and the frozen CLIP text-prior construction.
The symbol θ∗ denotes the weights associated with dataset d. The star marks the selected trained
d
checkpoint. For example, θ∗ represents the Cityscapes-specific weights. Snowflakes and flames
City
indicate frozen and learnable components, respectively.
ReTax-Seg: Visually Grounded Reversible Taxonomy Transport for Image Segmentation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_dMBwWu68Lm_M
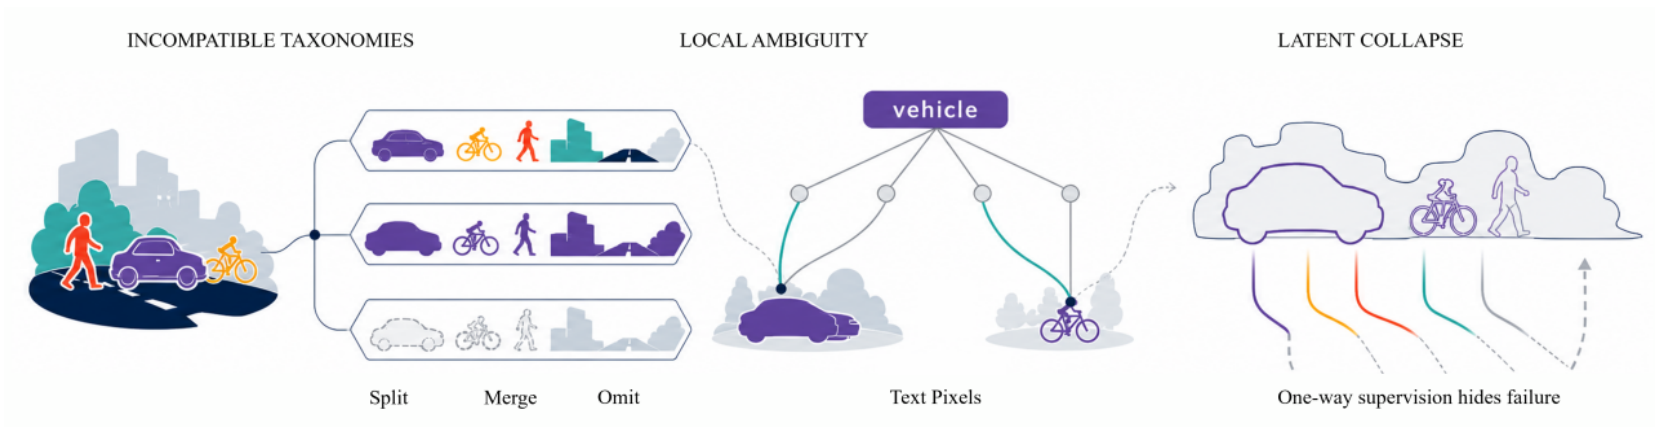
300 dpi PNG · 图注 · 源PDF
引言及图1用分类体系不兼容、局部视觉歧义和潜在语义坍缩三个场景引出问题。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown; authors_deny_generative_AI_assistance。第9页AI use statement明确表示未使用生成式AI辅助;具体绘图软件未知。
裁剪坐标:[107, 80, 505, 184],PDF点、左上角原点。
Figure 1: Three unresolved challenges in taxonomy-aware segmentation. Left: identical visual
concepts can be split, merged, or omitted by different annotation policies. Center: a coarse label such
as vehicle is compatible with several semantic atoms, but the correct relation changes with local visual
evidence, which a class name alone cannot observe. Right: forward-only supervision can preserve an
apparently correct coarse mask even when distinct atom channels become indistinguishable. A useful
compiler must therefore be local, visually grounded, and semantically recoverable.
Rethinking Unaligned RGB-T Dense Prediction as Cross-Modal Information Transport
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页 · ICLR27_OHqdlezqWF_F
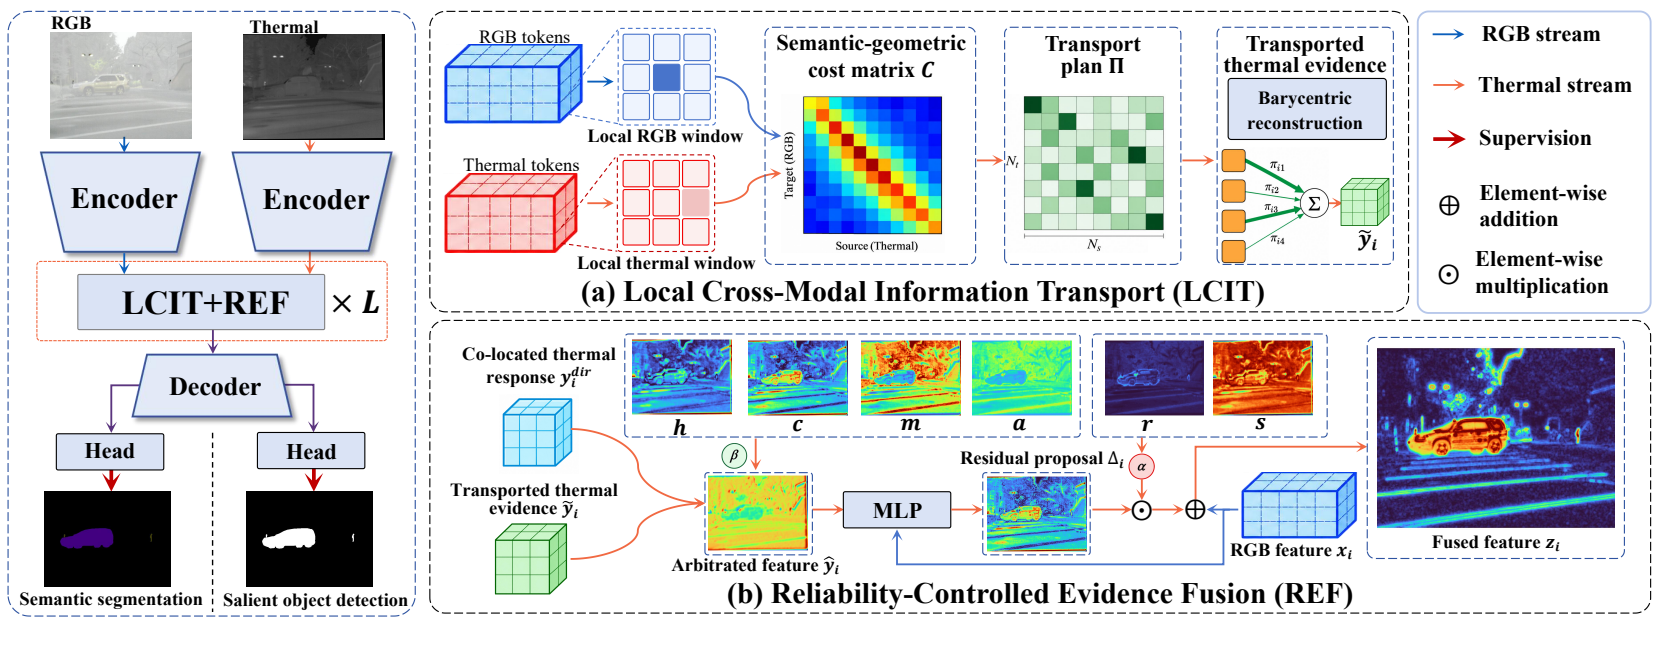
300 dpi PNG · 图注 · 源PDF
图2与方法节给出双模态编码、逐尺度LCIT传输、REF融合及解码器的整体语义分割计算路径。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[107, 80, 506, 235],PDF点、左上角原点。
Figure 2: Overview of the proposed UCMIT framework. At each scale, LCIT reconstructs RGB-
aligned thermal evidence from nearby thermal sources. REF then arbitrates between co-located and
transported evidence and regulates its residual injection into the RGB stream. The resulting multi-
scale representations are progressively aggregated for task-specific dense prediction.
Rethinking Unaligned RGB-T Dense Prediction as Cross-Modal Information Transport
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_OHqdlezqWF_M
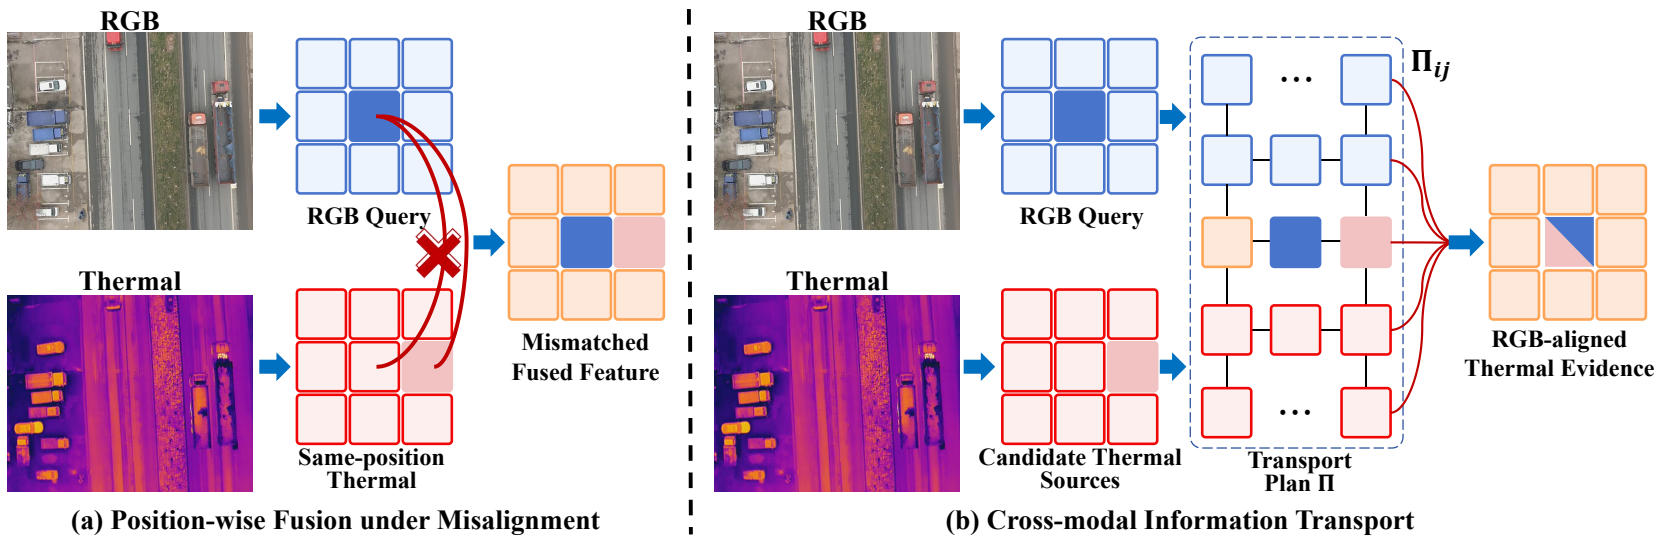
300 dpi PNG · 图注 · 源PDF
图1及引言对比逐位置融合与跨位置信息传输,解释RGB-T错位时直接重加权无法恢复互补证据的局限。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[107, 80, 506, 209],PDF点、左上角原点。
Figure 1: Motivation of UCMIT. Unlike position-wise fusion under cross-modal misalignment,
UCMIT retrieves complementary thermal evidence from plausible nearby locations and reconstructs
it in RGB coordinates before representation update.
SEER: Semantic Evidence for Executable Region Propagation in Open-Vocabulary Semantic Segmentation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第3页 · ICLR27_hEBqQJhg1b_F
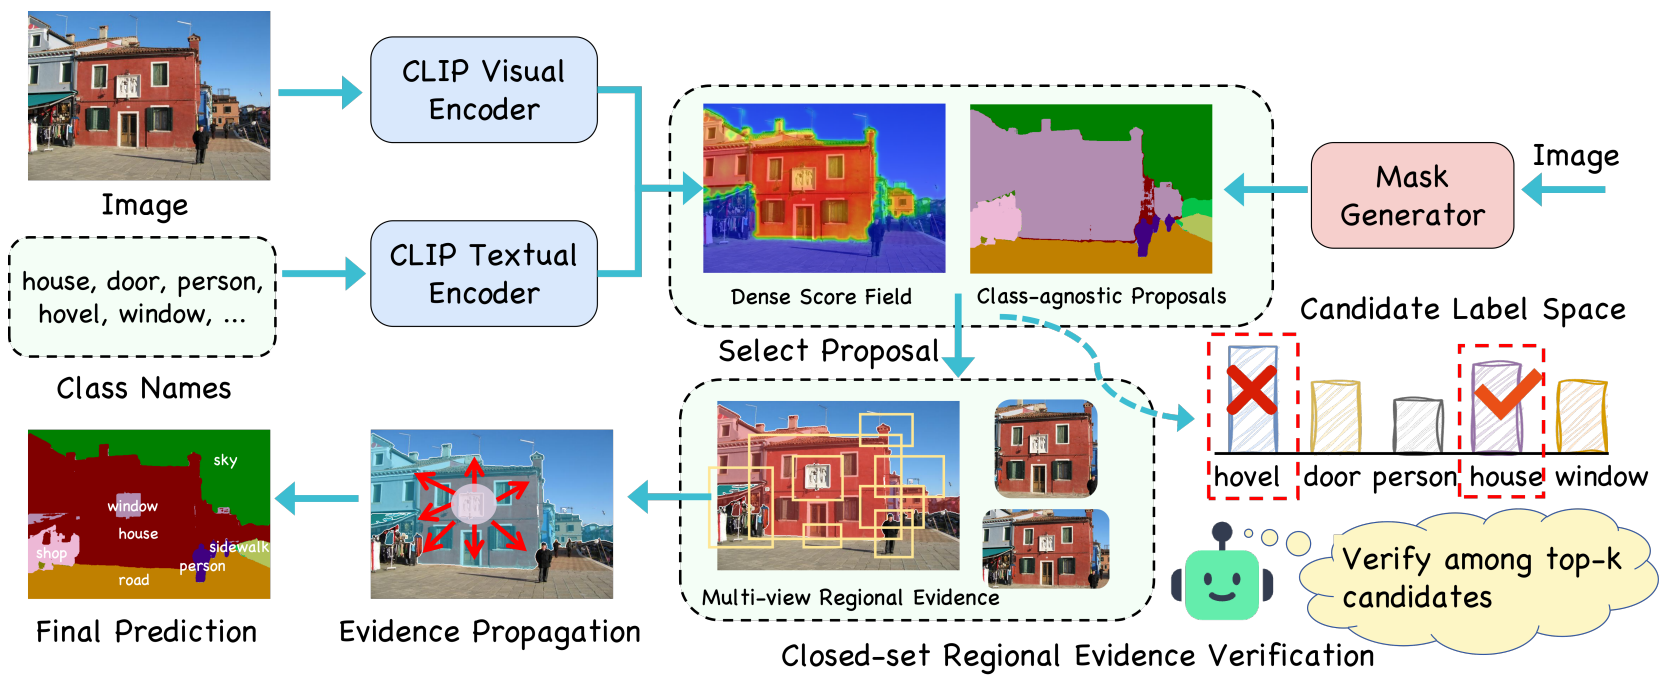
300 dpi PNG · 图注 · 源PDF
图2及第3节展示固定预测、候选区域、多视图证据、认证门控和像素传播的完整SEER流程。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 242],PDF点、左上角原点。
Figure 2: Overview of SEER. SEER converts regional VLM evidence into executable OVSS label
propagation. From a fixed prediction, it selects ambiguous proposals, derives score-based candidates,
and verifies them with multi-view closed-set reasoning. Score support and vocabulary legality certify
the verified label, and the OVSS model controls its pixel propagation.
SEER: Semantic Evidence for Executable Region Propagation in Open-Vocabulary Semantic Segmentation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 5 · PDF第9页 · ICLR27_hEBqQJhg1b_M
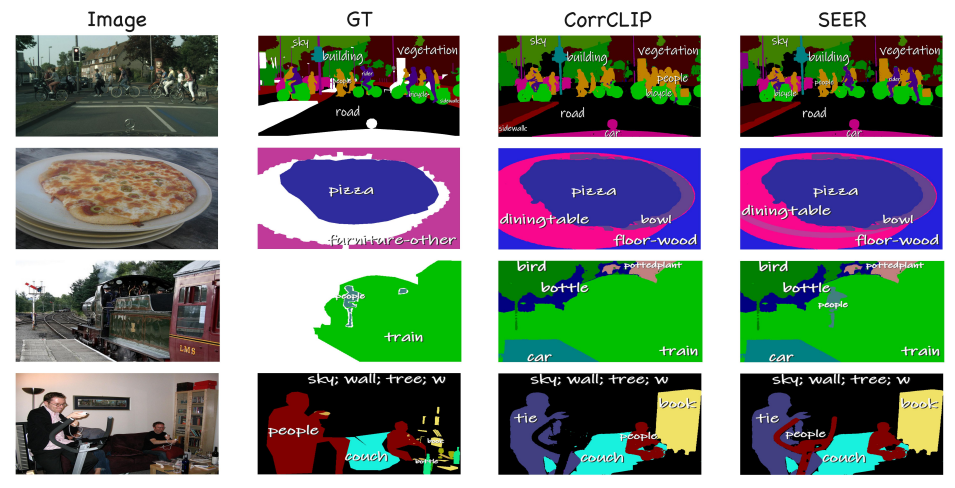
300 dpi PNG · 图注 · 源PDF
图5及4.5节Failure boundary具体列出混合候选、细结构和弱得分支持导致边界错误的失败类型。图1同时含流程和性能,功能混合不选。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[114, 91, 343, 208],PDF点、左上角原点。
Figure 5: Residual failure cases. Mixed proposals, thin struc-
tures, and weak score support can leave errors near boundaries.
Additional examples appear in Appendix K.
SHAPE: Structural Hierarchy of Affinities for Patch Enhancement in Training-Free Open-Vocabulary Semantic Segmentation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页 · ICLR27_67ApUu5dSo_F
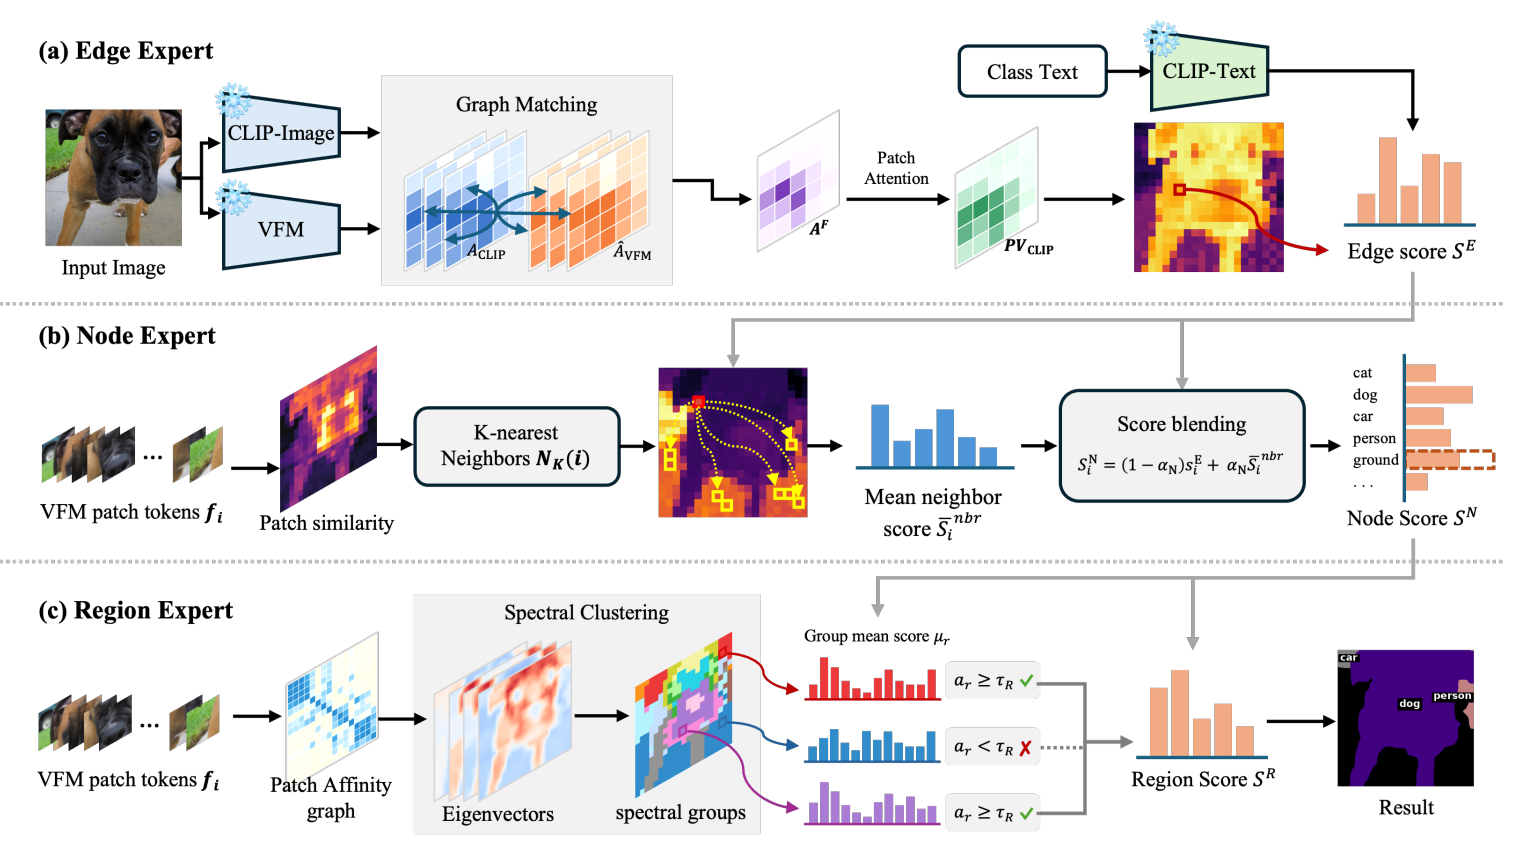
300 dpi PNG · 图注 · 源PDF
图2展示SHAPE三类专家的连续完整计算过程,从图像/文本特征到边、节点、区域得分和最终分割。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[122, 79, 490, 283],PDF点、左上角原点。
Figure 2: Overview of SHAPE. (a) The Edge Expert uses relation-level VFM support to guide
CLIP feature aggregation. (b) The Node Expert uses a patch-specific VFM neighborhood to refine
each score. (c) The Region Expert uses an agreement-gated regional support to reduce residual
fragmentation. Together, the three experts organize VFM structure into complementary supports for
feature aggregation, patch-specific correction, and regional consistency.
SHAPE: Structural Hierarchy of Affinities for Patch Enhancement in Training-Free Open-Vocabulary Semantic Segmentation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_67ApUu5dSo_M
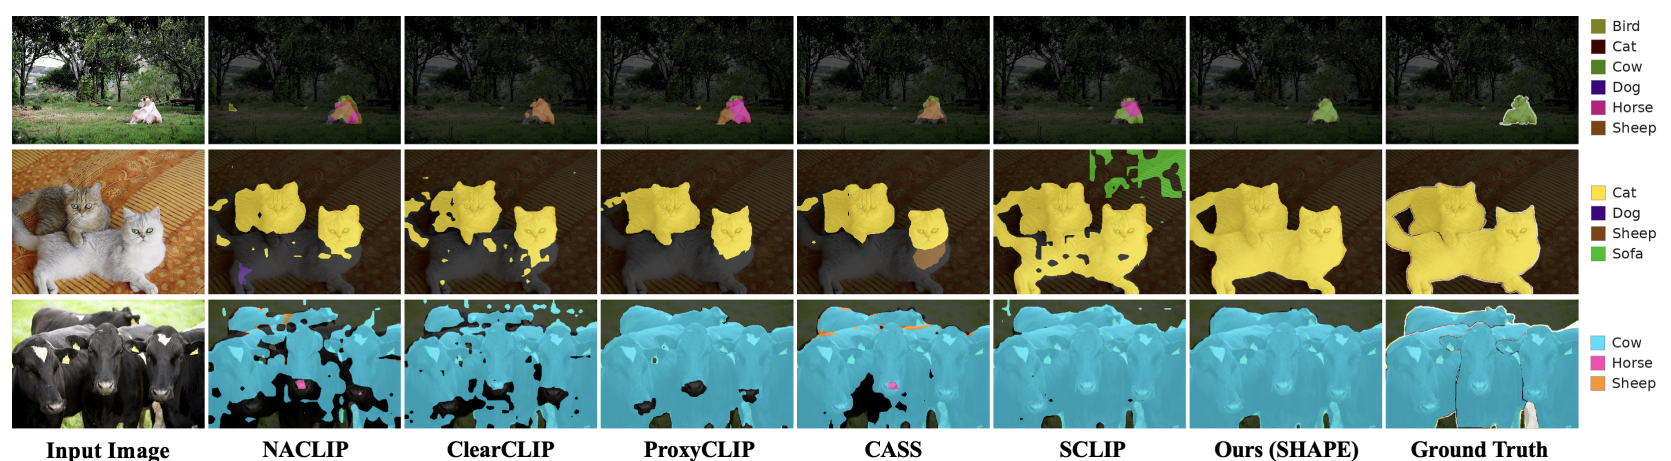
300 dpi PNG · 图注 · 源PDF
引言图1明确以牛和猫示例解释孤立patch噪声与语义区域碎裂两类失败,用于引出层次结构支持。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 189.5],PDF点、左上角原点。
Figure 1: Patch noise and region noise. Patch noise refers to isolated predictions that disagree with
surrounding patches, as seen in the cows (bottom), whereas region noise occurs when a semantic
region is split into inconsistent labels, as shown in the cow (top) and cats (middle). SHAPE reduces
both types of noise by selectively exploiting structural support through its Edge, Node, and Region
Experts at relation, patch, and region levels, respectively.
Where from Above, What from the Street: Learning Semantic Routing for Cross-View Segmentation under Pose Uncertainty
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页 · ICLR27_J2V6tPOCod_F
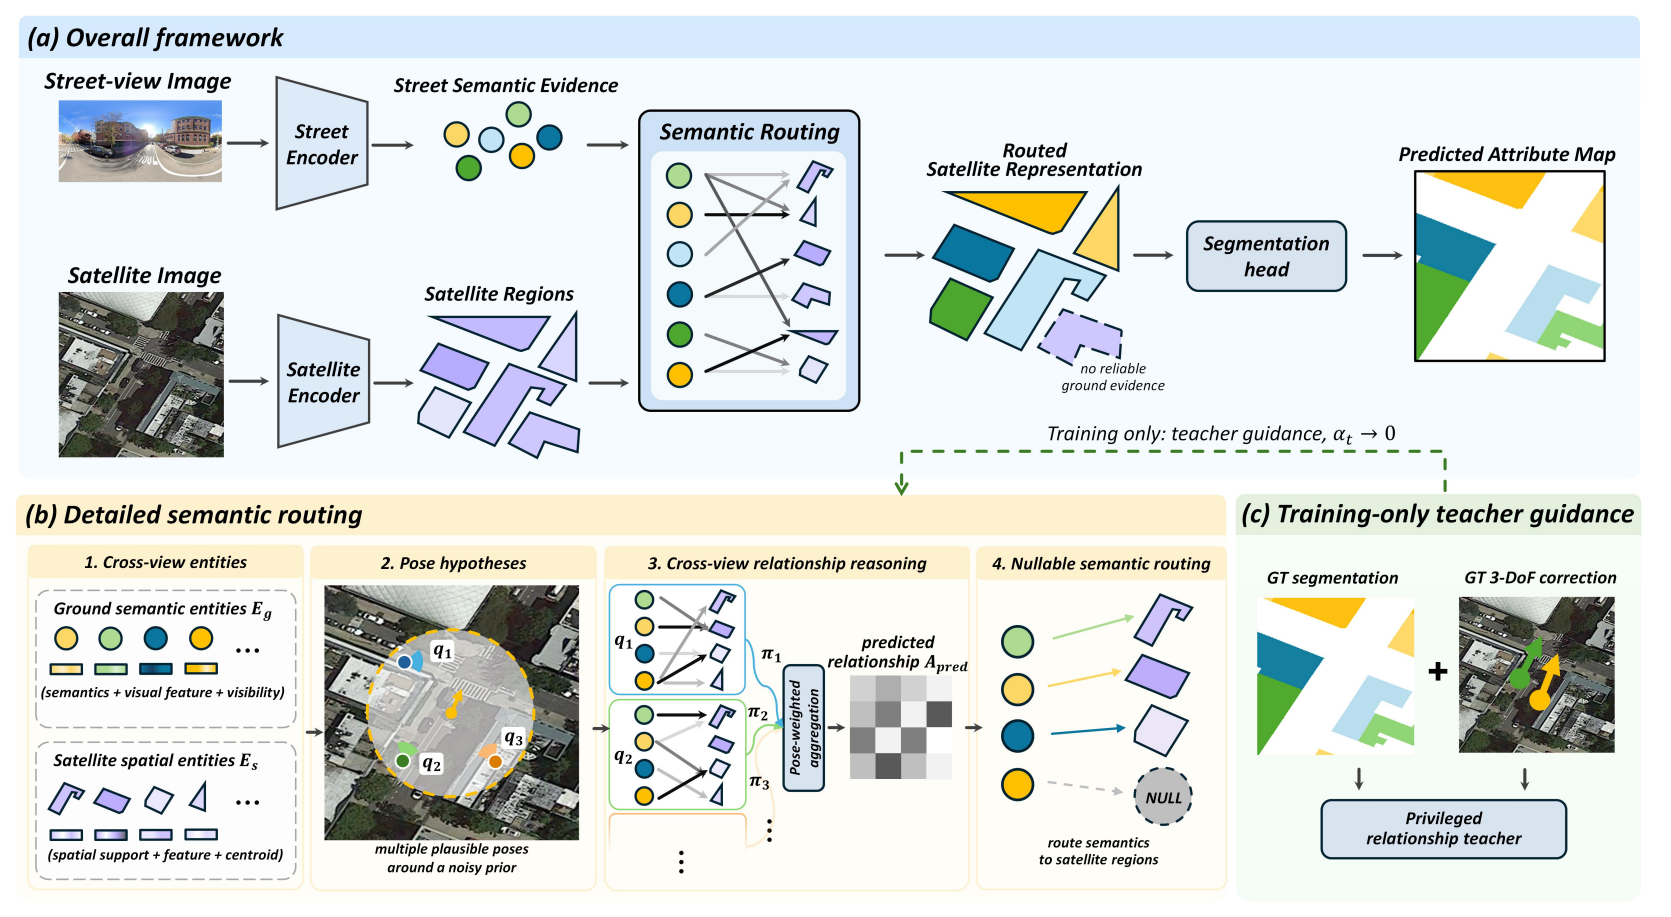
300 dpi PNG · 图注 · 源PDF
图2为CVRoute整体框架,覆盖跨视角编码、关系推理、姿态边缘化路由、训练教师和分割预测。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:generative_AI_figure_editing_unspecified_tool。作者声明用生成式AI编辑科学图;工具名及逐图对应未披露。
裁剪坐标:[106, 79, 507, 299],PDF点、左上角原点。
Figure 2: Overview of CVRoute. (a) Street-view semantics are routed to satellite-defined regions
for satellite-space prediction. (b) Cross-view entities are matched over multiple pose hypotheses and
fused through pose-marginalized nullable routing. (c) A training-only privileged relationship teacher
guides early routing and is gradually annealed out; inference uses only predicted relationships.
Where from Above, What from the Street: Learning Semantic Routing for Cross-View Segmentation under Pose Uncertainty
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_J2V6tPOCod_M
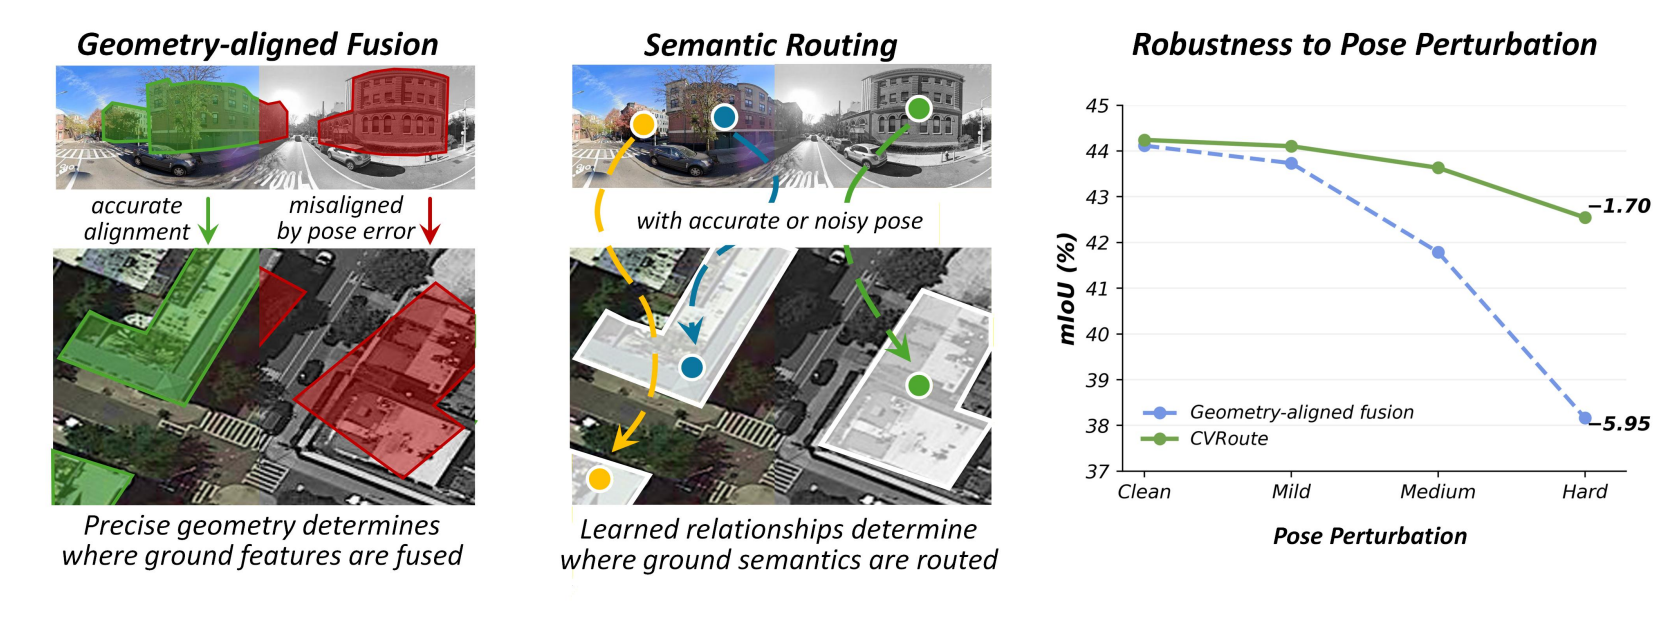
300 dpi PNG · 图注 · 源PDF
引言图1明确展示姿态误差破坏几何对齐的局限,对比语义路由概念。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:generative_AI_figure_editing_unspecified_tool。作者声明用生成式AI编辑科学图;工具名及逐图对应未披露。
裁剪坐标:[106, 79, 507, 229],PDF点、左上角原点。
Figure 1: Motivation for semantic routing under pose uncertainty. Pose errors weaken the spatial
correspondence used by alignment-based cross-view fusion, motivating CVRoute to associate street-
view semantic evidence with satellite regions through learned cross-view relationships.
$\mathrm{S}^{3}$-PnP: Plug-and-Play Denoising for Scientific Imaging with Self-Supervised Score Priors
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第6页 · ICLR27_v44KR7QgKE_F
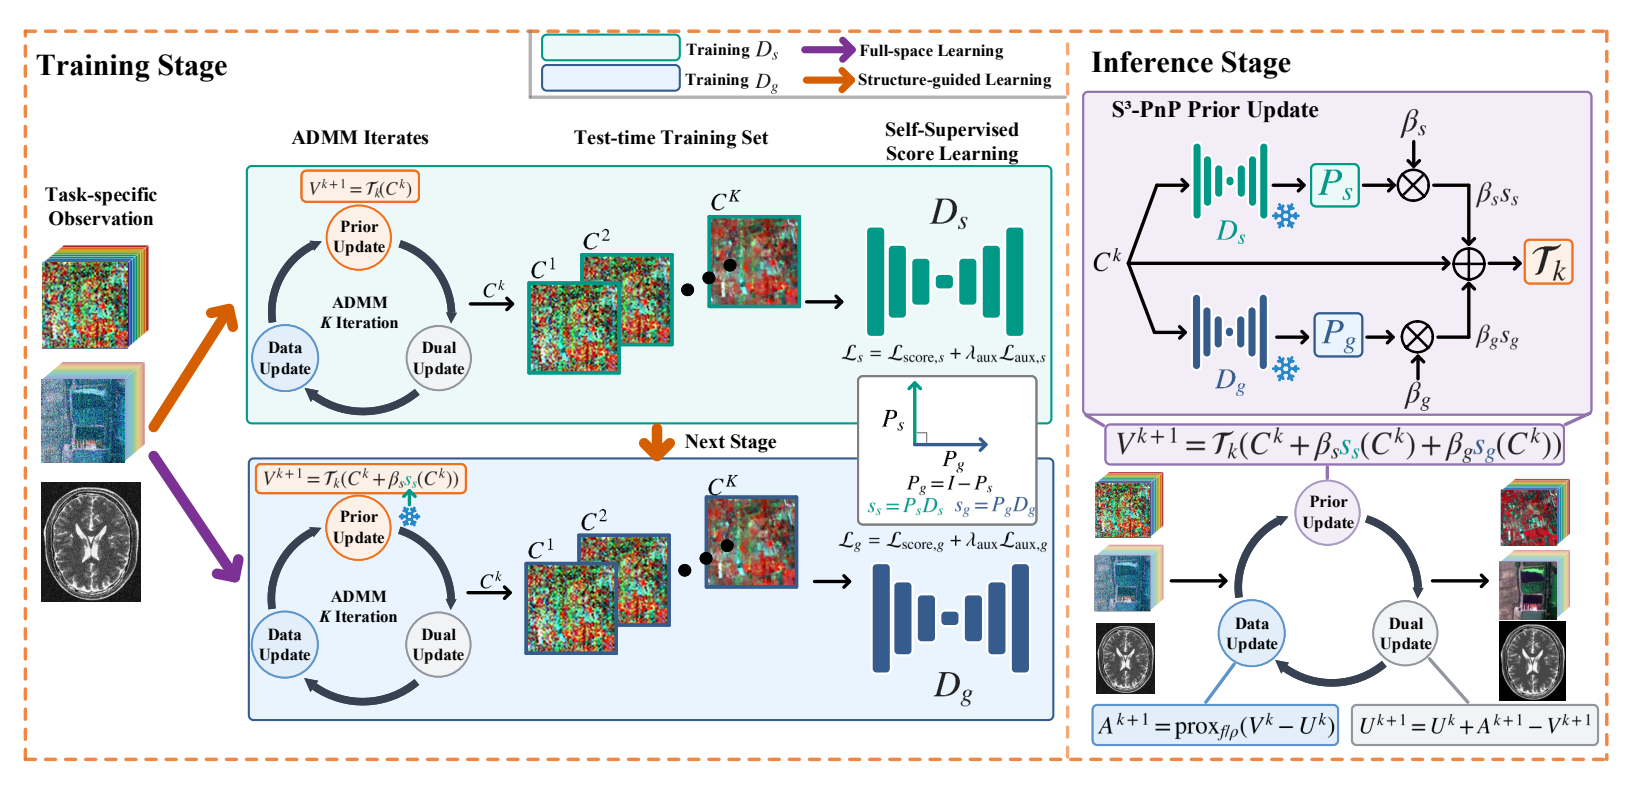
300 dpi PNG · 图注 · 源PDF
图2为S³-PnP训练和推理完整流程,覆盖全空间/结构引导学习及单步解析先验更新。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-10-13;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
固定OpenReview投稿PDF于10月3日公开;匹配的arXiv v1较后,不用于提前该视觉版本日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Konrad Schindler;47613;快照2026-10-21。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[111, 82, 501, 273],PDF点、左上角原点。
Figure 2: Training and inference of S3-PnP. Purple arrows indicate full-space learning with P = 0,
s
P = I, and β = 0. Orange arrows indicate structure-guided learning: D is trained and frozen, and
g s s
its correction is enabled to collect a new state training set for D . At inference, active corrections are
g
evaluated at the same ADMM input and combined before a single analytical prior update. Snowflakes
denote frozen networks.
$\mathrm{S}^{3}$-PnP: Plug-and-Play Denoising for Scientific Imaging with Self-Supervised Score Priors
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_v44KR7QgKE_M
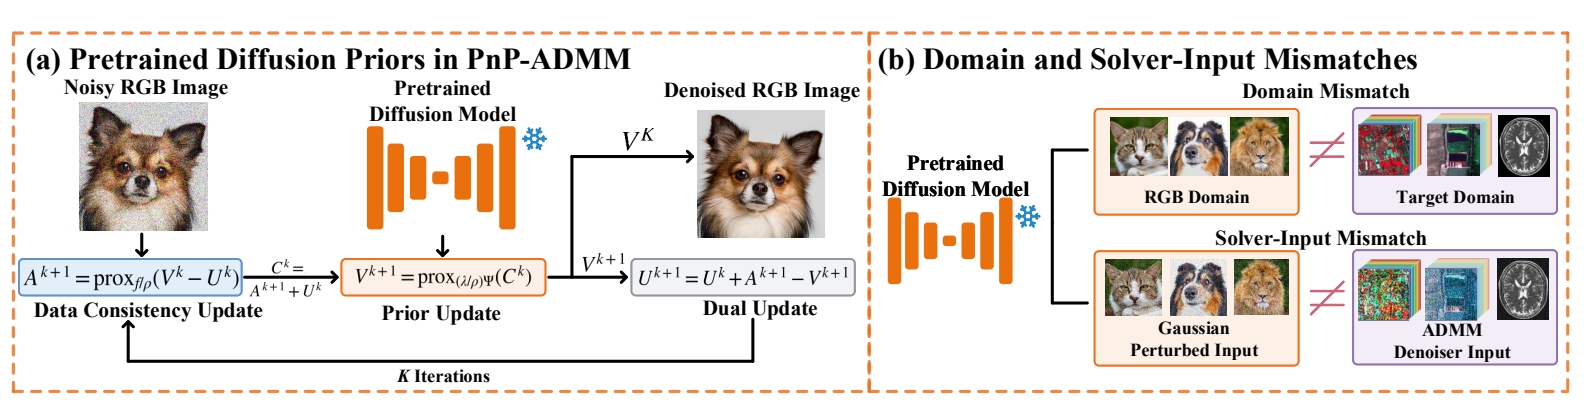
300 dpi PNG · 图注 · 源PDF
引言图1明确示意预训练与目标图像域、训练输入与ADMM输入两类分布失配。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-10-13;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
固定OpenReview投稿PDF于10月3日公开;匹配的arXiv v1较后,不用于提前该视觉版本日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Konrad Schindler;47613;快照2026-10-21。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[121, 81, 502, 181],PDF点、左上角原点。
Figure 1: Two sources of mismatch when using pretrained image priors in scientific imaging:
differences between the pretraining and target image domains, and differences between score-model
training inputs and ADMM denoiser inputs.
Degradation Frequency Curve: An Explicit Frequency-Quantified Representation for All-in-One Image Restoration
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 4 · PDF第6页 · ICLR27_IP9k9VdnnS_F
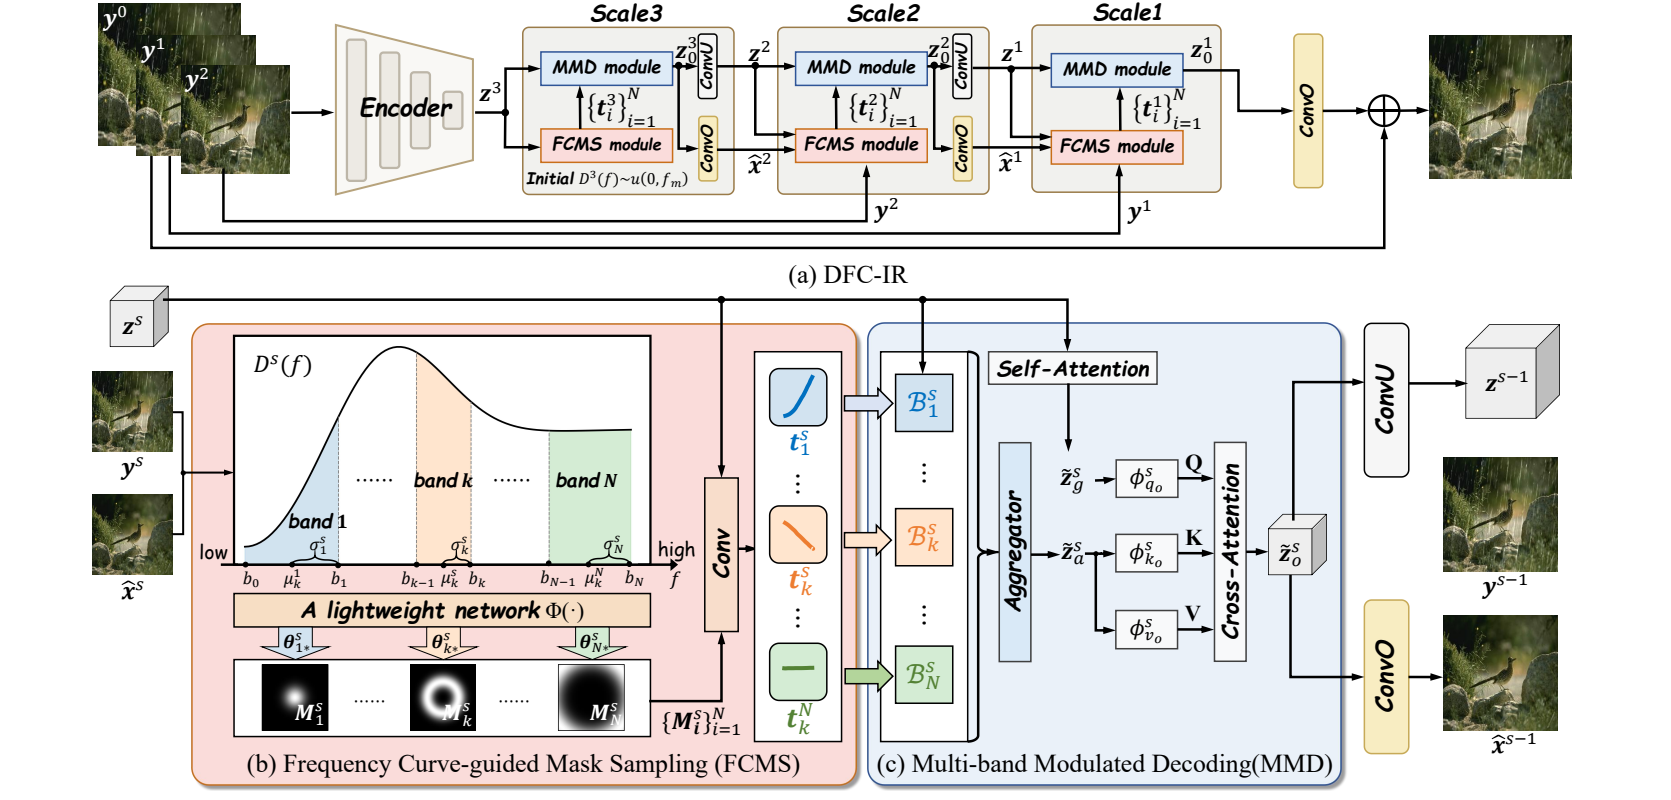
300 dpi PNG · 图注 · 源PDF
正文4节明确称图4(a)为DFC-IR整体框架,完整图同时包含FCMS与MMD关系。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-05-17;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
当前整体布局压缩调整,不把旧构图日期赋给投稿图
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Qibin Hou;34230;快照2026-10-21。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 271],PDF点、左上角原点。
Figure 4: (a) The overall framework of DFC-IR. (b) FCMS for adaptive DFC tokenization and
spectral token extraction. (c) MMD for token-guided feature modulation and aggregation.
Degradation Frequency Curve: An Explicit Frequency-Quantified Representation for All-in-One Image Restoration
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第1页 · ICLR27_IP9k9VdnnS_M
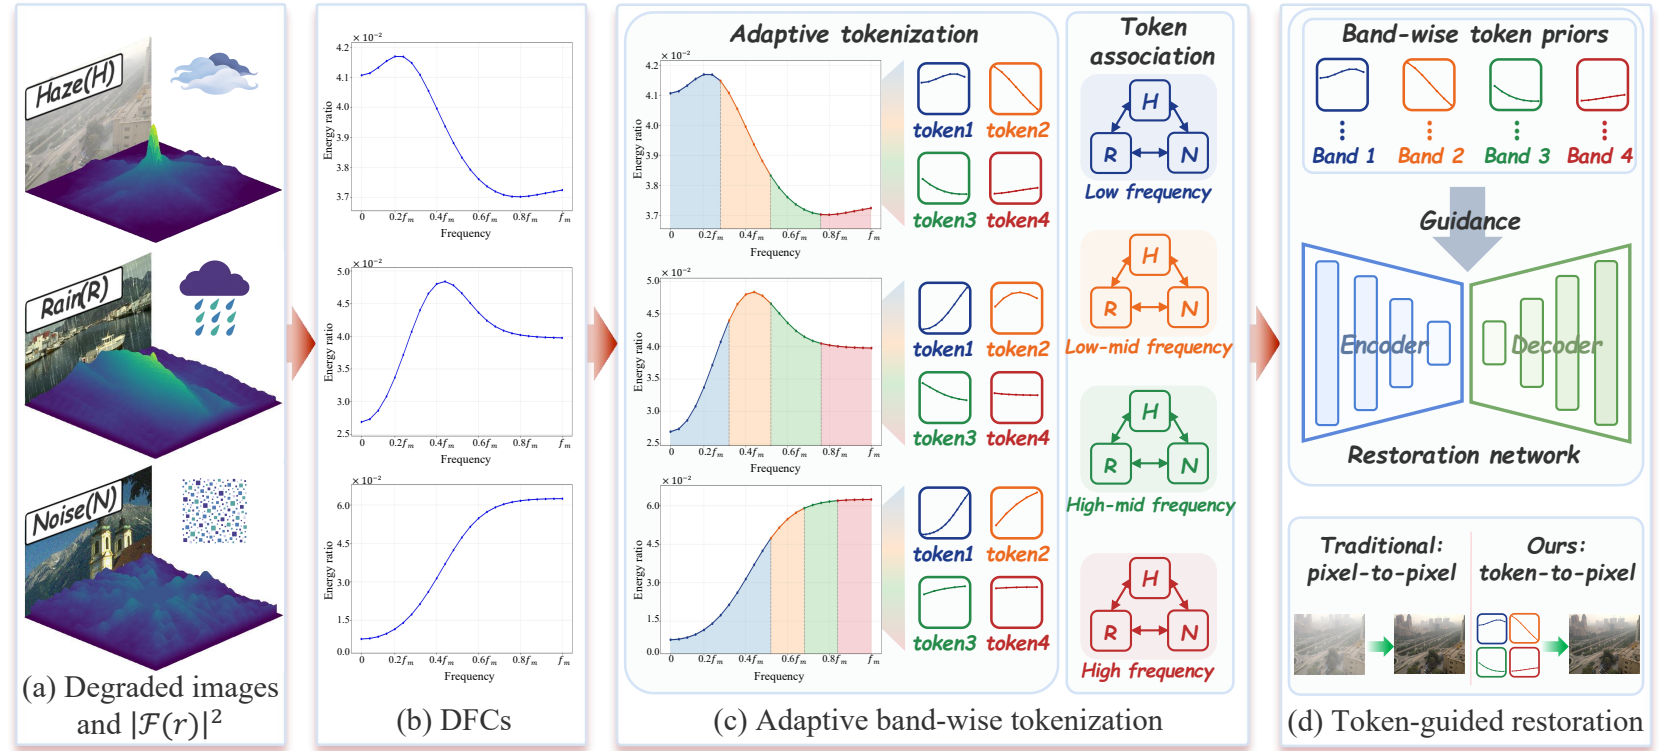
300 dpi PNG · 图注 · 源PDF
引言图1以退化图像、频域残差及传统pixel-to-pixel与token-to-pixel范式对比,引出将隐式退化显式量化的问题。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-05-17;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
v1六组变四组,图标与构图重绘
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Qibin Hou;34230;快照2026-10-21。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 189, 507, 370],PDF点、左上角原点。
Figure 1: Motivation of the proposed DFC-guided restoration paradigm. (a) Degraded images and residual frequency-domain energy maps; (b) DFCs derived from residual-to-degraded energy ratios; (c) Adaptive DFC tokenization into band-wise spectral tokens, where same-band tokens across degradations form reusable spectral priors; (d) Token-guided degradation-aware restoration.
Fixing the Last Mile: Failure-Aware Image Restoration with Region-Specific Guidance
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 6 · PDF第6页 · ICLR27_kQkih2eMHu_F
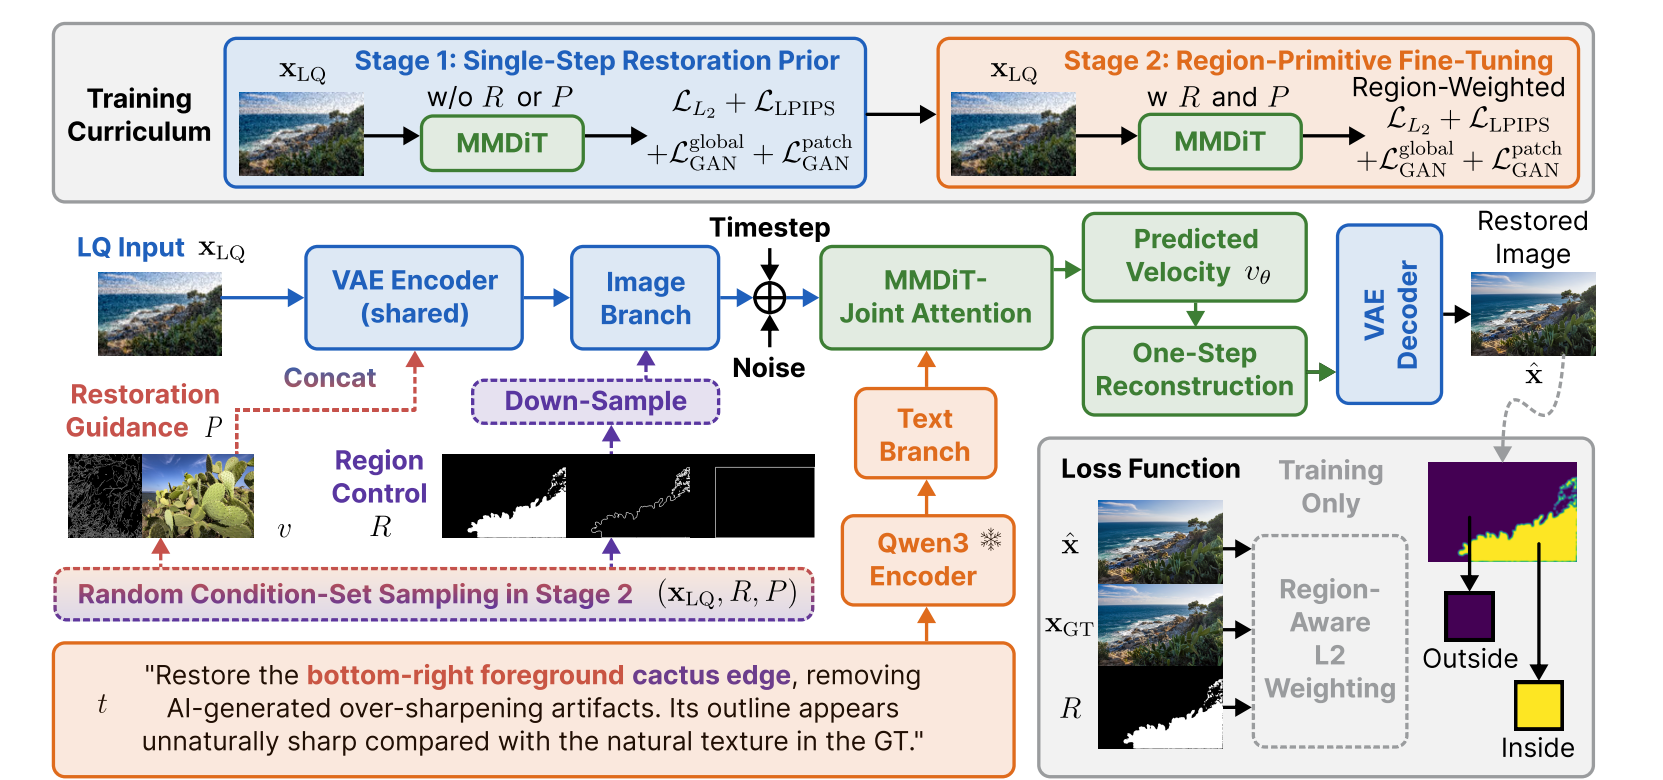
300 dpi PNG · 图注 · 源PDF
3.2.2节及图6明确展示FAIR完整两阶段训练、条件控制与区域损失;此前图3仅是数据构建流程,未作为整体复原框架选取。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[107, 79, 506, 266],PDF点、左上角原点。
Figure 6: Overview of FAIR’s two-stage training. Stage 1 learns a general restoration prior. Stage 2
conditions restoration on region control R and guidance P = (t, v), using region-aware supervision
to bind the guidance to its target region.
Fixing the Last Mile: Failure-Aware Image Restoration with Region-Specific Guidance
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_kQkih2eMHu_M
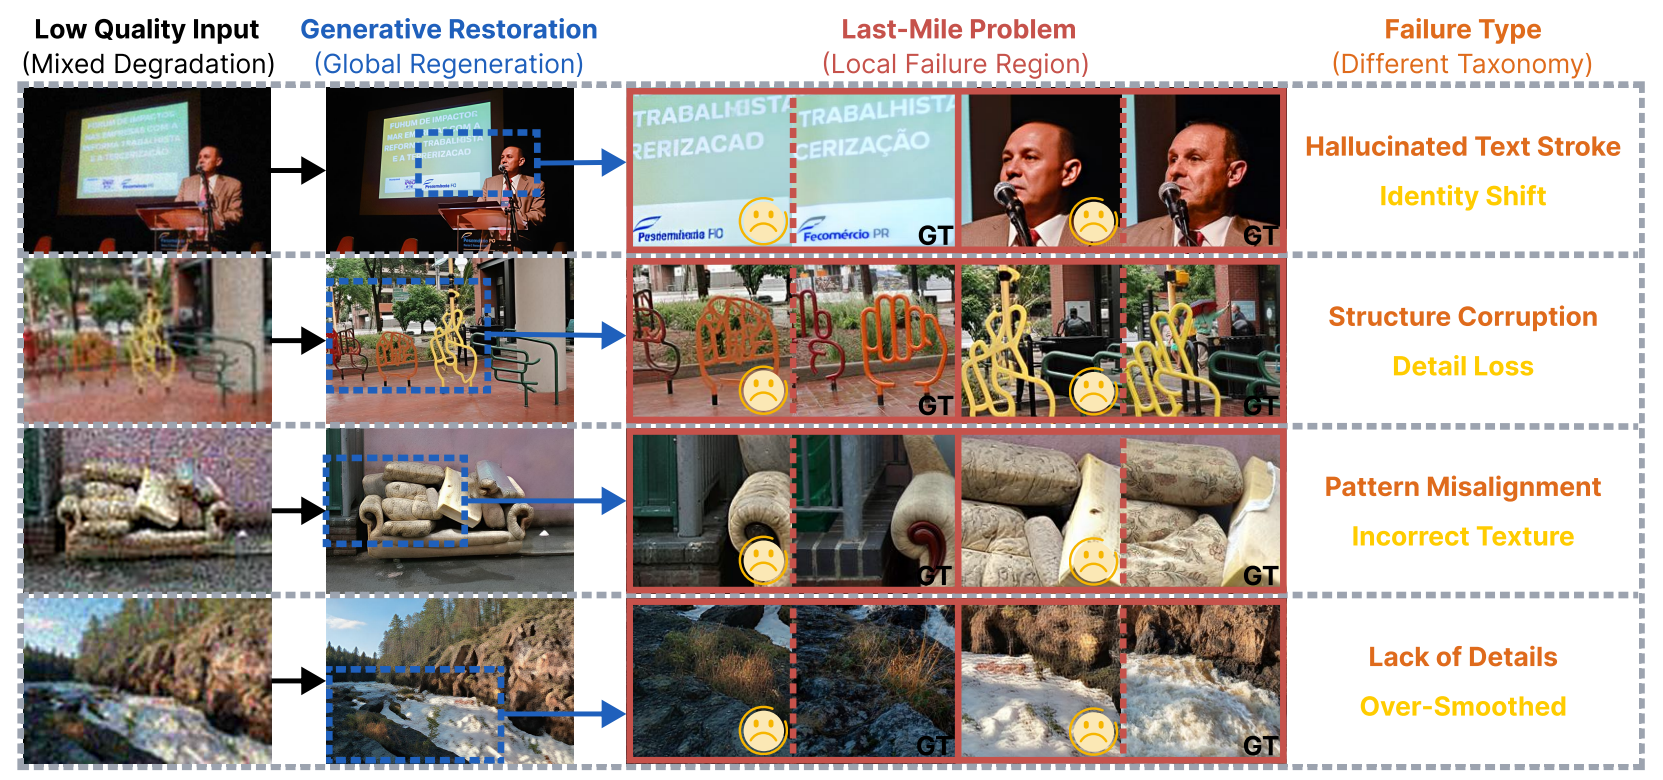
300 dpi PNG · 图注 · 源PDF
引言与图1特指全局合理但人脸、文字、纹理等局部失真的失败类型,引出最后一公里复原问题;不同于普通结果拼图。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[107, 79, 506, 266],PDF点、左上角原点。
Figure 1: The “last-mile” problem in generative image restoration. State-of-the-art methods (Yu
et al., 2024; Wu et al., 2024b; Lin et al., 2025) produce globally plausible reconstructions from
severely degraded inputs, yet localized failures persist. Despite their small spatial extent, these
failures dominate perceived quality and practical acceptability.
GGT-100K: Generative Ground Truth for Generalizable Real-World Image Restoration
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 3 · PDF第4页 · ICLR27_1n4L8nXB1I_F
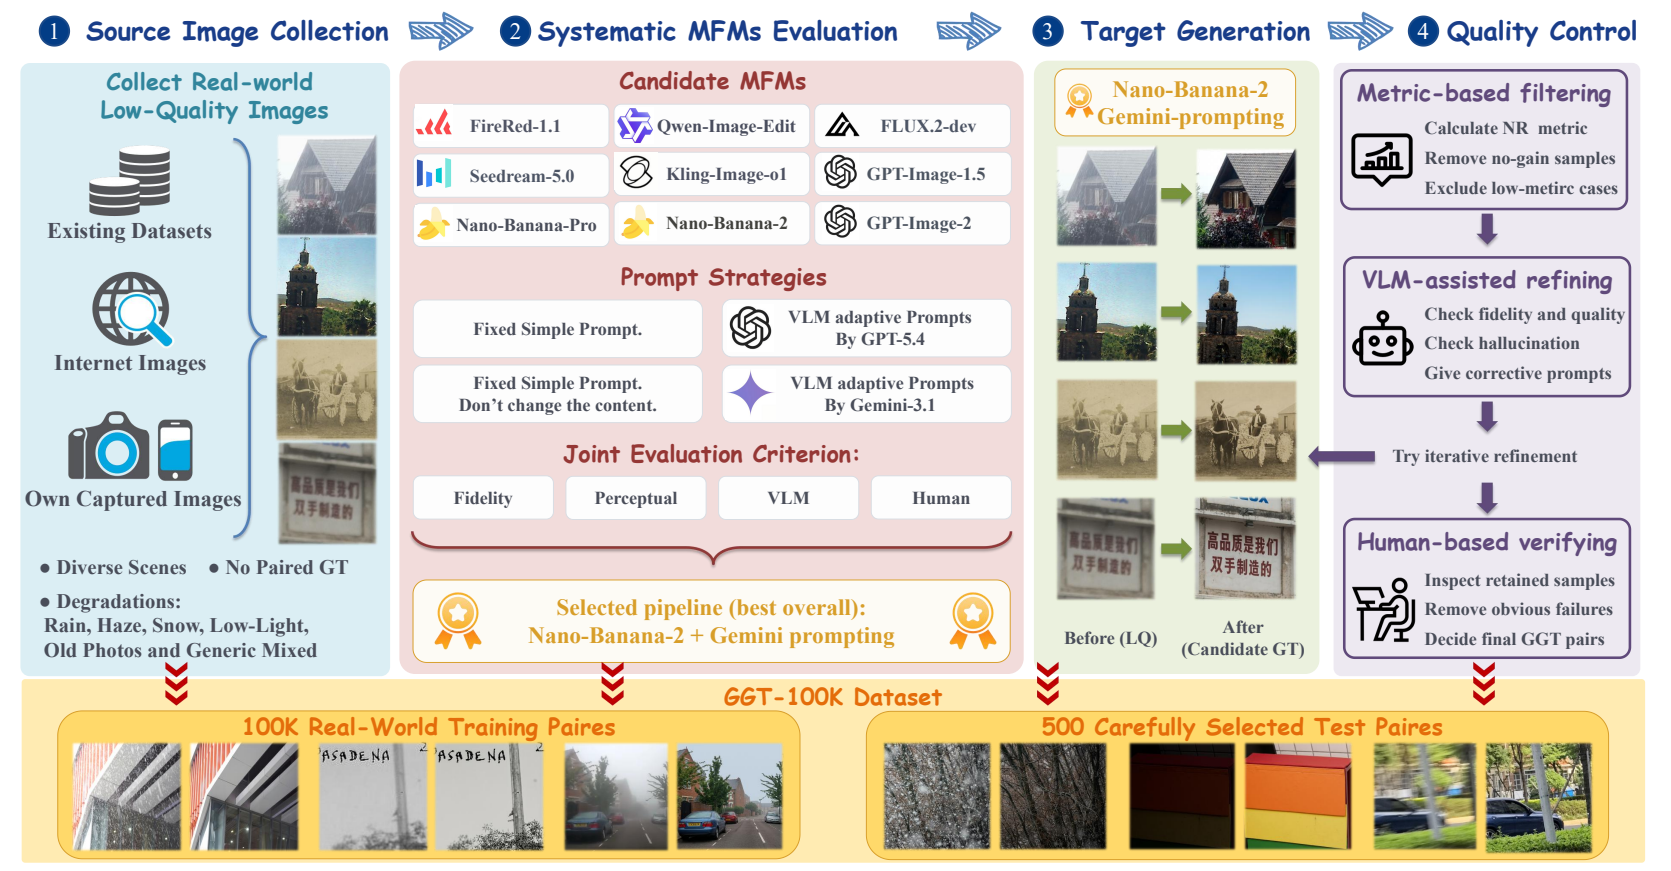
300 dpi PNG · 图注 · 源PDF
正文3节及图3图注均明确为GGT-100K完整数据构建流程,涵盖采集、模型评估、生成及质量控制。
完整图注、版本和筛选证据
最早核实视觉日期:2026-05-29;arXiv v1:2026-05-29;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
v1匹配
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。生成式图像模型用于数据集目标图生成,属于研究方法;不等同于M/F示意图绘制工具。
裁剪坐标:[106, 80, 507, 289],PDF点、左上角原点。
Figure 3: Overview of the GGT-100K construction pipeline. We collect diverse real-world LQ images,
evaluate MFMs for HQ target generation, and apply multi-stage quality control to build the dataset.
GGT-100K: Generative Ground Truth for Generalizable Real-World Image Restoration
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第2页 · ICLR27_1n4L8nXB1I_M
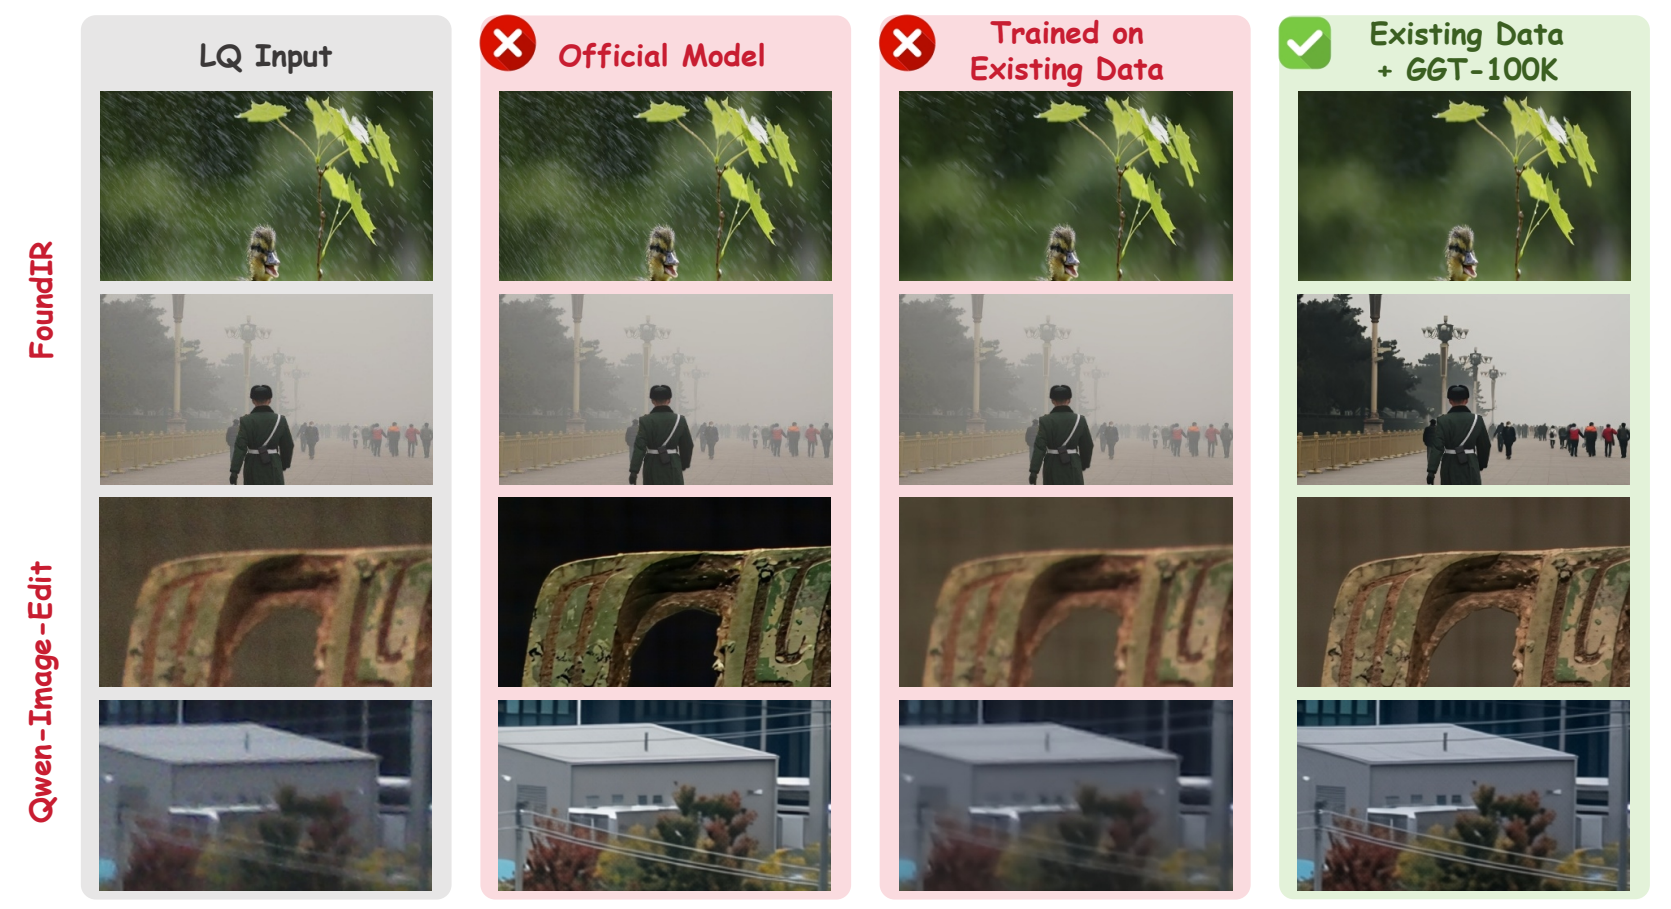
300 dpi PNG · 图注 · 源PDF
引言图2具体展示现有复原数据无法解决的真实雨雾、幻觉与色偏失败,正文据此提出数据缺口。
完整图注、版本和筛选证据
最早核实视觉日期:2026-05-29;arXiv v1:2026-05-29;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
v1匹配
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。生成式图像模型用于数据集目标图生成,属于研究方法;不等同于M/F示意图绘制工具。
裁剪坐标:[106, 80, 507, 298],PDF点、左上角原点。
Figure 2: Qualitative comparison of FoundIR (Li et al., 2025) and Qwen-Image-Edit (Wu et al., 2025)
trained/finetuned on different datasets. FoundIR shows limited generalization to real rain and haze,
even after finetuned on existing restoration datasets. Qwen-Image-Edit produces sharper details with
its strong generative prior but may introduce hallucinations or color shifts, while finetuning on existing
datasets weakens its detail generation ability. GGT-100K significantly improves the generalization
capability of them to real-world degradations, enhancing visual details while preserving scene fidelity.
HarnessIR: Harnessing Multimodal Foundation Models for Universal Real-World Image Restoration
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页 · ICLR27_QlpWNkJcBr_F
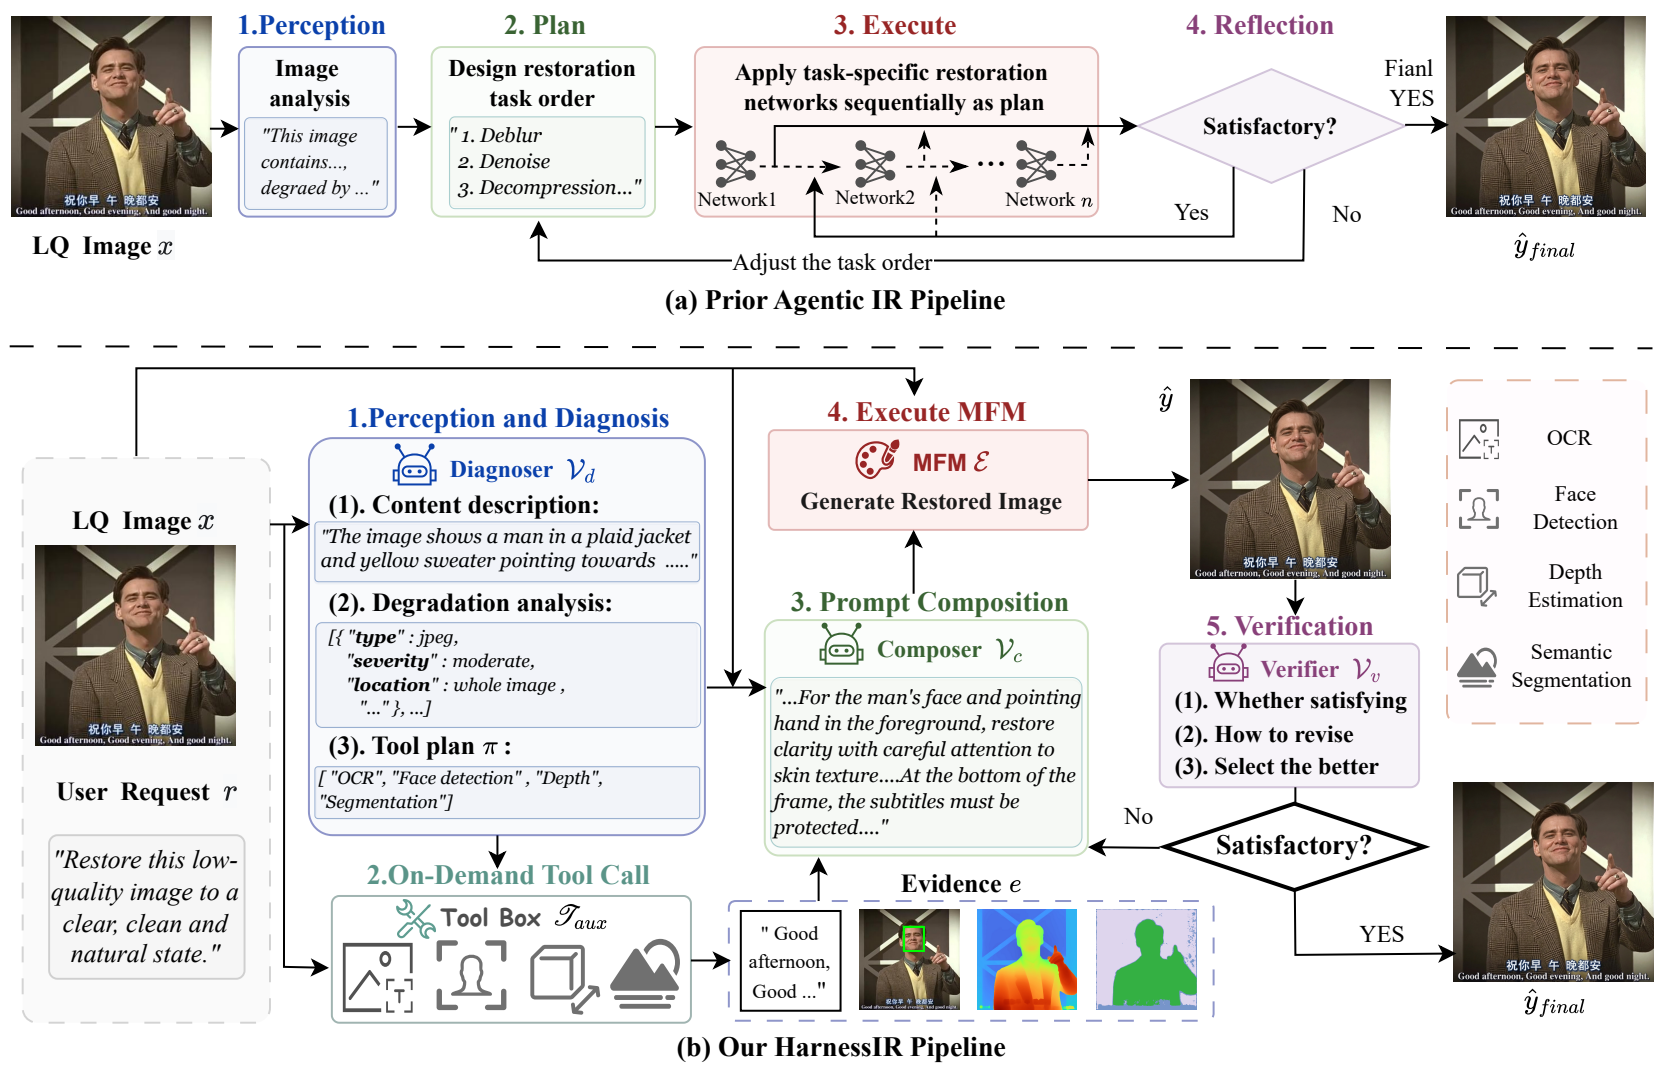
300 dpi PNG · 图注 · 源PDF
图2完整展示HarnessIR的诊断、工具调用、提示组合、生成及验证回路,正文3.1引用为总体框架。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-10-07;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
固定OpenReview投稿PDF于10月3日公开;匹配的arXiv v1较后,不用于提前该视觉版本日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。生成式模型是复原执行器,属于研究方法;不能由此推断M/F框图制作工具。
裁剪坐标:[106, 79, 507, 335],PDF点、左上角原点。
Figure 2: Comparison between (a) prior agentic IR pipelines (top) and (b) HarnessIR (bottom).
Prior methods sequentially apply task-specific restoration models planned by VLMs to produce the
output. HarnessIR instead uses auxiliary tools for image-specific evidence, composes a restoration
instruction for MFM, and invokes verification-driven re-execution when necessary.
HarnessIR: Harnessing Multimodal Foundation Models for Universal Real-World Image Restoration
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 3 · PDF第6页 · ICLR27_QlpWNkJcBr_M
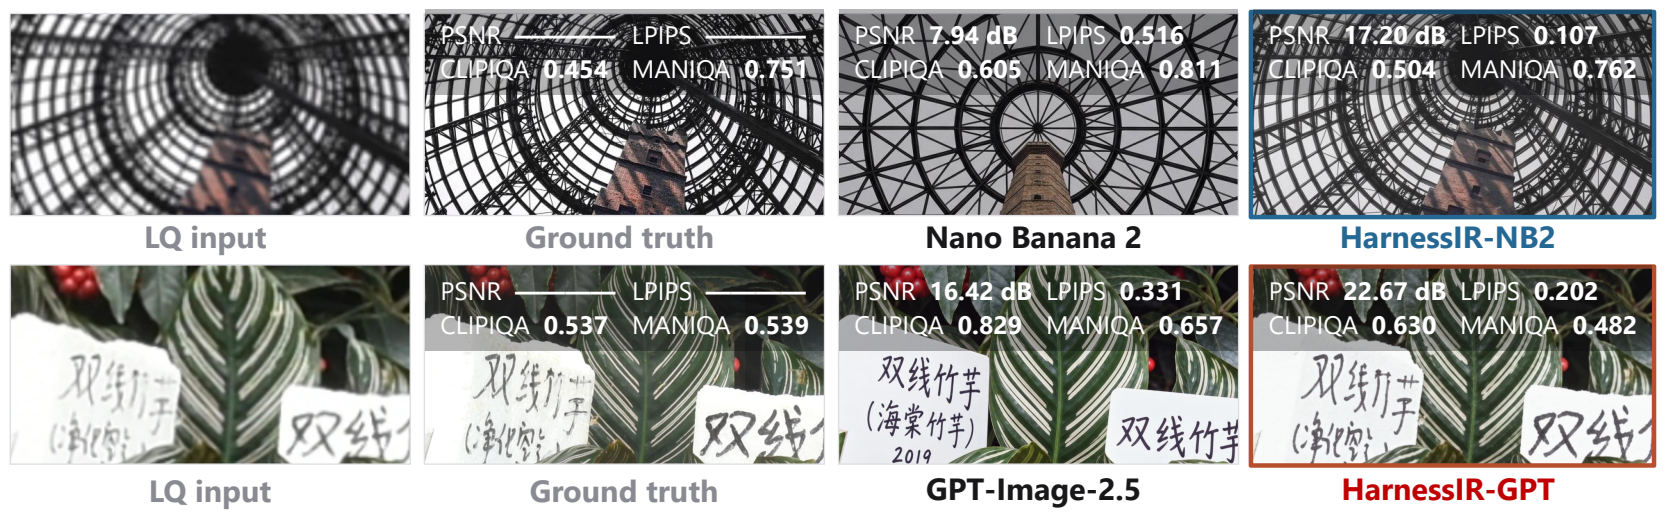
300 dpi PNG · 图注 · 源PDF
图3及实验设置段落用内容被改写却获得更高无参考分数的反例,说明NR-IQA单独评价的局限。图1含普通结果与雷达图不选为M。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-10-07;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
固定OpenReview投稿PDF于10月3日公开;匹配的arXiv v1较后,不用于提前该视觉版本日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lei Zhang;137335;快照2026-10-21。
绘图工具:unknown。生成式模型是复原执行器,属于研究方法;不能由此推断M/F框图制作工具。
裁剪坐标:[106, 80, 507, 205],PDF点、左上角原点。
Figure 3: Direct use of MFMs may yield higher NR-IQA scores than GT, even when the image
content is largely altered. NR-IQA should not be used as an independent metric for IR performance.
Learning to Restore More: Continual Capability Expansion for Pretrained Image Restoration Models
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第5页 · ICLR27_Cdx9a9GdBy_F
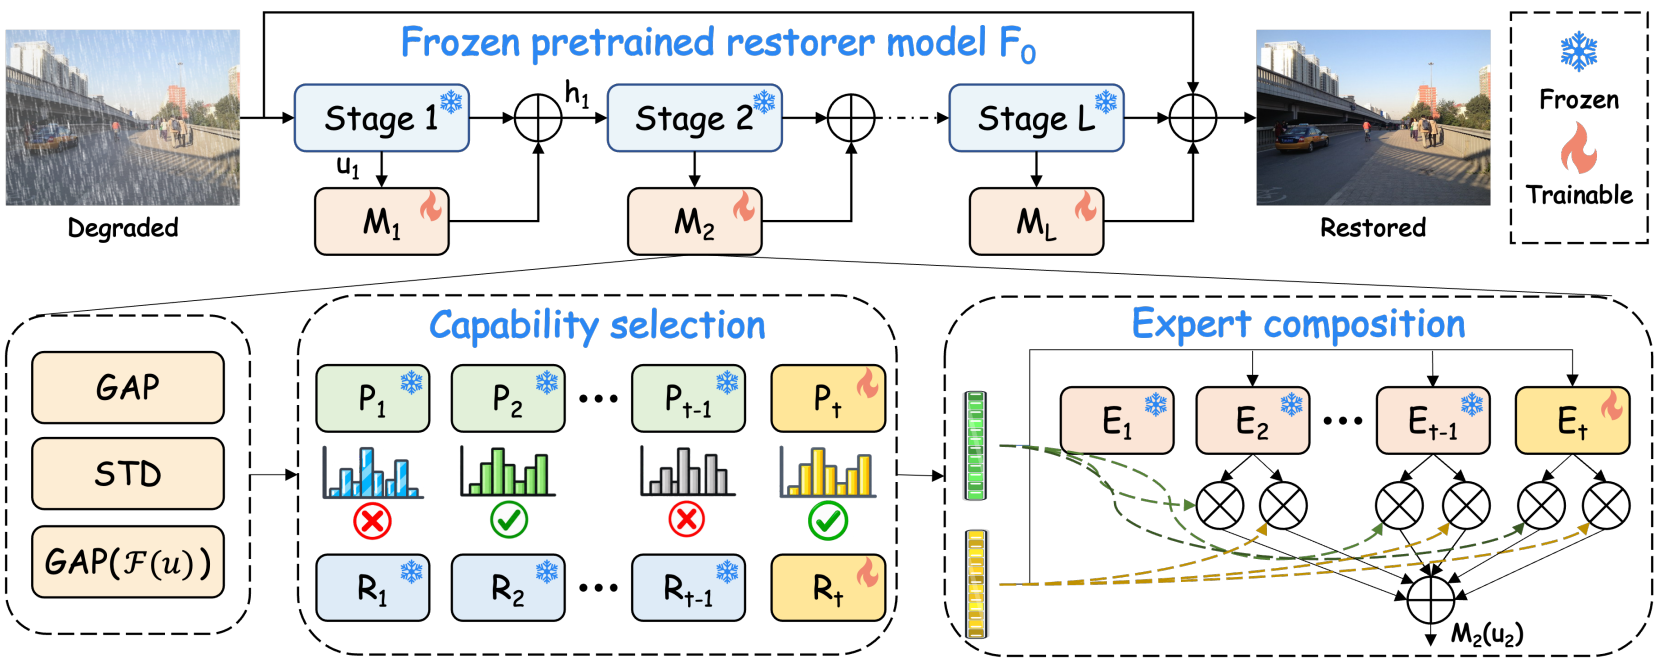
300 dpi PNG · 图注 · 源PDF
3.2节与图2明确给出整体框架,含冻结复原骨干、残差扩展模块、两级路由与专家库的完整计算路径。
完整图注、版本和筛选证据
最早核实视觉日期:2026-08-31;arXiv v1:2026-08-31;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
v1冻结骨干、能力路由与专家组合的图形元素和连接匹配
历史PDF · 引用证据 · 公开日期 · 论文入口
作者引用:Lizhuang Ma;13785;快照2026-10-28。
绘图工具:unknown。作者声明生成式AI协助Fig.5;本库所选为Fig.1和Fig.2,未将Fig.5披露推及M/F。
裁剪坐标:[107, 80, 505, 241],PDF点、左上角原点。
Figure 2: Overview of the proposed RestoreMore framework. A pretrained restoration model is
preserved as a frozen capability anchor, and lightweight residual expansion modules are inserted at
selected feature stages. Inside each expansion module, a degradation descriptor is first constructed
from spatial and frequency statistics. Top-M capability selection is then performed over accumu-
lated capability prototypes and routers. The selected routers further retrieve complementary experts
from the expert-key bank through query–key matching. Frozen historical components and trainable
current-task components are indicated by snowflake and flame icons, respectively.
Learning to Restore More: Continual Capability Expansion for Pretrained Image Restoration Models
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_Cdx9a9GdBy_M
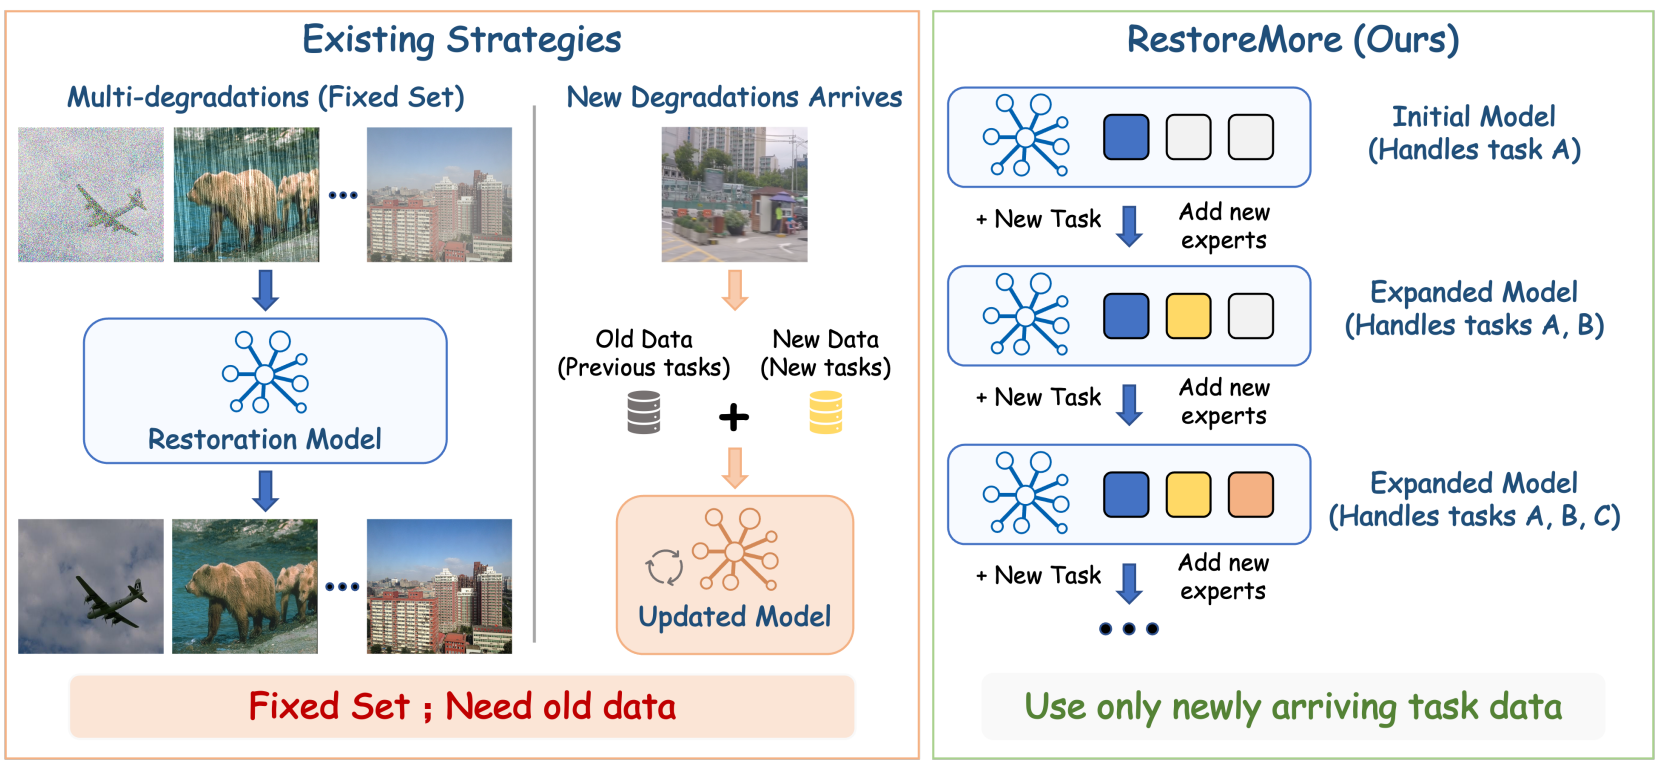
300 dpi PNG · 图注 · 源PDF
引言及图1对比固定退化能力、联合重训练与持续扩展,说明新退化到达时需要避免遗忘与历史数据重放的问题。
完整图注、版本和筛选证据
最早核实视觉日期:2026-08-31;arXiv v1:2026-08-31;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
v1固定集合与持续扩展对照的布局、图片及配色匹配
历史PDF · 引用证据 · 公开日期 · 论文入口
作者引用:Lizhuang Ma;13785;快照2026-10-28。
绘图工具:unknown。作者声明生成式AI协助Fig.5;本库所选为Fig.1和Fig.2,未将Fig.5披露推及M/F。
裁剪坐标:[107, 80, 505, 264],PDF点、左上角原点。
Figure 1: Comparison of existing restoration strategies and RestoreMore. Existing methods are
limited to a fixed degradation set and typically require joint retraining with historical and new data
when new degradations arrive. In contrast, RestoreMore continually expands a pretrained restorer
by adding new experts using only newly arriving task data.
Look Before You Restore: Learning to Predict Before Acting for Agentic Image Restoration
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页 · ICLR27_rCgxaWvBRj_F
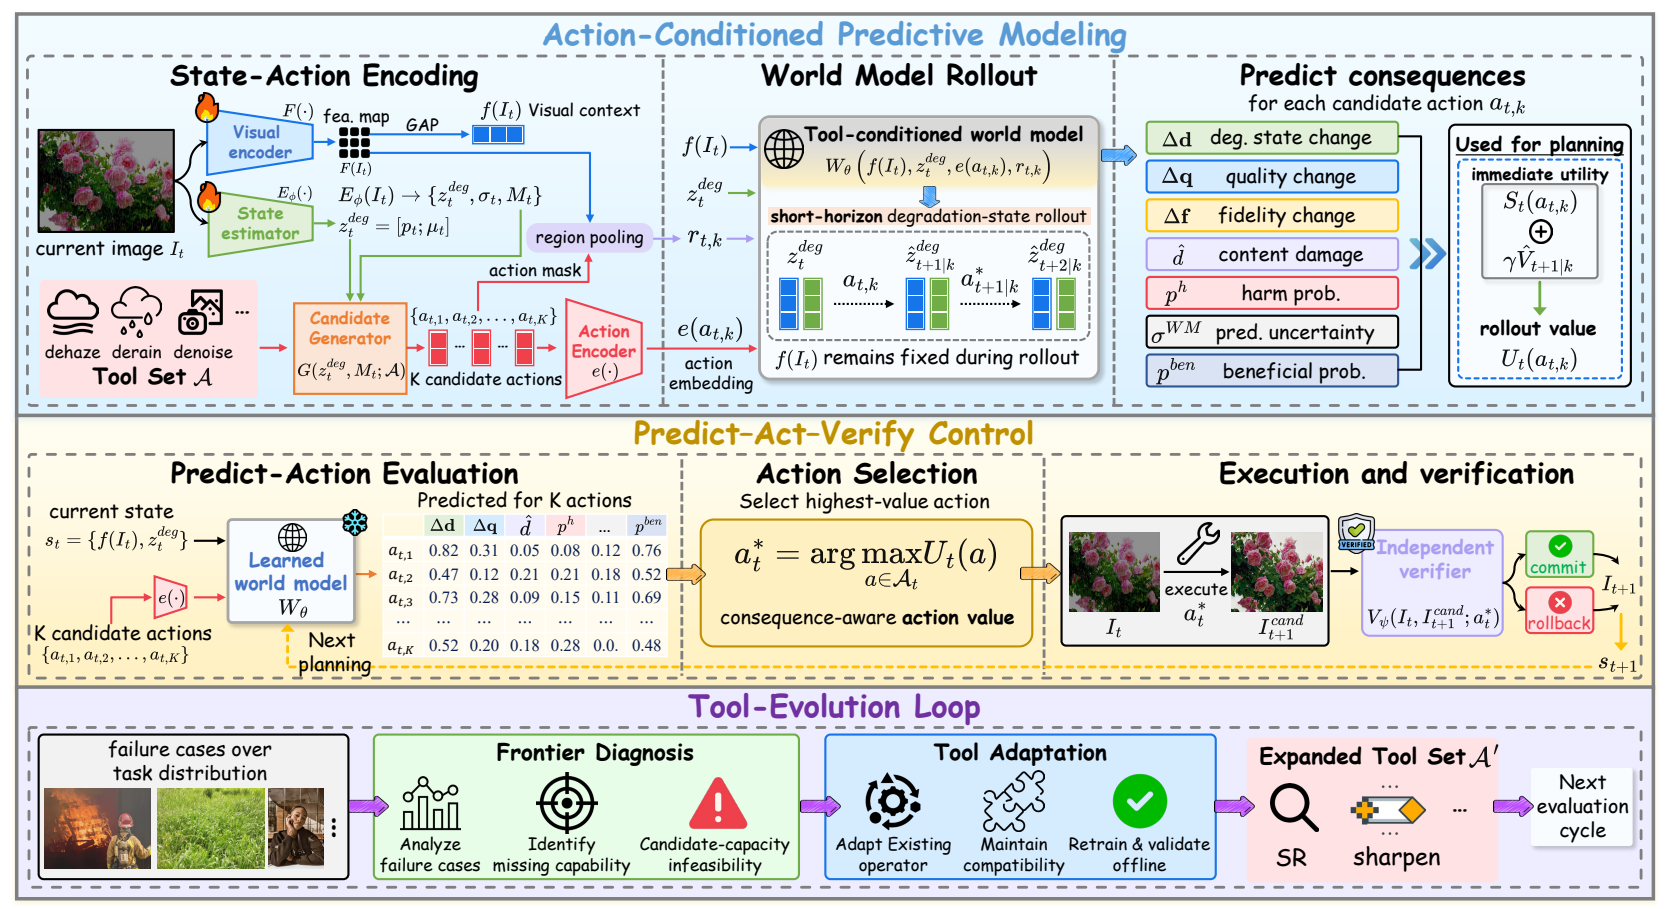
300 dpi PNG · 图注 · 源PDF
图2为PreActIR整体框架,包含世界模型、predict-act-verify控制及工具扩展回路。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-10-14;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
固定OpenReview投稿PDF于10月3日公开;匹配的arXiv v1较后,不用于提前该视觉版本日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lefei Zhang;18509;快照2026-10-21。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 80, 507, 298],PDF点、左上角原点。
Figure 2: Overview of PreActIR. The world model predicts action consequences before execution,
while the predict–act–verify controller executes and verifies the selected action with commit or
rollback. A tool-evolution loop performs candidate-frontier audit and targeted tool adaptation.
Look Before You Restore: Learning to Predict Before Acting for Agentic Image Restoration
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_rCgxaWvBRj_M
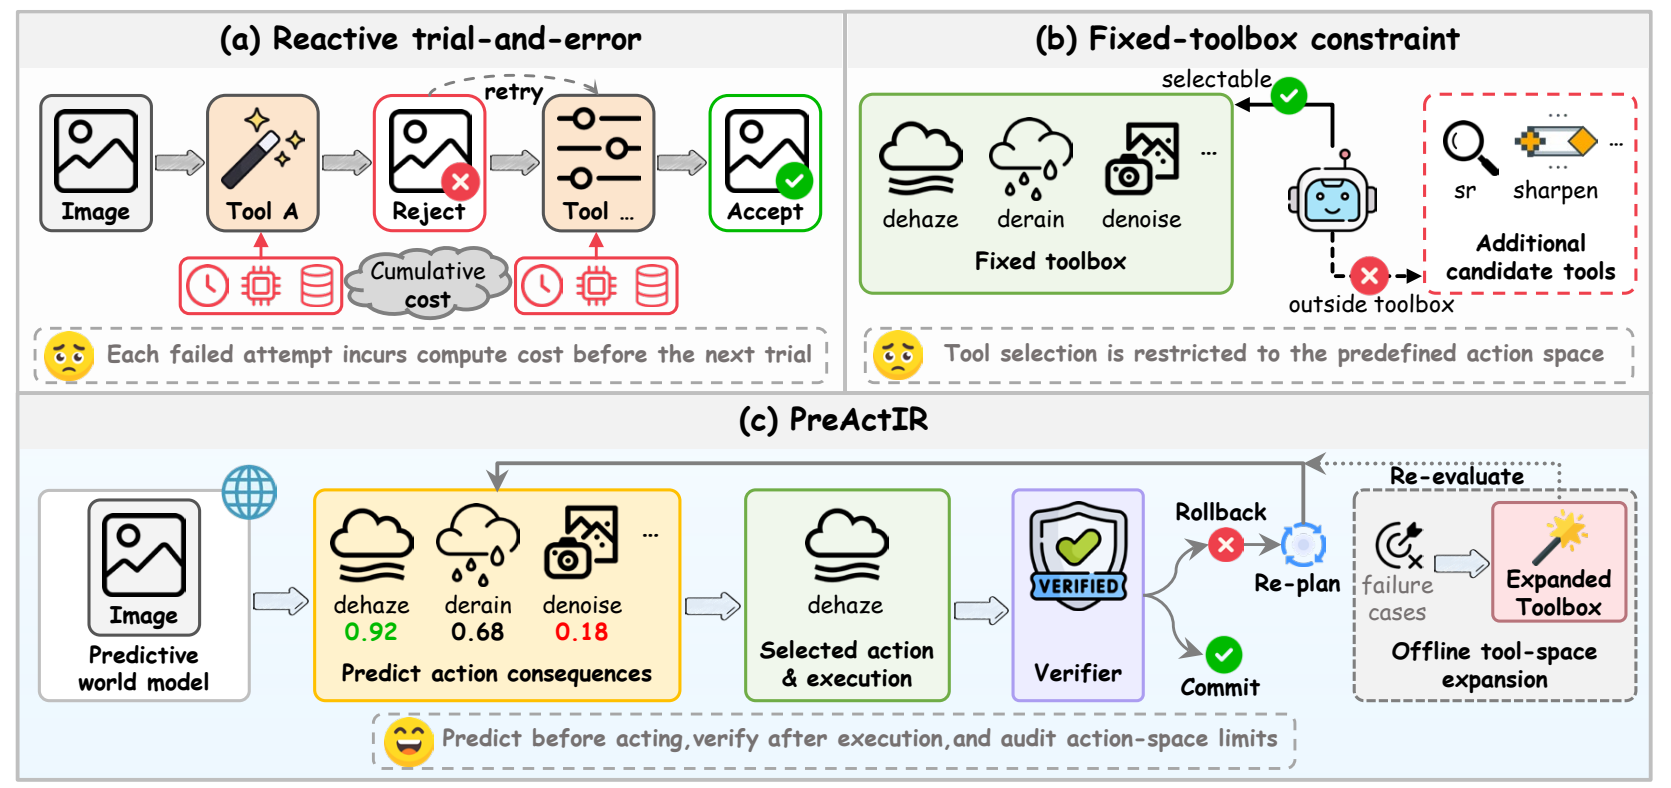
300 dpi PNG · 图注 · 源PDF
图1明确为动机图,对比先执行后观察造成的试错成本和固定工具箱限制,与预测行动后果的思路。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-10-14;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
固定OpenReview投稿PDF于10月3日公开;匹配的arXiv v1较后,不用于提前该视觉版本日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Lefei Zhang;18509;快照2026-10-21。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 81, 507, 270],PDF点、左上角原点。
Figure 1: Motivation of PreActIR. Existing agentic restoration is largely reactive: tool effects are
observed only after execution, while decisions remain restricted to the available action space. Pre-
ActIR predicts action consequences before execution.
PhoenixSR: Generative Heterogeneous Distillation Unleashes Efficient Models for Real-World Super-Resolution
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 4 · PDF第5页 · ICLR27_anN7bIopnC_F
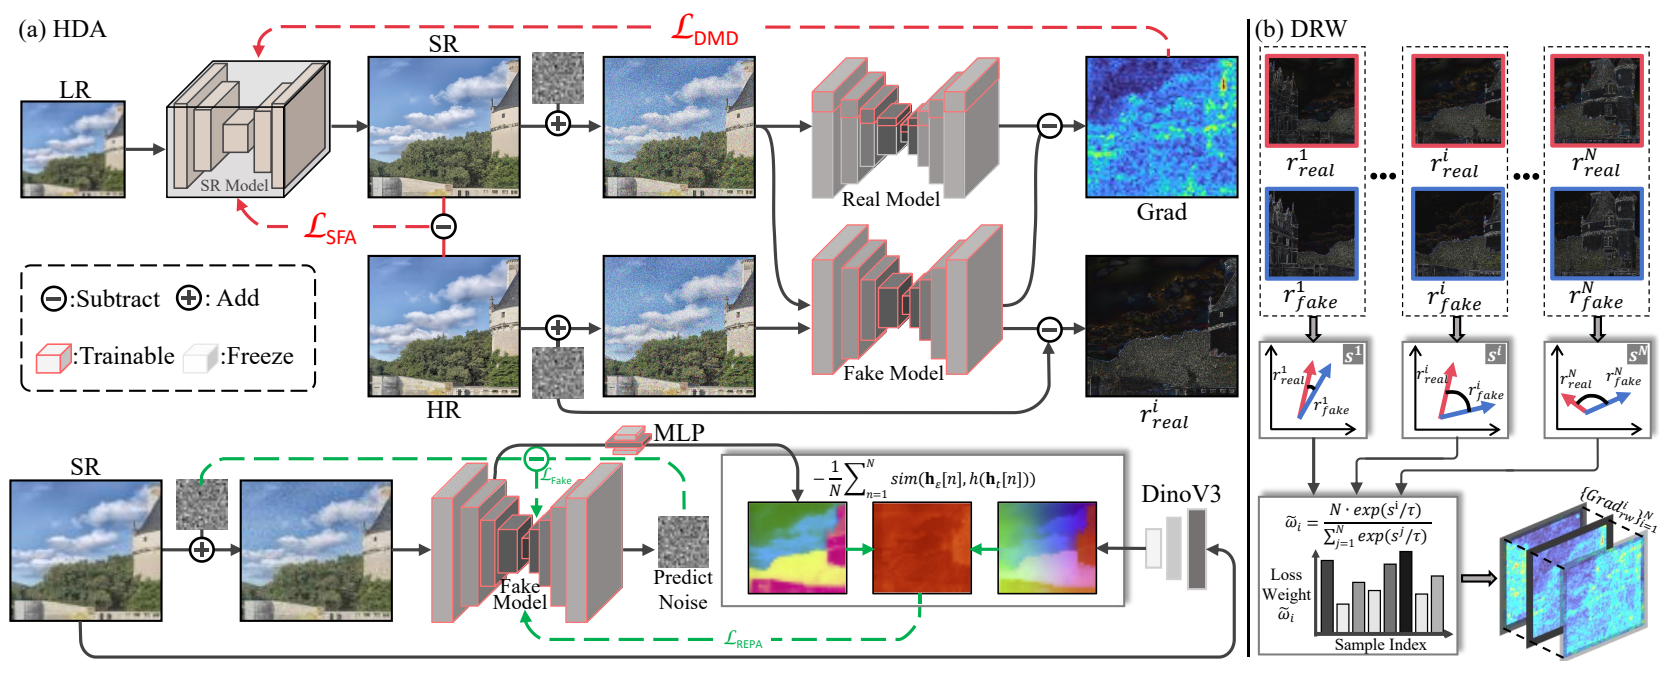
300 dpi PNG · 图注 · 源PDF
图4为PhoenixSR整体蒸馏框架,涵盖真实与伪分数、保真锚定及样本重加权关系。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-09-25;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
与9月v1相比模型堆叠、标注、连接表现有调整,保守使用投稿公开日期
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Zheng-Jun Zha;30479;快照2026-10-21。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 241],PDF点、左上角原点。
Figure 4: Overview of PhoenixSR. HDA adapts real-score estimation, tracks the evolving student
distribution, and anchors paired fidelity. DRW reweights sample-wise guidance according to residual-
direction consistency.
PhoenixSR: Generative Heterogeneous Distillation Unleashes Efficient Models for Real-World Super-Resolution
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第2页 · ICLR27_anN7bIopnC_M
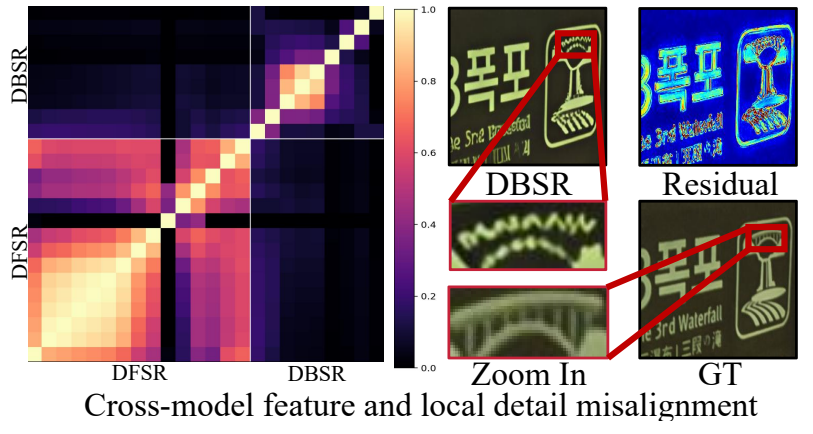
300 dpi PNG · 图注 · 源PDF
引言图2明确以CKA弱特征对应和残差/细节不匹配,解释异构蒸馏直接对齐的困难。图1混合产出与性能不选。
完整图注、版本和筛选证据
最早核实视觉日期:2026-09-25;arXiv v1:2026-09-25;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
v1特征热图及局部失配示例匹配
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Zheng-Jun Zha;30479;快照2026-10-21。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[312, 460, 507, 564],PDF点、左上角原点。
Figure 2: Motivation. CKA (Kornblith et al.,
2019) (left) reveals weak feature correspondence
between DBSR and DFSR, while residual and
zoom-in comparisons (right) show local discrep-
ancies between DBSR outputs and paired HR
targets.
Restoring without Forgetting: Filter-Level Continual Image Restoration via Parameter-Space Integrated Gradients
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第3页 · ICLR27_80XJOuh0nO_F
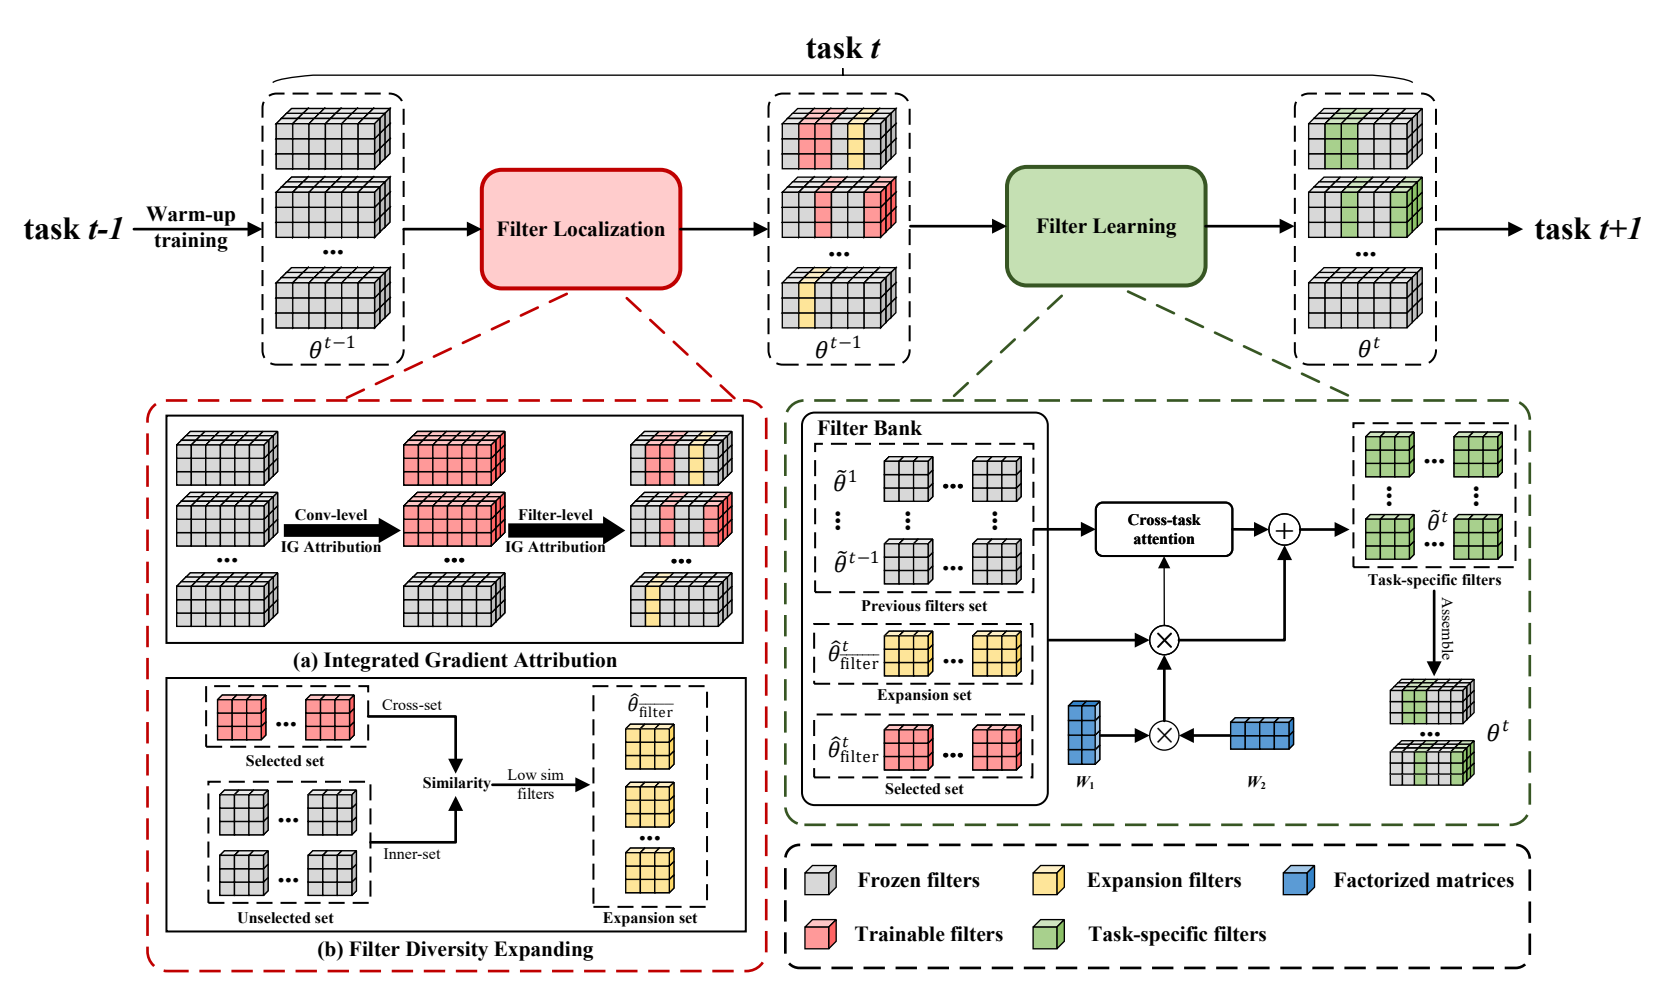
300 dpi PNG · 图注 · 源PDF
图2为RwF总体流程,显示滤波器定位、扩展、生成与回装到冻结主干的全过程。
完整图注、版本和筛选证据
最早核实视觉日期:2026-09-29;arXiv v1:2026-09-29;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
v1匹配
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Guangming Lu;13904;快照2026-10-21。
绘图工具:unknown; authors_deny_generative_AI_figures。作者明确否认使用生成式AI制作图;实际绘图软件未披露。
裁剪坐标:[106, 45, 507, 281],PDF点、左上角原点。
Figure 2: Overview of RwF. Filter localization (left): parameter-space integrated gradients rank
layers, then filters within them, and the selected set is expanded with high-IG, low-similarity filters.
Filter learning (right): the localized filters are regenerated from a filter bank by factorized matrices
with cross-task attention and assembled back into the frozen backbone.
Restoring without Forgetting: Filter-Level Continual Image Restoration via Parameter-Space Integrated Gradients
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_80XJOuh0nO_M
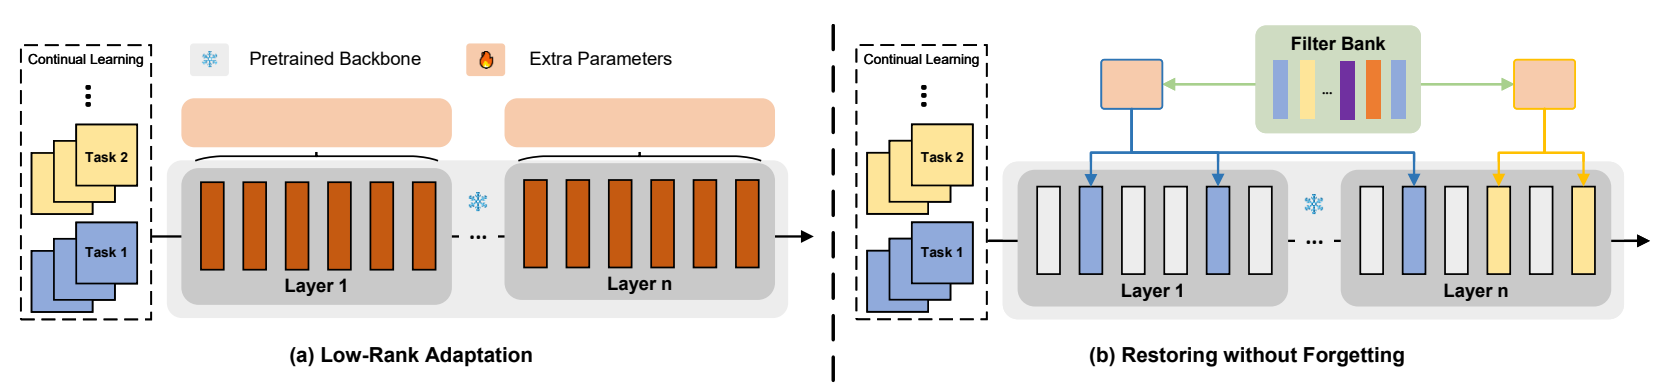
300 dpi PNG · 图注 · 源PDF
引言图1对比LoRA全层更新与局部退化关键滤波器更新,以概念对比引出遗忘与参数干扰问题。
完整图注、版本和筛选证据
最早核实视觉日期:2026-09-29;arXiv v1:2026-09-29;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
v1匹配
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Guangming Lu;13904;快照2026-10-21。
绘图工具:unknown; authors_deny_generative_AI_figures。作者明确否认使用生成式AI制作图;实际绘图软件未披露。
裁剪坐标:[106, 60, 507, 152],PDF点、左上角原点。
Figure 1: (a) LoRA updates every filter of each adapted layer through low-rank matrices. (b) RwF
localizes the few degradation-critical filters of each task and regenerates only them from a shared
filter bank, leaving the rest of the backbone frozen.
SegDem: Segmentation helps Demosaicing
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第3页 · ICLR27_3Kt188v0Yl_F
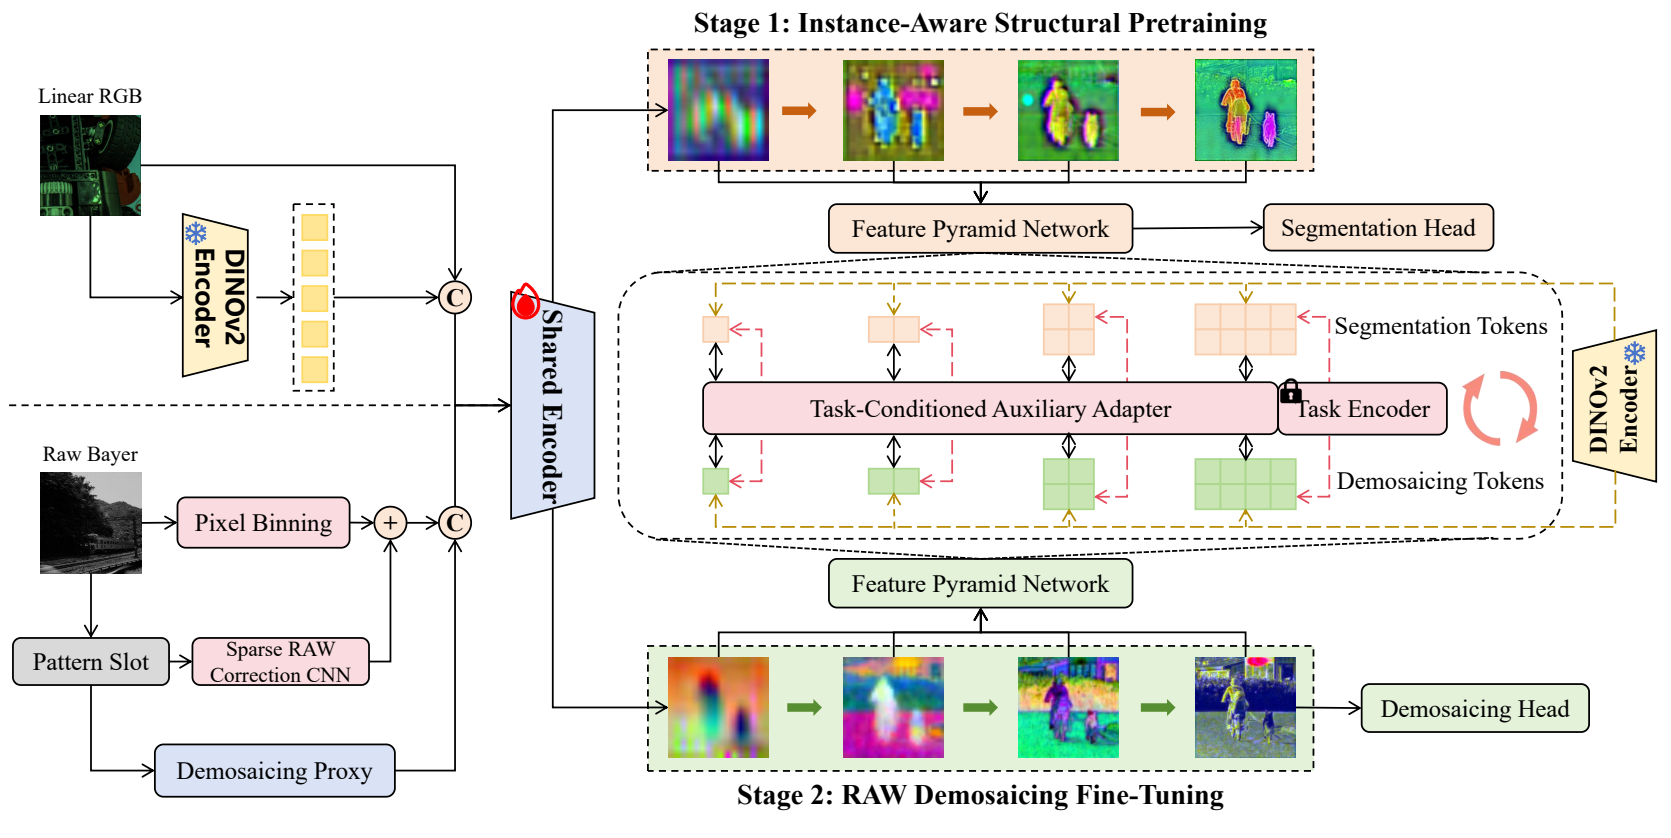
300 dpi PNG · 图注 · 源PDF
图2展示结构预训练到RAW去马赛克微调的双阶段整体流程,包含编码解码、条件与监督关系。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-08-08;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
相较8月v1新增线性RGB到结构预训练的连线等变化
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Kai Zhang;48468;快照2026-10-21。
绘图工具:generative_AI_figures_reported; selected_MF_tool_unknown。作者声明创建/修改科学图或图像,并提到GPT-Image2用于demosaicing视觉对比效果;无法将这项披露直接归到所选M/F两图。
裁剪坐标:[106, 79, 507, 280],PDF点、左上角原点。
Figure 2: Overview of SegDem. Stage 1 learns region- and boundary-aware representations using a
clean linear-RGB image state while retaining the mosaicked observation as an auxiliary RAW con-
dition. Stage 2 transfers the pretrained decoder parameters to demosaicing, while task-conditioned
auxiliary features and training-only DINOv2 alignment provide structural supervision without alter-
ing the sensor-conditioned output pathway.
SegDem: Segmentation helps Demosaicing
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第1页 · ICLR27_3Kt188v0Yl_M
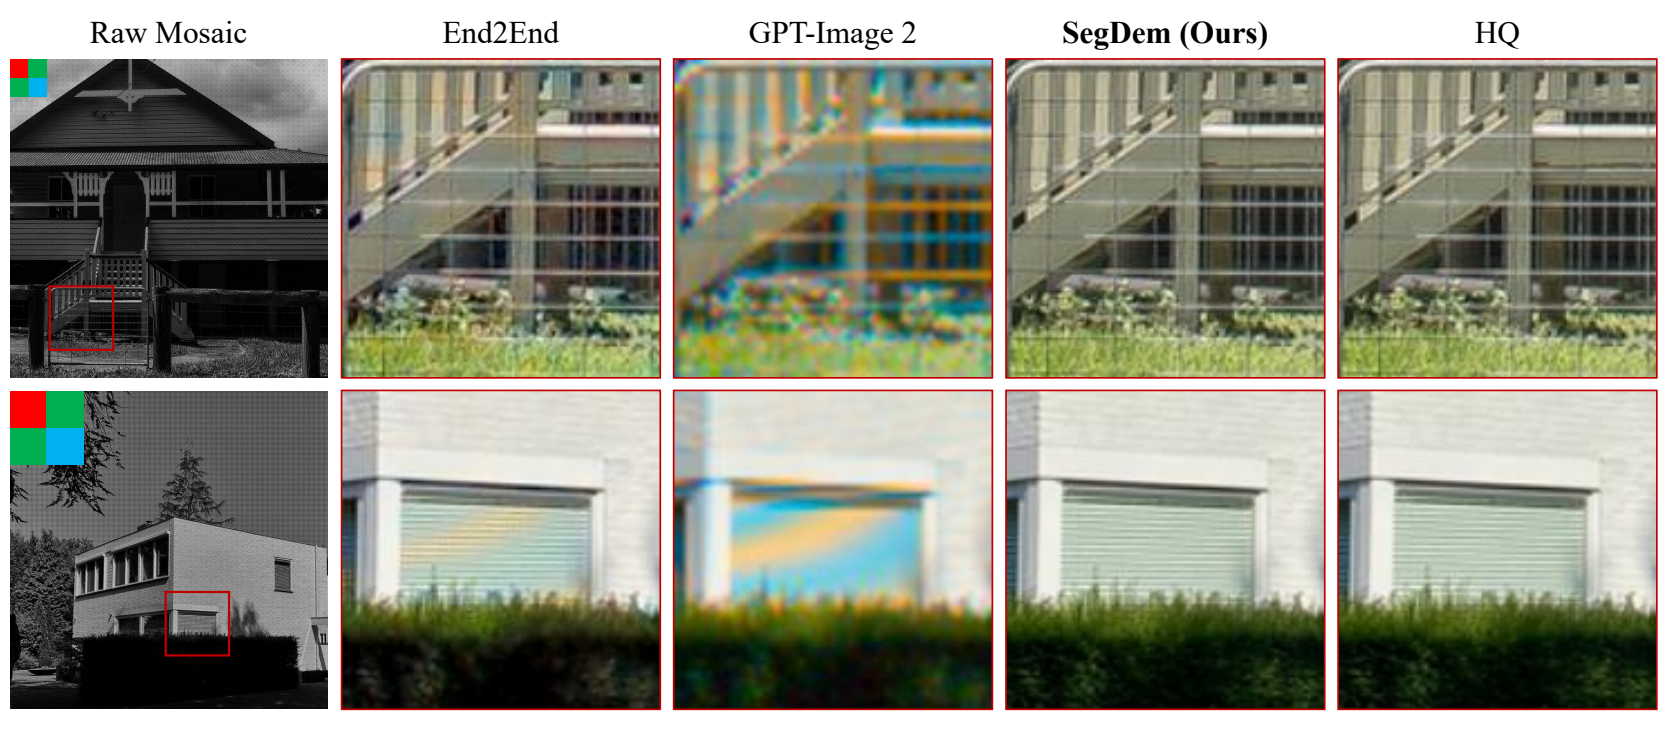
300 dpi PNG · 图注 · 源PDF
图1及引言展示回归模型伪色与生成模型无RAW依据的幻觉,借具体失败说明结构表征迁移的动机。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-08-08;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
相较8月v1新增RAW色块标识等视觉元素
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Kai Zhang;48468;快照2026-10-21。
绘图工具:generative_AI_figures_reported; selected_MF_tool_unknown。作者声明创建/修改科学图或图像,并提到GPT-Image2用于demosaicing视觉对比效果;无法将这项披露直接归到所选M/F两图。
裁剪坐标:[106, 168, 507, 345],PDF点、左上角原点。
Figure 1: Motivation of SegDem. Conventional regression is prone to false colors and moire´ arti-
facts in ambiguous regions, while generative models may hallucinate details unsupported by RAW
measurements. SegDem instead transfers structural decoder representations from segmentation to
demosaicing, improving boundary-aware reconstruction.
ARROW: Arbitrary Reconstruction and Tracking of 4D Observations in the Wild
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 3 · PDF第4页 · ICLR27_hShILxckIE_F
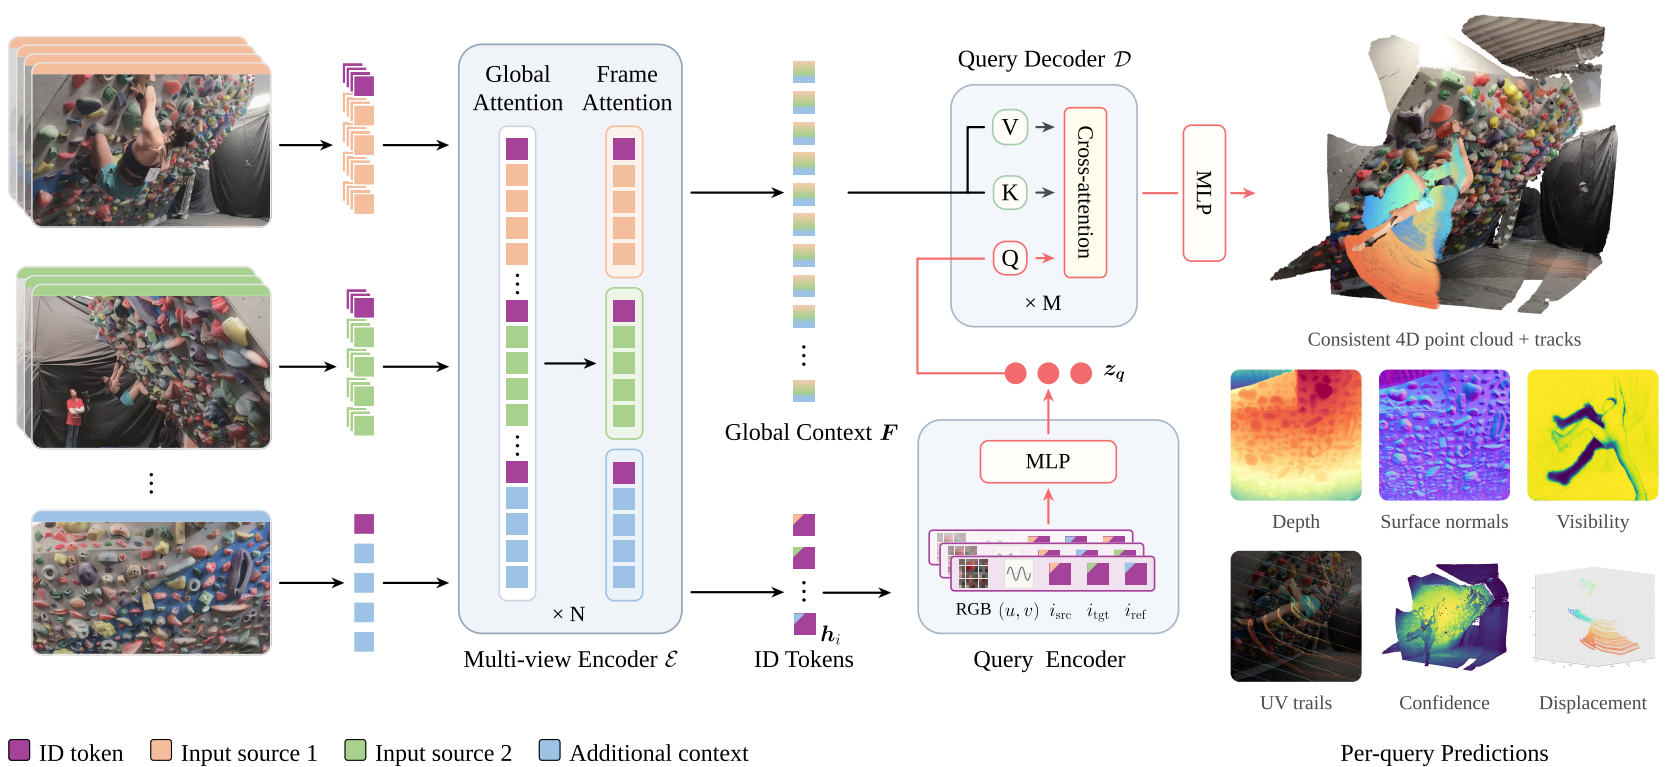
300 dpi PNG · 图注 · 源PDF
图3和方法节展示ARROW多视图编码、全局上下文、查询编码解码及四维预测完整路径。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-01;arXiv v1:2026-10-01;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
v1编码器-查询解码器-输出构图匹配
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Bastian Leibe;44197;快照2026-10-21。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 263],PDF点、左上角原点。
Figure 3: ARROW architecture. The multi-view encoder E tokenizes each frame independently
and employs global attention to produce a shared global context F together with an ID token h for
i
each frame. The query encoder combines a source-centered RGB crop, the Fourier-encoded (u, v)
coordinate, and the ID tokens of the queried source, target, and reference view frames into a latent
query token z . Each latent query token independently cross-attends to the global context, so a single
q
encoding serves arbitrarily many queries and yields a consistent 4D representation of the scene.
ARROW: Arbitrary Reconstruction and Tracking of 4D Observations in the Wild
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第3页 · ICLR27_hShILxckIE_M
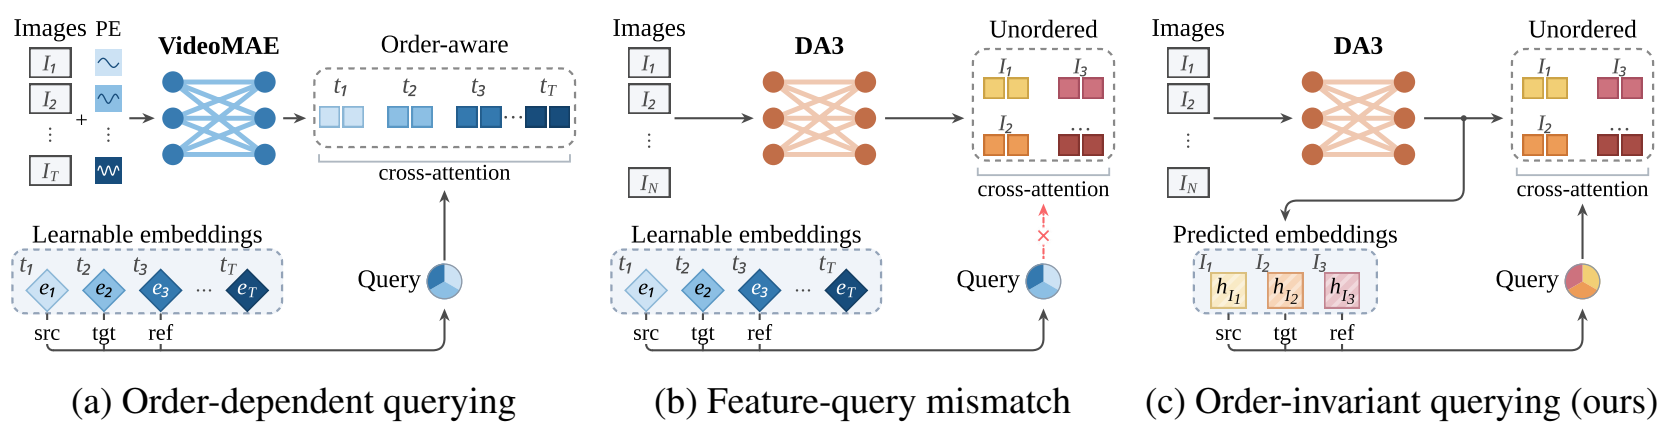
300 dpi PNG · 图注 · 源PDF
图2及引言对比顺序索引、无序上下文失配和内容身份查询,说明固定顺序假设的局限。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-01;arXiv v1:2026-10-01;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
v1三种查询示意构图、色块及连线匹配
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Bastian Leibe;44197;快照2026-10-21。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 181],PDF点、左上角原点。
Figure 2: From indexed to input-dependent correspondence. (a) Order-aware global context
enables position-based associations. (b) Order-invariant global context exposes no fixed order to
exploit. (c) Content-derived identity embeddings enable order-invariant associations.
Drive3R: Block-wise Streaming Geometric Foundation Models for Autonomous Driving
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 3 · PDF第5页 · ICLR27_4hJ82iauw9_F
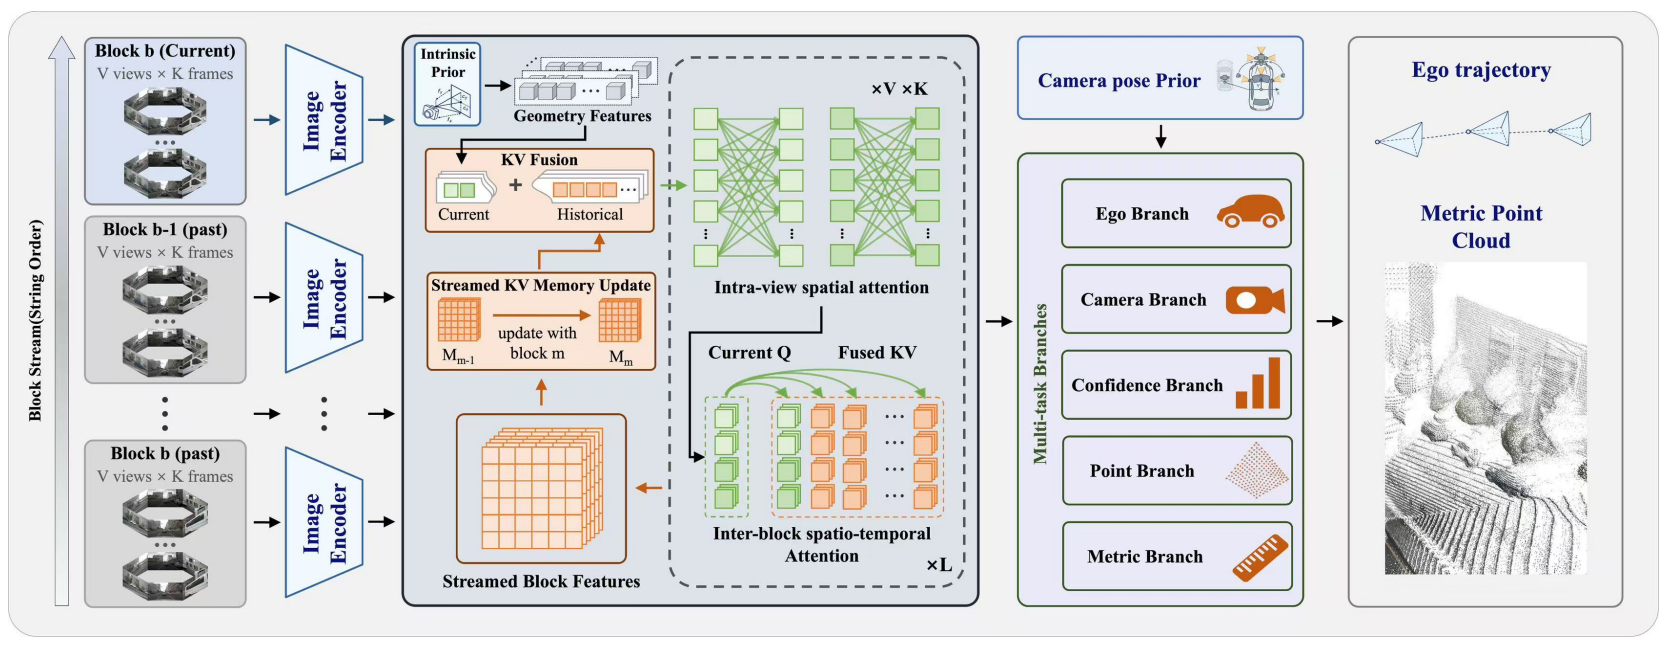
300 dpi PNG · 图注 · 源PDF
图3为Drive3R整体流程,从多视角输入及内参到流式KV记忆、时空解码和运动/几何预测。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-10-10;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
固定OpenReview投稿PDF于10月3日公开;匹配的arXiv v1较后,不用于提前该视觉版本日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Li Jiang;19563;快照2026-10-21。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 235],PDF点、左上角原点。
Figure 3: The pipeline of our method. Multi-view image streams are processed in a block-wise
manner. Each image block is first encoded with intrinsic priors and then processed by a spatio-
temporal decoder. By maintaining a streamed KV memory across consecutive blocks, the model
continuously extracts consistent geometry features for multi-task predictions, including ego-centric
motion and dense metric 3D reconstruction.
Drive3R: Block-wise Streaming Geometric Foundation Models for Autonomous Driving
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第2页 · ICLR27_4hJ82iauw9_M
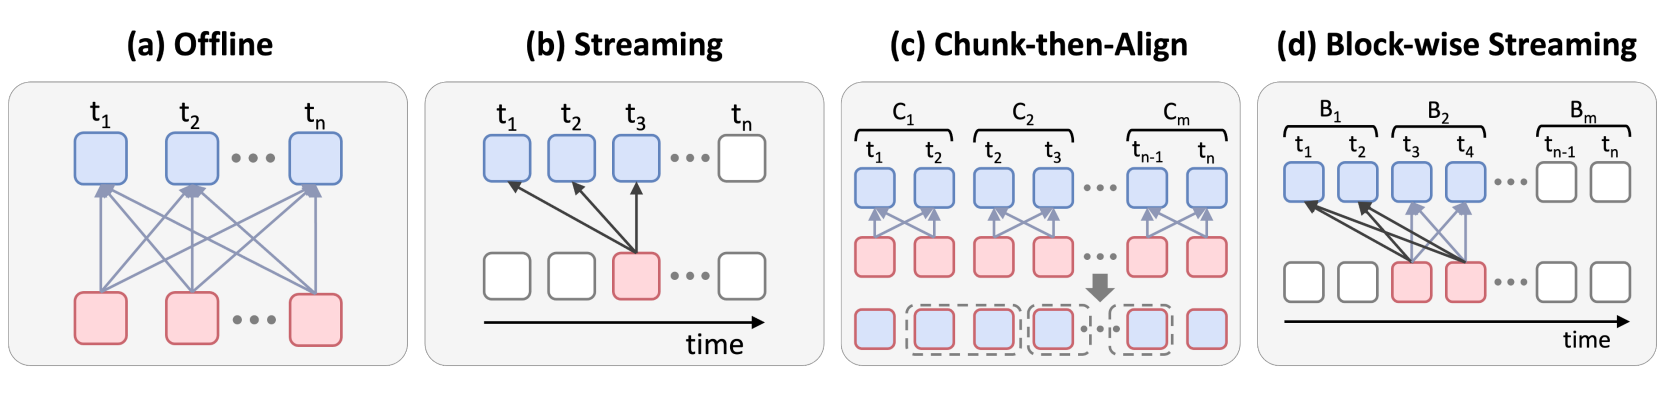
300 dpi PNG · 图注 · 源PDF
引言图2对比离线、逐帧、分块再对齐与块流式范式,用于说明全局注意力成本与跨块漂移的矛盾。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-10-10;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
固定OpenReview投稿PDF于10月3日公开;匹配的arXiv v1较后,不用于提前该视觉版本日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Li Jiang;19563;快照2026-10-21。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 174],PDF点、左上角原点。
Figure 2: Paradigm comparison between previous sequence processing strategies (offline, streaming,
chunk-then-align) and our proposed block-wise streaming approach, Drive3R.
Failure-Aware Adaptation for Transparent Objects in Feed-Forward 3D Reconstruction
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 3 · PDF第5页 · ICLR27_iRCP1uMP8S_F
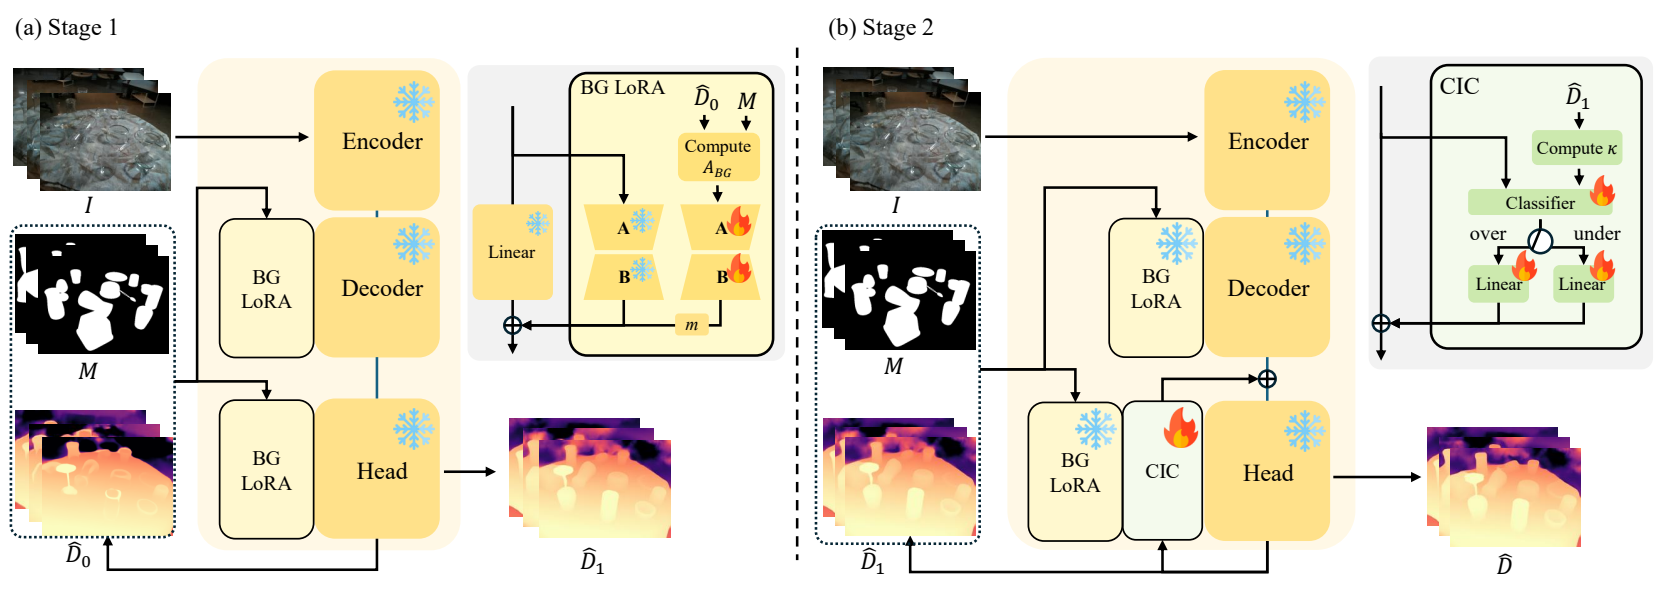
300 dpi PNG · 图注 · 源PDF
图3展示完整两阶段适配:背景感知LoRA及冻结后曲率修正,从输入与掩码到深度输出。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 224],PDF点、左上角原点。
Figure 3: Overview of our two-stage failure-aware adaptation framework. Starting from a
frozen backbone with adapted LoRA parameters, (a) Stage 1 trains Background-aware LoRA to
correct background leakage, and (b) Stage 2 freezes the preceding components and trains CIC to
correct the remaining directional errors.
Failure-Aware Adaptation for Transparent Objects in Feed-Forward 3D Reconstruction
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第1页 · ICLR27_iRCP1uMP8S_M
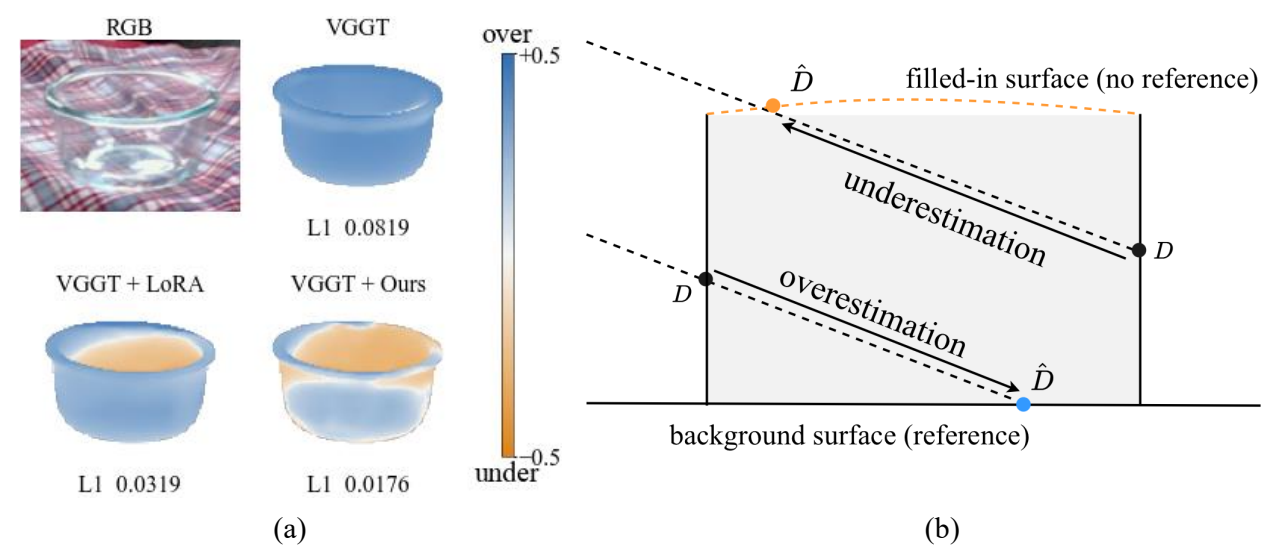
300 dpi PNG · 图注 · 源PDF
引言图1用透明物体深度错误及背景/凹面几何示意说明高估与低估的不同失败机制。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[143, 188, 450, 322],PDF点、左上角原点。
Figure 1: Feed-forward 3D foundation models fail on transparent objects in two opposite directions.
(a) L1 depth error for a transparent object under zero-shot prediction, LoRA, and Ours. The zero-
shot prediction is dominated by overestimation associated with background leakage. LoRA reduces
the error, but underestimation around the concave interior remains, whereas our method corrects both
error directions. (b) The two error directions differ in reference availability. Background leakage
can be related to an observable background surface, whereas a filled-in concavity has no analogous
geometric reference for recovering the missing depth.
Latent Bridge: From Video Latents to 3D Geometry via Feature Alignment
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页 · ICLR27_dPyGZiJESZ_F
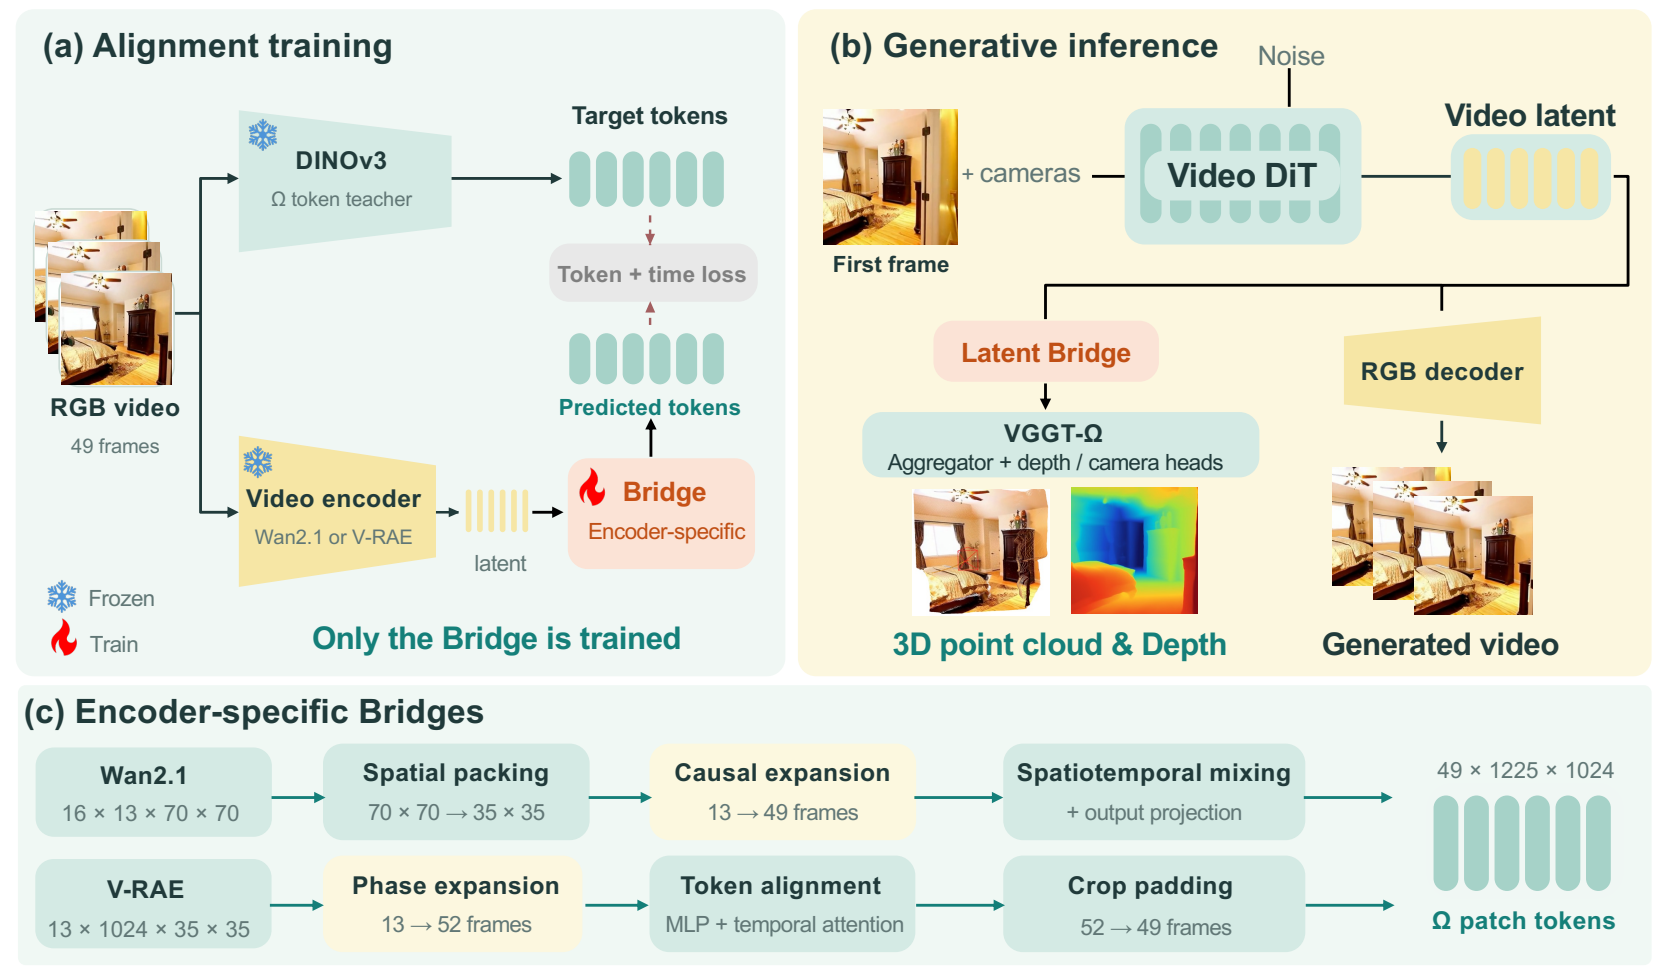
300 dpi PNG · 图注 · 源PDF
图2及方法节展示潜空间桥训练、生成推理、几何输出及桥接网络完整计算路径。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-10-20;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
固定OpenReview投稿PDF于10月3日公开;匹配的arXiv v1较后,不用于提前该视觉版本日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Xinggang Wang;65000;快照2026-10-21。
绘图工具:unknown。作者声明AI协助可视化脚本和3D可视化界面;未披露所选M/F绘制工具。
裁剪坐标:[106, 384, 507, 619],PDF点、左上角原点。
Figure 2: Overview of Latent Bridge, showing (a) feature alignment training, (b) video generation
and geometry prediction from a shared latent, and (c) the architectures of bridges.
Latent Bridge: From Video Latents to 3D Geometry via Feature Alignment
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_dPyGZiJESZ_M
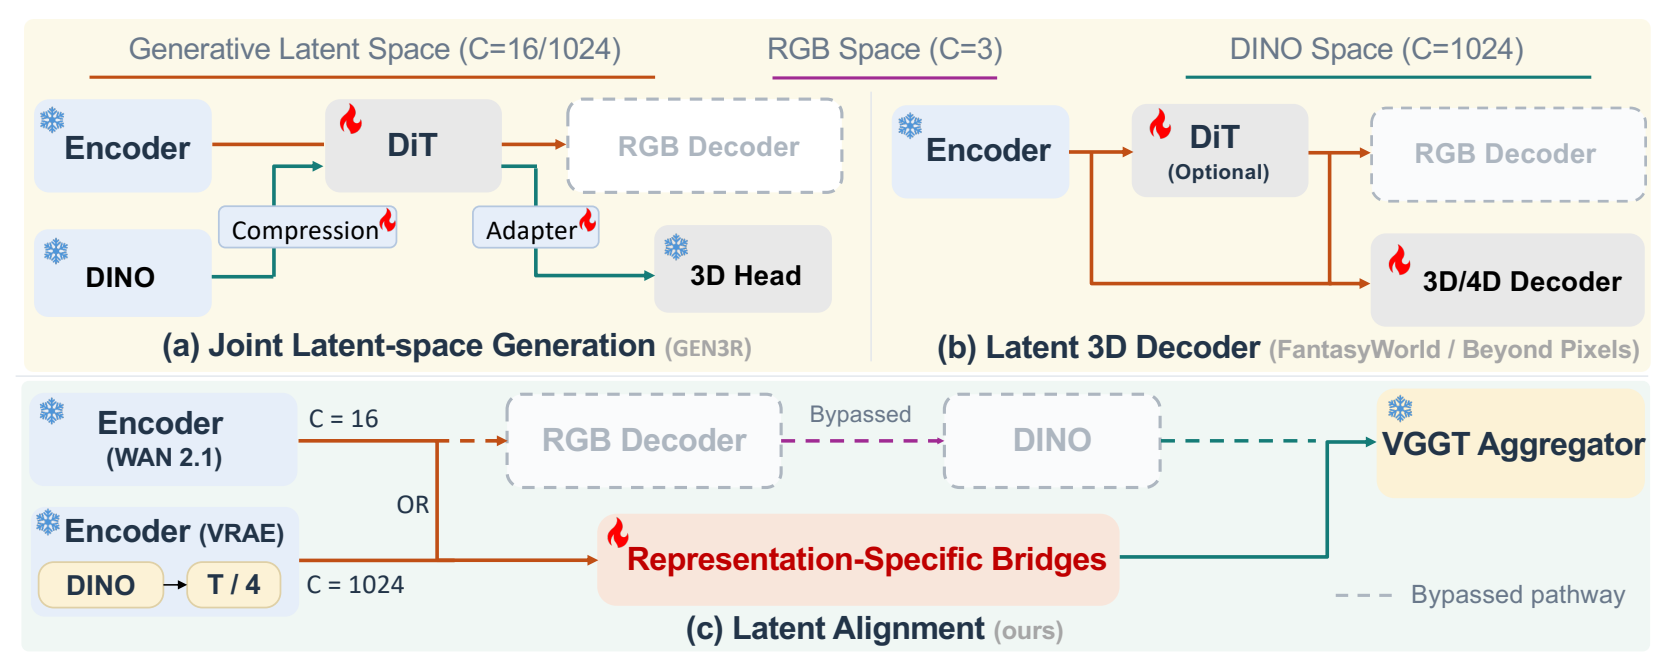
300 dpi PNG · 图注 · 源PDF
引言图1对比联合潜空间、潜空间解码与直接对齐三个范式,解释绕过RGB解码和联合重训练的动机。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-10-20;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
固定OpenReview投稿PDF于10月3日公开;匹配的arXiv v1较后,不用于提前该视觉版本日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Xinggang Wang;65000;快照2026-10-21。
绘图工具:unknown。作者声明AI协助可视化脚本和3D可视化界面;未披露所选M/F绘制工具。
裁剪坐标:[106, 79, 507, 239],PDF点、左上角原点。
Figure 1: Bypass the video decoder and directly align latent spaces to generate 3D outputs.
LonGaussian: Tracking Foundation Priors for Long-Context Feedforward Gaussian Reconstruction
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 3 · PDF第4页 · ICLR27_WiNCsgDP25_F
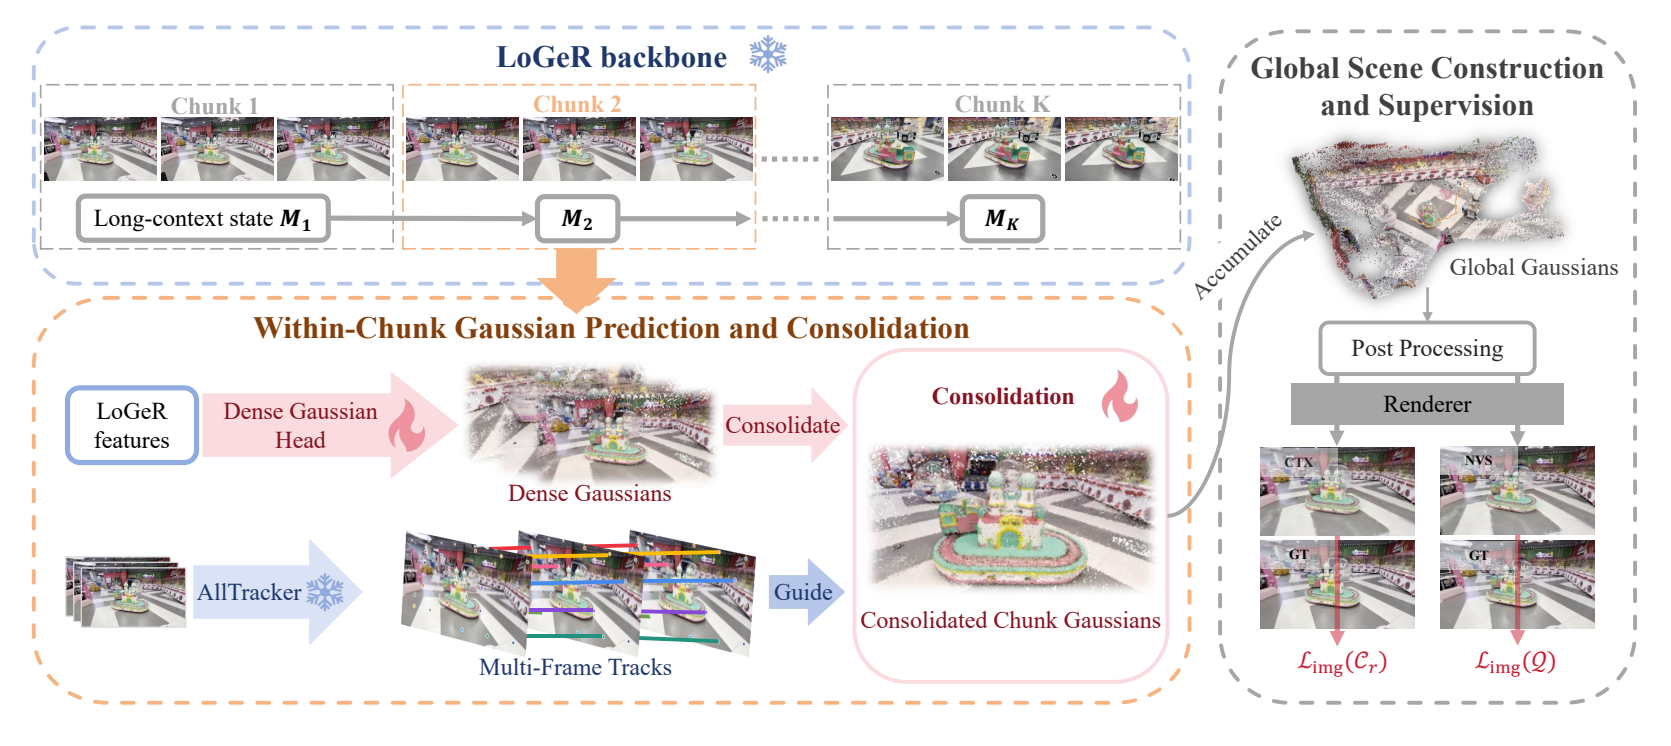
300 dpi PNG · 图注 · 源PDF
图3展示LonGaussian整体流程,包括长序列骨干、跟踪对应、高斯合并、跨块过滤和场景渲染监督。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-10-16;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
固定OpenReview投稿PDF于10月3日公开;匹配的arXiv v1较后,不用于提前该视觉版本日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Xinggang Wang;65000;快照2026-10-21。
绘图工具:unknown; authors_deny_generative_AI_figures。作者明确否认生成式AI用于创建科学图;实际绘图软件未披露。
裁剪坐标:[106, 79, 507, 258],PDF点、左上角原点。
Figure 3: Overview of LonGaussian. LoGeR processes overlapping chunks, and AllTracker cor-
respondences guide Gaussian consolidation before cross-chunk filtering and far-field modeling.
Snowflakes and flames denote frozen and trainable modules, respectively.
LonGaussian: Tracking Foundation Priors for Long-Context Feedforward Gaussian Reconstruction
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第2页 · ICLR27_WiNCsgDP25_M
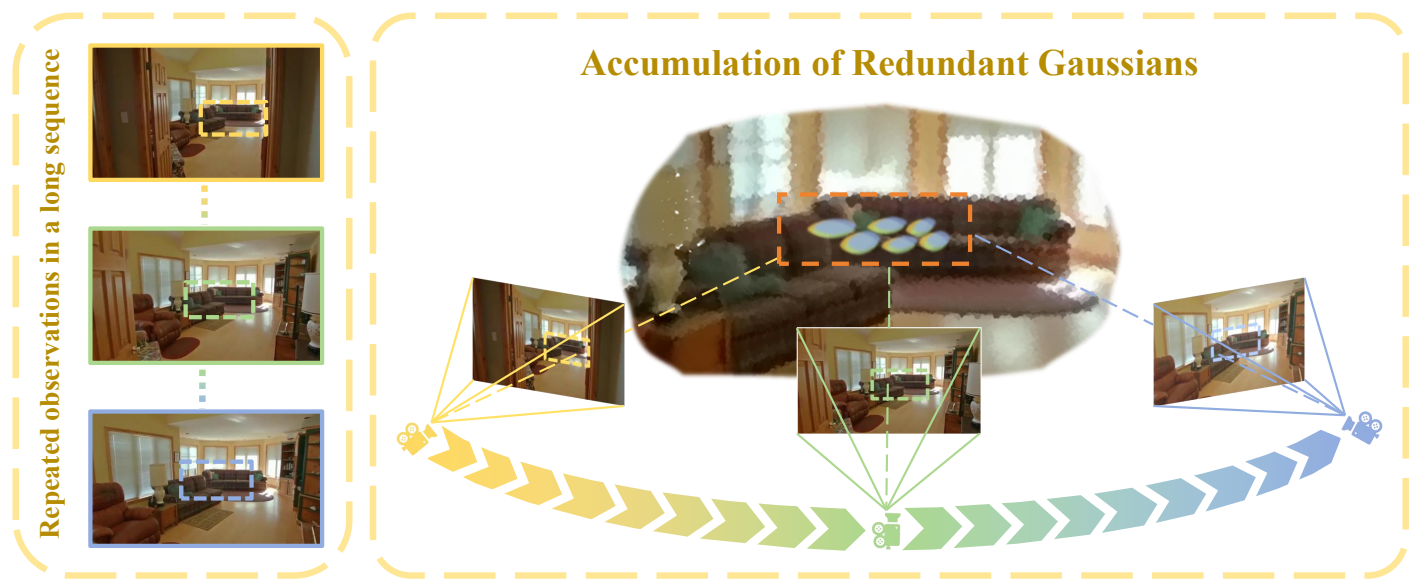
300 dpi PNG · 图注 · 源PDF
引言图2通过重复观察累积同一表面的重叠高斯,说明存储和渲染冗余的来源。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-10-16;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
固定OpenReview投稿PDF于10月3日公开;匹配的arXiv v1较后,不用于提前该视觉版本日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Xinggang Wang;65000;快照2026-10-21。
绘图工具:unknown; authors_deny_generative_AI_figures。作者明确否认生成式AI用于创建科学图;实际绘图软件未披露。
裁剪坐标:[136, 79, 478, 219],PDF点、左上角原点。
Figure 2: Gaussian redundancy from repeated observations. Pixel-aligned predictions accumulate
overlapping primitives for the same surface, increasing storage and rendering costs; matching colors
denote corresponding observations and Gaussians.
PAIR3D: Learning Physics-Aligned and Visually Consistent 3D Scene Layouts from Verifiable Rewards
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页 · ICLR27_e8KzLssuLH_F
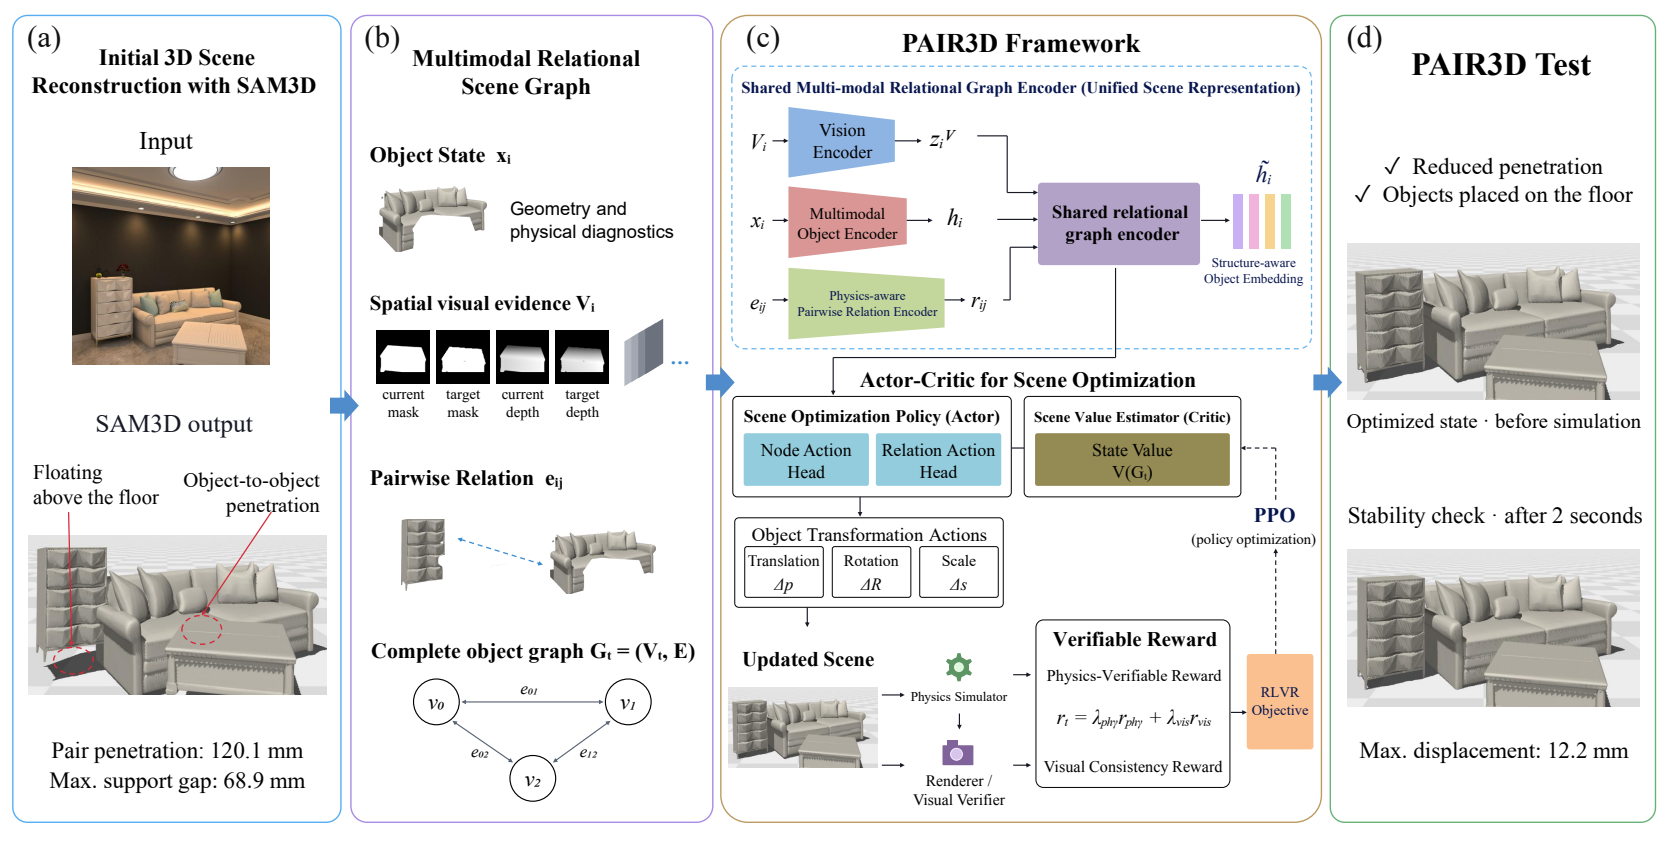
300 dpi PNG · 图注 · 源PDF
图2展示PAIR3D初始重建、关系场景图、策略优化、物理与视觉奖励和测试时优化的全流程。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 282],PDF点、左上角原点。
Figure 2: Overview of PAIR3D. PAIR3D aligns reconstructed 3D scenes with physical constraints
through verifiable feedback. Given an initial SAM3D reconstruction with artifacts such as floating
objects and inter-object penetration, we construct a multimodal relational scene graph from object
states, spatial visual evidence, and pairwise relations. A shared relational encoder provides structure-
aware representations to an actor–critic policy, which iteratively updates object translation, rotation,
and scale. Physics simulation and visual verification provide verifiable rewards for PPO training. The
resulting policy directly refines scenes at test time, reducing penetration and support violations while
producing configurations that remain stable under simulation.
PAIR3D: Learning Physics-Aligned and Visually Consistent 3D Scene Layouts from Verifiable Rewards
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_e8KzLssuLH_M
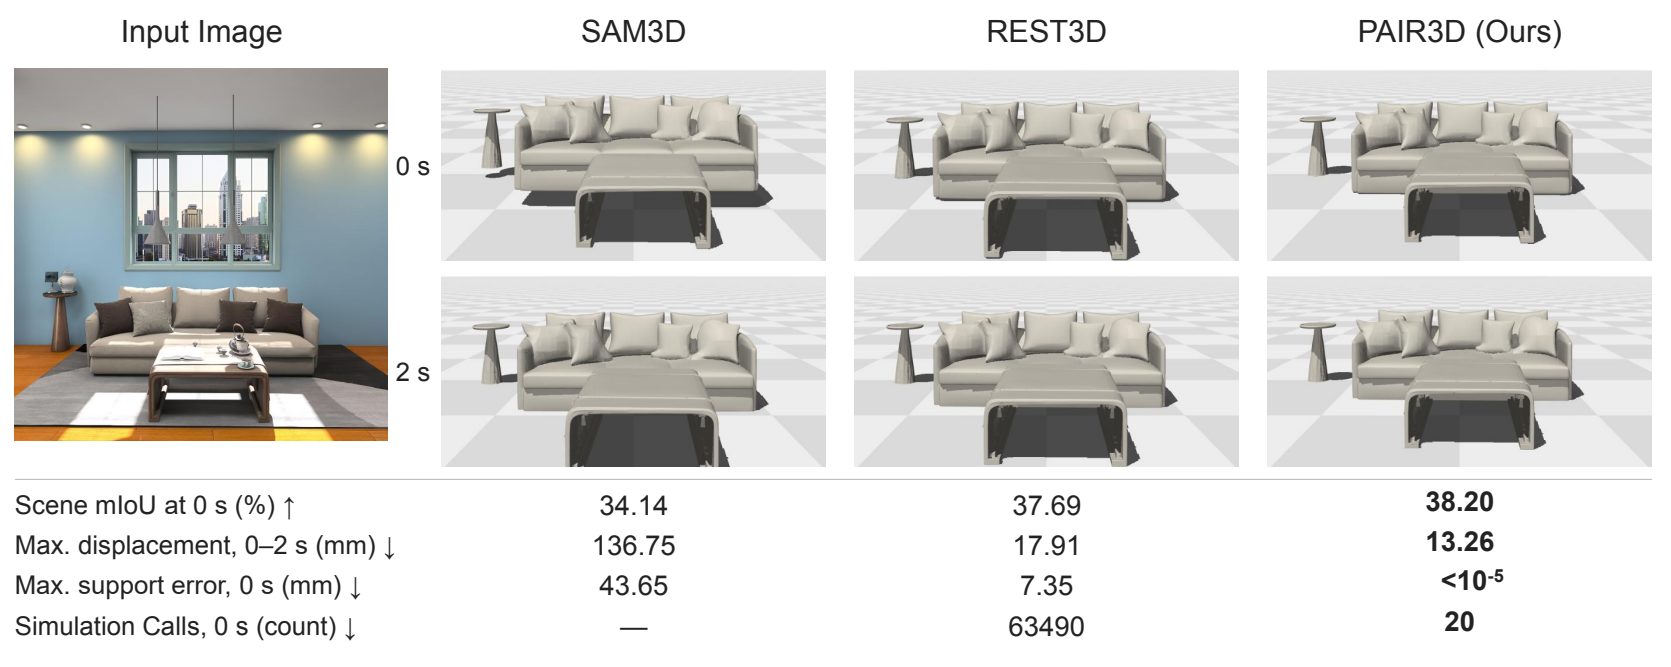
300 dpi PNG · 图注 · 源PDF
引言图1将同一重建场景置于物理模拟前后,展示几何看似合理却坍塌/位移的失败与物理约束动机;附带指标完整保留。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:未匹配;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
完整arXiv标题检索未找到匹配;补充标题检索未找到可确认的更早同稿。证据为公开投稿时间代理。
公开日期 · 论文入口
作者引用:按用户授权免除;未知值没有记为0。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 239],PDF点、左上角原点。
Figure 1: Physics alignment and visual consistency under various methods for a reconstructed
scene. We compare SAM3D (Chen et al., 2026), REST3D (Ma et al., 2026), and PAIR3D (ours)
at initialization and after 2 seconds of MuJoCo simulation, rendered from the input camera. In
this example, PAIR3D achieves the highest scene mIoU, near-zero support error, and the smallest
simulation-induced displacement, while using fewer simulation rollouts for scene refinement. The
mIoU and support error are measured at initialization; displacement denotes the maximum per-object
translation between 0 and 2 seconds.
PCAsplat: Gaussian Splatting with Local PCA Regularization
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页 · ICLR27_0X2ay3NW4Z_F
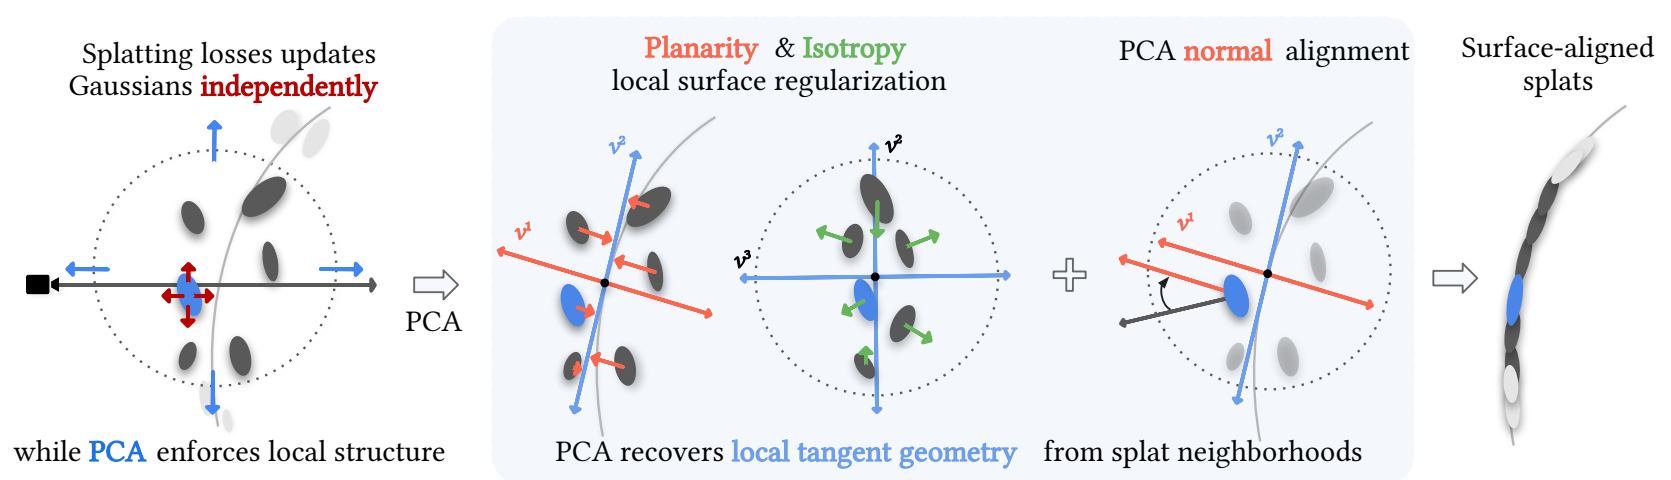
300 dpi PNG · 图注 · 源PDF
图2为PCAsplat核心计算路径,完整呈现高斯邻域、可微PCA、谱约束、法线对齐到表面对齐高斯。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-10-07;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
固定OpenReview投稿PDF于10月3日公开;匹配的arXiv v1较后,不用于提前该视觉版本日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Gordon Wetzstein;47402;快照2026-10-21。
绘图工具:unknown。作者声明AI协助可视化代码;未披露所选M/F绘制工具。
裁剪坐标:[106, 79, 507, 194],PDF点、左上角原点。
Figure 2: Overview of PCAsplat. We regularize Gaussian neighborhoods directly in scene space.
For each Gaussian, we estimate a local neighborhood and compute differentiable PCA statistics
that capture the underlying tangent structure. We then regularize the local eigenspectrum to reduce
neighborhood thickness and promote isotropic tangent-plane coverage. We also align Gaussian
normals with PCA-derived normals, encouraging surface-aligned and well-localized splats. Our
formulation is lightweight, differentiable, and directly compatible with existing splatting pipelines.
PCAsplat: Gaussian Splatting with Local PCA Regularization
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页 · ICLR27_0X2ay3NW4Z_M
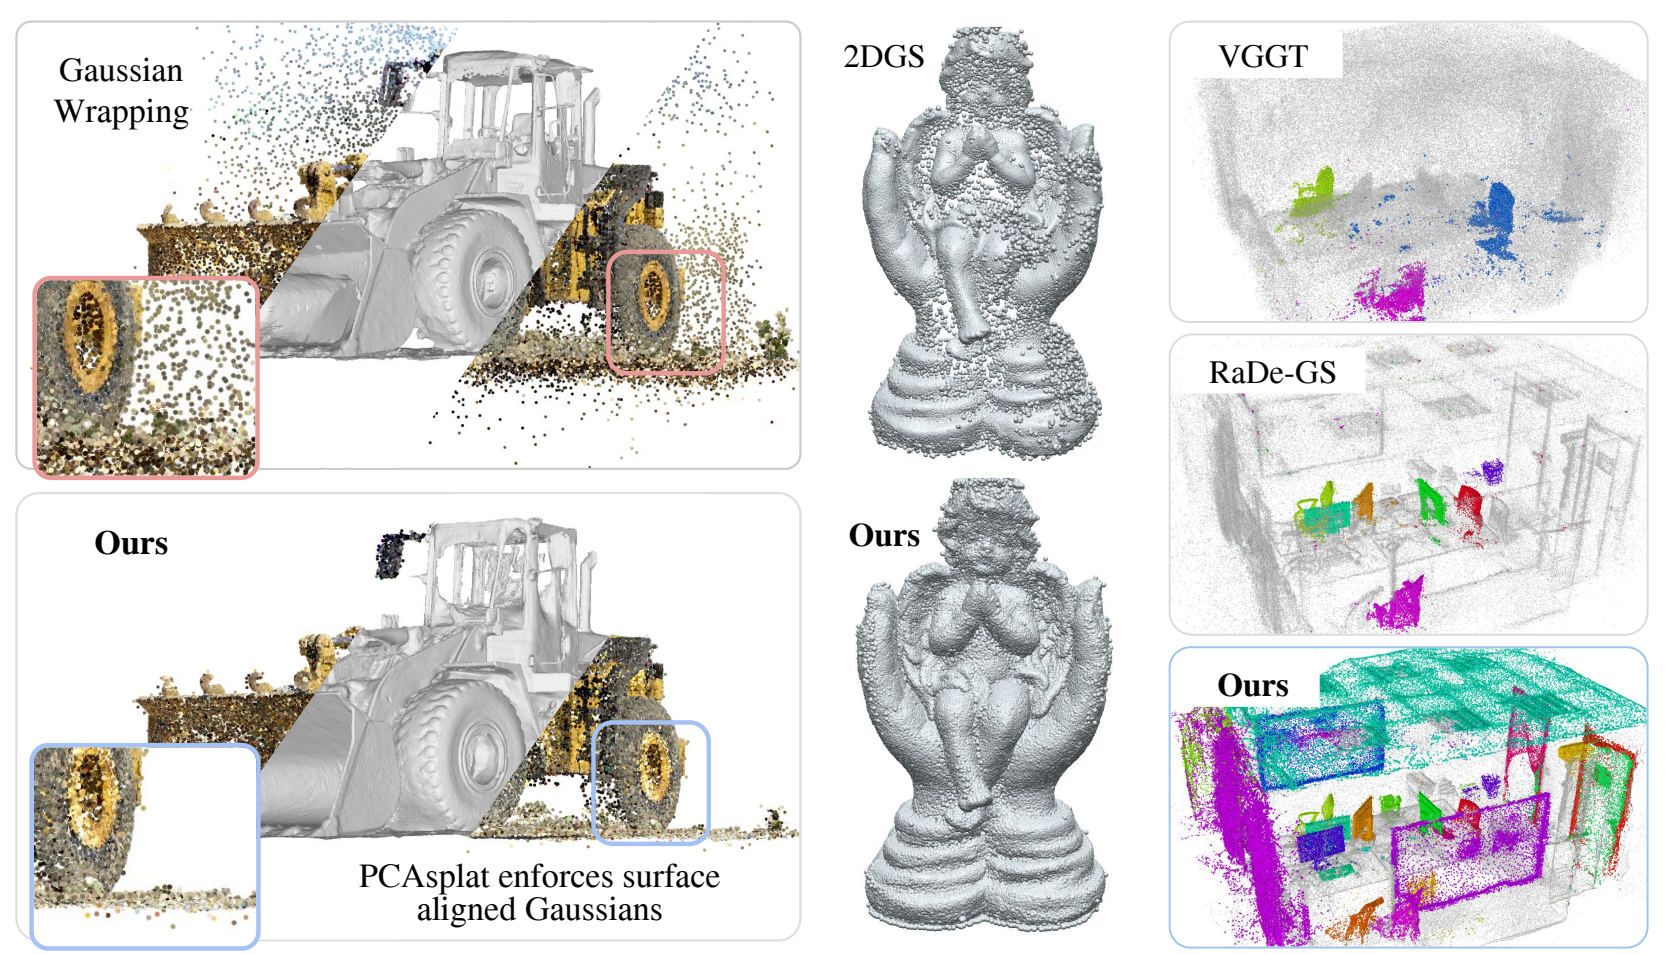
300 dpi PNG · 图注 · 源PDF
引言图1用浮点伪影、稀疏表面覆盖和失败的后续分割说明现有高斯几何的局限。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-10-07;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
固定OpenReview投稿PDF于10月3日公开;匹配的arXiv v1较后,不用于提前该视觉版本日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Gordon Wetzstein;47402;快照2026-10-21。
绘图工具:unknown。作者声明AI协助可视化代码;未披露所选M/F绘制工具。
裁剪坐标:[106, 79, 507, 308],PDF点、左上角原点。
Figure 1: We present PCAsplat, a geometric regularization of Gaussian splatting that aligns Gaus-
sians with surfaces through differentiable local PCA. Compared with current methods, PCAsplat
substantially reduces floaters (left) and produces cleaner point clouds with better surface coverage
(center). This improved point-cloud enables downstream tasks such as instance segmentation (right).
SM4RT: Learning Structured Motion Geometry for 4D Reconstruction
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 4 · PDF第5页 · ICLR27_Y69S27nWgp_F
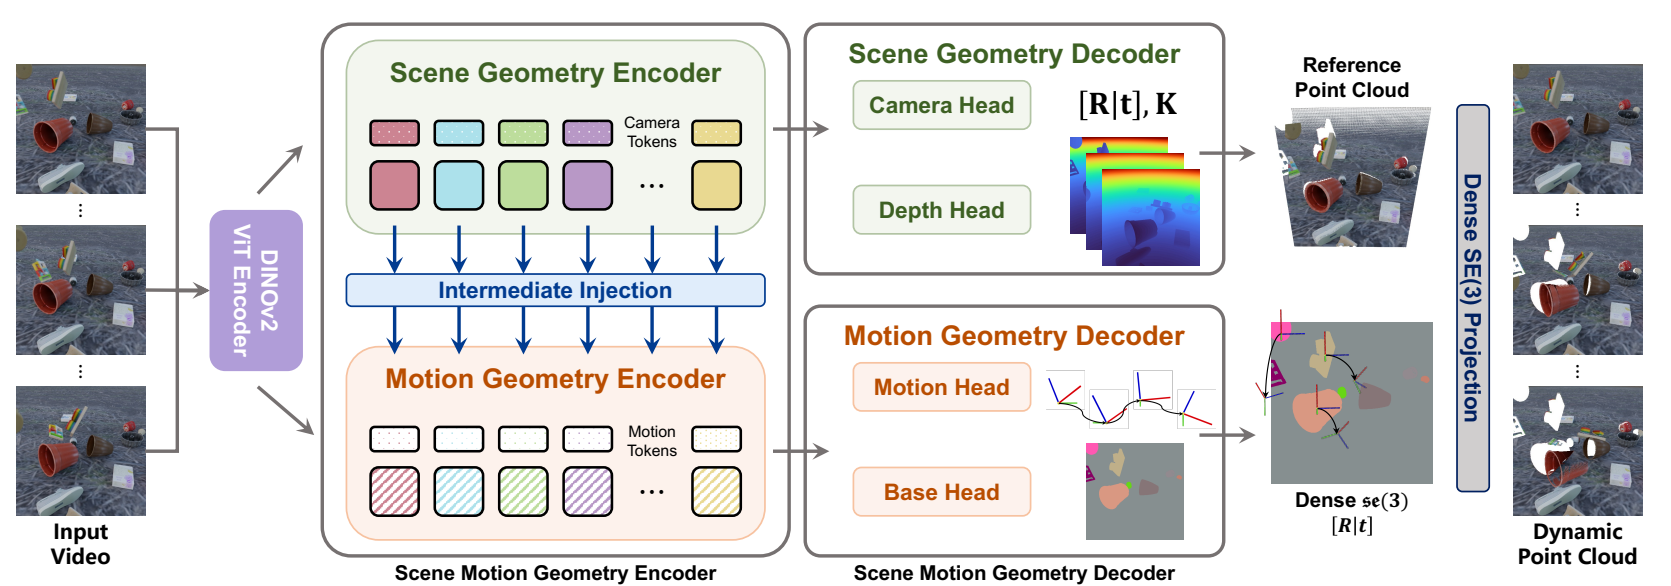
300 dpi PNG · 图注 · 源PDF
图4为SM4RT整体网络,涵盖几何与运动双分支、相机深度、运动基和稠密SE(3)投影。
完整图注、版本和筛选证据
最早核实视觉日期:2026-07-24;arXiv v1:2026-07-24;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
v1双编码/解码结构及输出布局匹配
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jie Zhou;56256;快照2026-10-21。
绘图工具:generative_AI_layout_guidance_unspecified_tool。作者声明AI用于figure layout和presentation建议;不等同于自动生成所选图。
裁剪坐标:[106, 79, 507, 219.5],PDF点、左上角原点。
Figure 4: Overview of our SM4RT. Given a monocular input video, SM4RT extracts latent geome-
try tokens with a DINOv2 backbone, then decouples them into scene geometry and motion geometry
tokens. The scene decoder predicts camera parameters and depth, while the motion decoder esti-
mates sparse se(3) transforms and motion base weights for dense SE(3) projection.
SM4RT: Learning Structured Motion Geometry for 4D Reconstruction
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第3页 · ICLR27_Y69S27nWgp_M
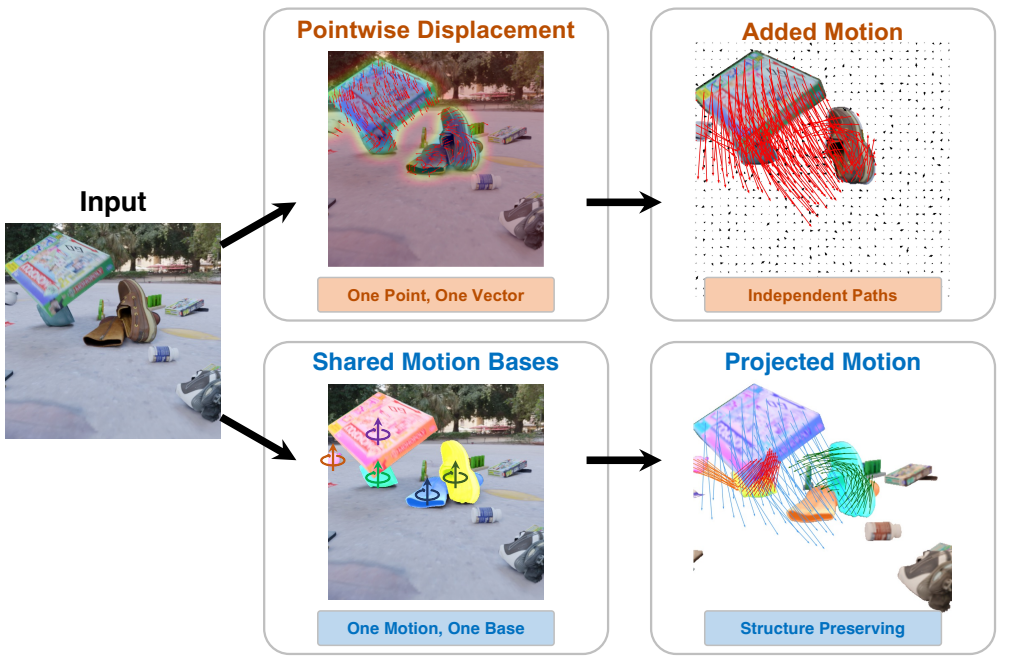
300 dpi PNG · 图注 · 源PDF
图2及3.1节以独立点位移与共享刚性运动基对比,说明缺少物体内运动约束的结构缺口。图1为方法产出示意未选。
完整图注、版本和筛选证据
最早核实视觉日期:2026-07-24;arXiv v1:2026-07-24;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
v1位移/共享运动基对照及配色匹配
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Jie Zhou;56256;快照2026-10-21。
绘图工具:generative_AI_layout_guidance_unspecified_tool。作者声明AI用于figure layout和presentation建议;不等同于自动生成所选图。
裁剪坐标:[265, 416, 507, 574],PDF点、左上角原点。
Figure 2: Comparison of motion representations. The
proposed representation preserves the structure of object
motion, which provides a more structured description than
standard per-pixel displacement and encouraging intra-
object homogeneity.
UniForge3D: Joint 3D Reconstruction and Generation in a Shared Anchor-Guided Space
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 3 · PDF第4页 · ICLR27_dpOjIHiDKY_F
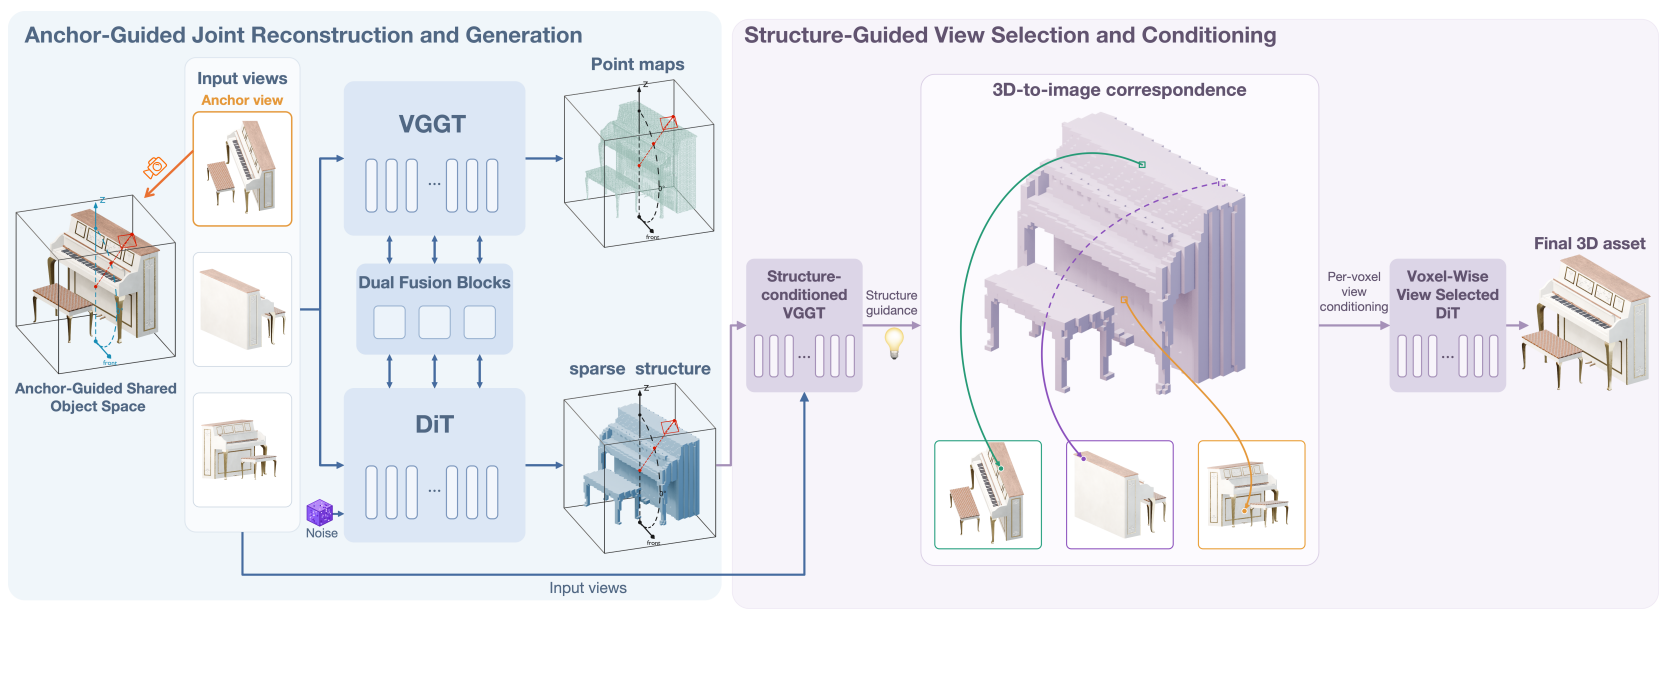
300 dpi PNG · 图注 · 源PDF
正文3节与图3明确给出UniForge3D完整双分支交互、共享空间及逐体素条件生成路径。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-10-11;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
固定OpenReview投稿PDF于10月3日公开;匹配的arXiv v1较后,不用于提前该视觉版本日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yuan Liu;12285;快照2026-10-21。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 243],PDF点、左上角原点。
Figure 3: Overview of UniForge3D. Left: The reconstruction and generation branches interact
bidirectionally to predict multi-view point maps and a complete sparse structure in a shared anchor-
guided space. Right: Structure-conditioned point maps establish voxel-to-pixel correspondences,
enabling the model to select informative views and use their image features to guide detailed shape
generation.
UniForge3D: Joint 3D Reconstruction and Generation in a Shared Anchor-Guided Space
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第2页 · ICLR27_dpOjIHiDKY_M
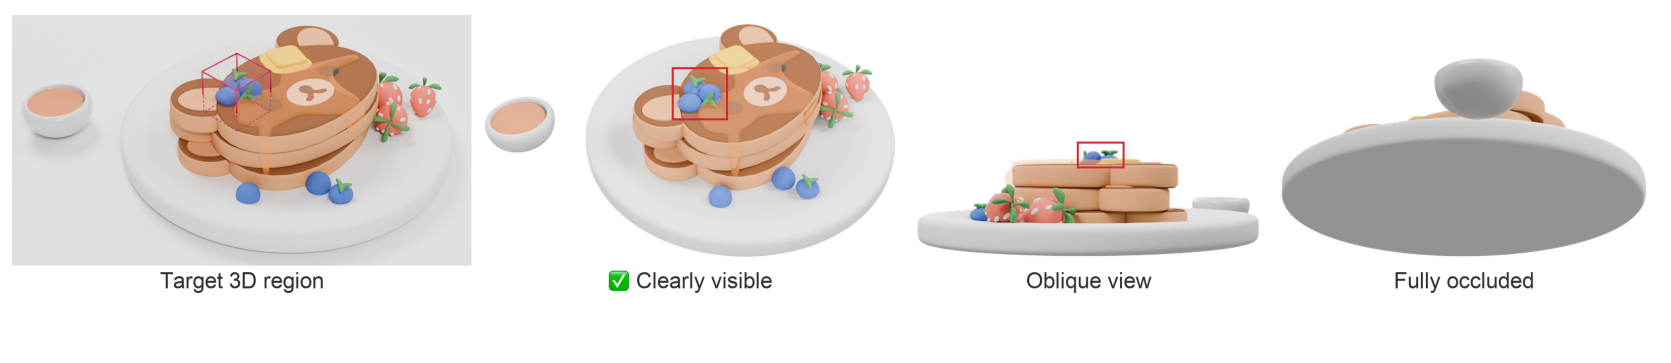
300 dpi PNG · 图注 · 源PDF
图2用同一区域在三个视角的可见、斜视与遮挡差异,说明区域特异的视角选择必要性。图1为普通产出展示未选。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-03;arXiv v1:2026-10-11;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
固定OpenReview投稿PDF于10月3日公开;匹配的arXiv v1较后,不用于提前该视觉版本日期。
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yuan Liu;12285;快照2026-10-21。
绘图工具:unknown。未发现针对所选M/F图的具体绘图工具披露;一般写作/代码AI声明不作绘图工具推断。
裁剪坐标:[106, 79, 507, 166],PDF点、左上角原点。
Figure 2: Different views provide different evidence for the same 3D region. The 3D box marks
three blueberries, which are clearly visible, seen at an oblique angle, or fully occluded across the
three views, motivating region-specific view selection.
VASC: Value-Aware Sparse Attention with Cross-layer Memory for Efficient 3D Reconstruction
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 4 · PDF第5页 · ICLR27_X7FI3N35Hq_F
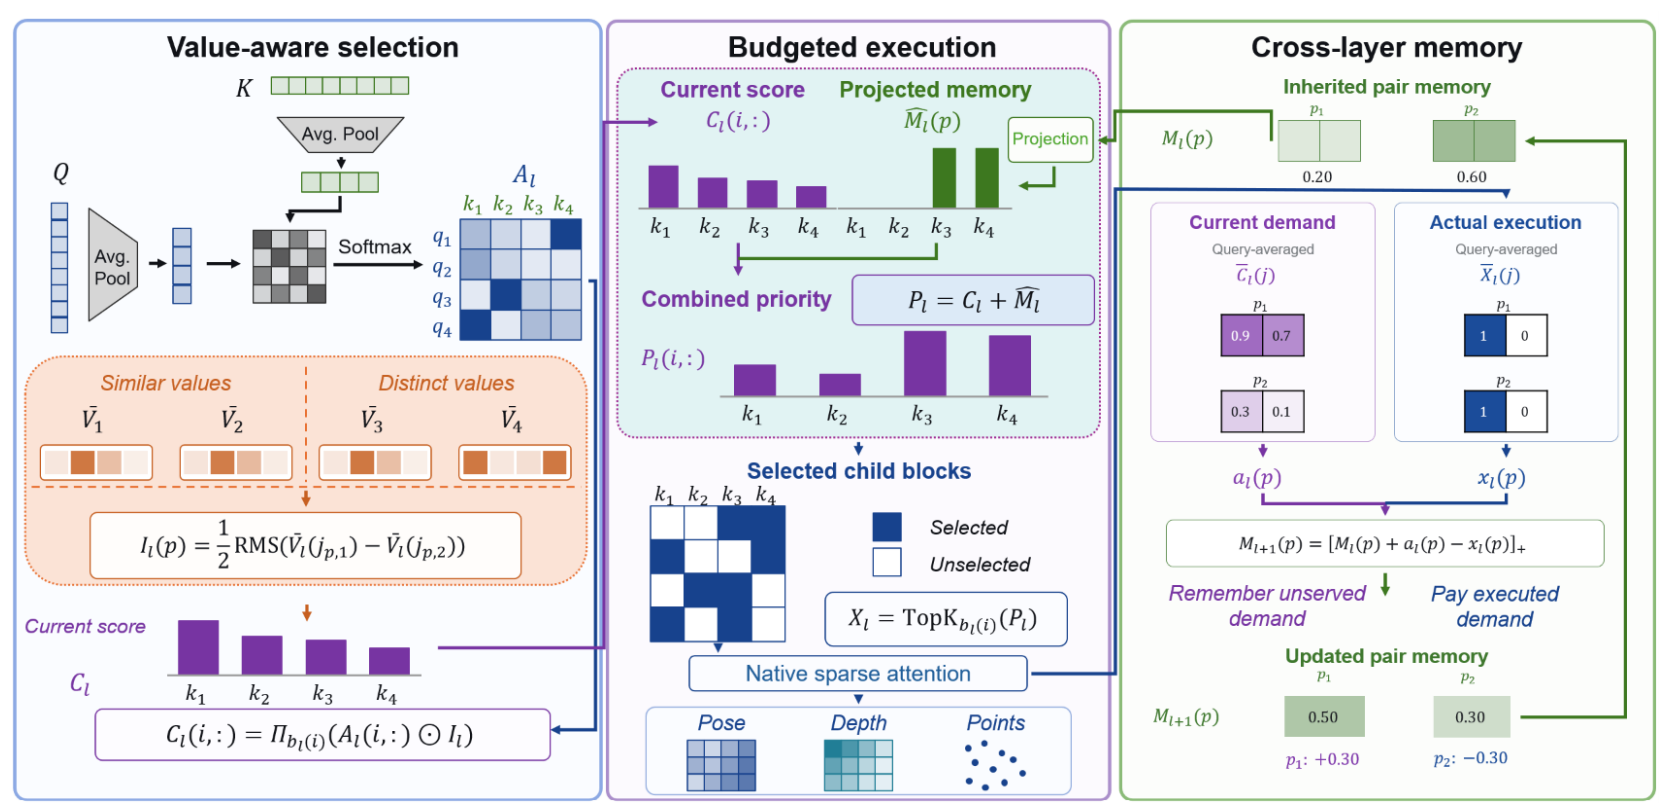
300 dpi PNG · 图注 · 源PDF
图4被正文称为VASC overview,完整呈现值对比、跨层记忆、预算内块选择及执行反馈。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-01;arXiv v1:2026-10-01;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
v1匹配
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yulun Zhang;40552;快照2026-10-21。
绘图工具:generative_AI_figure_composition_unspecified_tool。作者声明生成式AI协助figure composition;未给出工具名或逐图对应。
裁剪坐标:[106, 79, 507, 272],PDF点、左上角原点。
Figure 4: VASC overview. Value contrast and cross-layer memory jointly guide block selection
within a fixed budget. Actual execution updates memory for the next layer.
VASC: Value-Aware Sparse Attention with Cross-layer Memory for Efficient 3D Reconstruction
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 3 · PDF第4页 · ICLR27_X7FI3N35Hq_M
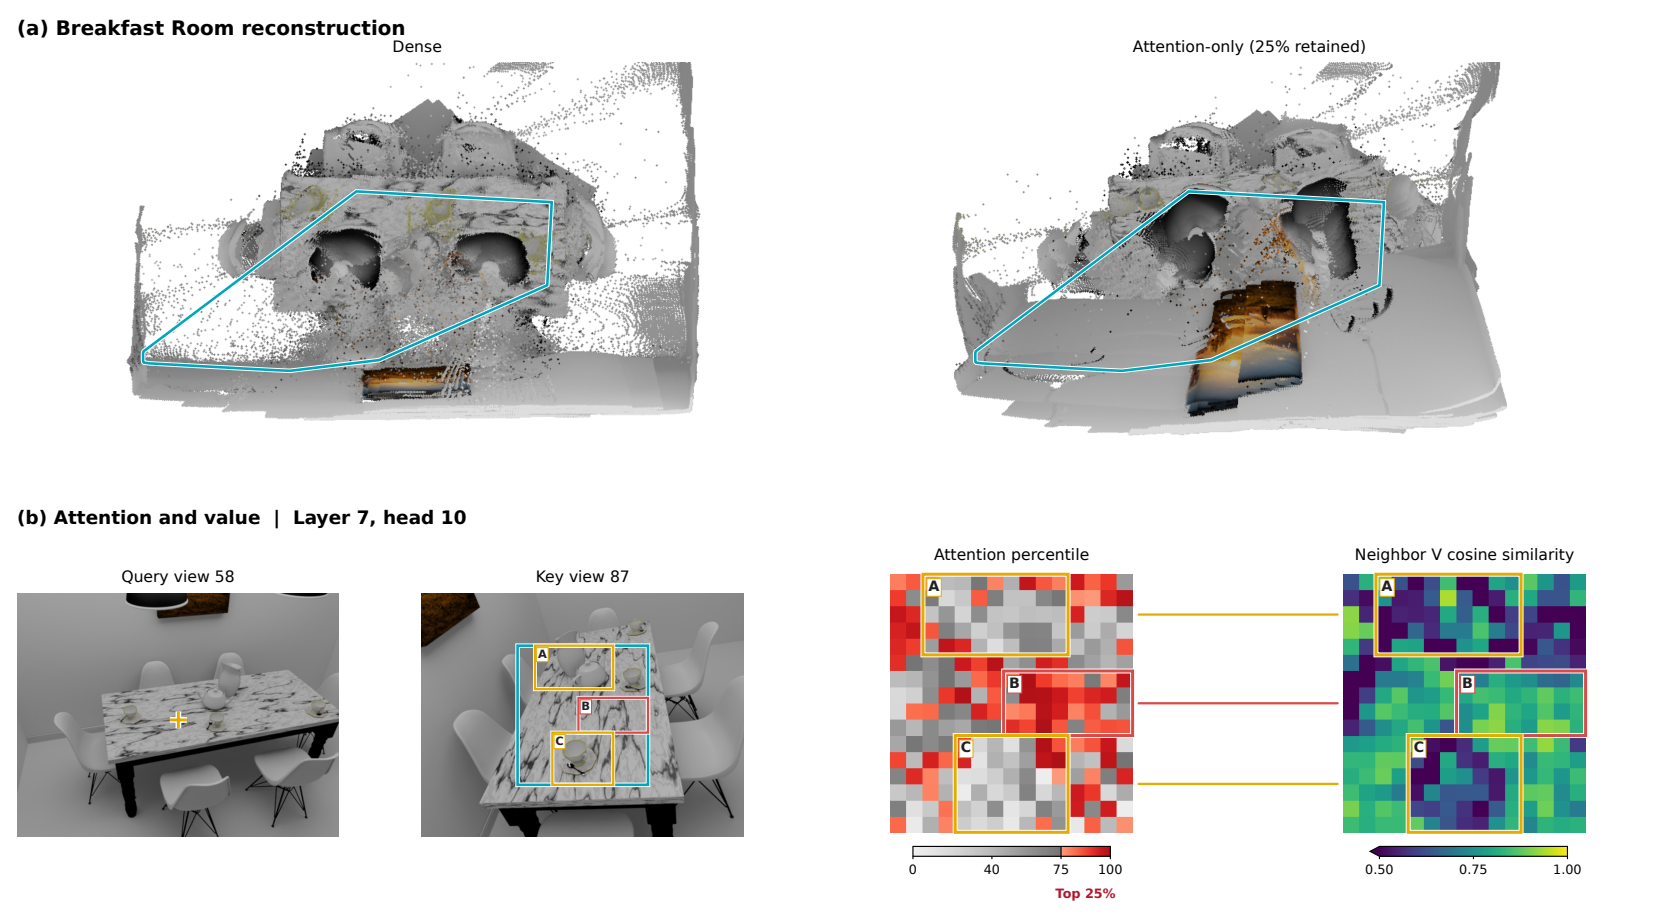
300 dpi PNG · 图注 · 源PDF
第3节图3通过仅保留高注意力连接造成重建退化的受控失败,说明注意力强度不能替代值信息差异。图1为结果展示未选。
完整图注、版本和筛选证据
最早核实视觉日期:2026-10-01;arXiv v1:2026-10-01;ICLR 2027 frozen anonymous submission PDF; retrieved 2026-10-28 UTC
v1匹配
历史PDF · 下载引用证据快照 · 公开日期 · 论文入口
作者引用:Yulun Zhang;40552;快照2026-10-21。
绘图工具:generative_AI_figure_composition_unspecified_tool。作者声明生成式AI协助figure composition;未给出工具名或逐图对应。
裁剪坐标:[106, 210, 507, 430],PDF点、左上角原点。
Figure 3: Attention priority and local value variation. (a) Dense and attention-only reconstruction
with 25% of connections retained. (b) Attention and neighboring-value similarity reveal different
spatial patterns; lower similarity indicates greater directional variation.
S4-AI-Style · 40 篇 · 51 张图(M 11 / F 40)
以下为额外风格对照样本,所有topic、目的性选图,不计入正式160篇。标签不表示已经证实AI绘制。
40篇清单
S4-AI-Style · 智能体图像复原 · MGRASP: Grounded Restoration with Agent-Refined Semantic Prompts for Real-World Image Super-Resolution
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页
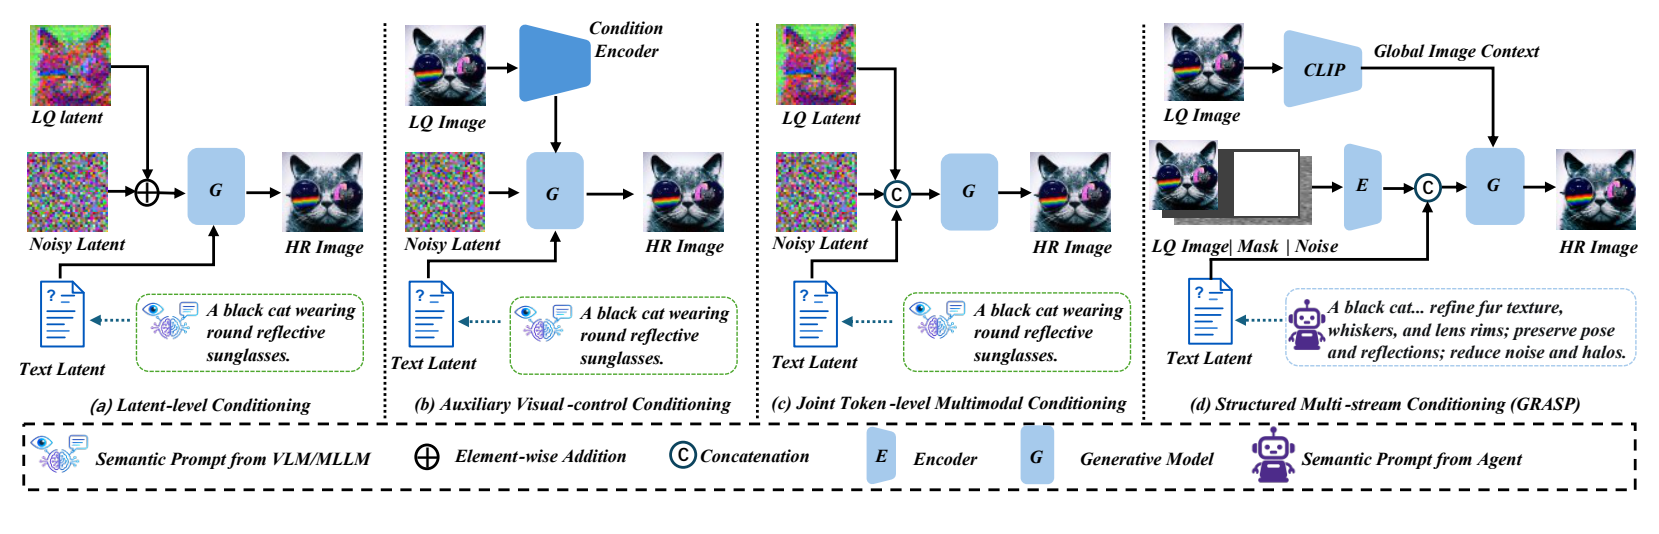
300 dpi PNG · 图注 · 原始PDF
风格入选理由:四个(a)–(d)并列面板、多层小框、指令文本卡、机器人与文档图标,配浅蓝浅绿浅紫。
引言用四种条件注入范式对照说明局部、全局和语义条件应分开组织的动机。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 208],PDF点、左上角原点。
Figure 1: Schematic comparison of conditioning paradigms in generative Real-ISR. Prior methods
typically inject low-quality observations and semantic prompts through latent-level conditioning,
auxiliary visual-control branches, or joint token-level multimodal conditioning. Panel (a) illustrates an
additive implementation of latent-level conditioning. GRASP organizes local visual evidence, global
image context, and agent-refined semantic prompts as distinct condition streams with complementary
functions for the SR objective.
GRASP: Grounded Restoration with Agent-Refined Semantic Prompts for Real-World Image Super-Resolution
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页
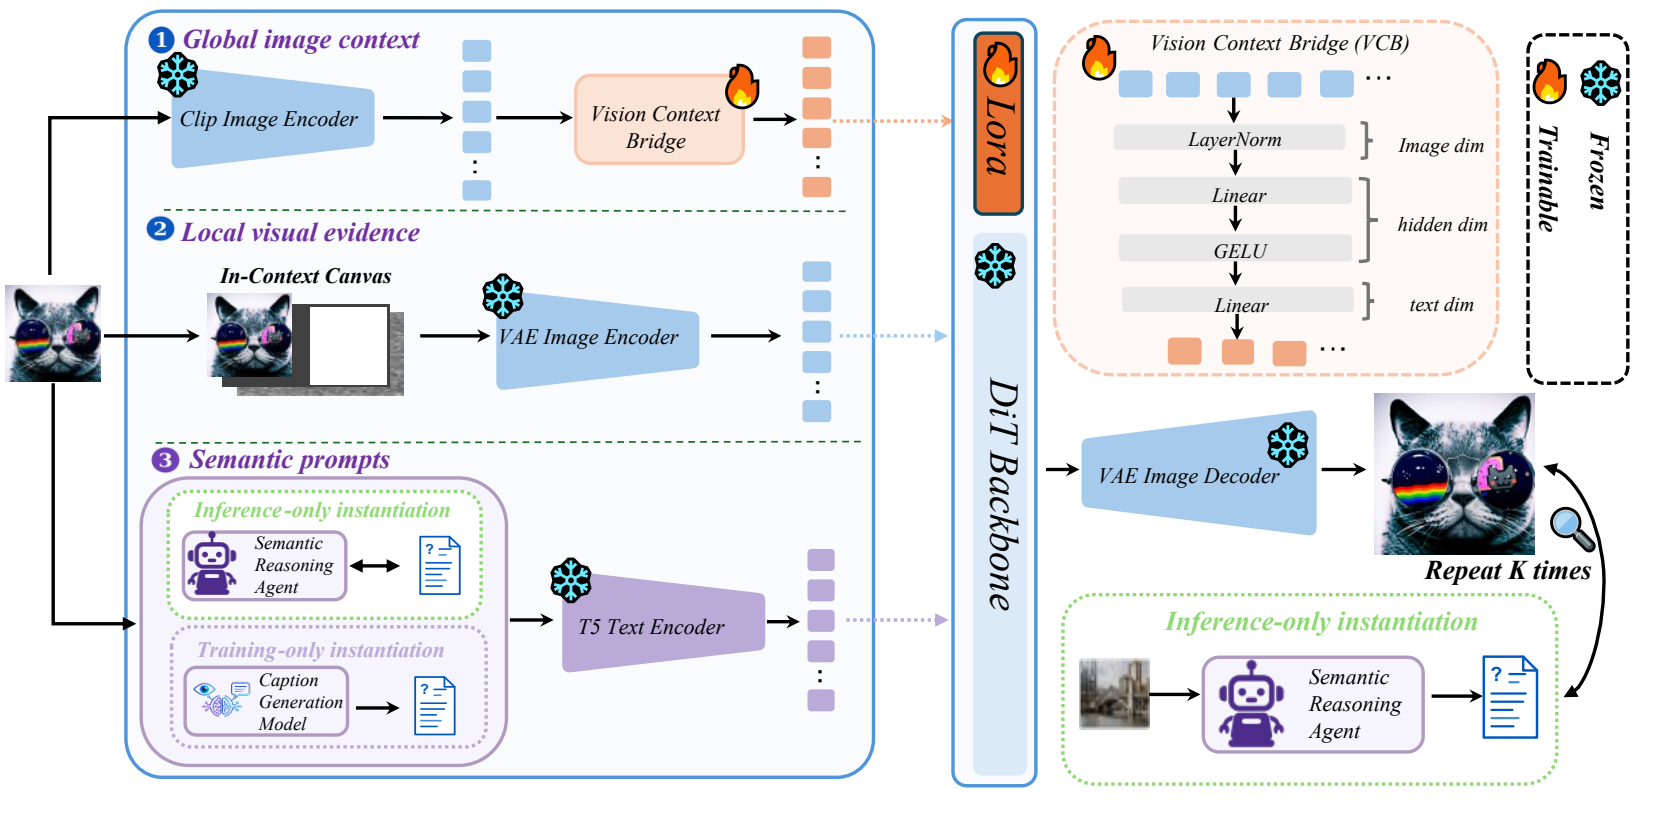
300 dpi PNG · 图注 · 原始PDF
风格入选理由:编号1–3的条件分区嵌套在大框中,右侧附桥接器卡片,结合机器人/火焰/雪花图标及浅蓝浅橙浅紫。
方法节图2明确给出GRASP整体条件通路、DiT骨干和输出。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 276],PDF点、左上角原点。
Figure 2: Overview of GRASP. Real-ISR is cast as visual in-context completion. Local visual
evidence comes from the diptych, global image context from the Vision-Context Bridge over CLIP,
and semantic prompts from LLaVA captions during training and agent refinement during inference.
$\mathrm{E}^2$IR-Agent: Experience-Driven Self-Evolving Image Restoration Agentic System
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第3页
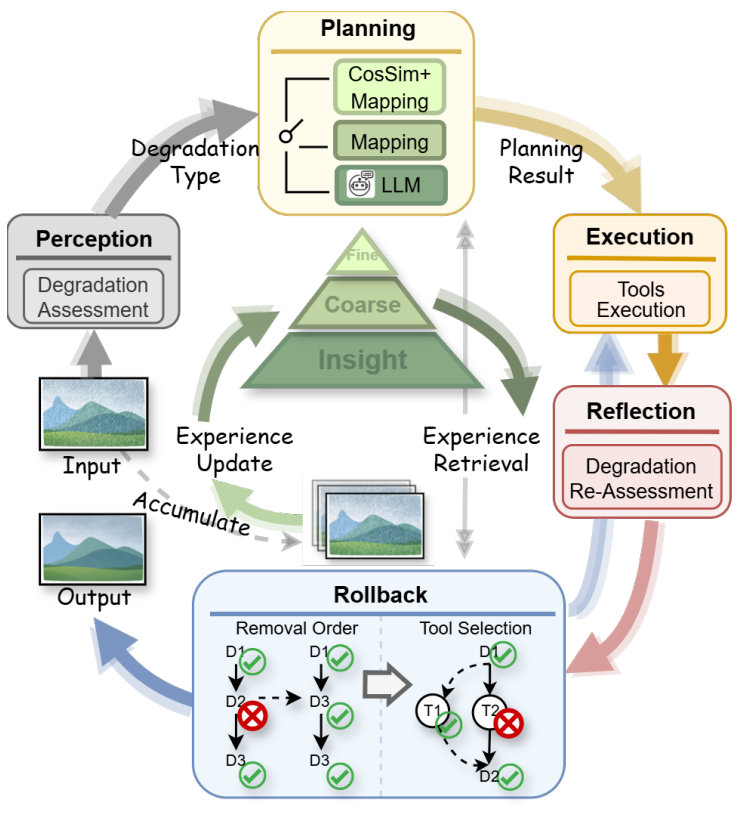
300 dpi PNG · 图注 · 原始PDF
风格入选理由:五种浅色圆角框围成循环,内部还有多层文字小框,辅以图片、勾叉、工具和符号图标。
方法节称图2为整体经验驱动推理流程,含感知、规划、执行、反思、回滚五个环节。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[328, 502, 505, 700],PDF点、左上角原点。
Figure 2: Overview of the experience-driven
inference workflow in E2IR-Agent.
GATOR: Generative and Agentic 3D Object Reconstruction from Casual Images
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页
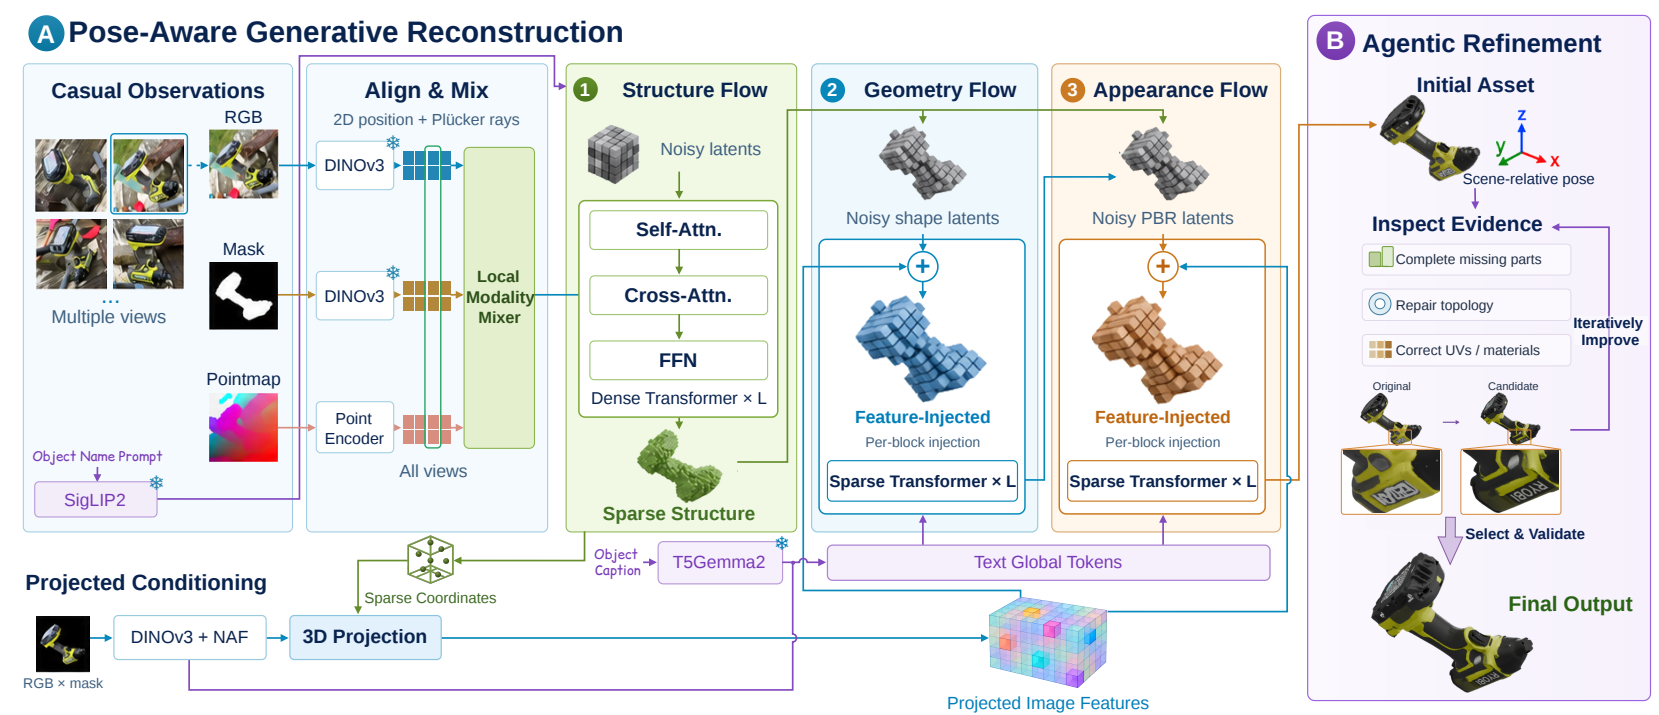
300 dpi PNG · 图注 · 原始PDF
风格入选理由:(A)/(B)大分区中嵌套编号结构/几何/外观流程,多色浅底卡片、细密标签、三维对象和冻结标识。
图2与方法节展示生成重建和智能体细化的完整两阶段体系。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。作者披露AI参与准备图形布局,未指明具体绘图模型或所选图号。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 251.5],PDF点、左上角原点。
Fig. 2: GATOR architecture. (A) Pose-aware generative reconstruction. Following TRELLIS.2 (Xiang
et al., 2026), GATOR uses conditional flows for sparse structure, geometry, and appearance. RGB images and
depth-derived pointmaps retain scene context, while masks identify the target. Tokens from all three modalities
share a patch grid with common 2D position and Plücker-ray encodings. A local mixer exchanges information
at each patch within a view (Secs. 3.2 and 3.3). Cross-view attention and SigLIP2 object-name conditioning
guide structure generation. At its active coordinates, projected DINOv3 and NAF-upsampled features from
target-masked images are averaged across valid views and injected into every geometry and appearance de-
noising block. Global image tokens and T5Gemma2-encoded captions supply cross-attention. Shape latents
condition PBR material generation (Sec. 3.4). ❄ denotes frozen encoders. (B) Agentic refinement. Initialized
with the complete, scene-aligned asset, an agent uses input images and structural priors to complete parts, re-
pair topology, and refine texture coordinates and materials. Its edit-render-review loop compares original and
candidate renders under matched cameras and lighting to retain or revert local edits. Within the time budget, it
selects the best inspected asset while preserving reliable regions and scene-relative placement (Sec. 3.5).
Stride: Scale-Aware Multi-Agent Evolutionary Refinement for Infographic Generation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第3页
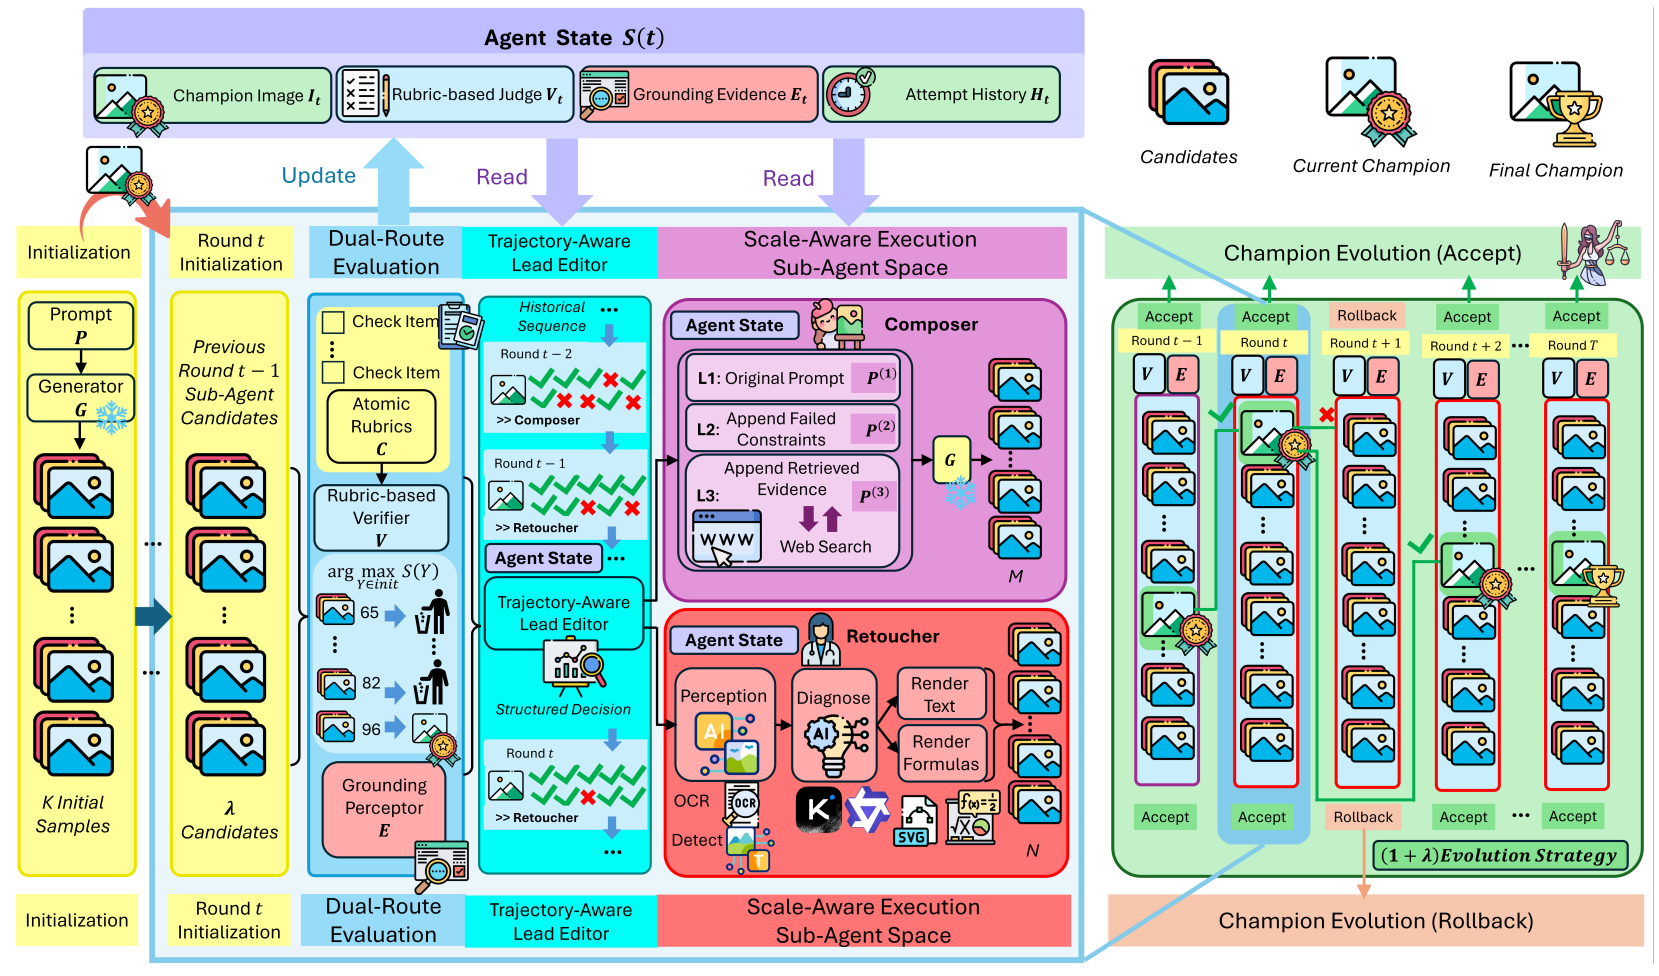
300 dpi PNG · 图注 · 原始PDF
风格入选理由:大面积卡片网格和状态列,密集说明文字与文档/机器人/奖杯等图标;浅紫浅黄底色混合较饱和的强调色。
图1及3.1节为STRIDE整体多轮评估、路由、编辑和接受/回退流程。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 314],PDF点、左上角原点。
Figure 1: Overview of STRIDE. From K initial samples, STRIDE selects a champion and refines it
for t rounds. Each round performs evolutionary refinement and agent state update through dual-route
evaluation: the verifier scores candidate images against the rubrics, while the perceptor provides vi-
sual grounding of the observed failures. The lead editor then analyzes the agent state and refinement
trajectory to route the champion to either the composer for global redraw or the retoucher for local
editing. The generated candidates are then re-evaluated, and the champion is updated only when a
candidate improves the verifier score. Repeating this process yields the final champion.
Frameworkers: A Dynamic Multi-Agent Framework for AI Video Production
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页
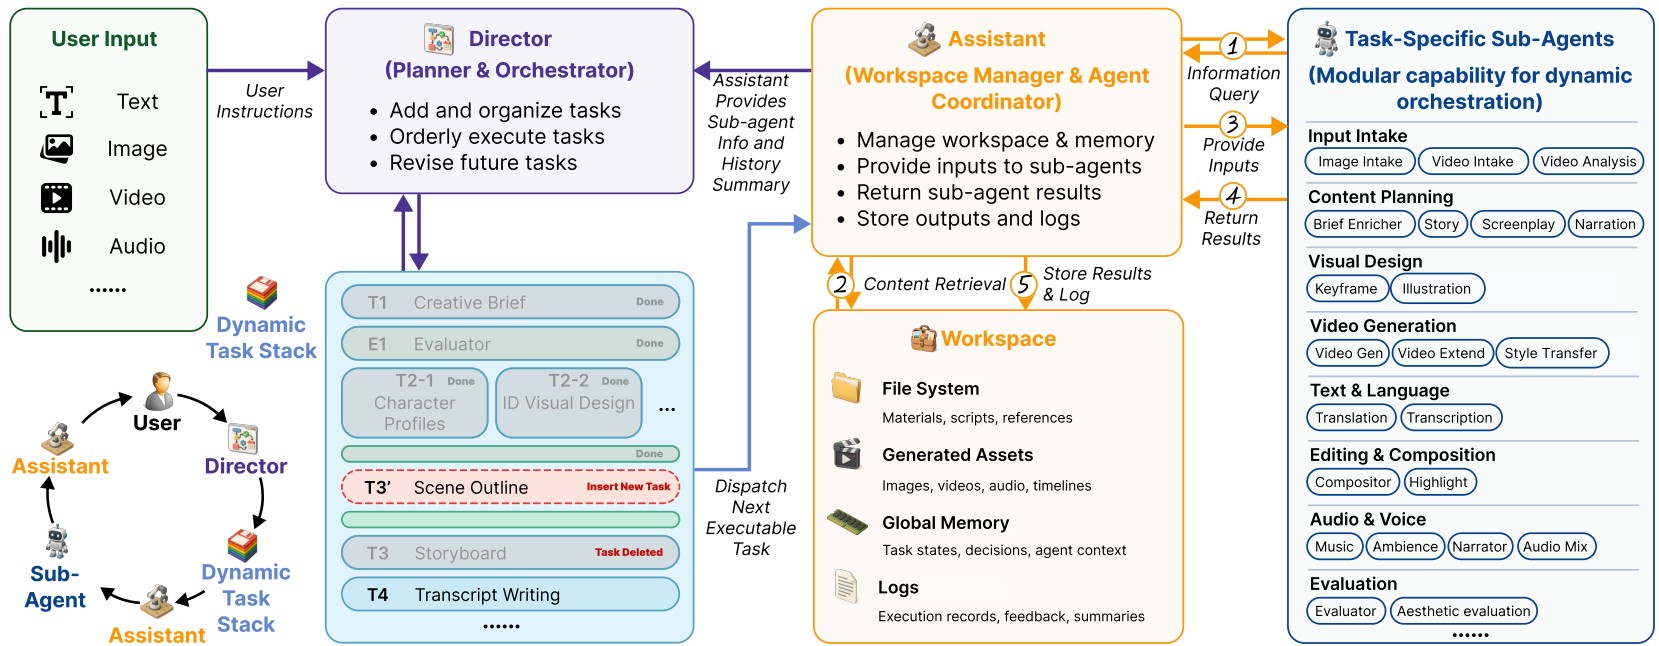
300 dpi PNG · 图注 · 原始PDF
风格入选理由:四列浅色框与多层条目卡片,段落式列表、序号箭头和人物/文件夹/文件图标密集组合。
图1及方法Overview展示Director、Assistant、任务栈、共享工作区与子智能体的闭环关系。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 235],PDF点、左上角原点。
Figure 1: Closed-loop orchestration in FRAMEWORKERS. The Director edits the Dynamic Task
Stack from the user input and the Assistant’s summaries; the stack shows completed tasks, an in-
serted task (T3′), and a deleted pending task (T3). The Assistant executes the dispatched task (arrows
1–5): it queries the sub-agent’s input requirements, retrieves the inputs from the Workspace, pro-
vides them to the sub-agent, receives the results, and stores results and logs in the Workspace. Right:
the sub-agent inventory, grouped by capability.
An Agentic AI Scientific Community for Automated Neural Operator Discovery
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页
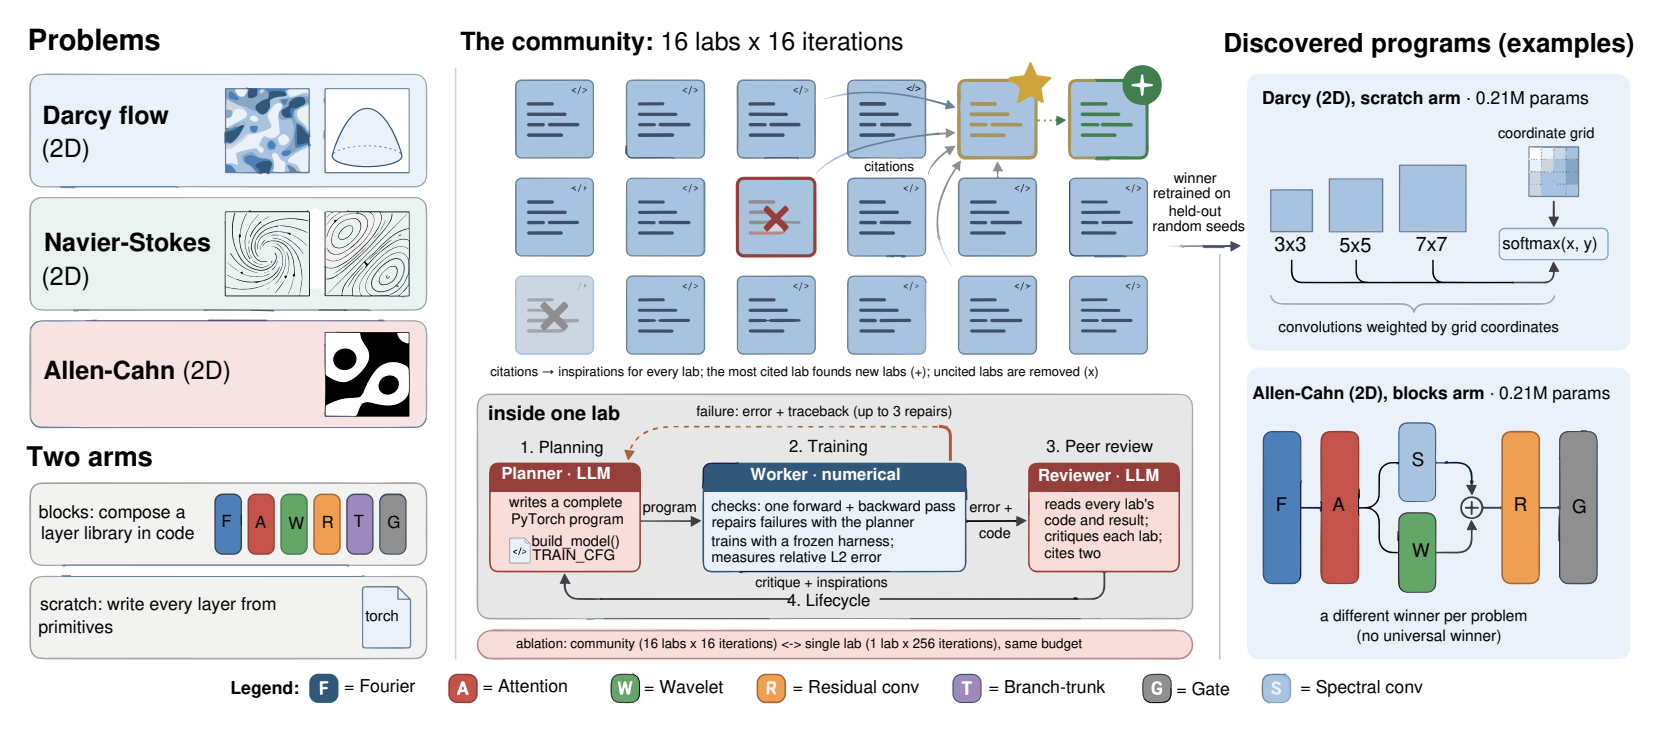
300 dpi PNG · 图注 · 原始PDF
风格入选理由:三栏容器、成阵列文档卡、星标与勾叉、内嵌三阶段说明,浅蓝/浅粉/灰绿组合。
图1及引言展示问题输入、16实验室交互、单实验室循环和发现的程序输出。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 256],PDF点、左上角原点。
Figure 1: The neural operator AI scientific community: the three problems and the two arms (left), a
community of 16 labs and the four phases of each iteration inside a lab (center), and two discovered
programs (right). Every winning program is retrained on held-out random seeds before it is compared
with other models.
Sprout: Building Dynamic Memory While Reasoning for Agentic Video Understanding
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页
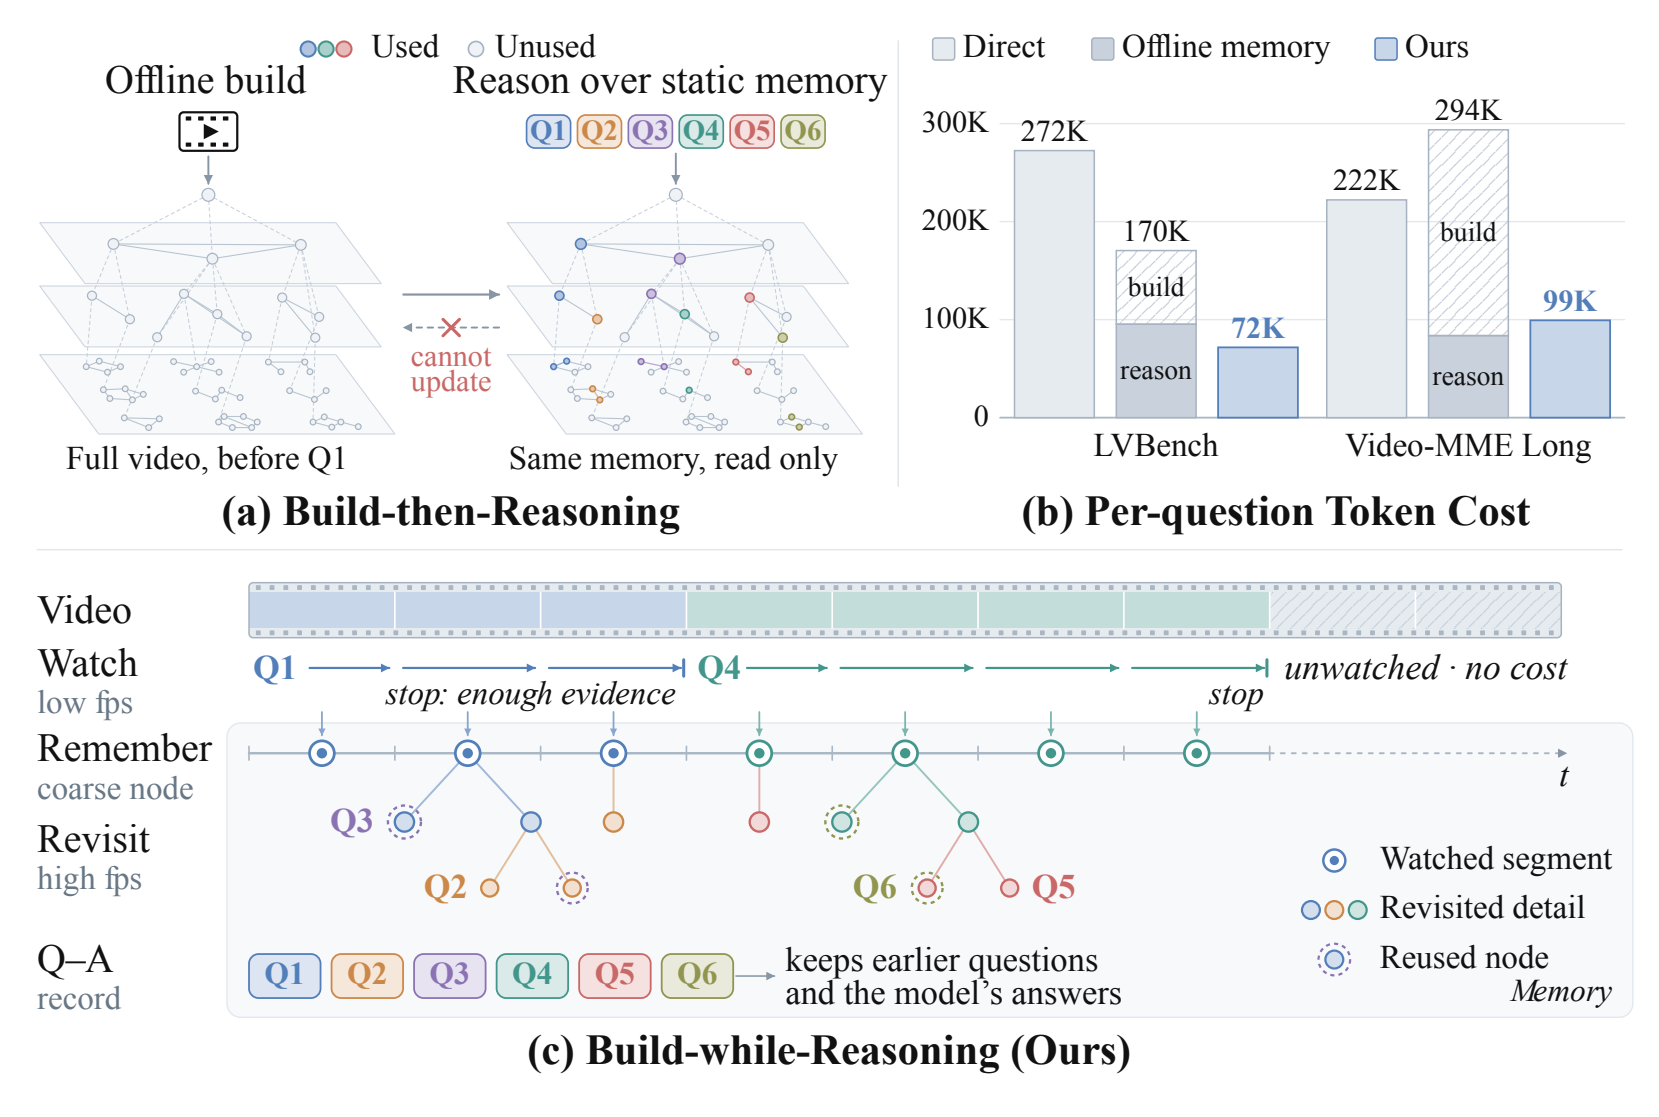
300 dpi PNG · 图注 · 原始PDF
风格入选理由:(a)(b)(c)堆叠结构、浅蓝浅绿时间轴与节点卡、短说明列表及视频/问答小图标。
引言图1对比离线构建静态记忆与推理时动态构建,解释旧方案无法更新与成本问题;保留同图性能面板。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。作者披露生成式AI参与图与表的起草、编辑,未指明具体工具或图号。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 348],PDF点、左上角原点。
Figure 1: (a) Offline memory is first built for the whole video before the first question; Q1–Q6 then
reason over the same memory without updating it. Nodes used by a question take that question’s
color, and the rest are never touched. (b) Per-question tokens with Gemini 3.8 Flash as the model.
Direct feeds the video and question directly to the model. Offline memory is Qwen-MM-Plugins:
its construction cost, amortized over the benchmark’s questions. Our method has no construction
stage. (c) Sprout builds memory while reasoning. The agent watches the video segment by segment
at a low frame rate and stops once the question has enough evidence, so the tail of the video is never
watched and costs nothing. Each watched segment is remembered as a coarse textual node written
into memory; revisits at a higher frame rate add child nodes beneath the intervals a question needs.
Sprout: Building Dynamic Memory While Reasoning for Agentic Video Understanding
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第5页
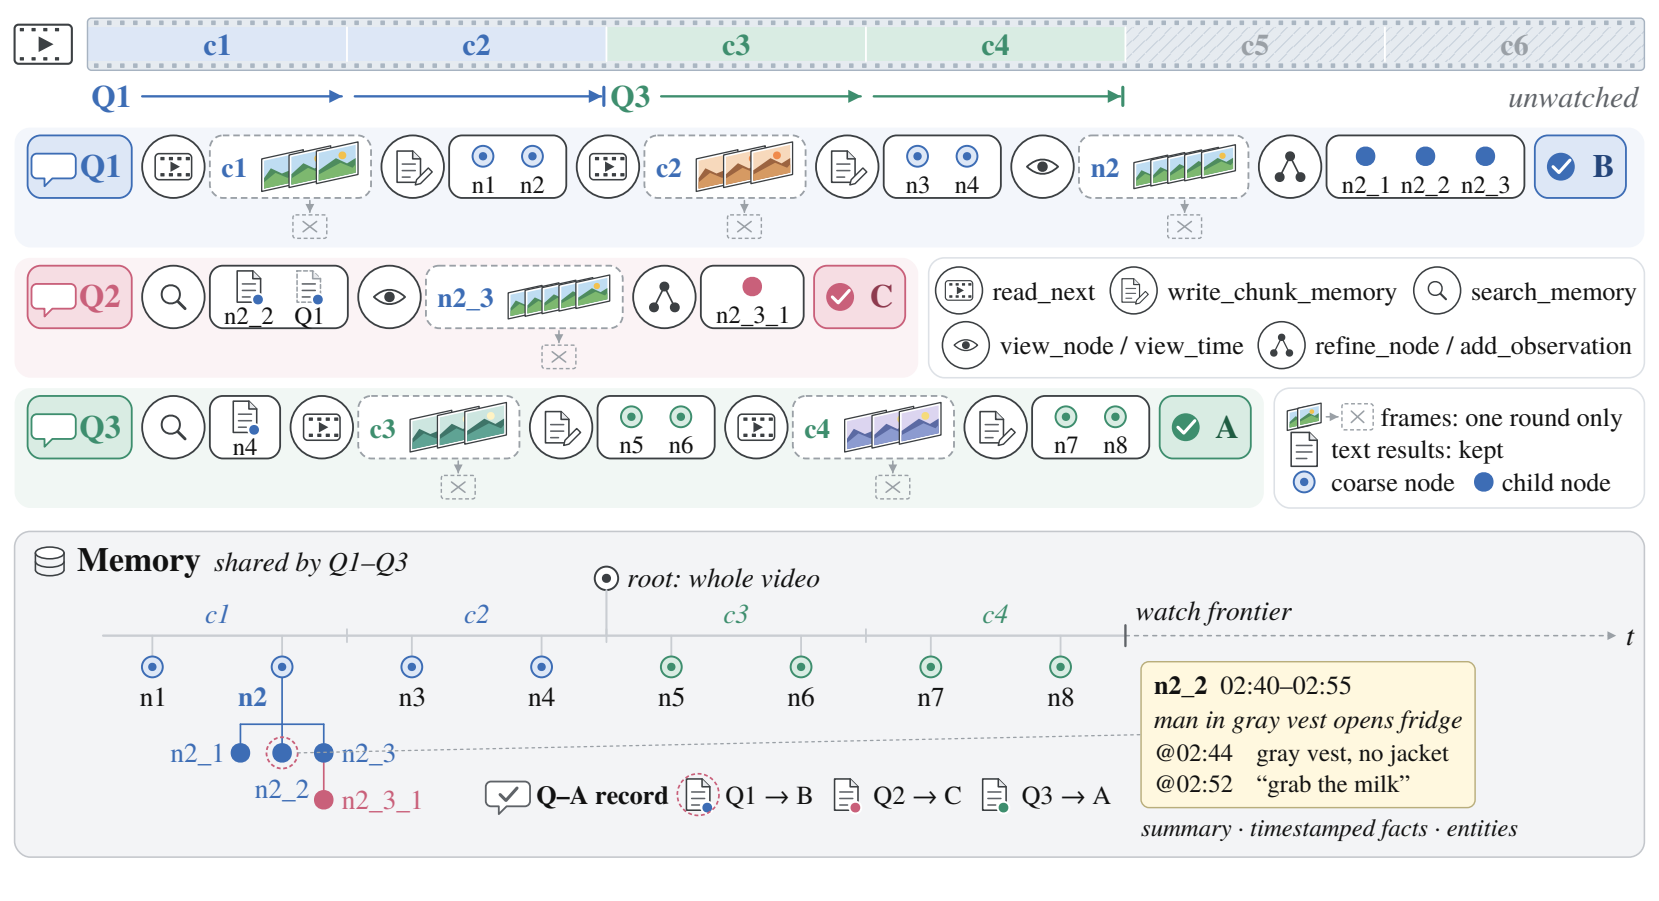
300 dpi PNG · 图注 · 原始PDF
风格入选理由:三层问答条带与下方记忆面板堆叠,大量工具圆形图标、节点框、文本便签,采用蓝粉绿浅色。
图2与方法正文给出连续三轮问题处理、工具调用及共享记忆的整体流程。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。作者披露生成式AI参与图与表的起草、编辑,未指明具体工具或图号。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 296],PDF点、左上角原点。
Figure 2: Pipeline of Sprout. Three questions about one video are answered in order, building one
memory. Each row shows the rounds of one question: tool calls (circles) and their results (boxes).
Video frames stay in the context for one round only; text results are kept. Q1 watches the first two
chunks, remembers them as coarse nodes, and revisits n at a higher frame rate to add finer child
2
nodes. Q2 reuses the memory: search returns a node and Q1’s answer, and a short revisit adds one
more detail, without watching new video. Q3 finds that the memory does not cover what it asks, so
it watches two more chunks. The last two chunks are never watched. The memory tree (bottom) is
drawn on the same time axis as the video; node colors show which question added each node.
MatGym: An Agent-Centric Environment Bridging Materials Discovery and Reproducible Synthesis
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第4页
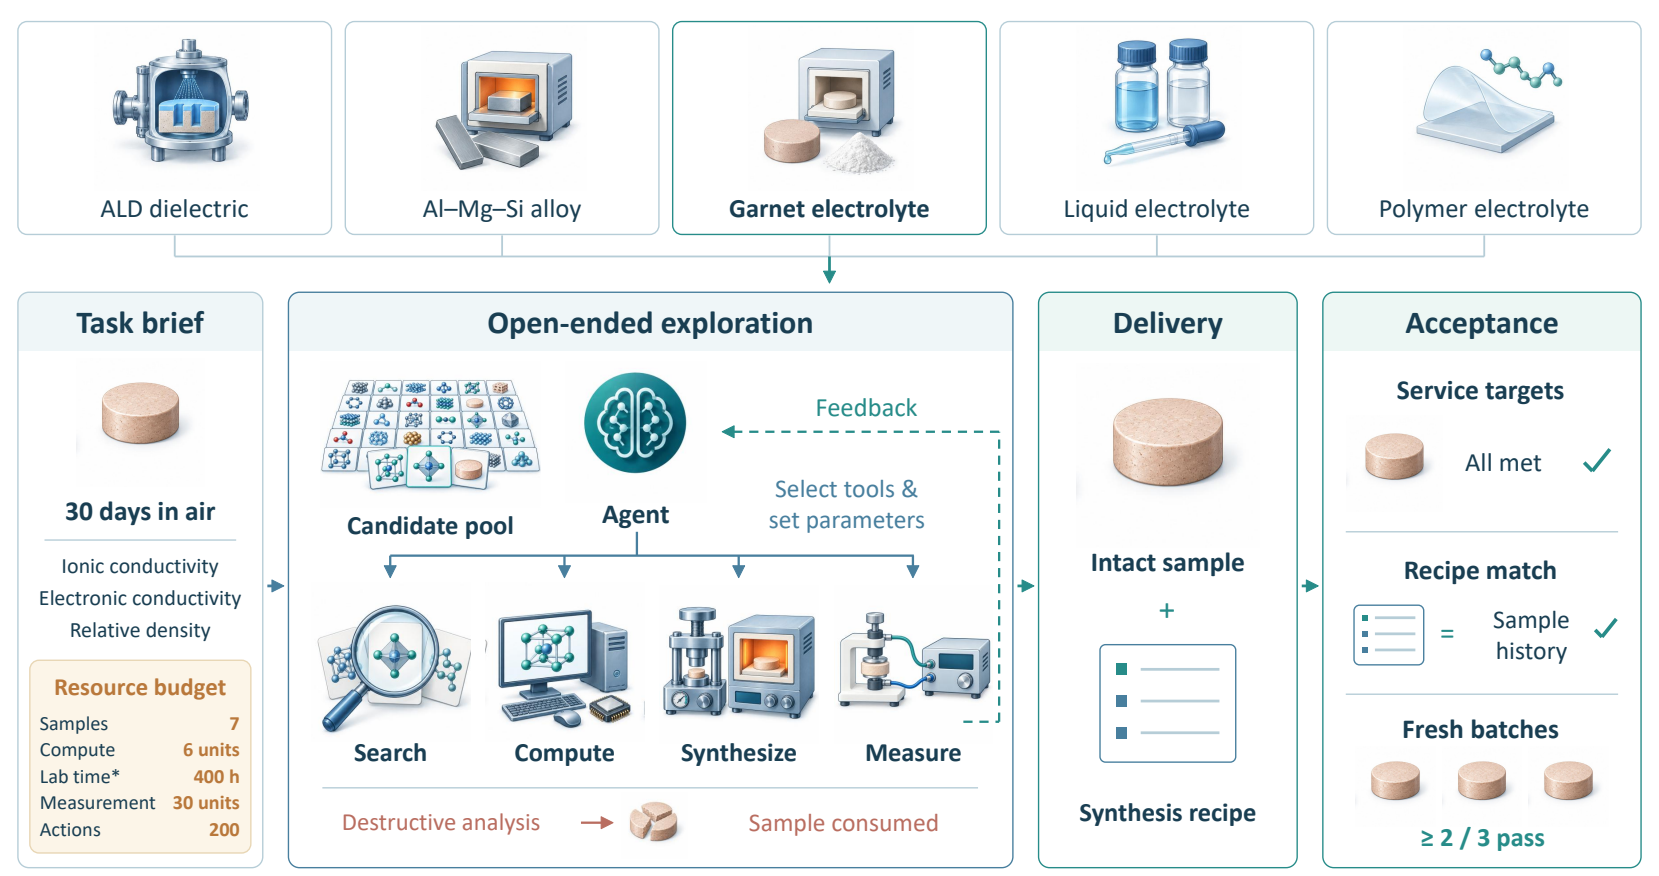
300 dpi PNG · 图注 · 原始PDF
风格入选理由:上排五种实验室图标卡,下排四列流程容器,内含设备/大脑/清单图标、资源文本和浅青橙粉分区。
图1与3.1节展示任务、开放探索、样品交付与验收的完整环境交互。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 290],PDF点、左上角原点。
Figure 1: Overview of MatGym. Across five simulated laboratories, agents explore candidates and
adapt tool use to feedback under resource budgets, then deliver a sample and its synthesis recipe.
Acceptance requires service performance, recipe–history consistency, and success on at least two of
three fresh batches. An earlier garnet task is shown. *Lab time excludes the simulated storage wait.
EmboScope: A Multi-Source Comprehensive Benchmark for Embodied Perception, Understanding, and Planning
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第4页
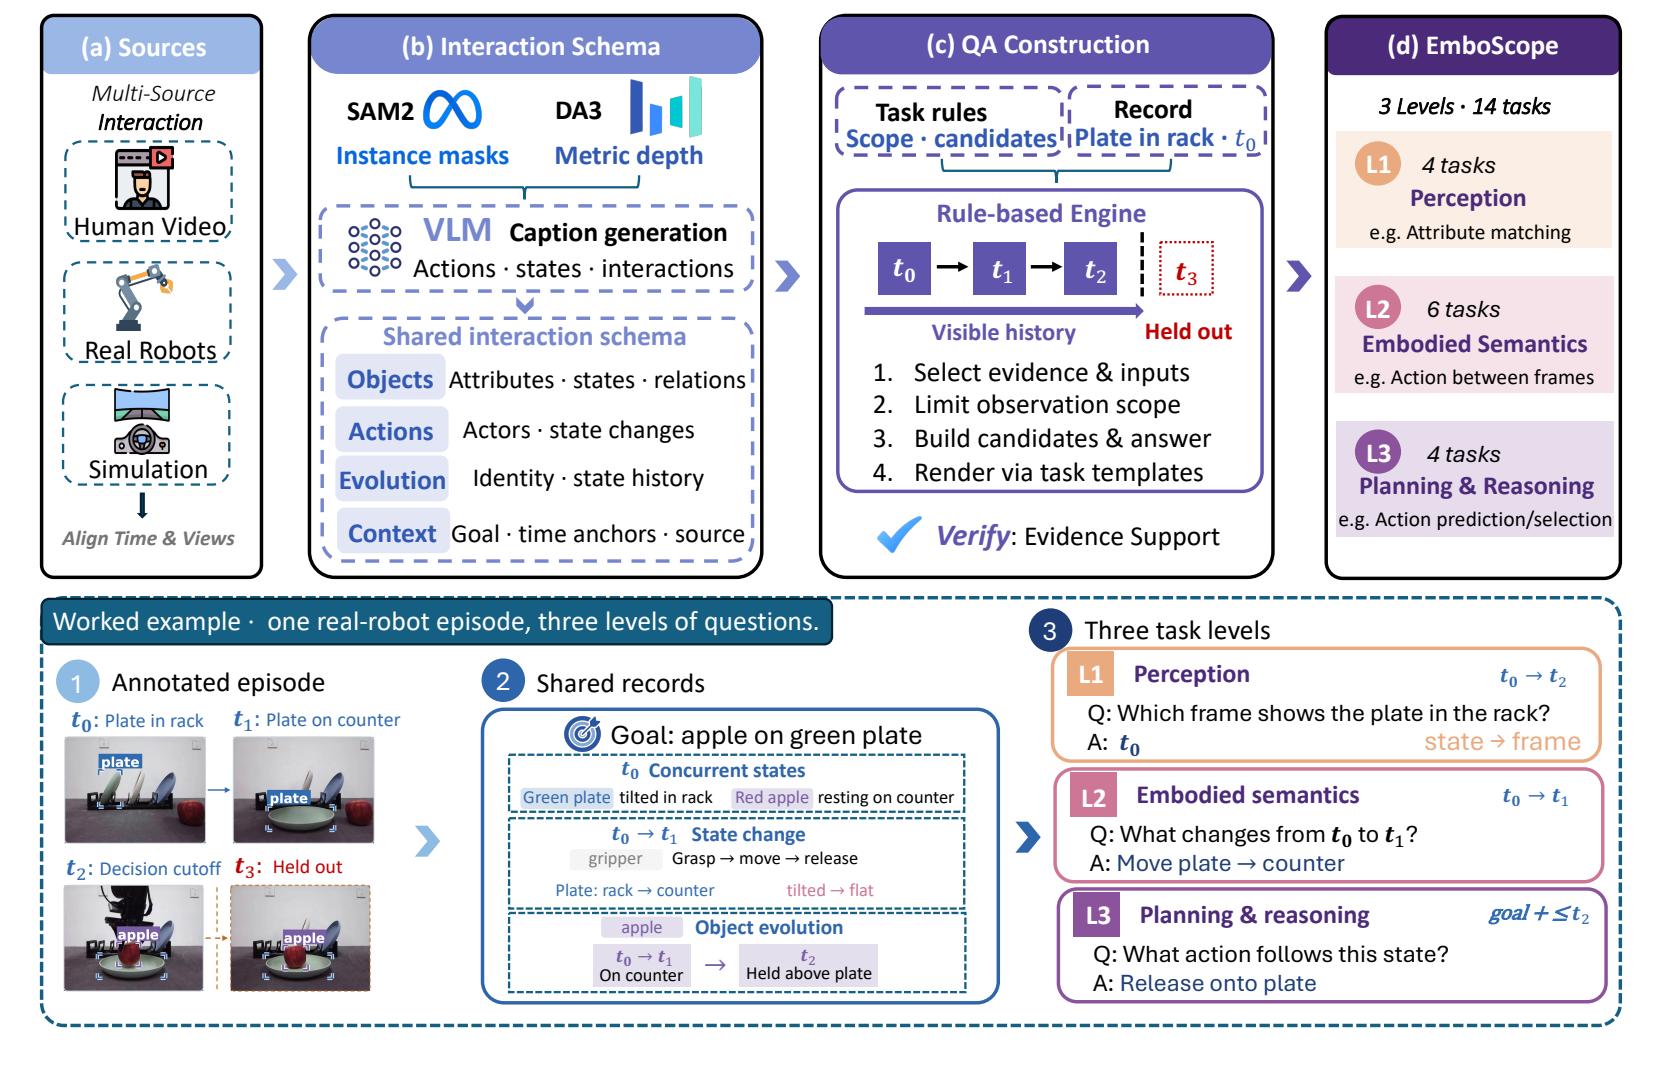
300 dpi PNG · 图注 · 原始PDF
风格入选理由:(a)–(d)四列与下方实例带组合,多重虚线框、问答文本、任务图标及浅蓝紫橙配色。
图1与3.1节为多源数据、交互模式、QA构建及评测层级的全流程。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。作者披露生成式AI辅助figure preparation,未指明具体工具或图号。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 339],PDF点、左上角原点。
Figure 1: Constructing EmboScope from shared interaction schemas with a rule-based engine.
Bottom: Illustrative annotations and QA at three capability levels from one real episode. L3 observes t₀–t₂; t₃ is held out.
MemVista: Benchmarking Long-Term Memory for Multimodal Agents in Evolving Projects
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第5页
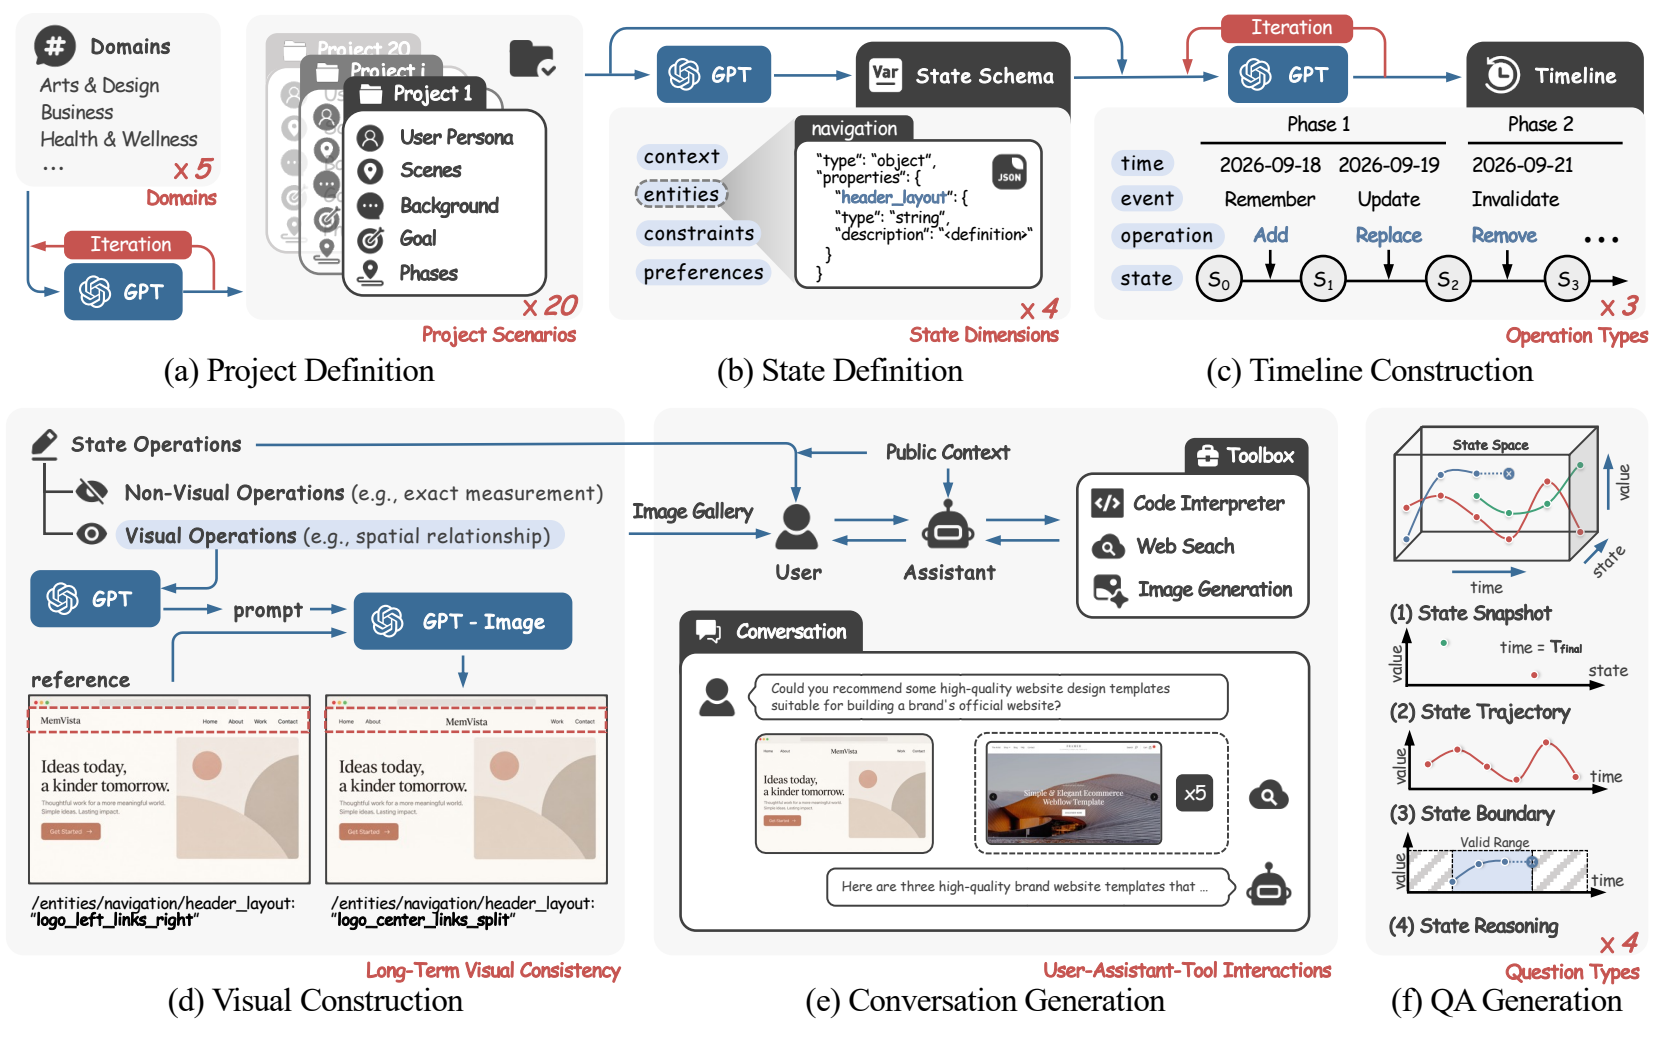
300 dpi PNG · 图注 · 原始PDF
风格入选理由:(a)–(f)两排多面板,密集schema/对话文本、文件/工具/人物图标、圆角框;灰蓝浅底为主。
图2与第四节展示项目、状态、时间线、视觉、对话到问题的完整基准构建流程。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 333],PDF点、左上角原点。
Figure 2: Overview of the MEMVISTA construction pipeline. Project scenarios and state schemas
define the setting, while state operations specify its evolution. Images and turn-by-turn user–agent
interactions realize this progression as multimodal histories. The completed histories and validated
state records support four task families: snapshot, trajectory, boundary, and reasoning.
OmniClinic: Evaluating Active Evidence Acquisition in a Multimodal Clinical Sandbox
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页
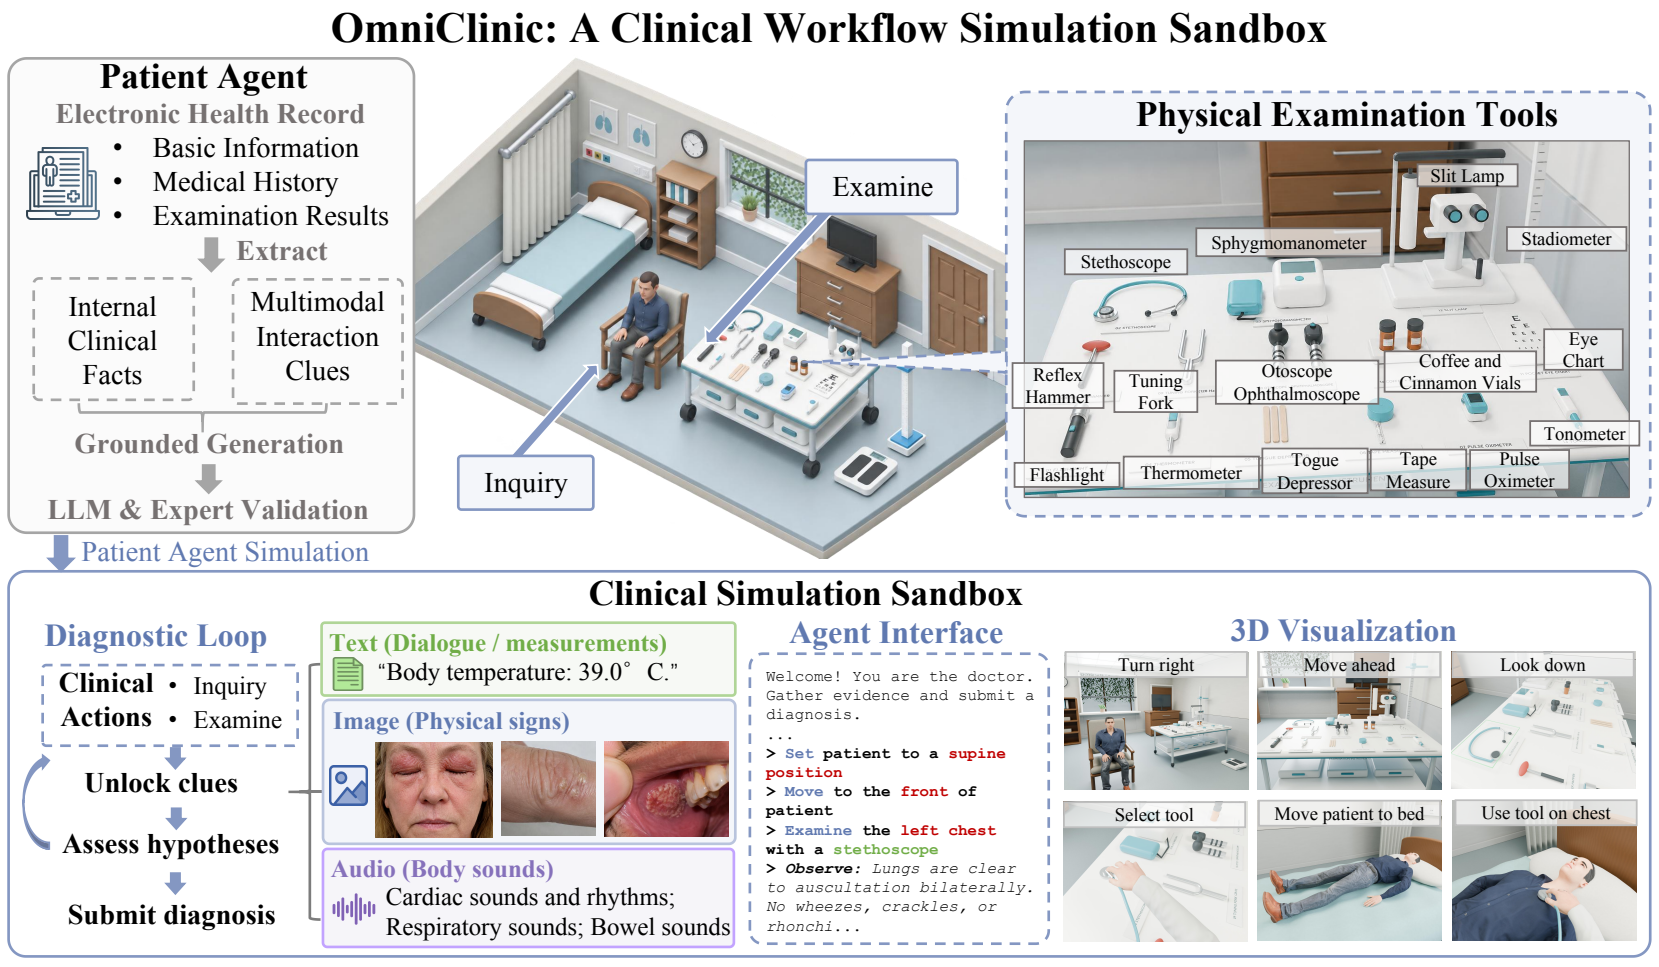
300 dpi PNG · 图注 · 原始PDF
风格入选理由:病房三维示意、工具图标矩阵和多层框并置,下层多列证据与代码描述,浅蓝浅紫框底。
图1及引言明确展示患者代理、检查工具和临床模拟沙盒的整体关系与操作路径。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 312],PDF点、左上角原点。
Figure 1: Overview of OmniClinic. Each electronic health record instantiates a patient agent and
defines the case evidence. The sandbox exposes a finite action space spanning clinical consultation
and bedside physical examinations with common clinical tools. The doctor agent selects among these
actions to acquire multimodal evidence before submitting a diagnosis. Examination succeeds only
with the appropriate tool, body region, patient pose, and doctor (agent) position.
DUDA-Bench: Benchmarking LLM Agents on Multimodal Data-Driven Urban Diagnosis
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第3页
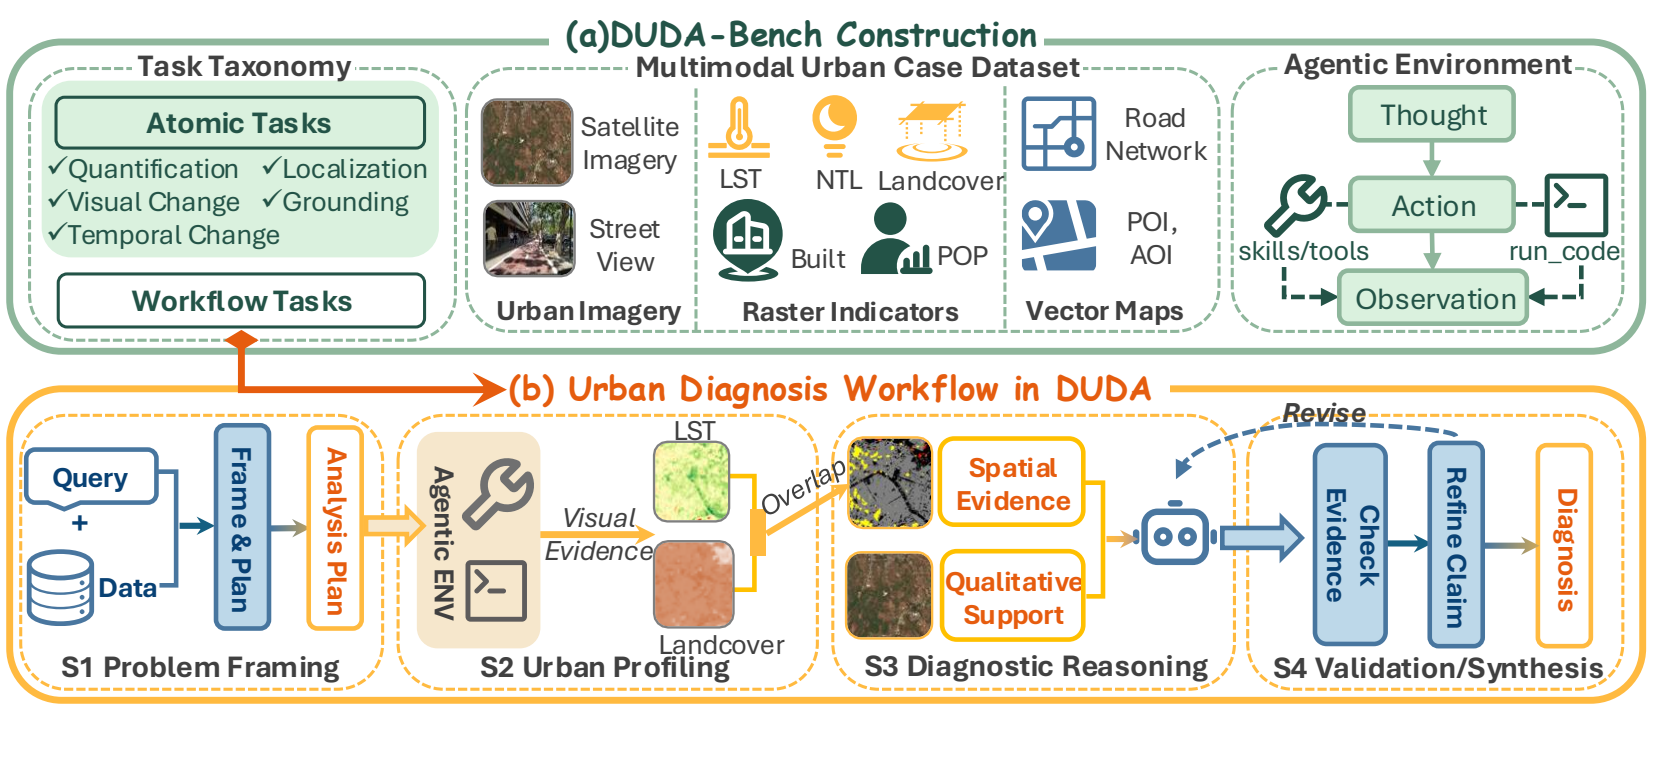
300 dpi PNG · 图注 · 原始PDF
风格入选理由:(a)(b)上下大框嵌套多列小卡,数据/地图/工具/机器人图标密集,浅绿、浅橙、浅蓝组合。
图1及第三节给出基准构成与四阶段城市诊断完整工作流。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:9 · 声明原文记录
裁剪位置:[107, 80, 505, 267],PDF点、左上角原点。
Figure 1: Overview of DUDA-Bench. The benchmark connects a hierarchical task taxonomy and
multimodal urban case dataset with an interactive agent environment, and formulates urban diagno-
sis as a four-stage analytical workflow.
When Should AI Chime In? Benchmarking Timely Contribution of Proactive Agents in Multi-Party Chat
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页
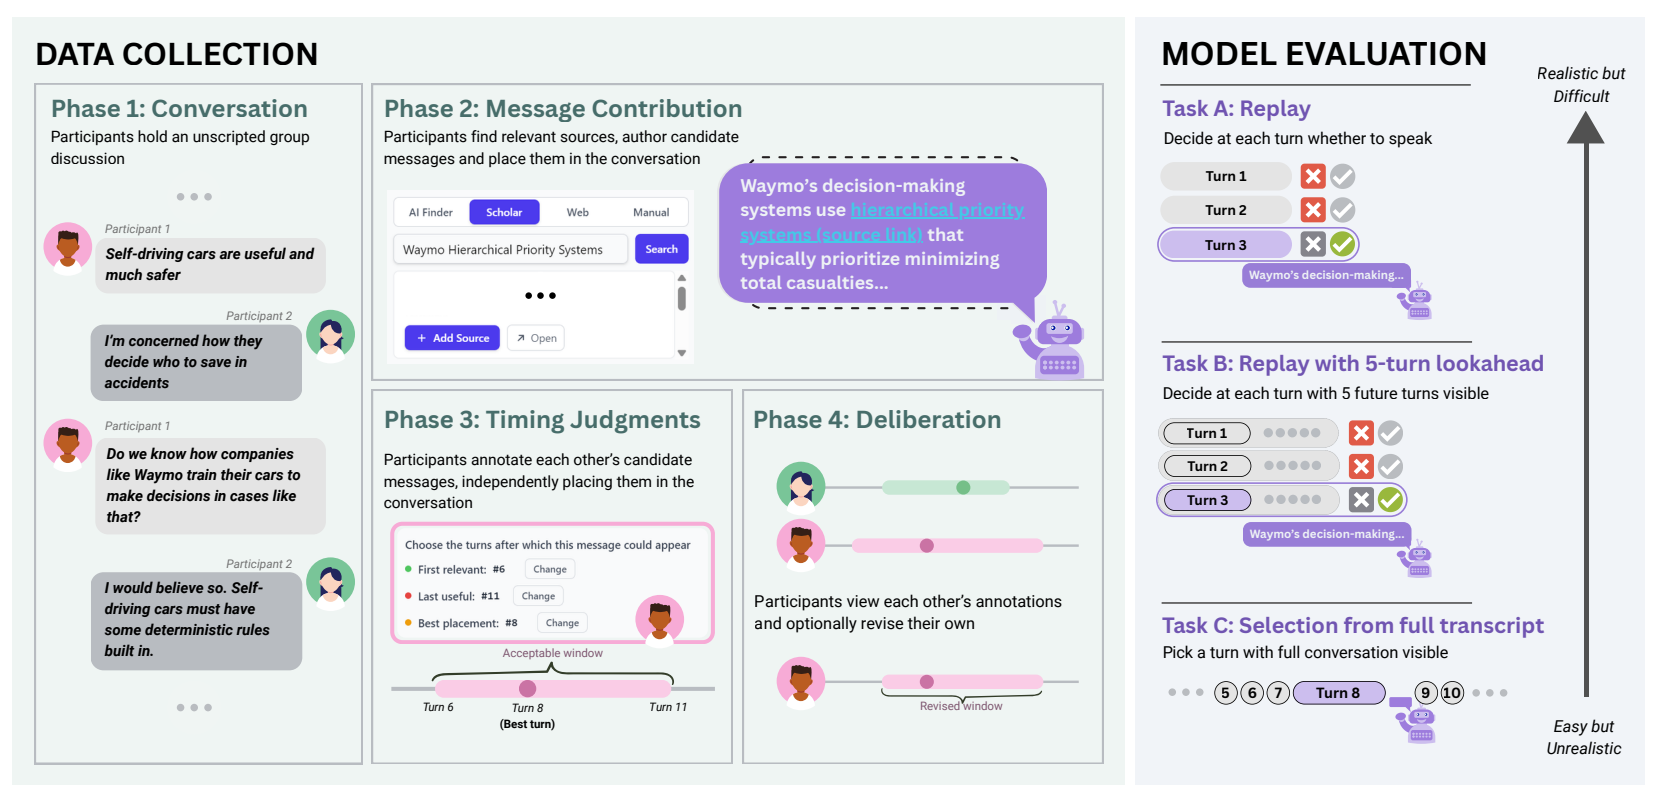
300 dpi PNG · 图注 · 原始PDF
风格入选理由:四个Phase文本卡加右侧Task列,多层聊天气泡、人物头像与机器人图标,浅青/紫/粉配色。
图1及引言说明四阶段数据收集协议和三种模型评测设置,属于整体研究流程。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 269],PDF点、左上角原点。
Figure 1: PITCH (Proactive Intervention Timing in CHat) is the first benchmark for proactive inter-
vention timing built from unscripted human conversations and participants’ own judgments of when
proactive interjections should occur. We collected the benchmark data via a four-phrase protocol:
Conversation, Message Contribution, Timing Judgments, and Deliberation. We then evaluated 15
models across 28 configurations against the benchmark in three task setups that differ in their task
difficulty and realism for real-world deployment of agents in group conversations.
LEGO-Anything: Coding Agents for 3D Scene Reconstruction
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页
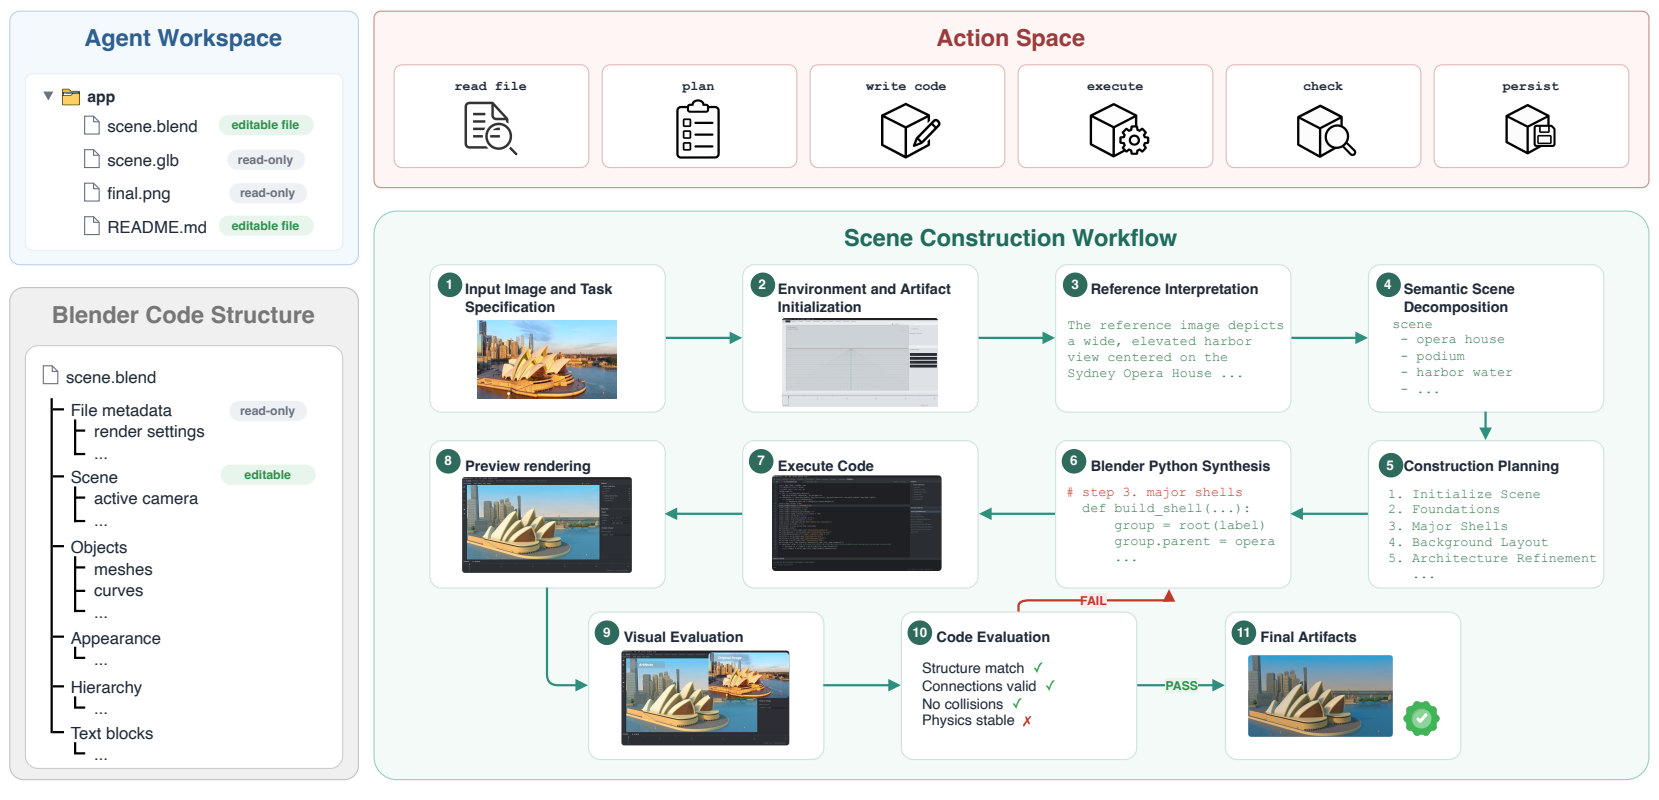
300 dpi PNG · 图注 · 原始PDF
风格入选理由:顶部动作图标条、左侧树形代码框、右侧多行编号流程卡叠置,长文本说明配浅粉/浅青/浅灰。
第三节及图2将完整场景构建轨迹抽象为工作区、动作空间、代码结构和构建流程。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 272],PDF点、左上角原点。
Figure 2: Agentic scene construction, abstracted from a GPT-6-astra trajectory: workspace,
action space, Blender code structure, and construction workflow.
Topological Coherence for Self-Evolving Multi-Agent Systems
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页
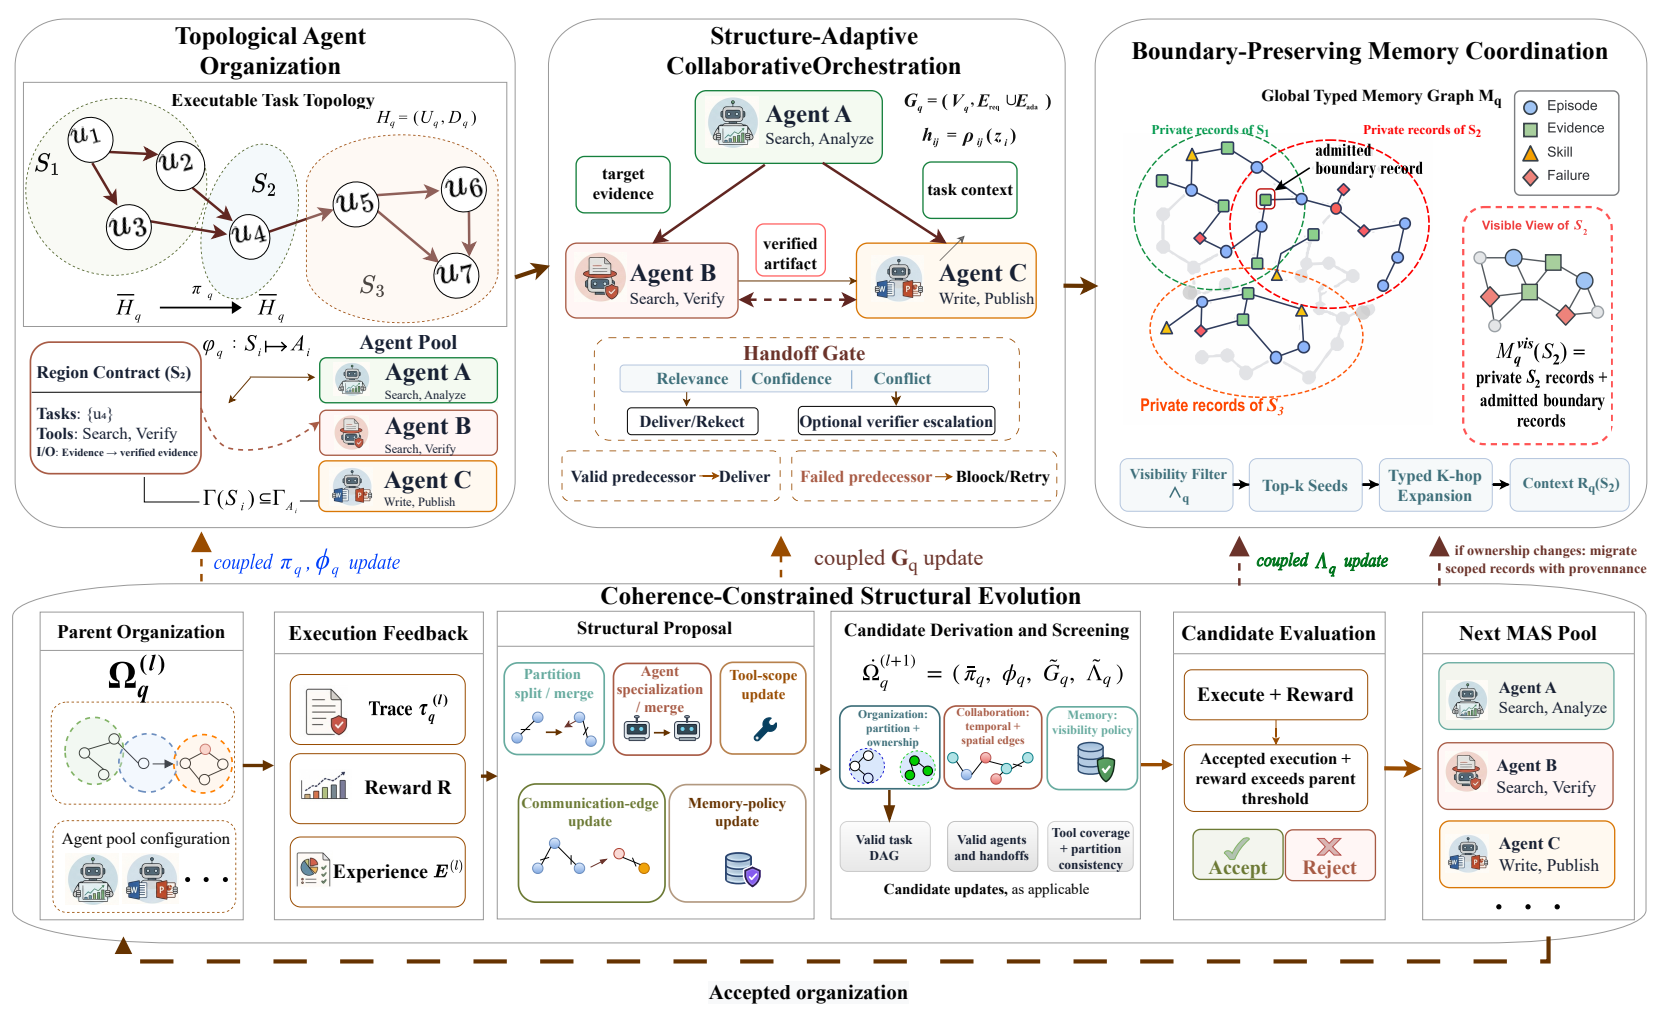
300 dpi PNG · 图注 · 原始PDF
风格入选理由:上下两层容器嵌套大量代理卡、图结构、文档/工具图标,细密解释文本配浅绿橙紫。
正文第3页明确称图2展示四个模块的整体构建与演化。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 324],PDF点、左上角原点。
Figure 2: Overview of TOCOMAS. Task-derived responsibility regions organize agents, handoffs,
and memory boundaries; online evolution preserves their coherence.
Harmony Harness: Multi-Objective Self-Evolution of Agent Harnesses
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第4页
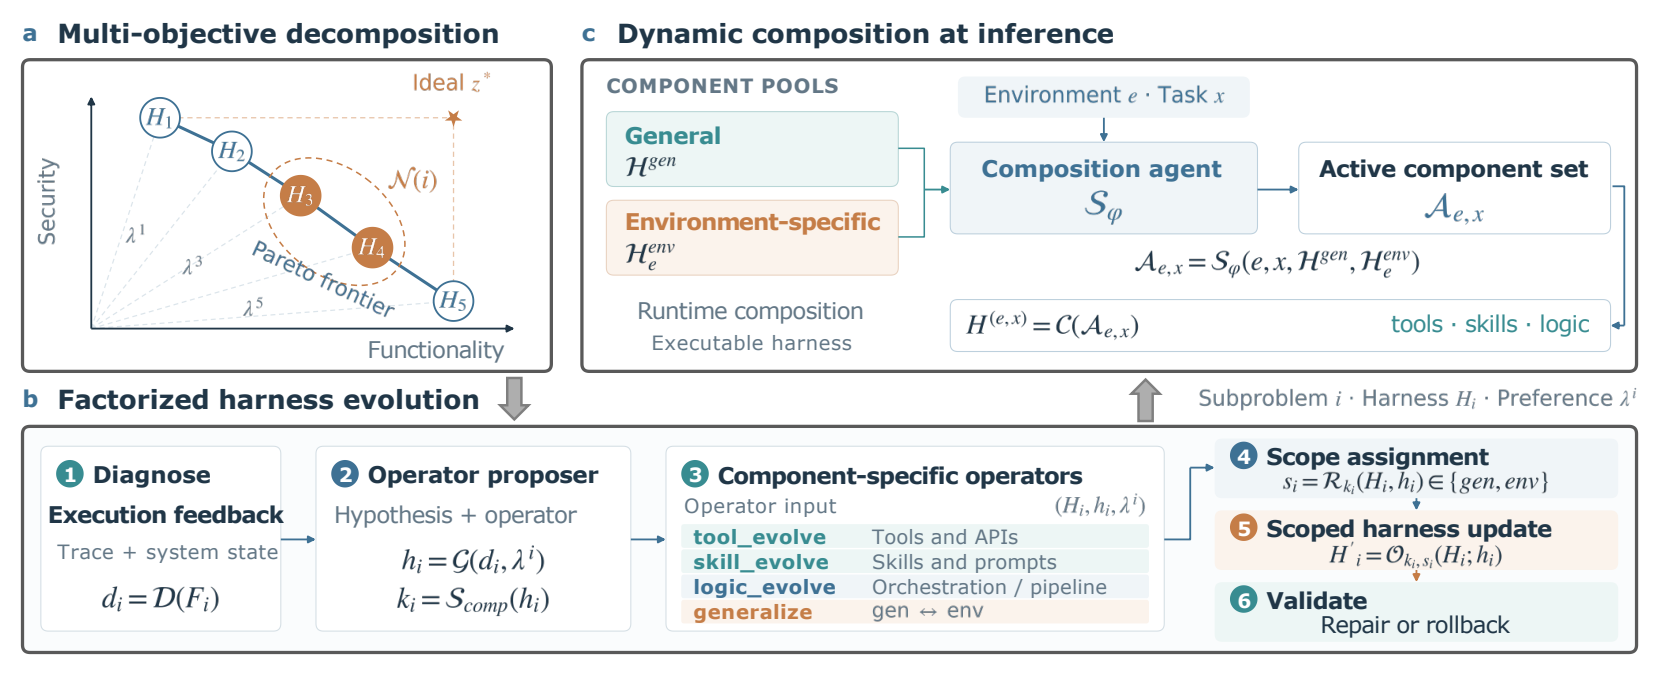
300 dpi PNG · 图注 · 原始PDF
风格入选理由:a/b/c三个面板,多层浅蓝浅橙卡片、六个编号步骤与列表式说明;装饰图标较少。
方法节称图1为完整演化循环,含分解、更新、推理时组合。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 242],PDF点、左上角原点。
Figure 1: Overview of HARMONY HARNESS. (a) The functionality–security space is split into
weighted subproblems. Each subproblem keeps a harness and together they approximate the Pareto
frontier. (b) An LLM proposer diagnoses failures and forms a hypothesis. Operators edit tools, skills,
or logic, and place each edit in either the general scope or the environment-specific scope. The child
is validated before evaluation. (c) At inference, a composition agent picks components from the
general and environment-specific pools to build a task-specific harness.
BodyBound: A Benchmark for Diagnosing Robot-Policy Responses to Body Changes Beyond Task Success
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页
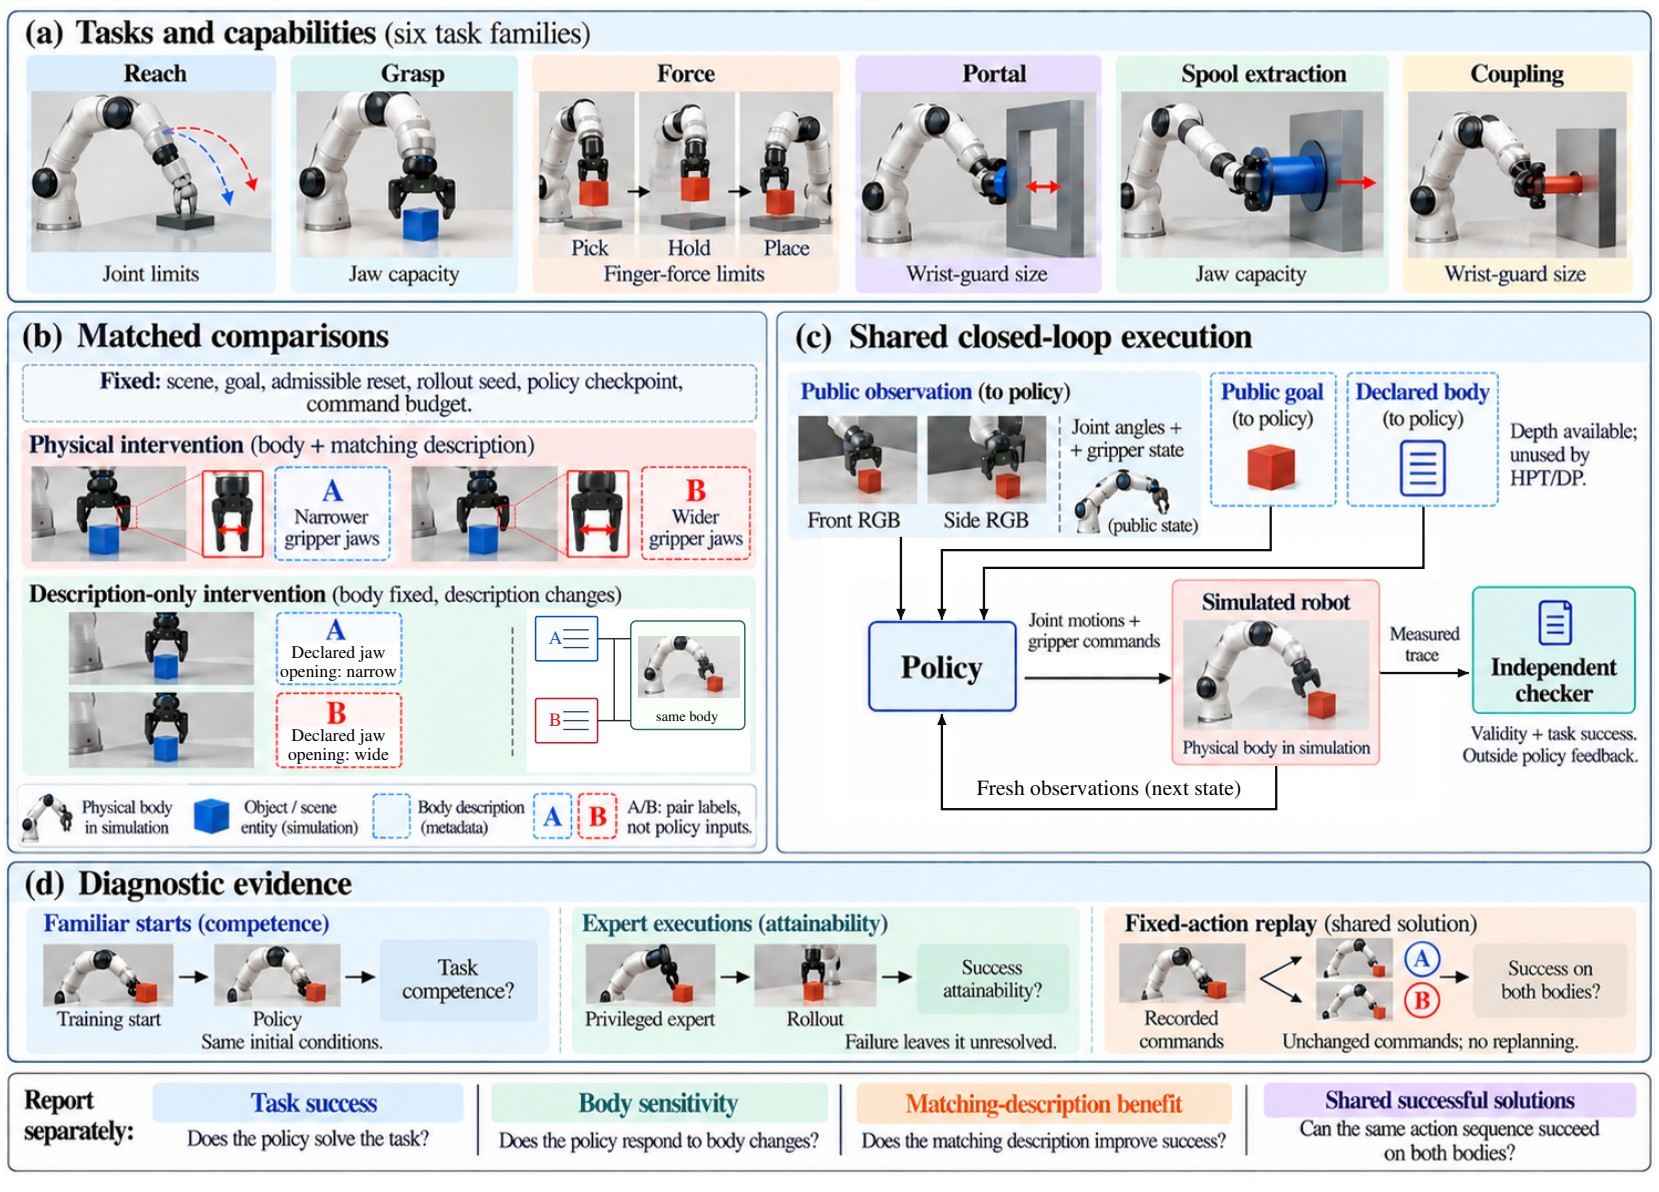
300 dpi PNG · 图注 · 原始PDF
风格入选理由:(a)–(d)层叠浅色面板、机器人示意与文档/盾牌图标、密集比较说明和嵌套框。
图1及引言展示任务、成对干预、闭环执行与独立诊断的完整基准流程。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。作者声明本研究未使用生成式AI;未披露具体非AI绘图工具。
披露页:8 · 声明原文记录
裁剪位置:[107, 80, 505, 366],PDF点、左上角原点。
Figure 1: BodyBound in simulation. (a) Task schematics show six families and their intervened
body parameters. (b) Paired comparisons change the physical body with its matching description,
or the description alone. (c) Policies act from public observations, goals, and body descriptions;
fresh observations close the loop, while an independent checker evaluates measured traces. HPT
and Diffusion Policy use RGB, not depth. (d) Familiar starts, expert executions, and unchanged-
command replay separate task competence, attainability, and shared solutions. Scene geometry
stays fixed within each pair.
CUAWright: A Minimal Unified Interface for Computer Use Agents
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第3页
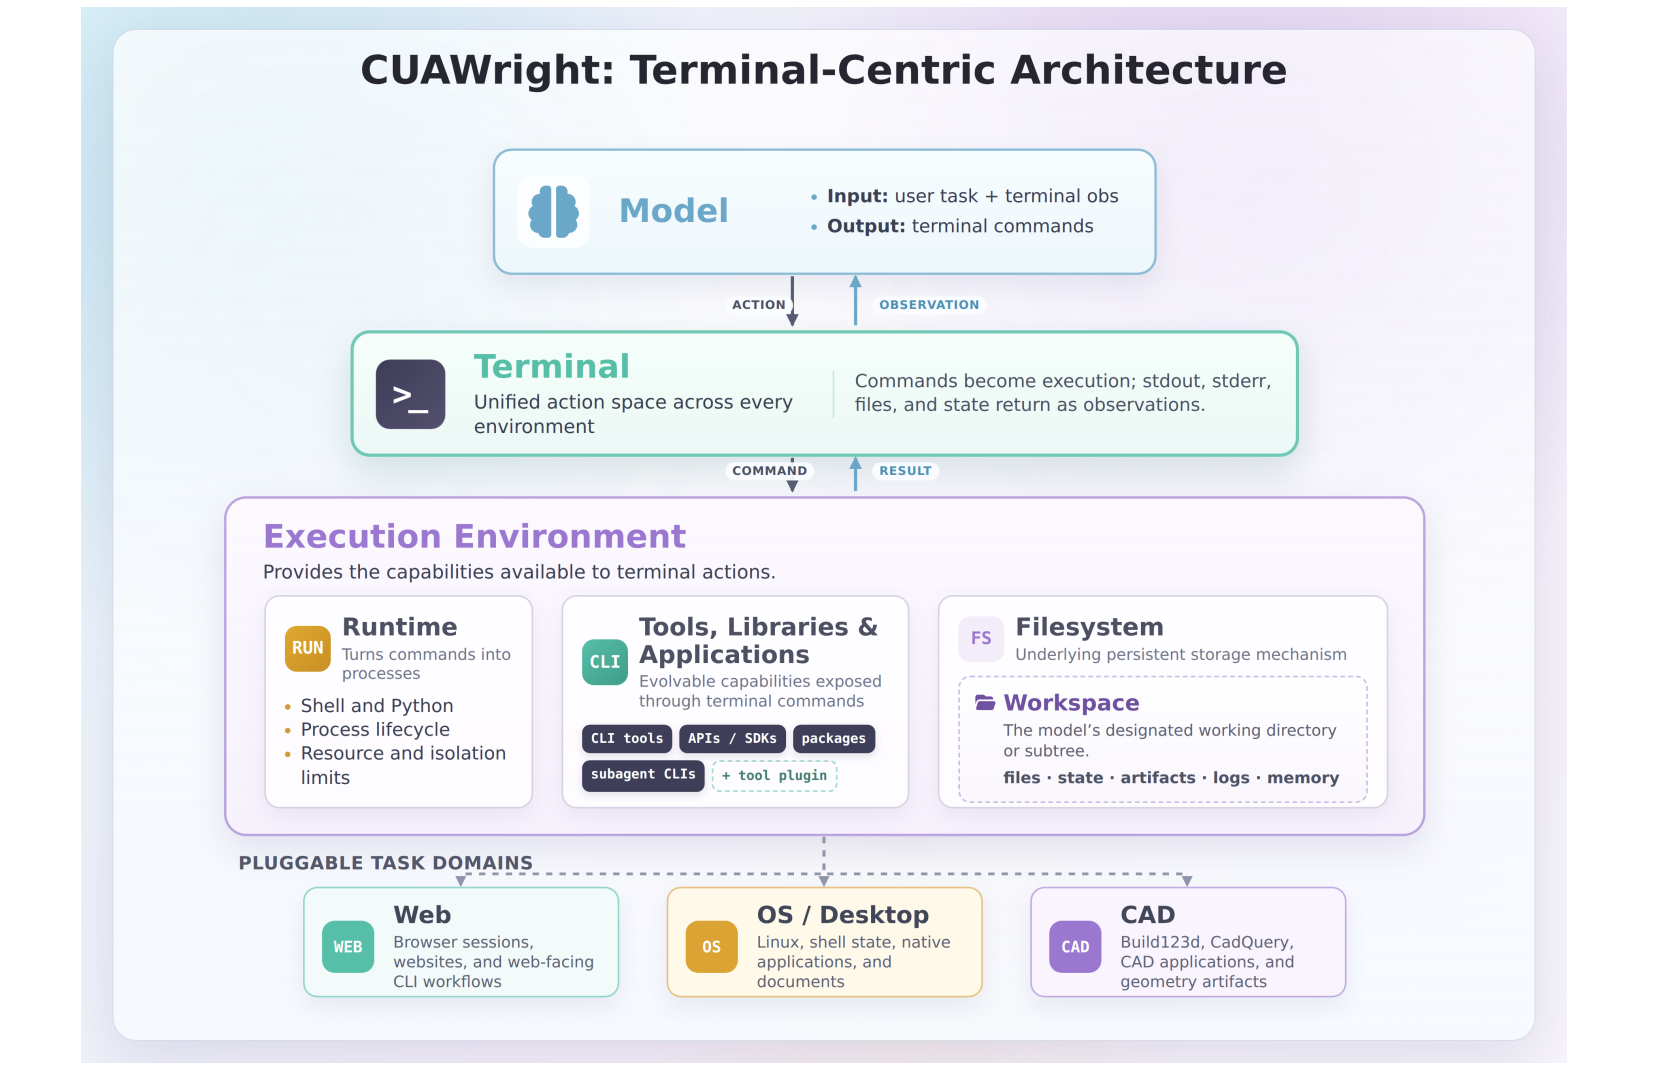
300 dpi PNG · 图注 · 原始PDF
风格入选理由:渐变浅蓝紫背景、多层圆角卡片、脑/终端/工具图标与多列说明文本。
第二页引用图2介绍模型—终端—运行环境的整体架构和交互。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:9 · 声明原文记录
裁剪位置:[107, 80, 505, 338],PDF点、左上角原点。
Figure 2: The CUAWright architecture. Terminal serves as the sole interface between the agent
and the task environment. At each step of task execution process, the agent model receives com-
mand line output as observation or call a CLI tool to load image into context on demand, and output
commands that gets executed. The underlying execution environment contains a runtime, an ex-
pandable set of installed CLI tools and applications, and a file system as the agent’s workspace to
programmatically manage system state and craft new tools.
Agent Skills Under Change: A Lifecycle Benchmark and Coordinate-Guided Updates
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页
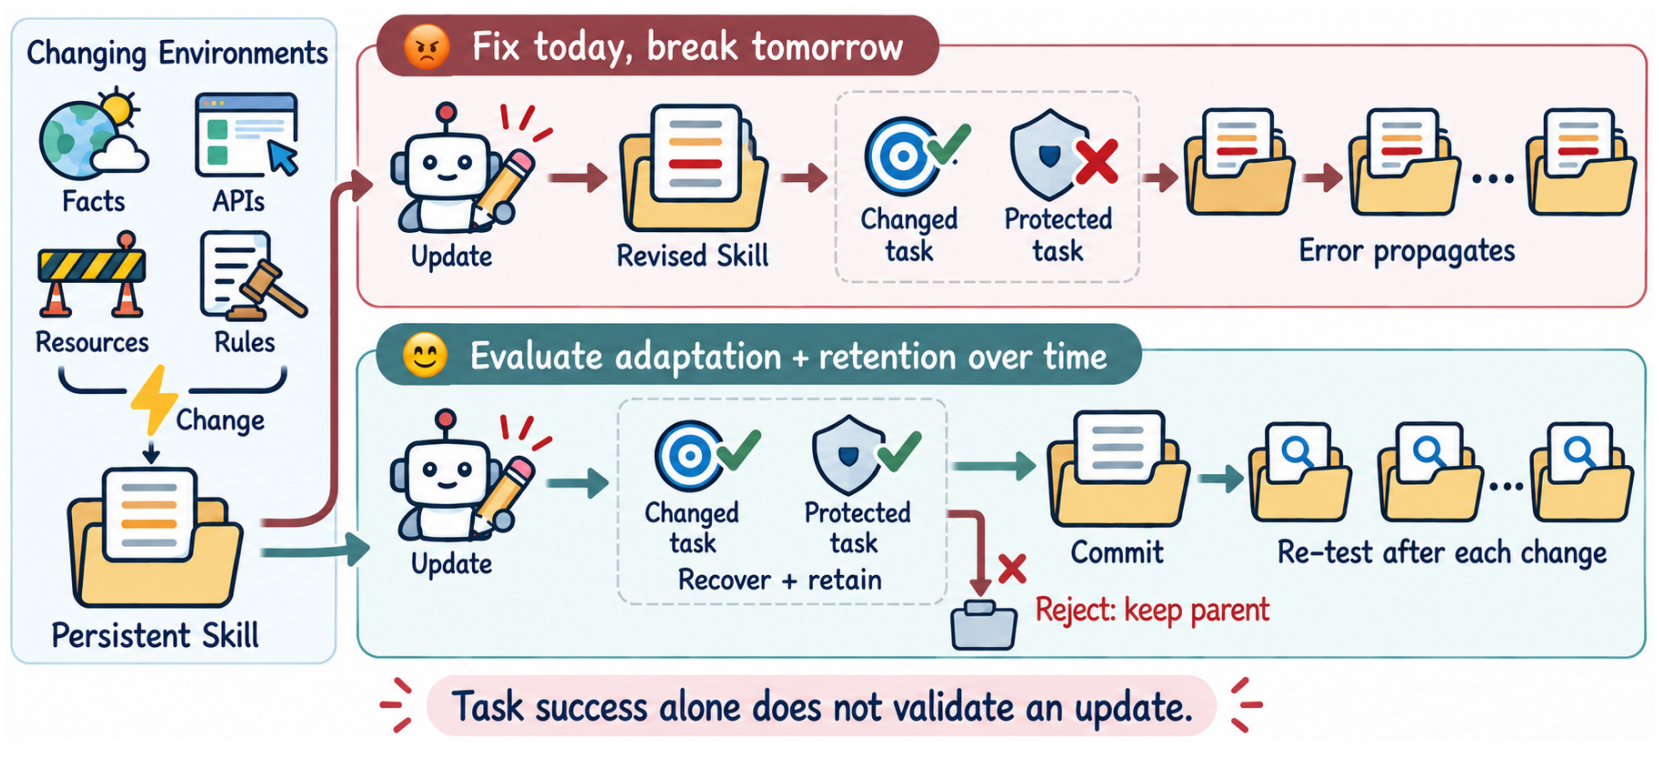
300 dpi PNG · 图注 · 原始PDF
风格入选理由:上下对照大框、多层文件卡、机器人/工具/表情图标,浅蓝粉绿配色与描述标签。
引言图1对比短期修复造成后续错误与持续检查的风险,直接引出问题。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。作者披露生成式AI参与illustrations,未指明具体工具或图号。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 262],PDF点、左上角原点。
Figure 1: Risks across successive Skill updates. An edit can repair the current task while breaking
existing capabilities, with errors persisting into later tasks. Checking recovery and retention after
each change informs whether to adopt the new version.
Agent Skills Under Change: A Lifecycle Benchmark and Coordinate-Guided Updates
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第3页
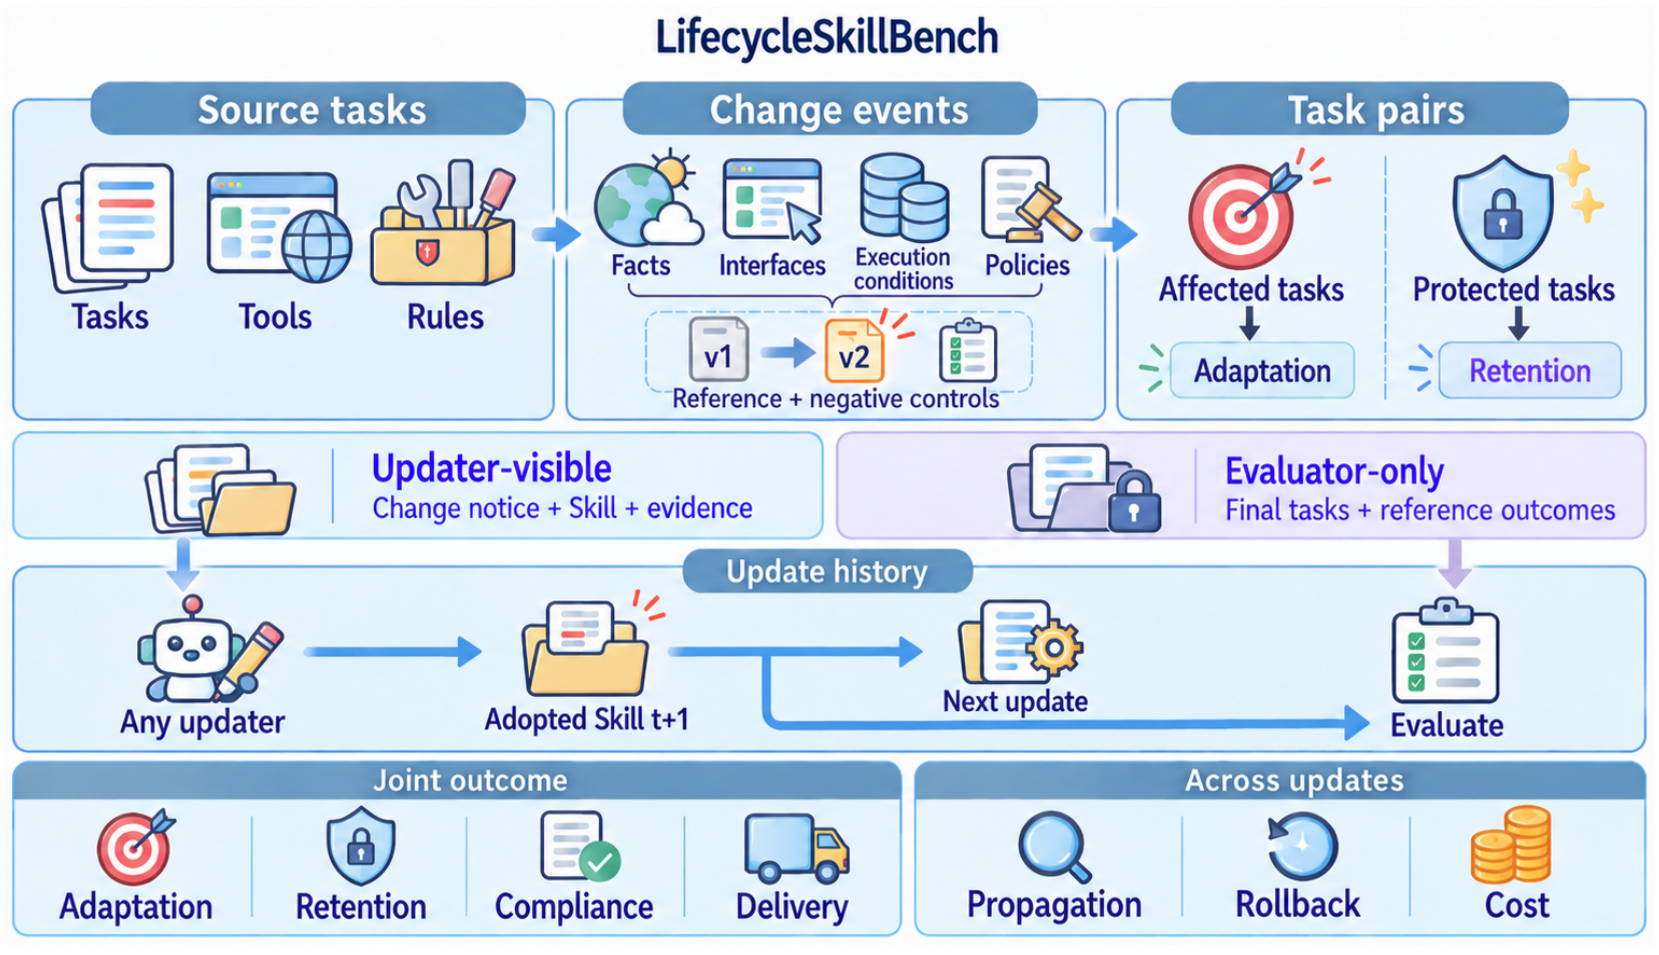
300 dpi PNG · 图注 · 原始PDF
风格入选理由:多排蓝色卡片、密集小图标、紫蓝标签和嵌套列表,构建与评测条带叠置。
图2和第三节说明基准构建、变化事件、任务对、更新记录与评测的整体流程。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。作者披露生成式AI参与illustrations,未指明具体工具或图号。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 309],PDF点、左上角原点。
Figure 2: LifecycleSkillBench construction and evaluation. Public tasks, tools, and rules support re-
producible environmental changes, paired affected and capability-retention tasks, and persistent up-
date histories. The evaluated method receives the change description, pre-update Skill, and available
evidence. The evaluator separately stores test tasks, reference outcomes, and recoverable historical
versions, and reports recovery, retention, error propagation, and execution cost.
Ontology-Harnessing Multi-Agent System for Abstractive Visual Understanding
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页
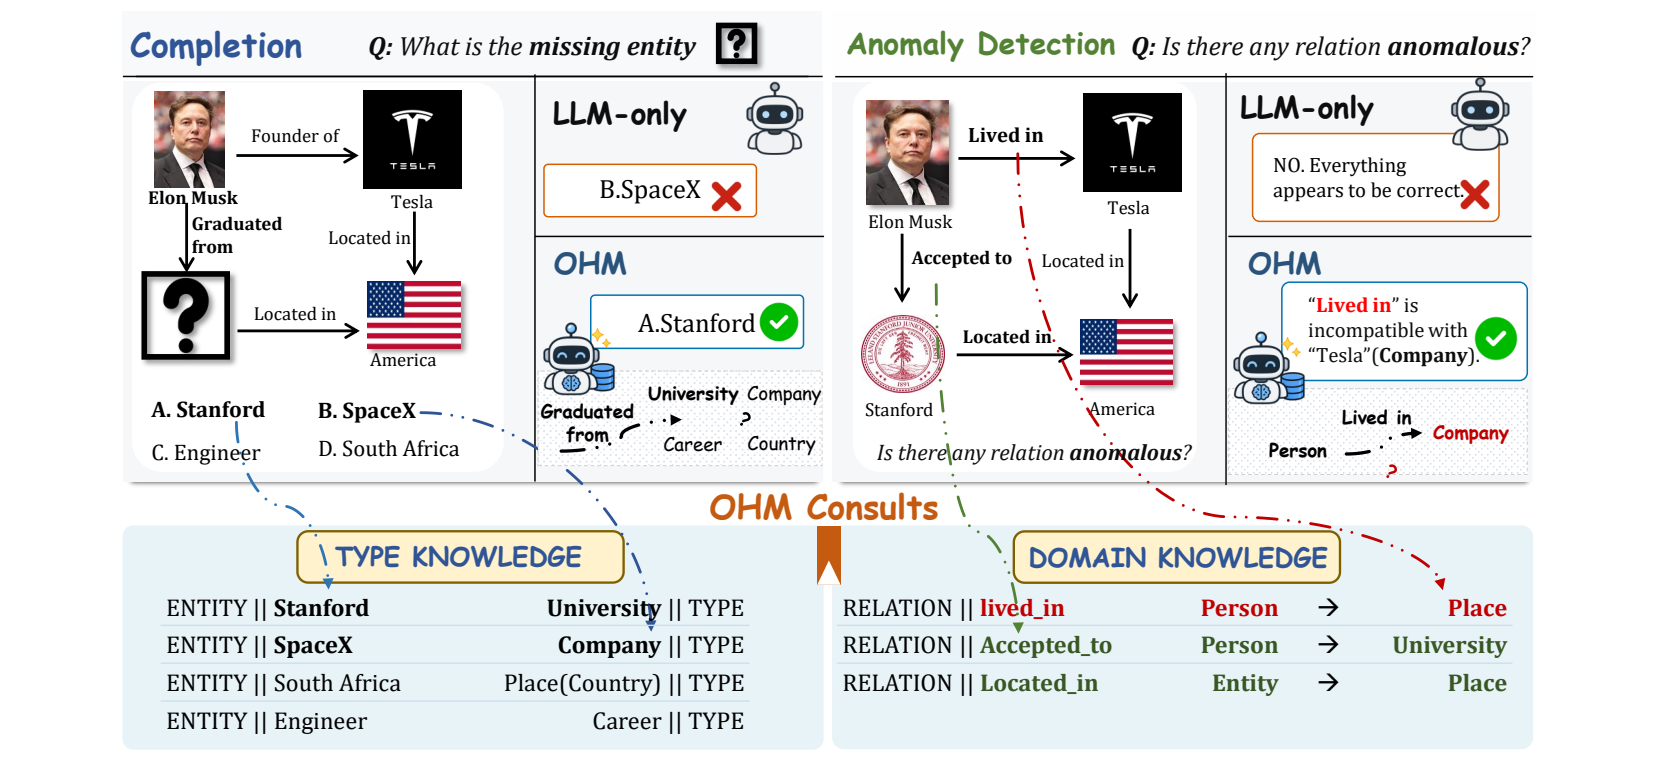
300 dpi PNG · 图注 · 原始PDF
风格入选理由:两列对照与下方知识表叠置,小框、机器人/勾叉/实体图标及浅蓝黄绿组合。
引言借图1的补全与异常关系案例,说明仅用LLM时出错而本体知识提供支撑。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 263],PDF点、左上角原点。
Figure 1: Illustrative examples of ontology-harnessed reasoning in OHM. In knowledge graph (KG)
completion (left), type knowledge helps identify the missing entity. In anomaly detection (right),
relation-domain knowledge reveals that Lived in is incompatible with Tesla as a company. The
ontology provides supporting evidence rather than a hard decision rule.
Ontology-Harnessing Multi-Agent System for Abstractive Visual Understanding
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页
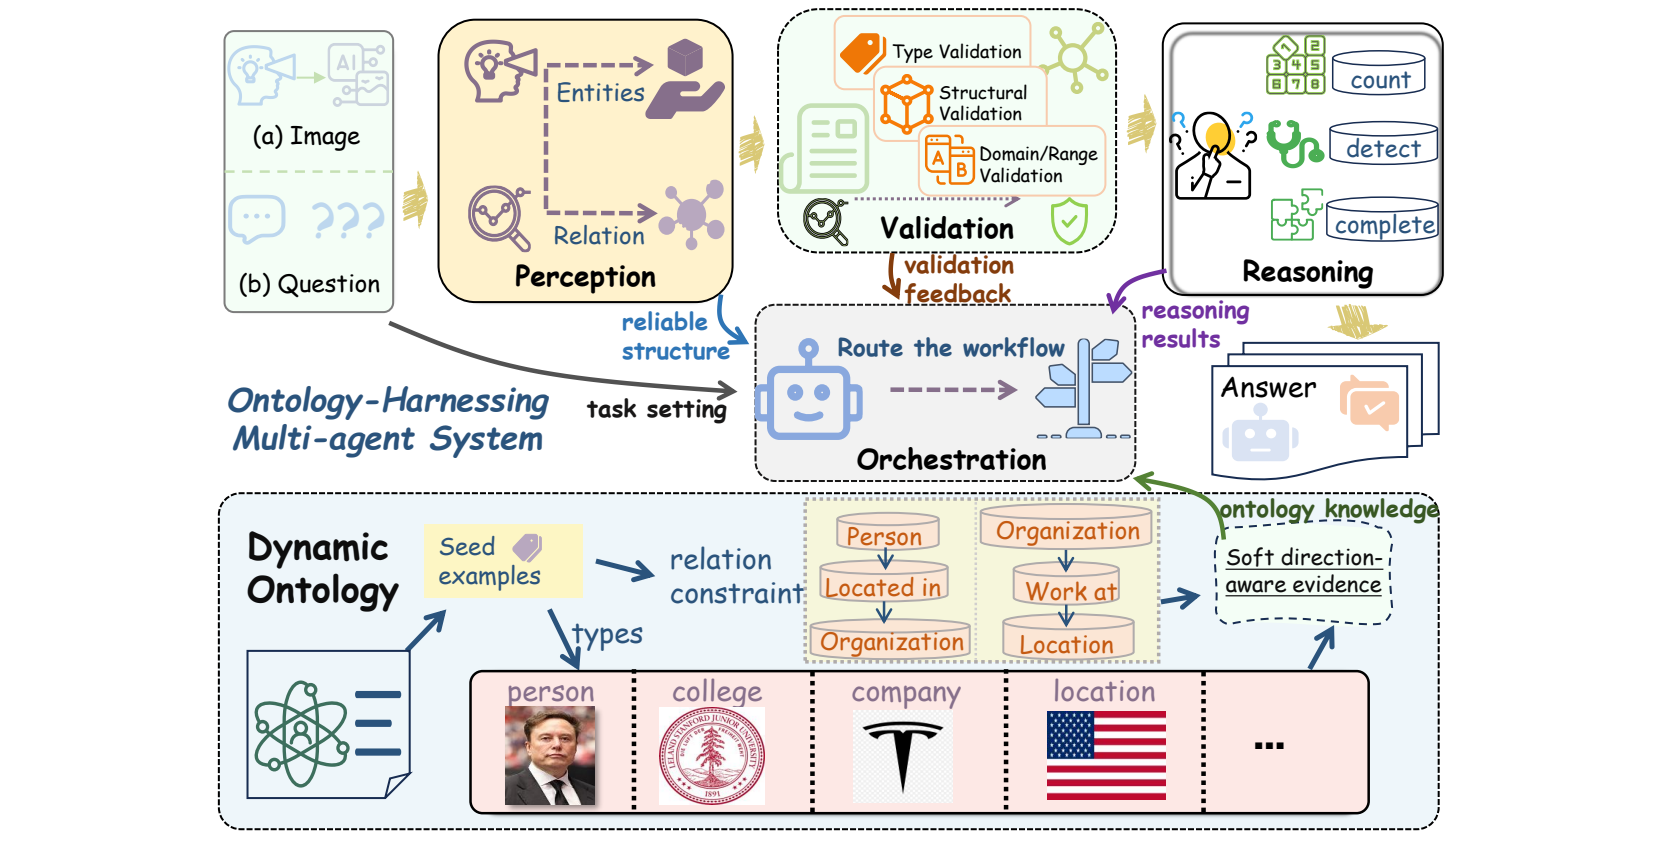
300 dpi PNG · 图注 · 原始PDF
风格入选理由:多彩圆角卡片和多重虚线框、知识实体/人形/机器人图标,细密标签与浅黄紫绿配色。
图2及方法节描述感知、验证、推理、编排与动态本体的核心计算路径。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 283],PDF点、左上角原点。
Figure 2: Workflow of OHM. Given a structured visual representation and a task-specific question,
the orchestration agent routes the input to perception agents that recover entities and relations. The
validation module examines the recovered graph with support from the ontology, after which task-
specific reasoning agents produce the final answer.
BrainIPAgent: Multi-Agent Interpretable Structural Priors for Multimodal Brain Network Learning
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第3页
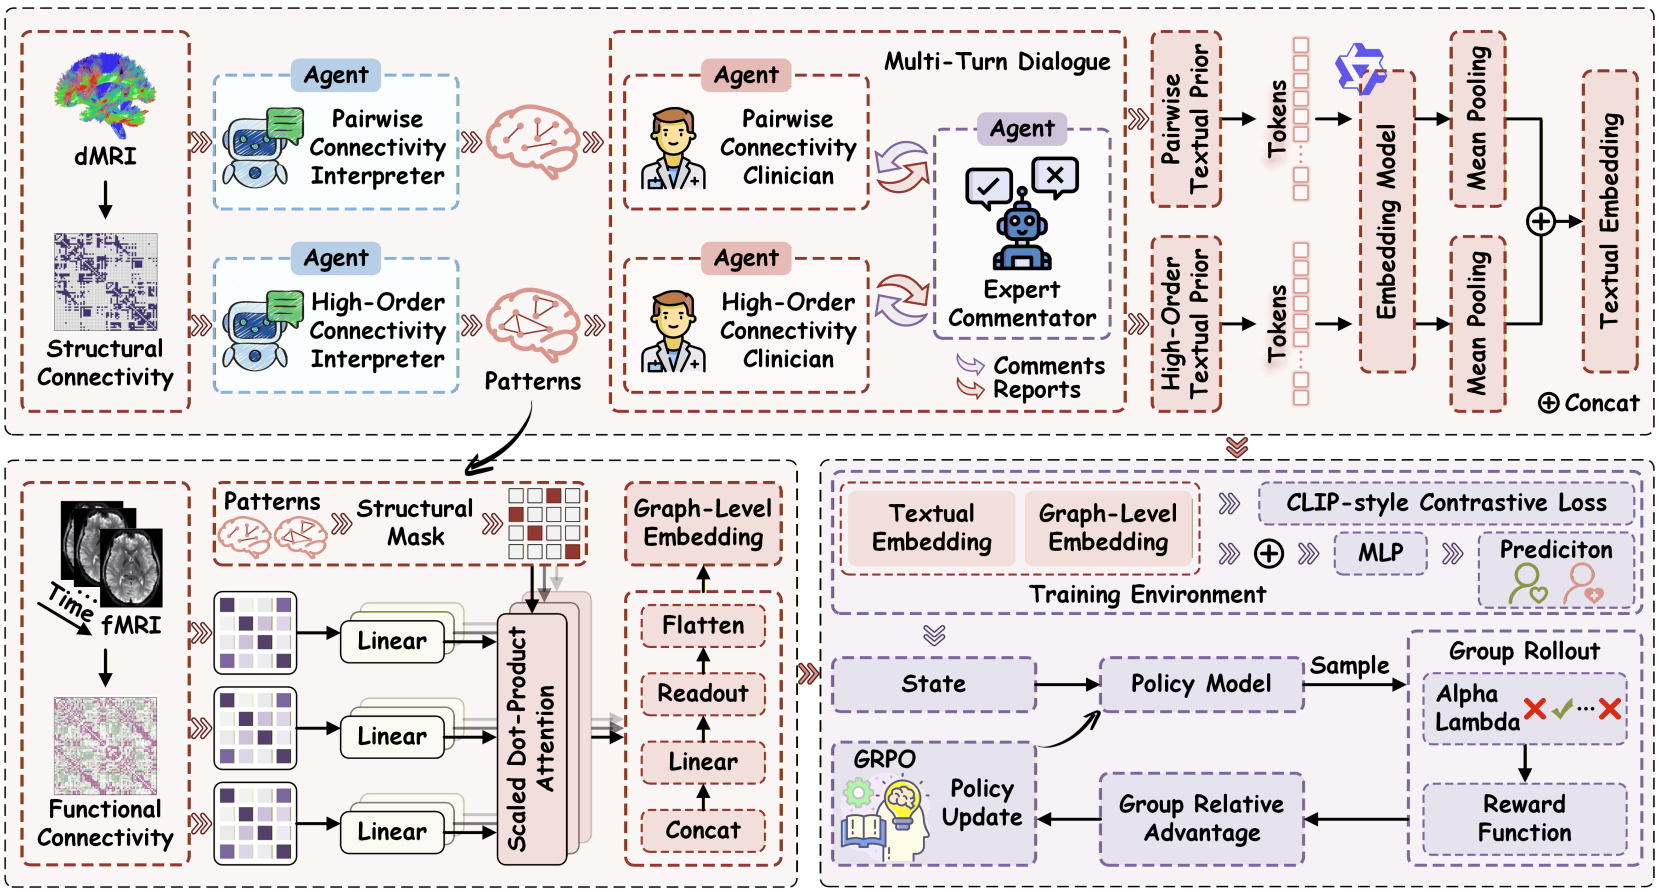
300 dpi PNG · 图注 · 原始PDF
风格入选理由:上下两层多重虚线框,医生/机器人/对话/脑图标、稠密模块标签,浅粉紫蓝分区。
图1和引言明确给出结构解释、功能编码和强化对齐的整体框架。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 294],PDF点、左上角原点。
Figure 1: Overview of the BrainIPAgent framework. (1) The Multi-Agent Interpretation Frame-
work extracts structural patterns via collaborative reasoning to generate sparsity masks and textual
priors. (2) The Structure-Aware Functional Encoder maps these patterns to attention biases in
the logit space and projects them via mask propagation. (3) The RL-Guided Alignment Module
dynamically regulates structural guidance strength Alpha (α) and alignment weight Lambda (λ).
Beyond Dyadic Memory: Interaction-Aware Multimodal Memory with Adaptive Agentic Retrieval for Multi-Party Spoken Conversations
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第5页
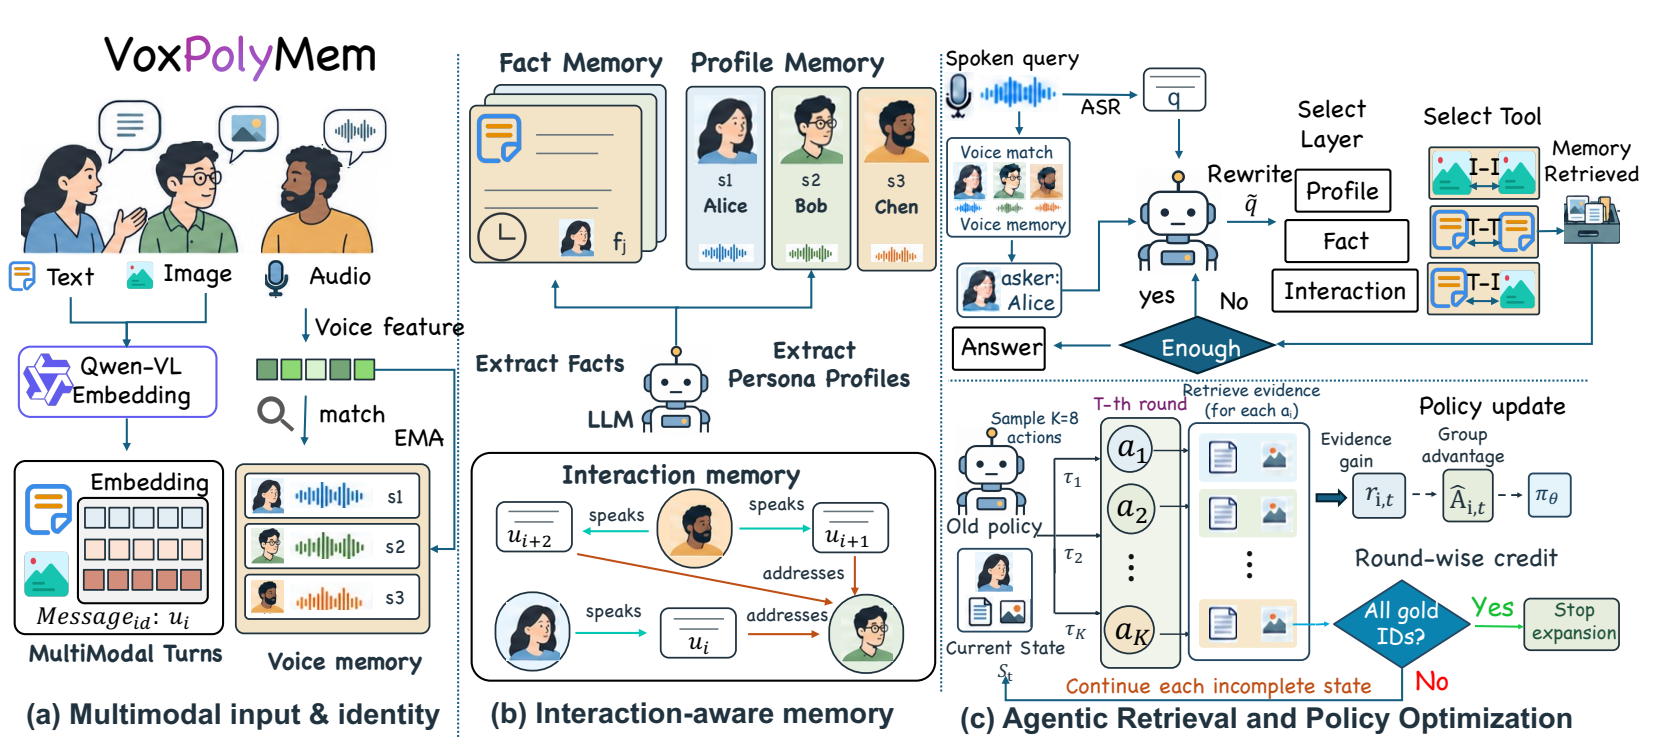
300 dpi PNG · 图注 · 原始PDF
风格入选理由:(a)(b)(c)并列框中嵌套头像、对话、记忆卡和机器人图标,短段解释与浅绿蓝黄面板。
第四节Overview明确引用图2连接输入处理、记忆构建与查询回答。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 261],PDF点、左上角原点。
Figure 2: VoxPolyMem identifies recurring speakers, constructs interaction memory, facts, and par-
ticipant profiles, and adaptively retrieves evidence across memory layers and modalities.
AccessWorld: A Benchmark for Computer Use Agents Operating Assistive Technologies
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页
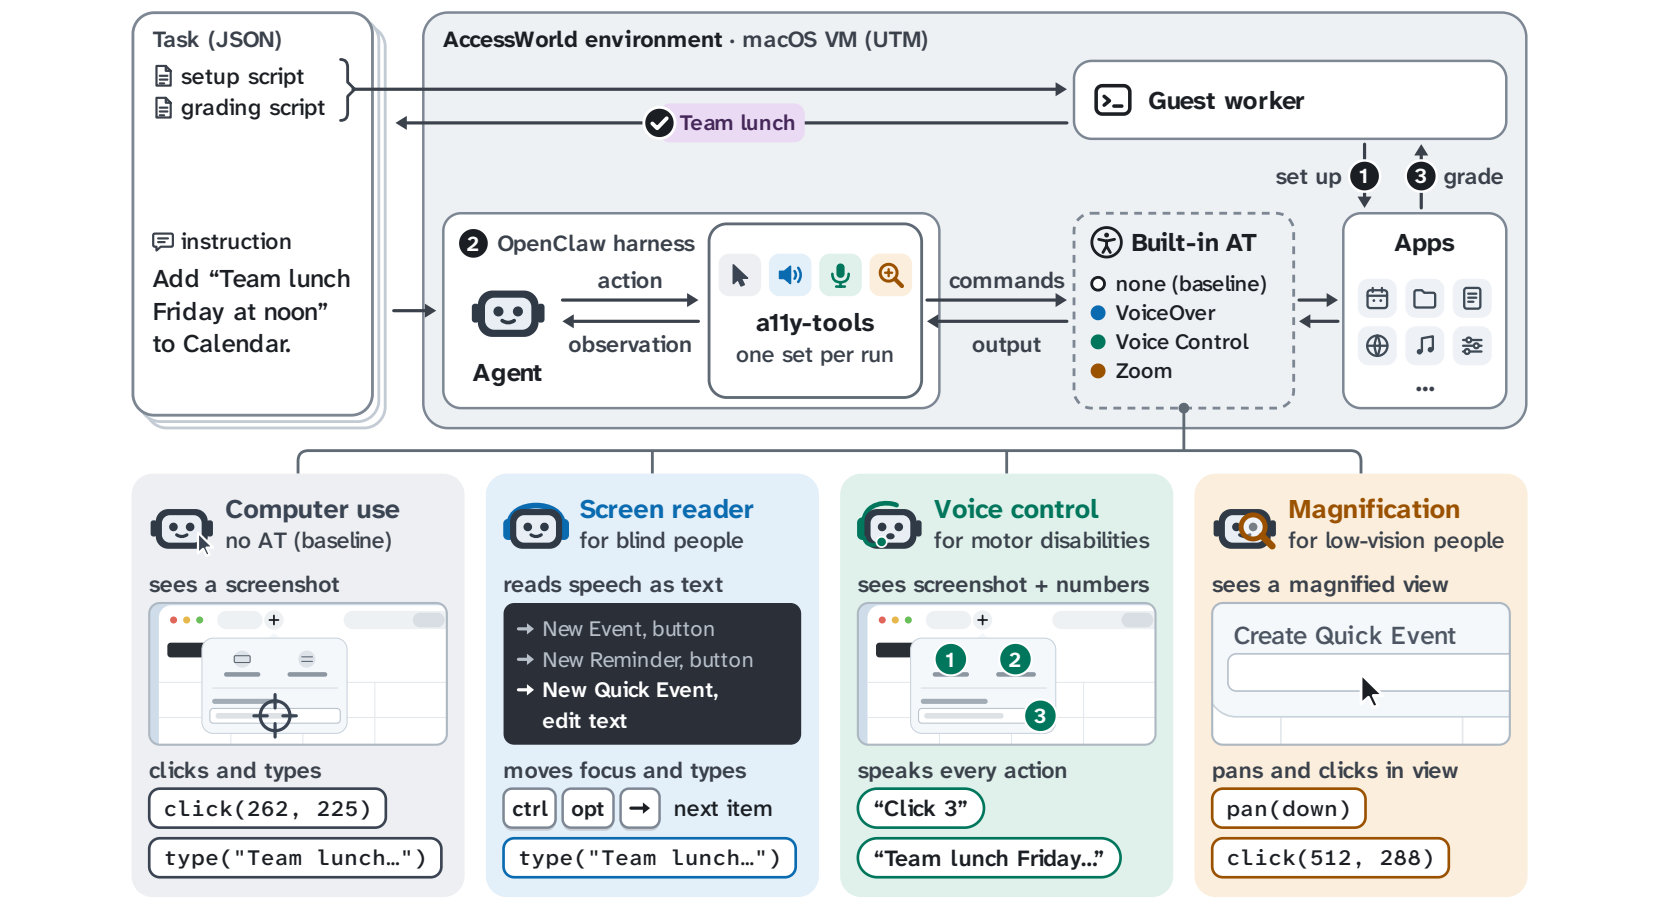
300 dpi PNG · 图注 · 原始PDF
风格入选理由:上层总架构加下层四列浅色接口卡,终端/机器人/文档图标与动作文本堆叠。
图1和引言定义任务、代理环境及四种交互接口的完整基准系统。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 300],PDF点、左上角原点。
Figure 1: AccessWorld Overview. Each task has an instruction and grader, with task-specific
setup when needed, and runs in the same macOS virtual machine. OpenClaw connects the agent to
standard computer use, VoiceOver, Voice Control, or Zoom. The task and grader stay fixed while
the available observations and actions change with the interaction condition.
SpatialAgent: Working Memory for Long-Horizon Spatial Reasoning
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第3页
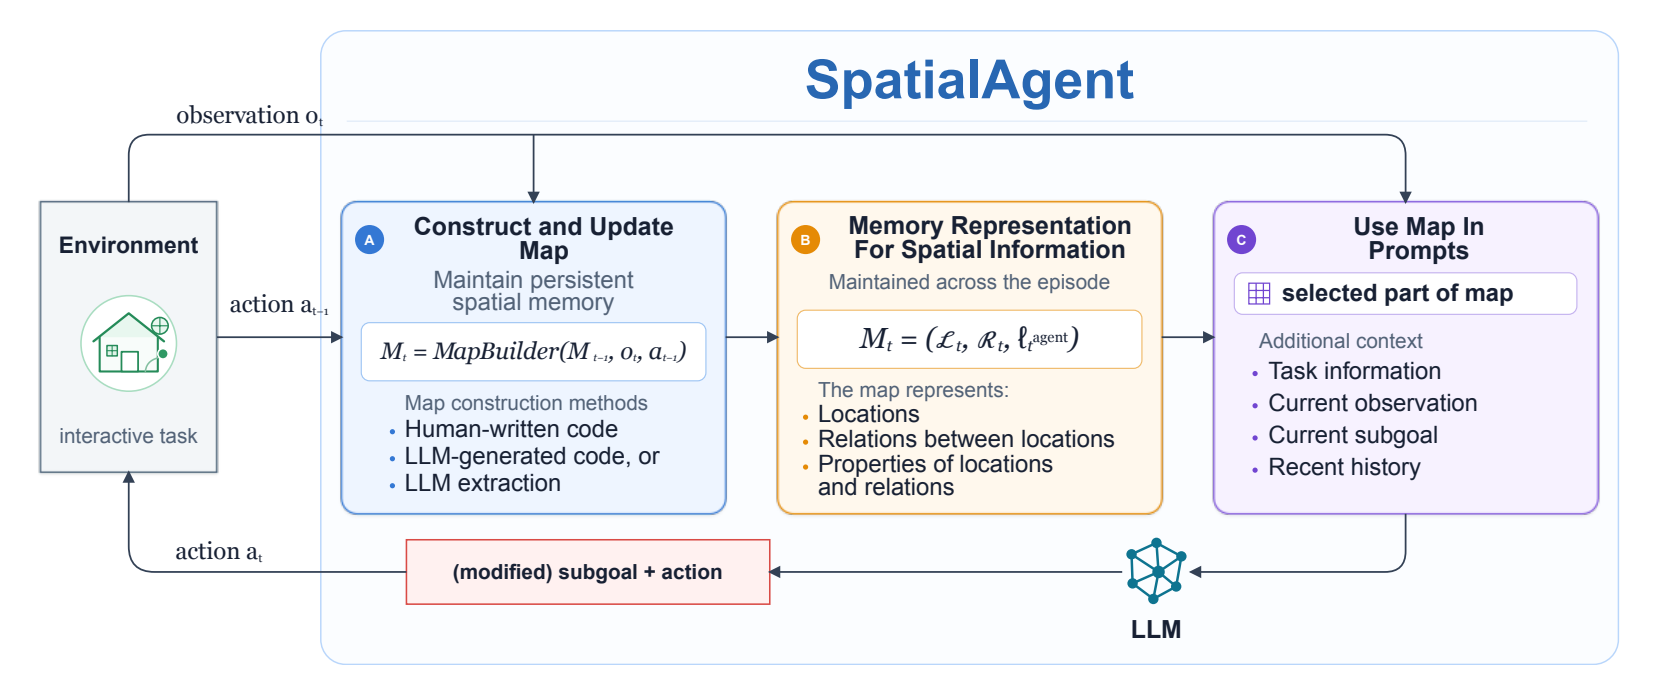
300 dpi PNG · 图注 · 原始PDF
风格入选理由:蓝黄紫三列卡片、嵌套输入框、编号与项目说明;图标数量较少。
2.1节明确称图1为整体架构,包含地图更新、记忆表示及提示决策闭环。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。作者披露AI用于construct diagrams,未指明具体绘图工具或图号。
披露页:10 · 声明原文记录
裁剪位置:[107, 76, 505, 240],PDF点、左上角原点。
Figure 1: Overview of SpatialAgent. The MapBuilder maintains a persistent spatial map from
observations and actions, which is provided to the LLM for decision making.
TARSphere: A Robot-Oriented Full-Stack Framework for Long-Horizon Embodied Agents in Evolving Physical and Social Environments
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第1页
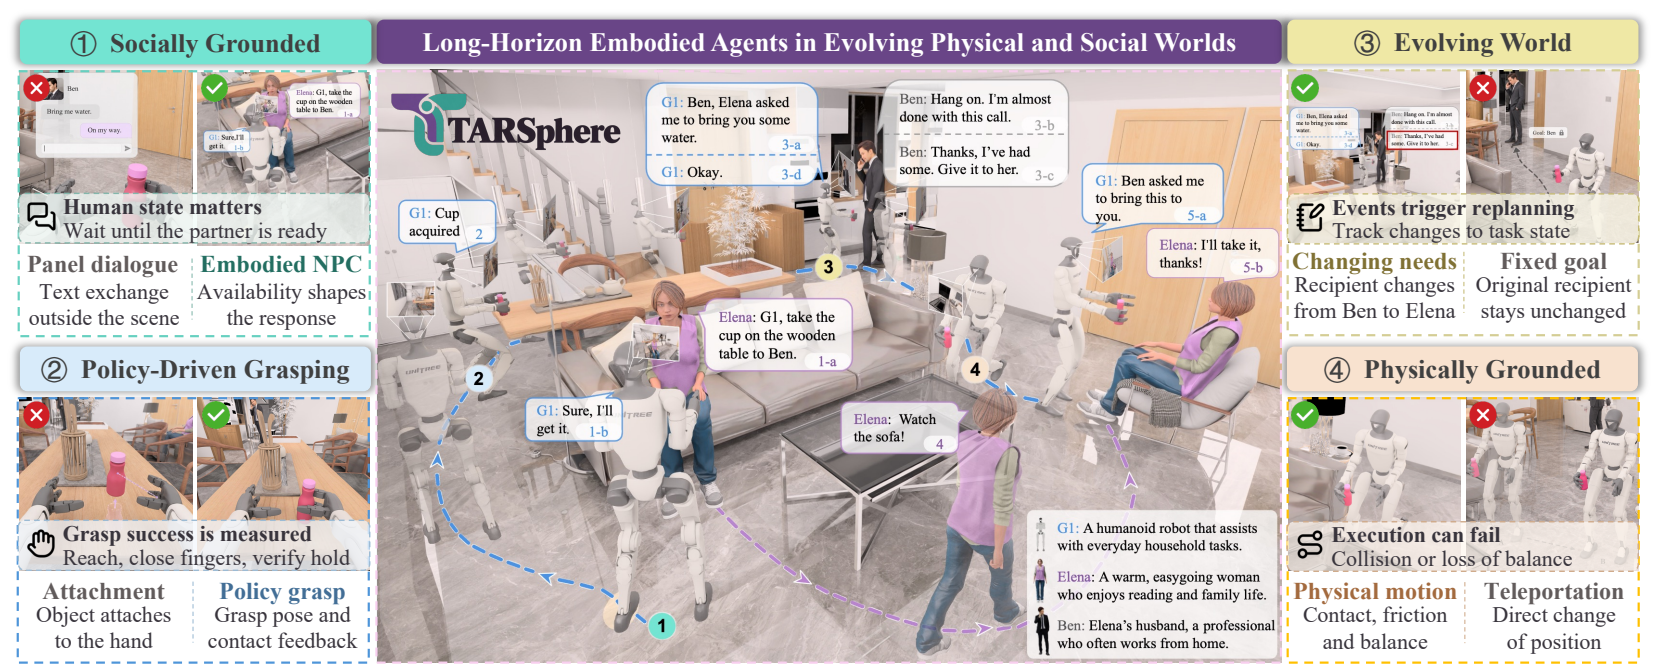
300 dpi PNG · 图注 · 原始PDF
风格入选理由:四个编号角落卡片围绕场景,密集对照文字、机器人/勾叉/感叹号图标及浅绿黄紫。
引言以图1的变化世界、人体交互和物理约束对照引出长程机器人执行难题。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 493, 505, 654],PDF点、左上角原点。
Figure 1: Robot execution and human interaction in a changing world.
TARSphere: A Robot-Oriented Full-Stack Framework for Long-Horizon Embodied Agents in Evolving Physical and Social Environments
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 3 · PDF第4页
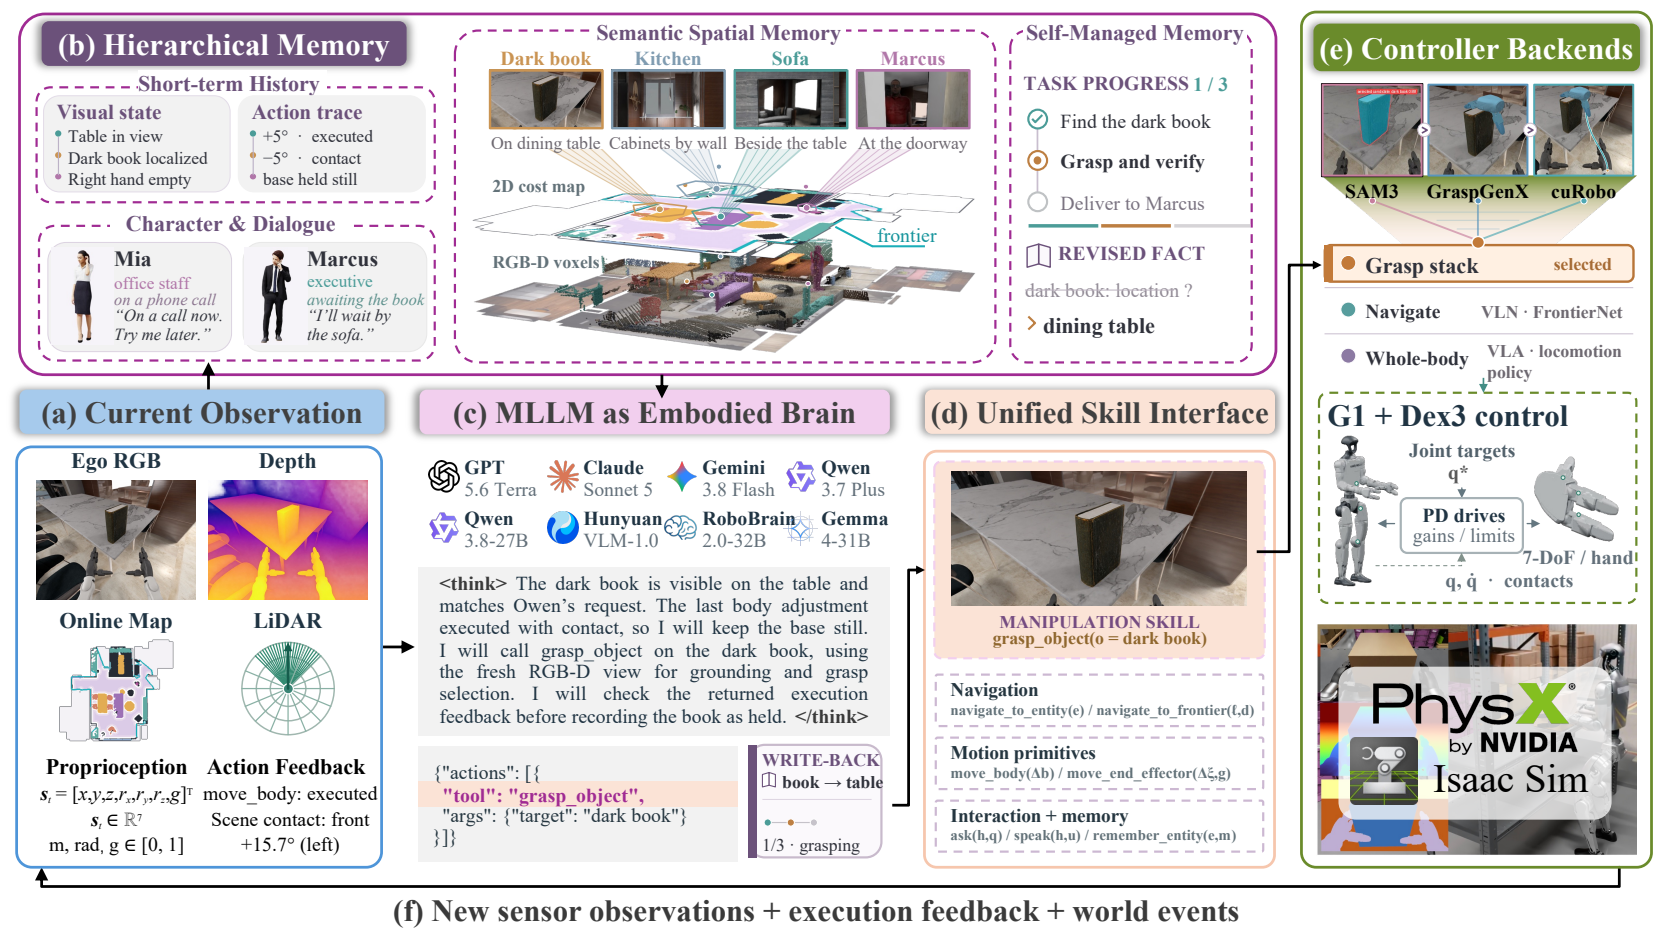
300 dpi PNG · 图注 · 原始PDF
风格入选理由:(a)–(f)多层面板堆叠,观测/记忆/控制器卡片中含密集文字、图标与紫蓝浅色底。
图3给出完整代理决策闭环,从观测和记忆到MLLM、技能接口、控制器再到反馈;图2仅为运行基础设施。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 304],PDF点、左上角原点。
Figure 3: TARSphere-Harness: the embodied brain harness. (a) Current observations and (b) hierarchical
memory inform (c) MLLM decisions. (d) The unified skill interface routes actions to (e) controller backends. (f)
Observations, execution feedback, and public world events close the loop.
BKBAgent: A Battery Parameter Identification Agent with Bayesian Experimental Design and Knowledge Graph
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页
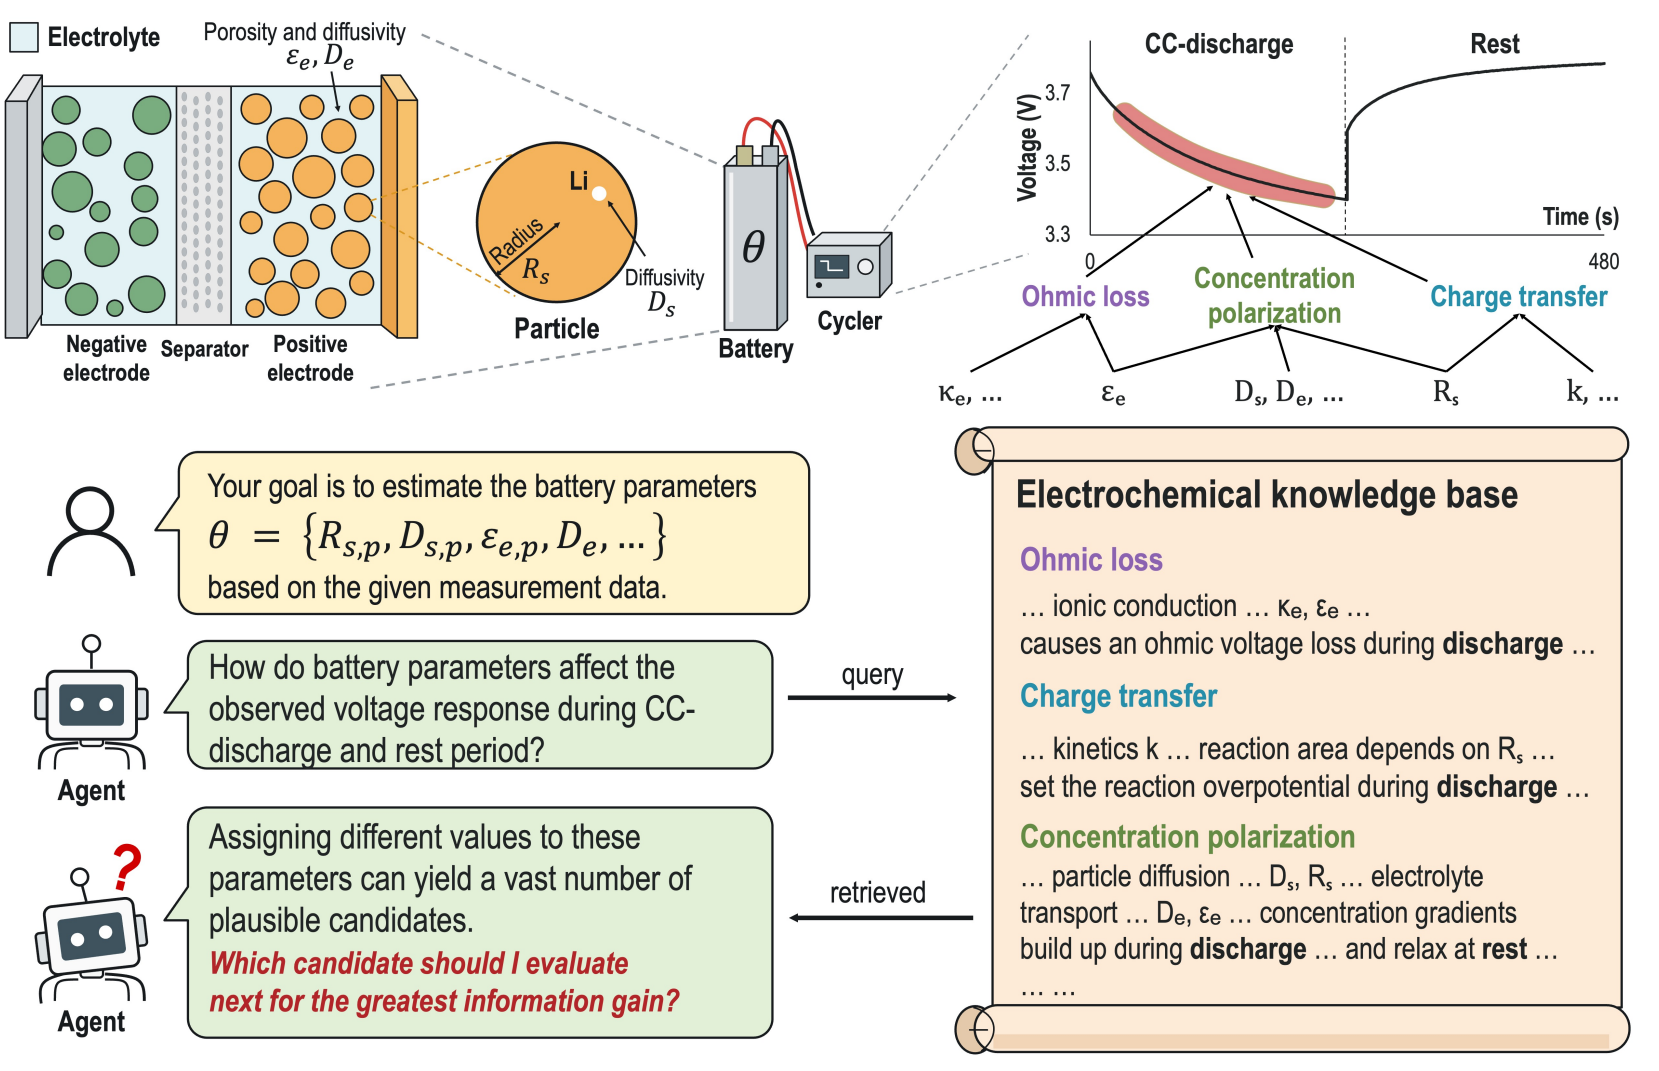
300 dpi PNG · 图注 · 原始PDF
风格入选理由:上下物理示意与代理对话分区,嵌套知识卡、机器人和电池图标,浅绿黄橙配色与解释文字。
引言图1以电池物理机制和代理交互说明参数识别的歧义与知识缺口。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。作者披露生成式AI参与figure preparation;未指明具体绘图工具或图号。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 337],PDF点、左上角原点。
Figure 1: Illustration of agent-based battery parameter identification and its key challenge.
BKBAgent: A Battery Parameter Identification Agent with Bayesian Experimental Design and Knowledge Graph
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页
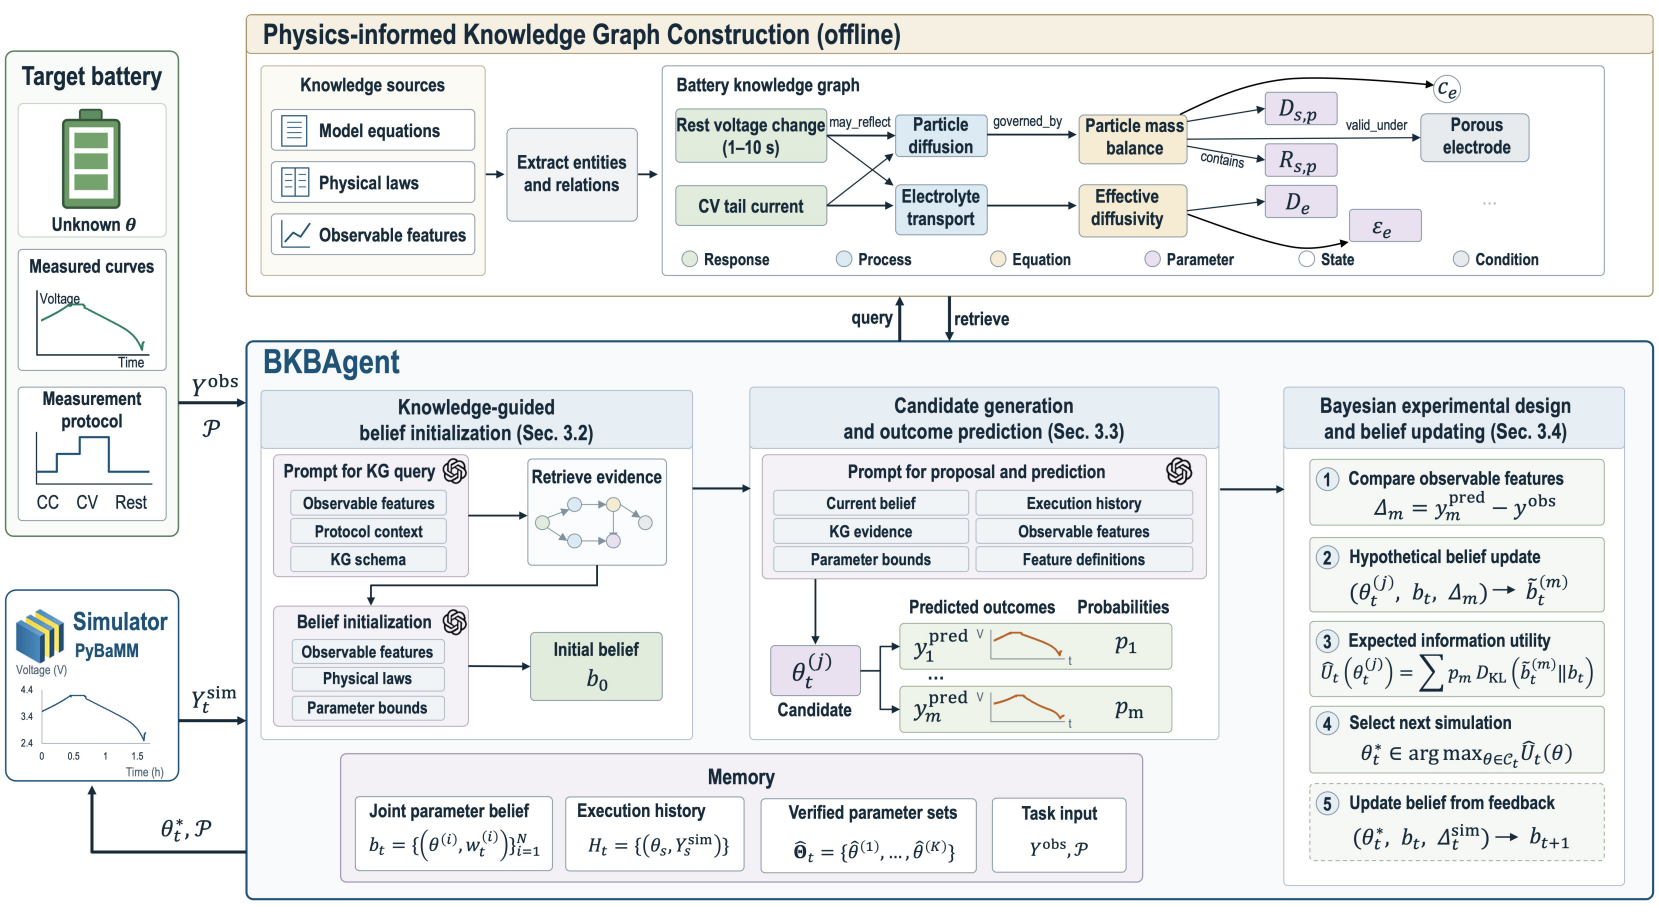
300 dpi PNG · 图注 · 原始PDF
风格入选理由:多层框格与并排模块,电池、文档、工具图标及密集说明文字,浅蓝紫黄分区。
图2和方法节描述知识图谱、信念更新、实验设计与模拟反馈的整体路径。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。作者披露生成式AI参与figure preparation;未指明具体绘图工具或图号。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 301],PDF点、左上角原点。
Figure 2: Illustration of the BKBAgent framework for battery parameter identification. Utility de-
notes the approximate expected belief change in Eq. (3).
FM-Bench: A Benchmark for Long-Horizon Management with Competing Agents
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页
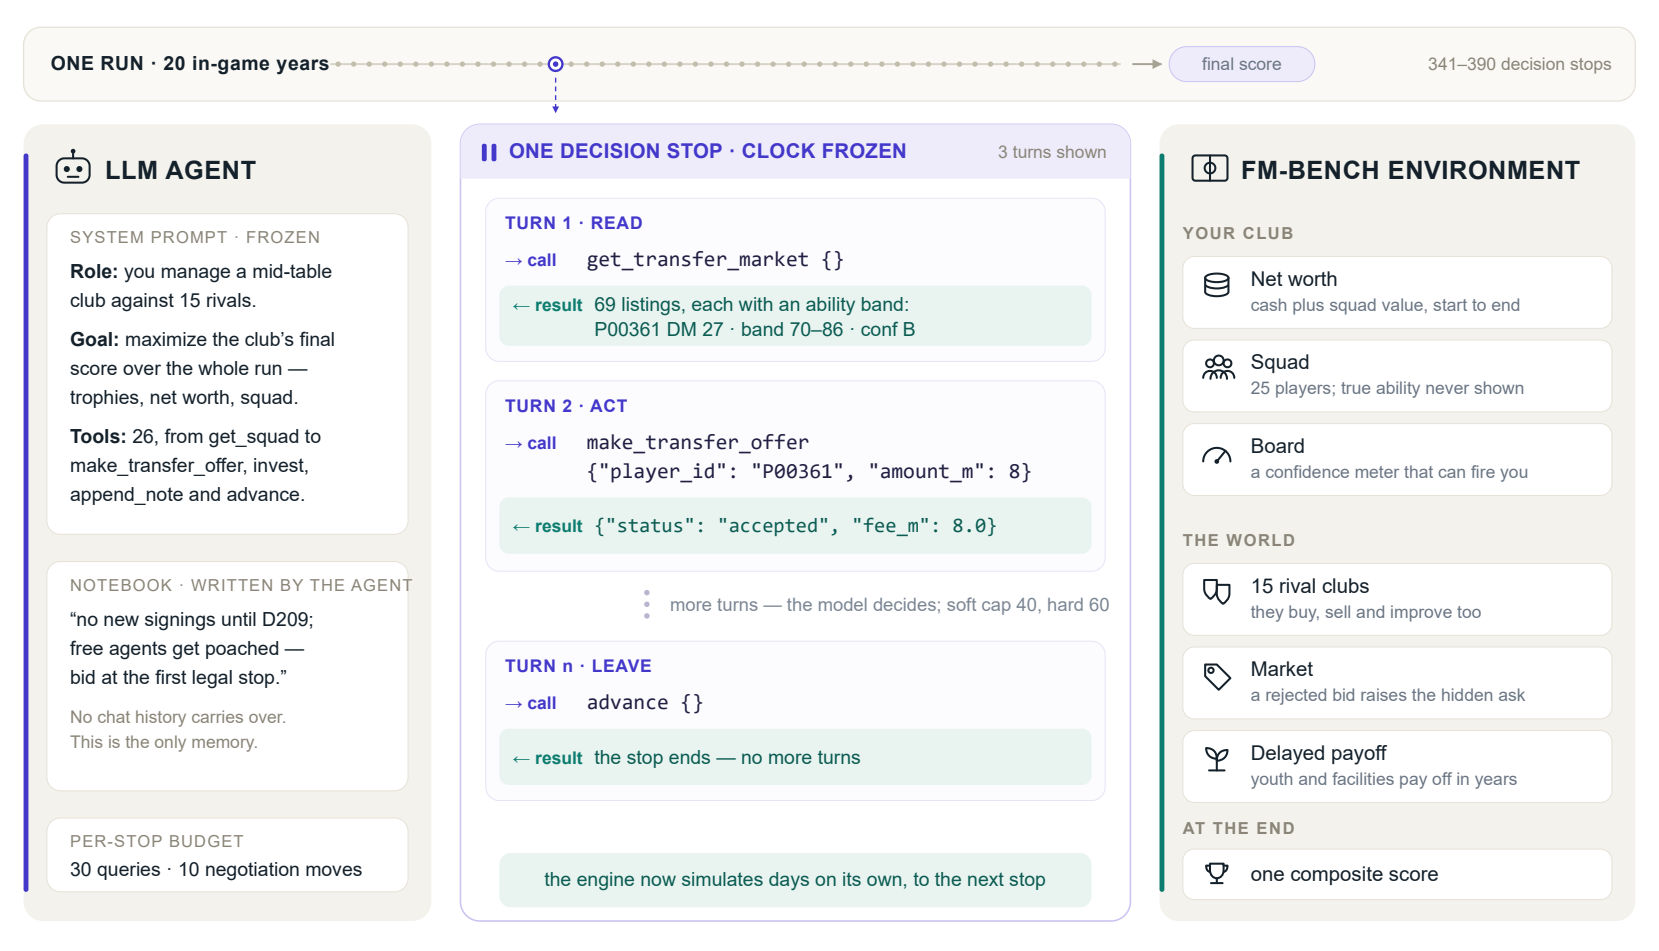
300 dpi PNG · 图注 · 原始PDF
风格入选理由:三列大面板套入工具和记忆小卡,密集条目、人物和管理图标,浅灰紫蓝组合。
图1及第3节说明单次管理运行中的代理、决策停点、环境与评测闭环。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 308],PDF点、左上角原点。
Figure 1: How a run works. One run spans 20 in-game years and roughly 340 to 400 decision stops,
ending in a single composite score. At each stop, the clock freezes and the agent takes as many tool-
call turns as it wants (read → act → advance). The agent’s only cross-stop memory is its self-
written notebook (§3.2); the environment side holds the club (net worth, squad with permanently
hidden true ability, a board that can fire the manager) and the world (15 rival clubs, a counter-
adaptive market, delayed-payoff investments).
EngiWorld: What Can Frontier Agents Deliver in Professional Engineering Environments?
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页
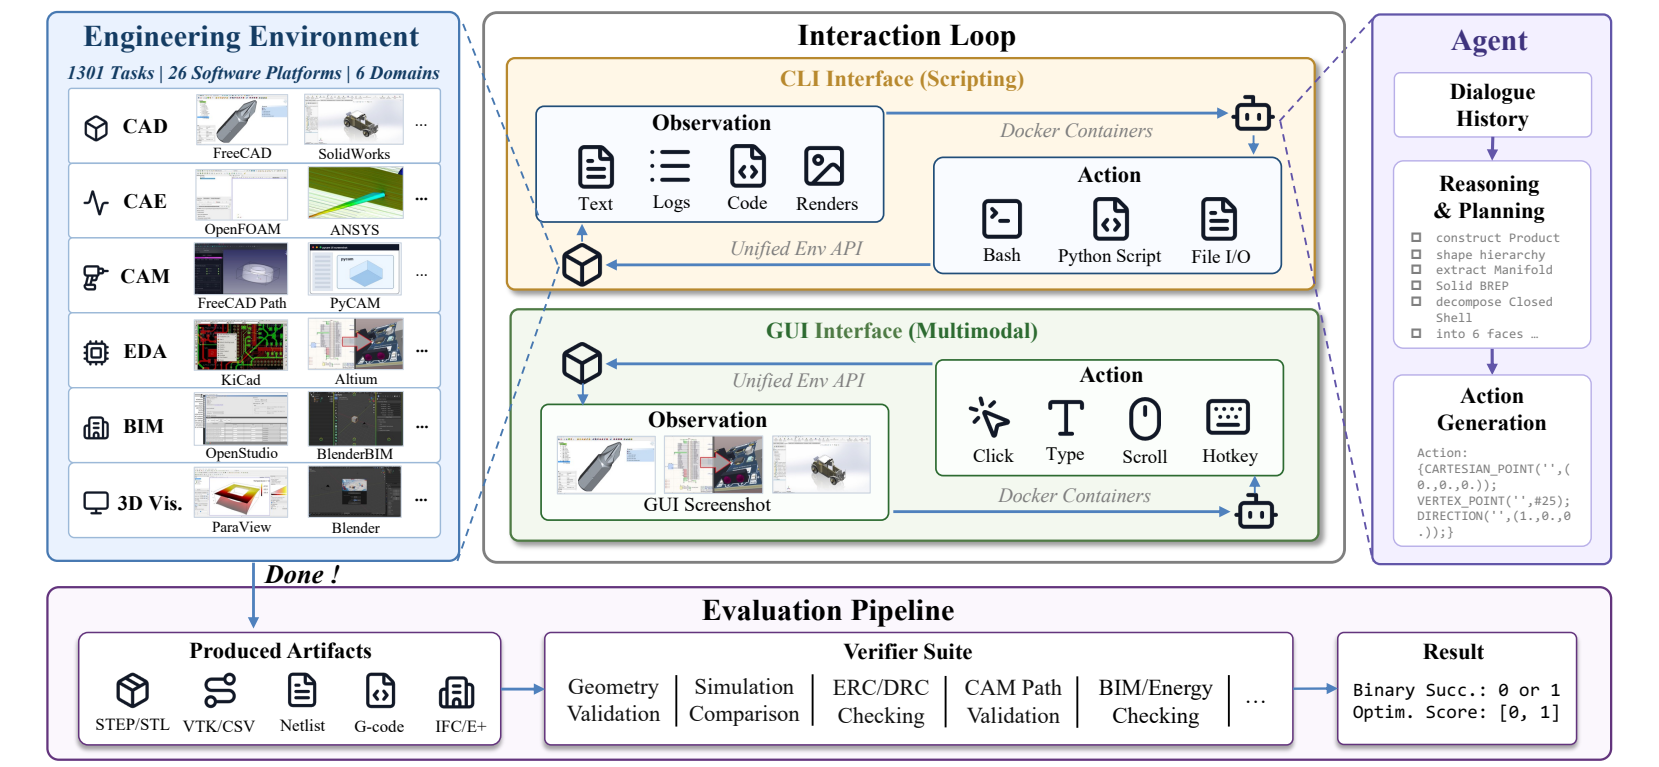
300 dpi PNG · 图注 · 原始PDF
风格入选理由:并排三栏加底部验证条带,多重卡框、工具图标和短段说明,蓝橙绿紫分区。
图2和任务定义正文展示工程环境、代理交互以及产物验证的完整框架。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 188, 505, 372],PDF点、左上角原点。
Figure 2: Overview of the ENGIWORLD framework. Agents interact with engineering applica-
tions through CLI or GUI interfaces and are evaluated from the artifacts produced during execution.
Domain-specific verifiers check whether these artifacts satisfy the required engineering constraints.
VEvo-Harness: Causally-Guarded Self-Evolving Harness for Agentic Image Generation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页
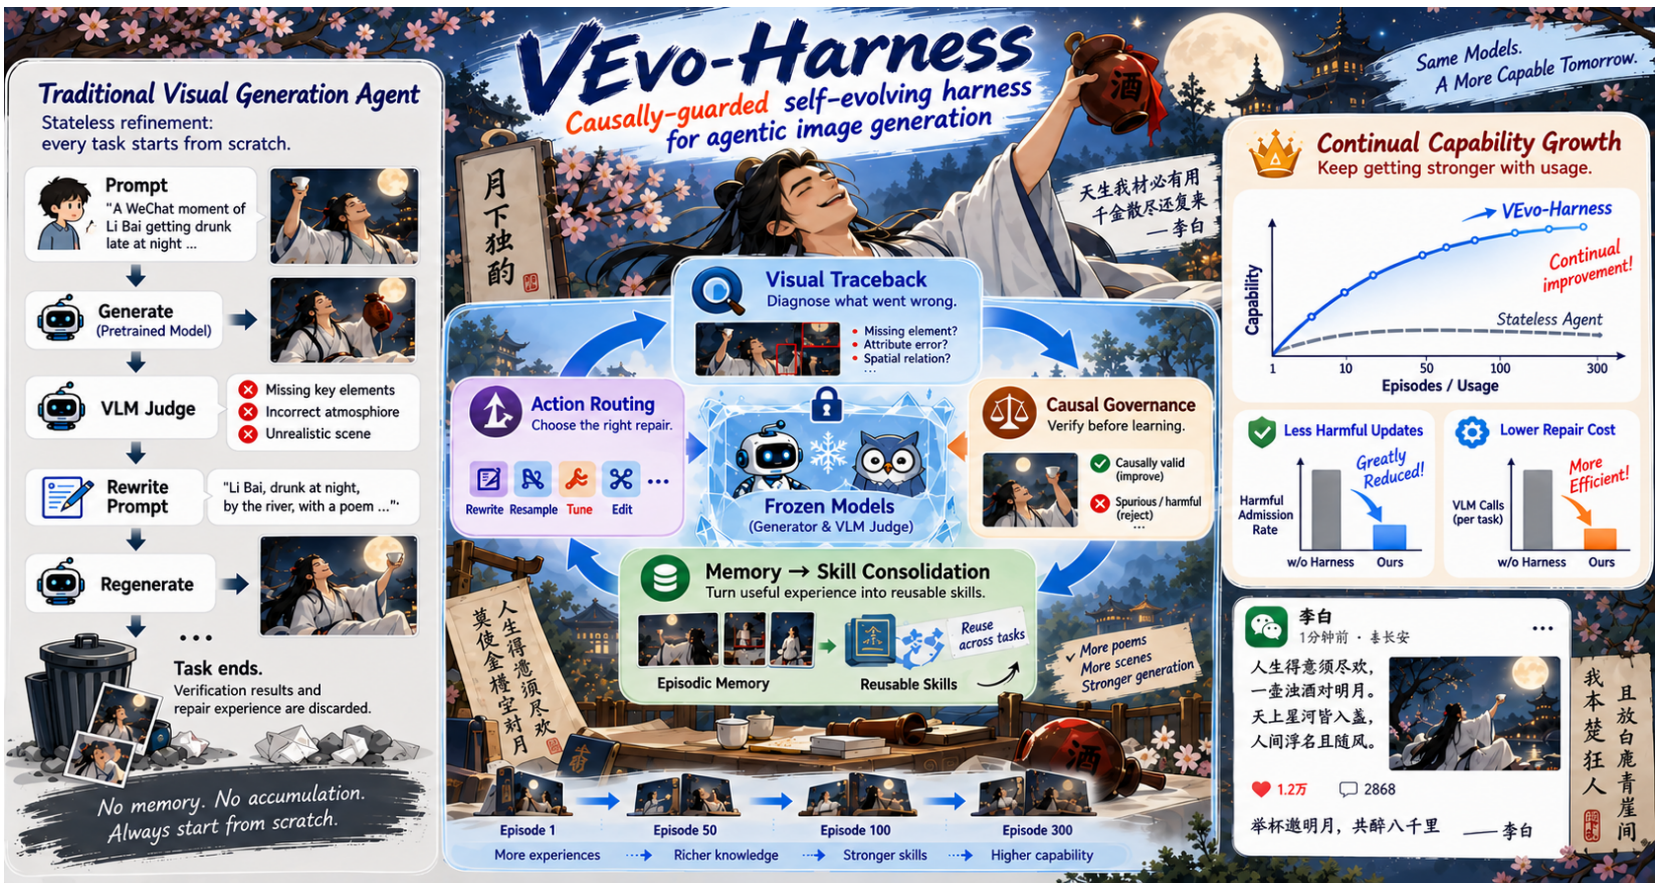
300 dpi PNG · 图注 · 原始PDF
风格入选理由:中心李白情境插画,左右方案对照与多层记忆/治理卡片,机器人、工具、图表和密集说明,浅色卡片叠在深色背景上。
引言借图1对比无状态修复和持续积累视觉经验,引出能力增长问题。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。作者明确披露对手工原版方法框架图使用生成式AI作美学改进;未指明具体绘图模型。此声明针对框架图,不能自动归因于M图。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 293.1],PDF点、左上角原点。
Figure 1: From stateless refinement to continual capability growth. VEvo-Harness causally verifies
and reuses visual experience, enabling frozen generators to become progressively stronger with usage.
VEvo-Harness: Causally-Guarded Self-Evolving Harness for Agentic Image Generation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第3页
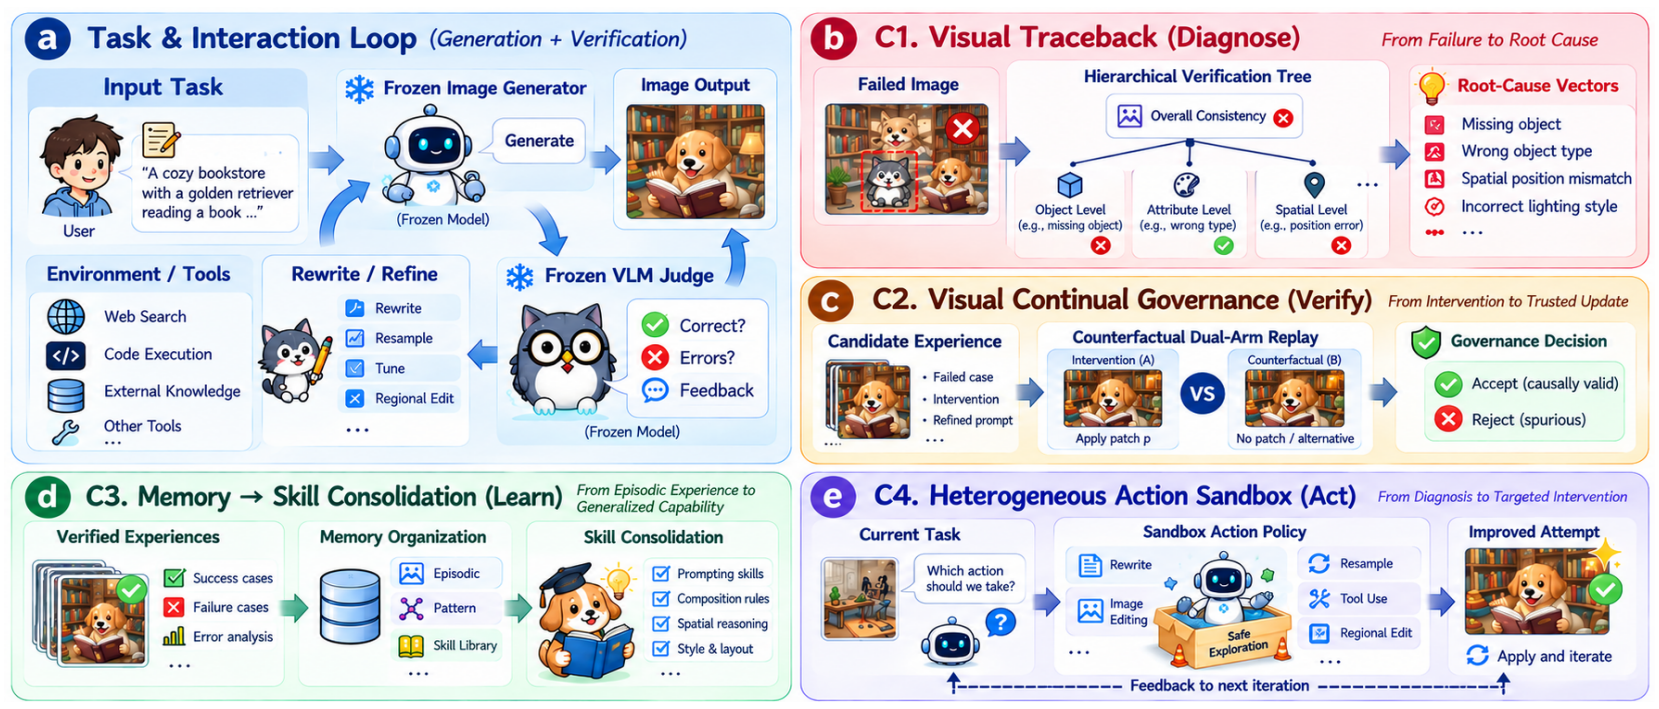
300 dpi PNG · 图注 · 原始PDF
风格入选理由:(a)–(e)多重面板堆叠,机器人、树形图、猫和记忆图标,密集说明与浅蓝绿黄紫色块。
图2明确给出交互循环、视觉溯源、治理、状态管理和动作沙箱的整体流程。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。作者明确披露对手工原版方法框架图使用生成式AI作美学改进;未指明具体绘图模型。此声明针对框架图,不能自动归因于M图。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 250],PDF点、左上角原点。
Figure 2: Overview of our proposed VEvo-Harness pipeline. A self-evolving scaffold is built around
(a) a Interaction Loop for generation and verification, comprising (b) Visual Traceback, (c) Visual
Continual Governance, (d) Lifecycle-Managed Harness State, and (e) Heterogeneous Action Sandbox.
VideoWeaver: Evaluating and Evolving Skills for Agentic Long Video Generation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第5页
300 dpi PNG · 图注 · 原始PDF
风格入选理由:多列多行的小卡片容器,机器人、音频、工具图标及很密的步骤文字,浅蓝绿黄橙分区。
图2和Evaluation Protocol段落定义从请求、轨迹和视频到工具评估与反馈的完整评估框架。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 288, 505, 416],PDF点、左上角原点。
Figure 2: Evidence-grounded agent-as-judge evaluation framework. Given the user request, reference
assets, execution trace, intermediate artifacts, and final video, the evaluation agent conducts an agentic
evaluation. At each round, it invokes evaluation skills to inspect traces, extract video metadata, sample
key frames, separate audio, run ASR, analyze errors, and understand visual or audio content. The
collected evidence is then used to score process and output metrics and provide textual feedback.
OpenAgentFlow: Enabling System-Wide Safety Boundaries for Heterogeneous AI Agent Fleets
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页
300 dpi PNG · 图注 · 原始PDF
风格入选理由:(a)(b)左右案例面板,代理、文档、警示图标,多层数据流卡片与浅蓝紫橙配色。
图1及引言用两个跨代理动作组合案例说明单独无害的步骤如何产生会话级风险。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 305],PDF点、左上角原点。
Figure 1: Session-level risks arise from composed action flows across agents or endpoints. The
unsafe condition may appear only after otherwise ordinary actions are composed within a session.
OpenAgentFlow: Enabling System-Wide Safety Boundaries for Heterogeneous AI Agent Fleets
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第6页
300 dpi PNG · 图注 · 原始PDF
风格入选理由:上下控制/动作平面,嵌套浅橙紫卡框、机器人和文件图标,密集说明和多条连线。
图2和系统节连接动作标准化、执行前检查、控制平面状态与审计的完整架构。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 305],PDF点、左上角原点。
Figure 2: OpenAgentFlow normalizes instrumented actions into AgentEvents and checks them
with a shared PEP before execution; the control plane maintains policy, provenance, session, audit,
and update state.
Maestro: Agentic Formal Proof Development by Coordination
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第3页
300 dpi PNG · 图注 · 原始PDF
风格入选理由:多列代理角色和上下工作区/事件队列,头像、任务卡与编号流程,浅绿蓝紫背景。
图1和正文展示协调者、并行证明工作者、事件队列、共享工作区与最终检查的循环。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 263],PDF点、左上角原点。
Figure 1: MAESTRO’s coordination loop. The persistent coordinator 1 dispatches or redirects
workers, which 2 attack open obligations in parallel and 3 report proofs, diagnoses, progress, or
blueprints to a shared queue. The coordinator 4 consumes these events as they arrive and 5 revises
the shared Lean workspace, here retracting H2 and H1.2, restating H3 as H3’, adding H4, and
keeping the proved H1.1. When the root closes, 6 Lean checks the final proof or falsification.
MASCraft: Multi-Agent Specialization through Role–Skill Composition and Self-Evolving Orchestration
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页
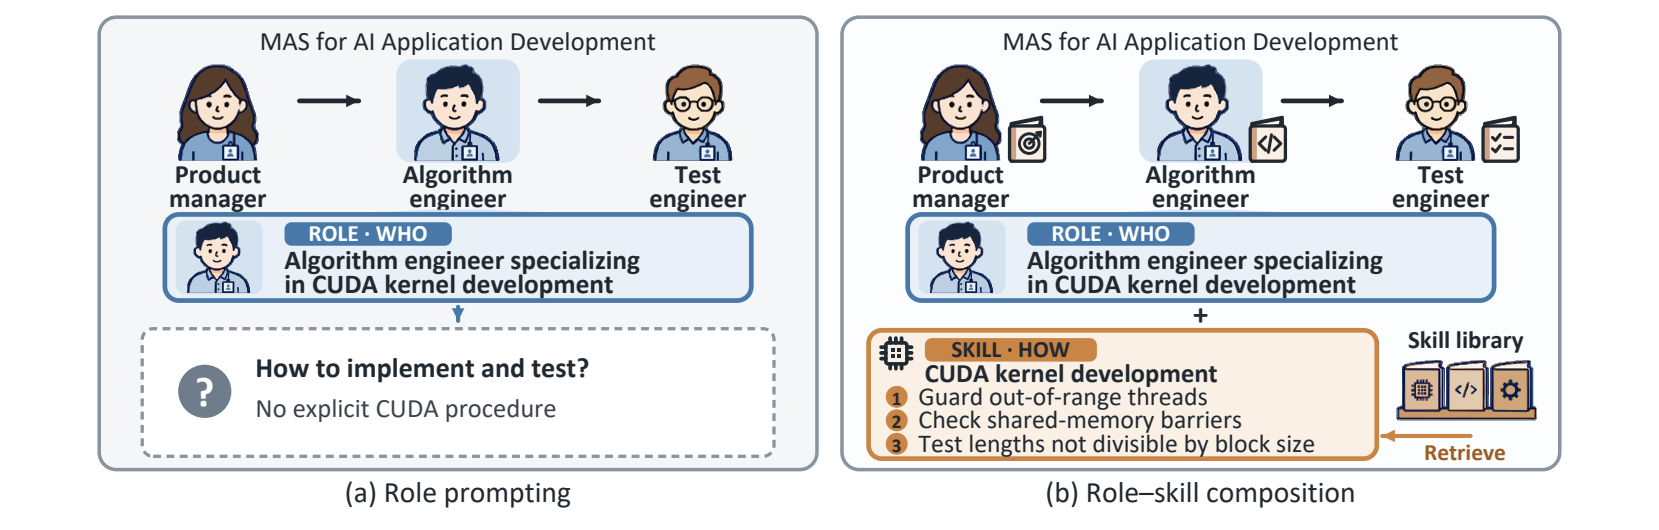
300 dpi PNG · 图注 · 原始PDF
风格入选理由:(a)(b)两个大框包含多张角色卡、人物图标及技能文档,浅绿紫蓝和较密的对话式描述。
引言用图1对比只有角色提示与显式角色技能组合,解释缺少过程指导的问题。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。作者披露生成式AI参与figure preparation;未指明具体绘图工具或图号。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 207],PDF点、左上角原点。
Figure 1: Role prompting versus role–skill composition in MAS for AI application development.
Both teams retain the same specialist roles, while role–skill composition adds explicit procedural
guidance, illustrated by a CUDA-specific skill for the algorithm engineer.
MASCraft: Multi-Agent Specialization through Role–Skill Composition and Self-Evolving Orchestration
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页
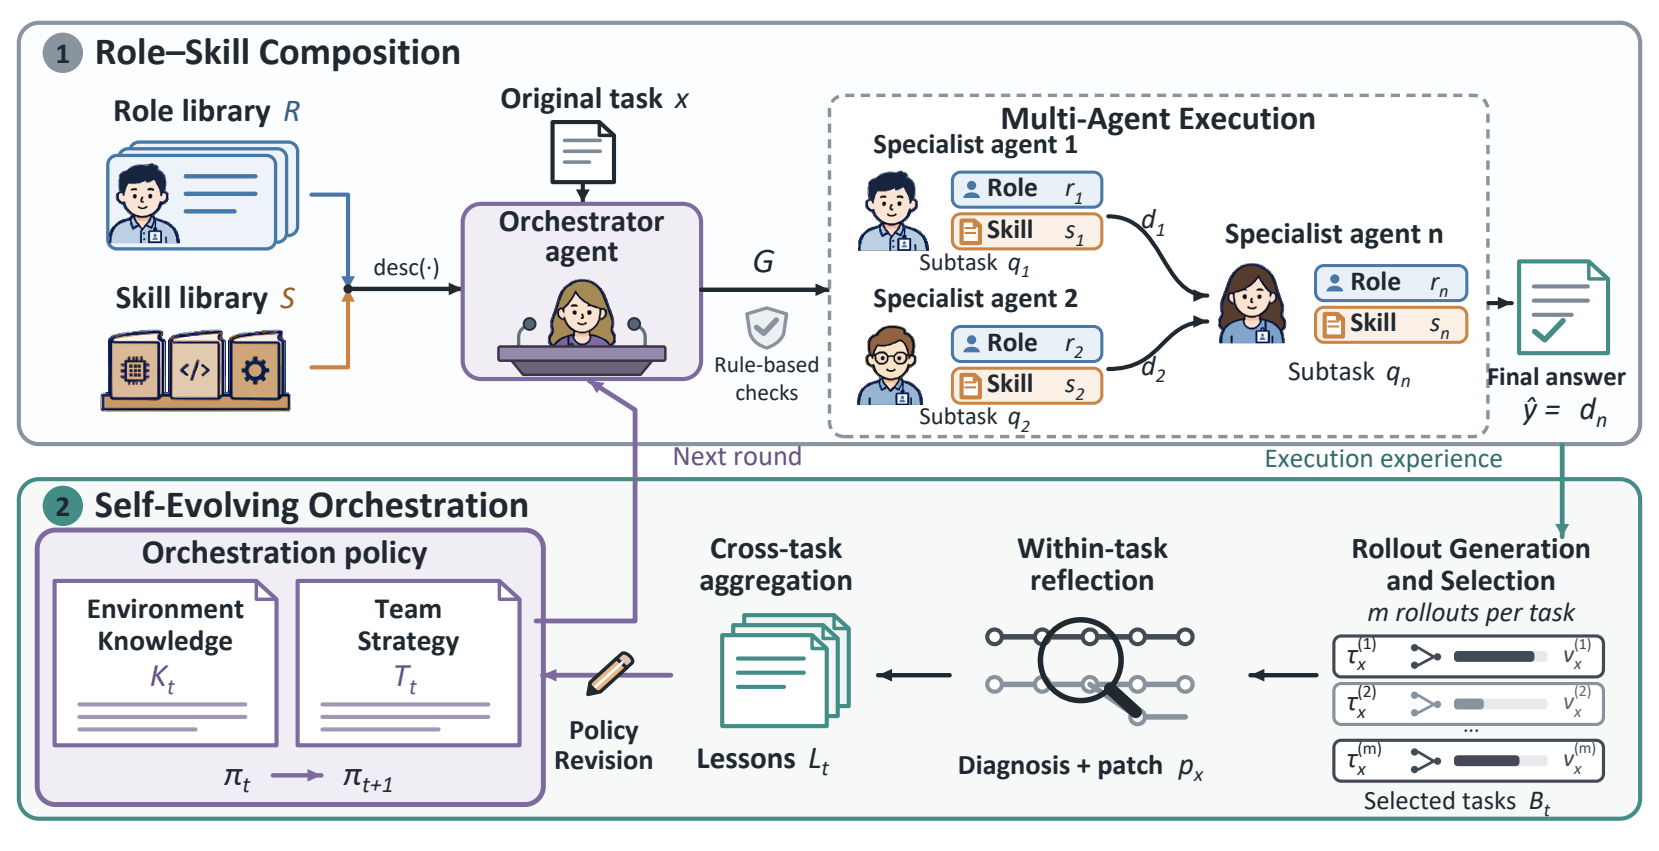
300 dpi PNG · 图注 · 原始PDF
风格入选理由:上下两层大面板、多列角色卡、人物和文档图标,浅黄绿蓝分区与任务说明堆叠。
图2及方法节定义角色技能组合和跨任务自演化编排两部分的完整过程。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。作者披露生成式AI参与figure preparation;未指明具体绘图工具或图号。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 284],PDF点、左上角原点。
Figure 2: Overview of MASCraft. (1) Role–Skill Composition: the orchestrator agent assigns sub-
tasks, selects role–skill pairs, and establishes information dependencies. (2) Self-Evolving Orches-
tration: within-task reflection and cross-task aggregation distill lessons from contrasting rollouts to
update Environment Knowledge and Team Strategy for subsequent team construction.
FinFIRST: Benchmarking Search Agents for Financial Information Retrieval, Sourcing and Traceability
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第3页
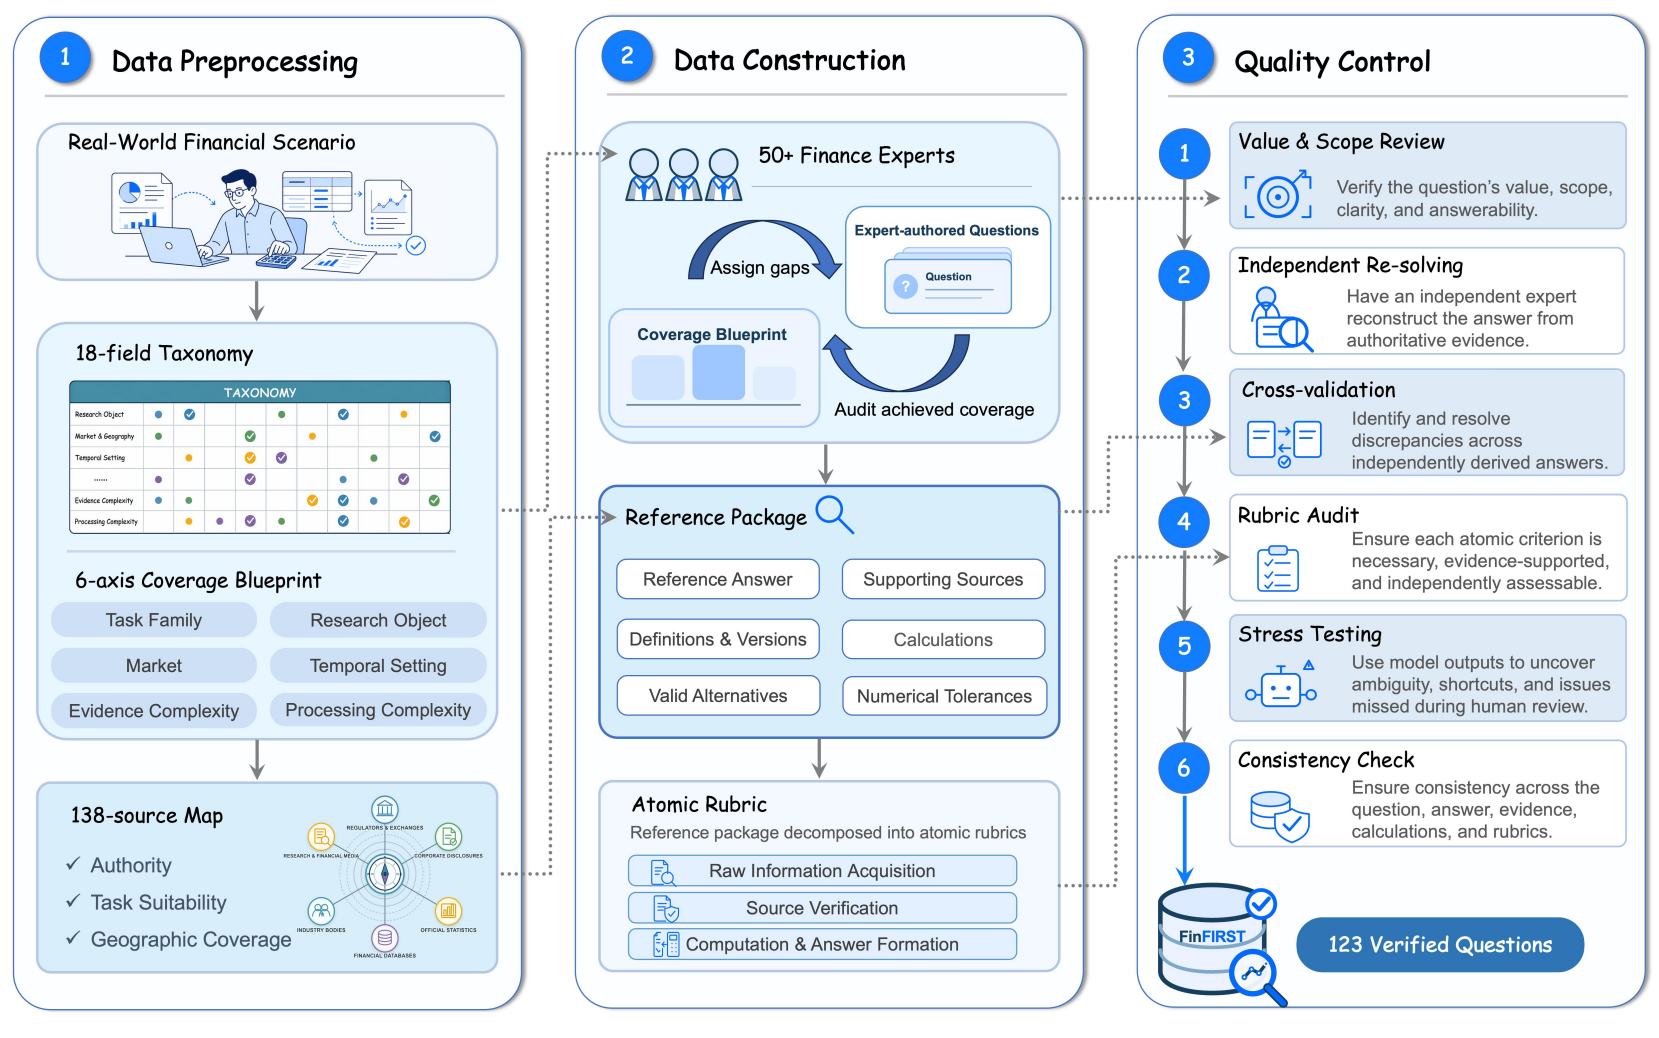
300 dpi PNG · 图注 · 原始PDF
风格入选理由:三列圆角大卡套小卡,六个编号质控步骤、大量线性图标与细密文字,浅蓝底色。
图1和数据构建段落明确给出预处理、专家构建、六阶段质控的完整基准生产流程。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 319, 505, 568],PDF点、左上角原点。
Figure 1: Overview of FINFIRST construction pipeline: Data Preprocessing derives a taxonomy,
coverage blueprint, and source map from real-world financial scenarios; Data Construction engages
over 50 finance experts to iteratively author tasks, balance coverage, construct evidence-grounded ref-
erence packages, and define atomic rubrics; and Quality Control applies a 6-stage filtering procedure,
yielding a final set of 123 verified questions.
EAGLE: Grounding Multimodal LLM Judges for AI-Generated Image Assessment via Evidence Anchors
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页
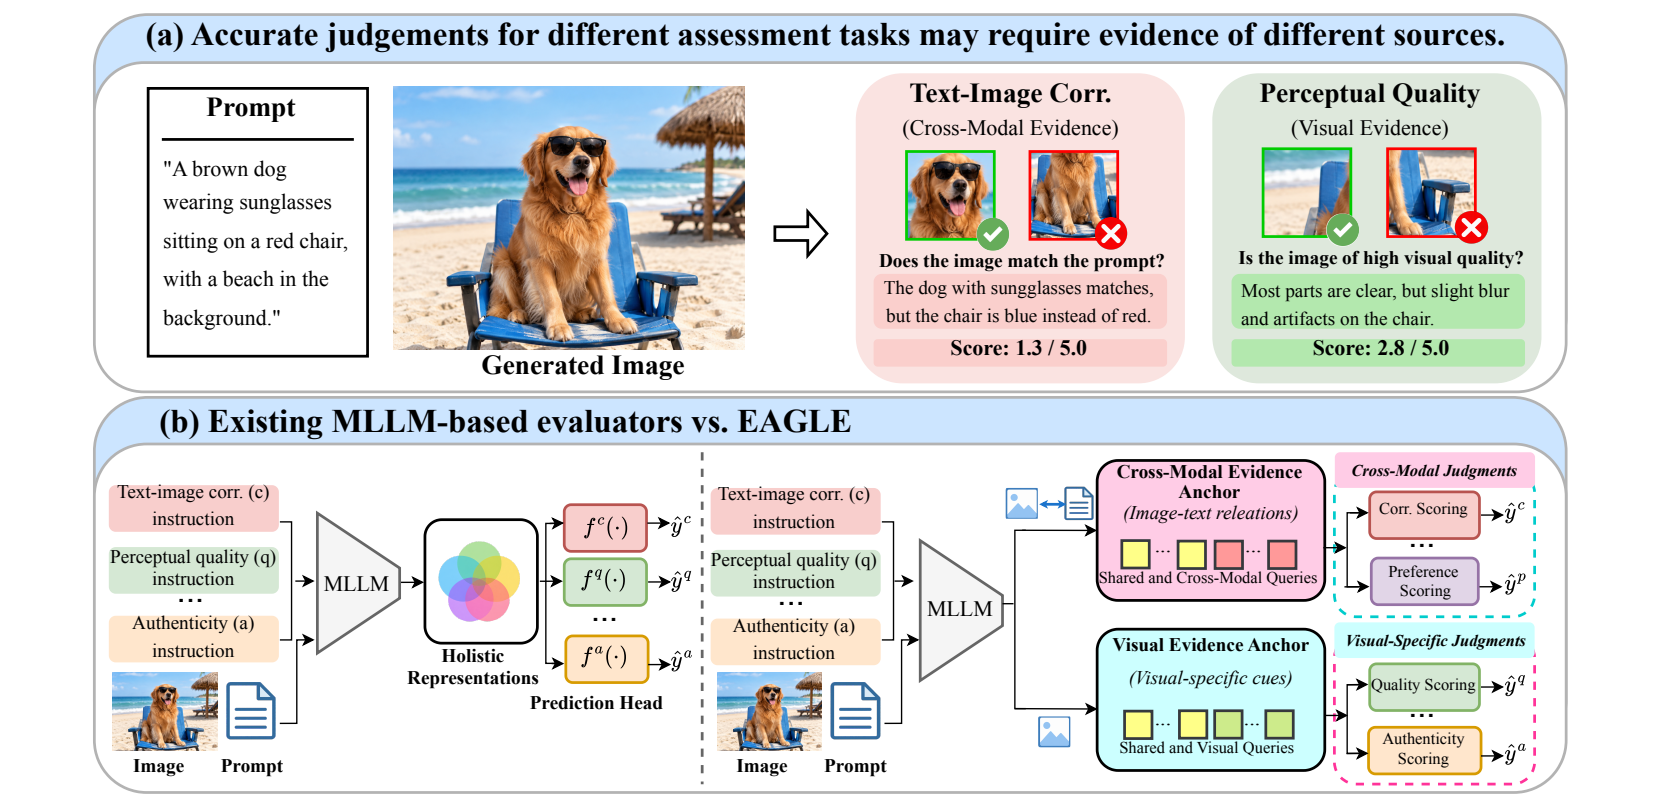
300 dpi PNG · 图注 · 原始PDF
风格入选理由:(a)(b)上下分面、任务说明卡和评分小框,浅蓝粉绿,图片与标签形成密集组合。
图1和引言说明不同评价判断需要不同证据,并对比现有整体表示与证据锚定。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。作者声明生成式AI仅用于语言编辑;具体绘图工具未披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 274],PDF点、左上角原点。
Figure 1: (a) Different assessment judgments may rely on different evidence for the same generated
image. (b) Left: Existing MLLM-based evaluators derive different assessment scores from a holistic
multimodal representation; Right: EAGLE grounds different judgments in cross-modal or visual
evidence anchors and uses shared and anchor-specific queries to acquire the corresponding evidence.
EAGLE: Grounding Multimodal LLM Judges for AI-Generated Image Assessment via Evidence Anchors
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页
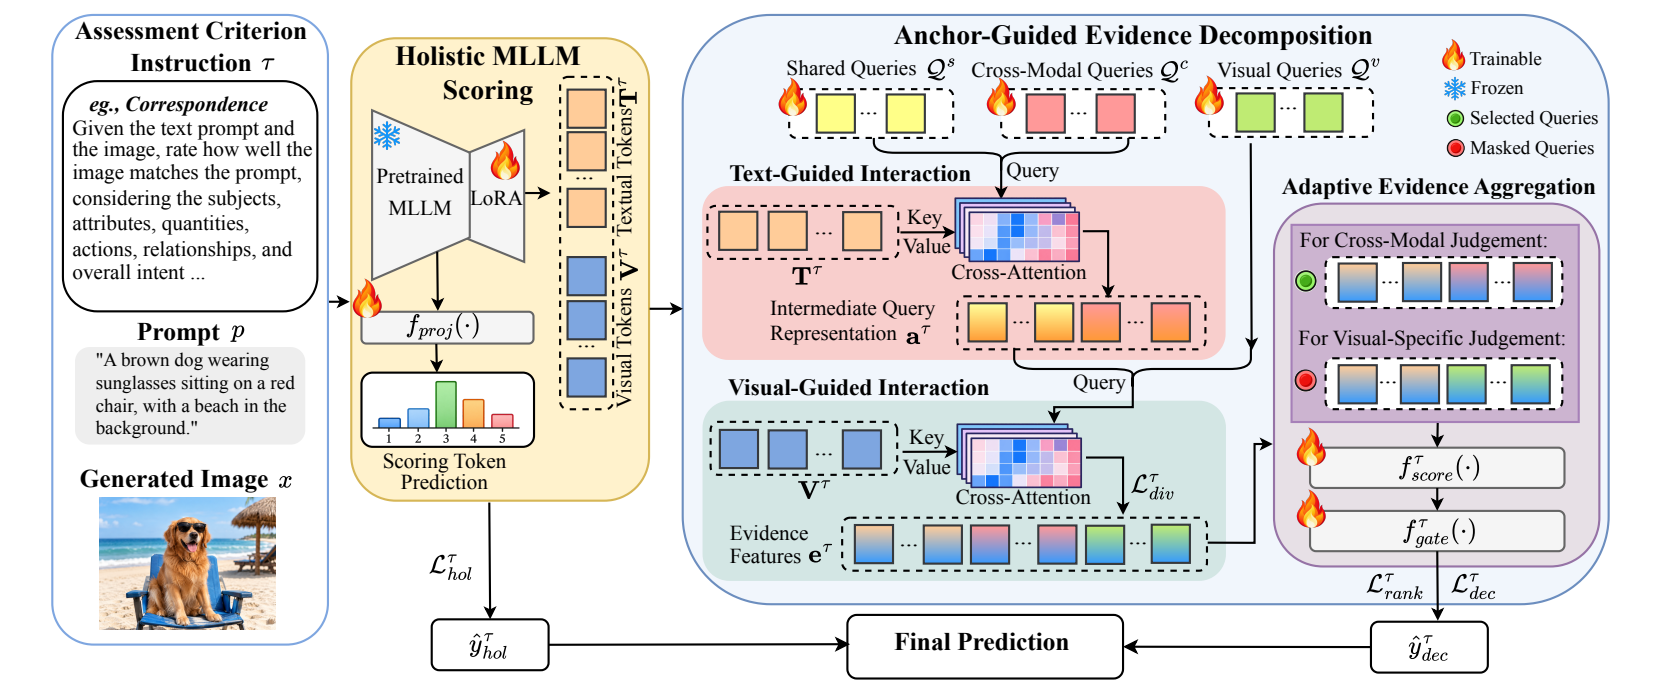
300 dpi PNG · 图注 · 原始PDF
风格入选理由:多层浅蓝绿粉框、查询卡与评价文字,火焰/雪花等状态图标及并排计算分支。
方法节称图2为整体框架,连接MLLM整体评分、证据分解、聚合和最终预测。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。作者声明生成式AI仅用于语言编辑;具体绘图工具未披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 247],PDF点、左上角原点。
Figure 2: Overview of EAGLE. It combines holistic MLLM scoring with anchor-guided evidence
decomposition. The decomposition branch organizes latent queries into shared and anchor-specific
groups to respectively acquire reusable evidence across judgments and cross-modal/visual evidence
anchor, followed by adaptive aggregation of these grounded judgments for criterion-specific scoring.
The decomposed prediction score is further combined with the holistic score for final assessment.
A Simulation-Grounded VLM Framework for Agentic Wildfire Monitoring and Reporting
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第3页
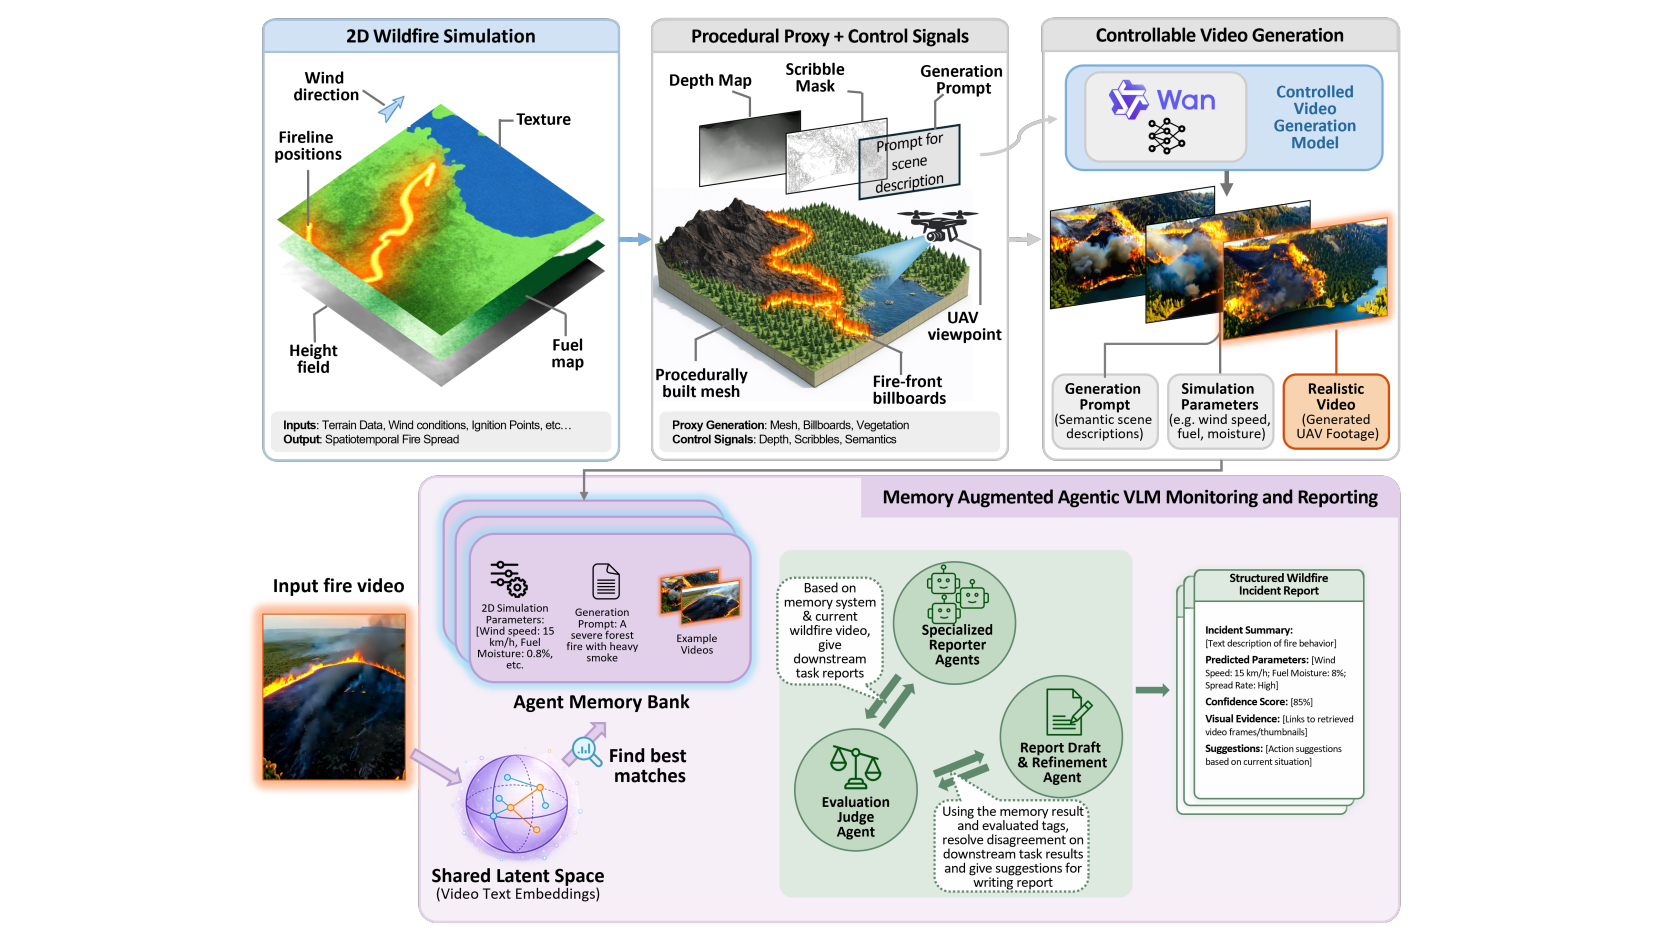
300 dpi PNG · 图注 · 原始PDF
风格入选理由:上排场景生成三栏、下排紫色代理循环,大量输入/记忆/工具卡、图标与解释文字。
图1和正文展示模拟与3D代理场景生成视觉片段,再进入记忆和智能体决策的整体框架。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 306],PDF点、左上角原点。
Figure 1: Overall simulation-grounded VLM framework. Top: 2D simulation and procedural 3D
proxies provide depth, scribble, and prompt controls for synthetic aerial-view episodes with simulator-
derived labels. Bottom: a memory-augmented multi-agent VLM reporter combines query frames,
retrieved labeled references, and disagreement adjudication for wildfire monitoring and reporting.
CADForge: Agentic Single-View CAD Reconstruction with Explicit Geometry Reasoning
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第4页
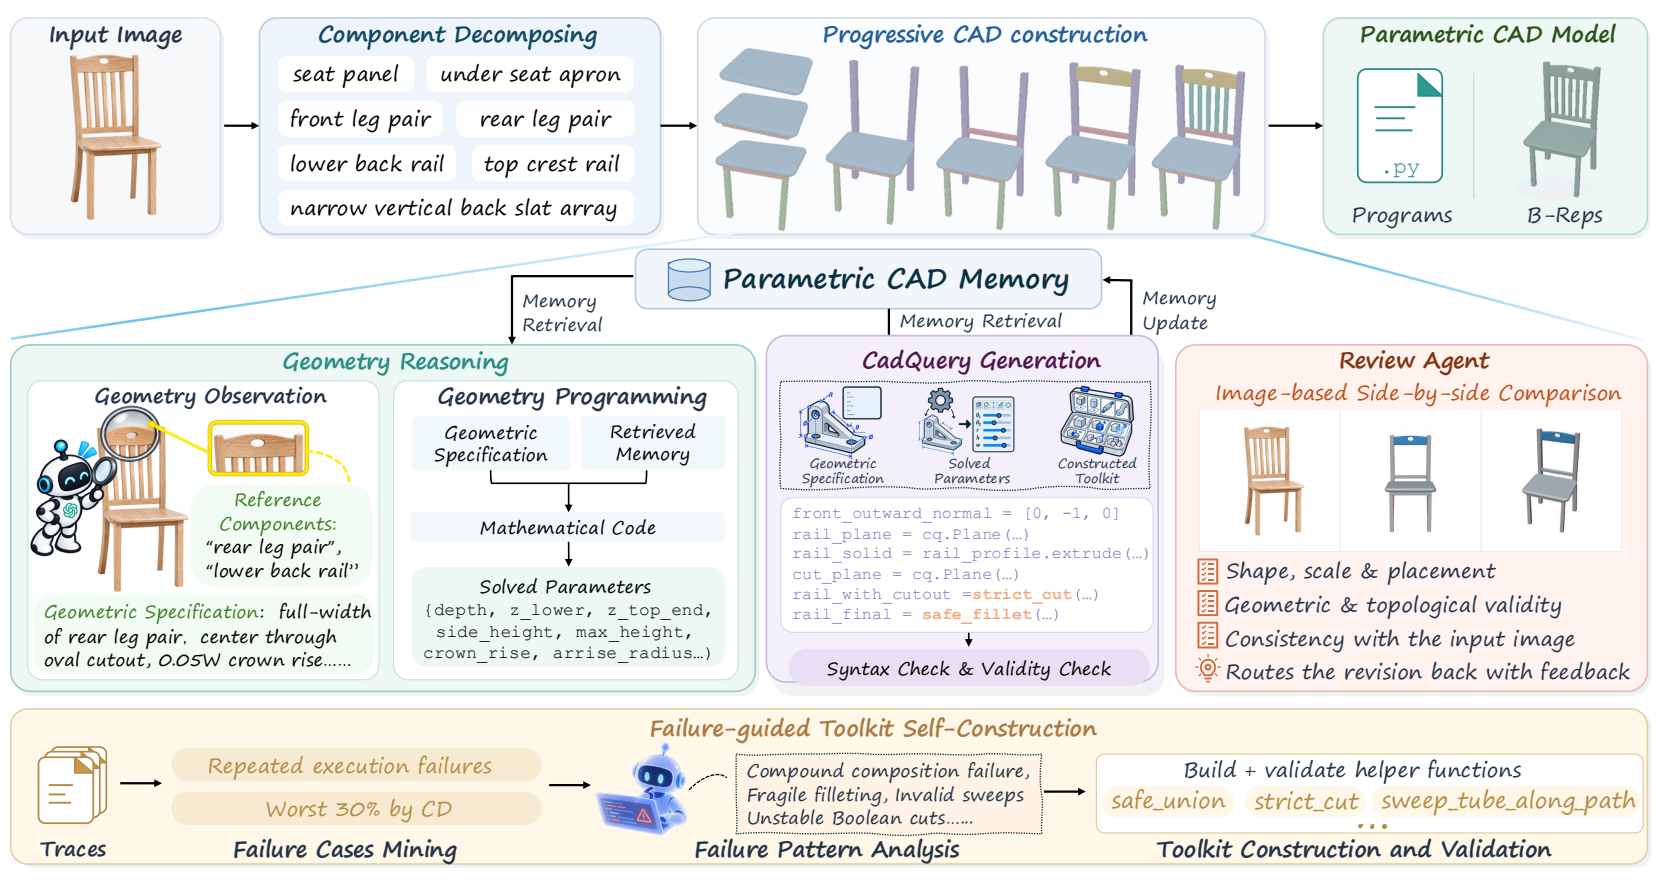
300 dpi PNG · 图注 · 原始PDF
风格入选理由:多排浅色框与代码卡,几何/机器人/工具图标、细密描述与橙紫蓝分区。
图1和方法节描述从单图分解、几何观察、编程、验证到工具自构建的整体路径。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:14 · 声明原文记录
裁剪位置:[107, 80, 505, 294],PDF点、左上角原点。
Figure 1: Overview of CADForge. Given a single image, CADForge decomposes the object into
several components and constructs them progressively. For each component, geometry observation
identifies reference components and CAD-relevant constraints, while geometry programming trans-
lates them into key modeling parameters. A code generator then synthesizes executable CadQuery
code, and a review agent evaluates the result and provides targeted feedback. Throughout the pro-
cess, a compact parametric CAD memory maintains essential CAD state for on-demand retrieval,
while a failure-guided toolkit offers reusable helpers for robust code generation.
Look Back to Move Forward: Learning to Revisit for Agentic Compositional Image Generation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页
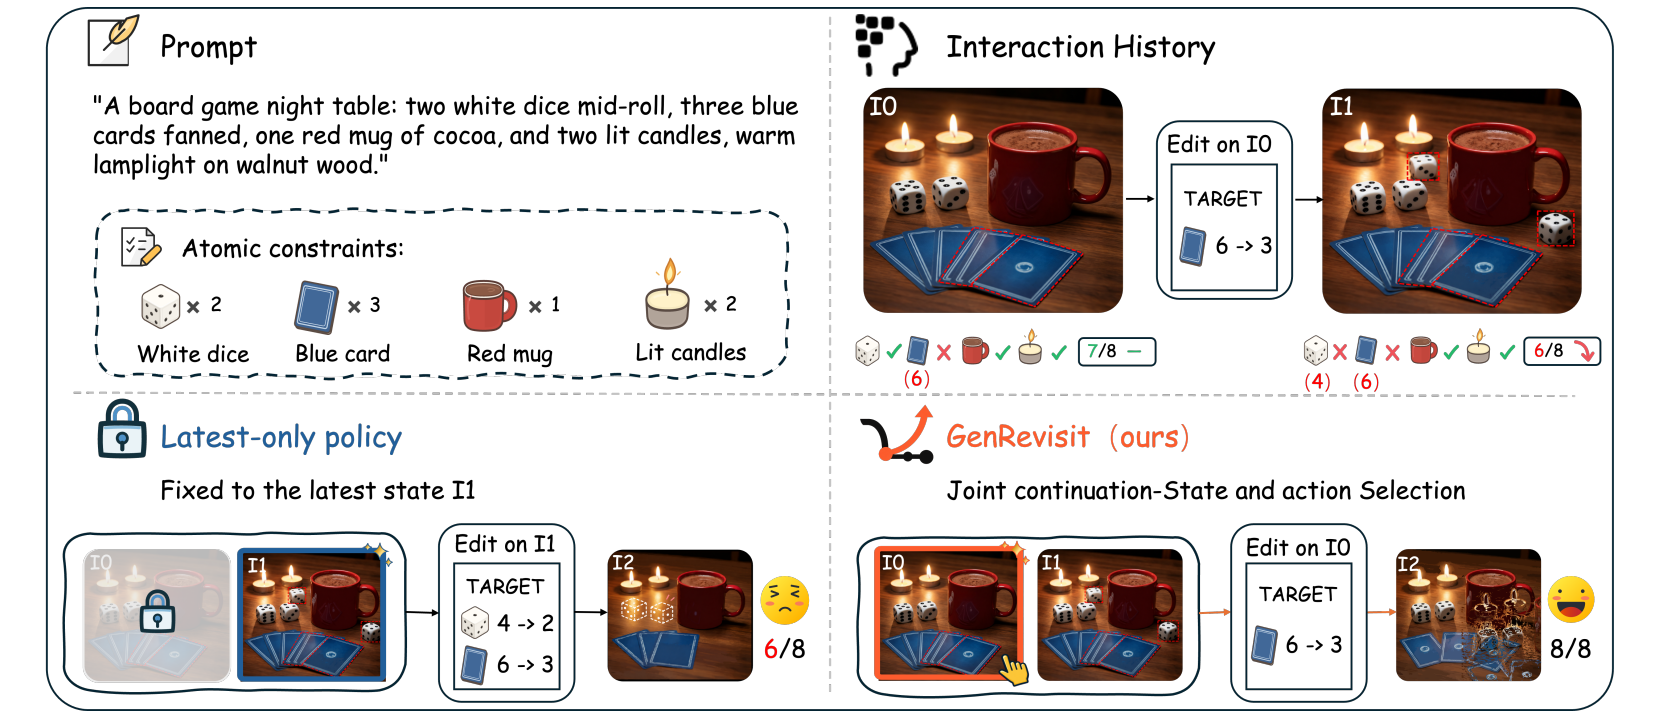
300 dpi PNG · 图注 · 原始PDF
风格入选理由:四区框格、嵌套提示和原子约束卡、锁/物体/勾叉图标与细密说明,浅灰蓝绿配色。
图1与引言通过同一编辑历史对比只能沿最新状态继续与可回访旧候选,解释决策空间局限。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 253],PDF点、左上角原点。
Figure 1: An illustrative comparison between latest-state refinement and our GenRevisit.
Look Back to Move Forward: Learning to Revisit for Agentic Compositional Image Generation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第4页
300 dpi PNG · 图注 · 原始PDF
风格入选理由:(a)(b)上下堆叠,多层圆角卡片包含大量文字和小图标,浅紫蓝绿分区。
图2明确用(a)整体工作流和(b)实例展示规划、动作选择、执行验证、状态更新的完整循环。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:10 · 声明原文记录
裁剪位置:[107, 80, 505, 366],PDF点、左上角原点。
Figure 2: Overview of GenRevisit. Panel (a) presents the overall workflow. At each decision step, the multimodal planner selects the next action based on the decision context and, when editing, jointly selects a source image as the continuation state and a corresponding edit specification. The resulting image is verified and recorded in the interaction history to inform subsequent decisions, while submission returns the historical GM-best image. Panel (b) illustrates an editing example. The planner selects I₁, which is neither the latest candidate I₂ nor the GM-best candidate I₀, and corrects the backpack count while preserving the other constraints. The resulting candidate I₃ passes all constraint-level checks and becomes the new GM-best image.
Don't Ask Agents to Do Everything: Selective Agentic Reasoning for Single Image to 3D Scene Generation
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 2 · PDF第3页
300 dpi PNG · 图注 · 原始PDF
风格入选理由:上下两排多层卡框,代理/几何物体/勾叉图标、密集操作标签,浅黄蓝紫色阶段条。
第3节明确称图2展示场景初始化、环境构建和场景细化的三阶段整体框架。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:9 · 声明原文记录
裁剪位置:[107, 80, 505, 220],PDF点、左上角原点。
Figure 2: Overview of our framework. From a single image, scene initialization (Stage 1), environ-
ment construction (Stage 2), and scene refinement (Stage 3) build a complete 3D scene. In Stage 1,
the geometry-aware layout predictor regresses per-object R, T , S, and floor rotation F .
OPTScientist: Toward Recursive Self-Improving Agents via Automated Optimizer Discovery
会议:ICLR 2027 · 投稿(采集时审稿中)
Figure 1 · PDF第2页
300 dpi PNG · 图注 · 原始PDF
风格入选理由:浅蓝绿紫圆角大卡套入研究条目与评估小卡,多个线性图标、细密说明和回路线。
图1及第4节连接研究专家、共享知识、程序约束、多保真评估和知识更新的完整系统。
图注、来源与作者披露
ICLR2027 OpenReview投稿 · 公开:2026-10-03T12:42:08.286000+00:00
固定公开投稿PDF;公开日为时间代理。未系统核查所有更早arXiv/项目页视觉版本,实际创作时间unknown;不声称ICLR身份能证明阶段起点后作图。
绘图工具:unknown。声明未明确披露所选图的绘图工具;研究中使用模型、文字润色或审查图表不等于绘图工具披露。
披露页:22 · 声明原文记录
裁剪位置:[107, 80, 505, 294],PDF点、左上角原点。
Figure 1: Overview of OPTSCIENTIST. Eight domain specialists share research knowledge, pro-
pose optimizer hypotheses, and submit programs through an extensible typed DSL. Compilation and
static admission checks precede a multi-fidelity pretraining cascade. Results, lineages, and lessons
are written back to guide subsequent proposals. Full-fidelity validation establishes transfer and in-
forms later system generations; it does not enter the online ranking of the same proxy-search run.